Tag: Hashicorp

  • Most Organizations Benefit From a Mature Cloud Strategy

    Most Organizations Benefit From a Mature Cloud Strategy

    Today’s cloud adoptions are wide and varied. Large enterprises are composed of vast, hybrid multi-cloud strata, often incorporating legacy technology acquired at various times and haphazardly equipped from department to department. But a fractured cloud approach can leave IT wanting in terms of shared automation and standard security policies.

    Not all organizations have addressed best practices around common areas like CI/CD, resource optimizations, or common policies for multiple clouds. And many teams are just getting the hang of the new cloud-native stack. But studies show that a mature approach to cloud operations can pay dividends in the long run—and this approach hinges on cloud platform teams.

    HashiCorp recently released the findings from its third annual State of Cloud Strategy Survey, which surveyed 1,000 technology practitioners on their cloud adoptions. In short, the report discovered that increased cloud maturity equates to increased overall value. Below, I’ll distill the major findings from the report to better understand how cloud-native operations are maturing.

    State of Cloud Maturity

    Most organizations are moderately increasing their cloud investments. Overall, 56% increased their cloud spending in the last year. Increases were much higher for higher cloud-maturity organizations and stilted for lower-maturity organizations. The findings demonstrate general confidence in cloud adoption, even amid economic uncertainties.

    There is also persistent optimism in multi-cloud strategies. In fact, 73% of companies said a multi-cloud strategy helped advance or achieve their business goals. And to successfully accomplish a multi-cloud strategy, respondents ranked security, uptime and availability, infrastructure scalability and regulatory compliance as top factors.

    However, there is still a lot of waste in the cloud. Nearly all organizations (94%) said they have avoidable cloud spending. These expenses most commonly stem from areas like over-provisioning resources, idle or unused resources, cost premiums or a lack of expiration date on cloud resources.

    Benefits of Maturing Cloud-Native Operations

    Overall, there are many reasons for adopting a multi-cloud approach—the report found reliability, cost reduction, security and governance and digital transformation as top motivators. And on average, high-maturity cloud adopters tend to reap the rewards more often, the report found. Some of these top rewards ranged from a stronger security posture to better visibility and increased automation. Furthermore, half of high cloud-maturity organizations reported successfully saving money using multi-cloud.

    Most interestingly, perhaps, is that high-maturity cloud adopters said they are better equipped to attract, motivate and retain talent than lower-maturity cloud adopters (74% compared with 48%). It’s generally easier to pull in talent when operating with attractive cutting-edge technologies that look good on a resume.

    Spotlight on Platform Teams

    Even then, skills shortages remained the top bottleneck in most organizations’ ability to operationalize multi-cloud and set up platform teams. This can be side-stepped by reskilling or upskilling staff, incorporating more consultants or increasing the budget. But the best strategy is to standardize on a common operating model.

    In that vein, investments into the platform engineering concept are rising. In fact, 92% of organizations are adopting, standardizing or scaling platform teams. Low cloud maturity firms tend to lag on platformification, most likely due to lacking the necessary skills to build and maintain internal developer-facing infrastructure, like the tools used to measure and improve developer productivity and satisfaction at LinkedIn. Others are still on the cusp of exploring how to implement it.

    The idea of platform engineering is still taking root, so it was interesting to see how organizations described the platform teams’ roles and responsibilities. The results showed platform engineers commonly take the reins on everything from architecting solutions to tooling acquisition and internal evangelism. Here are the five top-cited roles for platform teams:

    • Develop and standardize a cloud infrastructure strategy (95%)
    • Architect cloud solutions (95%)
    • Create and distribute cloud management, operational policies and best practices (94%)
    • Determine which cloud vendors and/or technologies are used in production (93%)
    • Define and measure site reliability (91%)

    The Path to Cloud Maturity

    In general, companies are still confident about their cloud trajectories. But, getting to a mature multi-cloud state will take work. One area that needs further scrutiny is cybersecurity, as password or credential leakage is now seen as the most prevalent cloud security threat. Organizations will require better DevSecOps best practices to avoid such leaks. That, and certain open source cloud-native tools could also aid security and compliance efforts.

    A mature cloud strategy will also require localizing development efforts through shared platforms and increasing infrastructure automation. On that note, 83% of organizations say automation tools are important or extremely important to operationalize their multi-cloud infrastructure. More automation for cloud-native areas like CI/CD, observability and Kubernetes management could also abstract complexity and fill the skills gap.

    As the HashiCorp study clearly showed, those organizations that have matured their cloud strategy are far better off because of it. They tend to understand their workflows better and can more seamlessly introduce new automation. Now, it’s only a matter of getting there …

  • HashiCorp Acquires BluBracket to Extend Secrets Management Reach

    HashiCorp Acquires BluBracket to Extend Secrets Management Reach

    HashiCorp this week revealed it has acquired BluBracket to add a set of scanning tools for discovering static secrets to its portfolio.

    James Bayer, senior vice president of research and development for the Secure product line at HashiCorp, said the existing Vault platform for managing secrets is designed to enable developers to manage them as they build applications. BluBracket has developed a secrets management tool that makes it possible to discover secrets in applications that have already been deployed in production environments, he said.

    The amount of secrets management-related technical debt many organizations have can be enormous, especially if they’ve been deploying applications for decades. IT teams need a tool that discovers secrets in applications that, in many cases, were deployed by application developers that are no longer with the company, Bayer added.

    The BluBracket tools make it possible to discover those unmanaged secrets even before efforts are put in place to improve application security, he noted.

    HashiCorp will initially integrate BluBracket’s functionality into HashiCorp Vault to expand HashiCorp’s zero-trust capabilities, and add detection and remediation workflows via additional capabilities expected later this year. That’s critical, because for decades, developers have been storing secrets in applications and forgetting to remove them before an application is deployed.

    In general, HashiCorp is moving to transform its Vault platform into an orchestration engine for managing secrets regardless of where those secrets might be stored, said Bayer. That approach will enable developers to build applications and store their secrets on, for example, the Amazon Web Services (AWS) cloud in a way that can be centrally managed via the Vault platform, he added.

    Most organizations today are at varying stages of embracing DevSecOps best practices to improve software supply chain security. It’s not clear how readily secrets management is being embraced as part of those modernization efforts, but as cybercriminals routinely scan for application secrets stored in clear text, the need to encrypt secrets becomes a higher priority.

    The core DevSecOps issue most organizations are wrestling with is how involved cybersecurity teams should be in application development. There’s clearly a concerted effort to push more responsibility for application security further left toward developers. The challenge is, even when those tools are provided, it’s not clear that developers can distinguish between the severity of one vulnerability versus another.

    Conversely, most cybersecurity teams don’t really understand how modern applications are developed. That doesn’t necessary mean cybersecurity professionals need to dive deep into application development workflows, but it does mean they should, at the very least, understand how applications are constructed to make sure the appropriate security guardrails have been put in place.

    Regardless of approach, it’s clear there is a need for some type of centralized security function to better ensure application security. Unfortunately, the cultural divide between application developers and cybersecurity teams remains fairly wide. The DevSecOps journey ahead will be long, as each organization determines how best to bridge that gap when the supply of available cybersecurity expertise remains constrained.

  • HashiCorp Releases Slew of Updates to Improve DevSecOps

    HashiCorp Releases Slew of Updates to Improve DevSecOps

    At a HashiDays event this week, HashiCorp launched updates to its Terraform implementation and a software-as-a-service offering, dubbed HCP Vault Secrets, that promise to simplify infrastructure security and ensure that secrets are not leaked.

    In addition, HashiCorp has added a self-hosted edition of its remote access security tool, Boundary, that can now also record SSH sessions. The company is also announcing general availability of Vault Secrets Operator, which provides a high level of abstraction for managing secrets in a Kubernetes environment and which synchronizes with the secrets management interfaces defined by the Kubernetes Technical Oversight Committee.

    Finally, HashiCorp is making available in beta a 1.16 update to the Consul service mesh for containers and virtual machines that adds a Sameness Groups capability to improve the resiliency of microservices by redirecting requests to an identical service. HashiCorp has also added a transparent proxy mode to enable failover between services along with a permissive mutual TLS (mTLS) that enables a service to be configured to accept both mTLS traffic from mesh-enabled services and non-Consul mTLS traffic from external downstream applications.

    Chris Van Wesep, senior director of product marketing for HashiCorp, said Version 1.5 of HashiCorp Terraform adds config-driven import workflow and check blocks capabilities that make it possible to declaratively use code to add existing resources into a Terraform state. Previously, the only way to update a Terraform state was to use an import command that could only be applied to one resource at a time. Terraform 1.5 also adds automatic code-generation capabilities for imported resources.

    In addition, version 1.5 of Terraform also includes a tool to validate that provisioned infrastructure is behaving as intended. That latter capability makes it possible to reduce the number of misconfigurations created by developers that might one day be exploited by cybercriminals to breach an IT environment.

    HCP Vault Secrets, meanwhile, provides a beta release of a SaaS edition of the existing Vault offering specifically designed to enable organizations to better manage application secrets that might inadvertently be exposed to cybercriminals in a production environment, said Van Wesep.

    HashiCorp is moving toward providing a portfolio of tools that enable DevOps teams to securely provision and manage hybrid cloud computing environments using a common workflow, he noted. A Forrester Consulting survey found nearly three-quarters (73%) of respondents are reporting this strategy is helping them reach their business goals, with another 19% adding they expected this strategy to help them achieve their business goals in the next year.

    It’s not clear whether organizations are fully embracing multi-cloud computing, but each additional cloud added to an enterprise IT environment increases the total cost of IT. The only way to mitigate those costs is to define a set of best practices for building and deploying applications that can be applied to any cloud computing environment.

    Unfortunately, many organizations will discover that, as they attempt to define those best practices, they have inadvertently become dependent on a set of proprietary application programming interfaces (APIs) that thwart those efforts.

  • Survey Finds Cloud Management Strategies Shifting

    Survey Finds Cloud Management Strategies Shifting

    Even though organizations continue to consume cloud resources inefficiently, they continue to increase the amount of money allocated. These were among the findings of a global survey of 1,000 technology practitioners and decision-makers conducted by Forrester Consulting on behalf of HashiCorp.

    The survey found a full 94% of respondents reported that their organization struggled with cloud waste. Top factors contributing to avoidable cloud spending included overprovisioning resources (50%), idle or underused resources (50%) and a lack of needed skills (43%). Nevertheless, more than half of respondents (56%) said they boosted their cloud spending in the last year compared to 22% which reduced it.

    At the same time, however, 92% of respondents said they are moving toward adopting, standardizing or scaling platform teams as part of an effort to centralize the management of cloud services, but only 39% are scaling the use of platform teams throughout the organization. The survey also found, however, that organizations are addressing skills shortages by adopting a common operating model/shared automated workflows (58%), reskilling/upskilling (56%) and working with partners (43%).

    The survey also found many organizations are also committed to multi-cloud computing, with nearly three-quarters (73%) reporting this strategy is helping them reach their business goals. Another 19% said they expected this strategy to help them achieve their business goals in the next year.

    The most-cited reasons for adopting a multi-cloud strategy were reliability (51%), cost reduction (48%), security and governance (45%), digital transformation (45%) and scalability (45%). Only 10% had no choice but to go multi-cloud due to acquisitions or other issues.

    Security (88%), availability (84%) and scalability (84%) were identified most often as being important/very important multi-cloud success factors, followed closely by regulatory/compliance requirements (82%), staffing and skill levels (82%), budget (80%), visibility into cloud infrastructure (78%), automated tooling (77%) and platform teams (75%).

    The top cloud initiatives were data protection (77%), followed by secrets management and access control (both at 75%), the survey finds. The top security concerns were password/credentials/secrets leakage (50%) followed by data theft (49%), phishing (46%) and ransomware (42%).

    Overall, respondents said the biggest benefits of having a multi-cloud computing strategy were a stronger security posture (74%) and helping attract, motivate and retain skilled staffers (68%).

    Chris Van Wesep, senior director of product marketing for HashiCorp, said it’s clear organizations are purposely using multiple clouds to reduce costs by pitting one cloud service provider against another. The challenge organizations face when using that approach is they need to define a consistent set of development processes that can be used across multiple clouds to keep total costs under control.

    Organizations that embrace multi-cloud computing are also more likely to implement security best practices because of their need to consistently manage multiple cloud computing environments, he added.

    Of course, there is always going to be a great disparity between high- and low-performing organizations. The survey found that about 25% of survey respondents are high performing, with an equal number falling at the other end of the spectrum. The rest fall somewhere in between those two ends of the spectrum. The issue is that the gulf between the high and low ends of that spectrum appears to be widening as more organizations fail to muster the level of skills and expertise needed to succeed in the cloud era.

  • 90% Of Orgs Say Multi-Cloud Helps Achieve Business Goals

    90% Of Orgs Say Multi-Cloud Helps Achieve Business Goals

    Multi-cloud is the new normal. And thankfully, this new normal isn’t just happenstance—it’s driving positive outcomes.

    New findings show that most organizations benefit from using multiple cloud providers. Multi-cloud adoptions are helping achieve business goals, such as improving reliability and scalability and increasing overall security and governance. However, nearly all organizations (94%) admitted that they have some avoidable cloud spending and skills shortages continue to hold back a fully-realized multiple-cloud success.

    HaschiCorp recently released the 2022 State of Cloud Strategy Survey: Making Multi-Cloud Work. In addition to showcasing the positive outcomes of multi-cloud adoption, the report found a trend toward automation frameworks that help operationalize multi-cloud. Below, I’ll explore the report’s key takeaways to see what CloudOps and platform teams can garner from current multi-cloud trends.

    Multi-Cloud is Achieving Business Goals

    First off, the use of the public clouds is increasing dramatically—the majority of public cloud workloads will likely double in the next two years. To support this influx, more organizations are moving toward multi-cloud. According to the HashiCorp survey, 60% are already multi-cloud and 21% plan to use multiple clouds within the next year.

    The good news is that a multi-cloud strategy appears to be working. A full 90% of respondents said multi-cloud is helping their organizations achieve their business goals. This figure is an impressive jump from HashiCorp’s 2021 survey, in which only 53% of organizations said multi-cloud was helping them achieve their business goals.

    So, what exactly are companies extracting from multi-cloud adoption? Well, the topmost business goal driving multi-cloud is reliability, at 46%. This is followed by digital transformation (43%), scalability (42%), security and governance (41%) and cost reduction (39%). As we can see, multi-cloud equally benefits various areas.

    Centralized Automation Supports Multi-Cloud

    With the rise of multi-cloud, CloudOps is becoming its own discipline. As such, it’s common for an organization to build a dedicated Cloud Center of Excellence (CCoE) or strategy team to manage cloud operations—86% said they relied on a cloud platform team. Such a team is often in charge of standardizing cloud services, developing cloud best practices, creating operational policies and related duties.

    To aid cloud platform teams, cloud automation is becoming increasingly important. The survey found that 99% see automation as important for operationalizing multi-cloud infrastructure. Multi-cloud automation could help solve inconsistencies across varying cloud workflows. Respondents also found it can be applied to deliver more flexible infrastructure, improve security and governance and better utilize cloud resources. Improving security is especially important here, as 89% said security is a key driver of cloud success.

    So how are these automations built? Well, folks are rarely developing cloud automation tools from scratch—only 27% do so. It’s far more common to either use open source or commercial tools for cloud automation. It’s pretty equal across the board whether these tools are run ‘as-a-service’ or are self-hosted.

    Regardless of the tooling type, companies are experiencing a broad set of benefits from using middleware to manage their multi-cloud operation strategy. 49% rank scalability as a benefit. This is followed by infrastructure provisioning (42%), cost optimizations (40%) and more flexible deployment options (39%).

    (Nearly) Everyone is Overspending on Multi-Cloud

    Unsurprisingly to some, the study found that 94% of organizations are wasting money in the cloud. The following were the top cited areas that contribute to cloud overspending and waste: Idle or underused resources (66%), overprovisioning resources (59%), a lack of needed skills (47%) and manual containerization (37%).

    The cloud overspending dilemma necessitates forethought into optimizations and reduction of idle resources. As I’ve previously covered, some organizations are even tinkering with employing a cloud economist, or Cloud CFO, to keep escalating cloud fees in check. To help this mission, 43% say consistent and automated tooling has or would lead to better utilization of cloud resources.

    Although wasteful spending is pervasive, the majority of companies are forecasting their cloud spending correctly. More than half (57%) said that in 2021 their organization’s projected cloud spend aligned with their actual cloud spend.

    Getting the Most Out of Multi-Cloud

    Multi-cloud is becoming more common across all IT divisions—as is middleware to operationalize and standardize logic between multiple clouds. And, widespread business success with multi-cloud signals increased maturity in this area.

    Yet, multi-cloud doesn’t come without its challenges. Skill shortages rank as the highest factor impeding an organization’s ability to operationalize multi-cloud. Businesses must face other challenges, such as siloed teams, compliance and risk management and lack of training in order to fully realize multi-cloud. Standardized operating models, along with shared workflows and policies, are possible ways to combat these roadblocks.

    The HashiCorp study surveyed 1,000 technology practitioners and decision-makers from around the world. HashiCorp also partnered with Forrester to provide additional analysis of the findings. To read the results for yourself, check out the full report here.

  • HashiCorp Previews Updates to Consul Service Mesh

    HashiCorp Previews Updates to Consul Service Mesh

    During an online HashiConf Global conference, HashiCorp today made available a beta of an update to its open source Consul service mesh for virtual machines and Kubernetes clusters that makes it possible for multiple administrators to share the same instance of a multitenant service mesh.

    Version 1.11 of Consul will also add support for a command line interface (CLI) for Kubernetes that will provide an alternative to Helm charts for installing Consul on those clusters.

    Raymond Austin, director of product marketing for HashiCorp, said it’s become apparent that there is a need for a higher level of abstraction for managing application programming interfaces (APIs) that is easy to deploy across both legacy IT environments based on virtual machines and cloud-native environments based on Kubernetes clusters.

    Of course, in many cases, those Kubernetes clusters are deployed on top of virtual machines. However, there are also now more instances of Kubernetes being deployed on bare metal platforms at, for example, the network edge.

    As IT environments become more complex, a service mesh makes it simpler to discover, access and secure APIs that are now rapidly proliferating across the enterprise. That transition requires a more dynamic approach to not only managing APIs but also the network services those APIs depend on, added Austin.

    HashiCorp is betting that many IT organizations will prefer to rely on a lightweight open source platform supported by a single vendor rather than relying on more complex open source service mesh offerings being developed under the auspices of a consortium.

    It’s still not quite clear who within an IT organization is assuming responsibility for deploying a service mesh. Most often, it’s a development team that makes the initial decision. However, as IT operations teams become more aware that service meshes represent a capability that needs to be horizontally made available across multiple applications, it may be only a matter of time before some organizations decide to standardize on a single service mesh to reduce operational overhead, noted Austin.

    Service meshes will also play a critical role in simplifying management of networking and security services at a higher level of abstraction within a larger DevOps workflow.

    It’s still early days as far as service mesh adoption in the enterprise is concerned, but there are already a large number of service mesh options. In fact, there may never be a single dominant service mesh platform. Interoperability standards still need to be ratified that enable organizations that have standardized on different service meshes to apply policies to microservices spanning hybrid cloud computing environments.

    Of course, not every IT organization requires a service mesh yet, either. Many IT teams can still get by using a traditional proxy server or an API gateway until the number of microservices-based applications deployed starts to achieve critical mass. One way or another, however, the more APIs there are to manage, the more inevitable it becomes that an IT team will deploy a service mesh.

  • HashiCorp Increases Terraform’s Enterprise Appeal

    HashiCorp Increases Terraform’s Enterprise Appeal

    During the online HashiConf Europe conference today, HashiCorp debuted the general availability of a 1.0 release of HashiCorp Terraform along with updates to HashiCorp Terraform Cloud service.

    Meghan Liese, senior director of product marketing for HashiCorp, said in both cases HashiCorp is moving to enable organizations to better secure and govern IT infrastructure-as-code provisioned using open source Terraform tools.

    Version 1.0 of HashiCorp Terraform provides access to a stable application programming interface (API) that will foster interoperability and simplify future upgrades.

    The Terraform Cloud service, which eliminates the need for IT teams to set up and manage a Terraform platform, adds workflows enhancements to the Terraform Cloud that include the ability to publish curated modules to a private registry, enhancements that make it easier to visualize elements of a workspace and a preview of an ability to check with third-party tools related to a Terraform run.

    Overall, the goal is to make it simpler for organizations to compose, collaborate and reuse infrastructure-as-code using modules and the public and private registry options, said Liese. The public registry already has more than 5,000 modules. Terraform Cloud now offers a native workflow to publish modules from the public registry directly into an organization’s private registry.

    Terraform, of course, has been widely employed since it first debuted in 2014. There have been 15 major updates prior to the release of Terraform 1.0, which is intended to provide a foundation that ensures backward compatibility between releases going forward.

    In some instances, Terraform can be too much of good thing. It has considerably accelerated the rate at which IT infrastructure can be provisioned within the context of a DevOps workflow. The challenge, though, is developers often lack the security expertise required to prevent infrastructure from being misconfigured at a time when cybercriminals have become more adept at scanning for those vulnerabilities. To enable IT teams to prevent those misconfigurations, HashiCorp makes available both an enterprise edition of Terraform as well as its Terraform Cloud service. Terraform Enterprise is used by more than 1,200 enterprises, while Terraform Cloud has more than 120,000 users that execute more than 30,000 runs per day.

    It’s not clear if security concerns might one day lead to a backlash against the concept of shifting more responsibility left toward developers to improve productivity. In some cases, developers are simply deploying more insecure applications faster. HashiCorp is making a case for Terraform platforms that allow centralized IT teams to exercise more control over how infrastructure is provisioned as code. The need for that approach is becoming more pronounced, as organizations not only employ Terraform to provision cloud infrastructure but also on-premises IT environments.

    Regardless of how infrastructure is provisioned by developers, security of infrastructure, both inside and outside of the cloud, remains a priority as more workloads than ever are deployed. In effect, the attack surface that needs to be defended has dramatically expanded. Of course, the best security issue of all is the one that never happened because infrastructure is being provisioned right the first time and every time thereafter.

  • Cisco Leans on HashiCorp to Manage Infrastructure as Code

    Cisco Leans on HashiCorp to Manage Infrastructure as Code

    HashiCorp and Cisco today announced a Cisco Intersight Service for Terraform offering based on HashiCorp Terraform Cloud Business software.

    Cisco Intersight is an IT operations management platform that enables IT teams to manage IT infrastructure across a hybrid cloud computing environment. Open source Terraform tools have emerged as the dominant tool for provisioning infrastructure as code in the cloud and, increasingly, in on-premises IT environments.

    HashiCorp Terraform Cloud Business is an instance of Terraform that has been extended to include some additional security and governance capabilities enterprise IT organizations typically require.

    In recent years, Cisco has significantly expanded its presence in on-premises IT environments as many IT teams opted to deploy its servers alongside its networking equipment. Like every other provider of on-premises IT environment, Cisco has been moving to extend the reach of its management frameworks to public clouds to help foster the rise of hybrid cloud computing.

    Prior to the pandemic, most public clouds and on-premises IT environments were managed in isolation from one another. However, in the wake of the economic downturn brought on by the pandemic, more IT teams are trying to centralize the management of IT platforms as part of an ongoing effort to reduce the total cost of IT. The multiyear alliance with HashiCorp fills a major hole in the Cisco management portfolio, as Terraform increasingly becomes a de facto standard for provisioning IT infrastructure-as-code.

    Vijay Venugopal, head of product management for Cisco Cloud and Compute Software, said the alliance with HashiCorp will make it possible to provide Terraform support across a management portfolio that, over time, continues to be enhanced with machine learning algorithms that add artificial intelligence (AI) capabilities, also known as AIOps. That platform is already being employed by 6,000 customers to manage more than 600,000 servers, running primarily in on-premises IT environments, added Venugopal.

    HashiCorp Terraform Cisco

    It’s unclear how the battle for control over hybrid cloud computing will ultimately play out. While providers of on-premises platforms such as Cisco are making a case for using existing management frameworks to also manage workloads deployed on public clouds, the providers of those platforms are now extending their reach into on-premises IT environments. Cisco is, of course, betting that most organizations would prefer to extend an existing framework to achieve that goal, versus having to rip and replace existing IT infrastructure to employ an alternative framework from a cloud service provider.

    Regardless of how organizations ultimately decide to manage IT in the age of the hybrid cloud, it’s clear developers, thanks to tools such as Terraform, are exercising more direct control over IT infrastructure. Incorporating Terraform within a larger IT management framework presents an opportunity to bridge the divide between developers and IT operations teams that have historically relied on visual tools to provision infrastructure. The challenge now is finding a way for developers and IT administrators – with varying levels of programming expertise – to work more closely as management of IT environments become increasingly more complex.

  • HashiCorp Expands Managed Services Offerings

    HashiCorp Expands Managed Services Offerings

    HashiCorp today announced the general availability of its Consul service mesh as a managed service on the HashiCorp Cloud Platform (HCP) along with a beta release of a managed instance of HCP Vault, a secrets management platform, on HCP.

    HCP is currently hosted on the Amazon Web Services (AWS) platform, on which the company is making available its complete portfolio as a managed service. In the longer term, HashiCorp plans to make its managed services available on all the major cloud platforms.

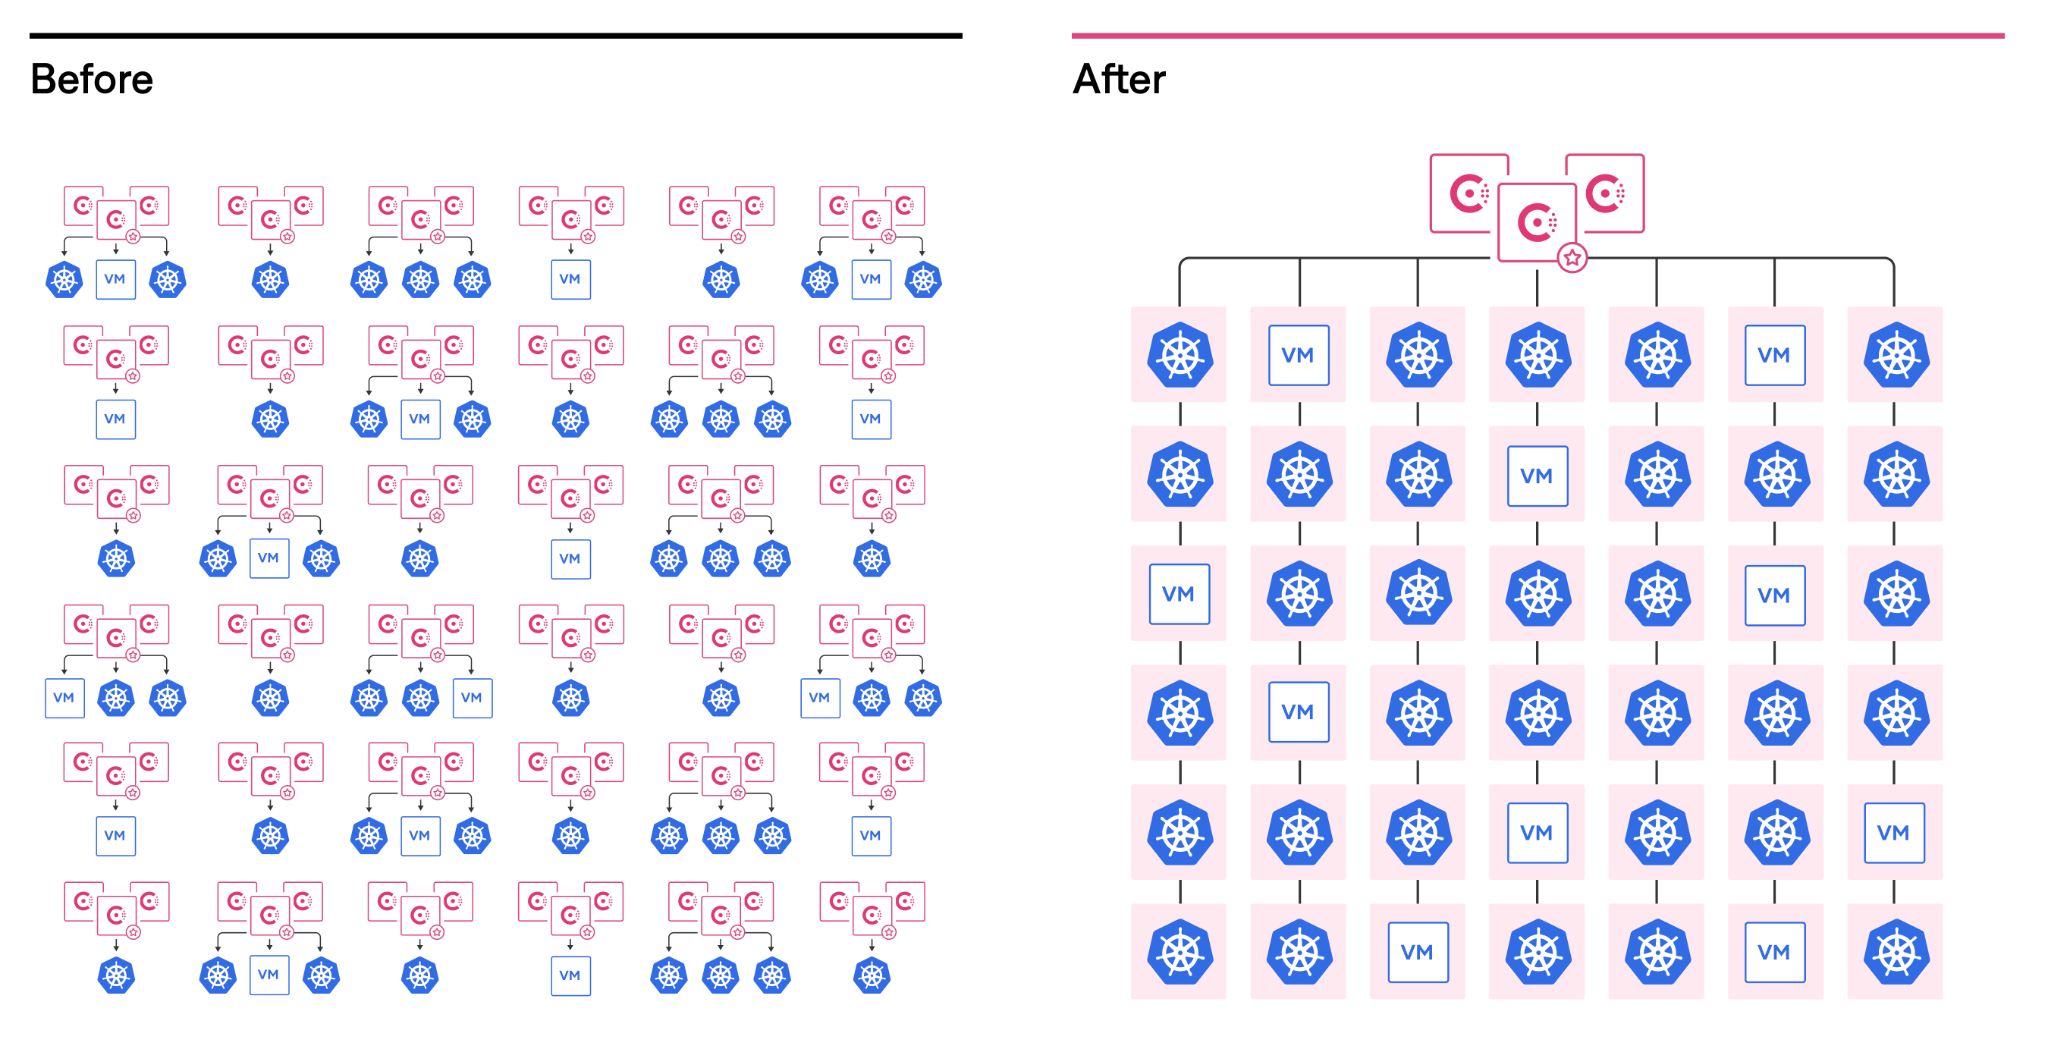
    Chris Kent, director of product marketing for HashiCorp, said despite the growing number of open source service mesh alternatives, many organizations would prefer to employ a service mesh provided by a single vendor that they didn’t have to provision and maintain. HashiCorp’s Consul service mesh provides a lightweight alternative that enables service-to-service networking and security via connection authorization and encryption and spans both Kubernetes clusters and virtual machine platforms using the mutual Transport Layer Security (mTLS) protocol.

    Applications can then employ sidecar proxies in a service mesh configuration to establish TLS connections for inbound and outbound connections without ever having to directly interface with Consul itself.

    HashiCorp is making the case for Consul at a time when internecine warfare is raging between proponents of open source service mesh platforms such as Istio, Linkerd and Kuma. The Consul service mesh provides an alternative that is simpler for developers to incorporate across both microservices-based applications running on a Kubernetes cluster and legacy monolithic applications running on virtual machines, Kent said. In contrast, Istio and Linkerd are designed solely for use in Kubernetes environments.

    It’s still the early days of service mesh adoption. In addition to simplifying application traffic routing between services, one of the other benefits of service mesh is that it provides a layer of abstraction above lower-level network application programming interfaces (APIs) and protocols that is more accessible to developers. As developers become more familiar with service meshes, the ability to programmatically include network and security operations within a DevOps workflow will grow. HashiCorp is collectively positioning Consul and Vault as foundational components for creating a zero-trust architecture.

    In the meantime, each IT organization will need to determine which type of service mesh makes the most sense for their environment. In many cases, organizations may find themselves employing multiple service meshes to address different use cases. Regardless of which they choose, service meshes will soon become a permanent fixture in the proverbial solar system around which IT services revolve.

    HashiCorp claims that more than 2,000 organizations signed up to participate in the HCP Consul and HCP Vault beta programs. That level of interest suggests interest is growing in consuming IT as a service rather than as a platform that requires deployment by an internal IT team. It remains to be seen the degree to which organizations will prefer to consume those services directly from a vendor, versus a cloud service provider or third-party IT services provider.

  • Help Developers Thrive by Finding the Right Platform

    Help Developers Thrive by Finding the Right Platform

    If our developers have what they need to create the best possible applications, they—and our customers—benefit

    Goji Investments was founded on the principle of democratizing access to real estate, business lending, renewables and other alternative investments. The idea is to allow financial service organizations to provide traditionally unavailable investment opportunities to private investors on a global scale. A critical component of the Goji plan for success is the investment platform. Not only do we make the application available as a white-label solution, it can easily integrate into other platforms via APIs. We wanted to create a modular platform that we could update in pieces when needed and easily scale up as clients came online.

    High-Performance Development Teams

    A major reason for Goji Investments‘ success in these first few years is our high-performance development organization, which is instrumental in building and delivering the vision of the investment products needed to generate new business. As we’ve moved from simply building our applications into making them more scalable, we’ve focused on getting the right tools in place for Ops and Dev. Of course, bonus—it makes developers happier if they have cool tools to use.

    One of the things we try to do is keep our application/platform deployment process as agile as the applications themselves—constantly looking to improve and making updates whenever necessary, whether needed to deploy new technologies and applications or based on feedback from the team. The idea is to keep our DevOps pipeline operating smoothly and efficiently.

    One of our key operational strategies is that if we make our developers happy at work, they will deliver better quality applications, which results in happier end users. Of course, developers like to create to come up with innovative ways to deliver great features. One roadblock to coding innovation is performing repetitive low-level tasks, so we’ve actually gone out of our way to automate whatever we can and free up Dev resources for more value-specific application development.

    Automating Deployments is a Start, but Just a Start

    We automate the deployment process through GitHub. Each developer pushes their own services into GitHub themselves, where it goes through a quick review process. After review (if it passes), it’s merged into the master. Any master merge triggers build pipeline execution (which is using ThoughtWorks GoCD), and this automation includes several rounds of testing: unit test and integration test followed by an automated acceptance test. Developers have the option of executing additional tests themselves when desired.

    Any new master is promoted into pre-prod, which mirrors production. When changes are finally rolled into production, we use HashiCorp Nomad’s blue-green deployment capabilities—if a problem were to occur (which means it was missed in official testing), Nomad takes care of any rollback needs.

    The stack is fairly straightforward: The applications are written in Java and run on a DropWizard framework in containers. Nomad is our orchestration platform. One of our foundational principles when selecting application and infrastructure technologies is the ability to automate our deployment processes. We’ve done a fairly good job of automating anything we possibly could, but automating monitoring was more difficult. Our traditional APM tool was fine for alerting us to issues such as an EC2 crash or a resource availability issue for a reboot, but if we wanted to actually troubleshoot the issue we essentially just had to examine logs and hope we could see something out of the ordinary.

    As much as everyone is excited about writing data into logs, combing through those logs to troubleshoot application issues is a waste of time and valuable developer resources. After all, operating 20 different microservices that cover everything from taxes and payments to customer notification required optimization of each element of the DevOps pipelines. The last piece we added was performance monitoring.

    The Value of End-to-End Distributed Tracing

    There’s a great line from Jurassic Park: “T-Rex doesn’t want to be fed. T-Rex wants to hunt.” Well, developers don’t want to be analyzing log files; they want to code. In fact, they want to be creating the next great feature. To get our dev team out of the weeds, we began thinking about a different way to get—and analyze—application performance data.

    We wanted a system that added observability, monitored performance, managed service levels and included visibility from our end user requests all the way into our back-end systems. Oh yeah, we also wanted all of that to happen automatically so that our developers never had to worry about anything other than their own features. Installation, agent setup, discovery, mapping, alert configuration and reporting—as much as possible without requiring human setup.

    We knew tracing was critical—so much so that we avoided missing any problems by specifying a 100% solution, wanting a complete trace of every request to the application.

    Troubleshooting Application Performance Problems

    The real reason you buy application monitoring software is to solve problems, so optimizing our ability to find bottlenecks and eliminate them is a key component of our monitoring solution. First, like the other aspects of monitoring, we didn’t want to have to spend time configuring thresholds for warning and danger alerts. Our need was for automatic anomaly detection with event analysis. Every little bit helps keep our dev team focused on dev, not analyzing data—especially in logs.

    Of course, sometimes, you can’t help it; you have to look at log data, but we wanted to be smarter about that, too. We wanted our application monitoring tool to automatically integrate log analysis tools so that all data could be analyzed at the appropriate level whenever needed.

    Don’t Forget Testing

    Sometimes, testing gets lost in the value of a good monitoring solution. While we weren’t necessarily looking for a testing tool, we knew if a monitoring solution could also operate effectively in test (that’s not just the ability to run in test; rather, I mean the ability to add value in the testing process), well, so much the better.

    It turns out that our applications are quite complex, and that complexity can create lengthier test cycles—commonly in this scenario:

    We recently released a new feature for distributing dividends. As you can imagine, this is a fairly important feature, so we wanted to ensure that it operated as desired and expected. We were especially concerned with being able to scale the feature appropriately. We set up a stress scalability test that took 20+ hours to run (essentially processing hundreds of thousands of payments).

    What we didn’t count on was having to stop some way into the test for someone to either submit an optimization update or actually fix a bottleneck—getting 10-12 hours into the test, then having to halt it and restart it—over and over and over again. We started thinking we might never finish.

    This is one of the pain points we hoped to solve with an automated way of monitoring. By pointing the automatic APM solution at our test environment, not only did we not have to configure anything (or even set up a special start command) but we also got almost immediate feedback on any change (both positive and negative). It also pinpointed the exact location in the code where the problem occurred, so the developer could almost immediately update their code and initiate a restart of the test. Finally, we could pick any two runs and compare their execution and performance to identify the real problem.

    Two things happened:

    • We were able to iterate different runs ~5 times faster.
    • We got such great bottleneck and debugging data from our solution that we cut the runtime of the test from 20 hours to less than one hour.

    Give Developers the Tools to Shine

    While all employees like to succeed, developers especially love when they can rise above their challenges and deliver high-performance code. We like to give our dev team the best possible tools to help them achieve this excellence. Approaching the decision process for selecting a tool for them should be handled no differently than thinking about your end users:

    • Identify pain points.
    • Find a resolution.
    • Execute the solution.

    For our development team, that meant relieving them of low-thought repetitive tasks that we could automate and stop making them spend their time culling through performance logs.

    Making the Right Choice??

    The long and short of it is that we replaced our legacy APM tool with a solution that delivers the automation we crave and eliminates the need for log deep-dive analysis to solve any problem. It also supports log analysis with various integrations, which was important to us.

    We get a trace of every single call, which is important to the Ops and customer support teams—and they profile every production process automatically, which gives our developers more than enough information to take action.

    Ultimately, we’ve accelerated our application delivery and update processes, streamlined testing and monitoring. And our developers are super happy that we give them the tools they need and then challenge them to make the best possible applications using those tools.