Tag: enterprise IT

  • Let’s Bury Bimodal Thinking in Enterprise IT

    Let’s Bury Bimodal Thinking in Enterprise IT

    We still hear a lot about mode-1 and mode-2 in enterprise IT. Like many other large enterprises, you might have adopted the terminology introduced by Gartner and use it every day to shape the way you deliver and operate technology. However, I have always been uncomfortable with the idea of bimodal, as it ignores architectural reality of tightly coupled systems that we have today and the cultural factors. There is also the cultural dimension that is emerging a lot in the transformations that I help clients with.

    The cultural problem with Gartner’s bimodal IT view is that it relegates legacy systems such as mainframe (Z series) or I-series to mode 1 and discourages the new generation of professionals from working on these platforms. If you are in mode 2, you get access to the latest tools and training opportunities, and if you are not, then you are relegated to the end of the queue!

    What do you think? Is bimodal creating two classes of people? Or am I being too harsh in my judgment?

    In a recent article by BMW CIO Klaus Straub, he went on record and said bimodal IT doesn’t work due to cultural issues. As he said in the article, “Until September of last year, I also had a bimodal world in my head—but then the concept was incomprehensible to me. However, it is not suitable for permanently structuring an IT department.”

    BMW is not alone. Other enterprises are joining the voices, such as Peter Jacobs, the CIO of ING Bank Netherlands, who also has expressed similar views on bi-modal. To quote Jacobs: “I would rather work agile at my core bank system than at the channels.”

    The full interview of Straub is below. Unfortunately, the article is in Dutch, so you will need to translate the article to read it: https://www.cio.de/a/amp/bmw-cio-haelt-bimodal-it-fuer-einen-irrweg,3562374

    A few other relevant and interesting articles are below:

    1. https://www.cio.com/article/3193793/cio-role/in-the-digital-era-cios-not-buying-this-bimodal-crap.html
    2. https://www.cio.com/article/3191810/it-industry/why-bi-modal-it-doesnt-really-work.html


    — Aditya Vadaganadam

  • From One-Size-Fits-All to Custom-Fit for IT Ops

    From One-Size-Fits-All to Custom-Fit for IT Ops

    The downfall of the all-in-one IT management suite and the rise of the customized IT Ops toolchain

    Here is how enterprise IT Ops used to work: you would make your choice among the Big Four vendors and buy in (quite literally!) to their strategy. This meant a suite of products that came preintegrated (more or less) out of the box, and—at least on the sales proposal—covered all of an IT organization’s needs across a huge spectrum of activities.

    selection of tools hanging ready to use
    Photo by Barn Images on Unsplash

    Broadly speaking, each of the Big Four’s suites included some flavor of the following: monitoring, ticketing, configuration management and asset tracking and automation and orchestration. Some vendors were stronger in one area than in another, but unless you had pretty specific needs, each vendor could be your one-stop shop.

    Development and improvement inside these suites was mainly incremental and occurred at a fairly leisurely pace. Meanwhile, startups with bright ideas would come along occasionally and challenge the incumbents in specific areas, only to be bought by one of the mega-vendors if they showed enough promise.

    There was a symbiotic relationship between vendor and IT buyer, as IT professionals built decades-long careers as experts in this or that vendor’s technology stack, with the wall of framed certifications to prove it. CIOs were reassured by the fact that there was a readily available pool of experts to hire, and continued reinvesting in the next iteration of their chosen vendor’s stack.

    The Old Model No Longer Fits Modern IT

    In the last decade or so, this comfortable status quo has broken down. The cracks were already showing before then, but only the most agile and forward-thinking organizations were moving fast enough to trip over them. As more and more businesses began to expect greater and greater responsiveness and speed from their IT departments, the huge sprawling suites of the mega-vendors were no longer able to keep up with the required rate of change. Leisurely 18-month release cycles no longer cut it in an agile world, where that time span may encompass several entire strategies.

    In the old world, to call something “best of breed” was a sniffy dismissal of a one-trick pony, as opposed to the more supposedly versatile offerings of the Big Four. In the new world, it became obvious that aside from a handful of tentpole products that were genuinely good and fit for purpose, most of the individual components of the big suites was distinctly unexciting. Worse, the main value proposition of the suites—that they came preintegrated out of the box—started to break down as well. Many IT professionals were still fiercely loyal to individual products, but they became more willing to pick and choose, rather than buying into the whole vision.

    In parallel, the rise of simple integrations—primarily REST APIs—made it easier than ever before to connect disparate solutions together into a single IT Ops toolchain. Worse (from the point of view of the incumbent vendors), sometimes it was easier to connect modern point solutions than their own component pieces, weighted down by the baggage of decades on the market.

    How to Deliver the Flexibility and Agility the Business Expects?

    These days, it is becoming commonly accepted even among the most staid and risk-averse organizations that the way to go is no longer to align to a single IT vendor and trust them to deliver on their vision, but rather to design custom-fit, multisolution toolchains, including home-grown, open source and commercial tools.

    agile jump
    Photo by Max Bender on Unsplash

    But what to do if you find yourself dealing with the consequences of this sort of IT monoculture?

    Look Back At How You Got Here

    The first step is to re-evaluate past buying decisions and strategic alignment. It is very important to do this without assigning blame; it was a different time, and those choices may well have been the right ones for the prevailing environment at the time, when integration between tools from different vendors was legitimately difficult.

    Don’t Just Throw Everything Out

    In many environments, too, the correct solution may well not be a clean sweep. One or more of those tentpole products that kept the overall suite looking good past its sell-by date may well still be perfectly fit for purpose and not worth the hassle of swapping out. However, other components are probably legitimately lagging behind the state of the art, in which case it is worth replacing them with something more fit for purpose.

    Count Costs – All Costs

    Include cost in these calculations, but remember to include all costs. Maybe you or a predecessor signed a big enterprise license agreement (ELA), so Product X is “free” in that context. But what does it cost to keep Product X running, in terms of ancillary licenses, hardware requirements and, last but not least, skill and effort on the part of the IT administrators? I don’t want to name specific products or vendors as examples, to avoid the discussion devolving into particulars, but it’s worth bearing in mind that many legacy products have shallow talent pools—not that many people are available on the market, and many of those people are coming to the ends of their careers, which makes them both expensive and reluctant to change employers. Instead, up-and-coming technologies often have much deeper and wider talent pools, with many more experienced specialists available at all salary and skill levels. If you don’t believe me, try hiring half a dozen COBOL programmers and half a dozen Node.js coders, and then we’ll talk …

    IT Ops hard at work
    Photo by Giu Vicente on Unsplash

    Your IT Ops Toolchain, For Your IT Ops Needs

    Moving from one of the big all-in-one suites to an assemblage of different tools, all flying in loose formation, is not easily done. Any technology transition of this sort is a Project with a capital P, and needs to be planned and managed with due care and attention. However, there is a large payoff at the end in terms of increased agility and flexibility within IT Ops. In turn, this affords IT the ability to offer their business counterparts the sort of responsive and even proactive IT support that moves IT from being a cost center, on a par with Facilities, to a strategic differentiator that enables new business initiatives.

    Business as usual doesn’t cut it any more, and assumptions that used to be valid have fallen apart. Decisions based on those assumptions need to be re-evaluated. New, more flexible approaches will set up IT Ops for success in the newly flexible world we are already living in.

    — Dominic Wellington

  • Measure What’s Important: DevFinOps

    Measure What’s Important: DevFinOps

    Lately there seem to have been quite a few DevSomethingOps terms being coined. However, I do think we need one more: DevFinOps.

    Dev-What-Ops?

    One of the biggest problems in IT is working out the cost of IT. Left unchecked, IT will expand to fill whatever budget it is given. This may mean evermore involved business continuity and redundancy, reinventing evermore elaborate wheels, irrational versus buy decisions and so on.

    In fact, the whole idea of cost estimates for IT projects has become something of a joke. Most IT projects are reputed to exceed their budgets.

    There is an entire #NoEstimates movement that rejects the idea that it is even possible to deliver a sensible estimate for a software development project. As is often the case, the basic idea is reasonable:

    it is possible to do small chunks of work incrementally, leading as rapidly as possible to a desired shippable product, and that when you do that there is no need to do much of anything in the way of estimating stories or the project.

    However, the simplistic interpretation that is all over Twitter is that because there is no estimate of the  overall project, there is no estimate at all. That is not the idea! It is simply to break down the overall estimate (which is probably wrong) and instead budget for much smaller chunks of work, which can presumably be estimated more precisely and accurately.

    So What Can We Do?

    Maybe what is required is integration of financial concerns directly into the fabric of IT development operation. We might call this DevFinOps, in line with other extensions of DevOps such as DevSecOps or DevNetOps.

    This is not such a leap; after all, we already integrate costs in areas such as SLA calculation, estimating the TCO of a tool or the ROI of a proposed purchase. However, these are generally calculations that are made after the fact, and may even be retconned to fit external assumptions.

    What I am proposing, though, is to build this information right into the IT metadata and processes to enable us to make better decisions.

    This is not IT Asset Management, although it would build on those data and extend their reach. A particular device or piece of hardware has its purchase price and current amortised value documented in the ITAM database, but the actual value it has at any given time might vary depending on which business function it is currently supporting. This calculation should change over time to reflect the real current value it is delivering to the organization at any given time.

    An idle server has no particular value beyond the intrinsic value of the hardware, back-end support (floor space, network, cooling, etc.), and perhaps any associated licensed software. However, the same server will take on a much higher value to the organization when it is provisioned as part of the infrastructure supporting a major business-critical application.

    Performing actions on these systems would therefore have different potential impacts, and should be treated as costs deducted from a limited budget. Live-patching a business-critical server is an expensive operation, not to be treated lightly. The cost of doing so should be deducted from an operational budget.

    This calculation has the benefit of making it easier to communicate the different impacts of various proposed courses of action outside the IT department. Deciding between cloud and on-premises deployment options, or between different flavors of cloud, can be a fraught process. Technical options and pricing models are rarely easily comparable, and then there are other costs such as compliance (yes, and GDPR) or vendor risk. Quantifying and normalizing these disparate factors would make it that much easier to compare options up front and calculate benefits after the fact.

    Is This Even Possible?

    Google already does something like this in its Site Reliability Engineering (SRE) program, with the notion of an error budget:

    The business or the product must establish what the availability target is for the system. Once you’ve done that, one minus the availability target is what we call the error budget; if it’s 99.99% available, that means that it’s 0.01% unavailable. Now we are allowed to have .01% unavailability and this is a budget. We can spend it on anything we want, as long as we don’t overspend it.

    There is a long and sordid history of attempts to make programming projects comparable and their estimates more reliable. Often this devolves to simply counting lines of code, according to the age-old management syllogism: “We need to measure something; this measurement is easy to gather; let’s measure this!” and of course the Mythical Man-Month.

    Fortunately, there is a way to calculate the complexity, and therefore the potential cost impact, of a piece of code: the Halstead volume. This is a measurement of the complexity of code, described in terms of the number of distinct operators, the number of distinct operands and the total number of operators and operands. While it is not guaranteed to be perfectly accurate in every case, it is at least accurate enough to be comparable, and therefore can be used to estimate the risk of a change, in terms of the relative Halstead volumes of the code to be changed and the patch to be applied.

    But What About the Squishy Meatbags?

    Connecting the human costs would also enable other metrics to be gathered. It has been historically difficult to differentiate between what is urgent and what is important, and how to prioritize each. If we connect salary data (including overtime) to changes, it becomes much easier to make the call on when enough time has been wasted on a problem and the cost-effective solution is to start from scratch.

    It sounds like a lot of work to gather all of this information, but these data already exist; they’re just not connected up in one place. When the business wants to launch a new service, there are (usually) pretty rigorous calculations behind that decision. The expectation is to acquire or retain a certain number of customers who have a certain average lifetime value and break-even points and other criteria are all mapped out ahead of time. For whatever reason, though, these islands of information are rarely if ever connected up.

    This, incidentally, is just one reason why it can be worthwhile to work with reputable and experienced vendors. I have written before about what this process looks like. The good vendor sales teams will help to unearth this sort of information—but even in the most positive sales processes, the kimono is rarely fully open. There is far more information inside the organization that could be enormously useful if only it were available in the right place and at the right time.

    Longer term, this would mean that business cases and ROI calculations would finally be concrete and factual, rather than extended performance pieces in the medium of spreadsheets. On that note, there is a wonderful little book, titled “How to Lie with Statistics,” which is even available as a free PDF. It’s one of those books that is fun to read because you start spotting the things it was talking about simply everywhere.

    If you wanted to be maximally Zeitgeist-compliant, you could probably verify all of this with blockchain, although I worry that the transaction costs (including thermal costs!) would be prohibitive. The good news, though, is that you could use this DevFinOps methodology to work that out too …

    All That Effort, for What?

    Bottom line, the goal is to be able to calculate (at least within reasonable limits) how much IT is costing today, and what the impact of any proposed changes would be—and crucially, to do so in real time.

    The goal is agile cost estimates. There is a reason I chose the DevFinOps coinage. The way we do cost estimates today is very “waterfall“: large teams have extended arguments over spreadsheets, and the process is so painful and expensive (in person-hours and disruption) that it is only undertaken for the largest changes.

    Agile’s faster release cycles do not align at all well to this process, which is where #NoEstimates is coming from. However, if we start gathering and processing all the cost data in real time, and make it available via a simple API call, it becomes possible to calculate both ends of the cost of a proposed change: the complexity of the code itself, and therefore the probability that it contains bugs, and the infrastructure impact that the deployment will have. This cost can then be compared to the team’s current SRE error budget to determine whether the change can be made automatically or whether it requires signoff as an exception.

    The result looks a lot like ITIL’s notion of a “standard change”, but without the inherent conflict between ITIL’s centralization and SRE’s decentralization. The key is a common accepted measurement of what a standard change actually is, which would otherwise require the ITIL Change Manager to make the determination ahead of time.

    What Does This Look Like in Ops?

    Let’s not forget Ops, either. Proper cost estimates like the ones described above would enable Ops to prioritize alerts correctly and estimate impacts accurately. Two outages with equal technical severity may have very different business impacts. Today, that reconciliation relies on tribal knowledge and systems that are often inaccurate or out of date. Given a central shared repository of data that describes the value of deployed systems, it becomes possible to calculate those impacts much more accurately.

    While we work to get to full DevFinOps, you might want to consider AIOps, which helps gather a contextual view of what is actually going on in IT. Gartner just released a Market Survey for this emerging space. Normally these documents cost $1,295, but you can get a free copy here, courtesy of Moogsoft.

    Dominic Wellington is Chief Evangelist at Moogsoft. He has been involved in IT operations for a number of years, working in fields as diverse as SecOps, cloud computing, and data center automation.

    — Dominic Wellington

  • AIOps: Managing the Second Law of IT Ops

    AIOps: Managing the Second Law of IT Ops

    Or, why IT systems keep breaking

    The tension between the two halves of DevOps is long-standing, going back long before the term was even invented. What underlies the split between Development and Operations is a fundamental difference, like an actual physical law. Let’s explore that analogy together.

    IT Ops is fundamentally a constant fight against entropy, meaning disorder. Sysadmins expend significant energy trying to keep everything up and running, in a process which can sometimes feel like trying to shore up a sandcastle while the tide is coming in. Systems are constantly breaking down; users need changes made that introduce risk; and, as if that wasn’t enough, the whole shebang is constantly under attack from malicious outsiders. It’s no wonder that sysadmins have a reputation for being a bit grumpy!

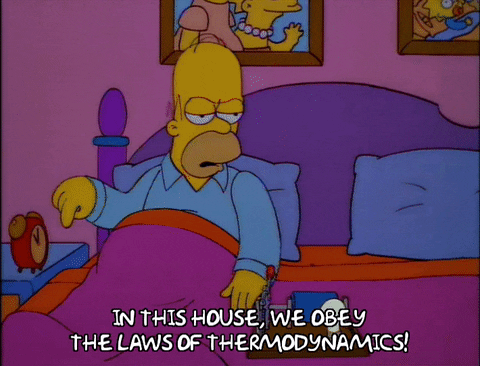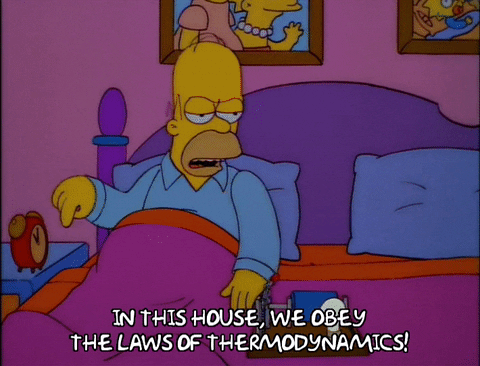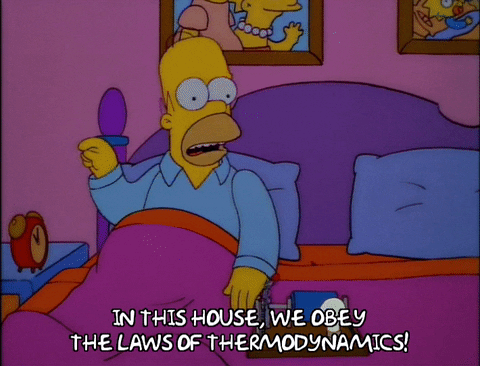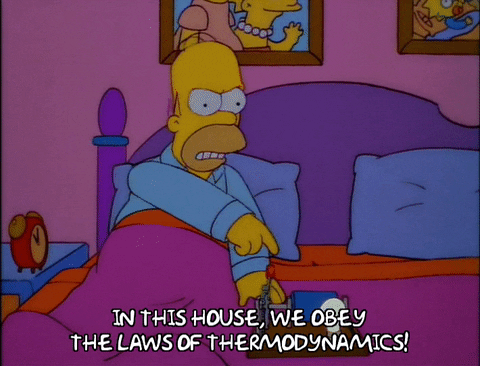
    Homer: In this house, we obey the laws of thermodynamics!
    It’s not just a good idea, it’s the law.

    In contrast, Dev actually increases the level of entropy. Every new release, be it as small as a one-line fix or finding that errant semicolon, is a change that has to be made, reducing the order that Ops fights so hard to maintain. Dev is entropogenic, embracing change as a positive force.

    The interaction between Dev and Ops is analogous to the second law of thermodynamics: Entropy can only increase over time, unless energy is introduced to the system from outside. In other words, unmanaged change will eventually cause something to break, unless people put in continuous effort to prevent those breaks.

    Thermodynamics: Lots of Heat, not Much Light

    These conflicting goals, taken to extremes, can get unhealthy, with Ops actively fighting change or Dev going around Ops to increase their velocity of change. Left unchecked, this tension can turn into a vicious cycle, as frustration with the “Department of No” drives developers into unmanaged “shadow IT.”

    The good news is that the analogy with hard laws of physics is not perfect. The process of increasing entropy is not irreversible, and does not require constant inputs of energy to prevent. New agile approaches to IT Ops are emerging that are light and flexible, taking their structure from that tension. In the physical world, this is called “tensegrity,” and was originally formulated by Buckminster Fuller, one of those annoying polymaths who seem to make breakthroughs in every field they touch.

    Tensegrity structure
    Tensegrity structure

    IT Ops needs its own equivalent to tensegrity, a flexible, holistic structure that is able to embrace change while maintaining its shape. Structures that try to resist change through rigidity are brittle and ultimately fragile.

    Today, this flexible strength is enabled by AIOps, a term coined by Gartner to describe a new way of operating IT, based on augmenting human skills with automated analysis enabled by modern algorithmic and machine-learning approaches.

    Complexity Breeds Complexity

    Modern IT is too complex for any single person or even team to keep track of, instead requiring multiple specializations. In turn, each of these functions requires its own specific support tools that enable that particular role. Beyond a certain point, it becomes very difficult to combine these partial views to gain a holistic understanding of what is actually happening in the environment.

    Because of the scale of modern IT environments and the sheer rate of change that businesses require, old-style rules-based “Managers of Managers” can no longer keep up, requiring more effort to build and maintain their worth. Especially as infrastructure becomes more and more self-modifying in response to changing conditions and demand, IT Operations needs to accelerate just to keep up.

    AIOps brings developing issues to the attention of sysadmins before they become visible to customers and end users, and gives them the tools to collaborate effectively between different teams and specialist roles to avoid outages or restore service quickly and efficiently. In this world, automation is used to augment the capabilities of the human operators to make them more effective, letting people concentrate on adding value, not just fighting fires.

    This is how Ops can get out of the business of fighting Dev, and instead become a supportive partner. AIOps can catch issues that are affecting services and flag them to the right people early on, including the DevOps engineers that are responsible for production support.

    For developers, one of the fears around DevOps is that in “picking up the pager,” they are opening themselves up to a constant stream of irrelevant alerts. Old Ops hands nod wryly at this, or maybe try to share their personal approach to filtering the noise. Instead, AIOps ensures that only valid, actionable alerts get as far as being shown to a human being and taking up their valuable time.

    Eyes on the Prize

    It’s not all roses. As the AIOps market begins to mature, there is a certain amount of “algorithm-washing” going on, with more and more vendors trying to claim that either their legacy tool was AIOps all along, or that their one-trick pony is actually a whole three-ring circus. What gets lost in the excitement is what all of those algorithms are actually supposed to achieve.

    Me too!
    Me too!

    In considering a shift toward AIOps, the goal should not be simply to build a better mouse trap, meaning a smarter filter for monitoring events. The success of the project can be measured not so much in the mathematical results of the algorithms, but in the smoother exchange between the human users. This easier collaboration is especially important across team boundaries, whether these be different specialist units within the Ops function or developers and software engineers who need to work with Ops to understand the performance of their code in production.

    The benefit of transforming operations this way—moving from sequential, waterfall Ops to abile, collaborative Ops—is to turn DevOps-enabled teams into a sort of perpetual-motion machine, able to continue operating without requiring constant massive inputs of energy from outside the system. Modern applications and the complex infrastructures that support them cannot be managed with the sorts of rigid, cobbled-together, industrial approaches that were appropriate in the mainframe days. AIOps is the agile, flexible approach that can not only accomodate that complexity, but thrive on it.

    — Dominic Wellington

  • From Waterfall Incident Management to Collaborative IT Operations

    From Waterfall Incident Management to Collaborative IT Operations

    What can Ops learn from Dev in the transition from sequential, reactive IT support to real-time DevOps?

    One of the signature ideas of DevOps is right there in the name: the blurring of the boundary between the historically separate worlds of Development and Operations.

    On the face of it, this seems like a great idea. Developers have always grumbled about how Operations is preventing them from deploying as rapidly or as frequently as they would like. Meanwhile, Operations people have harbored a dark suspicion that developers might code with more attention if they were the ones getting paged at 3 a.m.

    Another of the great things about DevOps is that it is pretty easy to adopt in one area or project without needing to get the entire company onboard before you can get started. This means that you can quickly produce some interesting results in terms of accelerated development times and release frequencies, faster resolution of problems and more time spent innovating instead of firefighting.

    Armed with these results, DevOps evangelists spread through the organization, telling their story and recruiting other departments and teams to join them in the bright future.

    This is Where the Problems Start

    Complex enterprise IT environments are, well, complex. Different teams have adopted different tools and methodologies to do their jobs, and are justly resistant to throwing out something that works for them. Specialists in different areas require their own specialist tools to be able to do their jobs. Because of this, when an incident occurs, all of that agility and collaboration that DevOps brings goes out of the window in favor of something that looks much more like a classic “waterfall” approach:

    • When an event is received, it is routed to one particular team
    • The event is placed in a queue
    • Eventually, someone from the relevant team takes a look at the event and makes a determination of whether it falls in their area or not
    • If it’s in their area, they begin working to resolve the issue within their team
    • If it’s not (believed to be) in their area, they reassign it, either back to the front-line team, or to whichever team they believe to be responsible (often, this is the network team)
    • Repeat until either someone takes ownership and fixes the issue, or it becomes a Major Incident and everyone gets paged at 3 a.m.

    Just to complicate matters, there may be multiple instances of this process going on at any one time, as two or more different teams grapple with what eventually turn out to be different aspects of the same problem.

    Why Does This Happen?

    In health care, there is only so much that can be done by way of prevention. There is always the need to react to patient’s issues, starting from their symptoms. In the same way, the starting point for Operations is monitoring—gathering the symptoms of the IT infrastructure to be able to return it to health as quickly as possible.

    To understand problems with the Ops part of DevOps, we needed to start at the beginning, with those symptoms. We wanted to do this the scientific way, so we polled attendees of Velocity and Monitorama to understand their top monitoring challenges.

    The interesting fact was that across both populations, the main challenge listed by attendees was “alert noise/fatigue/volume.” Simply put, Operators were drowning in alerts to the point that they had completely lost the ability to understand what was actually important, let alone an overall picture of how those alerts related to the service that IT was supposed to deliver.

    This is another parallel between IT and health care, where alert fatigue has long been a concern, and with potentially far more serious consequences than in IT.

    A big part of the cause of the alert fatigue on the IT side is the proliferation of specialist monitoring tools. In the poll, 66.67 percent of people we surveyed have five to 10 monitoring tools in place, and yet 61.90 percent of them are still struggling with that problem of alert noise/fatigue/volume.

    To be clear, those different tools are each very important. Trying to monitor the network with an APM tool is probably not going to go well for you. They only become a problem when it becomes too difficult to build up an overall picture of what is going on, and sharing that between different people to solve problems faster.

    So What Can Be Done?

    Dedicated Operations organizations have long worked to assemble tools and techniques that can give them a complete view of the environment that they are supporting, and of the services that run in it. The accelerated pace of release that comes with DevOps is causing the old models to break down, but fortunately, it also carries in itself the seeds of a new approach to the problem.

    As development moved from the sequential waterfall model to a more rapid, collaborative, and agile approach, operations teams can learn from that transition to come up with a more agile approach to IT Ops.

    What would this look like? The first thing to do is to get rid of the blame-storming and buck-passing: “It’s the network!” “No, it’s the database!” I don’t know about you, but personally, I’ve been in enough of those meetings to last me for the rest of my life, thank you very much.

    Let’s All Go Fishing in the Data Lake

    Instead, a common perspective is needed, so that everyone can quickly agree on what is going on and what needs to be done.

    This does not mean throwing out all of those specialist monitoring tools! They are there for a reason. Rather, gather all of those symptoms in one place where the whole team can collaborate to make sense of them more easily. These days, it should be easy to get information in and out of the various components of your toolchain (and if it’s not, that’s a glaring warning sign that maybe it’s time to migrate off that particular tool).

    This will, of course, produce a huge pile of data, so it’s not sufficient to stop here with the creation of a “data lake.” Things disappear into lakes and are never seen again—in which case, why did you bother gathering them in the first place?

    What you need is a way to make sense of what is going on in the lake, and show that to the right human operators. In the same way that developers resent sitting around waiting for the Change Advisory Board to meet, operations people get frustrated and bored just staring at a screen waiting for something to happen. If instead you can use automatic techniques to assemble all the related symptoms of a single issue together in one place, that will give you a good starting point to resolve that underlying issue quickly.

    Brainstorming, not Blamestorming

    This is where the collaboration comes in. Again, people are doing this already, but they are doing it in a disconnected way. The tools have evolved, from email and IRC, to Slack and Google Hangouts, or even (heaven help us all) WhatsApp. What has not evolved is the usage model; it’s still ad-hoc and reactive, and requires lots of copying and pasting.

    Operations people can learn from what their developer colleagues have built or adopted. Kanban boards are a great technique for tracking open issues and who is working on them. ChatOps is a fantastic way to integrate human-to-human communication with human-to-machine communication. Integrated collaboration tools capture knowledge that otherwise is stuck in people’s heads or inboxes, unavailable to their colleagues.

    I’m an Ops guy at heart, but I can recognize a good idea when I see it. Our Dev colleagues have come up with quite a few that we could stand to adopt in Ops. Let’s learn from what they already know to work, instead of trying to reinvent the wheel.

    — Dominic Wellington

  • Developers Cite Startling Lack of Digital Leadership

    Developers Cite Startling Lack of Digital Leadership

    Despite app backlogs, developers say their efforts are underfunded and undertrained, and lack a priority for security

    We’ve long written about the challenges enterprises face when developing the apps they need, digging out of app backlogs and technical debt, and the overall importance of running a productive development pipeline. And, how to keep up, enterprise’s are seeing more and more citizen developers rising to fill in try to close the lag between what software apps they need built.

    Which is why it was disheartening to read in a recently published report, “Investment in Enterprise Developers is the Best Risk Management System,” based on a survey of more than 100 developers by the Application Developers Alliance, that 40 percent of respondents have experienced failed development efforts from lack of funding, and a third are concerned that current projects could be pulled for budgetary reasons. Also, despite survey after survey of executives citing security as a “top priority,” only 45 percent of enterprise developers surveyed believe that their organization sets a “high” priority for security.

    Not surprisingly, according to the survey, four out of five enterprise developers surveyed work on Windows and/or OS X, and 24 percent work on Linux. Yet only 20 percent work on mobile platforms exclusively. And, interestingly, two-thirds of enterprise developers develop their apps exclusively HTML5, hybrid or native, with native being the most common. And, not surprisingly today, cloud is the most common way to deploy apps during development, test or production.

    Unfortunately, many developers report underfunding in technology, processes and training. A third report outdated technology and processes in their organizations—more than half (51 percent) of those in organizations with more than 100 employees.

    Leadership Falling Short in Many Areas

    When it comes to cultivating processes and technology guidance, many enterprises also fall short. Only 37 percent of those surveyed said their organization has a Center of Excellence. Not surprisingly, the larger enterprises were more likely to have a Center of Excellence; however the lack of such centers is more common in North America and Europe, Middle East and Africa. Most every organization surveyed in Asia, however, has a dedicated Center of Excellence. Additionally, a surprisingly low 29 percent of of developers surveyed reported that they are required to attend training, certification programs or other continuing education.

    That’s stunning, considering that increasingly businesses are driven by their digital efforts. There’s no shortage of surveys citing this. In a recent study commissioned by CA Technologies, “The Battle for Competitive Advantage in the App Economy,” 43 percent of survey respondents said that becoming software-driven is central to being competitive today, and nearly 80 percent said that would be true in three years. Broadly, to be competitive in the years ahead, enterprises are going to have to be exceptional software companies in addition to their core current products and services. Yet survey after survey finds that enterprises are falling behind in their app development goals and are having a challenging time finding the talent they need.

    Additionally, the Application Developers Alliance survey found that only 50 percent of enterprises discuss the capabilities and skills they need to succeed, while only 26 percent integrate such competencies in their evaluation process. And, just as when it came to establishing Centers of Excellence, Asian companies stood out, with 78 percent of Asian developers saying necessary skill development is discussed.

    Centers of Excellence, the Application Developers Alliance survey found, also are excellent indicators of whether an enterprise is committed to building secure software. While 64 percent of developers believe they’re “adequately” trained to build secure software, more than 70 percent at organizations with a Center of Excellence contend that security is a high priority where they work. If they work in an organization without a Center of Excellence, that number drops to 28 percent, and 17 percent rank security as a low priority in such enterprises.

    Clearly, if enterprises expect to compete globally in the years ahead they’re going to need to step up their priorities when it comes to budgeting app development, cultivating the skills they need and building the internal organization necessary to succeed as a digital enterprise.

  • “Show Me The Money!” – Delivering DevOps Value

    “Show Me The Money!” – Delivering DevOps Value

    HM Heath Solutions delivers new business applications in the healthcare industry to 35 million customers.  In order to embark on their DevOps journey to improve software delivery, Valerie Scott, their Manager of Shared Services Division, had to show senior management an ROI on a successful project, before they would invest fully. On June 2, Val Scott along with Rick Slade of IBM joined Alan Shimel of devopsy.kinsta.cloud in a webcast to discuss this interesting client case study.  During their discussion, they illustrated in vivid detail how HM Health Solutions showed success in DevOps to their senior executives, for them to buy in and sponsor the project.

    Val and Rick’s webinar parallels many similar discussions I’ve had with senior executives.  To net it out, the bottom line is, as it was so clearly and unequivocally articulated in this amusing clip from the movie Jerry Maguire: “Show Me The Money!”

    cuba gooding jr show me the money jerry maguire tom cruise show me the money jerry maguire
    When I meet with senior LOB, Finance or IT executives — they shout a similar refrain:

    “All I want to do is buy a business outcome.  I want to invest in an IT project, and have it pay back.  Unfortunately for many application development (or other types of enterprise IT) projects, that pay back is illusory, and ROI difficult to measure.”

    — Jane or John Executive, representing nearly every IT executive or CFO I have ever met

    Unfortunately, many struggle to quantify, monetize and demonstrate the financial return on investing in IT projects.  Yet as described in this blog, it is the primary responsibility and outcome of management; leading the economic performance of their department or unit.  Show me the money!  Fortunately, many clients experience positive returns, both operationally and economically.  Ten (with links to more) client case studies with returns are highlighted in this blog, and summarized on this page.

    As you undoubtedly have experienced yourself, senior executives respond to clear business value and benefits articulated as financial returns, as ROI.  But how do you do that for DevOps, a set of technical practices and associated culture change?  As Val and Rick described during their informative webcast, comparing productivity, time-to-market, speed of delivery, and quality, both before and after a DevOps pilot, are crucial.  These operational metrics will be improved by adopting DevOps.  However, to win the hearts and minds of senior executives, you have to monetize the results, in other words – show them the money!  Technical techniques and practices such as those Val and Rick described to Alan, shifting left, test driven development, and automating application build, deployment, and test are absolutely necessary, but they are insufficient to win the argument with senior executives.  The gains they produce are necessary, and impressive.  The operational results have been stellar thus far at HM Health Solutions, per Val:

    • a 67% reduction in resource demands on the release team & process,
    • a 75% reduction in relative hours to repair defects per environment,
    • an 82% reduction in application deployment time.

    Yet as impressive as these operational results are, they are insufficient.  As Val described, arguments about business value, technical value, or improvements to developer or operations staff productivity, alone did not persuade the management.  The magic word is an economic and financial one: “investment”.  Making a strategic investment to improve delivery speed and quality of business applications was the key to winning the hearts and minds of the senior executives.

    In addition to the technical practices described above, Alan asked Val to describe the tools HM Health Solutions adopted.  A continuous delivery solution with application release automation software from IBM UrbanCode was implemented, including application build, deploy, and release.

    As a way of summarizing the webcast for the audience, Alan asked Rick and Val for their two key takeaways; the two most important messages and things to remember.  Rick’s:

    1. Knowing which metrics are critical to your organization.  There are many benefits to adopting DevOps, and many potential hard numbers that are straightforward to capture and measure.  Deciding which metrics have the most impact and are most persuasive to your stakeholders is critical to making the case to invest in DevOps.
    2. Implementing tools and automation: automated testing, and linking that to build and deployment processes and automation.

    Val’s:  Rick’s two takeaways of course!   And one more…

    1. DevOps is new in the industry, and is not yet well understood or common practice in enterprise IT or among its leaders.  Understand your audience, and become good at explaining it in straightforward and clear business and financial terms to senior executives.  Especially persuasive are other client proof points, and the results of pilots in your own enterprise IT environment.  Make sure pilot results show that the solution works and delivers timely business value, and that the related facts and metrics clearly quantify the results.

    Read this blog to know more and Check out other customer proof points/ case studies

    This was a very informative, fast paced, and information rich webcast.  I hope that you find the replay useful in continuing your DevOps adoption journey.

    If you’d like to explore more about management responsibilities and know-how for establishing an ROI for DevOps and app release & deployment automation, see this ROI web page, and read this ROI blog for additional resources on method, approach, making the case, and calculating the ROI.  And please don’t hesitate to reach out to me on twitter: @paspung.

    I look forward to hearing your success stories in making the ROI case to senior executives, and delivering DevOps value to your organization!

    peter signature, small

    Peter Spung, DevOps Deploy and UrbanCode Integration Executuve, IBM Cloud, @paspung

  • Chasing consistency across the wild seas of enterprise IT

    Chasing consistency across the wild seas of enterprise IT

    Despite seemingly never-ending arguments to the contrary, DevOps has firmly arrived in the enterprise. No, the question is no longer if DevOps is appropriate for the enterprise anymore – the more appropriate question is to what extent has DevOps made its impact on the typical enterprise.

    But the enterprise move to DevOps isn’t a straight line. One of the steepest, and also most common, challenges for enterprises moving toward DevOps is how diverse the IT environments in large organizations tend to be. Yet, for continuous integration, continuous delivery, and DevOps to thrive – architects, developers, test, QA and other teams all need to be operating on uniform systems – but in most enterprises that not the case.

    Yet, as the 2014 State of DevOps Report from Puppet Labs found, DevOps enterprise adoption is increasing, and that DevOps adoption was accelerating, and that high-performing IT organizations that embrace DevOps are typically more agile and reliable, deploying code 30 times more frequently and with half as many failures as non-DevOps enterprises.

    However, it’s this enterprise IT inconsistency that is one of the main reasons why DevOps gets entrenched in certain departments within large enterprises, but is then slow to expand outward throughout the rest of the organization.

    “This is a huge problem in larger enterprises, especially as DevOps practices grow beyond just isolated departmental applications. Architects have one system for prototyping; developers have a different system to code on; test and QA have their own unique ‘standard’ systems; while operations have untouchable systems for production,” Andi Mann, a VP at CA Technologies wrote in this post, Making DevOps Work in Complex Enterprise Environments, for devopsy.kinsta.cloud.

    In this roundtable, DevOps Summit Power Panel | Is DevOps Changing Enterprise IT?, both JP Morgenthal, director of cloud computing practice at Perficient, Inc., and Gordon Haff, cloud evangelist at Red Hat agree that DevOps is still in its early days and that enterprise DevOps adoption will be relatively slow, as enterprises build more consistency in their IT environments. “I think enterprise needs to mold DevOps to its needs and understand the differentiation for how to deploy that in a large multi-faceted IT department,” says Morgenthal.

    This is why DevOps in the enterprise doesn’t typically move quickly. There’s so much variance between department and team languages they use, as well as methodologies, tools, and procedures they have in place that all need to be normalized. This inconsistency across the enterprise is the enemy of broad, enterprise-wide DevOps success.

    Justin Arbuckle, former chief architect at GE Capital (currently, vice president of Europe and chief enterprise architect for Chef) created an adept analogy for the enterprise journey to DevOps and consistency with Herman Melville’s classic work Moby Dick. “The whale isn’t DevOps. In my opinion, every organization has a whale called consistency. Consistency of environments, whether it be the consistency of the images running on your service. Whether it be the consistency of the IT environments, consistency of the processes, or whatever the thing happens to be: consistency is at the center of many of the organizational challenges that we have today. So driving that consistency message, in our experience, has been absolutely critical to delivering the message as to why we need to go to sea,” he says.

    That doesn’t mean there aren’t many places where DevOps can succeed, and succeed swiftly. As Arbuckle points out, regardless of the size of the enterprise you will find there will be shared problems among groups, and in shared problems there is the shared motivation to solve these problems. “It’s about getting a bunch of people who want to work on a common set of problems and together you start showing results,” says Arbuckle.

    For instance, most every large team has security, compliance, QA and other challenges. What GE Capital did, to help solve them better, was to provide regular weekly demonstrations where everyone in the organization was invited to watch and learn how applications and systems were developed being developed. And dozens of employees from throughout the organization have attended some of the larger demos, with one hitting 80 attendees, Arbuckle says.

    “We’ve evolved this process in GE Capital called “compliance by demonstration.” Compliance by demonstration means essentially instead of waiting for some form to be filled out, and we then have to spend three months explaining to people why the answers we put down are correct, we involve everyone from the beginning. And you know what happened? The amount of support that we’re getting from that is now amazing,” says Arbuckle. “They [different teams] want to do the right thing. They don’t want to get in the way of business value. So any way that we can help them see what we’re doing is awesome,” he says.

    The key to finding those shared set of problems, teams need solved is to get everyone involved in the process early. “That’s when it becomes real. What is real is not DevOps or using a new process, rather it’s a whole bunch of people around the organization saying, “Wow, they’re moving really, really quickly and we had an interesting discussion about data portability between two geographies and they [these other teams] have a really good plan for that.”

    When it comes to moving a large enterprise to DevOps, as David Mortman, contributing analyst at Securosis puts it, there’s no right or wrong. “If your enterprise is collaborating and the teams are working together on how to improve processes, or automate what can be automated, share lessons learned and just collaborate more effectively then you are essentially practicing DevOps. And there are many ways to get down this path,” says Mortman.

    That increased level of collaboration and sharing is one of the great ways that IT, dev and ops can stop being seen as part of the enterprise bottleneck, and “start being part of the story where other parts of the organization begin to see how they can change and become better,” says Arbuckle.

    The whale isn’t DevOps. The whale is the elusive goal of getting enterprises to do things consistently, and through that consistency, add value more quickly back into the enterprise – and while that storyline may never become an American classic – it’s certainly a modern narrative worth chasing.