Tag: Enterprise IT Operations

  • Are ERP-Centric Enterprises Being Left Behind?

    Are ERP-Centric Enterprises Being Left Behind?

    Many large enterprise companies are rife with departments that depend on customized ERP software applications. These systems accommodate vital business tasks ranging from inventory management to ordering capabilities to accounting programs to CRM platforms—all of which were custom-built to fit the enterprise’s specific needs and meet the KPIs of each unique organization. These applications tend to sustain grades, patches and reworks, sometimes resulting in multiple redesigns over the course of decades, and these often are not properly documented. To make matters worse, these ERP software systems also tend to be written in outdated programming languages such as ABAP for SAP and PL/SQL for Oracle, making them a challenge to update.

    For example, 91% of respondents in a recent ASUG survey of 110 SAP companies said they use custom code, and 41% of those applications were created at least six years ago. The majority of these companies said that the existence of these custom code environments has become a hindrance to digital transformation and is holding back innovation.

    These conditions create the bloated and overly complex legacy environments that are now commonplace in the enterprise market. Widespread, customized core business systems have made digital transformation particularly daunting for enterprise companies. They require significant developer resources, excessive time commitment and ample expense to strip down and redesign these custom systems for the cloud. 

    A Lack of Developers—and of Developer Interest

    U.S. Department of Labor statistics from December 2020 indicated that there will be a shortage of 40 million skilled workers worldwide, amplifying these issues further. That figure is predicted to grow to 85.2 million by 2030. What’s more, new developers entering the marketplace gravitate to more contemporary programming languages such as JavaScript and Python, as opposed to wanting to revamp archaic code used in most ERP solutions, such as ABAP.

    For this reason, large enterprise companies in a range of verticals are lagging behind when it comes to upgrading mission-critical software applications to the cloud or to a more modern architecture. These organizations are well aware they stand to gain significant productivity benefits from digitally transforming their systems so that, for example, inventory data can be accessed via a mobile device or shared from anywhere on a cloud-based platform. Yet these large organizations are stalled in their efforts to modernize. Some companies have gone as far as to scrap their current systems and start reprogramming their software applications from scratch—a hugely expensive, lengthy and laborious endeavor that’s also full of risk. 

    Leveraging Low-Code to Simplify Enterprise IT Environments

    One method that has shown progress in unraveling these overwrought environments is to apply automation through low-code integration. Ideally, an effective low-code development solution will automatically convert existing business processes to modern, cloud-native applications, allowing the organization to maintain the business logic it has built into those applications over the years, while drastically reducing the time commitment, costs and potential disruption associated with traditional, long-form integration. In SAP environments, for example, using a low-code rapid application development solution can separate the application layer from the core SAP system, automating a large portion of the migration while preserving a “clean” SAP core.

    With many organizations under pressure to keep budgets under control in what continues to be an uncertain economy, these large-scale companies are looking for ways to modernize their operations on a more controlled schedule. When enterprises use low-code solutions—and furthermore, don’t have to search for developers of these more archaic languages—they’re free to approach digital transformation in a far more incremental and cost-effective way.

    For instance, the 12 million users of SAP’s solutions are being compelled to upgrade to the modernized version of its product, S/4HANA. Yet the American SAP User Group (ASUG) research shows that only 33% of these organizations have taken on the challenge so far despite the looming end-of-life of the current prevalent version. This is because lacking a low-code development solution, companies are being pressured to convert and rebuild all their business processes in one fell swoop. Few organizations have the resources to absorb such a drastic and risk-prone undertaking. 

    A rapid application development program acts as a bridge for companies that are looking to modernize their businesses, allowing them to upgrade their applications incrementally, according to their own schedules. Low-code can be a catalyst for technical debt-ridden enterprises, allowing them to simplify complicated legacy environments and get down to the business of innovating their systems.

  • 4 Steps to More Agile Operations

    4 Steps to More Agile Operations

    After over a year of business disruptions, modern enterprises have realized that speed and agility are the only way forward. In fact, according to Gartner’s Top Strategic Technology Trends for 2021 eBook, “Organizations that don’t focus on efficiency, efficacy, and business agility will be left behind.”

    In order to stay future-ready, organizations across all industries are moving to adopt an operating model that is agile and competitive.

    Roadblocks on the Path to Agility

    Driving operational agility is easier said than done. Enterprises face a variety of challenges when it comes to streamlining their end-to-end processes, including a lack of visibility into business gaps, monolithic legacy systems, siloed departments and evolving regulatory requirements.

    Enterprises have no choice but to overcome these hurdles and streamline their operations or else they will fall behind their competition.

    Now more than ever, business and IT leaders must recognize the importance of investing in business agility when it comes to their bottom line. Especially since, as the Gartner report said, “agile software development practices are fueling software innovations globally. Agile techniques create more value for the business, and faster, than do traditional methods.”

    The real question is: how can enterprises seamlessly shift to a more agile operating model?

    Agile Operating Model: The Four-Step Approach

    Understand Business Needs

    An effective agile operating model is rooted in a comprehensive and deep understanding of an enterprise’s needs and gaps. This goes beyond identifying business goals, requiring organizations to analyze the nuances of their operations, the challenges impacting day-to-day functions and all their expected outcomes.

    Based on this holistic picture, business leaders can begin to recognize which technologies and strategies to implement and where to generate the most return on investment (ROI).

    Connect, Collaborate, Contextualize!

    The bedrock of agility is a connected enterprise, and so bridging operational and departmental silos is of the utmost importance. Every relevant stakeholder across the organization must have complete visibility as well as access to collaborative tools such as live dashboards, remote and mobile functionalities and personalized user interfaces.

    By leveraging modern technologies to enable anytime, anywhere collaboration, enterprises can make intelligent decisions and changes without compromising on speed or quality.

    Focus on Generating Value

    Of course, the overarching goal of implementing an agile operating model is to generate business value; however, to ensure that expected outcomes are met, enterprises must clearly define—and periodically redefine—how value and ROI are assessed.

    By leveraging process analytics and monitoring tools, business leaders can maintain complete visibility into their operations, quickly readjusting their approach whenever necessary.

    Empower Employees with Modern IT Infrastructure

    Organizations can drive continuous improvement and increase productivity by embracing modern technologies and low-code development capability.

    To respond to the evolving business needs, enterprises can leverage new-age technologies, including cloud, robotic process automation, artificial intelligence and machine learning while maintaining a well-integrated IT infrastructure.

    Furthermore, with low-code, enterprises can empower their employees by helping them easily develop applications per business requirements, with less dependence on IT.

    Agility: The Need of the Hour

    There is no slowing down for modern enterprises. To successfully navigate growing competition, heightened customer expectations, and a continuously evolving market, organizations must prioritize business agility.  In fact, “with the speed of change expected to continue, the need has never been greater for an operating model that can keep up.”

    And so, for business and IT leaders with their eyes on the future, the time is now to take steps toward establishing a more agile enterprise.

  • Documenting: Don’t Build Your Replacement’s Nightmare

    Documenting: Don’t Build Your Replacement’s Nightmare

    Want to reduce headaches tomorrow? Document everything today

    About once a year I feel the need to remind you that you are creating technical debt. DevOps is good stuff, and most shops got over the “whatever a given project team decides” multiplication of services pretty quickly, but every line of DevOps code you write is creating technical debt.

    There is no way around this fact. You are writing code (scripts, if you prefer) and developing configs that make assumptions. Those assumptions will change—products will get incompatible upgrades, vendors will go under, libraries will become outdated … the list goes on.

    We have a long history with technical debt. DevOps partially grew out of the need to spend less time maintaining and more time releasing features, and yet we’re re-creating technical debt; in some cases at a much larger scale. It is unavoidable but can be managed. Keep a reference list of assumptions—“This app assumes environment contains X,” or “This app supports Cisco Network APIs version X.Y”—so you know where to look when things inevitably go wrong. The list conveniently doubles as a handy reference to what needs updating when you find out your middleware vendor is going under or that MySQL is out and MariaDB is in.

    The more cutting-edge tools you use, the more likely that you are baking future problems into your environment. This is not advice to avoid cutting-edge; it is advice to recognize reality and keep closer track as you move new things into your environment that might be half-baked or whose market is destined for consolidation.

    Our IT environment has become super-complex. DevOps helps us manage that complexity but discourages adequate documentation. We’ve all heard, “It’s self-documenting” (no, it’s not) or “There is basic documentation” (basic almost always means, “We scratched some notes when it was first set up”… and haven’t touched them since). Don’t do that. Make sure that the new guy after all of you have left can figure out what is going on in this highly complex environment. It is not up to new people to be super-learners with mind-reading skills; it is up to implementors to make certain new people can figure out what is going on without wasting 5,000 hours pawing through scripts.

    It does not take much time to document dependencies. It doesn’t take much more to document relationships. Future you will be grateful when they walk in and need to come up to speed in a short amount of time. Because it doesn’t matter how automated it is when the automation breaks—it matters how quickly staff on hand can fix it and get things going smoothly again.

    You’re keeping the world running. Take a second and make sure the next person can, too. And keep rocking it.

  • Why ITOps Is Moving to the Cloud

    Why ITOps Is Moving to the Cloud

    There’s been a lot of movement in the IT operations management (ITOM) business lately, from the acquisition of SignalFx by Splunk to the PagerDuty IPO, and all signs point to a Datadog IPO in the future. What’s with all this consolidation? I believe we’re seeing the rise of a future-state of ITOM; that is to say, it’s the rise of SaaS-based ITOM. And it’s easy to see why.

    In my previous consulting career as lead enterprise systems architect, our team had an impeccable record in designing and implementing well-architected hybrid infrastructure solutions. We maintained an immaculate record and near-flawless customer satisfaction record. By project sign-off, our job was always done. And yet, returning to the same solutions six months later told a different story entirely.

    Well-architected solutions are similar to human bodies: They are perfect when they’re born but need constant care and feeding. These same solutions that satisfied SLAs, exceeded expectations and transformed organizational efficiency can easily degenerate, and just like our bodies have their nervous systems to monitor, brains to send alerts and tissue to self-heal, well-architected systems need operational maintenance to keep them humming.

    The traditional approach for solving this eternal need was and still is to design and implement well-architected IT operation management (ITOM) solutions, around a well-architected infrastructure. And yet, this is a self-fulfilling paradox because the ITOM solution itself needs the same care and feeding.

    There’s a Problem On-Premise

    ITOM is a broad term encompassing application and operating system (OS) performance, alerts, log management, notification, asset configuration, incident management and more. It typically involves the purchase of a suite of on-premise point tools addressing each need, and then to develop an internal framework to help those tools interoperate in a meaningful way. While that is possible conceptually, the facts on the ground reflect a very different reality:

    • Multi-vendor tools are often not designed to work together.
    • Creating an internal logical framework that orchestrates various teams and technologies can be very complex in large enterprises.
    • It’s near-impossible to create technical integrations flexible enough to adhere to inevitable organizational and technological changes that will affect this logical framework.
    • Predicting cost-of-ownership is nearly impossible since each tool is controlled by a different vendor, and the internal integration effort is often unknown.
    • Predicting the cost of the manpower required is also very difficult, as each tool requires its own set of specialists, in addition to integration specialists to make it all work together.
    • Upkeep is often overwhelming, as vendors offload software patches, upgrades and on-premises hardware costs to the customer.

    In the face of all these challenges, the end result is often unrealized value, overwhelmed operational teams, loss of service and inability to accommodate new technologies resulting business service disruptions.

    Why Cloud? Why Now?

    It’s historically been near-impossible to build a traditional ITOM platform on-premise. Vendors typically sell a collection of white-labeled tools cobbled together by acquisitions, and this is far from a platform. The complexity and the rate of technological change make it difficult to provide consistent quality and value across the various product lines. This puts the ITOps team squarely in the middle of a pickle: How can they ride the wave of a changing environment without relying on static tool suites?

    The Future is Flexible

    Enterprise ITOps has been stretched now more than ever. There is a serious skills gap, shortage in IT workforce and ever-increasing technical complexity. Time and resources are precious, and Enterprise ITOps need simplicity and predictability along with flexibility and control. Enter SaaS ITOM. By moving the ITOM function to a SaaS orientation, the responsibilities, workloads and daily tasks can transform according to the needs of the organization:

    Keeping Up with the Business

    SaaS ITOM can keep up with technological change, and keep pace with cloud, DevOps, artificial intelligence and more. In the world of SaaS, change is an accepted constant and not an inconvenience. What’s more, SaaS ITOM is infinitely more consumable than the tool suites of legacy past, and that reduces the learning curves associated with running ITOps.

    Keeping Up with Industry Needs

    A SaaS ITOM platform will be able to deliver a framework that’s both flexible and governed and can accommodate technical and organizational complexities. This agility is a feature of modern SaaS. SaaS ITOM can also integrate features running on a single code base supported completely by the SaaS vendor, who will absorb maintenance and upgrade cycles, freeing considerable and valuable time back to the operator. All of this results in a more predictable total cost of ownership, improved service quality and more value to the business user.

    It’s not news the world of IT is moving to the cloud. It is news, however, that cloud can offer such transformational benefits in ways we’ve never seen before.

    — Wael Altaqi

  • Measure What’s Important: DevFinOps

    Measure What’s Important: DevFinOps

    Lately there seem to have been quite a few DevSomethingOps terms being coined. However, I do think we need one more: DevFinOps.

    Dev-What-Ops?

    One of the biggest problems in IT is working out the cost of IT. Left unchecked, IT will expand to fill whatever budget it is given. This may mean evermore involved business continuity and redundancy, reinventing evermore elaborate wheels, irrational versus buy decisions and so on.

    In fact, the whole idea of cost estimates for IT projects has become something of a joke. Most IT projects are reputed to exceed their budgets.

    There is an entire #NoEstimates movement that rejects the idea that it is even possible to deliver a sensible estimate for a software development project. As is often the case, the basic idea is reasonable:

    it is possible to do small chunks of work incrementally, leading as rapidly as possible to a desired shippable product, and that when you do that there is no need to do much of anything in the way of estimating stories or the project.

    However, the simplistic interpretation that is all over Twitter is that because there is no estimate of the  overall project, there is no estimate at all. That is not the idea! It is simply to break down the overall estimate (which is probably wrong) and instead budget for much smaller chunks of work, which can presumably be estimated more precisely and accurately.

    So What Can We Do?

    Maybe what is required is integration of financial concerns directly into the fabric of IT development operation. We might call this DevFinOps, in line with other extensions of DevOps such as DevSecOps or DevNetOps.

    This is not such a leap; after all, we already integrate costs in areas such as SLA calculation, estimating the TCO of a tool or the ROI of a proposed purchase. However, these are generally calculations that are made after the fact, and may even be retconned to fit external assumptions.

    What I am proposing, though, is to build this information right into the IT metadata and processes to enable us to make better decisions.

    This is not IT Asset Management, although it would build on those data and extend their reach. A particular device or piece of hardware has its purchase price and current amortised value documented in the ITAM database, but the actual value it has at any given time might vary depending on which business function it is currently supporting. This calculation should change over time to reflect the real current value it is delivering to the organization at any given time.

    An idle server has no particular value beyond the intrinsic value of the hardware, back-end support (floor space, network, cooling, etc.), and perhaps any associated licensed software. However, the same server will take on a much higher value to the organization when it is provisioned as part of the infrastructure supporting a major business-critical application.

    Performing actions on these systems would therefore have different potential impacts, and should be treated as costs deducted from a limited budget. Live-patching a business-critical server is an expensive operation, not to be treated lightly. The cost of doing so should be deducted from an operational budget.

    This calculation has the benefit of making it easier to communicate the different impacts of various proposed courses of action outside the IT department. Deciding between cloud and on-premises deployment options, or between different flavors of cloud, can be a fraught process. Technical options and pricing models are rarely easily comparable, and then there are other costs such as compliance (yes, and GDPR) or vendor risk. Quantifying and normalizing these disparate factors would make it that much easier to compare options up front and calculate benefits after the fact.

    Is This Even Possible?

    Google already does something like this in its Site Reliability Engineering (SRE) program, with the notion of an error budget:

    The business or the product must establish what the availability target is for the system. Once you’ve done that, one minus the availability target is what we call the error budget; if it’s 99.99% available, that means that it’s 0.01% unavailable. Now we are allowed to have .01% unavailability and this is a budget. We can spend it on anything we want, as long as we don’t overspend it.

    There is a long and sordid history of attempts to make programming projects comparable and their estimates more reliable. Often this devolves to simply counting lines of code, according to the age-old management syllogism: “We need to measure something; this measurement is easy to gather; let’s measure this!” and of course the Mythical Man-Month.

    Fortunately, there is a way to calculate the complexity, and therefore the potential cost impact, of a piece of code: the Halstead volume. This is a measurement of the complexity of code, described in terms of the number of distinct operators, the number of distinct operands and the total number of operators and operands. While it is not guaranteed to be perfectly accurate in every case, it is at least accurate enough to be comparable, and therefore can be used to estimate the risk of a change, in terms of the relative Halstead volumes of the code to be changed and the patch to be applied.

    But What About the Squishy Meatbags?

    Connecting the human costs would also enable other metrics to be gathered. It has been historically difficult to differentiate between what is urgent and what is important, and how to prioritize each. If we connect salary data (including overtime) to changes, it becomes much easier to make the call on when enough time has been wasted on a problem and the cost-effective solution is to start from scratch.

    It sounds like a lot of work to gather all of this information, but these data already exist; they’re just not connected up in one place. When the business wants to launch a new service, there are (usually) pretty rigorous calculations behind that decision. The expectation is to acquire or retain a certain number of customers who have a certain average lifetime value and break-even points and other criteria are all mapped out ahead of time. For whatever reason, though, these islands of information are rarely if ever connected up.

    This, incidentally, is just one reason why it can be worthwhile to work with reputable and experienced vendors. I have written before about what this process looks like. The good vendor sales teams will help to unearth this sort of information—but even in the most positive sales processes, the kimono is rarely fully open. There is far more information inside the organization that could be enormously useful if only it were available in the right place and at the right time.

    Longer term, this would mean that business cases and ROI calculations would finally be concrete and factual, rather than extended performance pieces in the medium of spreadsheets. On that note, there is a wonderful little book, titled “How to Lie with Statistics,” which is even available as a free PDF. It’s one of those books that is fun to read because you start spotting the things it was talking about simply everywhere.

    If you wanted to be maximally Zeitgeist-compliant, you could probably verify all of this with blockchain, although I worry that the transaction costs (including thermal costs!) would be prohibitive. The good news, though, is that you could use this DevFinOps methodology to work that out too …

    All That Effort, for What?

    Bottom line, the goal is to be able to calculate (at least within reasonable limits) how much IT is costing today, and what the impact of any proposed changes would be—and crucially, to do so in real time.

    The goal is agile cost estimates. There is a reason I chose the DevFinOps coinage. The way we do cost estimates today is very “waterfall“: large teams have extended arguments over spreadsheets, and the process is so painful and expensive (in person-hours and disruption) that it is only undertaken for the largest changes.

    Agile’s faster release cycles do not align at all well to this process, which is where #NoEstimates is coming from. However, if we start gathering and processing all the cost data in real time, and make it available via a simple API call, it becomes possible to calculate both ends of the cost of a proposed change: the complexity of the code itself, and therefore the probability that it contains bugs, and the infrastructure impact that the deployment will have. This cost can then be compared to the team’s current SRE error budget to determine whether the change can be made automatically or whether it requires signoff as an exception.

    The result looks a lot like ITIL’s notion of a “standard change”, but without the inherent conflict between ITIL’s centralization and SRE’s decentralization. The key is a common accepted measurement of what a standard change actually is, which would otherwise require the ITIL Change Manager to make the determination ahead of time.

    What Does This Look Like in Ops?

    Let’s not forget Ops, either. Proper cost estimates like the ones described above would enable Ops to prioritize alerts correctly and estimate impacts accurately. Two outages with equal technical severity may have very different business impacts. Today, that reconciliation relies on tribal knowledge and systems that are often inaccurate or out of date. Given a central shared repository of data that describes the value of deployed systems, it becomes possible to calculate those impacts much more accurately.

    While we work to get to full DevFinOps, you might want to consider AIOps, which helps gather a contextual view of what is actually going on in IT. Gartner just released a Market Survey for this emerging space. Normally these documents cost $1,295, but you can get a free copy here, courtesy of Moogsoft.

    Dominic Wellington is Chief Evangelist at Moogsoft. He has been involved in IT operations for a number of years, working in fields as diverse as SecOps, cloud computing, and data center automation.

    — Dominic Wellington

  • AIOps: Managing the Second Law of IT Ops

    AIOps: Managing the Second Law of IT Ops

    Or, why IT systems keep breaking

    The tension between the two halves of DevOps is long-standing, going back long before the term was even invented. What underlies the split between Development and Operations is a fundamental difference, like an actual physical law. Let’s explore that analogy together.

    IT Ops is fundamentally a constant fight against entropy, meaning disorder. Sysadmins expend significant energy trying to keep everything up and running, in a process which can sometimes feel like trying to shore up a sandcastle while the tide is coming in. Systems are constantly breaking down; users need changes made that introduce risk; and, as if that wasn’t enough, the whole shebang is constantly under attack from malicious outsiders. It’s no wonder that sysadmins have a reputation for being a bit grumpy!

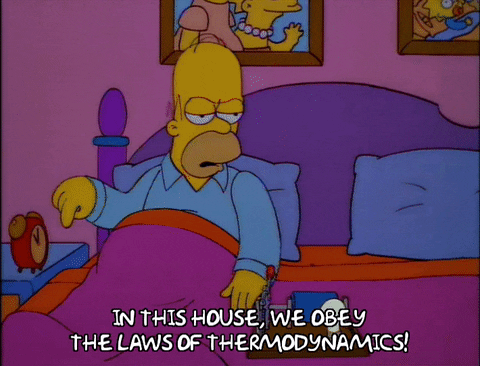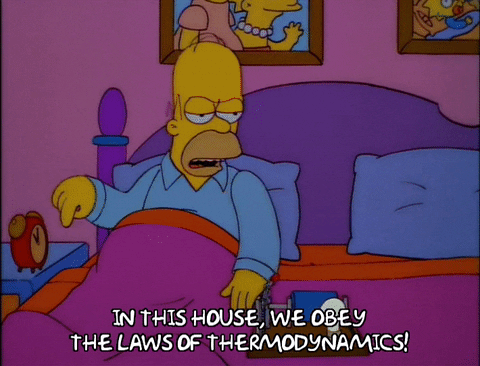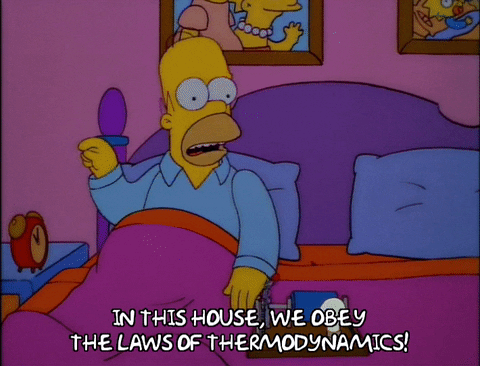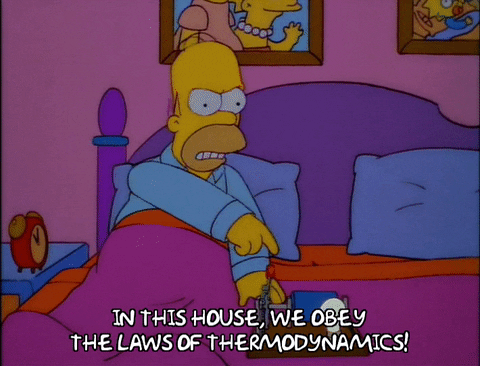
    Homer: In this house, we obey the laws of thermodynamics!
    It’s not just a good idea, it’s the law.

    In contrast, Dev actually increases the level of entropy. Every new release, be it as small as a one-line fix or finding that errant semicolon, is a change that has to be made, reducing the order that Ops fights so hard to maintain. Dev is entropogenic, embracing change as a positive force.

    The interaction between Dev and Ops is analogous to the second law of thermodynamics: Entropy can only increase over time, unless energy is introduced to the system from outside. In other words, unmanaged change will eventually cause something to break, unless people put in continuous effort to prevent those breaks.

    Thermodynamics: Lots of Heat, not Much Light

    These conflicting goals, taken to extremes, can get unhealthy, with Ops actively fighting change or Dev going around Ops to increase their velocity of change. Left unchecked, this tension can turn into a vicious cycle, as frustration with the “Department of No” drives developers into unmanaged “shadow IT.”

    The good news is that the analogy with hard laws of physics is not perfect. The process of increasing entropy is not irreversible, and does not require constant inputs of energy to prevent. New agile approaches to IT Ops are emerging that are light and flexible, taking their structure from that tension. In the physical world, this is called “tensegrity,” and was originally formulated by Buckminster Fuller, one of those annoying polymaths who seem to make breakthroughs in every field they touch.

    Tensegrity structure
    Tensegrity structure

    IT Ops needs its own equivalent to tensegrity, a flexible, holistic structure that is able to embrace change while maintaining its shape. Structures that try to resist change through rigidity are brittle and ultimately fragile.

    Today, this flexible strength is enabled by AIOps, a term coined by Gartner to describe a new way of operating IT, based on augmenting human skills with automated analysis enabled by modern algorithmic and machine-learning approaches.

    Complexity Breeds Complexity

    Modern IT is too complex for any single person or even team to keep track of, instead requiring multiple specializations. In turn, each of these functions requires its own specific support tools that enable that particular role. Beyond a certain point, it becomes very difficult to combine these partial views to gain a holistic understanding of what is actually happening in the environment.

    Because of the scale of modern IT environments and the sheer rate of change that businesses require, old-style rules-based “Managers of Managers” can no longer keep up, requiring more effort to build and maintain their worth. Especially as infrastructure becomes more and more self-modifying in response to changing conditions and demand, IT Operations needs to accelerate just to keep up.

    AIOps brings developing issues to the attention of sysadmins before they become visible to customers and end users, and gives them the tools to collaborate effectively between different teams and specialist roles to avoid outages or restore service quickly and efficiently. In this world, automation is used to augment the capabilities of the human operators to make them more effective, letting people concentrate on adding value, not just fighting fires.

    This is how Ops can get out of the business of fighting Dev, and instead become a supportive partner. AIOps can catch issues that are affecting services and flag them to the right people early on, including the DevOps engineers that are responsible for production support.

    For developers, one of the fears around DevOps is that in “picking up the pager,” they are opening themselves up to a constant stream of irrelevant alerts. Old Ops hands nod wryly at this, or maybe try to share their personal approach to filtering the noise. Instead, AIOps ensures that only valid, actionable alerts get as far as being shown to a human being and taking up their valuable time.

    Eyes on the Prize

    It’s not all roses. As the AIOps market begins to mature, there is a certain amount of “algorithm-washing” going on, with more and more vendors trying to claim that either their legacy tool was AIOps all along, or that their one-trick pony is actually a whole three-ring circus. What gets lost in the excitement is what all of those algorithms are actually supposed to achieve.

    Me too!
    Me too!

    In considering a shift toward AIOps, the goal should not be simply to build a better mouse trap, meaning a smarter filter for monitoring events. The success of the project can be measured not so much in the mathematical results of the algorithms, but in the smoother exchange between the human users. This easier collaboration is especially important across team boundaries, whether these be different specialist units within the Ops function or developers and software engineers who need to work with Ops to understand the performance of their code in production.

    The benefit of transforming operations this way—moving from sequential, waterfall Ops to abile, collaborative Ops—is to turn DevOps-enabled teams into a sort of perpetual-motion machine, able to continue operating without requiring constant massive inputs of energy from outside the system. Modern applications and the complex infrastructures that support them cannot be managed with the sorts of rigid, cobbled-together, industrial approaches that were appropriate in the mainframe days. AIOps is the agile, flexible approach that can not only accomodate that complexity, but thrive on it.

    — Dominic Wellington

  • From Waterfall Incident Management to Collaborative IT Operations

    From Waterfall Incident Management to Collaborative IT Operations

    What can Ops learn from Dev in the transition from sequential, reactive IT support to real-time DevOps?

    One of the signature ideas of DevOps is right there in the name: the blurring of the boundary between the historically separate worlds of Development and Operations.

    On the face of it, this seems like a great idea. Developers have always grumbled about how Operations is preventing them from deploying as rapidly or as frequently as they would like. Meanwhile, Operations people have harbored a dark suspicion that developers might code with more attention if they were the ones getting paged at 3 a.m.

    Another of the great things about DevOps is that it is pretty easy to adopt in one area or project without needing to get the entire company onboard before you can get started. This means that you can quickly produce some interesting results in terms of accelerated development times and release frequencies, faster resolution of problems and more time spent innovating instead of firefighting.

    Armed with these results, DevOps evangelists spread through the organization, telling their story and recruiting other departments and teams to join them in the bright future.

    This is Where the Problems Start

    Complex enterprise IT environments are, well, complex. Different teams have adopted different tools and methodologies to do their jobs, and are justly resistant to throwing out something that works for them. Specialists in different areas require their own specialist tools to be able to do their jobs. Because of this, when an incident occurs, all of that agility and collaboration that DevOps brings goes out of the window in favor of something that looks much more like a classic “waterfall” approach:

    • When an event is received, it is routed to one particular team
    • The event is placed in a queue
    • Eventually, someone from the relevant team takes a look at the event and makes a determination of whether it falls in their area or not
    • If it’s in their area, they begin working to resolve the issue within their team
    • If it’s not (believed to be) in their area, they reassign it, either back to the front-line team, or to whichever team they believe to be responsible (often, this is the network team)
    • Repeat until either someone takes ownership and fixes the issue, or it becomes a Major Incident and everyone gets paged at 3 a.m.

    Just to complicate matters, there may be multiple instances of this process going on at any one time, as two or more different teams grapple with what eventually turn out to be different aspects of the same problem.

    Why Does This Happen?

    In health care, there is only so much that can be done by way of prevention. There is always the need to react to patient’s issues, starting from their symptoms. In the same way, the starting point for Operations is monitoring—gathering the symptoms of the IT infrastructure to be able to return it to health as quickly as possible.

    To understand problems with the Ops part of DevOps, we needed to start at the beginning, with those symptoms. We wanted to do this the scientific way, so we polled attendees of Velocity and Monitorama to understand their top monitoring challenges.

    The interesting fact was that across both populations, the main challenge listed by attendees was “alert noise/fatigue/volume.” Simply put, Operators were drowning in alerts to the point that they had completely lost the ability to understand what was actually important, let alone an overall picture of how those alerts related to the service that IT was supposed to deliver.

    This is another parallel between IT and health care, where alert fatigue has long been a concern, and with potentially far more serious consequences than in IT.

    A big part of the cause of the alert fatigue on the IT side is the proliferation of specialist monitoring tools. In the poll, 66.67 percent of people we surveyed have five to 10 monitoring tools in place, and yet 61.90 percent of them are still struggling with that problem of alert noise/fatigue/volume.

    To be clear, those different tools are each very important. Trying to monitor the network with an APM tool is probably not going to go well for you. They only become a problem when it becomes too difficult to build up an overall picture of what is going on, and sharing that between different people to solve problems faster.

    So What Can Be Done?

    Dedicated Operations organizations have long worked to assemble tools and techniques that can give them a complete view of the environment that they are supporting, and of the services that run in it. The accelerated pace of release that comes with DevOps is causing the old models to break down, but fortunately, it also carries in itself the seeds of a new approach to the problem.

    As development moved from the sequential waterfall model to a more rapid, collaborative, and agile approach, operations teams can learn from that transition to come up with a more agile approach to IT Ops.

    What would this look like? The first thing to do is to get rid of the blame-storming and buck-passing: “It’s the network!” “No, it’s the database!” I don’t know about you, but personally, I’ve been in enough of those meetings to last me for the rest of my life, thank you very much.

    Let’s All Go Fishing in the Data Lake

    Instead, a common perspective is needed, so that everyone can quickly agree on what is going on and what needs to be done.

    This does not mean throwing out all of those specialist monitoring tools! They are there for a reason. Rather, gather all of those symptoms in one place where the whole team can collaborate to make sense of them more easily. These days, it should be easy to get information in and out of the various components of your toolchain (and if it’s not, that’s a glaring warning sign that maybe it’s time to migrate off that particular tool).

    This will, of course, produce a huge pile of data, so it’s not sufficient to stop here with the creation of a “data lake.” Things disappear into lakes and are never seen again—in which case, why did you bother gathering them in the first place?

    What you need is a way to make sense of what is going on in the lake, and show that to the right human operators. In the same way that developers resent sitting around waiting for the Change Advisory Board to meet, operations people get frustrated and bored just staring at a screen waiting for something to happen. If instead you can use automatic techniques to assemble all the related symptoms of a single issue together in one place, that will give you a good starting point to resolve that underlying issue quickly.

    Brainstorming, not Blamestorming

    This is where the collaboration comes in. Again, people are doing this already, but they are doing it in a disconnected way. The tools have evolved, from email and IRC, to Slack and Google Hangouts, or even (heaven help us all) WhatsApp. What has not evolved is the usage model; it’s still ad-hoc and reactive, and requires lots of copying and pasting.

    Operations people can learn from what their developer colleagues have built or adopted. Kanban boards are a great technique for tracking open issues and who is working on them. ChatOps is a fantastic way to integrate human-to-human communication with human-to-machine communication. Integrated collaboration tools capture knowledge that otherwise is stuck in people’s heads or inboxes, unavailable to their colleagues.

    I’m an Ops guy at heart, but I can recognize a good idea when I see it. Our Dev colleagues have come up with quite a few that we could stand to adopt in Ops. Let’s learn from what they already know to work, instead of trying to reinvent the wheel.

    — Dominic Wellington

  • Dev & Ops: These Are Reconcilable Differences

    Dev & Ops: These Are Reconcilable Differences

    The new world of IT requires a different approach from what worked in the past. As usual, the technology is the easy part, but without people and processes being aligned, it won’t deliver value. When evaluating how data science and machine learning can help manage highly dynamic IT environments, old reflexes may be actively harmful.

    By their nature and due to their experiences, Ops people tend to be a pretty (small-C) conservative bunch. Rule No. 1 of Ops is “If it ain’t broke, DON’T TOUCH IT!” and if we’re honest with ourselves, most of the rest of the rulebook is just variations and commentaries on that theme.

    One of the ways in which Ops people try to control their world is through automation. DevOps mostly looks to the moment of release and deployment, as that is where the handover to Ops typically occurs—and this is a big focus of the drive to automate. However, there is another part of Ops where automation is key, something that Dev is not always nearly as involved in; namely, day-to-day operations. Which alerts should even be sent, whom they should be routed to, what are the valid responses and so on—all these have been automated over the years, to a greater or lesser extent.

    Ops people have laboriously documented their architecture and spent a long time in meetings planning which information is relevant to share and who should respond to alarms. Much of this is implemented in various pieces of software, whether commercial, open-source, home-grown or that special grey area, where something that started out as a standard component has been so customized that it is effectively bespoke. Rules, filters and thresholds determine what action to take in which case.

    These approaches have been in place for years or even decades, but now they are starting to fail. Simply put, IT’s increased complexity and the ever-accelerating rate of change are outpacing administrators’ ability to keep up and reconfigure their management systems.

    The Coming ‘New Normal’

    New approaches are emerging to deal with the new normal, but as ever, the technology is the easy part. For new technology to be a success, people and processes need to be in sync.

    Right now, the emerging approach is to use data science and machine learning to process events, instead of the old deterministic rulesets and databases. The results speak for themselves, especially at scale and in highly dynamic environments. People building container-based or SDN architectures no longer assume that there will be a database of configurations that will always be up to date; quite the opposite.

    The new way is to throw out all the filters and rules, feed all the alerts into a single place, and then use data science and machine learning techniques to sift them and identify relationships with them. The result will be a shift in focus from individual alerts to the business problems those alerts are the symptoms of.

    Algorithms are great at these sorts of repetitive, high-volume tasks. They can look at massive volumes of events and figure out which are even relevant and worth taking a second look at, and then identify how those events relate to each other and what they really mean. This is where the humans come in, with their strengths in low-volume and unpredictable situations. Because they are not constantly drowning in irrelevant noise, they can work together effectively to understand the actual problem and get it fixed quickly.

    Where’s the Catch?

    The difficulty is that for many Ops people, there is a big cultural change required to adopt this model. The old deterministic systems may have required laborious maintenance, but at least it was possible to model them and understand why a specific result was achieved. New algorithmic techniques take a radically different approach, and while the results are impressive, they come from a black box. This does not inspire confidence for people who are very comfortable with the old approaches.

    Often, the response of Ops people coming from legacy tools is to get stuck into the minutiae of what is going on inside the black box and to look for traditional failure modes. The problem is that these approaches are no longer valid in the new world, as I discussed in my last post about getting to SRE.

    For instance, while it is indeed important to make sure that no issues are missed due to over-aggressive filtering, this does not mean that we need to see every single alert. As long as we know about the actual business problem, we don’t actually care about the single alerts, except insofar as they help us debug the underlying issue and resolve it.

    The other direction is even more insidious, where people spend a lot of time chasing down “extraneous” events that they think they should not be seeing. The risk is, of course, that the Ops team ends right back up in the same place that they were trying to escape, where they are only able to identify expected problems, but are getting blindsided on a regular basis by the “unknown unknowns,” the conditions that simply should not happen.

    Ultimately, Ops needs to let go of reflexes that were good in the old world, and focus on the goal: ensuring the uptime and stability of business-supporting systems. The how is less relevant than the what and the why; the algorithmic black box might as well be full of magic leprechauns, as long as they are telling Ops what they need to know, when they need to know it. Call it the “Chinese Room” theory of Ops: For as long as the results are useful to Ops, it does not matter what is inside the room.

    The benefit for Ops is precisely that they no longer need to focus on the minutiae of individual alerts, but can concentrate on solving actual business problems. That is how IT can make itself a value generator and avoid being viewed as another undifferentiated cost center.

    Pay no attention to the algorithm behind the curtain.

    — Dominic Wellington

  • Site Reliability Engineering: How to Make the Operations Side of DevOps Actually Work

    Site Reliability Engineering: How to Make the Operations Side of DevOps Actually Work

    The DevOps movement often has been accused of focusing too much on the first half (Development) and not enough on the second half (Operations). Certainly there has been more attention paid to deployment of payloads than to operating running systems, leading to the dismissal of the handover between Dev and Ops as “throwing it over the wall.”.

    Lately, we have seen the emergence of a new focus on the stability and reliability of the systems that are the targets of those deployments, with the creation of the new practice of site reliability engineering (SRE). This has been a welcome addition to the IT toolbox, but it can still seem to put all the onus on Ops teams to catch whatever comes over the wall.

    The Problem with Site Reliability Engineering = IT Infrastructure

    In SRE, the IT infrastructure is expected to be highly automatic and self-healing in the face of any events. Here is the problem: That approach works well for foreseeable events, but less well for the unforeseen ones. Because of that factor, it works well in environments that run few types of individual workload types, but do so at very large scale. If you’re thinking that sounds like Google and Facebook, you’d be right.

    What this amounts to is massive engineering of the infrastructure to withstand known or foreseeable problems. However, typical enterprise IT environments are not like that. A large bank might have thousands of applications, each of which must accommodate changes on a pace that is dictated from outside the IT environment. Applying assumptions from one environment to the other is asking for trouble.

    To illustrate this, let’s look at an example from outside IT. Recently was the anniversary of the sinking of the Titanic, on April 15, 1912. The RMS Titanic itself embodies the principles of SRE, engineered to prevent or survive all manner of emergencies. The ship was equipped with state-of-the-art everything to transport its passengers in comfort and safety across the Atlantic.

    As we all know, that plan did not quite work out. A combination of unexpected changes in the environment (more icebergs than normal), business imperatives to maintain speed and mishandled warnings about the ice from other ships led the Titanic to disaster.

    While the consequences of an IT failure are rarely quite as dramatic as the sinking of an ocean liner, many of the same factors apply. IT administrators may believe that in the worst case their backups and disaster recovery plans will be sufficient to handle any problems, but these plans are designed around known and foreseeable problems. Unexpected circumstances can easily lead to cascading failures, which is why it is critical to be ready for the unexpected when it—inevitably— occurs.

    The Problem with Traditional IT Ops = Static Models

    The key flaw in IT Ops is reliance on static models of the world. These models come in many shapes – the CMDB is the “model” that many think of first, but static rulesets are also a model. The most dangerous models, though, are the ones that are invisible: namely, the filters that are put in place to determine which alerts and events are even worth considering.

    This is the flaw that ultimately sank the Titanic: The crew were unable to correctly priorities events and react to them in time to avoid failure. It is also the flaw that causes countless much more minor issues every day in data centers everywhere: the filesystem that filled up with logs, taking down the database that the critical business application relied on—and the filter that had not forwarded that alert because it usually was harmless. Or the loss of one leg of the redundant network link, which was ignored because the other leg was still up, so there was still a link—until that one failed too, and an entire site went dark.

    The key factor is that the filters were not wrong to suppress those alerts. By definition, informational or warning alerts are not the same as major or critical ones, and most of the time they can be safely ignored, to be dealt with later.

    Every now and then, though, a pattern of those alerts, if understood correctly, can identify a future problem in the making. These developing issues could be nipped in the bud, if only Ops teams had enough hours in the day to look at them and review them. But, of course, they don’t—every Ops team I have ever met is drowning in issues, and behind those there is a long and lengthening to-do list.

    What Can DevOps Do to Make Operations Better

    New approaches are emerging to make the principles behind SRE more widely accessible and applicable. In particular, more dynamic noise reduction and correlation is now possible, to sift those important alerts from the constant background noise and put them together into a picture of what is really happening. The key factor is to be able to do this in real-time and without a human having to plan out laboriously what are all the possible scenarios that they might need to know about in the future.

    Gartner has called this new approach Algorithmic IT Operations, or AIOps. The idea is to bring together all possible sources of events, whether those are alerts from the compute or network infrastructure, transaction slowdowns reported by an APM tool, automated deployments being run from a CI/CD toolchain, or anything else the might conceivably be relevant. All of this information then can be sifted by algorithms to understand what is actually important to Ops and brought to the attention of the right specialists who can work on the issues and get them solved fast. Part of that process is also the integration with systems of record (which generally means IT service management), and with automation and orchestration tools that can accelerate remediation activities.

    This is how we can get the Ops side of DevOps to where they need to be to be able to accommodate the ever-accelerating pace of change—whether from Dev teams wanting to run ever more frequent deployments, or from business users needing help with their own goals—or from the next unexpected issue to come down the line.

    — Dominic Wellington

  • Tuning in to the real pain of customers

    Tuning in to the real pain of customers

    In my product management and marketing experience, I discovered that I carry a deep bias about our product capabilities and why it’s special — before a launch. On a whiteboard, in a spec, or in a usability lab, our product can and will change the world. Post-launch, when customers get their hands on our product, magical things happen. Intended use cases become irrelevant. Intended benefits change. Intended value changes.

    Over the past weeks, I’ve had the privilege of talking to many of our customers and prospects. They educated and helped me reframe the value we deliver to our customers.

    Real pain

    Much has been written about the DevOps revolution, driven by applications moving to the cloud, mobile computing, and the business need to compete. The journey to an agile build-test-release cycle is real, and it’s hard. It’s hard for customers who are cloud-born, and it’s even harder for traditional operations and development teams. Listening to our enterprise customers who are several years into their transformation, I heard a lot about the explosion of technologies and the cultural challenge. The pain of the change is more excruciating than I realized. One large customer told me that two years ago, he (VP of Cloud Operations) and his team couldn’t stand to be in the same room as the development team. Today, they’re collaborating to the point where they now sit together.

    Demanding developers

    Secondly, developers are more demanding. Again, it seems obvious, but hearing firsthand how hard it is to empower developers brings it home. Developers want and require more agile build, release and deployment capabilities, but they don’t want to be infrastructure experts. Enterprises are beginning to offer self-service to their private and public clouds so that developers can have autonomous access to environments and resources. A leading biotech customer told me that he can’t dictate policies and processes anymore, that he needs the researchers and scientists to adopt and embrace what the DevOps team is providing. Finding the appropriate balance between freedom and speed along with control is a common challenge across the board for our customers.

    Delivering value

    At ElasticBox, we talk a lot about the technology and cultural shift in enterprise DevOps teams, and how we can enable greater collaboration by being at the nexus of the transformation. That is what we ultimately deliver to our customers: a new way to deliver applications to the cloud that’s better, faster and more efficient.

    It’s a big promise, and we’re excited to fulfill it. Today, we deliver the foundational tools for self-service provisioning, service catalogs and continuous integration and delivery — wrapped with a flexible box architecture that’s reusable and agnostic to the underlying infrastructure and deployment tools. We approach the problem from a developer mindset to drive speed and autonomy, and at the same time, provide the policies and reporting to ensure scale. We’re hungry to continue learning from you, so check us out and let us know how we can help.