Waiting for a single annual pentest to secure your application is like locking your front door only once a year and hoping for the best. In an era where 133 new vulnerabilities are reported every single day, relying on periodic snapshots leaves your organization exposed to evolving threats for months at a time.
This approach is no longer just risky; it is a significant financial liability. Data from the IBM Systems Science Institute highlights that fixing a bug in production costs 100 times more than catching it during the initial design phase. For modern teams, the ‘window of vulnerability’ between tests is where attackers find their greatest opportunities.
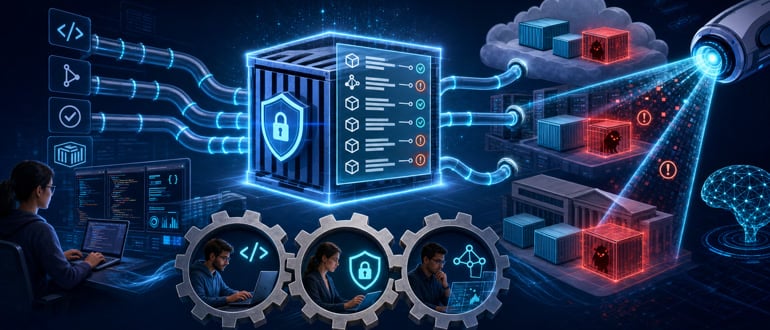
Transitioning to continuous security in DevSecOps is the only way to close this gap. By embedding automated validation into your CI/CD pipeline, you move from a reactive ‘checkbox’ mentality to a proactive, resilient posture. This guide explores how to move beyond one-time testing to build a defense that evolves as fast as your code.
What is Continuous Security in DevSecOps?
Continuous security in DevSecOps means integrating security checks into every stage of the software development life cycle. It is not a one-time audit. It runs alongside your code, from the first commit to production deployment.
Traditionally, security testing happened at the end. That model does not work anymore. With faster release cycles, vulnerabilities left unchecked for weeks can cost companies an average of $4.44 million per breach, according to IBM’s 2025 report.
In DevSecOps, security becomes part of the pipeline itself. Automated scanning, real-time threat detection and policy enforcement run continuously. Every build gets checked. Nothing waits for a quarterly review.
The Problem With One-Time Security Testing
Most teams still treat security like a final checkbox. You build the product, hand it over to the security team and wait for a report. That process made sense 10 years ago. It does not make sense now.
Release cycles have shortened dramatically. Teams ship code daily, sometimes multiple times a day. A penetration test done once a quarter cannot keep up with that pace. New vulnerabilities get introduced with every pull request.
The numbers back this up. According to Veracode, 76% of applications have security flaws on initial scan. Most of those flaws come from code written between testing cycles. That gap is where attackers operate.
One-time testing also creates a false sense of security. You pass the audit, check the box and assume you are covered. But your attack surface keeps changing. Static snapshots of security do not protect dynamic, constantly evolving systems.
Core Principles of a Continuous Security Model
Building continuous security is not about adding more tools. It is about changing how security fits into your entire development process. These five principles form the foundation of that shift.
1. Automate Security at Every Stage
Manual reviews cannot scale with modern development. Automated security checks need to run at every stage of your CI/CD pipeline. From code commit to deployment, automation catches issues before they reach production. It removes the human bottleneck without removing human judgment.
2. Shift Security Left Without Abandoning the Right
Shifting left means catching vulnerabilities early in development. But security cannot stop there. Runtime monitoring, post-deployment scanning and incident response all matter just as much. A strong continuous security model covers the full software delivery life cycle (SDLC), not just the beginning of it.
3. Treat Security as a Shared Responsibility
Security is not just the security team’s job. Developers, DevOps engineers and product teams all play a role. When everyone understands their part, vulnerabilities get caught faster. Building a security-aware culture is just as important as any tool you deploy.
4. Integrate Threat Intelligence in Real-Time
Static threat models go stale fast. Continuous security means feeding real-time threat intelligence into your pipeline. When new vulnerabilities are disclosed, your system should respond immediately. Waiting for the next scheduled review gives attackers a window they will use.
5. Measure, Monitor and Improve Continuously
You cannot improve what you do not measure. Track metrics such as mean time to detect, vulnerability closure rate and false-positive rates. Regular review of these numbers tells you where your security program is strong and where it needs work. Continuous improvement is the goal.
How to Integrate Continuous Security in DevSecOps
Integrating continuous security into DevSecOps is not a one-day project. It is a step-by-step process that embeds security controls directly into your development and deployment workflows.
Step 1: Audit Your Current Pipeline
Before adding anything new, understand what you already have. Map out every stage of your CI/CD pipeline and identify where security checks are missing or manual. This gives you a clear picture of your gaps before you start filling them.
Step 2: Embed SAST DAST Early
Static application security testing (SAST) should run on every code commit. Dynamic application security testing (DAST) should follow in your staging environment. Running both consistently means vulnerabilities get caught at the source, not weeks later during a scheduled review.
Step 3: Automate Dependency Scanning
Third-party libraries are one of the biggest sources of risk. Use software composition analysis (SCA) tools to automatically scan dependencies with every build. Tools like Snyk or Dependabot flag known vulnerabilities in open-source components before they make it into production.
Step 4: Secure Your CI/CD Configuration
Your pipeline itself is an attack surface. Harden your CI/CD configuration by enforcing least-privilege access, securing environment variables and auditing pipeline scripts regularly. A compromised pipeline can undo every other security control you have put in place.
Step 5: Add Runtime Security Monitoring
Security does not stop at deployment. Implement runtime protection tools that monitor application behavior in production. Solutions such as Aqua Security and ZeroThreat.ai can detect anomalous activity and trigger alerts the moment something unusual happens in your live environment.
Step 6: Set Security Gates in the Pipeline
Define clear pass/fail criteria for security checks. If a build introduces a critical vulnerability, it should not move forward. Security gates enforce standards automatically and remove the pressure of manual judgment calls during fast-moving release cycles.
Step 7: Improve Continuously
Continuous security never truly ends. Schedule regular reviews of your security metrics, tooling and policies. As your application evolves, your security posture needs to evolve with it. Treat it like any other part of your engineering process, always improving.
Top DevOps Tools for Continuous Security
Selecting the right tools is the foundation of a successful continuous security strategy. You need solutions that not only find vulnerabilities but also integrate smoothly into your existing development workflows without causing delays.
Here are the best picks for ensuring security right from your CI/CD pipelines:
1. Burp Suite
Burp Suite is a widely used web application security testing platform known for its strong manual penetration testing capabilities. It works as an intercepting proxy, allowing testers to analyze and modify HTTP and HTTPS traffic to uncover vulnerabilities in real-time.
It supports the full testing workflow, from mapping the attack surface to identifying complex vulnerabilities. While it includes automated scanning, it is mainly preferred for deep, expert-driven testing where precision, context and detailed validation are required.
Key Features of Burp Suite:
- Intercepting proxy for HTTP and HTTPS traffic analysis
- Advanced vulnerability scanning and crawling
- Intruder tool for fuzzing and attack simulation
- Repeater for manual request testing and validation
- Session handling and authentication testing
2. OWASP ZAP
OWASP ZAP is an open-source web application security scanner designed for both beginner and experienced teams. It provides automated vulnerability scanning along with proxy-based testing, making it a flexible tool for integrating security into development workflows.
It is widely used in DevSecOps environments because of its automation capabilities and CI/CD compatibility. ZAP performs both passive and active scanning, helping teams detect common vulnerabilities continuously without requiring heavy manual effort.
Key Features of OWASP ZAP:
- Automated passive and active vulnerability scanning
- REST API support for CI/CD integration
- Intercepting proxy for traffic inspection
- Scriptable interface for custom testing
- Strong community support and extensions
3. ZeroThreat.ai
ZeroThreat.ai is a modern, AI-powered automated penetration testing platform. It supports the DevSecOps approach with simplified CI/CD integration. The tool simulates real attacker behavior to identify exploitable vulnerabilities across web applications and APIs, going beyond traditional vulnerability scanning.
It focuses on continuous validation by chaining vulnerabilities, testing business logic and running security checks across staging and production. This helps teams identify real risk exposure and maintain strong security posture without slowing down release cycles.
Key Features of ZeroThreat.ai:
- Agentic attack path simulation for real-world testing
- Exploit chaining and business logic vulnerability detection
- Continuous, production-safe automated pentesting
- CI/CD integration for ongoing security validation
- AI-driven risk prioritization and remediation insights
4. Mend
Mend is a software composition analysis platform designed to secure open-source dependencies across the development life cycle. It helps teams detect vulnerabilities, license risks and malicious packages early, directly within developer workflows and CI/CD pipelines.
It stands out with reachability analysis, which focuses on exploitable vulnerabilities instead of noise. Mend also provides real-time alerts and automated remediation, allowing teams to fix issues faster while maintaining visibility into software supply chain risks.
Key Features of Mend:
- Advanced reachability analysis for real risk detection
- Automated vulnerability remediation workflows
- Open-source dependency and license compliance scanning
- SBOM generation and supply chain visibility
- CI/CD and IDE integrations for continuous security
5. Semgrep
Semgrep is a lightweight static analysis tool that helps developers find security vulnerabilities directly in source code. It supports multiple languages and integrates easily into CI/CD pipelines, making it a strong choice for continuous code security testing.
It uses rule-based semantic analysis, allowing teams to customize detection logic based on their codebase. With support for SAST, SCA and secrets detection, Semgrep enables fast and flexible security checks without slowing development workflows.
Key Features of Semgrep:
- Static application security testing with semantic analysis
- Custom rule creation for tailored vulnerability detection
- CI/CD and IDE integration for continuous scanning
- Multi-language support across modern stacks
- Combined SAST, SCA and secrets detection capabilities
6. Black Duck
Black Duck is an enterprise-grade application security platform focused on managing open-source and third-party risks. It provides deep visibility into dependencies, helping teams identify vulnerabilities, compliance issues and supply chain threats across the entire SDLC.
It combines multiple scanning techniques, including dependency, binary and snippet analysis, to detect hidden risks. With continuous monitoring and automated policy enforcement, Black Duck ensures secure software delivery at scale.
Key Features of Black Duck:
- Comprehensive SCA for open-source risk management
- Multi-layer scanning including binary and snippet analysis
- Continuous monitoring of dependencies and vulnerabilities
- SBOM generation and compliance tracking
- Integration across CI/CD pipelines and developer tools
7. Spectral
Spectral is a developer-first security platform focused on detecting secrets, misconfigurations and sensitive data exposure in codebases. It continuously scans code, logs and assets to prevent credential leaks and reduce security risks early.
It uses AI-powered detectors and integrates directly into CI/CD pipelines and pre-commit workflows. This allows teams to identify exposed API keys, tokens and sensitive data before they reach production environments.
Key Features of Spectral:
- Secrets scanning with thousands of built-in detectors
- Real-time detection of API keys, tokens and credentials
- CI/CD and pre-commit integration for early detection
- AI-powered risk detection across code and assets
- Custom rule creation for organization-specific policies
Wrapping Up
Security can no longer be treated as a final checkpoint. Modern DevOps teams deploy multiple times a day, and each release can introduce new risks. To tackle this, continuous security must be embedded for automating security testing, monitoring and validation into every stage of the life cycle. It ensures vulnerabilities are identified early, fixed faster and never left unnoticed as new deployments are made. This shift helps build a resilient security posture that keeps pace with fast-paced SDLC.