Tag: devops

  • Agile Service Management in Practice

    Agile Service Management in Practice

    It turns out agile and service management go together quite nicely. But how, and how do you translate the agile philosophy to actual changes in your work? There is much to learn on the topic.

    Agile Service Management: A Checklist

    Here are several practical examples on how to make your service management more agile:

    Make Sure Everything You Do Adds Value for the Customer

    IT departments usually place a good deal work into tasks that have little actual value for their customers. For example, a colleague of mine recently visited an organization where its IT department had written an extensive manual for a new smartphone it offered. While this might sound useful, most of the information was already available to users on the internet. That and next OS update would have made the manual outdated and useless.

    Plainly speaking, this is a waste of time and resources. There’s no need to replicate work already done and content that is readily available anywhere on the web. Taking a focus on agile, a better way to go may have been of documenting information to keep the manual limited to what is strictly necessary, and provide these instructions to a small test group. In doing so, only describe company-specific information, such as how to synchronize your work email with the new smartphone, and respond to the documentation based on the feedback you receive from your test group. Following this feedback, you are able to update the documentation before you officially begin to supply the smartphone, for example.

    Always Work Closely with Your Customers

    As it designs its services and processes, service organizations must make many assumptions about the needs of its customers. For example, for years a facilities organization encouraged its customers to log a call when something was wrong in the office building. Recently, it discovered that customers were annoyed to receive five or six status update emails after they log a call—one reason many customers stop logging calls altogether.

    In agile service management, you always involve your customers as soon as possible with everything you do. Using the example above, come up with a solution together with customers. When customers log a call, they can tick a box saying they want to receive status updates. One question and a single checkbox can spare a great deal of frustration.

    The Right People in the Right Place

    Many IT organizations lean heavily on processes, unfortunately, but their goal is to guarantee consistent quality of services, no matter who supplies the service. While good in theory, in practice it matters who supplies a service. For example, an unmotivated service desk likely probably leaves a less-than-positive impression on your customer than a happy, motivated employee. You simply can’t cover this outcome with a “process.”

    An important part of the agile mindset then is providing enough time and attention for your team members, which only functions well with people who are good at the work they do and when the work they do makes them happy. If a team member is no longer motivated, talk to the employee and see if you can find a role where they’ll be happier, and better able to support the organization as a whole.

    Make Your Processes as Flexible as Possible

    ITIL processes are usually not flexible, to say the least. Change management is a great example. A request for change must go through a set number of predefined steps. The only choice you usually have in the process is approve or decline the change. There’s no room to change plans and if you want to change them, you need to stop the process, make a new plan and get approval. Plan, change, stop with obstacle. Plan change and plan all over again. Not efficient in most cases.

    Your design and planning must remain flexible enough to address ever-changing organizational demands. This, however, doesn’t mean you need to implement every single planned change, and you also must allow your team to deal with new processes as they see fit.

    Design, Implement and Improve Your Services Step by Step

    New software or services implementations can take up months and even years. When the implementation is finally done, you’ve gained new insights and probably want to change many things, but by that time there’s likely little budget left or the project team members have moved on and it’s up to the application manager to process all the feedback on their own.

    Delivering new services in an agile way means you deliver something workable as soon as you are able, collect feedback and use this feedback to improve the product. The process isn’t perfect, but that’s okay. While you continue working on the next process, you can receive feedback to improve your incident management.

    Keep Your Services and Operations Straightforward

    Requests for services often contain a good deal of unnecessary management authorizations. In many cases, IT department leaders assume that department management wants control over every individual request or, alternatively, the IT department doesn’t carry any responsibility. This creates a process unnecessarily full of authorizations and a manager who gets loads of emails with authorization requests.

    Nothing should be this cumbersome. Things will be much smoother when the IT department members ask managers how much control they really want or need. They usually don’t really want to receive a number of emails, but there is an alternative solution: Requests don’t need to be authorized and managers can receive a monthly overview of the costs. This way, the manager still has control over costs, but he or she doesn’t have to process numerous emails. And the employee, the user, is helped much more quickly.

    Making Your Incident Management More Agile

    Where do you need to start when you want to work with agile? The response to this question depends on the organization. The best approach may be starting with taking a look at your current services and compare these with agile principles. For example, where’s the friction? What improvements are easy to implement? That’s where you begin. Then you start by making a small improvement, ask for feedback and move on to the next improvement.

    Incident management is the most important process of a supporting department. It’s also quite straightforward, but how can it be made more agile? Simply start by stripping out everything from the incident management process that has no customer value. Take a critical look at your current processes and evaluate each step by asking yourself if every step of the process adds value for the customer. To answer this question, you first need to know what your customer want, which is probably nothing more than a quick solution.

    Every step in your incident management process must contribute to how quickly an incident is processed. If there is a step along the way that doesn’t contribute to your goal, remove it. Eliminate everything wasteful from your process.

    — Nancy Van Elsacker Louisnord

  • DevOps: The Things We Must Stop

    DevOps: The Things We Must Stop

    Anytime there is a popular movement in technology (and I would argue any other field), people get carried away. We’ve seen it over and over, and DevOps attracts this kind of attention. In fact, DevOps caters to those who get carried away by mainstream folks screaming, “THIS CHANGES EVERYTHING!” That type of hyperbole pushes those who get carried away even further. And marketing always takes things to whatever place they have to in order to, well, sell their ideas to the market.

    Rack ’em Stack ’em Robots

    My all-time favorite purposeful over-the-top is the tendency to pretend that prior to the cloud, every project was started with “rack ’em, stack ’em.” This is demonstrably false, as by the time the cloud was taking off, VMware’s market penetration was significant. And yet, the number of blogs/amount of marketing material that starts out with the premise that every application required waiting for physical server delivery and configuration is insanely high.

    No. Enterprises, in particular, had to wait for VM allocation and configuration.

    Another that isn’t really mainstream—and I’ve mentioned in other locations—is the AWS TCO calculator. The simple calculator is not a bad tool, and I’ve used it numerous times in the past, but the TCO calculator makes some assumptions about deployment costs that are a little wild, such as that TCO includes the cost of VMware and its supporting hardware for an individual app. Of course, that’s not how enterprises do it. There is a VMware infrastructure and it is shared across apps. While it would increase the complexity a tiny bit, a simple checkbox that asks, “Do you already have a VMware cluster?” would go a long way—or better, one that asks how many apps you are running on VMware and divides the overhead by that number before including it in TCO. But of course, if you are getting your TCO comparisons from a competitor, expect the TCO will be stilted, no matter who is generating it.

    Oversimplification

    Whether it is infrastructure orchestration or app deployment, there is a lot of content out there that talks about how much easier infrastructure as code will be, and how much less documentation we will need. This, sadly, is a bogus premise. Whether you’re using the 50,000 service offerings of AWS or the power of HashiCorp’s Terraform—or any of half a dozen other competitors—it is complex. We’re not doing anyone any favors by glossing over the complexity that inevitably occurs in enterprise-class deployments, and we’re doing a massive disservice every time someone claims that documentation needs will be less because it’s “self-documenting code.” Self-documenting code sucks without a ton of comments in App Dev, and it’s worse in deployment. Employees new to the process need, and should be provided, solid documentation on how the system works and where different pieces fit.

    We’re deploying complex apps on complex infrastructures with evermore complex compliance and security requirements. It is not simple.

    All or Nothing

    There is a belief among too many aficionados that their way is the “One True Way.” The fact of the matter is that all enterprise application portfolios are complex and there is a metric ton of extant code that must be managed. A startup with one web-based app (no matter how large it may be) or a games developer focused on Android as its only platform might well have agile and DevOps as their only development/deployment methodology. No one else does. The enterprise running a hundred or a thousand different apps on several platforms is not going to flick a switch and say, “We’re all X now,” no matter what X is. Anyone who has tried to standardize the database in an enterprise knows that just doesn’t happen (I did, as an architect in a financial services org. It was ugly).

    Some projects are simply great fits for agile and DevOps—those with a high rate of change, where a little bit of instability in return for rapid feature rollout—while others simply are not—ones that maintain data that must be rock-solid, ones with a low level of change, etc. Any given enterprise is a mix of these things. Back in the days of the language wars, I used to say, “Right tool for the job,” and today, in the days of the architecture/automation wars, I say the same thing. If the project is rapidly evolving and you want lots of small changes in a constant stream, agile and DevOps are the right tools. If the project moves slowly and has an emphasis on stability or data quality, it’s not a great candidate for these tools at this time.

    I’ve talked about some of the bad vendors in this post, so I’ll call out IBM for being a good vendor on this point. Looking at the company’s model for moving the mainframe is a good example of how you could look at all of your IT, because IBM doesn’t say, “This changes everything!” It says, “Here’s how to tell what offers the most bang for the buck in moving to agile and DevOps.”

    Just Keep Rocking It

    Working in IT? You’ve been keeping your org running. Don’t start second-guessing your gut now just because the new shiny is being waved in front of you. Learn, change, do. But don’t rush into something with misinformation. Obey your gut and keep rocking your org’s world.

    — Don Macvittie

  • Making the Database Key to DevOps

    Making the Database Key to DevOps

    Here are three best practices for doing DevOps with the database

    The speed of business today demands that the development and deployment of applications is fast-moving, with frequent yet error-free releases. That’s why the adoption of DevOps is trickling down from Amazon, Facebook, Google and the other usual suspects to every company that relies on technology to drive its communications or sales with users.

    The database is now entering the picture, too, because when front-end applications are changed, there often needs to be a change at the back end to accommodate it. Redgate’s 2018 “State of Database DevOps Survey” found that more than one-third (35 percent) of organizations are deploying database changes either daily or more than once a week.

    Some are working even faster, with companies such as online travel provider Skyscanner moving from releasing database changes once every six weeks to 95 times a day when it first introduced database DevOps—and increasing the frequency since.

    This accelerated speed of delivery is a key benefit of database DevOps, with 28 percent of respondents to the DevOps survey quoting it as the biggest advantage. But as releases become more frequent, so, too, does the chance of something going wrong, along with the difficulty of pinpointing the exact cause in a large, complex, fast-changing environment.

    Database DevOps Best Practices

    Even with the most comprehensive testing, issues can occur. And as more and more developers now work across both the application and database, and with larger, more disparate teams, companies need the ability for everyone to drill down quickly to identify and fix issues.

    Achieving this means bridging the database and application worlds by focusing on three key areas.

    Deployment Choice

    Different developers and database administrators will use specific tools to deploy database changes. This can depend on their experience, skills or simply that they have a preference for a particular way of working.

    You need to be able to allow this choice, but without affecting the ability to track down issues. Therefore, ensure that you have a monitoring tool in place that can pinpoint not just when and where changes were made, but which tool was used. This will help quickly find the root causes of any issues, by providing the full context around the problem.

    A Single View

    Data is the lifeblood of many businesses—companies now have more and more databases within their organization, often spread across different locations. However, no matter how complex your IT environment or the size of your estate, you need to be able to monitor database performance from a single place. That way, you can easily identify issues and pinpoint precisely which database is being affected.

    Wherever a database is, and whatever the distance it is being monitored from, the monitoring also needs to be in real time, with updates in seconds, not minutes, providing the reassurance that you always have the latest picture of what is occurring. This enables you to become more proactive, spotting developing trends and issues such as deadlocks or blocking processes, before they affect your users or overall performance. Having a single, up-to-date view is therefore essential when integrating the database into DevOps processes.

    Fast, Customizable Alerts

    The ability to make frequent, reliable, repeatable changes to the database as well as the application is integral to DevOps flows, and monitoring them means evaluating dozens of different parameters constantly.

    Clearly, it’s impossible to keep an eye on everything that is happening, even when events are condensed to a single monitoring screen. Therefore, ensure you’re able to easily create and customize alerts for specific parameters that are important to your business, so that they don’t get missed. This enables you to better understand DevOps processes and ensure that you have early warnings of potential complications, no matter where they occur.

    For the database to be an integral part of DevOps, organizations need a complete, interoperable view of their entire estate so  they can track down problems, monitor processes and spot issues before they affect users. That view should be equally available to the whole DevOps team, including developers, so they can see immediately what effect their latest change is having and take the appropriate action to fix any breaking change while it is still fresh in their mind.

    Only then can databases take their key place in DevOps flows, eliminating bottlenecks and speeding up development to meet fast-changing business needs.

    — Matt Hilbert

  • What Can the Cloud Do for DevOps?

    What Can the Cloud Do for DevOps?

    The cloud has enabled DevOps to grow and expand well beyond traditional boundaries set forth by on-premises production environments. With Amazon Web Services (AWS) and other cloud services providers, DevOps devices are intended to speed advancement by empowering engineers to change, test and push code in a computerized design. This enables organizations to create and send administrations and applications significantly faster than in traditional development environments.

    Organizations following DevOps and continuous delivery (CD) practices follow various approaches such as Agile, scrum or even hybrid models to define what is to be built. Whatever your approach, having clarity, context and communication around requirements is critical.

    Modern Requirements4TFS, along with TFS/VSTS, make a great platform for requirements management, DevOps and CD.

    AWS characterizes DevOps as “the combination of cultural philosophies, practices, and tools that increases an organization’s ability to deliver applications and services at high velocity.” Especially for SaaS programming organizations, DevOps is one of the essential drivers for moving to the cloud in any case. Quickening item advancement can give programming organizations a focused edge with quicker time to showcase for items and highlights.

    Integration is the most important part here. DevOps integration is known to target testing, development, maintenance and product delivery for improving security and reliability. Using continuous integration (CI), the developers should acknowledge the business needs and get new productions and applications.

    AWS underpins DevOps by giving administrations to manufacture store and send applications and design administration devices. Chef, for example, utilizes Ruby to compose framework design “formulas,” which computerizes the procedure for arranging and working nearby and cloud-based administrations, including AWS.

    While DevOps isn’t one of a kind to AWS, AWS has different devices and best practices to make DevOps less demanding and more successful, particularly with regards to mechanization of use advancement and conveyance.

    The center best practice is a way to deal with DevOps of “ceaseless incorporation and persistent conveyance” (CI/CD). A CI/CD approach enables you to ceaselessly refresh applications and administrations to present new highlights, settle bugs and react to client needs.

    AWS Features

    Major AWS features are as follows:

    CodeBuild: This tool helps in running the tests and producing software packages which are ready to deploy. It can handle multiple application processes at a time.

    CodeDeploy: AWS CodeDeploy can be utilized to computerize code sending to AWS instances to one occurrence or to a large number of examples, and even to nearby servers. This incomprehensibly streamlines application refreshes all through your AWS, eliminating the requirement for a careful manual arrangement.

    CodeStar: CodeStar helps in creating new projects with the templates which have selected programming languages that provides AWS services. This also provides identity and access management (IAM) access policies for the secured application environment. For projects using AWS CodeBuild, AWS CodeDeploy, AWS CodePipeline or AWS CodeCommit, this helps in automating the configuration of a continuous delivery pipeline.

    The confirmation of-idea process additionally shows you something about your current association, including the current ability and the capacity for the advancement and operational workforce to adjust to new procedures and innovation.

    DevOps is by all accounts important to creative associations, as it is a perceived way to convey an incentive to the business quicker, and it’s a situation that can oblige change.

    DevOps process requires a solid coordinated effort between developers, operations and managerial staff. That is the reason increasingly DevOps experts are swinging to effectively available cloud-based stages; for example, AWS instead of customary, privately based servers. With AWS, everybody included can access pertinent, institutionalized creation environments, regardless of their specialty or physical location.

    What’s more, AWS’ cloud-based framework can be much more financially attractive to organizations than an on-premises infrastructure, as AWS enables clients to rapidly scale processing limit up or down as the necessities dictate. Also, with AWS EC2 depictions, clients can rapidly scale up EC2 occurrences and copy generation situations as required.

    It is likewise conceivable to plan EC2 and RDS cases to begin and stop at foreordained circumstances, which guarantee clients aren’t wasting money on unused resources—for example, evenings and weekends. This adaptable, pay-as-you-go approach means AWS clients pay for the servers and capacity they really utilize, which can bring down expenses by as much as 70 percent.

    DevOps and AWS have helped IT in various factors to improve in various aspects:

    Quality output: Infrastructure as a code has changed the skill set of the team to improve the processes. Code reviews, testing and agility has increased output quality by collaborating and experiencing with the development team.

    Process improvement: It’s obvious that combining the two teams can result in an increase in performance. The adaptability and “codification” of the foundation that cloud suppliers such as AWS empowered along with this cross-group joint effort has spurred the desire to do more. Including operations groups in the development procedure and the other way around empowers sharing of understanding and skills.

    Bringing out improvements: To provide agile development a quality process, development and delivery tools helps without involving integration in development and delivery. To bring improvements and for bug fixes, teams should work repeatedly, rapidly and reliably at low risk.

    Coordinating data management: Data management is combined in the process. Schema management tools actually help with tough tasks such as handling changes in the database schemas code for the requirement of code repositories. This process decreases the risk by rolling the database front and back and being controlled and repeatable.

    Security: Security is an important area that needs to have a more pronounced role in DevOps. Every code is stored in AWS CodeCommit, so any change in the code can be known and the security can be built.

    Conclusion

    The flexibility provided by the cloud and AWS provides the platform for a cultural shift that has brought benefits to both operations and development teams.

    — K Maneesha

  • Picking a Git for the Enterprise

    Picking a Git for the Enterprise

    Some of my Agile and DevOps transformation work, not surprisingly, involves helping clients with tooling adoption—to set up, scale and operate across the organization. This blog piece is about a recent experience of setting up Git across a client organization.

    Git, as most of you are aware, is a fundamental building block for many of the modern engineering practices associated with Agile and DevOps. Software configuration management tools such as Git, in simple words, allow you to track and manage your software code and configuration changes in the most-effective, efficient and distributed way. Git, as the choice of source control, has remained steadfast over the years, while other tools across various categories of DevOps tools have seen their fortunes go up and down with the ever-changing technology landscape of DevOps tools. In fact, one new buzzword is GitOps—some even calling it the next stage of evolution for DevOps.

    Origins of Git

    More than a decade ago , the Linux community faced a challenge  because none of the existing revision control tools met their need for a distributed version control tool. And from that need Git was born. In the words of the creator of Git, Linus Torvalds, “The main issues with SCMs is the politics around who can make changes.” Ever since its creation, Git has radically changed the notion of software configuration management (SCM), by enabling engineers to work remotely and autonomously. (If you are new to Git and interested in exploring more about Git and its features, Atlassian has a tutorial and GitHub has a list of resources.)

    Git and More

    While Git as the core product is fundamentally the same whichever flavor your prefer—GitHub, GitLab or Bitbucket—the wrapper around it determines the important non-functional characteristics such as operatability, security, usability and maintainability. Our quest for an enterprise-scale Git focused on the wrapper and not the core product itself, as much has been written, debated and documented on the core product of Git itself already. The value and relevance to enterprises is in the wrapper that these productsplatforms provide.

    We looked at the core product and related offerings; as you can imagine, the three tooling vendors have different positioning and taking different directions with the future road map for their respective tools. Bitbucket’s strength lies in the fact that Atlassian is bundling the product with the omnipresent Jira Software and Confluence. GitLab’s road map seems to be taking the product beyond Git and into the idea of a single product for your entire pipeline automation, from concept to cash. GitHub, which is being acquired by Microsoft, is increasingly relying on the strength of integrations with other tools and the workflow capability the company is bundling with it.

    (I avoid an overemphasis on the commercial aspect in this blog; however, I’m not ignoring it completely. Part of the reason is due to the fact that enterprise pricing is not entirely transparent and may vary wildly depending on organization’s negotiating capability, the scale of usage, future potential and marketable track records as perceived by the tooling vendors. This blog is also not meant to be a feature by feature comparison, as this is something you can Google and find out yourself very easily.)


    The Verdict

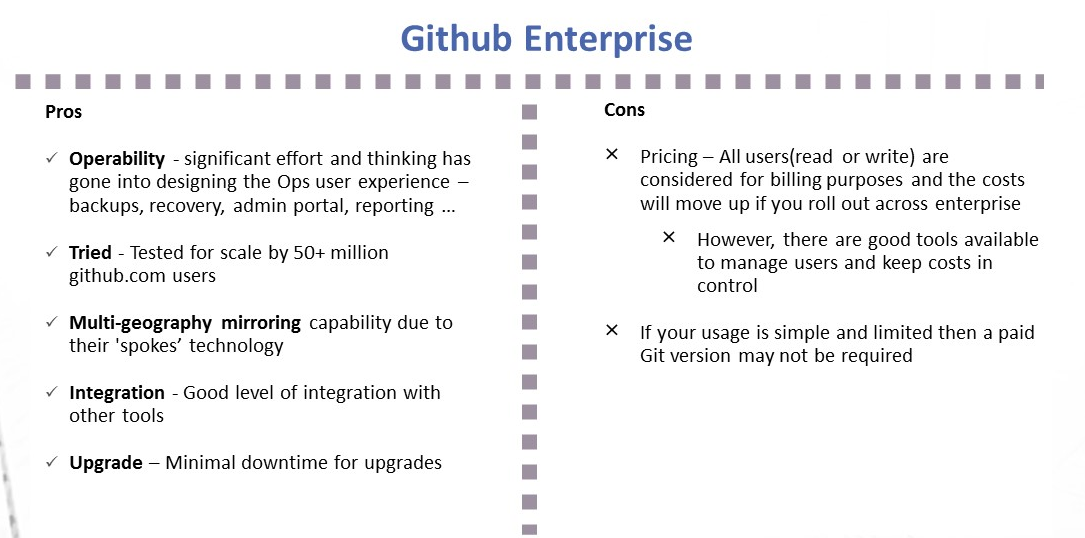
    Github Enterprise pros and cons
    Image1; Github Enterprise – Pros and Cons
    Gitlab Ultimate and features
    Image 2:  Gitlab Ultimate – Pros and Cons

    My Recommendation: It Depends

    1. I liked the vision of GitLab as a single-stop tooling platform for continuous integration/continuous delivery (CI/CD), which goes beyond source control. I think the tool is simple and intuitive to use and great for small to midsized setups or even large enterprises that are focused on having smaller and autonomous teams.
    2. GitHub seems to be well-suited for large and complex enterprises with significant outsourced and offshore-based technology teams.

    I would love to hear your views on what has been your thinking with regards to choosing a Git-based product for your enterprise or teams. Meanwhile, here are some links you might find useful in your decision-making:

    1. Why and how GitLab abandoned Microsoft Azure for Google Cloud – https://venturebeat.com/2018/04/06/why-and-how-gitlab-abandoned-microsoft-azure-for-google-cloud/
    2. Tooling integrations of GitLab – https://docs.gitlab.com/ee/integration/README.html#doc-nav%20for%20list%20of%20integrations
    3. GitHub add-ons are listed at Addons are listed at https://github.com/marketplace
    4. Security and scalability info of GitHub is at https://github.com/jonico/github_security_and_scalability_overview
    5. Products that integrate with GitHub platform – https://github.com/works-with
    6. Pricing of GitLab – https://about.gitlab.com/pricing/

    — Aditya Vadaganadam

  • Why Open Banking Should Consider DevOps

    Why Open Banking Should Consider DevOps

    There is a craze sweeping Europe, and rippling across the world—and no, I’m not talking about the next British Invasion. Open banking is a trend that’s significantly altering how banks work with fintechs and maintain agility in the global marketplace.

    A main enforcer is PSD2, a piece of EU legislation that sanctions access to personal banking data. It’s resulted in an explosion of EU banks providing public application programming interfaces (APIs) for fintechs to develop with. The implications aren’t limited to Europe; many banks all over the world are looking to PSD2 as a baseline, forcing some tough evaluation of how financial architecture should adapt.

    Banks are also under consumer threat to evolve or get out — a 2016 Accenture study found that 78 percent of respondents would bank with a tech firm such as Amazon or Google.

    As banks transition into savvy software providers due to market pressure, one thing is certain: they must adopt agile software development strategies that streamline the deployment and maintenance of these services. In other words, banks must adopt a DevOps philosophy to maintain a market advantage.

    Open Banking Evolves Bank Architecture

    The bank has become programmable. Many banks are now required to allow third-party authentication and access to payment, account information, fee details and other data. This involves support for various integration methods; SDKs, APIs and OAuth for authentication, as well as documentation, sandboxes and other developer tools. Whether they like it or not, banks are now SaaS providers.

    It should be noted too that open banking is not limited to the European Union. The UK’s open banking standard is the Competition and Markets Authority (CMA), and Australia, Japan and other countries are making similar inroads with regulating banking data. The excitement has also encouraged North and South American players to open up.

    The new bank APIs help bypass traditional methods, saving a ton of time. In an article in American Banker, BBVA noted that online e-commerce system Dwolla was able to slash the typical three-day to six-day deposit time frame using their payment APIs. “We’re allowing that all to occur in real-time,” said Chad Ballard, director of mobility and new digital business technologies at BBVA Compass.

    Letting FinTechs focus on web UI development helps banks focus on their core competencies: banking and authentication. Establishing connections via API-driven microservices is also a safer alternative to screen-scraping.

    Why DevOps for Banking?

    Banking Exchange defines agile banking as “the future of retaining relevancy for banking as a whole.” For open banking to be successful, the platform must be tested, monitored and secured for fintech consumers. Sounds a lot like the hallmarks of quality DevOps practice.

    Popular services Google Maps, Uber, Stripe, Twilio and others have adopted an API-as-a-product mentality. These programs adhere to best practices, iterative feedback and agile development methodologies to excel. Similarly, for banks to remain competitive, they must treat their platform architecture and public gateways with the same tenacity.

    For banks, uniting iterative development with stability testing—essentially the Dev + Ops mantra—for their APIs, microservices and frameworks will go a long way to help reach open banking goals and maintain future regulations on API performance standards.

    A DevOps mindset is crucial to consider early on in the open banking journey, as it can impact how banks address:

    • Iterative development and testing: By tying in iterative development with stability testing, organizations can surpass the time limitation often incurred between shipping versions between development teams and testing teams.
    • Continuous monitoring: Many tools are available to monitor the CI/CD pipeline, helping banks respond to issues and improve uptime.
    • Versioning strategies: DevOps in banking will see the larger picture, working in the REST mantra to build on the scale of decades to avoid breaking change.
    • Transition to microservices: As enterprises dispose old monolithic architectures, bitesize services are arguably more appropriate for modern banking; however, they come with unique caveats that DevOps can address.
    • Collaboration between silos: By pivoting to more point-to-point, collaborative processes, banks can reduce friction to meet the responsive expectations set by FinTech, who are becoming new public faces for banking.

    An end result of DevOps is to increase agility in an organization. Especially for large banks, this signifies drying up the traditional “waterfall” development life cycle known to stigmatize the corporate approval process.

    Case Studies: How Banks Are Utilizing A DevOps Cycle

    Many banks have been vocal about what they are doing to ignite positive technological innovation alongside third parties. For example, Capitol One’s DevExchange recently announced a new initiative called experimental APIs. “They are designed with the goal of getting early feedback from the community around API desirability and design before the product release,” the company noted in a blog post.

    In this experimental setup, operational cues inform development. Getting the two sides to talk and respond to community feedback is paramount for DevOps to succeed.

    For banks to adopt an agile makeup, Manfred Bortenschlager, Red Hat’s director of Business Development for API-based Integration Solutions and API Management, recommends what he calls an “agile integration.” This involves a distributed integration for greater flexibility, containerization for the ability to scale better and managed portals for reusability.

    Another interesting effort is that of CIBC, a Canadian bank that is responding to the open banking movement with a responsive microservices framework the company has developed using open source components.

    What’s evident is that many banks already acknowledge DevOps principles as key for innovation in their sector. Through the the use of iterative testing, innovative tooling and automated workflows, banks can achieve greater operational efficiency.

    Open Banking Must Follow Software Development Practices

    A result of the open banking movement is that banks must keep technological pace with fintech. Especially with regulatory pressure, banks must consider how best to approach new technological initiatives.

    DevOps is a way to mitigate concerns. As a philosophy for uniting technical procedures with responsive operations, it’s a prime strategy for banks to consider when readdressing their technology.

    In defining what “agile” embodies for banks, Steve Williams of Cornerstone Advisors said: “The idea is you need to start taking the management and operations of a financial organization and start adapting some of the things that have made technology companies viable.”

    American Banker echoes this, believing that “banks should be more like software companies.”

    Now prodded by open banking, it’s high noon for luddite banks to embrace contemporary software development practices; that means incorporating DevOps into the open banking agenda.

    — Bill Doerrfeld

  • Transforming with the Cloud: If Not Now, When?

    Transforming with the Cloud: If Not Now, When?

    The question of whether to move to the cloud is no longer relevant for most organizations. Migrating workloads to the cloud has already become an inevitable requirement for a vast majority of companies regardless of their sizes, and if your organization isn’t doing that already, then it is simply the question of when and how you’ll consider doing so.

    The agility, redundancy and elasticity with regards to scaling compute resources present a compelling need to move to the cloud sooner than later, let alone other factors such as reduced overall capital expenses associated with managing a robust on-premises infrastructure. The finance sector is usually a little behind in embracing major changes in IT operations because of their strict regulatory compliance requirements and the complexity in their application portfolio as a result of several mergers and acquisitions. These restrictions are quite common, especially with insurance companies, but surprisingly there are several major insurance companies that have made significant investments to modernize their traditional applications and migrate them to the cloud for efficiency, agility and cost reasons.

    To effectively support the business that constantly strives to be highly competitive and to reduce the time-to-market, most applications development efforts are planned in an Agile fashion with short sprints that produce usable deliverables within a few weeks. When development teams go Agile, it is important that all other associated services operate in a similar manner.  Without agility in infrastructure provisioning and other support services, it is simply impossible for the development teams to be successful in producing deliverables at high velocity. A commonly heard complaint from most of the application development teams is about the delays from infrastructure teams on provisioning servers. Provisioning a virtual machine (VM) takes more than three weeks in many companies, even today. This is due to a variety of factors such as work backlog, complexity in approval processes, compliance requirements, lack of automation and several others that are organization-specific. IaaS and PaaS offerings from cloud leaders such as Microsoft Azure and AWS address these issues to a great extent. Even if companies are not ready to migrate their existing applications to the cloud, they should seriously consider IaaS and PaaS from well-established cloud providers for new applications being developed.

    There are several factors that could influence IT leaders’ decisions on their strategy regarding cloud and some of the areas that certainly cannot be overlooked are discussed here. The purpose of this article is to provide a general high-level overview, especially for companies that have been hesitating to migrate their workloads to the cloud. It should be noted that we are barely scratching the tip of the iceberg in this discussion.

    Complexities in the Application Stack and Infrastructure

    It is not uncommon for organizations to be overwhelmed by complexities and issues with their current infrastructure setup and get bogged down dealing with their day-to-day operational challenges. Due to these ongoing issues, one might develop a false notion on the actual effort involved in migrating to the cloud and may even wonder whether it is an achievable target state. It is important to map out the current infrastructure that supports the business applications and have a clear view of the complexities, dependencies and licenses that are in play. The application servers, database servers, storage arrays, enterprise messaging bus, document management systems and several other key components that work together to power your key business applications need to be taken into consideration. This will not only help decide the right applications that are suitable for the cloud, but will also help pick the right cloud provider to suit your needs. You can notice the convergence of IaaS and PaaS as it is becoming difficult to separate one from the other. Most leading providers are offering these services as a package.

    It is better to categorize your applications based on their level of complexity and shape up your cloud strategy accordingly. Standalone applications that simply require a web server, application server and database server are ideal candidates for your first phase of migration efforts. You can ensure that with the right architecture on the cloud, there will be better availability, load balancing and performance and less maintenance overhead for your standalone applications.

    Amazon Elastic Compute Cloud (EC2) provides availability of 99.99 percent and its auto-scaling feature allows automatic scaling of the fleet up or down depending on the needs to maximize performance and minimize cost. Similarly, Microsoft Azure offers VM Scale Sets that can be configured for your applications to scale automatically. If the requirement is to develop brand new applications for the cloud, the options are endless. As an example, .net based web applications to be hosted on Azure can be developed to be run as Docker containers.

    Containers and the management of a cluster of container nodes have come a long way since their inception. Docker Swarm and Kubernetes have drastically simplified the management, load balancing and scaling of containerized applications. Containers are not only for your new applications; they also come in as a great solution for modernizing your legacy/traditional applications and migrating them to the cloud.

    Storage

    Identity and access control used to be prevalent challenges in the past, but cloud providers have greatly simplified identity management services such as application authentication, user management and single sign-on by providing rich features to support the information security and compliance requirements of organizations. Microsoft Azure offers Azure Active Directory and provides a few different protocols such as WS-Federation, SAML-P and OpenID Connect to authenticate the user. It also supports multi-factor authentication. For brand new applications that are developed using Visual Studio 2017, it is extremely simple to integrate the application for authentication and authorization workflows on Azure AD using the above protocols.

    Databases play a vital role in the decision-making process when it comes to migrating to the cloud. Senior IT managers are usually highly concerned about the security of data while technical personnel are worried about ensuring storage, performance, recoverability and availability. Application developers and DBAs end up spending a great deal of time fixing code or other application configuration parameters even when databases are simply migrated from one server to another within the same data center. Cloud solutions address such concerns. Microsoft Azure, for instance lets you migrate your native on-premises SQL databases to Azure SQL Database Managed Instance by providing the native virtual network (VNET) support. You don’t have to change your applications as a result of this migration. The Managed Instance offered by Azure is quite promising and it is certainly a great solution for migrating large numbers of on-premises SQL Server databases to Azure. Similarly, managed database services are offered by AWS for both relational (RDS) and NoSQL (DynamoDB) databases. Amazon EC2 service is integrated with Amazon RDS and Amazon VPC to provide a complete, secure solution for computing, query processing and cloud storage including, but not limited to, a wide range high-performance web applications, DB servers and batch processing needs.

    Disaster Recovery

    Cloud providers offer data centers in several regions around the world. It requires a major investment for any organization, both financially and operationally, to match the redundancy and recoverability provided by major cloud providers. Even organizations that have a highly virtualized infrastructure setup have physical infrastructure for some of their mission-critical applications. The reasons for having such a setup could be argued, but the costs associated with setting up a disaster recovery environment for such infrastructure would be significant. To ensure comparable performance and capacity, the disaster recovery environment is typically a replica of the production environment that is underutilized most of the time, consuming significant investment.

    Planning for setting up a disaster recovery site involves considering several factors such as, ensuring compute capacity and scalability (servers and storage), networking (bandwidth, load balancers, switches, routers), identity management (directory services, authentication, authorization), facility to host the DR site (location, floor space, power, air conditioning) and operational aspects (personnel, monitoring, alerting, break-fixing, hot-hands support). Cloud providers give you the option to choose the location of your DR site anywhere in the world. Depending on the contract you have with your cloud provider, you could either quickly deploy compute resources on your DR site on the cloud or utilize the necessary automated processes to switch over to an already running replica of your application environment on the cloud DR site.

    There are numerous features that AWS offers to address each of the above-mentioned aspects that need to be considered for setting up a disaster recovery site. Amazon Machine Images (AMIs), for example, lets you preconfigure images with the operating system and your application stacks. It is also possible to configure your own AMIs to allow the recovery process to launch these images automatically in the event of a disaster, saving a significant amount of time.

    Microsoft also provides highly dependable DR alternatives on Azure. You can use Azure as your secondary site for DR purposes or completely eliminate the need for data centers by picking different Azure regions as primary and secondary sites. Azure offers the Active-Passive and Active-Active topologies. In case of the active-passive topology, all user traffic flows to the primary region while preparing the secondary region to take over at any point since the database runs in both regions with a synchronization mechanism implemented between the regions. Active-active topology ensures running of cloud services and databases on both the primary and secondary regions and user traffic goes to both the regions. In the event of a failure at primary, all the user traffic will be directed to the secondary by simply disabling the DNS at the primary region. Auto-scaling features of Azure will allow the scaling up of compute resources in the secondary region as needed.

    DevOps Maturity

    Any discussion on migrating to the cloud would be incomplete without highlighting the significance of a solid DevOps practice to complement the cloud strategy. From a technical standpoint, companies that settled on Linux environments used to have a slight edge over those that went the Microsoft route, especially with regards to implementing open source solutions and technologies that support DevOps and cloud initiatives. This is highly arguable now as Microsoft has not only opened its gates wide for several major open source tools but also allowed for better integration of several leading open source products such as Docker, Jenkins and Puppet with ALM tools such as Microsoft TFS 2017.

    Depending on the goals of an organization with regards to its cloud strategy, the level of maturity required from a DevOps perspective needs to be analyzed. DevOps can be looked at from infrastructure as well as applications development perspectives. If your goal is to use cloud services only for IaaS, it will be extremely valuable to develop strong, infrastructure-focused DevOps capability, practices, processes, tools and automation. Through proper scripting and integration with IT services management (ITSM) tools such as Service Now, the entire process—from requesting infrastructure through having them provisioned with all the patches, hardening, etc.—can be fully automated by leveraging tools such as Chef or scripting via PowerShell. Features such as metered billing and quotas that are already offered by cloud providers can be leveraged and integrated with organization units’ budgets, approvals and other processes to establish a well-managed, fully automated infrastructure provisioning process.

    Organizations considering leveraging the cloud for applications development are definitely at an advantage compared to those considering development on-premise. Microsoft, for example, offers IaaS at a highly competitive price and provides Visual Studio Team Services (VSTS), a cloud version of Team Foundation Services (TFS), on Azure. The PaaS services offered by Azure are also quite extensive, along with integration with a variety of open source tools. With this combination, developers have a complete, end-to-end solution to address all their requirements without losing time in waiting for environments to be set up. DevOps can play a significant role here. With a fully integrated continuous integration (CI) framework, the developers could commit code to a managed Git repository on the cloud, and automated continuous integration can be kicked off via VSTS, which handles the build, automated testing, code quality control, building container images, automated spinning up of infrastructure needed for an environment and deploying code or containers on the environment following a fully integrated change control process and quality gates. Developers can focus fully on developing code and enjoy the freedom of being able to deploy code on a transient environment on the fly to test their code before it goes through other phases of testing. In highly competitive business environments, this provides the ability to perform multiple production deployments in a single day if need be.

    Organizations with a high level of maturity in DevOps are the ones most likely to leverage cloud to its fullest potential. Similarly, those that are striving to attain this level of maturity are likely to get there sooner by moving to the cloud. Developing the expertise, building the process framework, and implementing the right DevOps tools will make it easier to solidify your cloud strategy.

    Compliance & Security

    Several organizations have refrained from migrating to the cloud mainly due to the strict compliance and security requirements that are mandated by the industry. Companies that are still hesitating to embrace the cloud are those that are skeptical about the security of their data on the cloud. Irrespective of the cloud provider or the strict SLAs and contractual terms that you may have with them, you are still accountable for the data that you own. So, it is extremely important to understand more about the security setup and the features offered by your cloud provider to secure your valuable data on the cloud.

    As the owner of your organization’s data, you have to know where your data is going to physically reside, what kind of encryption will be applied to your data at rest and in transit, who will physically have access to your data, how your data will be segregated from other tenants’ in a multi-tenanted environment, what recovery processes exist, what the regulatory compliance certifications that the provider has obtained are and answers to many more questions. Security experts highly recommend classifying your data based on risk levels and devising a strategy accordingly. You may decide to host your most critical data on-premises and use the cloud for other types of data.

    Microsoft offers a very comprehensive checklist and reports to help you assess the risk to your organization in moving to the cloud. Both AWS and Microsoft are certified by almost all major regulatory bodies with regards to data security and compliance. However, as outlined earlier, while your provider can take the responsibility to host your data in the most secure manner, you as the owner of the data will still be accountable for its integrity and security. So, this is an area that requires thorough analysis before you decide on your workloads that need to migrate to the cloud.

    To Make the Long Story Short …

    While savings on capital expenses is a given, this is not the prime motivator for most organizations to migrate to the cloud. As stated in the Gartner report, “Cloud Computing Primer for 2018,” the role played by cloud in this decade is way beyond simply setting expectations and providing a platform for better economic models. Digital initiatives such as artificial intelligence (AI), internet of things (IoT) and several other technological innovations and disruptions are fueled by digital platforms that cloud offers. Agility, scalability and flexibility, on the other hand, are certainly some of the key drivers that would encourage companies to migrate to the cloud. Furthermore, reducing your time to market can be better accomplished by moving your development workloads to the cloud. The combination of IaaS, PaaS and a solid DevOps practice to automate deployment of infrastructure and application stack makes cloud far more superior to running applications development on-premises. Companies that haven’t invested much in DevOps should seriously consider doing so before it is too late.

    Containers, the tools and practices to orchestrate, load balance and scale microservices add a completely different dimension to how cloud services could be further leveraged. They help ensure seamless, defect-free, repeatable deployments, and with the necessary automation to spin up transient environments, it is difficult to match the benefits of using containers on a fully automated IaaS in an on-premises setup.

    The auto-scaling features offered by cloud providers make cloud a far more superior alternative compared to hosting internally. The elasticity provided by cloud helps with scaling compute power, storage, load balancing and several other infrastructure services as needed, without having to make massive hardware investments.

    Cloud providers offer solid disaster recovery options and support. Implementing an active-passive or active-active primary and secondary sites is a lot more straightforward and easier to set up on AWS or Azure than doing it on-premises.

    Compliance and security are also important factors that could drive the cloud strategy. It is important for decision makers to evaluate the risk factors and then decide on the type of data that could reside on the cloud as opposed to staying internally.

    NetworkComputing provides interesting statistics on public, private, and hybrid IaaS adoption in their article, “IaaS Cloud Adoption Trends.” The article further refers to research from Interop ITX and InformationWeek on how organizations are moving and managing workloads to the cloud. Per their findings, several companies are expected to deliver over half (67 percent) of their IT and business services through the cloud in the next year. Of all the companies they surveyed, 31 percent plan to allocate over 50 percent of their budget to cloud initiatives.

    With a clear strategy, budgets, categorization of applications, prioritization and staff with the right expertise, you can be sure that your journey in moving your workloads to the cloud will be a pleasant one.

    — Sridhar Asvathanarayanan

  • Software Development: A Better Way to Measure Success

    Software Development: A Better Way to Measure Success

    Here’s a metaphor for software development you probably haven’t heard before: It’s like flying a plane. You have a starting point and a destination in mind, there’s a good chance you’ll change course midflight, and … sometimes you get a little nauseated?

    Okay, it’s not the best analogy. But there is one aspect of piloting a plane that offers valuable insight into how to measure your team’s performance more consistently. It’s called the performance-control technique, and it may be the best method you’ve never heard of for keeping your engineering teams aligned behind a common goal.

    Imagine for a second sitting in the cockpit of a plane, surrounded by clouds. Forget using the ground to orient yourself; you have nothing but your instruments and wits to guide you. It’s a situation I’m plenty familiar with, having taken flying lessons out here in rainy Seattle. In those cases, you use your altitude and power settings to set up a particular control scenario that results in your desired output, whether it’s ascending, descending, straight and level or turning. And then you monitor your performance—in this case via altitude, vertical speed and airspeed indicators—to verify that you’re achieving your desired output.

    Now unless your software development pipeline is irredeemably broken, you are probably not flying completely blind as you work to build and ship new features. But the technique still applies: Choose your control metrics (time to release, for example), and then set up a series of performance metrics to keep it on track.

    Cloudy Skies Ahead

    The greatest strength of the performance-control technique is its acknowledgement that any control can result in unintended consequences. Take reducing the time from check-in to release. It’s a fantastic goal: The quicker you get code into production, the quicker you deliver updates to your customers. The quicker you do that, the quicker you get feedback and respond to their needs. The quicker you do that, the quicker you can iterate on features. And the cycle continues.

    But it’s also a goal that can result in unintended consequences: When you single it out for attention, it’s only natural team members will want to do everything they can—at the expense of almost everything else—to achieve it. That’s not to say they want to do wrong; rather, they’re just trying to be good citizens. (And, okay, they don’t want their name to show up in a report about why the team didn’t meet its quarterly goal.)

    So people make compromises. Maybe they drop full regression passes and replace them with incremental feature and integration testing. It’s not that they don’t care about quality. But in their quest to help the organization meet its single-minded goal of reducing the time from check-in to release, they opt for the easiest change that could get them there, indirectly prioritizing speed over quality in the process. And that happens because there aren’t checks in place to keep it from happening.

    Taking Control

    How do you put this into practice at your own organization? Start by choosing your goals and then selecting the control metrics. For many, it could be as simple as increasing speed; it’s a natural goal to chase, for the reasons already discussed. But it may be something different; only you and your teams can decide by being intentional in how you evaluate your production environment.

    Then it’s time to choose your performance metrics for each of your goals. You can do that yourself, but it may be more illuminating—and, honestly, more fun—to get your software development team involved. That could range from encouraging them to brainstorm the negative consequences of implementing that goal to straight-up asking them how they’d game the system.

    The following chart offers examples of control goals, their resultant unintended consequences, and the performance metrics necessary to keep them in check.

    Desired Output Control Goal Performance Goal Unintended Consequences
    Climb to 4500’ Increase power, nose up Airspeed, Altitude Stalling
    Reduce bounce rate Reduce site latency Revenue, Conversions, Customer Engagement Smaller pages, poor experience, feature attrition
    Generate more conversions Increase availability Releases, Backlog Ticket aging. Lower frequency of releases, cherry picked work items, no risk taking.
    Reduce MTTR Speed up ticket closure Re-open rate, new ticket rates. Premature closure, delay in opening tickets for issues.

    It’s important to note that how closely you monitor each of these performance metrics will vary, and in some cases significantly. Rather than attempt to apply a one-size-fits-all approach, instead think of each in terms of how long it takes to detect that the metric is falling out of its control envelope and how long it would take to recover if it did. If it takes one day to detect that you’re outside of your envelope and three weeks to recover, then by all means, check in daily. But if it takes three months to fall out of the control envelope and just a day to recover, you may only need to check it once every couple of weeks.

    A Soft Landing

    As we’ve supported software development teams in their efforts to modernize their software delivery methods, we’ve heard time and time again, “What’s the best metric for measuring success?” And we struggle to come up with an answer because there is no golden metric that works for everyone. But more important, even the good ones can lead well-meaning engineers and team leaders to optimize for one thing while letting others suffer.

    So rather than search for a magic bullet, the secret is to find goals that work for your needs—and then build in metrics that keep you and your software development team accountable.

    — Rob Duffy

  • DevOps and Digital Transformation: Q&A with Cloud Foundry Foundation’s Chip Childers

    DevOps and Digital Transformation: Q&A with Cloud Foundry Foundation’s Chip Childers

    I had the chance recently to sit down with Chip Childers, CTO of the Cloud Foundry Foundation. One of Chip’s roles is working with companies digitally transforming their business, from legacy to a more DevOps-centric technology and culture. Here’s what he had to say.

    Swapnil Bhartiya: What are the greatest challenges facing those deploying DevOps? Where do companies usually go wrong?

    Chip Childers: In transitioning to a more modern, DevOps-driven approach, companies with a legacy infrastructure may encounter a number of challenges, both technological and cultural. There are risks both in inertia and in impatience—attempting to modernize too quickly can lead to technical disruption or even outages, and can also create cultural friction within an organization. However, a failure to modernize at a steady rate can lead to an organization being left behind as competitors choose DevOps and digitize more rapidly.

    Chip Childers, CTO, Cloud Foundry Foundation

    Ultimately, you can’t buy DevOps. It’s not something that is a tool or a product, even with plenty of companies trying to sell it to you. It is about a cultural shift, and it requires implementing the technologies, tools and products that are actually a fit, in the context of that culture, between new processes and existing systems.

    Bhartiya: Why is DevOps a good fit for automation? What are the specific challenges in such deployment?

    Childers: DevOps is fundamentally about the culture, process and tools working together to achieve a better “flow” through the business. Getting changes deployed quickly, with high quality and with as little effort as possible naturally leads to automation. That said, there are risks in automating too much too quickly, or attempting to automate more nuanced tasks. Certain tasks require more adaptable approaches or are more error-prone, so attempting to automate those can create challenges rather than generating benefits.

    Bhartiya: How should companies approach DevOps deployment to avoid the pitfalls and leverage the benefits?

    Childers: Start with people and culture. Get everyone talking and understanding each other. Ensure that everyone involved really knows what the business is about and how they fit into it. Establishing shared understanding and trust among traditionally siloed roles is the hardest and most important step to take. Beyond that, it would be impossible to provide a blanket approach for all companies, since every business is in a different chapter of its journey. For example, a small startup with brand new applications and infrastructure can be a lot more ambitious in its approach to DevOps than an enterprise with an existing, older infrastructure. One thing that is important for all companies to understand about DevOps is that no matter where they fall on that spectrum, they have to have a realistic approach based on their own resources, teams and technology stack.

    Bhartiya: Rather than being in opposition, DevOps and Agile are often touted as being complementary. How do companies use these two together for the best results?

    Childers: Both are fundamentally about achieving a better, more incremental and responsive approach to technology changes. Agile is about the development process of getting ideas manufactured into software, and DevOps is about being nimble with both deployment and changes to IT environments. Specifically for software, DevOps essentially extends agile software development methodologies into the realms of operations and infrastructure.

    — Swapnil Bhartiya

  • Why You Need Chaos Engineered into Your Hybrid Cloud Infrastructure

    Why You Need Chaos Engineered into Your Hybrid Cloud Infrastructure

    Nearly a decade ago, I began working at Amazon as an engineer. Cloud technology was just starting to revolutionize how companies launch applications, and early adopters were seeing the benefits of not having to purchase, provision and manage their own hardware. On the flip side, larger companies (especially those that store sensitive information) were still hesitant to fully embrace the black box that was “the cloud,” holding onto the belief that for critical applications, the cloud was neither reliable nor secure.

    Fast forward to today, and all of that has changed. We are seeing government institutions, banks, and hospitals all moving their infrastructure over to the cloud. The benefits of being agile, innovative, and highly efficient have mostly overshadowed the concerns around the cloud’s reliability. According to Cloud Technology Partners, cloud adopters see an average reduction of total cost of ownership (TCO) of around 40 percent. And top-performing banks are 88 percent more likely to implement a hybrid cloud solution than their underperforming peers, cites a recent report from IBM Institute for Business Value.

    Long story short, the question is no longer “if” but “which”—and there are three major options: AWS, GCP and Azure. Today, many companies are doing their best to avoid vendor lock-in, opting instead for a distributed strategy, where teams are empowered to choose the best option for what they are working on. While having a hybrid approach helps avoid vendor lock-in, it also can save teams from disaster if one of the cloud providers has a major outage like the great S3 outage of 2017.

    But just because you have a hybrid strategy—running active-passive across different cloud providers—doesn’t mean you’re home-free. Unless you’ve actually tested that your passive stack will jump in to save the day in the event of a crisis, you’re more or less closing your eyes and crossing your fingers in the hopes that your active stack never goes down. Think of it like running a fire drill: How can you be sure everything runs smoothly during a time of disaster if you never actually run the drill?

    We need to shift how we think about operations to place more of the burden of Ops work upfront. While it’s important to reduce MTTR (mean time to resolution), that still means there has been an incident that has affected customers and potentially your bottom line. As someone who has been a call-leader for Amazon and Salesforce, I know firsthand that we could save ourselves a lot of headaches by being more proactive about running experiments in a controlled environment and focusing on reducing the MTBF (mean time between failures).

    This is why it is important to have a chaos engineering solution that can run experiments across all of your environments regardless of their build, technology or provider in one simple to use, unified experience. By consistently testing that your “failsafe” actually behaves the way you want it to, you can be much more confident that the operations work you’ve put in to make your architecture more resilient isn’t all for naught when a real-world outage comes calling—and it will.

    — Matthew Fornaciari