Tag: devops

  • NGINX Unveils Hybrid Application Delivery Controller Platform

    NGINX Unveils Hybrid Application Delivery Controller Platform

    NGINX this week announced it has developed a common framework for managing application delivery that can be applied across both monolithic and microservices-based applications.

    Announced at the NGINX Conf 2018 conference, the NGINX Application Platform has been rearchitected to provide traditional load balancing capabilities and a web application firewall (WAF), as well as a built-in service mesh for managing microservices and an integrated application programming interface (API) management platform.

    Sidney Rabsatt, vice president of product management at NGINX, said an update to NGINX Controller is at the heart of a much more comprehensive to approach to integrating load balancing, service mesh technologies and API management. Due out later this year, NGINX Controller 2.0 is based on a modular architecture that enables additional functions to be added via plug-in modules. The module for API management is slated for release in the fourth quarter, while the service mesh module is scheduled to become available in the first half of 2019.

    Rabsatt said it’s become clear IT organizations don’t want to replicate existing application delivery controllers just to manage microservices. There will never be such a thing as an enterprise IT environment this is made up entirely of microservices. The latest release of the NGINX Controller makes it possible to manage application delivery across the broad spectrum of applications that need to be addressed within modern IT environments, he said, noting that in effect, it’s a one-size-fits-all approach to managing application delivery via a single fabric.

    As part of that effort, NGINX this week also revealed that NGINX Plus R16, an enterprise-grade version of the core NGINX load balancing software, has been updated to apply load balancing algorithms to microservices running on Kubernetes clusters, in addition to support for Amazon Web Services (AWS) PrivateLink integration.

    Finally, NGINX announced version 1.4 of Unit, an open source web and application server that support TLS encryption, dynamic reconfiguration via an API and experimental support for JavaScript with Node.js to extend existing support for Go, Perl, PHP, Python and Ruby languages support. Full support for JavaScript and Java is planned for 2019.

    In general, Rabsatt said it’s clear organizations that have embraced DevOps are the most advanced when it comes to the need to unify management of application delivery. In fact, much of the recent success NGINX has enjoyed as of late starts with developers downloading an open source instance of NGINX to embed within their applications. As those instances of NGINX start to proliferate across the enterprise, more IT operations teams become exposed to the rest of the NGINX platform.

    It may take a while for microservices-based applications to achieve enough critical mass to force organizations to rethink their approach to application delivery. But it’s now a matter of time before organizations need to decide the degree to which they want to deploy standalone application delivery controllers and service meshes for microservices applications instead of pursuing a more hybrid approach. NGINX is clearly betting on the latter, given the number of legacy monolithic applications that will be running for years.

    — Mike Vizard

  • DBmaestro DevOps Platform 7.5 released with PostgreSQL Support – DB2, SQL, Oracle, and PostgreSQL

    Manages multi-database environments for DB2, SQL, Oracle, and PostgreSQL

    BOSTON, MA, October 11th, 2018 – DBmaestro, the pioneer and leading DevOps for database solution provider announced today the launch of DBmaestro DevOps Platform 7.5 which enables CI/CD and release automation for PostgreSQL. PostgreSQL is becoming the preferred database for more and more enterprises and smaller organizations. It is currently ranked #4 in popularity amongst hundreds of databases worldwide (See more info at DB-Engines Ranking).

    DBmaestro’s DevOps Platform 7.5 includes database release automation solutions to streamline database changes with confidence and control while enabling companies to reduce the time to market for their applications. The fast adoption of continuous delivery and deployment methodologies to accelerate application development has created a strong demand for database release automation tools to prevent errors and downtime.  According to the 2018 DevOps for Database Report, 83% of companies have already embraced DevOps, while continuous delivery for databases lags behind, with only a 37% adoption rate.

    DBmaestro’s DevOps Platform 7.5 zero-friction solution provides the ability for DevOps teams and database professionals to manage multiple databases more easily, without having to change existing processes.  Providing an overarching solution for CI/CD adoption across platforms and operating systems including Oracle, DB2, Microsoft SQL Server and now PostgreSQL, DBmaestro meets the evolving database release automation needs of enterprises across industries and borders.

    “Our DevOps platform unleashes the power of PostgreSQL databases by enabling DevOps and database teams to implement DevOps best practices and accelerate time to market with a high level of confidence, minimal risk and maximum efficiency,” said Yaniv Yehuda, CTO at DBmaestro.

    DBmaestro will be demonstrating DBmaestro DevOps Platform 7.5 solution at DOES18  from October 22– 24th in Las Vegas, Booth #811.

    About DBmaestro

    DBmaestro brings DevOps best practices to the database, delivering a new level of efficiency, speed, security and process integration for databases. DBmaestro’s platform enables organizations to run database deployments securely and methodically, increase development team productivity and significantly decrease time-to-market. The solution enables organizations to implement CI/CD practices for database activities, with repeatable pipeline release automation and automatic drift prevention mechanisms. For more information, visit www.dbmaestro.com.

  • DBmaestro DevOps Platform 7.5 released with PostgreSQL Support

    Manages multi-database environments for DB2, SQL, Oracle, and PostgreSQL

    BOSTON, MA, October 11th, 2018 – DBmaestro, the pioneer and leading DevOps for database solution provider announced today the launch of DBmaestro DevOps Platform 7.5 which enables CI/CD and release automation for PostgreSQL. PostgreSQL is becoming the preferred database for more and more enterprises and smaller organizations. It is currently ranked #4 in popularity amongst hundreds of databases worldwide (See more info at DB-Engines Ranking).

    DBmaestro’s DevOps Platform 7.5 includes database release automation solutions to streamline database changes with confidence and control while enabling companies to reduce the time to market for their applications. The fast adoption of continuous delivery and deployment methodologies to accelerate application development has created a strong demand for database release automation tools to prevent errors and downtime.  According to the 2018 DevOps for Database Report, 83% of companies have already embraced DevOps, while continuous delivery for databases lags behind, with only a 37% adoption rate.

    DBmaestro’s DevOps Platform 7.5 zero-friction solution provides the ability for DevOps teams and database professionals to manage multiple databases more easily, without having to change existing processes.  Providing an overarching solution for CI/CD adoption across platforms and operating systems including Oracle, DB2, Microsoft SQL Server and now PostgreSQL, DBmaestro meets the evolving database release automation needs of enterprises across industries and borders.

    “Our DevOps platform unleashes the power of PostgreSQL databases by enabling DevOps and database teams to implement DevOps best practices and accelerate time to market with a high level of confidence, minimal risk and maximum efficiency,” said Yaniv Yehuda, CTO at DBmaestro.

    DBmaestro will be demonstrating DBmaestro DevOps Platform 7.5 solution at DOES18  from October 22– 24th in Las Vegas, Booth #811.

    About DBmaestro

    DBmaestro brings DevOps best practices to the database, delivering a new level of efficiency, speed, security and process integration for databases. DBmaestro’s platform enables organizations to run database deployments securely and methodically, increase development team productivity and significantly decrease time-to-market. The solution enables organizations to implement CI/CD practices for database activities, with repeatable pipeline release automation and automatic drift prevention mechanisms. For more information, visit www.dbmaestro.com.

  • CollabNet VersionOne and Parasoft Partnership Brings Automated Testing to Enterprise DevOps

    Atlanta and Monrovia, Calif. – October 10, 2018 – CollabNet VersionOne, a global leader in Enterprise Value Stream Management, Agile management, Git version control, and DevOps, and Parasoft the global leader in automated software testing and continuous quality, announce a new partnership. CollabNet VersionOne will integrate Parasoft’s automated testing suite within its Value Stream Management (VSM) offering.

    Developers can spend several hours a day on testing software manually. That siloed manual approach conflicts with the organizational goals of scaling Agile and DevOps, and orchestrating and automating workflows to establish value streams. This new alliance addresses that problem by integrating automated testing practices within their value streams to enable continuous integration and delivery.

    The initial integration will bring together CollabNet VersionOne Continuum, a DevOps release management and performance optimization product with Parasoft’s automated software testing tools, including its sophisticated analytics. Continuum will give users a single-pane view and control of their automated testing stages and results data, and it will connect the testing phases with the rest of the development workflow.

    “Automated software testing is critical for our customers to succeed with their most strategic development initiatives, and we are focused on helping organizations efficiently scale their testing practices to deliver quality software quickly, especially with recent innovations in machine learning and AI,” said Elizabeth Kolawa, CEO of Parasoft. “By integrating the deep code analysis and broad testing practices of the Parasoft tool suite with the CollabNet VersionOne DevOps solutions, we are able to provide the software development community with complete visibility into the quality of its value streams in order to release with confidence.”

    “This alliance reflects our commitment to the Agile community and DevOps innovation,” said Flint Brenton, CEO and President of CollabNet VersionOne. “With this integration, teams will have a single interface to execute automated tests, view test processes and results data that quickly reveal quality gaps, security issues, and other bugs and risks, while allowing them to see the relationship of their testing phases to other upstream and downstream development processes.”

    Continuum’s visual interface makes it easy for users to understand the progression of what is happening in the process of development. With the integration of Parasoft’s testing tools, Continuum users will be able to execute tests against the application being tested (including unit testing, code quality and coverage analysis, API and functional testing, and performance and load testing), and then access the analytics and results of these tools right in the Continuum interface, so the impact of testing practices on the workflow is visible to the entire team.

    “We help customers make software development and delivery a transparent well-orchestrated practice that remains consistently aligned with business objectives. Adding testing automation capabilities supports our vision to remove barriers to adopting Agile at scale, extending DevOps and establishing enterprise value streams. We are pleased to have a partnership with Parasoft because they share our goal to improve software development practices,” said Brenton.

    Share This: Learn about this exciting partnership bringing automated testing to Enterprise DevOps with @Parasoft and @CollabNetV1

    About CollabNet VersionOne

    CollabNet VersionOne is the Enterprise Value Stream Management leader that accelerates high value software development and delivery, while improving quality and reducing risk. Our offerings provide global enterprise and government market leaders a cohesive solution, spanning idea through delivery, that enable them to capture, create, deliver and measure the flow of business value throughout their application development lifecycles.

    www.collab.net

    CollabNet VersionOne is a Vector Capital company.
    Company trademark and logo details available here: https://www.collab.net/legal

    Follow us on:

    About Parasoft

    Parasoft provides innovative tools that automate time-consuming testing tasks and provide management with intelligent analytics necessary to focus on what matters. Parasoft’s technologies reduce the time, effort, and cost of delivering secure, reliable, and compliant software, by integrating static and runtime analysis; unit, functional, and API testing; and service virtualization. Parasoft supports software organizations as they develop and deploy applications in the embedded, enterprise, and IoT markets. With developer testing tools, manager reporting/analytics, and executive dashboarding, Parasoft enables organizations to succeed in today’s most strategic development initiatives — agile, continuous testing, DevOps, and security.

    www.parasoft.com

  • DevSecOps and Development: Making the World Safer One Application at a Time

    DevSecOps and Development: Making the World Safer One Application at a Time

    If you have been around software development much at all in the past five or 10 years, then you’ve certainly heard of DevOps and know it’s here to stay. And it is very likely that you have also heard the term “DevSecOps” even more recently. With today’s extensive proliferation of application capabilities being delivered through services—and all the inherent complexity that comes with the delivery systems for them—it’s no wonder that cybersecurity has moved to the forefront for many companies. In fact, according to research from Stratistics MRC, the current global application security market is growing at a CAGR of 23.4 percent and is expected to reach more than $10 billon by 2023.

    But it is one thing for there to be an interest in cybersecurity; it’s another thing entirely to implement it well—and that is where the conversation gets more interesting. Today, the name of the game in application security is all about bringing the role of the developer into the fold and equipping developers to code, fix and maintain security as part of the software development process. In an article on DevSecOpsDays.com, DevOps thought leader and author Jon Willis offers the following comments:

    Fast forward to February 2017. I was speaking at the RSA Conference in San Francisco and I started seeing for the first time people talk about security as an interesting new way of integrating it into DevOps. They were unapologetically calling it DevSecOps. They were talking about this in a way that included security as a systems (end to end) approach to the traditional DevOps pipeline.

    This was not the first time I had heard people talk about security and DevOps.

    The thing that most caught my eye was that this approach was clearly putting the ownership of security on the developer. I immediately thought back to Werner Vogels’, the CTO of Amazon, statement of “You Build It, You Run It”, back in 2006. However, what I was hearing this time was “You Build It, You Secure It”. This thing they were calling DevSecOps was describing a holistic and systems approach to security as part of the software delivery pipeline.

    This notion of developer empowerment being a critical aspect to success was something I heard again and again at the recent 2018 Black Hat USA Conference. You can read more about my experience at Black Hat in this DZone article. But how do you effectively bring developers into the security fold? That is what we will explore in this multi-part series.

    In this first article, we will focus on what I (and many others) believe is the single most important factor for long-term success: the organizational culture. And by culture I am talking about the day-to-day environment of the organization the developer is a part of, and how they are (or are not) allowed to do their work. A successful DevOps culture is one that promotes collaboration to foster innovation and speed delivery, and the following two sections of this article depict perhaps the two most critical components for a strong DevOps culture: leadership and trust.

    It All Rises and Falls with Leadership

    Many would easily agree with the notion that long-term success for DevSecOps in an organization needs executive support and buy-in—and they would be correct—but real success needs much more than just budget approval and a shifting of resources. It needs ownership. It needs visibility. It needs truth-telling and that is where leadership comes in. According to the PuppetLabs “2018 State of DevOps Report,” 64 percent of C-Suite respondents firmly believed that security teams are involved in technology design and deployment, but only 39 percent of actual team members agreed. Bridging that kind of a gap requires breaking down traditional silos and evolving for better communication and transparency. The same survey also found that high-performing organizations were 24 percent more likely to use automated security policy configurations—a clear indication of tighter cooperation between security teams and the operations teams maintaining production environments.

    So, what are some of the key ingredients of successful leadership in this space? Glad you asked. Here are some things to look for:

    • Balance: Is the organization able to balance lowering technical debt with new work?
    • Shared ownership: Does everyone see how they contribute to business success and how their role impacts it? Is security included in that?
    • Shared learning: As projects progress and complete, is information moving across teams and projects? Are there best practices, lessons learned, etc., that are communicated both internally and externally?
      • Another way to think of this one: Is the level of “tribal knowledge” in your organization getting reduced?
    • Shared Vision Goals: Does everyone see and understand what matters most? Do they know the core metrics and KPIs, and how what they do impact them? Can they see their own success and bottlenecks?

    To have great success, you need leadership that defines the key standards, actively facilitates learning and collaboration and then provides the freedom necessary for innovation to occur. And there is another reason why you need it: Great leadership builds trust. Let’s explore that next.

    Your Speed of Delivery is Directly Proportional to Your Level of Trust

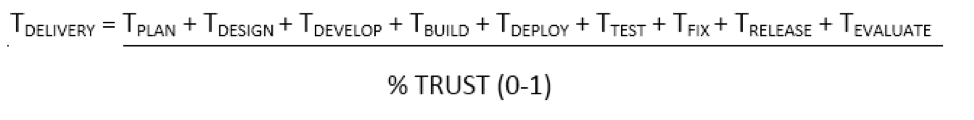
    The best depiction I have seen that correlates the speed of delivery with trust is this simple equation shared with me by DevOps Technical Evangelist Al Wagner from our mutual friend and Senior IT Specialist Lee Reid. It can also be found here. It simply states:

    Where “T” simply stands for time. In this simple equation, you can see that the HIGHER the percentage of trust is in the organization, the LOWER the overall value of the Time to Delivery will be, which is what we are all after. What that tells us is that today, businesses cannot tolerate a trade-off between speed and quality—you need both simultaneously.

    But how to you calculate trust?  In this model we are not talking so much about the work habits of the individuals as much as we are considering the outcome of each part of the process.  We  have to consider how often each of these areas “gets it right” versus how much we have to go back and rework.  Lee provides this example based on a client scenario:

    On a given project team the plan has about a 50/50 chance of being right, and the design is about 85 percent right, and the developers will get about 90 percent of the implementation right, and the testers have about 90 percent of the test cases right, and the release team has about 95 percent reliability of having the right stuff together to release, then your trust factor is something like

    .5 x .85 x .9 x .9 x .95 = 32 percent Trust

    Putting that back into the simple equation above, this level of trust means that your delivery time is three times longer than it could be.

    When my children were in elementary school and doing homework, I used to tell them that sometimes the best way to go fast is to go slow. The point was that if you wanted to solve problems you first had to understand them. Rushing to a formula or just trying combinations of numbers doesn’t work well and it ends up taking you twice as long to get done. This notion of trust and DevSecOps is similar and when you make the initial investment to build trust it can make a real impact.

    While it is true that adding application security to the Tplan and Tdeisgn parts of the process will initially increase those values, having application security as part of the software delivery process from the start—instead of at the end of a release cycle—will naturally cause the values for TDevelop, Tfix, and TEvaluate to shrink. This is largely because you are NOT having to go back to rework security into those areas midstream. It could also actually shrink Tplan and Tdesign over the life of the project for the same reason. In addition, the overall level of trust goes up because the risk that is associated with the delivered items decreases. We are more confident that artifacts are secure if vulnerabilities were identified early and fixed then.

    If you would like to learn more about how you can build trust, lower risk and make real business impact with application security, or to learn more about the potential impact of cognitive capabilities and artificial intelligence on your development efforts, download this complimentary Ponemon Institute study.

    — Rob Cuddy

  • OutSystems Infuses DevOps Processes into Low-Code Platform

    OutSystems Infuses DevOps Processes into Low-Code Platform

    OutSystems has turned its low-code platform into a framework for generating microservices that can run on-premises or in a variety of public clouds.

    Mike Hughes, senior director of product marketing at OutSystems, said applications generated using OutSystems 11 now can be deployed on both platform-as-a-service (PaaS) environments and container-as-a-service (CaaS) environments, including Amazon Web Services public clouds and the Pivotal PaaS based on open source Cloud Foundry software and CaaS platforms such AWS ECS, Azure Container Service, or as a set of Docker containers running on-premises.

    In addition, OutSystems 11 includes a set of monitoring tools capable of identifying issues emanating from within the applications and external dependencies, as well as a set of impact analysis tools that identify issues before an application is deployed. Those tools are critical elements of a concerted effort to apply DevOps practices and principles to the development of applications created using low-code tools, said Hughes.

    OutSystems 11 also now includes an entitlement model for controlling who can create and manage services and who can consume them, using a full entitlement model that extends to all applications and services.

    Finally, OutSystems has added support for automated risk assessments, granular access controls and activity monitoring of supplemental manual processes along with a revamped user interface.

    IT organizations of all sizes are trying to cope with a growing application development backlog by embracing low-code tools that can be employed either by professional developers to accelerate development or so-called citizen developers to create applications on their own. Legacy approaches to application development have created a gridlock issue that organizations are not going to be able to break without embracing a more modern approach to application development that combines the best of low-code application development platforms and DevOps practices, said Hughes.

    Hughes noted that more organizations than ever are trying to accelerate application development at a time when digital process transformation has become a much high priority. The rate at which new applications can be built, tested and deployed has a direct impact on an organization’s ability to compete, he said. The challenge organizations face is that much of the subject matter expertise required to build these applications resides in business units that have limited application development expertise. The central IT organization, conversely, typically has a limited number of developers available to work on applications at any one time. Rather than simply providing citizen developers with low-code tools, OutSystems is making a case for an approach to rapid application development that provides guidelines for citizen developers in a way that doesn’t create the equivalent of a black box that professional developers can’t later drill down into to determine how an application is behaving.

    It may take a while for low-code application development and DevOps processes to meld within enterprise IT organizations. But the more DevOps tools that come included with the application development frameworks being provided, the greater the chances DevOps processes eventually will pervade the enterprise.

    — Mike Vizard

  • Are Legacy Apps the Antithesis to DevOps?

    Are Legacy Apps the Antithesis to DevOps?

    Do you have an application marked with cryptic warning signs and a wealth of cobwebs that is running on legacy hardware hidden away in the back corner of your data center? If you’re in enterprise IT, chances are high that you do. These old platforms are often considered a bane to IT. More importantly, legacy applications can present a real headache when attempting to uplift the people, processes and tooling needed to embrace a hybrid cloud model.

    Providing self-service, orchestrated workflows and delivery pipelines are just a few signature attributes to constructing a hybrid cloud. Imaging trying to apply these ideas to legacy technology, where the interface requires using an archaic console and software that looks like it was written for Windows 3.1. It’s not fun and often derails any efforts to deliver services living in an on-premises software-defined data center (SDDC) or public cloud environment. It also splits up a team focused on working within the realm of a DevOps cultural model, because concepts such as infrastructure as code, stateless configuration and collaborative code check-ins crumble. For most folks I speak with, legacy applications remain with a small skeleton crew that keeps the lights running and the old hardware humming.

    Hybridity is a reality for most infrastructures rather than being purely in the public cloud or purely on-premises. This is where the importance of DevOps and embracing an API-first mentality is multiplied. Having an API-first approach isn’t necessarily about having a single code repository or a single application that does “all the things.” It is about leveraging APIs across multiple repositories and multiple applications to weave together a single, programmatic software fabric in which everything can communicate and integrate regardless of whether legacy or cloud-native.

    The way to end chaos induced by the complexity with hybridity is a progressive, policy-driven state with proper implementation.

    Here are four tips on how to integrate your legacy crew with your DevOps team to create a high-functioning hybrid cloud model:

    • Find tools that play well with others: Legacy applications do not have to be the anchor holding you back from adopting a DevOps strategy. Find solutions that treat legacy applications, modern applications and cloud-native applications as if they were all first-class citizens. Legacy applications tend to run on old OSes, including some that are no longer supported. Eventually this configuration becomes increasingly fragile, requiring manual care and feeding. Adopting an automation strategy can reduce risk associated with build, testing, deployment, remediation and monitoring.
    • Strive for simplicity; don’t create silos: Make sure the workflows that deliver services are applicable to the vast majority of use cases. Historically there has been little to no incentive to building mechanisms that are shared across the enterprise. Systems thinking advises that there are dependencies, but if you only improve one application in the cluster, there will be no benefit. The entire cluster must be addressed for successful progress. The use of RESTful APIs is turning tables, allowing for a single set of tooling across many applications, platforms and services. Share data across the organization; leverage APIs to streamline how the team interacts with legacy workloads by extracting data from the legacy architecture.
    • Embrace a one-team mentality: Don’t form multiple teams or tiers of teams. If the decision is made to adopt DevOps, then it must be embraced by the entire organization. As the old adage goes: “There are no legacy systems, just legacy thinking.” DevOps isn’t about developers and operations folks collaborating; rather, it’s about two separate silos becoming one team. Focus on improving communication and set aside time for learning.
    • Avoid infrastructure-specific solutions: Abstract storage and compute; work instead on the application layer and how to deliver services for those applications. Legacy applications often are coupled tightly to the underlying hardware, making it challenging and risky to manage any application component individually. This means maintenance and upgrades are incredibly time-consuming, difficult and even expensive. The adoption of infrastructure-as-code, whether on-premises or in the cloud, gives teams the permissions and tooling provision infrastructure on-demand. As you can imagine, not every legacy application can be easily migrated to this type of infrastructure, but many can.

    Using automation increases the organization’s agility by reducing human interaction and orchestrating dependencies across the organization. Self-service consumption of infrastructure further eliminates silos. DevOps is not incompatible with legacy applications, but it requires an organization to evaluate what this implementation actually means and how to embark upon this transformation. Never fear: You can still depend on a legacy application and embrace DevOps. It requires additional design considerations, elbow grease and a little bit of creativity. The fundamental element is to apply these principles in a consistent and efficient manner in the context of all applications, both legacy and modern.

    — Rebecca Fitzhugh

  • DevOps Chat: The New Security Breed with Veracode’s Mark Curphey

    DevOps Chat: The New Security Breed with Veracode’s Mark Curphey

    DevSecOps has changed the way developers approach security in their application development cycle. But it’s also been the source of confusion, as some developers grapple with understanding how DevSecOps is different from application security. Mark Curphey, VP of strategy at CA Veracode, is clued in to the differences, which he discusses in this DevOps Chat.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Alan Shimel: Hey, everyone. It’s Alan Shimel, DevOps.com, Security Boulevard, and you’re here for another DevOps Chat. Today’s DevOps Chat is all about DevSecOps, AppSec, what’s happening on the front lines. I’m joined by an old friend of mine, Mark Curphey. Mark is currently VP of strategy at CA Veracode. Hey, Mark, welcome to DevOps Chat.

    Mark Curphey: Thanks, Alan. Great to talk to you again.

    Shimel: All right. So Mark, let’s start off with this. I know you’ve fairly recently joined Veracode. Give our audience a little bit of your background and how you came to be where you are.

    Curphey: Yeah, sure. So misspent youth, went back to university late, did a master’s degree in information security, and wound up working for a bunch of banks in the city of London. Moved here to the states in 2000, then ran software security for Charles Schwab. So Microsoft were creating the SDLs. You know, sort of Gates had sent out the famous memo and I was doing the same for an online service basically at Charles Schwab. So that’s where I started. Then at OWASP, which some people sort of associate my name with, which is the Open Web Application Security Project.

    And since then I’ve worked at Microsoft around the security tools team and then I think with MSDN, the Microsoft Developer Network. I more recently created a startup called SourceClear which was focused on helping developers use open source code safely in the modern DevOps world. We were acquired by Veracode about five months ago. So I’m now the VP of strategy at Veracode helping the Veracode platform and how we really sort of work with DevOps and the new way of doing things.

    Shimel: Fair. Okay, so Mark, let’s start off with this though, and I think there’s some confusion out there with both security people as well as non-security people in terms of what’s the difference between AppSec and DevSecOps? Is one really just synonymous with the other? Is DevSecOps another name for AppSec? I don’t think it is. What do you think and how do you define the differences between them?

    Curphey: Well, certainly every vendor’s got a DevSecOps product these days, right? So it’s easy why people are getting confused. I mean I think the reality is the way you have to do AppSec in a DevOps world is fundamentally different to the way we’ve done it before. It used to be about educating developers, writing policies that people had to read, human processes to do final check off, things like threat modeling, you know, all of these sort of things. They kind of worked okay in a waterfall world were kind of modified a bit to work in an agile world. But, you know, DevOps is changing the game completely. So we’re in a world of automation, and, you know, the modern ways that we have to secure it are fundamentally different. So for me DevSecOps is about how do you apply security in this modern, you know, DevOps world and that’s predominantly focused around, you know, automation. What can you automate and, you know, how can we put automation in those pipelines that are happening so that security happens inline as code is created and it’s moved through the pipelines?

    Shimel: Fair enough. We talked pipelines. We talk left to right, Mark. You know, and Veracode is probably one of the leaders in this space when we talk about DevSecOps and shifting left and working. But I think what people want to know is really how does the security person or the security team work with the development team? It’s easy to say, but what does it really –

    Curphey: Sure.

    Shimel: What does it really mean?

    Curphey: Yeah. I mean, look, I think there’s a new breed of security people which is exciting to see. Like the old world that used to be the development team and then there were the security team. There were kind of the two separate teams. The security team needed to sort of bless things before they went into production, but we get appointed a data center and whatever. These days what you see is it’s all about velocity.

    So, you know, there are security people that are embedded into the security teams and they’re kind of acting like consultants and helping the dev team do security as and when it’s needed and make the right decisions without slowing things down. So instead of it sort of being this procedural thing where they were required to go through whatever a control grate, they’re just tired of the flow. That’s exciting to see because I think we’re seeing a paradigm shift of how that happens.

    Shimel: Yep, I think we are seeing a paradigm shift in this. So here’s going to be a question you’re going to say, “Alan, you’re crazy,” but Mark, does it make a difference? Is it definitively improving our security here?

    Curphey: Yeah. First, Alan, I’m never gonna call you crazy, but that’s good to know, I think.

    Shimel: I figured you would.

    Curphey: No, but look, I mean like, for sure, like think about like we all know what happened with Equifax, right? Like biggest data breach in history, result of open source that was insecure and hadn’t been updated. That problem is solvable and it’s solvable at scale in a pipeline. So what we were doing at SourceClear – I don’t want to turn into a product pitch in any sense, but we were basically trying to close the loop of this library is out of date, issue the pull request, figure out if it’s going to break things, and if so, update it. And the developers loved that, not because they’re fixing security but they’re fixing the dependency hell problem.

    So we’ve not been able to do that before because, you know, we hadn’t been injected directly in the pipelines. So these are opportunities that really make a difference and companies that implement these tools like us and there are others around, totally can avoid the whole Equifax thing. It’s not a case of like no one got notified or no one knew. Like it happens automatically in the pipeline. So there are great opportunities to do things like that.

    And I think moving forward we can also look at things like are people using dangerous APIs? Are they calling, you know, external services that we don’t want them to call? Like to a large extent the pipeline has become the new firewall and it’s a place where we can put controls, inspect the traffic, and decide what we want to allow and what we don’t want to allow which is a great place to be.

    Shimel: I agree. I agree there. So Mark, I guess where I wanted to go next with this is a lot – again, I’m a man who lives with a foot in each world, right? I spend a lot of time with my security friends and colleagues that I’ve known for years and years and years, but as part of DevOps.com I’m out speaking to developers an awful lot, right?

    Curphey: Mm-hmm.

    Shimel: And some of the questions that I hear from both sides is, okay, you can’t serve two masters, there can’t be two people in charge. How does the day-to-day of this flow? You know what I’m saying?

    Curphey: Yeah, no, for sure. I mean look, the reality is in all organizations the digital transformation and everything else happens that it’s all about value creation and the value is created by developers. So they’ve been empowered to choose their tools. They’ve been empowered to figure out which process allows them to innovate faster and all those things. With that we’ve seen the rise of the cloud and everything else. So it can’t be an us or them scenario. It’s how do you support those developers on their mission to change things and create this digital transformation? So the old ways, you still see it but you still see the old school of security people saying no and stopping people; but those battles are not going to be won. It’s about how do we help people move forward at the right rate.

    I mean I kind of equate it like someone was saying the other day, like similar to autonomous cars, like you’re not going to stop them. Like figure out how to make them work properly, safely, and securely. But if you don’t like it, you’re not going to stop that, have that technology happening and being created so you’ve got to embrace it. That I think is the philosophy that is going to win out the day.

    Shimel: Fair enough. I don’t disagree with you there, Mark. Let’s talk a little bit about what you see near term and maybe a little bit longer term in developments here that, you know, our listeners, you know, could fundamentally change their day to day. Where do you think we’re heading?

    Curphey: Yeah, sure. So, you know, I think machine learning and artificial intelligence and big data were sort of touted and, you know, the hype cycle kick off and, yeah, people didn’t always deliver on that. But there are exciting things happening in that which allow us at scale and at speed to do things that we couldn’t do before. So a good example of that is in the security world most of the vulnerabilities no longer exist in the CV system open source code. They just can’t keep up with the scale. We’re releasing thousands of libraries. In the DevOps world, developers find things, fix them, push them out. They don’t go back to monitor and publish these vulnerabilities, etc.

    But the great news is, you know, there are big data systems, machine learning that can process that data and we can identify those things at scale. Those same kind of techniques have been applied by Google and the Android App Stores and things like that. So that application of like that modern tech I think has great opportunities for us to do things which we’ve not been able to do before, and you’ve certainly seen some of the big vulnerabilities that have been released have been a result of that stuff coming out.

    Shimel: Got it. Got it. I just had my phone ringing there. I apologize. Mark, let’s, if I can and if you’re not too shy about it, I doubt you will be, let’s talk specifically a little bit about Veracode.

    Curphey: Yes.

    Shimel: You know, you’ve been there five months. What do you see? What gets you excited there in the morning?

    Curphey: Yeah. We had loads of places to sort of land. We came to the conclusion that people wanted to have less tools than more. So they wanted to buy a suite. When you look around, what the Veracode guys had done is built sort of best-in-class SAST and it started working on software composition analysis. We had best-in-class software composition analysis. So it made sense from that perspective.

    Also as you know, the heritage of the company, you know, it isn’t a fly-by-night company. It’s Chris Wysopal and Christien Rioux, right? These guys were in the loft, right? So that legendary around the place. So the company has this real DNA about it around security. So for me it’s kind of this exciting security DNA in the company embracing the way we build modern software. So that’s what attracted us to join forces. We’ve been extremely excited since. A lot of exciting things happening that for sure will start to come out of it at the other side no doubt.

    Shimel: I agree with you. I actually have Chris on a panel we’re doing on DevSecOps next week. I’m really excited to have Chris as well as Dave Duncan from CA, I think is on the panel with us.

    Curphey: Right. Right.

    Shimel: So Mark, you know, running out of time here, but I wanted to talk a little bit more about, you know, you came into Veracode, as you said, about five months ago via the acquisition. There’s a lot of people out there seeing a lot of buying and selling, M&A kind of stuff going on in especially around DevSecOps and DevOps related companies. I mean obviously a rising tide lifts all boats and there’s consolidation going on, but is there anything else at play that you’re seeing that’s kind of driving this stuff?

    Curphey: Well, I mean, you know, in the place that you look on the horizon is actually where the dev tools are going. So you know, if we look at companies like AWS, it’s not really just a hosting platform. It’s a full tool suite, right, of everything from machine learning libraries in the cloud to real-time databases and things. Google and Azure are building the same. As we start to think about like what is a next generation of developer look like, they’re likely to use an IDE and a browser. It’s not going to run on a desktop anymore. And you know, co-changes happen and everything happens up in the cloud. So I think there are a lot of exciting things happening there and how do you integrate security into that world for sure. So that’s a lot of the stuff that I’m focused on. Then you can get scaled I think.

    Shimel: Got it. Got it. Mark, you know, I appreciate you talking to us today. I think we’re about out of time. But for people who want to get more information on what’s going on, veracode.com obviously, correct?

    Curphey: Yeah, veracode.com is an excellent, well-trafficked blog with Wysopal and various other people and myself contributing to it which is great and we’re out speaking at conferences and talking about some of the both current work and sort of some of the futuristic stuff as well. So love to engage with the community and the industry for sure.

    Shimel: Perfect. All right. Hey, Mark Curphey, VP of Strategy, CA Veracode. Thanks for being our guest in this episode of DevOps Chat and we look forward to having you on again soon.

    Curphey: Yeah, great, Alan, thanks a lot. Great to reconnect and look forward to doing so the next time.

    Shimel: Okay.

    Curphey: Take care.

    Shimel: This is Alan Shimel for DevOps.com. You’ve just listened to another DevOps Chat.

    — Alan Shimel

  • Splunk Aims to Trigger DevOps Processes

    Splunk Aims to Trigger DevOps Processes

    Splunk this week at its .conf18 conference continued a campaign to extend the reach of its operational analytics platform into the realm of DevOps through a partnership with Puppet.

    Spunk also announced the 4.0 release of Splunk IT Service Intelligence (ITSI), which extends a platform for managing IT using machine learning algorithms by integrating it with incident management software Splunk gained via its acquisition of VictorOps. Other new capabilities include support for a set of key performance indicators (KPIs) for tracking metrics such as application workloads and the ability to do root cause analysis on any event the machine learning algorithms predict.

    Andi Mann, chief technology advocate for Splunk, said the alliance with Puppet furthers Splunk’s ambitions to be a primary source of data used to inform automation frameworks that are at the heart of any set of DevOps processes. Over time, Splunk will continue to expand its DevOps partnerships with an eye toward being the analytics platform used to trigger automated processes using frameworks developed by Puppet and others, he said.

    At the same time, Splunk continues to develop orchestration capabilities of its own based on technologies it gained via its acquisition of Phantom. While that orchestration software primarily is used today in a security management application, Mann said Splunk is now looking at applying that software more broadly, as it encouraged developers to build applications using a Splunk Developer Cloud now in beta.

    Mann said that when it comes to machine learning in IT operations, otherwise known as AIOps, the most challenging task ahead is establishing trust. IT professionals are not going to sanction a “black box” approach that doesn’t enable them to see how a machine learning framework is determining what to automate. Because of that issue, Mann said, providing a root cause analysis capability in ITSI is critical.

    The next big issue facing organizations, he noted, is improving the quality of the data being used to inform a machine learning framework. One of the benefits of the DevOps movement is that, as developers take responsibility for both building and running applications, more of them are paying attention to how log data is being created. Mann said the notes developers leave within an application on how to resolve issues are becoming more detailed, a process that Splunk refers to as “semantic logging.”

    Mann noted the goal is to create a closed-loop system where every IT issue eventually creates a ticket in a DevOps system for developers to address. The bridge between those processes will be the chat capabilities provided by the VictorOps incident management platform. In fact, Mann said Splunk is moving from being a provider of log analytics software to being a provider of a continuous monitoring solution that analyzes data both stored in logs and in near real-time using a Splunk Data Stream Processor, which is currently in beta.

    It may take a while for that loop to be completely closed. But it’s clear that many of the tools that IT operations teams rely on today are becoming increasingly DevOps-friendly.

    — Mike Vizard

  • Log Management: What DevOps Teams Need to Know

    Log Management: What DevOps Teams Need to Know

    One of the most important shifts of this decade is the rise of interconnected data across distributed systems. This explosive growth not only sparked the need to rethink cloud and global IT strategies, but it also disrupted traditional development, DevOps and ITOps practices. These changes are pushing requirements for higher-velocity development of features and products—together with more responsive support requests—onto technology professionals. These new requirements have prompted teams to evaluate new tools and agile processes that help support the needs of a competitive modern business.

    Regardless of the pace of change within your group, basic functions such as infrastructure monitoring are crucial to operating production applications. At this new speed of business, concepts such as observability are important for enabling successful deployments with fewer user interruptions—not only in production, but also in the early stages of your continuous integration/continuous delivery (CI/CD) pipeline. As part of “shifting left,” log and event management in your CI/CD pipeline empowers developers to monitor and observe application behavior before releasing it to production. While some might say this adds additional layers of process, time, effort and due diligence in dev environments, it can help you evolve your organization’s fundamental software development behaviors while reducing preventable issues from post-deployment into production. It can create a smoother, more seamless user experience and reduce the need to fight fires or rearchitect your solution after the application is live in production and at scale.

    Setting the Testing and Dev Stage

    The rapidly evolving technology landscape has increased the need for log management and observability across distributed systems and containers. Changes to how applications and services are created, the ability to deploy applications across combinations of global logging-as-a-service (LaaS) providers and the pervasiveness and volatile lifespan of containers, along with the capacity to build services using various development languages, has increased the need to collect, monitor and trace data points across connected systems, which provide critical end user-facing value.

    Traditionally, many considered log management a tedious task because each instance of a new server required you to run a search command across the logs local to that server. That approach isn’t scalable when every cluster of more than 20 servers is built up in minutes, and each application has independent logging formats. In this scenario, you’d need to run 20 individual searches across multiple systems, compare timestamps across servers residing in different time zones and so forth. With the decreasing cost and increasing prevalence of containers and virtual systems, the number of systems running within a typical organization has grown exponentially as the business prospers.

    In addition to increased usage of virtual systems and containers, independent scrum teams of developers can build in parallel using technologies which are the best fit for the services they are producing, while also sharing environments for builds, staging and production. With these distributed services, aggregated log systems can quickly determine the root cause for debugging their application’s errors, exceptions or performance bottlenecks. A log aggregation system can reduce the element of “personalization” that can often happen when developers are using different technologies with various logging formats, and also reduces the noise by filtering out information that delays the team’s ability to find the source issue. This can cause confusion or slowed productivity when one developer is left to understand another’s non-standardized, yet shared, workload.

    The reduced cost, increased collaboration and prevalence of container services are collectively driving an uptick in virtual environments and containers, often requiring more logs to be created in testing and dev environments, which can force organizational shifts to enable full observability across their infrastructure.

    The 3 Pillars of Observability

    Businesses are in the midst of a shift toward adopting these principles—the three pillars of observability—and using a three-pronged method of monitoring that takes data from several vantage points to depict a more accurate and consumable view of overall health and stability:

    1. External Monitoring: An example of this is health checks run against your internal and external applications and websites to see the “digital experience” of your users.
    2. Metrics and Distributed Tracing: This enables you to trace communications between applications distributed across systems/containers to identify errors and exceptions from your applications and resolve latency quickly.
    3. Events and Logs: Data, which helps provide contextual information about events, enables you to identify issues in the code when combined with information from the first two pillars.

    The above types of information are critical to DevOps to provide elastic and resilient services. Bringing application, system and infrastructure events into logs together with external monitoring and metric collection is quickly becoming the standard. With powerful log-parsing features such as live-tail search accessible from a web browser and the ability to visually pair log insights with added health metrics, the real value of log data is made apparent with little effort.

    Site reliability engineering (SRE) is another area where significant evolution has occurred. ITOps has always been asked to react to fire and run from fire to fire. The evolution from ITOps to DevOps to SRE is forcing the alignment of different types of data to be used very early in a CI/CD pipeline, and enabling SRE teams to get involved in architectural discussion at project inception instead of in the latter stages or at release. The SRE is more involved in monitoring, understanding the development and architectural principles used to develop application services and build in automation, and high availability and circuit breaker patterns from inception.

    This approach has allowed teams to be proactive and responsive rather than reactive. It has equipped our teams (which keep our business running successfully and our customers loving what we do) with the ability to focus on being scalable, elastic and resilient. Instead of troubleshooting systems in production, we auto-scale and replace to minimize disruptions and investigate that incident offline when possible.

    Best Practices

    Given the increasing pace of application development required to support the needs of the business, the spread of containerized applications and virtual environments and the emergence of new disciplines for observability (due to the lowered costs and increased reliability), log and event management has become a critical aspect for all involved in building, supporting and even using mission-critical applications. It’s moving to a defined area where logs should be compartmentalized, and access control should be defined:

    1. Compartmentalizing Logs: Critical as a best practice so we can differentiate development, staging and production environments and segregate logs based on practical grouping. Using a log aggregation service provides you with a consistent experience and a common set of capabilities across all your environments.
    2. Access Control: Another best practice that should be implemented more broadly; for example, developers don’t need access to all of your production logs if approximately 95 percent of their work happens prior to reaching production environment. In other words, even though tech pros are working to “de-silo” log management, we still want to silo access control and manage visibility. This can also help to ensure personally identifiable data (PII) isn’t exposed to anyone it shouldn’t be.

    Looking Toward the Future of Log Management

    As the landscape evolves and best practices become more defined, we should expect revitalized strategies with elevated expectations for the traditional scenarios where basic/free monitoring is leveraged. While the pillars of observability are leveraged more broadly in the ITOps and DevOps communities, we’ll be able to move more efficiently from an end user-facing incident—for example, an application error traced across distributed systems—straight into the logs to find the specific error causing the issue. We’ll be able to see greater correlation between logs and other custom metrics, as well as much broader use of these techniques outside of production environments.

    DevOps teams need an intuitive event and log management system that is as de-siloed as we are. No longer can log management systems be relegated just to one on-premises storage system or one virtual environment; they need to fit the reality of how work is increasingly done today and will be in the future.

    — Keith Kuchler