Tag: DevOps

  • DevOps 2022: The Year That Was and Wasn’t

    DevOps 2022: The Year That Was and Wasn’t

    We will be wrapping up our DevOps coverage for the year by the end of this week. It’s hard to believe that another year has gone by. The gravitational lensing of COVID-19 makes it hard to see the progression of the last nine years here at DevOps.com. Things seem to get a bit hazy looking back. However, 2022 was certainly one for the record books in ways both good and bad. 2022 saw DevOps, our community our countries and our world pushed and pulled in directions we would not have imagined just a few short years ago. To understand what happened in DevOps in 2022, we need to account for several macro factors that played outsized roles this year. They are:

    1. COVID-19: It’s still here; still killing hundreds of people every day. While some in the U.S. and Western Europe have “moved beyond” it, COVID-19 is still draining our resources, sucking the air out of the room and impacting not just the economy but how we interact with each other individually. In the next few months, I am afraid we will see the 1.4 billion people of China experience a backlash as they move away from zero-COVID policies. Not to mention the other viruses and diseases that are circulating.
    2. War: When I was a young boy, I remember a popular poster/sticker that said something like, “War is not healthy for children and other living things.” That’s still true; it’s not healthy for the economy, either (unless you sell ammunition). The human toll of the war in Ukraine is heartbreaking in the present moment, and the toll that this war will take on the once-healthy tech sectors in Ukraine, Russia and the rest of Eastern Europe also will be felt for a very long time.
    3. Inflation: Again, I am transported back to my youth as inflation rears its ugly head and puts its foot on the throat of our economy. Sometimes I wonder if the Fed and other central banks won’t stop raising interest rates until the economy is good and dead, but their fear of inflation is almost genetic. While recent signs point to a potential peak, we still have a long way to go and the possibility of more interest rate hikes ahead of us. These will continue to make it harder to raise money and put a crimp in companies’ budgets. That means layoffs and budget cuts; projects cut or pushed out. We haven’t seen disruption like this in tech for more than 10 years. But for those of my vintage, we have seen cycles like this before. This too shall pass.
    4. Hate: Is it me or has the whole world gone crazy with tribalism, nationalism, racism, antisemitism and a bunch of other “-isms”? We seem to be ripping ourselves apart from the inside out. I don’t have a clue how to combat this on a macro level, but I pray every day that things get better.

    With these four horsemen of the apocalypse riding among us, you may think that I am not very bullish on DevOps now and in the future. But you’d be wrong. Like the little boy in a room full of horse manure, I remain very excited because I know there must be a pony around here somewhere.

    DevOps has continued to evolve, continued to mature and has become an indispensable part of today’s modern software factories. Like their own version of Marvel’s Avengers or DC’s Justice League, DevOps, along with cloud-native, SRE, Agile, CI/CD, DevSecOps and dare I say it, platform engineering, are wielded by IT teams around the globe to continue to push forward as we digitally transform our businesses and the very fabric of our lives. That is what gets me up and out of bed every day and makes me excited to come to work.

    While some marketers are busy running around printing stickers and shirts proclaiming that DevOps is dead, nothing could be further from the truth. Look around—as far as the eye can see, DevOps is everywhere. As we explored in our DevOps Experience virtual event in October (the sessions are still there for you to watch on demand), DevOps is everywhere. It is at the edge; it is in the “connected things”; it is inherent in technologies like WebAssembly (Wasm) and DevOps is distributed.

    In 2023, I think DevOps at the edge, the DevOps of things and Wasm will be huge areas of growth. I realized that some of these folks claiming that DevOps is dead are trying to say platform engineers will replace DevOps engineers. But like Darth Vader trying to strike down Obi-Wan, all they are doing is making DevOps stronger than ever. You see, DevOps was never about DevOps engineers; it’s not about one role or one individual. In fact, some of my best friends helped kick off the DevOps movement and they’d react quite loudly when they heard the term DevOps engineers. DevOps is about building, maintaining and managing our software and applications. It’s a way of thinking about how we can go faster, be smarter and achieve better quality. It’s not about a particular tool you use or the role you play on the team, it’s about the fact that you have a team.

    So, what does 2023 have in store for DevOps? More of the same, I think. DevOps, along with all of the associated frameworks and technologies, will continue to allow us to do more and do it faster and better. As I think about the coming year, I am very excited about the potential for ML and AI and I think they are going to have an outsized role in allowing us to be more successful. I think the novelty of these technologies has worn off and we will get to the productivity phase. I remember interviewing Luke Kanies years ago; he told me that one day software would write software. I asked him when he thought this might happen, and he said maybe 2035 or so. I think we are on track. Much like ChatGPT and Jasper’s impact on copywriting, AI won’t take the place of developers. But it will free them of some of the mundane, repetitive chores they do now.

    I think we’ll also see an emphasis on feedback loops and iteration. I think automation, ML/AI will contribute to this in a big way. We have put so much of our DevOps emphasis on the development, integration and deployment of software. But observability allows us to see patterns and use cases as never before. We need to incorporate those findings into the next revision of our software. This is going to be a big story in 2023. That old infinity loop model for DevOps will rise to the top once again.

    Thank you for all of the support for DevOps.com this year and over the past few years. I hope this holiday season finds you and yours healthy and happy. Merry, merry. Happy, happy. See you in 2023.
  • The DevOps Workflow is Broken. Here’s How to Fix It

    The DevOps Workflow is Broken. Here’s How to Fix It

    While great progress has been made in bridging the gap between developers and operations engineers, fundamental differences in roles and responsibilities, alignment, and access to information hinder further progress. 

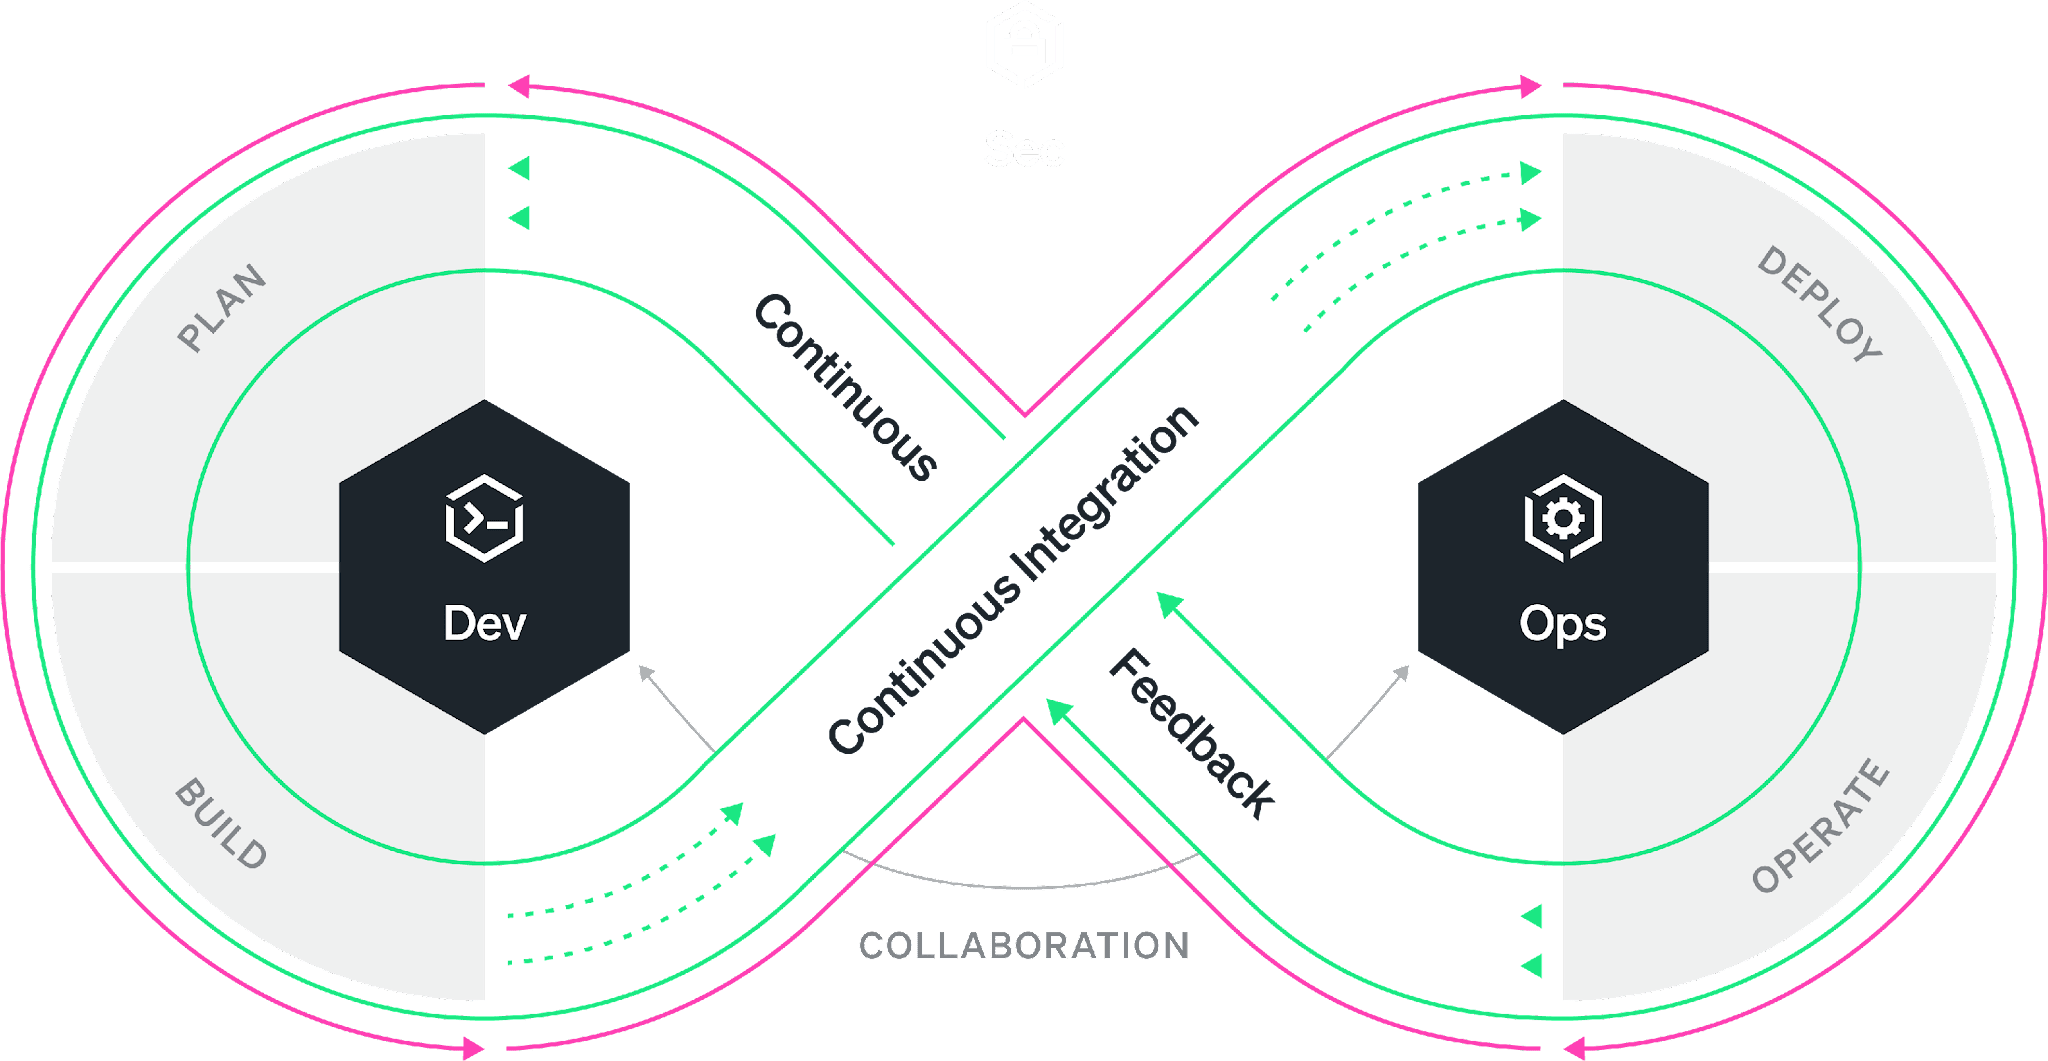
    Everyone is familiar with the DevOps infinity loop: This is an ideal workflow where every stage of the software development life cycle feeds into the next. While the philosophy is well understood, organizations have worked on bringing developers and SREs closer together under the DevOps banner. The reality is most of the time, the DevOps infinity loop is broken. Developers continue to focus on building features without the benefit of data-driven insights that production data can provide. Developers often “push and pray” without fully understanding how their changes will affect performance and the user experience. As a result, companies miss the opportunity to improve products faster and delight the customer sooner.

    According to Gartner, 90% of DevOps initiatives will fail to fully meet expectations. And yet, the global DevOps market, which accounted for $7.3 billion in 2021, is expected to reach $37 billion by 2030. So to summarize, we’re all spending billions of dollars on the implementation of initiatives that are expected to fail in some meaningful way 90% of the time. The question is: What is failing and what can be done about it? 

    As the DevOps toolchain continues to expand, collaboration across tools is difficult and success depends on your organization’s ability to simplify and automate while achieving alignment. Developers use a variety of tools from various vendors in their daily work. The most widely used are VS Code from Microsoft, Jira from Atlassian and Slack from Salesforce. The most popular code hosts/repositories include GitHub, GitLab and Bitbucket. Bridging the gap are CI/CD vendors such as Jenkins and CircleCI. Ops engineers typically rely on other vendors for their daily work, such as New Relic, Datadog and Dynatrace. So, how do we ensure that all stakeholders in the SDLC have access to all the relevant information simultaneously, understand the objectives and get an integrated perspective of the different inputs and workstreams independently of the tools used?

    There are three essential areas that DevOps initiatives must tackle to create alignment, collaborate successfully and streamline workflows. Let’s tackle each of these areas individually.

    1. Collaboration. The first step is good collaboration. Most organizations rely on Slack or Microsoft Teams for this purpose, but they are both suboptimal when it comes to collaborating on code and incidents that point to code. Having code and data at the center of DevOps collaboration ensures that everyone has access to the information needed to tackle issues, reducing and even eliminating differences of opinion in the process.
    2. Visibility. Second, ops engineers and developers must have visibility into the performance of applications across the entire tech stack. These three barriers can occur in different aspects of an organization’s operations and their impact can limit the team’s ability to deliver value to the customer just as much as workflow inefficiencies. Visibility helps the organization reach alignment on common objectives.
    3. Context Switching. Third, given the number of processes and tools involved in a successful DevOps implementation, it’s important to work toward reducing context switching and integrating tools within established workflows. Integrating collaboration, tracking, history and observability into a single pane of glass can greatly improve clarity and time to resolution.

    For DevOps teams, increased velocity and transparency are always worthwhile pursuits. However, it’s important to avoid myopic focus on workflows when other nagging problems could be hiding in plain sight.

    By committing production telemetry, developer teams can adopt an objective, data-driven approach to software engineering—saving time and avoiding potentially misguided approaches based on opinions rather than facts. Visibility, transparency and velocity can help engineering teams meet ever-increasing requirements and provide their organization with the best possible business outcomes.

  • Navigating the MLOps Revolution: Three Missteps to Avoid

    Navigating the MLOps Revolution: Three Missteps to Avoid

    With nearly 60% of businesses set to adopt MLOps by 2024, this function has quickly established itself as an indispensable part of the enterprise technology world. And with computing needs rapidly expanding as digital transformation efforts continue, the growth of the MLOps market is unlikely to stop anytime soon.

    That said, as with any emerging technology–particularly something as powerful as MLOps–there is no shortage of potential pitfalls that businesses and their tech teams can fall into if they move too quickly. More importantly, these missteps can have significant impacts on a company’s ability to generate revenue and optimize performance.

    With that in mind, below are three of the biggest mistakes that companies tend to make when adopting MLOps.

    Jumping in Without Testing the Waters

    If you doubt your MLOps maturity, you should probably wait. One of the biggest factors that undermine MLOps adoption and long-term success is that companies jump in before they are actually ready to adopt the technology. This not only leads to MLOps feeling like a burden but also often devolves the customer-vendor relationship into a transactional sales relationship rather than what it should be: a partnership. Onboarding technology needs to be a give-and-take process with ongoing dialogue between the customer and the vendor. If not, vendors – even the most ethical ones – have to rely on partial situational intelligence and guesswork to offer solutions that may or may not address the problems and deliver results. The best way to overcome this is for companies to map out exactly what MLOps challenges they are up against, what barriers are present, and also the outcomes they are looking for. With these key components understood and agreed to in advance, not only can companies make sure they are getting the best vendor partner, but the vendor can then provide much more tailored guidance.

    Misunderstanding What MLOps Actually Is

    There is a tendency among new adopters to distill MLOps down to the idea that it is made up of two components: Storage and compute. Yes, these are two significant elements of the MLOps equation, but this view is a massive oversimplification. Also, if it is not clarified at the outset, this misperception can lead organizations to feel overwhelmed by MLOps and make adoption less “sticky” as a result.

    The fact is, MLOps is composed of numerous pieces–from experimentation to deployment–that each come with their own specific nuances. Each of these parts is interconnected to the next and can derail MLOps results if not properly planned for and maintained. In addition, making sure that every necessary component is functioning the way it should in order to meet the needs and expectations of each client takes time. So businesses and their broader DevOps teams need to be prepared to exercise patience if they have any hopes of successfully adopting MLOps in a way that is geared towards long-term sustainable results.

    Not Realizing the Amount of Iteration MLOps Takes

    When looking at projects from a traditional DevOps perspective, there is a common belief that if a project is stable enough to get it to DevOps, it is ready for production. With MLOps projects, however, this simply isn’t the case. In comparison to DevOps, MLOps is prone to evolution – meaning that iteration and reiteration are incredibly common. For example, in the midst of the MLOps process, companies will want to iterate over the existing process, sometimes at a much more frequent cadence than their software release cadence. This means that there is greater ongoing contact and collaboration between MLOps teams and other teams. This interaction stands in stark contrast to traditional DevOps projects where once production is complete, developers hand over the keys and are essentially hands-off. Businesses and their traditional DevOps teams need to become comfortable with this new way of doing business and build in the flexibility and leeway to make sure that while their MLOps is able to function correctly and grow, that it does so in a way that works for them.

    Businesses are right to be excited about the prospect of adopting MLOps. However, to hit the ground running and deliver impact over the short, medium, and long term, it is essential that companies deploy a comprehensive strategy to ease onboarding headaches and make the process as seamless as possible. And by keeping these key missteps in mind, businesses can do just that.

  • Decidability: SLOs to Measure Quality Attributes

    Decidability: SLOs to Measure Quality Attributes

    You may be familiar with the “-ilities”–the quality attributes that define a system’s so-called “non-functional” parts. One that isn’t on the list is decidability, which is the ultimate quality attribute because it focuses on what truly matters to your team and your customers.

    You can’t do it all. Fast, cheap and good? Here in the real world, we have tradeoffs. Software is the mouth that keeps on eating, but it isn’t a digital free lunch. When we decide what not to do, we bring greater clarity and productivity to the team.

    Of course, the world is full of “shoulds.” We should make our product accessible, we know. It should be secure; it should be reliable. Of course. But how do you decide the limit of your shoulds? To enable decidability, you need context. To gain a contextual understanding of your most critical quality attributes, you must talk to real people and reason about your situation. There’s no other way.

    New Design, Wrong Decision

    I had an eye-opening experience that demonstrated firsthand how quality attributes don’t necessarily deliver business results. Six years ago, I was working on e-learning software for public schools. One of the main problems was user management. We were selling to massive institutions that often had only one administrator responsible for onboarding all the users across hundreds of schools. While school was out, they had to enter data for the schools, create classes and assign teachers.

    Once we had a design for improving the workflow (luckily, before implementing it), we took the mockups to a customer to show the fancy ideas we had built. They surprised us by showing us “what it looks like for them”–a spreadsheet! They were copying/pasting everything by hand.

    So we asked them, “What if we gave you a way to upload the spreadsheet? Would that work?” And, of course, the answer was yes! So we scrapped our plans to build a fancy form and made a drag-and-drop input field to validate and upload the sheet. The decision was clear.

    Measuring Decidability

    How do we measure the critical business drivers and turn them into decidability? The closest answer I’ve found is service level objectives (SLOs). These take the fuzzy -ilities and turn them into metrics and goals that can quickly inform decisions.

    SLOs are a universal tool for measuring quality attributes from an indicator expressed as a proportion of “good” events for a given quality like reliability or scalability. Decidability comes from aggregating the SLO data across your services, geographies, user groups and quality attributes over time.

    Comparing an indicator to a particular goal (tuned over time as the business and engineering context changes), we can derive an allotment of allowable “bad” time or events–an error budget. Setting an error budget for reliability, performance, scalability, etc., allows you to decide how poorly your service can operate and still keep customers happy. Further, you can find the breaking point of user behavior and defend your service proactively from violating the quality attributes you expect.

    Technical debt inevitably stems from all the -ilities you should focus on but couldn’t quite get to, given your situation. Some technical debt is deliberate and even prudent. To tackle technical debt, you must decide which new features to put on hold to make space in the roadmap. SLOs provide a data-driven baseline to make this decision quickly and accurately by telling you when your -ilities are within error budget or out of whack.

    Scaling Decidedly

    You might start on a small, single-purpose project that’s rarely used. But if that changes, you must decide how to invest, redesign and maintain it. Suddenly, you might care about performance, scalability, security and the rest. First, you need decidability so you can prioritize your work. So you gather the people together who care about the service, and you start to think and talk and stack rank. You use your instrumentation to build metrics, set clear goals and do what it takes to keep the system running within expectations.

    Automating action based on error budgets is the magic of setting SLOs. They aren’t just for sophisticated, highly available services. Error budgets are extremely valuable in systems when you aren’t sure what to do. SLOs create decidability in all the trade-offs of all the quality attributes and the functional needs of the app or service you’ve carefully built.

    If you put decidability first, the rest will fall into place.

  • From Frontend to Full Stack: How I Leveraged Modern Dev Tools to Make the Leap 

    From Frontend to Full Stack: How I Leveraged Modern Dev Tools to Make the Leap 

    A few years ago, I had an idea about how to make publishing recipes on the internet more accessible and profitable. As a front-end engineer-turned-product manager, I could write code as long as it involved JavaScript. But I needed someone who could handle the whole stack, especially the back end—you can’t build a platform with frontend tools only. So I searched for a technical co-founder, poked around online forums and talked to friends. Eventually, I found a candidate (let’s call him Tom) who seemed like a good fit. He’d built a recipe app in the past and was comfortable with both the front and the back end. It seemed great. We struck a deal and dove in.

    Tom started building the API and database while I made prototypes with a no-code builder called Bubble. I loved using Bubble. Without writing any code, I could build things fast and see what I was creating. Eventually, though, there were too many limitations with the no-code approach, including the lack of a Git repository for version control and history. So we decided to switch to full code with React Native mobile apps. 

    A few years prior, I’d switched career paths and became a product manager, but it had been a while since I had dug deep into writing code. And although I had a background in React, I felt insecure about building the frontend of a whole web platform on my own. But alas, you do all sorts of scary and undesirable things when you’re a startup founder!

    After jumping into it, though, I quickly remembered that I really enjoyed coding. I picked up React Native pretty quickly and started building screens. Tom took care of the data while I took care of the UI. All was good.

    Well, all was good until it wasn’t. We were a few weeks away from launch day and were finishing up. We even had a few early-access bloggers lined up to launch with us. And then, surprise! Tom decided to take a job as the CTO of another startup. His parting words were, “You’re technical enough; seems like you can handle it.” 

    I was floored. Aside from the front end, I had no idea how anything worked. We had cloud functions running on Pulumi hosted in Google Cloud, and I had no idea how they worked. I didn’t know how to train the machine learning AI models we used for ingredient recognition. The most I knew about SQL was that you used it to get stuff from a database. And to top it all off, our recipe scraping API was written in Python, a language I had no experience with, running a version that did not work on my M1 Mac. What in the heck was I supposed to do?

    Well, I guess I did what any engineer would do. I figured it out step by step. When the Postgres database ran out of rows on the free Heroku plan, I figured out how to migrate it. When the recipe scraper API needed updating, I learned how to code in Python and deployed it with Docker. It was an incredibly stressful time. I was up against a looming launch deadline with a codebase teetering on collapse at any moment—mostly because I didn’t know how to hold it up.

    The silver lining was the GraphQL API platform, Hasura. It was by far the easiest part of the stack for me to grasp. Understanding how our data was laid out was easy enough—I could simply explore it like a spreadsheet. I wasn’t sure how to build GraphQL queries, but the tutorials on the Hasura website helped me learn the basics and the query builder in the console did the rest. It’s no-code, but better—a no-code console makes it super easy to add new tables and modify permissions, and a Git repository keeps everything in check and easy to reference. 

    Once I understood how Hasura and the rest of the stack worked, I was able to finish the screens that I needed for launch.

    Today, the company has grown significantly. We have a new co-founder, but she’s nontechnical. After figuring out how to run the entire stack, I decided I was technical enough to be the primary engineer. I’ve learned how to use all sorts of Hasura functionality that makes our lives so much easier—listening for events, firing off actions in our API to run business logic, and much more. Through all this, I now consider myself a full-stack engineer. 


  • We’re Doing More Less Development

    We’re Doing More Less Development

    My roots are in software development. I’ve written tax software, SmartGrid firmware and servers, enterprise integration code for many developed and purchased servers, mapping software, cell phone firmware—the list goes on. The point is development is in my blood. When I look at something that impacts software development, I look at it through a practitioner’s lens as much as an analyst’s. And there is a lot of change going on in the realm of software development.

    For a very long time, there have been options out there that reduce the amount of software we develop. And those options are often popular. There was a time where the most common phrase in enterprise IT was “Develop core systems, purchase support systems,” and the message sank in enough that we don’t need to say it anymore. There was a time when enterprises cobbled together systems as essential as email–some developing their own systems, but most working hard to integrate available offerings. We have completely flipped that equation, and now almost no one would consider spending significant IT resources on email. Not on development, not on integration. There are of course corner cases that do have to–our industry could be defined as a collection of sharp-corner cases we haven’t yet smoothed out–but few, if any of those reading this blog have had to worry about those corners. So, change number one: Purchasing IT solutions is massively successful at reducing our time. From CRM to email to security, we’re using far more tools written by others.

    There have also been code-generation tools forever. While the most well-known ones have historically been UI-focused, 4GLs generally tried to address development with less code. Again, time, failures and iterations have given us useful code-reduction techniques. From pre-formatted ‘if’ statements that we just plug in variables to API generation through (sometimes AI-powered) initial program generation engines that give us code to start a project. The requirements for writing code are less per-project.

    And the big one: Open source. There are entire software markets for which it isn’t worth developing solutions because there are good open source solutions on the market. If it is popular but even vendors cannot afford to make solutions because everyone is using the OSS solution—well, that reduces the amount of code developed. There are several companies whose entire business model is simply offering enterprises service and support on OSS. No development required, even for the “vendor.” Large portions of any given application we develop these days are based on open source that we include to solve one piece of the problem. We’ve had some spectacular hacks and failures based upon that model, but it is undeniably an enabler for more solutions.

    With all of these (and arguably more–like API-first and API standardization) reducing the amount of code we’re developing, you would think developers would be less busy, right?

    DevOps and Agile streamlined our development and shortened delivery timelines for subsets of a given project, but haven’t—and weren’t designed to—reduce the amount of software developed. Indeed, quite the opposite. With faster iterations, more could be tried out.

    But it is wrong to think there is less development effort. There are several reasons for this, but I’m going to focus on the big one. People invested in the company—business leaders, etc—have always had a massive pent-up desire to improve software to increase efficiency, competitiveness, etc. And IT was the bottleneck. Agile/DevOps are by no means perfect, but they offered a pressure release valve for that pent-up demand. And we’ve been at it long enough to know that rapid iterations in response to those demands inspire more new ideas, creating another iteration… So it will be unlikely to stop. Indeed, we all know what technical debt is, but there seems to be a disconnect between knowing intuitively that more code means more debt in the form of maintenance overhead. So developers are doing more because the organization has good ideas that need implementation, even though we have plenty of tools to reduce development effort. Some organizations have reduced developer headcount, but not many. And that might slow, but that’s unlikely. In the coming highly competitive environment, more features and solutions will be desired, not less.

    And you’ll be there, continuing to rock it. Pay attention to ways you can further reduce code effort. This is a long-term process, but the goal should be to reduce the growth rate in staff time. It is unlikely to go down overall–because maintenance overhead plus new projects is a constantly growing number–but slowing growth helps developers and working managers stay sane and take the time to find good hires.

    And just keep doing more less development.

  • Three is the Magic Number: Planning and Executing a Successful DevOps Project

    Three is the Magic Number: Planning and Executing a Successful DevOps Project

    Diligent preparation, clearly defined workflows and watchful monitoring are key to delivering a high-performing DevOps project. DevOps is one of the hottest buzzwords in programming, but everyone seems to have their own ideas when it comes to structuring and deploying a DevOps team.

    In basic terms, DevOps is the integration of developers and IT operations workers into a single group, with the goal of increasing the speed and quality of software deployment. Its creation was a response to concerns over the segregation of teams, which led to communication breakdowns and a lack of cohesion.

    Since its inception, DevOps has grown in popularity, with 83% of IT decision-makers stating that they have implemented this style of working in some form.

    However, transitioning business focus in this way does not guarantee an immediate change in fortunes–this dynamic represents an IT culture shift, with increased emphasis placed on collaboration and interpersonal skills. For this model to yield returns, engineers should be open to new information, technology and ways of working.

    So, what vital steps must a DevOps team take to ensure the successful delivery of a project?

    Understanding the Needs of the Client

    The preliminary stages can make or break a DevOps project. If the team does not emerge with a vivid idea of what the client wants and how this can be delivered, the venture is doomed to failure.

    It is crucial that both the team and the client are willing to put the time in to understand each other’s goals, ensuring that their visions align for the steps to follow. This can be done through a series of meetings and workshops, where objectives are identified and both establish a good comprehension of how the final product should look.

    If executed correctly, the DevOps team will exit the project’s first phase with a well-defined brief and a crystal-clear understanding of what the client wants to see delivered. When this step is rushed, engineers will be held back by a lack of direction, increasing the chances that the finished product will not reflect the client’s hopes.

    Configuring the Environment

    This next phase is where the developmental process of the app begins, which is usually facilitated using a cloud-based solution. The team begins by preparing the environment’s aesthetic, working out the components it should contain and exploring how they should be configured to maximize efficiency.

    It is during this period that cybersecurity measures are added so that the final version of the app is as close to impenetrable as possible. This shows why a DevOps team needs a diverse range of skill sets: Cybersecurity experts are few and far between, but there should be at least one member of the group whose knowledge can be called upon to ensure protective measures are properly implemented.

    A successful developmental phase is underpinned by clearly structured workflows, with the project mapped out step by step and everyone involved understanding where they fit into the plan and how they can contribute.

    However, a DevOps project is rarely smooth sailing from start to finish–development is often disrupted by missed deadlines, bugs and conflicting duties pulling engineers away from their stations. For this reason, agile and multi-skilled team members, who can ably jump in and assist in various areas, are extremely important for ensuring continuity when workflows are derailed.

    Avoid Failing at the Final Stages of the Project

    Just because the development of a product is complete and the app is live, this does not mean it is time for the DevOps team to rest on their laurels and move on to the next project. It is essential that they continue to monitor the app in its early stages so that any bugs can be identified and immediately fixed.

    Engineers should be in place to see how much the environment is burdened and how it responds depending on the rate and number of new users. Any data obtained is a precious commodity and should be treated as such, with teams ordering and labeling results as soon as they are collected.

    Once the baseline data has been gathered, results can be analyzed to pinpoint which parts of the app may need recalibrating. After making these improvements, the final result should be a product performing at an optimal level while also meeting the client’s specifications.

    Don’t Rush the Project’s Process

    At the conclusion of all three phases, DevOps teams should have absolute confidence that the project is headed in the right direction and that they are fully equipped to execute the next procedural steps.

    A well-designed app is far easier to produce when a team is made up of specialists from an array of fields eager to collaborate and communicate with one another. Assembling the right personnel will aid the smooth transition between the stages of a DevOps project.

  • Why SaaS Vendors Need to Give Back to Open Source

    Why SaaS Vendors Need to Give Back to Open Source

    There aren’t many tech organizations that don’t leverage open source technology. Companies that refuse to import software will rely on a freely available library tool or codebase. Open source is one of the largest and most powerful mechanisms of software propagation. However, open source is in danger.

    The Two Sides of Open Source Development

    In recent years, the ubiquity and dominance of open source tooling have led companies to adopt them en masse. Products like Elasticsearch, Spring and Akka are incredibly popular as open source, freely available tools. But unfortunately, often only one-half of the open source philosophy is being honored.

    The Open Source Philosophy

    What does that mean? Well, open source depends on two things. Customers use the software and those same consumers contribute to the codebase. It’s a feedback loop of like-minded individuals who have a shared interest in building and using an outstanding product and are happy to donate their time to realize their collective goals. This agreement has driven some of the most exciting software achievements of the past two decades.

    Alas, while it became prevalent to use open source software, the popularity of contributions did not scale equally. Suddenly, small teams of dedicated developers were inundated with demands from huge enterprises that equated “open source” with “free.” This caused the owners of open source projects, like Elasticsearch, MongoDB and Akka, to reevaluate their position and change to the increasingly prevalent source available license.

    Growing Risk to the Open Source Community

    If users contribute to the codebases they leverage, then those codebases can thrive and no one needs to worry about subscription fees or fines. Moreover, users can maintain the certainty that they are not doing anything illegal when they depend on a piece of software. Without contributions from the engineering community, an open source project’s commercial and practical basis quickly disintegrates.

    So Why Should SaaS Vendors Give Back?

    SaaS solutions inhabit a particular corner of the market, assisting companies in solving a cross-cutting problem. For example, observability. This is an important detail because many open source tools also operate in this arena. This is exemplified by the fact that it’s common for SaaS vendors to regularly compete against an open source, homegrown alternative. Many SaaS solutions actually base their core infrastructure on the same open source software.

    This means that SaaS providers are often in direct competition with the open source solutions they leverage to build their product(s).

    SaaS Vendors Depend on Open Source Software

    The communities that support vital pieces of open source software, like Apache Kafka or OpenDistro, are helping to unlock innovation in enterprises worldwide. The continued pace of this innovation is inextricably linked to the continued growth and development of the open source tooling on which it depends.

    The only sensible course of action is for SaaS vendors to make every effort possible to contribute back to the open source space. They do not need to give up their unique features, nor do they need to release their proprietary software, but the simple act of maintaining patches, improving performance, increasing compatibility and even correcting poor documentation—all of this is a contribution that will benefit the entire SaaS ecosystem.

    Those Contributions Will Breed Specialization

    A big challenge of using open source software is finding engineers that understand how it works. The plug-and-play nature of many tools means that users never need to dive into the details of a library or application. This, however, comes at a cost. Users often don’t know why the software breaks or behaves unpredictably.

    If a SaaS vendor begins to contribute back into the core of the open source tools on which they depend, not only are they benefiting their product and the open source community, but they’re also seeding specialist knowledge in their teams. This specialist knowledge means they can utilize open source features in new and exciting ways, giving them insights and advantages over their competitors.

    Open Source Contributions Make Commercial Sense

    The SaaS community thrives when open source tooling works smoothly. Conversely, if fundamental open source tools like Kafka or OpenDistro begin to falter, then the success of the SaaS community is also at risk. They are highly interdependent. This means a contribution back to core open source tools is a contribution to the stability of SaaS products. Moreover, growing specialist skills within engineering teams means that when it comes time to leverage a new open-source feature, your developers may have skills and insights that other companies won’t have. This is a clear commercial advantage, and all for the cost of doing the right thing, and keeping the dream of free, open source software alive.

  • What Customers Need From Sales and Marketing

    What Customers Need From Sales and Marketing

    There are plenty of historical examples of good solutions being buried by inadequate or outright wrong sales and marketing tactics. As an analyst, I often talk to the marketing, marcom or AR/PR department of a company and think they could do their solution more justice. Normally, it is little things; sometimes, not so much.

    But there is one industry-wide thing that I would like to see changed because it impacts all of us and is endemic.

    We don’t want to hear about your five biggest customers. We’re thrilled that you sold into several Fortune 100s. But you spent those five slides of your presentation basically saying the exact same thing five times: “We sold into a Fortune 100!” (or 500, whatever). You lost the opportunity to expand the message to “… and we support all organizations.” The idea that supporting a company with a run rate larger than most nations is in any way relevant to supporting small-to-medium-sized enterprises is mistaken. Talking about an example of a large customer helps us to understand scalability and support levels. Then, we want to know how that works for the rest of the market because most organizations are not Fortune 500s, by definition.

    Tell us how the product is used in organizations closer to our size. Instead of five slides about massive multinationals, include the best two that showcase the product and its benefits. Then, use those other three slides to talk about the wider market. People expect that large enterprises like the Fortune 500 pay more in raw dollars and get more support in raw hours. They want to understand how that relates to an organization their size. Because if you don’t work at an F500, information about F500s has limited usefulness.

    I recently had a presentation with a vendor; I love the technology, have been following them for years and use their solutions in a small business (not the reason for the presentation, but an expression of my belief that they offer a good solution). And their presentation was all about how well they serve large organizations. Thing is, they do a great job of serving small organizations, too, but unless you were an analyst like me, you would not have known that from the presentation. I get a lot of briefings, so while this one spurred me to write this blog, they are not the only ones, by far.

    So do us a favor: Give us presentations that are relevant to the entire market, not the subset someone told you is “most important.” It is, indeed, impressive if the solution can scale to multinationals and it is relevant. Just don’t obsess about it; we need to know if it supports our architecture, tooling, etc.

    We’re here rocking it every day, you should bring the broadest focus you have to let us know if you can be part of the solution moving forward. If you don’t, well, we might just think our business isn’t all that important to you. And we’re pretty sure most vendors don’t want that.

  • Avoiding Developer Burnout With Clean Code Best Practices

    Avoiding Developer Burnout With Clean Code Best Practices

    Employee burnout is common in the tech industry, especially for developers. In fact, 83% of software developers feel burnt out from their work and of those, nearly half of them feel overworked. Often, this is because the processes currently in place at their companies are not effective and too much time is spent doing mundane work.

    Resolving coding errors is a necessary part of software development, but this isn’t always an easy chore. Given the complexity of code today, developers do tend to spend a large percentage of their bandwidth on maintenance issues, refactoring, debugging or just modifying code that they never wrote in the first place. That said, 44% of developers stated that fixing software defects and problems is their biggest frustration.

    Every developer wants to create good code, but repetitively dealing with issues that aren’t part of the code they write steals away time from doing interesting work. More than a third of developers claim that they would prefer spending more time with their families, participating in more physical activity and even getting a full night’s sleep than spending the majority of their time fixing code. Developers also stated that they could use the time at work to focus on new features and capabilities.

    By implementing clean code best practices across the organization, development teams can create an environment that prioritizes new and interesting projects while organically addressing errors. Clean code practices help keep developers engaged and interested.

    What is Clean Code?

    Every organization relies heavily on software and the source code that powers it to run successfully. Companies are aware that the source, or DNA, of their software is what counts as its most important asset. The behavior and functionality are both governed by the source code and if it’s not kept in good condition, the source code can turn from an asset into a liability.

    Clean code refers to a codebase that has reached a flawless and problem-free state. It is code that is maintainable, reliable, secure, readable and embodies other such attributes of code. While developers write clean code for their new projects from the beginning, they simultaneously address existing issues through set quality standards. The overall workload of security and development teams also is greatly reduced when clean coding practices are considered and integrated into the development workflow.

    With this method, fewer issues reach the final stage of inspections. It also avoids pricey post-production rework or drawn-out feedback processes. The outcome is a simplified and effective method for managing the state of your code.

    How Clean Code Helps Developers

    By giving your developers access to the power of clean code practices, organizations can make sure that their development teams are working on projects that are impactful and exciting rather than dealing with mundane repetitive work. This means that they have more time to research, put new ideas into action, and also be part of new initiatives that have a direct impact on their organization’s success.

    When using the clean-as-you-code approach, you create a precedent that, moving forward, new code that is added or updated won’t result in new problems. As new updates are made to old code, the overall quality of that code progressively improves. This is a much more manageable process and a huge step toward improving the overall quality of code.

    Additionally, the clean-as-you-code approach empowers developers to take charge of the quality of the code they deliver. The feedback loop to detect and fix issues is naturally shortened with the proper tooling they can use in their current DevOps workflow. And contextualized education helps them quickly understand the root cause and get guidance to fix them. When their everyday routines automatically incorporate this technique, the possibility of recurring or exposed weaknesses is greatly reduced. In the long run, this helps save development time and effort, making development so much more enjoyable.

    There are many things that are a necesssary part of a developer’s everyday responsibilities. Making it simple and efficient is a win-win for everyone. No matter the state of your codebase, the maturity of your development team, or the size of your organization, clean code best practices are easy to embrace and will make your developers happier and more satisfied at work.