Tag: DevOps

  • How to Manage Multi-Cloud Infrastructure and Reduce Costs

    How to Manage Multi-Cloud Infrastructure and Reduce Costs

    It’s no secret that the public cloud has been a game changer for businesses. In today’s world, every organization is looking for ways to store data more efficiently, support agile application development and reduce the burdens associated with on-premises data centers.

    The public cloud is essential for meeting those objectives and achieving the higher degree of innovation and digital transformation that many organizations seek. While the shift to the cloud has unlocked unprecedented innovation, it has also created a new layer of complexity and sometimes unexpected costs.

    The Nutanix Enterprise Cloud Index found that nearly every organization (99%) has moved one or more applications to a different IT infrastructure in the past year, and the vast majority (86%) agree that moving applications is both complex and costly. Accordingly, 56% plan to focus on gaining more visibility into their cloud consumption and costs this year, while 52% plan to leverage solutions that minimize cloud waste.

    As Scott Sinclair, senior analyst for TechTarget’s Enterprise Strategy Group explains, “The typical enterprise now has multiple data centers and public cloud providers, and many are also using lots of different colocation facilities and multiple edge locations.” As such, “It presents a new paradigm with companies having to look at different factors and considerations like cost, portability and security because their data is no longer all locked in one room.”

    Organizations must carefully plan their cloud strategy to avoid getting bogged down by complexity and sticker shock. But in most cases, this is easier said than done. The majority of companies are not using a single environment — their infrastructure includes some combination of on-premises and public cloud resources. One of the challenges this creates is additional expenses and complexity associated with data mobility and data protection: Moving data around so that it’s available where and when it’s needed while simultaneously keeping it safeguarded requires careful planning and budgeting. In other words, data has gravity, and unless data movement and orchestration are planned, one can end up stranded when the primary location for a dataset is unavailable.

    Even companies that were born in the cloud have their work cut out for them. Managing different cloud environments might be relatively straightforward for a cloud-native organization initially, but if at some point their data needs to be relocated on-premises to address compliance, data sovereignty issues or budget, it can result in soaring costs if not properly executed.

    With this being said, here are four considerations CIOs should take into account to keep cloud complexity and costs in check from the start.

    1. Have Your Head in the Cloud but Your Feet on the Ground

    To reap the benefits of the cloud, organizations need to adjust their expectations and plan realistically. There’s a false perception that companies can run an application on AWS in the morning, Azure in the afternoon, and Google Cloud Platform at night. In actuality, multi-cloud is a medium-to-long-term strategy that occurs over months or years. Building a cloud operating model with this in mind lets organizations benefit from the flexibility of leveraging multiple clouds while avoiding the cost and complexity associated with trying to do too much too fast with the cloud. When appropriate expectations are in place, hybrid multi-cloud is achievable, affordable, and undoubtedly beneficial.

    2. Learn on Others’ Dime as Much as Possible

    There are several best practices organizations should follow as they begin their hybrid multi-cloud journey. These include things like ensuring key application capabilities have API wrappers, containerizing modern applications as much as possible so they are portable, and automating application deployments through CI/CD pipelines to avoid manual errors and reduce costs. Public clouds have been around for almost 15 years, and designing for the public cloud is now quite well understood across the industry. Still, companies need to be mindful of how they leverage public cloud for certain applications or workloads. For example, modernizing a legacy application portfolio might sound like a good idea in theory, but in reality, it is cost-prohibitive and it will not provide ROI —lift and shift is a much better option for legacy applications.

    3. Standardize, Automate and be Paranoid

    Public cloud environments are fundamentally different from traditional on-premises infrastructure, so organizations need to think about them differently—especially where security is concerned. While a fortified exterior with unfettered internal freedom might be a workable model for on-premises, the same model could spell disaster in the cloud. Host-based security approaches have become more critical in the public cloud. Automation and standardization ensure that security measures are applied consistently across all cloud resources and services within an organization and shorten the window to detect unauthorized behaviors. Organizations must also consider the non-technology aspect of this: training and education for their teams. All teams and departments must be on the same page when it comes to security so they can collaborate effectively on security-related initiatives.

    4. Build in Optionality From Day One

    The public cloud is by far the best place to begin innovation. However, as companies experiment in the public cloud and a smaller portfolio of applications gain traction, enterprises need to adjust to the reality that — for the vast majority of applications — the public cloud will always be more expensive than running them on-premises (or perhaps even another cloud). To avoid lock-in, enterprises must build in optionality for migrating their compute when needed, as well as the mechanism to move their data out of public clouds when needed. Organizations that are flush with cloud engineering talent can do this on their own, but the vast majority will require an underlying platform that’s explicitly designed for data and computation mobility.

    The perks of one platform to run all workloads across clouds, on-premises, and the edge are undeniable: From increased flexibility to optimized performance, compliance, agility and more. By heeding the advice above, companies can keep multi-cloud challenges like complexity and unexpected costs at a minimum and fuel innovation.

  • How to Make the Most of In-House Software Development

    How to Make the Most of In-House Software Development

    Let’s be blunt: Maintaining an in-house software development team can be tough. You must hire skilled developers – which is no easy feat in today’s economy, where talented programmers remain in short supply – and then manage them on an ongoing basis. You must also ensure that your development team is nimble enough to respond to changing business needs and that it can adapt as your technology stack evolves. Given these challenges, it’s no surprise that most organizations now outsource application development instead of relying on in-house teams.

    But I’m here to tell you that just because in-house development can be hard doesn’t mean that outsourcing is always the best approach. On the contrary, IT organizations that choose to invest in in-house development for some or all the work can realize lower overall costs and a competitive advantage by creating domain-specific expertise. Keeping development in-house can help organizations address unique security requirements and maintain full control over the development lifecycle and roadmaps. For businesses with specialized technology, security and operational needs, in-house development is often the best strategy.

    Managing an in-house development team presents some steep challenges. At Komprise, we have refined several practices to keep our team efficient and productive, even in a business environment that is constantly changing.

    Scaling Up

    Scaling teams up is a key challenge for in-house development teams. Finding skilled developers to grow a team can be very difficult, especially when working with a bespoke technology stack.

    There is no simple solution to this challenge, but there are steps you can take to maximize your ability to find and hire development talent. For example, we invest significantly in engaging with college students, allowing us to identify promising developers while they are still in training.

    At the same time, we invest in upskilling our developers who are already on our team so they can take on additional responsibilities. We train our engineers in the latest cloud development and security skills and knowledge. The notion of embedding security into our designs and practices is fundamental to what we do. We also rotate engineers between different teams so they learn new technologies that are important to our business. This strategy allows us to align the work for every developer with their interests and to build reusable skills within our teams. We also hold a technical brown bag three times per month where we cover issues like development for cloud and how it differs from on-premises due to costs or how to design for performance and scalability.

    Focus on Customer Value

    Figuring out which features customers want most is a constant challenge. To address it, we quantitatively track how our customers use our product – which functionality they use most often, for example, and how usage patterns vary across different customer demographics. We evolve these metrics as we develop the product. Additionally, we identify customers who are “power users” and occasionally set up calls between them and our developers to gain additional insight into what customers want. Our marketing team also conducts customer advocacy interviews with our users to learn more about what they like and don’t like.

    Looking at third-party applications and interfaces helps us gain perspective on how best to meet user needs, too. For example, we might examine how Wayfair or Amazon are evolving their UI constructs to inform how we could change our product interface in ways that better meet customer needs. We want our B2B product to be as easy to use as consumer products.

    Invest in QA

    Quality Assurance (QA) operations are distinct from development operations, but if you want a successful in-house development team, you need a great QA team, too. Our QA engineers complement our in-house developers by helping them to deliver the highest-quality product, while also strategizing over how best to handle scale and efficiency challenges. In addition, we’ve invested heavily in QA automation, allowing us to test our applications thoroughly while keeping our team lean and efficient. This ensures that as our product feature set expands, our ability to test the entire product does not increase and we can maintain a monthly release cadence. We use test harnesses to simulate error and failure conditions, by injecting failures into the system or making our network experience a brownout or a blackout. You can’t automate every software test, but you can automate most of them, and QA automation is one of the key ingredients in effective development operations.

    Leverage AI Strategically

    AI is not the solution to every development challenge, but when used properly, AI can accelerate development and help in-house developers work more efficiently. Using AI tools to churn out code has become a hot use case for AI in development since the introduction of solutions like Copilot. AI can be a very useful solution, but the quality of the results it delivers hinges on the quality of the data it ingests. Inhouse development teams working on AI applications have much to consider from the data perspective. To leverage unstructured data, they need ways to find it across data silos, enrich it with new metadata as needed to support search and leverage AI tools like Amazon Macie and Rekognition to further refine the data.

    Optimizing In-House Development for the Long Term

    The importance of keeping in-house development teams happy and productive is likely only to increase as the tasks they work on grow more complex and as new paradigms, like those driven by AI, change the way developers work. The more IT organizations and enterprises can upskill their existing developers and empower them with the right tools and processes to succeed, the better they can leverage their teams to build products and features that bring value to the business.

  • Security Across the SDLC

    Security Across the SDLC

    We’ve seen some interesting movements in the security space over the last couple of years. My focus is on application security, but one of the movements we’ve seen is the blurring of what is application and what is infrastructure security, so I do a fair amount of that also. And then, with the advent of WAAP, we have network security playing a role in AppSec… It’s a growing snowball.

    I will start with the mandatory happy declaration that DevOps no longer treats security as an annoyance. While we’re well past that, I think the shock of the whole “security is a problem, not protection” mentality that DevOps started with is still hanging with us, and some still actively believe that. But at this point, we’re well on the “Security is part of the process” trail we should be on.

    If you look at the top-level changes, static application security testing (SAST) vendors have grown to be development security, covering SAST, DAST, IAST, RASP and even a bit of data security. Meanwhile, load balancers and WAF slowly evolved into full-on web applications and API security that covers the production side with active protections for things like DDoS and DLP.

    Likewise, we’ve seen this with the growth of cloud workload protection and how the entire digital architecture is being pulled into CSPM.

    I’ve said it before – we’re in a consolidation phase. It looks like it will go even further than I thought, though. Now, we are starting to see an interesting development: WAAP vendors are starting to include some or all of DAST, SAST and RASP. Arguably, they always did some IAST because their focus was on runtime protection, but their emphasis is more on protection than test, so it will be interesting to see that bit expand also.

    And all of this includes an inconvenient fact. We don’t have any more people to do security than we ever did; in fact, we have less. That’s part of the reason that we haven’t shoved security everywhere – there aren’t people to do it. In true DevOps fashion, we have distributed the work across other teams – Dev is right there where code security and API security start, so we’ve implemented SAST and DAST bits right into the IDE, for example. Or Ops has always done some amount of security, and we’ve just upped the amount. But they don’t magically have more time, either. I’m sure you are feeling it if you are a practitioner; almost all of us are. AI promises to help with that, and in security, it will likely deliver. Another thing I’ve pointed out before is that security is one space that really does stand to gain from generative AI – in helping make more secure code, in helping make all the permutations of tests, in making rules based upon observed data and more. The time-saving benefits will deliver, in my opinion. But it’s still a lot of work, and some of it is straight-up additional work because we weren’t doing things like container security a few years ago.

    In the short term, if full SDLC security is applied, there will be more work. In the long term, the mega platform for security may well reduce this work as it limits notifications across tools. Maybe we should name the coming mega platform SecArch. Also in the long term, AI will help alleviate some of the load. Until then, buckle in. You’re not likely to get staff to cover new work. But it will be worth it. Just keep plugging along, and know when to say you just can’t add one more thing to the pile.

  • Anima Adds Ability to Personalize Generative AI Code

    Anima Adds Ability to Personalize Generative AI Code

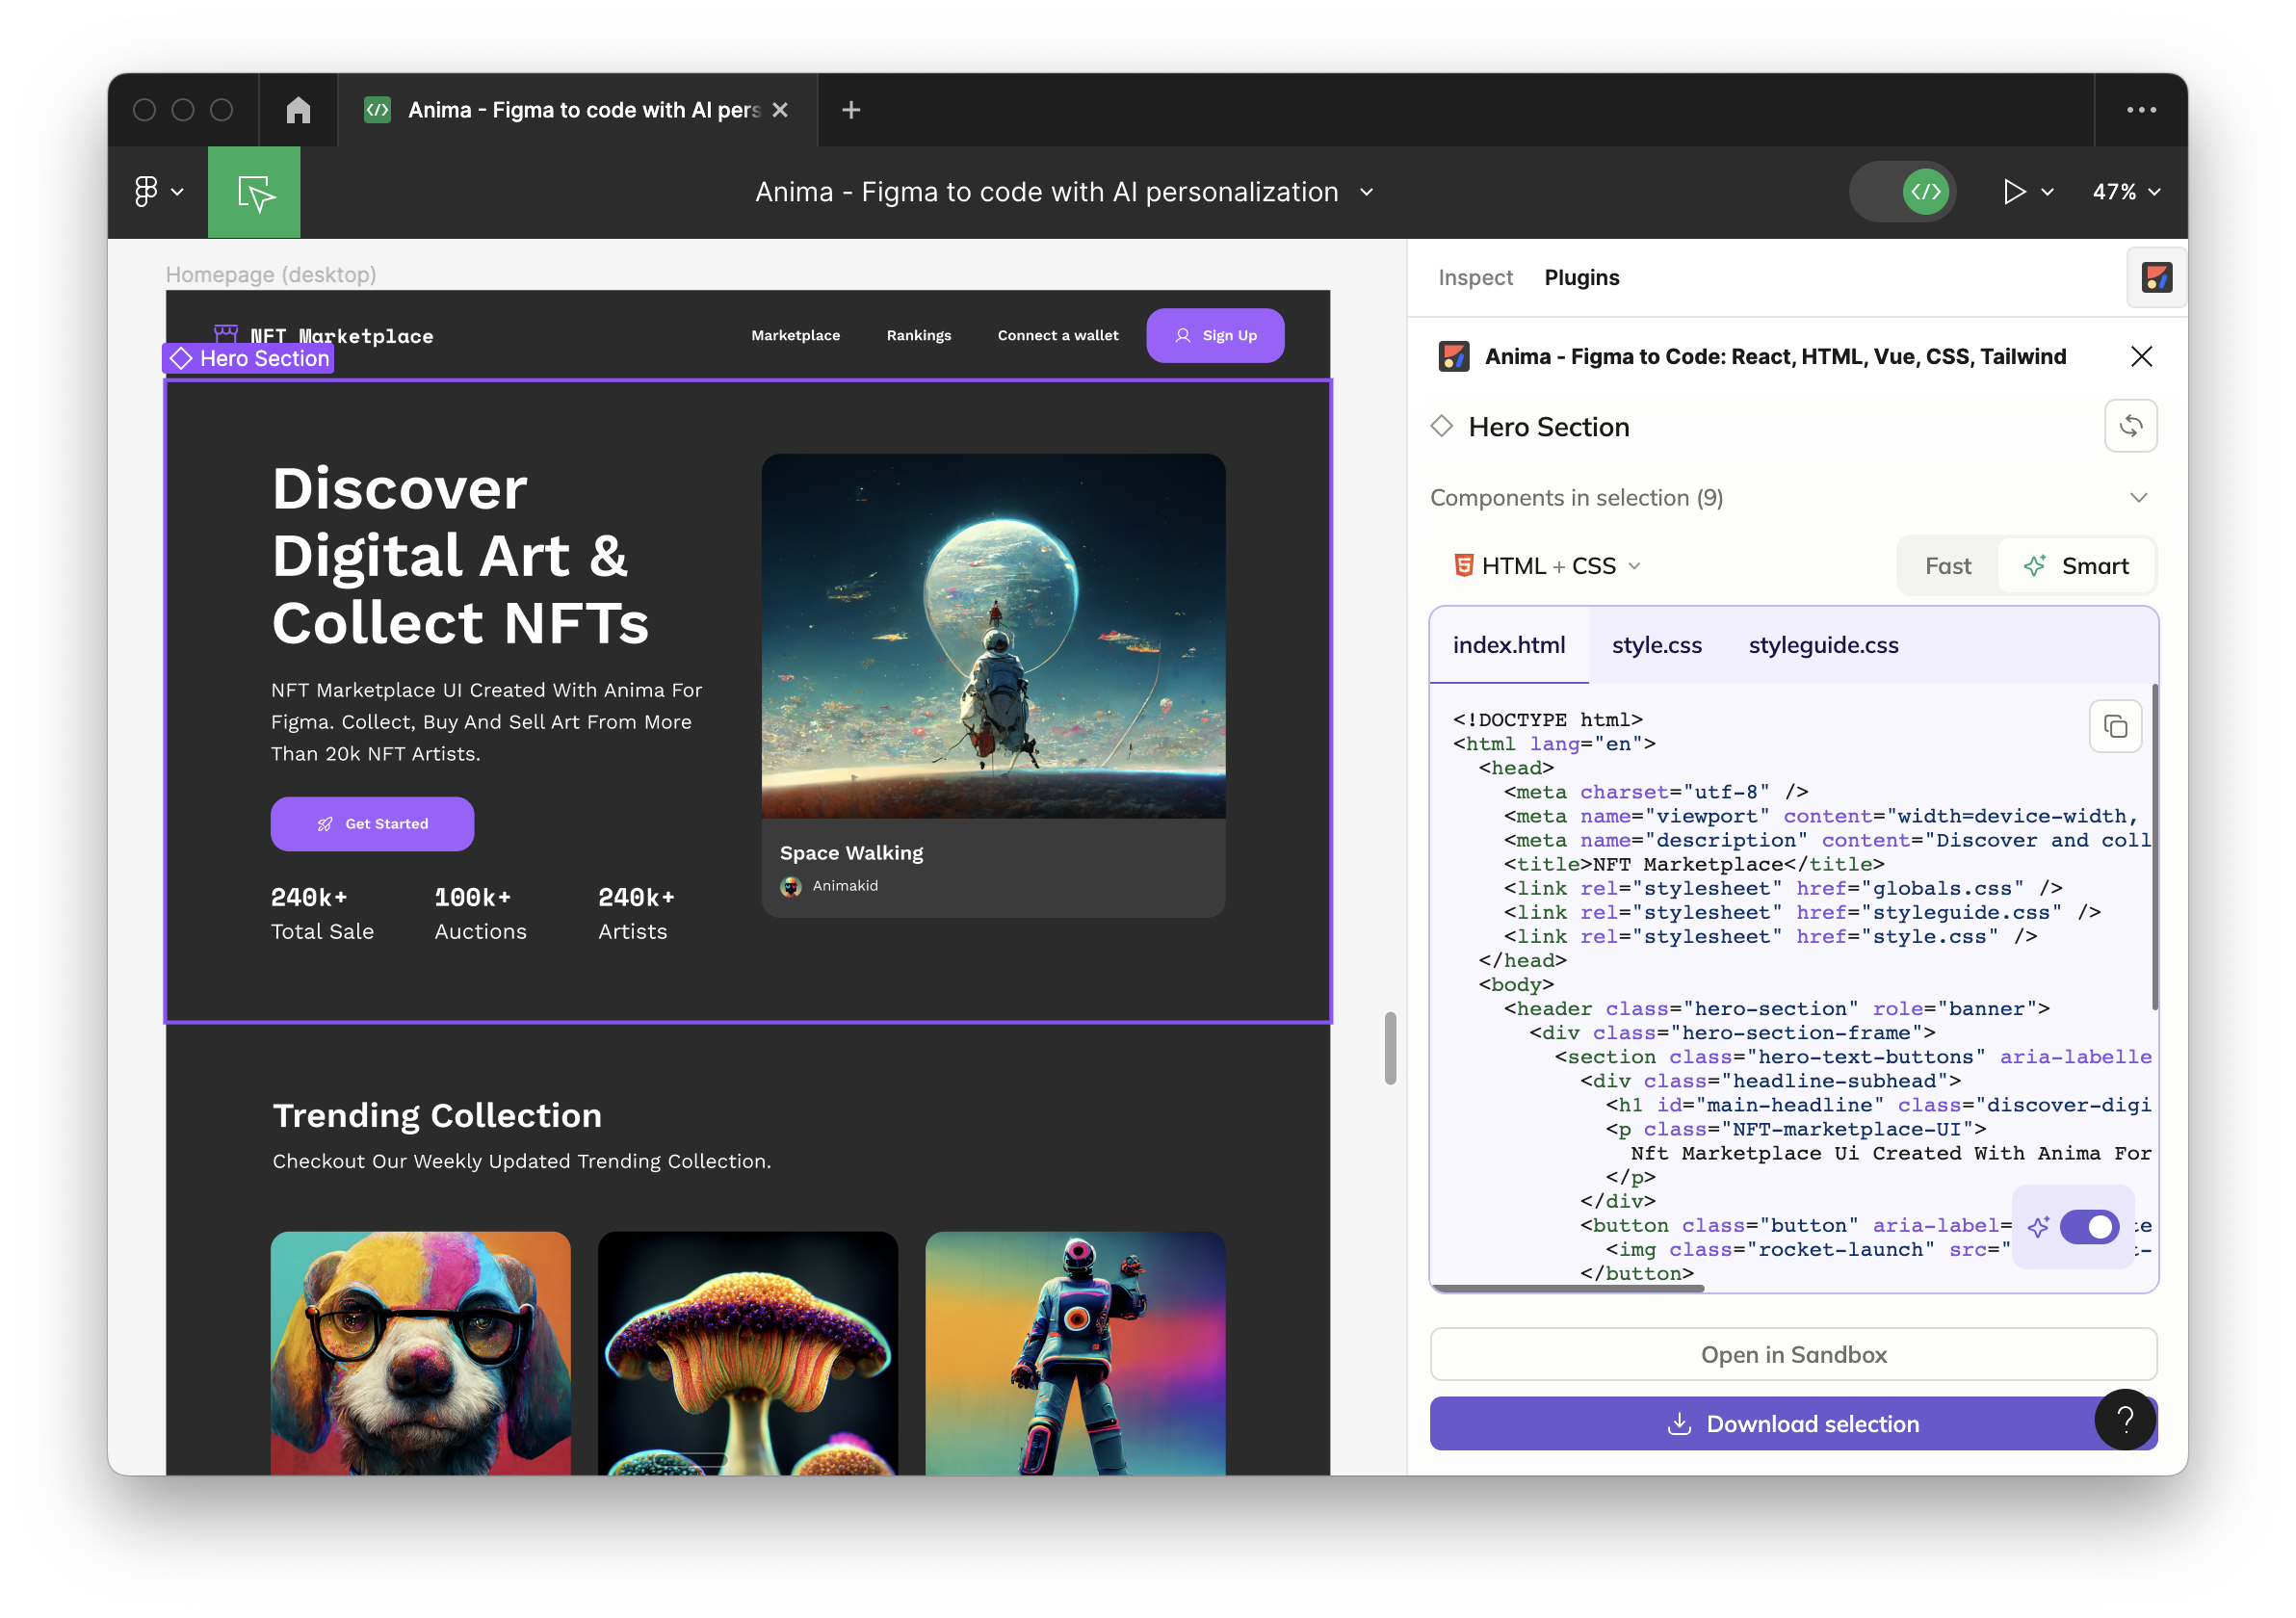
    Anima today revealed is has added an ability to personalize the code its generative artificial intelligence (AI) platform creates based on how an application is described using tools from Figma and Adobe.

    That capability makes it possible for the code being generated to resemble the coding style of an organization or specific developer more closely.

    Anima CEO Avishay Cohen said the company developed this capability to reduce the editing time that is otherwise required when trying to embed code generated by a large language model (LLM) within an application that has a well-defined coding methodology.

    The platform that Anima provides is based on a mix of LLMs and heuristics that the company developed to generate code. In this case, the code being generated is written in React or HTML to make it simpler to build an application’s front end. In contrast, a general-purpose LLM such as ChatGPT is not optimized for creating these types of graphical applications.

    Developers no longer need to worry about, for example, making sure each pixel is perfectly placed because the Anima platform automates that part of the application development process, including adding responsive behavior, animations and logic, noted Cohen. In addition, customized instructions may be applied to an entire project or even a specific component.

    In effect, the platform enables backend developers to automatically create a front-end for their application from a description in tools provided by Figma or Adobe. As a result, developers can allocate more time to writing business logic and optimizing application performance, said Cohen.

    Later this year, Anima will integrate its platform with GitHub and other continuous integration/continuous delivery (CI/CD) platforms as part of an effort to extend the reach of the platform across an entire codebase, he added.

    There is, of course, already no shortage of generative AI tools for writing code, but the degree to which they have been incorporated into DevOps workflows varies from one organization to the next. Much of the code created using platforms such as ChatGPT can vary widely in terms of quality. These platforms were trained using code collected from across the web so it’s not uncommon for the code generated to include known vulnerabilities that DevOps teams need to scan before incorporating into a build. In other cases, the code generated might simply break when installed.

    Regardless of these issues, however, the amount of code being generated by machines is only going to increase, especially as more LLMs that are specifically trained to create code based on examples that have been closely vetted become more widely available.
    In the meantime, developers who never especially enjoyed building the visual front ends of applications can now focus more of their time on tasks they prefer. Alternatively, developers who specialize in the front ends of applications will find that much of the toil involved will soon be automated in a way that should provide more time for them to create customized experiences.

    One way or another, the overall pace at which applications are built is about to exponentially increase. The challenge now will be finding ways to take advantage of AI to enable DevOps teams to keep pace.

  • Aembit Announces New Workload IAM Integration with CrowdStrike to Help Enterprises Secure Workload-to-Workload Access

    Aembit Announces New Workload IAM Integration with CrowdStrike to Help Enterprises Secure Workload-to-Workload Access

    Silver Spring, Maryland, January 30th, 2024, Cyber Newswire

    Aembit Becomes the First Workload IAM Platform to Integrate with the Industry-Leading CrowdStrike Falcon Platform to Drive Workload Conditional Access

    Aembit, the Workload Identity and Access Management (IAM) platform that enables DevOps and security teams to discover, manage, enforce and audit access between workloads, today announced the availability of a new integration with the industry-leading CrowdStrike Falcon® platform to give enterprises the ability to dynamically manage and enforce conditional access policies based on the real-time security posture of their applications and services. This integration signifies a significant leap in Aembit’s mission to empower organizations to apply Zero Trust principles to make workload-to-workload access more secure and manageable.

    Workload IAM transforms enterprise security by securing workload-to-workload access through policy-driven, identity-based, and secretless access controls, moving away from the legacy unmanaged, secrets-based approach.

    Through this partnership, the Aembit Workload IAM solution checks to see if a CrowdStrike Falcon agent is running on the workload and evaluates its real-time security posture to drive workload access decisions to applications and data. With this approach, now enterprises can protect their workloads from unauthorized access, even against the backdrop of changing conditions and dynamic access requirements. Additional customer benefits from this partnership include:

    • Managed Workload-to-Workload Access: Enforce and manage workload access to other applications, SaaS services, and third-party APIs based on identity and policy set by the security team, driving down risk.
    • Seamless Deployment: Drive consolidation by effortlessly integrating the Aembit Workload IAM Platform with the Falcon platform in a few clicks, providing a unified experience for managing workload identities while understanding workload security posture.
    • Zero Trust Security Model: Embrace a Zero Trust approach, ensuring that every access request, regardless of the source, is verified before granting access rights. Aembit’s solution enforces the principle of least privilege based on identity, policy, and workload security posture, minimizing potential security vulnerabilities.
    • Visibility and Monitoring: Gain extensive visibility into workload identities and access permissions, enabling swift detection and response to potential security threats. Monitor and audit access logs based on identity for comprehensive security oversight.

    This industry-first collaboration builds on the recent CrowdStrike Falcon Fund strategic investment in Aembit, underscoring the global cybersecurity leader’s commitment to fostering innovation within the space. The investment reflects the recognition of the growing demands for securing workload access.

    Aembit Workload IAM is available in the CrowdStrike Marketplace, a one-stop destination and world-class ecosystem of third party products. See more here.

    Supporting Quotes:

    “Today’s attacks are increasingly identity-based, which is why enforcing identity-protection across the enterprise at every layer is critical for modern security. The CrowdStrike Falcon platform is rapidly becoming the center of cybersecurity’s ecosystem. This integration with Aembit enables organizations to secure machine identities as part of a holistic approach to security.” said Daniel Bernard, chief business officer at CrowdStrike.

    “The launch of the Aembit Workload IAM Platform on the CrowdStrike Marketplace represents a significant advancement in our joint mission to securely manage workload-to-workload access,” said David Goldschlag, CEO and co-founder at Aembit.

    “We are excited to bring the power of Aembit’s Workload IAM to the CrowdStrike Marketplace. This collaboration enables us to deliver Zero Trust for workload access in a way that simplifies and automates the evolving security challenges faced by DevOps and DevSecOps teams,” said Apurva Dave, CMO at Aembit.

    Press Contact

    Apurva Dave

    Chief Marketing Officer

    press@aembit.io

    About Aembit

    Aembit is the Workload Identity and Access Management (IAM) Platform that lets every business safely build its next generation of applications by inherently trusting how it connects to partners, customers, and cloud services. Aembit provides seamless and secure access from your workloads to the services they depend on, like APIs, databases, and cloud resources, while simplifying application development, delivery, compliance, and audit. Follow Aembit on LinkedIn.

    Learn: Website or CrowdStrike Marketplace

    Follow: LinkedIn | Twitter

    Use: Free-Forever Tier


    Contact

    Chief Marketing Officer
    Apurva Dave
    Aembit
    apurva@aembit.io
    (202) 525-6661

  • Using LLMs to Automate Pipeline Conversions From Legacy to Tekton

    Using LLMs to Automate Pipeline Conversions From Legacy to Tekton

    There have been many technological advancements in the market today, but the main hindrance is the cumbersome process of switching from the existing technology/framework to the new one. This is where teams and organizations are left behind in the tech curve. In the DevOps landscape, CI/CD pipelines are the backbone of DevOps, and how you work with them largely dictates your DevOps efficiency.

    CI/CD pipelines, too, like other major technologies and frameworks in the past, have seen various evolutions; the latest among them is being made reusable in an attempt to standardize CI/CD. However, here too, there are several cons:

    1. The pipelines are not proprietary to end-user enterprises and belong to the DevOps platforms which are not open-source
    2. Migrating to these platforms and pipelines is a huge task
    3. They may not be as efficient as depicted

    Speaking of new advancements in technology, most might be familiar with Tekton for CI/CD pipelines: It is Google’s open source framework that is now a graduated CDF project. It redefines how pipelines are built (through reusable tasks) and these tasks are open source and community-vetted. They allow for pipeline authorship, and enterprises can re-use them across platforms that are compatible with Tekton, thus preventing vendor lock-in.

    While this mitigates the first challenge of pipeline ownership and migrations, however, the same problem plagues DevOps teams – transitioning from existing legacy technologies/frameworks to newer, much more capable frameworks like Tekton.

    However, what if there was a way to seamlessly automate your transition from legacy pipelines to cutting-edge, reusable Tekton pipelines without toil? This is precisely what the article aims to explore – automating the conversion of Yaml scripts of existing pipelines to Tekton Yaml scripts.

    Let us consider the three most popular CI/CD platforms for this use case – Jenkins, GitLab and Azure DevOps. Before we proceed to the proposed approach to achieve this (which is detailed in the second half of this article), let us first look at the limitations of Jenkins, GitLab and Azure Pipelines and why one should convert.

    Common Limitations of Jenkins, Azure and GitLab Pipelines

    Resource Intensive: Legacy pipelines can be resource-intensive, especially for larger organizations or projects. Managing server resources, optimizing configurations and ensuring sufficient hardware can be a challenge.
    Complex Setup: Setting up and configuring Jenkins, GitLab and Azure DevOps can be complex, particularly for self-hosted instances. This complexity may require experienced administrators and substantial time investment.
    Plugin and Integration Compatibility: All three platforms may face compatibility issues with certain plugins or integrations.
    Scaling Challenges: Scaling in organizations, especially when dealing with multiple microservices, necessitates a shift from individualized scaling to a template-based approach. Failing to do so leads to a chaotic increase of pipelines, undermining standards and organizational processes.
    Costs: While both Jenkins and GitLab offer free and open-source versions, some advanced features or capabilities may only be available in higher-tier paid plans. This can lead to cost considerations at scale.
    Customization Complexity: These platforms can be complex to customize workflows and integrate custom scripts as they require advanced scripting knowledge.
    User Interface Complexity: Though they have feature-rich interfaces, it can sometimes be overwhelming for new users to navigate the platforms and find specific settings or options.
    Limited Native Integration & Plugins: The native integrations of Jenkins, GitLab and Azure may not cover the full spectrum of tools and services a team may need. Additional integration efforts or third-party tools may be required to bridge gaps in the development workflow.

    As can be seen in the above limitations, many are common including scalability challenges, being resource intensive, limited integrations etc. All the challenges boil down to one common denominator: Complex pipeline management at scale.

    This is where a framework like Tekton can help tackle all the challenges at once, by just easing pipeline management: with its K8s-native pipelines that are reusable, open source and tasks that are community-vetted.

    Tekton Pipelines: Advancing CI/CD with Kubernetes-Native Automation

    Tekton, an open-source project, is rapidly gaining traction as a game-changer in the world of CI/CD pipelines. Its Kubernetes-native design is a standout feature, seamlessly integrating with Kubernetes clusters to harness its scalability and resource efficiency.

    Furthermore, Tekton’s cloud-native roots ensure it can execute tasks in lightweight, ephemeral containers, optimizing resource utilization. The ability to declare CI/CD pipelines as code, coupled with GitOps practices, enhances automation and reproducibility.

    How are Tekton Pipelines Different?

    Kubernetes-Native Automation: Tekton pipelines are deeply integrated with Kubernetes, utilizing Custom Resources and Operators to define and execute CI/CD workflows.

    Declarative and Modular: These pipelines are defined declaratively using YAML manifests, promoting version control, collaboration and code reviews. The modular design of tasks and pipelines enables teams to create reusable components for building, testing and deploying applications.

    Containerization and Isolation: Each task in a Tekton pipeline runs within a dedicated container, ensuring isolation and reproducibility of the build and deployment environment.

    Event-Driven Architecture: Tekton pipelines can be triggered by various events, such as code commits, pull requests, or external events, providing a responsive and event-driven CI/CD process.

    Scalability and Efficiency: Tekton pipelines leverage Kubernetes’ inherent scalability, enabling efficient execution of tasks across a dynamic pool of worker nodes.

    Visibility and Observability: They offer built-in monitoring and logging, allowing teams to gain insights into pipeline execution, track progress and diagnose issues.

    Integration and Extensibility: Tekton pipelines can be easily extended with custom tasks and integrations, enabling teams to connect with various tools, services and cloud platforms.

    Cloud-Native Best Practices: By embracing Tekton pipelines, organizations align with cloud-native best practices, promoting the use of Kubernetes and containerization for streamlined application delivery.

    Why Transition From Jenkins, GitLab, and Azure Pipelines to Tekton Pipelines?

    Migrating from Jenkins, GitLab, or Azure pipelines to Tekton pipelines can be a strategic choice, especially for organizations deeply entrenched in Kubernetes and cloud-native methodologies.

    Optimize Kubernetes-Centric Workflows: Projects tightly integrated with Kubernetes may find Tekton pipelines more aligned with their ecosystem.

    Accelerate Cloud-Native DevOps: Organizations aiming to embrace a cloud-native approach and leverage Kubernetes infrastructure.

    Performance and Scalability: Tekton pipelines run on clusters that can dynamically be created and destroyed according to demand, thus taking resource optimizations to the next level.

    Cloud-Native Best Practices: Best practices, such as containerization, declarative configuration and infrastructure-as-code are a natural fit due to their Kubernetes-native design.

    Proposed Workflow for Automating Pipeline Conversions at Scale

    The overarching objective of this workflow is to facilitate a seamless conversion process using large language models (LLM) without delving into the intricacies of fine-tuning but rather using the benefits of prompt engineering. Central to this approach is the use of the chat context and the strategic application of roles for LLM models to establish context. Along with this, sample pipelines are leveraged to train and fine-tune the model to define how the corresponding YAMLs of all these platforms look for any given pipeline.

    The use of prompts and instructions tailored to fit the use case of generating contextual pipeline YAML and conversion of Jenkins/Gitlab pipelines to Tekton pipelines makes this workflow possible. We maintain a context and a contextual mapping of real-world examples and the most appropriate prompt designs to produce the most accurate responses. The role of users in this context adds weight and further refines the response received.

    However, before proceeding into details and examples, let’s set the base for what exactly generative AI means and its context in our use case:

    Generative AI and LLM for Automating YAML Script Conversions

    Generative AI, such as LLMs, create content like text, benefiting from patterns in large datasets. Large language models (LLMs), with billions of parameters, excel in generating human-like text by understanding language structures. They have broad applications, including natural language understanding, summarization, translation and content generation, promising automation and human-like interactions with AI.

    Adapting the Model to Solve Real-world Use Cases

    Fine-tuning and prompt engineering are two common methods used to train large language models (LLMs) like GPT-3, BERT and others. These methods help adapt pre-trained models for specific tasks or generate contextually relevant responses. Both fine-tuning and prompt engineering play crucial roles. Fine-tuning helps the model comprehend complex use cases, while prompt engineering provides detailed requirements, extracting the best results from the model.

    Why Prompt Engineering?

    Prompt engineering stands out as a highly advantageous approach in specific use cases where precision, control and customization over AI model behavior are paramount. This method empowers developers and users to meticulously design input prompts, effectively guiding AI models to produce contextually relevant and desired responses.

    Prompt engineering is both an AI engineering technique for refining large language models (LLMs) with specific prompts and recommended outputs and the term for the process of refining input to various generative AI services to generate text or images.

    The process of prompt engineering to fit our use case includes :

    Defining the goal: The first step in the process of AI prompt engineering involves setting a clear objective.

    Crafting the initial prompt: With the goal in mind, it’s time to draft an initial prompt. This could take the form of a question, a command or even a scenario, depending on the goal.

    Testing the prompt: The initial prompt is then input into the language model, and the response is analyzed.

    Analyzing the response.

    Refining the prompt: With the insights gathered from testing and analysis, it’s time to revise the prompt. This could involve making it more specific, adding more context or changing the phrasing.

    Iterating the process: The testing, analyzing and refining steps are repeated until we are satisfied that the prompt consistently guides the model toward generating the desired response

    To conclude, here’s an example of typical YAMLs from Jenkins, GitLab and Azure DevOps, and how the same YAML looks when converted to a Tekton YAML. This goes a long way in facilitating teams to finally make a jump from their existing pipelines to cutting-edge reusable pipeline frameworks:

    Jenkins YAML

    GitLab YAML

    Azure YAML

    Converted Tekton YAML

  • Control D Launches Control D for Organizations: Democratizing Cybersecurity for Organizations of All Sizes

    Control D Launches Control D for Organizations: Democratizing Cybersecurity for Organizations of All Sizes

    Toronto, Canada, January 29th, 2024, Cyber Newswire

    In an era where online threats no longer discriminate by business size, Control D, powered by Windscribe VPN‘s robust security expertise, announced today the launch of ‘Control D for Organizations‘. This modern DNS service democratizes cybersecurity, making it accessible to businesses of every size, from budding start-ups to late stage SMBs and MSPs.

    Leveraging the strength of the world’s largest physical VPN network, Control D is bringing unmatched expertise in navigating cybersecurity challenges and global surveillance into the hands of businesses that traditionally lacked these advanced protections.

    Control D for Organizations is geared at companies, schools, and NGOs of all sizes offering simplicity for smaller teams and highly specific and advanced controls for larger organizations. Control D is packed with an arsenal of tools designed to secure and empower diverse teams:

    1. Malware Blocking: Protecting business continuity against malicious threats with state-of-the-art detection techniques, all built in-house. Protect individual devices or entire networks in just a few minutes.

    2. **Multi-Tenancy: Addresses the complexity of managing access and filtering policies across different departments, subsidiaries, or customer accounts within a large enterprise or service provider setting.

    3. Modern Protocols: Security cannot be assured using standard DNS protocols. That’s why Control D supports all modern (and encrypted) protocols like DNS-over-HTTPS/3 and DNS-over-TLS.

    4. Custom Filtering: Highly granular web filters provide power users with ultimate control, while more general curated lists allow DNS security newcomers to gain maximum security benefits with minimal effort.

    5. Actionable Insights: Detailed network activity analytics empowers businesses to improve their security posture and make strategic decisions.

    Control D for Organizations is more than a security tool—it’s a declaration that first-rate cybersecurity is no longer a luxury. It embodies a new era where organizations, irrespective of their size or financial prowess, can confidently protect their operations and data.

    ‘Control D for Organizations ‘, Empowering Every Business with Advanced Cybersecurity

    Control D is a pioneer in software security, devoted to offering next-level, user-centric solutions. Backed by the years of security expertise of Windscribe VPN which protects over 68 million people, Control D leverages the largest physical VPN network and one of the fastest anycast DNS networks to deliver unparalleled security and freedom from surveillance on a global scale.

    Join the DNS security revolution and equip your business with Control D. Visit controld.com for more information and take your first step towards comprehensive digital protection. Additional assistance for onboarding channel partners available. Free no-payment-details required trial is available.

    Media Contact Information:

    For further details, please contact Yegor Sak at business@controld.com or our channel partner lead Joe Jaghab at Joe@controld.com


    Contact

    Founder
    Yegor Sak
    Control D
    business@controld.com
    +1(848)500-9848

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    SimplyHired.com

    D2 Consulting
    Springfield, Virginia
    DevOps Engineer
    $150,000 to $180,000

    Indeed.com

    Mariner Finance
    Remote
    DevOps Engineer
    $120,000 to $150,000

    ZipRecruiter

    Cogility Software
    Irvine, California
    DevOps Engineer
    $110,000 to $140,000

    CareerBuilder.com

    BAE Systems
    Manassas, Virginia
    DevOps Engineer
    $92,290 to $156,860

    Dice.com

    Rackner
    Falls Church, Virginia
    Software DevOps Engineer
    $90,000 to $140,000

  • Kubernetes Troubleshooting in GitOps: Dealing with Unexpected Helm Chart Modifications

    Quiz #17 was:
    You’re working in a GitOps environment where developers use Helm charts to manage Kubernetes deployments. One day, a developer makes a change to a Helm chart to adjust the replica count of a deployment. However, after the change is applied, you notice that the deployment’s pod template has also been unexpectedly modified, leading to errors. Which of the following is the most likely cause of this issue?

    1. Version control conflicts
    2. Incorrect values file usage
    3. Helm version incompatibility
    4. Namespace configuration error
    5. Insufficient RBAC permissions

    Correct Answer: 2) Incorrect values file usage

    99 people answered this question with 27% getting it right.

    Meta Description: Discover how to tackle Helm chart issues in GitOps environments. Learn about common pitfalls and find solutions to keep your Kubernetes deployments error-free.

    Are you managing Kubernetes deployments using GitOps and Helm charts? It’s an excellent approach to maintain infrastructure as code and ensure reproducible deployments. However, like any technology, it comes with its challenges. In this blog post, we’ll explore a scenario and guide you through Kubernetes troubleshooting in GitOps, specifically when unexpected Helm chart modifications occur.

    The Scenario

    Imagine a typical day in your GitOps environment. Developers are busy making changes to Helm charts to fine-tune Kubernetes deployments. One day, a developer makes a seemingly innocent adjustment to a Helm chart—changing the replica count of a deployment. But as you apply the change, something unexpected happens. The deployment’s pod template is also modified, leading to errors and chaos in your cluster.
    The Most Likely Cause
    The culprit in this scenario is often “Incorrect values file usage”. Helm charts rely on values files to customize deployments. When values files are used incorrectly or contain erroneous values, they can inadvertently modify various aspects of your Helm chart, including the pod template.

    How to Tackle It


    1. Review Values Files:

    Start by thoroughly reviewing the values files used in your Helm chart. Ensure that the values provided align with the intended changes. It’s crucial to understand how each value affects your deployment.

    1. Validate Chart Versions:

    Check that you are using the correct Helm chart version. Helm chart versions can evolve, and using an incompatible version may lead to unexpected behavior. Maintaining a well-documented Helm chart repository helps.

    1. Test Changes Locally:
      Before applying changes to your live environment, consider testing them in a development or staging cluster. This allows you to catch issues early and prevent unexpected modifications.

      1. Collaborate with Developers:

      Encourage close collaboration between developers and operations teams. Clear communication about changes and their potential impact is essential. Developers should provide detailed documentation for values files.

      1. Implement Access Controls:

      Utilize Kubernetes Role-Based Access Control (RBAC) to restrict who can make Helm chart modifications and deployments. This helps prevent unauthorized or inadvertent changes.

      Conclusion

      In the world of GitOps and Kubernetes, troubleshooting unexpected Helm chart modifications is a part of the journey. By understanding the most likely causes and following best practices, you can mitigate issues and maintain the integrity of your deployments.

      Remember, Kubernetes troubleshooting in GitOps is not just about fixing problems; it’s about preventing them in the first place. Embrace a proactive approach to ensure that your Kubernetes environment remains error-free and efficient.

      But when things do go wrong, issues like these can be time consuming to debug increasing downtime. In the last quiz we looked at a similar issue where, at times, it is essential to bypass best practices to address an urgent issue. When this happens, and it invariably does, Webb.ai leverages AI to automate troubleshooting to reduce downtime and make SRE and DevOps more productive. Similar to how Github Copilot is automating software development and making developers more productive, Webb.ai is automating troubleshooting to make Ops more productive! The goal should be for the machines to do the repetitive stuff so that we humans can think about the more fun and creative stuff!


      Ready to streamline your GitOps and Kubernetes troubleshooting efforts? Participate in our Early Access Program.