Tag: DevOps Unbound

  • EP 13: Observability and Performance Testing

    EP 13: Observability and Performance Testing

    In this episode of DevOps Unbound, Alan Shimel is joined by Christine Yen of Honeycomb, Paul Bruce of Tricentis and Mitch Ashley from ASG/MediaOps to discuss how to effectively test the performance of your applications and how bringing observability into testing environments helps DevOps teams identify and resolve issues early in the SDLC. The video is below, followed by a transcript of the conversation.


    Alan Shimel: Hey, everyone. I’m Alan Shimel, CEO of MediaOps, Editor-in-chief of devopsy.kinsta.cloud, Security Boulevard, Container Journal, and you’re watching DevOps Unbound. DevOps Unbound is a biweekly video series where we have some of the leading lights in our community talk about topics of interest around DevOps. We’re lucky enough to be sponsored, DevOps Unbound, by our friends at Tricentis, so many thanks to Tricentis for their sponsorships. But this is a media ops event.

    Let me introduce you to today’s panel and then we’re going to jump into our topic. Let me first introduce the guy with all the robots in his background there: Paul Bruce, with a 404 shirt. Paul, welcome. Why don’t you introduce yourself to our audience?

    Paul Bruce: Sure. Thanks, Alan. So, my name is Paul Bruce, as you said. I’m on the nerdy side. I’m a performance and reliability geek. That’s just a place of complexity that I love to – it’s just what – it’s just my bag; it’s just what I like to do. On the other side I’m a community organizer. I work with DevOpsDays Boston and the Boston DevOps Meetup. I am hosting an event along with Liz Fong-Jones this year called o11yfest around observability, a vendor-neutral and also – community-focused but also the open telemetry project-focused two-day event. It’s half days so that we don’t burn people out. And I work with the Tricentis team since the NeoLoad acquisition – again, performance reliability. I was with Neotys and NeoLoad for years now. I really loved that team. And I love my new one, the broader one at Tricentis. So, that’s me.

    Shimel: Very cool. Thanks, Paul. And then, joining Paul today is – we’re very lucky to have her – someone I’ve had the pleasure of interviewing more than several times now over this past year of Covid but hopefully soon to see in person, my friend Christine Yen. Christine is CEO of Honeycomb. Christine, welcome.

    Christine Yen: Hello. It’s wonderful to be here. Alan, you shared my title, but my background is as a product engineer. Honeycomb, for anyone who isn’t familiar, is a tool who – a tool for observability. And I love working on it and I love talking about this topic because even though I tend more towards the software engineering side I have done my fair share of breaking production, and so this topic is near and dear to my heart for software engineers to do that less and find out what their code really did more quickly.

    Shimel: Very cool. Thanks, Christine. It’s great to have you here. And then last but not least is my cohost of DevOps Unbound. We’ve worked together for probably longer than either of us want to admit, but it’s hard to believe we’re both only 25. But CTO here at MediaOps, CEO of the Accelerated Strategies Group, Mitch Ashley. Hey, Mitch. Welcome.

    Mitch Ashley: Thank you, Alan. But the best 25 – this year again. Twenty-five again, right?

    Shimel: Yeah, 25 again again.

    Ashley: Good to be here.

    Shimel: Anyway – yep. Thanks, Mitch. So, today’s show, really, we’re going to explore the intersection – or maybe it’s a border between performance, performance testing, and observability. What – how do they play with each other nicely? What is the interaction? What is the relationship? And for those in our audience, you may be looking at it and saying, “Well, observability is kind of almost post-deployment. Hopefully we’re doing some performance testing pre-deployment and then post-deployment.” But how – I don’t know if I see a nexus right away but there’s – in my mind anyway there’s an obvious nexus. There’s an obvious connection.

    So, let’s talk about it at a high level. How is observability and performance testing connected? And how can they – how can we get a one plus one equals five or four out of performance testing and observability? Christine, if it’s okay, I’m going to ask you to kick off with that and kind of lay out the framework, the ground rules, the – and we’ll all jump from there.

    Yen: Well, laying out the framework and ground rules is a little bit of a big ask for early in the morning, but I’ll do what I can.

    Shimel: Okay. I’m sure you’ll do great.

    Yen: I’m wearing the wrong shirt for this. I often – I think I’ve come on one of these interviews with my “test in production” shirt, but it’s a phrase that too many folks – it can be interpreted in many ways. What does testing in production mean? There is a version of it that means, well, I’m not going to run tests beforehand; I’m just going to see what breaks in production and try to fix it after it’s impacted users. Obviously, that’s not what any of us mean. And there’s a version of it that means, hey, look, when you write preproduction tests, when you write any sort of tests, what you’re trying to do is you’re trying to compare actuals versus expected. You’re trying to form a hypothesis, observe reality, and then think about that difference. Isn’t that really just a different phrasing of what we’re trying to do when we’re looking at production, where we’re using our logging or monitoring or observability tools to see what actually happened when our code is in production?

    And so, I love – I think it’s a huge intersection, a huge overlap between things like performance testing and observability because we are all using the same skill set, we’re all using the same brain sequence, but there’s – people seem to think that observability is – can be more exciting because it’s incidents and downtime and alarms are going off. I don’t think it is. I think it’s all the same. It’s just at different points in the development life cycle. It’s on different timelines. It’s with a different level of urgency. But it’s the same thing we’re all just trying to do to come up with hypotheses, validate them, and learn.

    Ashley: I really like, Christine, the way you kind of intersected them together because the environment that we’re doing all of this has changed substantially. It wasn’t that long ago where it was kind of a static flow of writing codes, we’d test it, we’d CI/CD, we’d test it, we’d deploy it into production. And DevOps helped speed that up with automation and tools, and of course tools of automation for testing. But now the software stack is fluid. The infrastructure is fluid. The code is fluid because we may have introduced three new changes to containers, for example, in a cloud-native application since we’ve really had an opportunity to go and debug or determine what the source of that was. We also have dynamic applications that start up and go away, and those things may be long gone by the time we actually look at them. So, I think this key to observability is also giving you insight into an environment that may not exist at the time that happened, and so you need that information to be able to understand “This is really something I need to fix, address” – a bug, a feature, whatever it might be.

    Bruce: Yeah, and I think there’s a lot of intersection between putting pressure on systems, whether that’s through actual users and risking revenues and all sorts of things or doing prerelease type testing or testing in production. There’s a – performance is about how does this system perform to expectations? And there are a number of different people with a number of different expectations. There’s the technical expectation, maybe articulated – hopefully articulated in something as legitimate as an SLO or an – and then measuring them with SLIs and stuff. But there’s also user expectation. There’s the CEO expectation. There’s B2B. If you’re in some kind of regulated industry and that SLA is actually part of a legal requirement that becomes really important. Like, we saw that unemployment sites – I don’t mean to pick on that kind of work, but that was a mess. Same thing with various different – trying to get the vaccines scheduled and stuff. And it’s like why are we still suffering from these systems that are out there and they’re good enough maybe for the day to day but have never been exercised, have never been – the concept of that being – that scaling has never really come about for that system.

    Okay, well, what about systems that do by default have scalability as a first class citizen? Going back to some of the stuff that Christine said – and actually, Christine, I love – your cofounder Charity has a phrase and I’m going to butcher it, but “It’s never not a good idea to have your glasses on when you go driving.” That idea that if you can’t see what’s going on that’s a big problem.

    So, a lot of people traditionally would have used something like “Let’s just throw all our APM tools at production.” And that’s great. But going back to that original thing where I was saying pressure on systems really shows us how well we’re doing engineering, the impact of that pressure matters too. So, as a performance engineer, performance and reliability engineer, I’m constantly not just trying to – as my French team would say – make load on a system, put load, put pressure on a system, but I also care deeply about being able to measure the impact of that.

    I’ll pause there because we probably some other questions. But there’s more to go into about that. It’s not an either-or. And it’s not about just production or preproduction. It’s about what’s not a good idea to have visibility. Isn’t it a good idea to have visibility on a thing, whether it’s putting pressure before release and having visibility or doing that in production? We’ve got a lot of customers who do testing – who do load testing in production on production systems. This is not an impossible thing, folks, you know?

    Shimel: So, let me try to put this in some kind of context that we can jump on. So, here’s what I say Christine saying, which is – and maybe I’m taking it up a couple notches, getting out of the SLO woods – at the end of the day what do we all want? We all want our apps, our infrastructure to run better. We want to have good predictability, visibility into how things are performing. And whether that is an aspect of performance testing, or you want to call it performance monitoring, or do you want to call it observability, at the end of the day the aim is the same, which is let’s understand how our stuff is running and make sure it’s running the way we think it should be running. So, at a very high level it’s almost equating performance or observability – I mean, it’s all with the same goal, which is let’s make sure our stuff’s running good, as the best we can.

    In my mind – and Christine, I’ll defer to you – certainly over the last year, year and a half, maybe two even, observability has taken on – as it’s become more hyped and a real word, a real thing out there, has taken on almost an even bigger mission than that, where it just doesn’t equate with – the goal may be “Hey, let’s make sure things are running the best we can make them run and how we expect them to run,” but there – observability has a whole uber mission of things that people want to do with it or use it for. Paul, you mentioned APM. Kind of observability subsumed APM, AI ops, all of these things. But yet, wait, there’s more. Observability does more than that. It’s become this whole big thing out there. And maybe it – maybe that’s right, maybe that’s wrong. I’m not here to judge.

    But that, I think, is really the crux of this. Yeah, we all have the same goals. Is observability – part of what observability does helping the performance engineer? Absolutely. Is there more to observability? I think so. Christine, you’re the observability expert. I’m going to ask you.

    Yen: You know when you say a word enough times and it starts to lose its meaning and you’re like “This is starting to sound funny”?

    Shimel: Yeah.

    Yen: We – I think you’re – there’s – we are definitely approaching that with observability a little bit. And whenever I get to that point I like to pause and remind folks “Let’s look at the – let’s take a deep breath and look at the English word we are using to describe this. It’s not a bucket full of buzzwords. It’s not a bucket full of types of data. It is an ability to see. And it’s the ability to see into our production systems. What do you want to do with that? What can you do with that if you have an improved ability to see?”

    Okay, well, now we have the laundry list of all the things that we can do once we have the ability to see into these systems that, as Mitchell mentioned, are so different than they were five or ten years ago.

    Shimel: Oh, yeah.

    Yen: And that to me is – that zooming out behavior is what re-centers me when it feels like we’re trying to do all the things. And you’re like “Well, it kind of makes sense. I want to have my glasses on when I’m driving.”

    Shimel: Yeah. Paul?

    Bruce: Christine, you’re definitely right about a buzzword merry-go-round. I have experienced that with “DevOps.” I have experienced that with – oh, man, I can’t believe I’m saying it again but I’ve got to because people will know – “shift left.” These terms that just get all the things. And we go at these things, these different terms, we latch onto them, we try to make it our own. Oh, man, vendors love to do that. We’ll take a word and we’ll make it ours and we’ll try to align it to our product strategy. And at the end of the day it’s like there’s 150,000 different versions of this thing, which as a performance guy I’m kind of like “Well, it’s not bad to have a big sample set,” but the sample set of what’s going on in the delivery chain from good idea to working software that’s making you money is not just in production.

    Let’s take an example of Nike, for instance. This is a known thing that they ship the watch, the watch that you open up on Christmas Day, and you go to connect to the internet and because the servers were swamped you don’t have a good Christmas experience. That’s not the only – I’m just picking on… But that kind of situation is a situation where there’s a lot of stuff you can do to prevent obvious faults from getting to the point where that’s the bad experience. And you also need visibility on the day where your production is having problems. And it’s not just the day; it’s every day. Every day you have a certain un-zero amount of events and issues in your production systems. How do you address those things? Well, there are plenty of situations where if you’re only thinking about observability as it only applies to production – which, by the way, production is where – what makes you money. If code is not sitting in production doing something useful for people you are not making money off of it necessarily. And production isn’t just out for consumers. It could be all the different constituents in your larger organization. So, even private systems are production. And so, if something is not out there then it’s not making money.

    So, is that the only place where we should pay attention, where we should have good visibility on logs, traces, and metrics, on understanding how the business is impacted, long and complicated queues and delays in these systems? No. I mean, yes, in our edge and final production systems, yes, of course we will want that because we don’t want to be in a bad situation not having the right visibility into problems when they’re happening in production. But how do you think problems come about in production? Well, there’s the emergent ones that we can’t possibly know about. Ooh, there’s just so much time in the day. But then there’s a whole bunch of other stuff. Every line of code is not just an asset; it’s a liability. So, as you’re constantly shipping these things out there’s plenty of things you can do to prevent obvious – and I mean dumb and stupid and obvious things from getting out there, causing toil, waste, risk, and loss of brand, revenue, and all that stuff.

    So, I think the observability for me is not just in production. It’s really useful to have classic monitoring in preproduction environments except for that it’s super expensive. Oops. And then, observability, pieces of observability, which Christine would probably be better to go into, all those things that you can do and what you get out of that, and now we can have use cases, that also applies to preproduction situations. That’s why I’m so excited about that open telemetry project and the community over there, this notion of being able to emit information from your systems, to either build it in directly from your systems or put it on sort of after the fact, sort of replacing some of the obvious early agent type stuff that monitoring used to be the only thing that could do. That open telemetry stuff now makes it a standard that we can all benefit from no matter which environment. How about all environments? That would be super nice. And to get tracing and traceability from – all the way from the Web app that somebody is touching all the way down to the database and the 30 different APIs that it touches.

    That’s really useful, not only to firefight in production but to see “Am I risking dependencies? Am I go wildly off my architecture diagrams?” You know what I mean? Those things slide. Your conceived architecture diagram is never what’s actually running in production. So, to actually be able to have visibility on that is really important.

    Ashley: Well, you know, Paul, the lines between production and, let’s say, tests are blurred, to use a phrase – are really kind of blurred, and oftentimes when we adopt whatever new technologies or approaches we’ll attempt to do what we used to do just using a new technology to do it. So, we’ll test the way we used to. And just what sort of clicked with me with cloud early on was how Netflix was doing their rolling upgrades and being able to flip back and forth. The same is really true for testing and performance testing because your availability to resources generally is not an issue, or not the issue it would be normally in an environment where you’re not in the cloud or at least partially in the cloud. So, there’s a lot of things you can do not just in your current testing environment but to set a pretty elaborate – with resources to do different load tests, performance test scenarios, in addition to what you experience in production.

    And I think one of the points that you made is salient, is if you’re paying attention to this you now understand your systems, your applications, your environment enough to identify “Well, we may be able to handle the number of unemployment claims we’re getting today but I know when we reach the next peak these are the three things it’s going to impact. I know those are the things we have to go adjust or fix or whatever it might be.” Because you’ve already instrumented it well enough and you have the information through observability to be able to do that. So, I think that’s a different mindset of how we think about performance testing.

    Shimel: Yeah. So, I tell you, I think one of the big breakthroughs of DevOps has been to create our “testing environments” to be more lifelike, to be more real lifelike. I mean, because prior to DevOps, the world I grew up in, the classic thing is the developer developed, gave it to the ops guy, the ops guy puts it up and says, “Wait a second, this stuff don’t run.” And he says, “Hey, developer, this doesn’t run.” And the developer says, “I don’t know, dude. It ran on my machine.” And so, there was that disconnect between what the developer wrote and ran it on or they tested it on versus the real life production environment. And one of the great things about cloud and virtualization and all of this stuff is that we can theoretically really duplicate our production environments and test environments and we can increase loads and we can do all those things theoretically so that there’s no or less surprises when we go live in production. And that – look, that’s – thank you, DevOps. That’s part of what this whole DevOps thing, I think, was.

    But I don’t know, is – Christine, is that really – does that dog hunt or is that just DevOps urban myth? You know?

    Yen: I think you’re on – right on the ball. I mean, when Charity and I started Honeycomb she came right – that story you told, I was that dev; she was that ops. I did the whole “It works on my machine; I don’t know what you’re talking about.” And when we started Honeycomb we thought honestly we were going to be talking to more of the Charities of the world. We were like “Oh, this is a tool for ops people. They’re the ones who understand the pain.” And as Honeycomb grew and as observability grew it became more and more obvious: “No, this is for the Christines of the world too.” This is for the people who need to understand what happens beyond that testing environment. This is – the boundaries are blurring or – I like to think of it as dev and production are coming closer together because there are more and more things we just can’t test in a test environment. As good as we make the test environment, we just can’t.

    Shimel: I totally agree.

    Yen: And there are so many things that can be learned – the same – by thinking of production as part of the development environment. With feature flags we can start to take code that is really not quite ready for production but test it out in a safe way and learn from it. And that’s so cool. It’s – there’s so much for developers to be able to learn when everyone kind of gets over this mindset of “Well, there’s a wall between development and production.” There isn’t. There shouldn’t be between people or the software. And that’s where all the exciting parts live.

    Shimel: I don’t disagree. I don’t disagree.

    Bruce: So, Alan, one thing that you said – you painted sort of the stage so that we could have part of this conversation. I’m not a big fan of setting up huge staging environments. In classic world it was like, okay, well, here’s production and it uses 36 Oracle back-ends and – if we were going to run a proper performance test of course we needed 36 on our side. And before the cloud that was incredibly expensive and you’d fax your IT person and they’d get back six months later with the right hardware. And I think there’s a myth that, well, yeah, you need to be realistic at some point, especially when you’re putting pressure on a system, to answer the final question, which is – what? – is it ready enough for me to be – what? – confident enough that this thing is going to transition like we talk about in standards, the transition process, that that’s actually going to go smoothly? And not in a waterfall way, just in a – to get away from this notion of “It worked on my machine” and now the ops person is putting out fires and doesn’t know how to operate the thing.

    But I’m not a big fan on spending a ton of money on this staging system which ultimately even if – even if at a very root level it’s exactly the same as the production system there’s always that jerk in the corner going “Yeah, but it’s not production.” And it’s like “Okay, you have a point but you don’t know what goes on.” And the point is I think almost like a – I’m going to do my idiot thing and pull in a mathematical and then probably get it wrong, a mathematical concept of the limit. You remember limits? And the idea is we need to be able to express are we talking about the very ends of things? No, it’s a continuum.

    So, there’s a lot of companies that I work with that actually do have requirements, that they go through a particular amount of testing and particular things before they can transition this to production. They don’t have the luxury of treating production like a dev system. There is a ton of people in the world, and it’s not their dysfunction – that’s not a dysfunction, just because the unicorns can fart rainbows and sneeze glitter and launch whatever they want. I see that happening in Boston all the time in some of the startups, and they do actually put themselves at risk. And even when you don’t do that, when you have an extreme amount of maturity and you’re working with relatively complicated technologies like Kafka things can go wrong pretty quickly. And the question is do you have the people and the process and the technology and the knowledge and the experience and the expertise to handle those when those things do come up in real time?

    How do you get there? How do you get to people who know how to use your monitoring and observability tools really effectively? How do you know what those systems, how close to your perceived architecture versus your actual in production, how do you know how much delta there is there? How often do you exercise the process of disaster recovery is one of those other classic questions you might ask yourself.

    And it gets back to who would be involved when there is a firefight or a last-minute thing like what we’ve done with some of the companies that I worked with very closely through the NeoLoad side of things, is when the education system, when colleges shut down and they finally said, “We are shutting our doors to the people that are paying us money,” that was a scary and real and significant flag for the rest of our US education system to go “Holy crap. We’re going – we have to provide virtual not as a stopgap for the past few months but this is going to be a serious reality for us for the next year.”

    And so, a lot of the vendors that help the education system have the right platforms in place. They go “Holy crap. We really need to test for 10X the size that we’ve ever tested before.” So, they’re testing in production on nights and weekends in various different places and doing it at a smaller pace. But who do they have on the call? Not just the Ghostbusters, but the devs, the ops. There’s people from infrastructure, the DBA teams. They have 20-plus people white-knuckled on the call, like [makes quivering sound] – white-knuckled on the call, and that’s a lot of money. And by the way, you’re asking them to do from 10:00 PM to 2:00 AM to 3:00 AM work. And so, they’re not going to be available for all those fancy meetings, architecture meetings that they should be stakeholders at.

    So, when you get to the point where you’re doing those massive things sometimes it’s necessary to go massive. But the vast majority of the exercises, you go to the gym – not so much me, but you go to the gym to exercise. You go and you get on your bike and that’s an exercise. You don’t expect to run a race without exercising first, without knowing that path a little bit before you just run a 5K race. So, why would you expect to do that with your systems and your teams?

    And that’s where some of the testing, the lower order performance testing comes into play. It’s systematizing the stuff, making a process that can be executed and re-executed no matter which environment it’s pointing to. And the telemetry that you’re getting out of it aligns in each of those environments. If all of a sudden we have really great telemetry in a pre-prod environment but we don’t have it in prod that would be a big problem. Why was it put in here and it’s not represented in production? What if we need that? Or vice-versa: We’re only doing things in production, and so now there’s only – there’s stuff that’s only in production that has no representation of how it would show up in lower environments.

    So, keeping those things in synchronous but also keeping the process and the exercised skills in place is why this isn’t just a big environment at the end kind of a situation.

    Shimel: Again, I think “Thank you, DevOps” where we have been able to say, okay, not only do we need those or can we use those testing dev environments, but as Christine said, with things like feature flags and some of the other technologies, processes that we use, it is possible to continue that – the feedback loops and iterations in real time while using the – while in production. And that again is one of the things that allows us to continually update, continually iterate, continually – and feedback loops was kind of an original concept as part of this DevOps thing. We’re going to have those feedback loops and we’re going to iterate and reiterate.

    But where we’ve gone with observability with that and with performance testing and these things with that have really just opened the floodgates in how we do these things now. I mean, just think about how – when I first started devopsy.kinsta.cloud eight years ago, I mean, there were the unicorns who were updating multiple times a day. But for many people in the world, for many organizations in the world, look, moving from once a year to twice a year, twice a year to quarterly, quarterly to monthly was huge. It was huge. It’s not so huge anymore. It’s common for people to be updating their code daily or more than once a day now.

    I saw – I did an interview this week, a recent survey of developers who they claim that they have sped up their deployments by over 100 percent in the last year and a half. That was – something like 70 percent of developers said that. Think about it. I mean, that’s – a billion here, a billion there, you’re talking real money. Seventy percent of developers say they’re going 100 percent faster. Wow. Wow. What a golden great time to be living. And it’s because of things like observability, DevOps, our better performance testing. Anyway.

    Guys, we’re coming up on our time limit here. I wanted to kind of – let’s wrap it up. Let’s – what advice – for our folks listening in, watching in here, what can we give them? What can we tell them about this nexus of observability and performance that will make their life better? Paul, I’m going to – if you don’t mind, I’m going to put you on the hot seat and ask you to go first.

    Bruce: Sure. Well, there’s a couple things I’ve been working on for a while and then there’s a couple things that I just want to give a shout out to. I’ll start with – Christine doesn’t get to do the pitch thing but I do. Honeycomb is awesome. You see that thing in play and it’s awesome because the team behind it is awesome. You know what I mean? It’s kind of the Conway’s law situation where – the version of it I hear most is the systems are a result of the teams that build them. So, definitely check that out.

    Same thing with some of the other tools around there. But don’t get too bought up into the whole observability – don’t just Google “observability” and look at the first one because most people are paying through the nose for SEO placement there. Really actually look at what’s available, and then also dig into the team, the blog, the spirit behind that thing.

    The second thing I’d suggest is we just released – I was one of the members of a working group for a standard on DevOps principles and practices that applies to highly regulated industries. It’s IEEE 2675-2021, which we’re hoping to get adopted in ISO so it’s global as well. And what it does is really align what is – how are each of the important processes that can be applied continuously through many different life cycles as they’re going along? You know, that DevOps eternity symbol means we’re all going to be stuck in hell forever, that thing is happening, all the things are happening all the time but there are precise things that need to go on in highly regulated industries, and even not. So, we’ve been working on that for four years. And you can reach out to me on LinkedIn, on Twitter – although LinkedIn is probably a better way to go – if you want to know more about that.

    But essentially it’s a body of work that a lot of people have been putting time and effort into to really say, “Hey, look, this is not about what DevOps is. This is about how to do this in these complicated situations.” And you know me; as a performance geek I tried to – I was involved in QM/QA, verification, validation, risk management process, those kind of things. And I tried to make sure that evidence-based decisions, that – which is a hook to basically say visibility, telemetry, the proper SLOs in place, those are definitely in the standard along with other things.

    So, definitely check those two things out: Honeycomb and the IEEE 2675.

    Shimel: Excellent, Paul. Christine.

    Yen: Thank you for that plug, Paul. The one piece of advice I’d like folks to internalize, we’ve talked quite a bit about – or, I’ve talked a bit about developers in production and developers in observability. An asterisk there is that that is not – the practice – the muscles and the practices should transfer well but there are a lot of things in the DevOps world in production that are, well, in some cases outright hostile to developers and in many cases just kind of scary and unfamiliar. And so, if this is something that’s interesting to you, if you’re like “Ah, yes, I would also like to bring development and production closer together,” take a step back and look for things like that. Do your production tools primarily talk about AWS instances and CPU and memory use? Those may be things that might scare your developers off. How can you make the vocabulary that your production tools talk about more familiar to developers? How can you help them bring the concepts and nouns that they’re used to in testing – customer ID or endpoint or logic, something that feels more familiar to the developer world, how can you have that exist in your production tooling as well so that developers can show up and be like “Oh – oh, this isn’t so different”?

    I think that there’s a lot of things that are encoded in certain practices because we assume that a certain persona is the one using them. And those walls are blurring – or those walls are coming down; those edges are blurring. There’s a little bit of work left to do to facilitate it.

    Shimel: Absolutely. Hey, Mitchell, you want to bring it home?

    Ashley: Yeah, I’m going to wrap it up this way because there’s some great practical advice – and by the way, both companies have fantastic products, so please check them out. I think we have this mental model, this habit of thinking of things in one state. Matter has four states – well, five states if you count Higgs boson – Bose higgson. It’s not just solid. It is also fluid. I mean, think of our systems. Don’t think of it as software tools, all the layers of it. Combined together they operate more like a fluid, in a state that’s changing, constantly moving. Things are happening. And that causes you to rethink developers and production, doing production – doing performance testing in a production environment. And the flow of software through that DevOps tool chain is really part of that – the fluidity of that state.

    So, I think we like to think things – of things like “Let’s make everything a solid so it doesn’t change, so we can look at it, observe it, do something with it.” It’s not really that way. That’s not the world we live in today. But if you think about it as something that’s under constant change like a fluid, then I think we have a much better chance of figuring out better ways, whether it’s through technology, new paradigms, new ways of working, of how to make our software the best it can absolutely be.

    Shimel: And at the end of the day that’s what we all strive for. Right?

    All right. What a great way to end this, then. This is a wrap. I think it’s episode 13 of DevOps Unbound. But it’s a wrap on whatever number this was because it’s fluid anyway. It’s a wrap on this episode of DevOps Unbound. Many thanks to Tricentis for sponsoring us on DevOps Unbound. We will be back in two weeks with another great episode. Stay tuned. We also have a big roundtable coming up this month; check that out.

    Paul, hey man, congratulations on joining the Tricentis team as part of the acquisition there.

    Bruce: Thank you.

    Shimel: Christine, they’ve all said great things about Honeycomb, but well deserved. Say hello to Charity for us as well.

    Yen: I will. Thank you.

    Shimel: Keep doing what you’re doing. I hope to see you all soon or a couple months from now in person. Maybe we will do a live DevOps Unbound at some time somewhere. But until then, this is Alan Shimel for MediaOps. You’ve just watched DevOps Unbound.

    [End of Audio]
  • EP 12: DevOps Unicorns

    EP 12: DevOps Unicorns

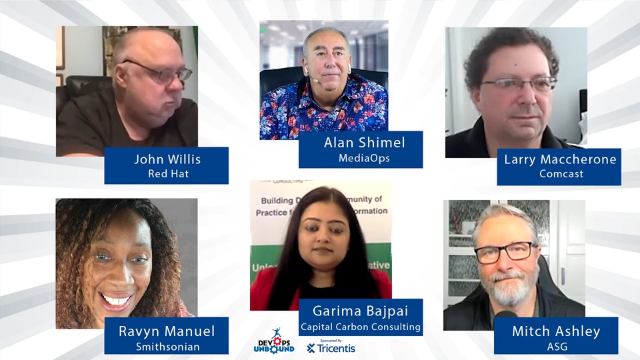
    What should you look for when choosing a DevOps vendor? What criteria are others in your industry using to inform their decisions? How do you choose a vendor that is a good fit for your organization? And how do you know if you made the right choice? In this episode of DevOps Unbound, host Alan Shimel welcomes Larry Maccherone of Comcast, John Willis of Red Hat, Ravyn Manuel of the Smithsonian, Garima Bajpai of Capital Carbon Consulting and Mitch Ashley of Accelerated Strategies Group for a panel on DevOps unicorns. The video is below, followed by a transcript of the conversation.

    Alan Shimel: Hello, everyone. Welcome to another edition of DevOps Unbound, where we talk about DevOps, hence the title. Thanks for joining us. This episode is titled DevOps Unicorns: The Quest for End-to-End DevOps.

    You know, I’ve been in IT 30-plus years and there’s always been this tension or this pendulum that swings between the one throat to choke versus the best of breed solutions in any area. Today it’s DevOps and software delivery and deployment. But in anything, in the security world, in everything, in hosting, in infrastructure it’s always been a common theme. But it’s really, really becoming acute within the DevOps sector now. And we’ve assembled what we think is a great panel to discuss this issue. Let me introduce you to them and we will go from there.

    First of all I want to welcome, well, to a panel for the first time in a long time, my friend Larry Maccherone. Larry, welcome to DevOps Unbound. Give people a little background, if you don’t mind.

    Larry Maccherone: Sure. Thanks for having me here, Alan. First of all I want to say so I launched the Dev PsychOps Transformation Program at Comcast and grew that for five years. And I’m a developer at heart, though, so I was sort of the ideal person to take what was actually becoming more common outside of big enterprises, Dev PsychOps, and try to actually do a diverse approach inside of a large enterprise like Comcast. And so all of my experience is around that recently, the last five years or so, around that.

    Shimel: Excellent. Next let me introduce you, she’s a repeat visitor to DevOps Unbound. Garima, if I mess up your last name I apologize in advance, but Garima Bajpai. Close?

    Garima Bajpai: Almost. Yeah. So I’m Garima Bajpai. I’m based in _____, Canada and I’m the founder for the DevOps Community of Practice here in Canada, which has three chapters: Toronto, Ottawa, and Edmonton. I’m also the organizer of the DevOps Summit in Canada, which happens in November 8th and 9th. And I’m also associated with organizations like DevOps Institute as an ambassador, as well as CD Foundation as an ambassador.

    Shimel: Fantastic. And, Garima, I apologize on your last name. My bad. I’m trying to read it and the monitor’s too far away from me without my glasses. But thank you for correcting me, and welcome.

    Next up, another good friend of mine, my actually business partner on Digital Anarchist. And though that’s not his full-time gig these days; he’s very busy with his red hat career. The one and only Botchagalupe, John Willis. John, welcome.

    John Willis: Thank you, sir. Thank you, Alan. Hey, yeah, John Willis, Botchagalupe on Twitter. My current day job is in a team called Global Transformation Office at Red Hat. I’m sort of blessed to be on a team with Andrew Clay Shafer; Kevin Behr, the co-author of The Phoenix Project; and Jabe Bloom. Just quickly, you know, I’ve been in the industry for 40-plus years, 10 or 11 startups, 12 books, if somebody’s counting. Probably the most notable is the co-author of DevOps Handbook.

    Also was involved in basically the starting and building of the original DevOps Days. Was the only American at first DevOps Days and Damon Edwards and I created the first DevOps Days event in the USA.

    Shimel: Yep. And that’s only a partial list, John. Thanks for joining us today, man.

    And then I want to introduce – she’s off-camera right now, but hopefully when you’re watching this at least you’ll get to see her picture, but she was having some video difficulties, but happy to have her on audio, my friend, Ravyn Manuel. Ravyn, welcome. And if you wouldn’t mind, give people a little background.

    Ravyn Manuel: Thank you, Alan. I do appreciate being on your show. It is awesome. It makes me laugh. I am the senior application developer for the National Museum of African-American History and Culture. And I’m also the DevOps engineer for that particular unit. As a developer I implement some of the hands-on interactive that you play with in the museum, and as a DevOps engineer I am in charge of just about everything that’s DevOps, from the cloud solutions and how we – from the application development side, how we’re using cloud and the tools and writing strategies and keeping my leadership informed of all the good things that are out there.

    Shimel: Fantastic. Ravyn, welcome and thanks for joining us today.

    Last but not least, my co-host here on DevOps Unbound, Mitch Ashley. Hey, Mitchell, welcome. You want to just introduce yourself?

    Mitchell Ashley: Great. Great to be here. Man, what a panel. I am so excited to be with these folks on today. Yeah, I head up Accelerated Strategies Group, analysts from focusing on, of course, DevOps and digital transformation, full cybersecurity and cloud. And I also serve as CTO with MediaOps, so heading up the platform strategy and technology, so we used to deliver programs like this.

    Like John, I think we’ve been probably in the industry about the same amount of time and have zero books to my credits, so he’s made a lot more progress in those areas, but also a startup person and run a lot of software projects, product, as well as IT groups, as well as on the vendor side. So this will be a fun discussion.

    Shimel: Absolutely. I should mention DevOps Unbound is sponsored by our friends at Tricentis. To give you an idea of what a great sponsor they are, they don’t even have anyone on our panel today. But they do enable this show to go forward every other week, so many, many thanks to Tricentis.

    So, John, I laid it out, right, it’s the one throat to choke versus best of breed, how many vendors can we support, how do I package solutions that are more than just point solutions, or maybe I just want point solutions. What’s the answer here, John?

    Willis: The answer is, Alan, I would say if I had the right answer I’d be on a Grady-White right now in the Gulf of Mexico.

    Shimel: Exactly. And I’d be right with you.

    Willis: But no, I think this is a great panel. I agree with Mitch; I’m excited about just the discussions we can all have. I think the question – you know, I was thinking just that sort of Chinese curse translation, “May you live in interesting times,” right? And that’s clearly where we are right now. And I think your question starts with a shift, right? Like there was this – talking about you, Mitchell, some of us have been here forever, and like back in the day there was this question of one throat to choke versus should I do an ELA with computer associates versus piecemeal things, right? And probably less than one-percent of the enterprises were do-it-yourselfs.

    Now today you will find probably – I’m just going to swag the number, but it’s probably north of 10, maybe 15-percent, maybe even higher of companies that are now being challenged to do it yourself. You know, Kubernetes is a great example. That’s a can opener for companies to make a decision of are my vendors keeping up with what comes from basically sort of upstream technology that I should build myself.

    So I think that’s the sort of question we move into, is more about do you build internally to solve your problems, to keep up with the changes in the market and the technology, or do you try to find a pair of vendors or a single vendor – and there really is very few single vendors that can give you the whole scope of what’s going on in modern technology today. But I think that’s the question that I think we’ll have fun just talking about today. _____.

    Shimel: I don’t disagree. Panel?

    Manuel: So, Alan, this is Ravyn. I agree with you, John. I think one of the things – because that’s a struggle for me and my organization, is we need help with implementing DevOps, but I think the vendors are very tool-focused and the tools are like the third priority in the stack of there. And what I’ve been doing when I’m building the strategy for how we’re going to implement DevOps, I looked, and we’re talking about tools. I look at the standards, because if they’re making standards and the tool has to follow that standard then it’s plug-and-play, you don’t get – like if Docker decides that they’re going to go out of business then you can have another container-type technology to do that.

    So when we are looking at benders we actually kind of do a piecemeal, because we’re really unicorns. We’re not a software company, we don’t have software products; we have digital products, and they’re all one-offs. And so it really just depends on what fits for us. So we don’t really go for the one vendor solution; we actually go for who can help us get to where we need based on our business problem.

    Bajpai: Excellent. And I wanted to add a few things, because when we drill deeper into this conversation we will find out that there are two sides of this coin. One part is where an organization from a maturity perspective is. And the second thing is what are the vendors and key capabilities you’re looking at. But if you look at both sides of the coin there are three things which are needed to calibrate these DevOps tools in the overall context. The first thing, and this is – I want to reiterate the fact, because I come from a very large complex organization background, that it is very essential to have an enterprise architecture view. So I would suggest and recommend that before even, you know, taking this approach of single vendor or multivendor discussion, we need to kind of break down what are the key capabilities which are needed. So whether it’s a single vendor which can provide you that enterprise IT architecture capability, or it will be your organization who will be doing it. So that’s essential.

    The second thing I think which is also essential is orchestration layer. You know, you will have to have that governance of total cost of ownership, compliance, security, identity access management, and that orchestration layer has to be there to stitch all you calibrated DevOps tools. So it’s a question of whether you want to kind of build it in house in that organization or you kind of have a vendor-centric approach where this capability should be or could be brought in.

    So these are like two things, and then you start calibrating these DevOps tools. So you don’t have to look at the foundation aspects of compliance, security, governance, total cost of ownership, and the job becomes much more easier. The question is that, you know, how to bring these DevOps tools and enable business value.

    Maccherone: So I want to riff off of that orchestration layer idea, but I want to backtrack a little bit on sort of the – we have a binary sort of difference here between unicorn and best of breed. But I think within the unicorn bucket there’s really two major flavors of unicorn that are wildly different, and so I want to sort of bring that out. You have these Frankenstein vendors that are piecing together acquisitions into this monster and those are not pleasant experiences. The only benefit you get out of one vendor in that case is really the contracting benefit of having a single master service level agreement. You’re not getting an integrated product that really allows you to actually smoothly do the workflow, insist in the workflow that developers are using to produce value for your company.

    And then you have this other class of unicorns in the DevOps world, but less so in the security world, and I’ll talk about that in a second, which have taken a marketplace approach. And this is not a DevOps vendor, but I think the first vendor to really pull off this marketplace approach was Atlassian. You know, they had one product that was really great, but they said, “Okay, plug into this product” and they created APIs and they created toolkits and they created a whole community. Most of those people did it for free and they just sort of did it for themselves and then they shared it with the community. But some of those people became vendors and sold their product in the Atlassian marketplace, and then Atlassian acquired those. They were already pre-integrated with Atlassian’s other offerings when they got acquired, and so their acquisition unicorn approach doesn’t look like a Frankenstein’s Monster in the end, because they were built with the APIs of the vendor in place.

    And I think Github is definitely taking that marketplace approach and pulling it off really well, even into the security space. And so I think that kind of unicorn – and Github to a lesser degree, that kind of unicorn doesn’t suffer from that Frankenstein Monster’s sort of problem. No one in the security space has really pulled off the marketplace approach yet, though. We have some Frankensteins and Frankenstein Monsters over there, but we don’t have a full sort of marketplace approach. And I’m waiting for somebody to do that. I think that’s going to be the big win, somebody _____.

    Willis: I’d like to do a whole podcast on that, because that’s all I’ve been thinking about right now, is what is the end-to-end on security. But like if I got into it now it would take up way too much time. So I did want to comment on some of the things. You know, the first, Ravyn, I think the interestingly about standards, I agree, right? The problem we have right now is figuring out which standards are actually going to last, are malleable. I mean that’s one of the things I’ve really been working hard on and looking at like OSCAL versus OVAL versus S-CAT versus, you know, just NIST _____ – in order for – I mean there’s just so many things and they all sort of have a little bit of different approach.

    So I agree, the question we have to deal with now in these sort of, you know, may we live in interesting times is it’s like picking sort of an early vendor, like I like this vendor technology, but are they going to be around? Are they going to be acquired by a company that I don’t really want to do business with? I think the standards is just it’s such complicated.

    Just the other thing I wanted to say is I think that for vendors, you know, and I’m not _____ ’cause I work for Red Hat. Because I will say right now the thing that like in the grand scheme of technology, if you’re going to go all in a vendor, look around. You know, I’m going to say this. I’d love to be corrected and I’m not saying, you know, Red Hat because I work at Red Hat. Anybody that knows me, I’m not a shill for any vendor I’ve ever worked for. But it’s VMware and Red Hat, right? They can keep up with – because you’ve got to – in this world you have to have people on staff, their full-time job are contributors to an open source project.

    And if you think about what’s going on with like Kubernetes and clusters and server list, you know, you think of the two companies that are positioned really well at that sort of scale version to be able to keep up with the complexity and change of technology because they’ve put the resources in. I mean a longer list that you can probably make after that. And I’m not including the cloud providers either, ’cause that’s a different story.

    But anyway, those are the two comments I wanted to make on some of the things people talked about.

    Ashley: I just wanted to jump in. What’s fascinating about this conversation is how diverse and complex it is. There are a lot of aspects to consider, whether it’s an enterprise architecture like Garima is talking about, John’s talking about, who are the vendors that can pull it off. Larry is too, if you’re talking about this sort of roll-up strategy, but retro-ally integrated strategy.

    I think another dimension to consider is every organization has a DNA about how they think and operate when it comes to vendors and software and tools. And while I’m not always an advocate of go with the flow, sometimes when you’re thinking about how do we have something adopted, think about how the organization operates. If you are kind of a large tool vendor, let’s work with, you know, Red Hat or VMware or Broadcom or whoever might be – think about that. That’s oftentimes, you know, save yourself some brain cells and live a little longer.

    There’s also the innovation curve, and some of the best ways to ride the innovation curve is the open source route and the vendors that are built around that kind of a strategy. There’s combinations of all those.

    So I guess the thing I would add to the consideration of the conversation here is think about how you match up your strategy with the DNA of the organization so you can accomplish as much without killing as few brain cells as possible.

    Bajpai: And thank you, Mitch, for bringing up this point of DNA of an organization. I think that this is a pathway of dialogue which we are having. I do believe that the mindset is shifting, and even I see in large legacy enterprises that they have started to realize that, you know, this vendor-based approach is something that needs to shift, and they need to bring people as partners in this context. Because when you think about DevOps it’s basically exploring your opportunities, breaking the barrier for, you know, your technology onboarding, the gaps – the alignment and outcome gaps you have created in the past.

    I think this is the opportunity where the organizations can shift and bring more access to innovation through these partners. So I truly believe that there are softer aspects of this conversation as well which we need to kind of consider that traditionally how contracts are _____, you know, how we look at these DevOps tools from a vendor perspective, how can we bring them as partners, what we need to change if we start doing that.

    It’s not kind of done overnight, right? So we have to kind of set what kind of modeling practices we need to bring in. And this opens up another door of possibilities. And probably during this conversation we will have some opportunity to discuss these SLA constraints which we have built in the organizations which steer us to a specific vendor or steer us to like a specific window through which we can outsource a lot of capabilities and just, you know, a choke the throat approach, right?

    So let’s maybe in the upcoming discussions we also can bring these points and highlight.

    Shimel: Ravyn, I know Smithsonian is sort of quasi-government, or it’s not true government. But to Garima’s point about SLA and being able to only deal with chosen vendors like that, it is; it is a real governor on your ability to choose best of breed, on your ability to have choice in how you want to do things. Interested in your experiences around that.

    Manuel: It’s been difficult. I’ve been listening to this conversation and it just hit – I don’t know why it just hit me, but the vendors – and I love Red Hat, so I’m not trying to talk Red Hat or anything, and open-ship. But when you get a vendor that you have worked with and you trust, and Smithsonian, we use Red Hat a lot in our OCIO. Red Hat is doing open shift and Kubernetes and they are driving their tools to these specific tools. And for me, as a unit within the Smithsonian, I may not want to use open shift and I may not want to use Kubernetes, but I don’t actually have a choice, right? Because that vendor is a great vendor and they’ve got great tools, but they have chosen for me what I am going to be using, and that makes it really hard for me to say “Does that really fit what I really need? Is that too much?”

    Because I can tell you that a lot of the vendors that I talk to, they’re expecting us to use this like suite of products, and it’s too much for what we want to do, and so I’m left with I either go with this vendor and overspend and use tools that I don’t really need, or I have to do it myself because I can’t really find somebody that can customize that for me. So it’s a challenge.

    Shimel: Yeah, it sounds like it.

    Willis: You know, one of the things I struggle with, you know, I sort of love committees and hate committees, right? Because like I so – HashiCorp has this cluster manager called Nomad, and I’ve actually seen people use it effectively with like incredibly less toil, 80-percent of the features of it, but it’s never going to get any escape velocity. It hasn’t and it won’t.

    And I fear for our industry that we’re like so focused on there’s just only one way to do cluster management today where like – so to Ravyn’s point, like whether it’s Red Hat or whatever, it seems like you’re not even able to explore possible emerging containerized cluster management solutions because all of the oxygen in our industry right now is consumed by Kubernetes.

    Manuel: Amen.

    Shimel: Thoughts on that? I’d like to jump in with some thoughts on that. I mean this is sort of a dream/nightmare scenario. Right? I’ll take it – let’s take it off Kubernetes, let’s go back to PC operating systems. It was great that we had only Windows to develop on, and this way if you were an inept developer you only had to worry about developing on Windows. You had one operating system, you could make your app on it and it worked and you got 90-percent market share with it. What a fantastic thing for app developers. Of course, it gave Microsoft the inside track on Office and everything they did. And from a security point of view what a big, fat juicy payload that was, right, to go attack.

    So then we started seeing, for as long as I’m in IT, “This is going to be the year of the Linux desktop.” Right? How long have we heard that? And so, you know, and then of course Mac resurfaced.

    But this is we strive for some uniformity. We strive for Kubernetes to be the standard, ’cause it’s open source and it’s run by a foundation, and we want a standard. But then we chafe that, “Hey, we all can’t fit into that same standard. We want to be our own unicorn.” And that’s really what we’re talking about here today. If you go back to early, John, you sold the company to Docker before Kubernetes dominance, right? And there were several cluster management solutions vying. Right? There was Mesosphere and Rancher out there _____.

    Willis: Mesosphere and _____, yeah. [Laughs]

    Shimel: You remember. Yeah, _____ of these, exactly. So, you know, this is – but this is the world we – you know, to quote Hyman Roth in the Godfather II, “This is the world we chose to live in,” right? We strive for these single kind of standards that one-size-fits-all. And maybe that’s a huge mistake; I don’t know. Maybe it is a mistake. Larry, what do you think?

    Maccherone: Yeah, I do see that problem, John, you’re sort of focused on here, that sometimes the de facto standard is not the best technical choice. You can go all the way back to Betamax versus VHS, for those of you who are old enough to remember that, right? VHS won out, but Betamax was considered by everyone to be a superior technology. Why?

    You know, so I think if you’re going to take a best-of-breed approach you’re going to have to – when you have a true de facto standard like Kubernetes you don’t have to isolate yourself from it, but when you’re making a bet on which one is going to win out – and John is really good at this; John talks about this all the time. John sort of like doesn’t want to put his chips down on something that’s not going to survive long-term, so he wants to think about what’s going to survive.

    So in order to hedge your bet there I think you need this orchestration layer that was talked about earlier. You need to sort of isolate the tool vendor from the way it’s consumed to a certain degree, so you can plug-and-play a little bit as time goes on. And this is what we did at Comcast, we built a layer between all of the tool vendors for security tools, because they don’t have a good unicorn solution there. There is no good unicorn solution there anyway, even if I wanted to. And so we had more than one vendor in every tool category competing internally, and sometimes we had three tool vendors. But from the developer’s perspective it was really easy for them to switch out from one to the other, and they got the same feedback channels, they got the same visualization, it aggregated and scored the same way across all these different vendors.

    I think that orchestration layer is really key when you have a best-of-breed approach, and I think you have to build it yourself. I don’t think you can buy it today. I really don’t think you can do that.

    Willis: I’ll try to shut up quickly. I just want to make a comment. I think there’s two books that help us understand our world. One is Guns, Germs, and Steel by Jared Diamond, which actually shows you why we get into these predicaments. If you haven’t read it, it’s a fabulous book. And then Start With Why by Simon Sinek is the sort of anti-pattern to that, which I would say like there’s clusters – atomic computed things like sort of serverless or functions or containers will be around for 10, 15 years. Clusters of those things will be around for 10 years. So if you think in those terms instead of thinking about Kubernetes and Docker – and Docker is already slowly dying, then you get that sort of start with why isolation against these sort of Guns, Germs, and Steel trends.

    Bajpai: Right. Then I also wanted to kind of bring another aspect of this, which is connected, but I think companies might start looking at it from a scaling perspective. We talk about a lot of tools and how to calibrate these tools in our DevOps pipeline. Of course when you have a large organization you have multiple product lines, and these product lines will choose to be flexible, so they need to have that flexibility to deploy their DevOps pipeline in the way they choose. And that’s the whole power of DevOps, right?

    But I also feel that the conversation in this discussion is leading us to a point where we start looking at our technical oversight committee from a governance perspective, where we can stitch the dots, we can actually lay that common foundation which is required in order for people not to kind of rewind the _____ over and over again. So I think that’s the key here.

    And of course when we talk about a specific random _____ with huge capabilities it has pros and cons, right? So one pro would be like they can mutually enforce new capabilities. So when they bring one feature in one product it’s mutually enforcing another product, which is a beautiful advantage they bring in. But that also limits our possibility to look beyond what the vendor is bringing in. So we are kind of essentially not exploiting our own innovation cycles to introduce more capabilities around how we want to experiment, how we want to kind of build innovative new features into that life cycle.

    So these are kind of good considerations to look at and I truly believe that the technical oversight committee is something that you will see in large organizations a wave kind of starts in a bigger way when it comes to DevOps.

    Ashley: And there’s interesting too, when you think about different sizes of companies that are in the market for technologies, you know, Larry mentioned what he did at Comcast or what he was part of that was created as sort of an architecture where tools can be plugged in, unplugged, replaced, etcetera. It sounds simple, but I know that they have an architecture to do that. And some organizations have the wherewithal to create those things. What we see in the data, looking at the market, is in the small business, the kind of sub-200 people or so companies, they have really good high-performance teams that can work to create software or set up their own environments, kind of create a very productive setup for themselves, tool chains, etcetera.

    Then on the high end or the large end, the enterprises, you know, they have a lot of resources available to them that they can potentially marshal to figure out how to do some of those things. The mid-tier market, the medium-sized company is often where they’re most challenged to – they want to do what the enterprise can do, but they just don’t have the resources. They don’t have the money or the vendor relationships across the board to do all those things and they’re expected to deliver at almost an enterprise-class level, but they don’t have all of the resources to be able to do that. And that’s often where somebody – the non-Frankenstein vendors that do a good job of kind of delivering a suite of solutions can work in those situations. Not that they can’t work in the others; they can, too.

    But depending where you are in that kind of a company, that size of a company, makes a big difference on what strategy you can take.

    Maccherone: I think that’s a great point and my recent experience last five years has really been enterprise. But prior to that I was talking to lots of companies, and you’re right, the mid-sized companies are the ones that are sort of in that no-man’s land sometimes, where they need some standardization, they need some consistency, but they don’t have the wherewithal to put it all together. And a vendor unicorn approach might actually be better in those circumstances.

    Shimel: Hey, guys, I want to – Ravyn, I’m going to let you in a second. John, the name of the first book that you mentioned – I want to put these books in the notes somewhere.

    Willis: Oh yeah. I did a presentation with Josh Corman way back with Guns, Germs, and Steel. Anyway, it’s an amazing book about how civilizations move from sort of – you know, how they go from sort of agriculture and they move into these clusters. If you can see the forest beyond the trees you can see how we get into these like Kubernetes is the only word we can use. Anyway, Jared Diamond, Guns, Germs, and Steel, it’s incredible.

    Shimel: All right, we’ll try to get it in there. Ravyn, did you want to say something and I cut you off?

    Manuel: No, I don’t think that was me.

    Shimel: Garima?

    Bajpai: Yeah. I wanted to actually enhance what Larry was saying about midsized companies. This is totally based on my experience and exposure with the Canada DevOps Community of Practice. We are seeing more and more of these midsized companies, not only the consulting companies, as well as the companies who want to build a DevOps capability coming to the community of practice and starting to steer this discussion of evaluation and assessment of tools. And I’m also seeing that the winter side. You know, specifically we are talking about tier two companies here. The winters and coming and exposing the tool capabilities in the community of practice, and they want some support and help for us to kind of steer this conversation “Is this a good tool? Is this a good capability where they are in their context?”

    And it’s a very interesting discussion because the technical side is one side of the story. I would also like to kind of emphasize the fact that the questions we ask these vendors and these companies are like, “Okay, do you have a product owner for this product?” Because essentially, you know, what it means is that how accountability is built in a specific tool perspective. I also kind of ensure that we ask them what kind of themes they have, like what kind of cross-functional themes they have, so that we do not miss out on the point of interoperability, integration, automation, all these like are important points.

    So I just wanted to mention that how we take that approach from the community of practice perspective when we’re asked to kind of assess.

    Willis: You know, I totally agree with all of that. One of the things I was thinking about, I’ve had this luxury of being involved in these different communities. Like I’m in Alan’s community, you know, so I’ve gotten hooked into usually what’s interesting and going on in Alan’s world, which is a pretty big world. I’ve been hooked into Gene’s world pretty heavily, you know, DevOps Enterprise Forum/Committee. And then, you know, I’m one of the co-founders and advisors for the DevOps Days.

    And one of the things that I get to see is true leaders. And I don’t want to put all this sort of weight and gravity on like you have to have a great leader to be successful, but like as I think about the people – Larry is a great example. Like, you know, you can talk all day long about what Comcast does. I’ve seen Larry in action. Like that’s the kind of guy you want in your enterprise.

    Courtney Kissler now, you know, was at Nike and now she’s moved on to a startup. Ross Clanton now at American Airlines, Heather Mickman. I mean I can go on on the list, but these are people that impact change in larger organizations that where it’s incredibly hard. And there’s just something about that.

    Maccherone: There is an immune system at large enterprises, though, that makes it hard for someone like me to actually be hired and be successful. You know, the idea of disruptive change is not something that enterprises are sort of seeking out ever. And so if you’re sort of like grassroots and you’re sort of like ground up and you get a few pilots going, that’s easy; there’s not a lot of resistance. It’s when you get enough momentum that somebody feels like their domain is threatened that you get the political pushback in an enterprise. And, you know, that’s really hard to overcome. Companies have to be very conscious about that. And Comcast has done a great job of that for me in the past, but I see it in the nature of the enterprise immune system essentially.

    Ashley: We probably could take any one of those last three comments and turn that into a whole other dialogue. Maybe we can get some help from the folks in the production department for pulling us back together.

    Alan, do you want to close this out?

    Shimel: One thing’s for sure, is we’ve got a lot more to talk about on this subject. I’d love to – I invite you all back to continue the conversation. But for now, Ravyn, I appreciate you soldiering through this on audio only. If we do it again we’ll make sure to get that video working. Garima, always a pleasure to have you on here; you bring so much. Larry and John, what can I say, it’s a pleasure to see you guys. I can’t wait till we can see each other in person. I know a lot of us have gotten our shots; it won’t be long. But thank you so much for adding so much. Mitchell, fantastic job.

    Most of all, hey, thank you people that are watching this, because that’s why we do this, is for you guys to get something out of it, join in the conversation, let us hear what you’re thinking. Many thanks to Tricentis for sponsoring DevOps Unbound.

    Until next time, though, this is Alan Shimel, Media Ops for DevOps Unbound. Have a great day, everyone. Bye-bye.

    [End of Audio]

  • EP 11: Unburdening Developers

    EP 11: Unburdening Developers

    Every app development need seems to ultimately fall to developers to fulfill. Build in security. Shift testing left. Provide users cooler, more customized experiences at cloud speed and scale. And do it all faster, of course. How do we accommodate the rising expectations without burning out developers? What can other team members do to lighten the load and allow developers to focus on the creative work they require to thrive? In this episode of DevOps Unbound, hosts Alan Shimel and Mitchell Ashley are joined by panelists Adam Kalsey of Tricentis, Tracy Ragan of DeployHub and Justin Hutchings of GitHub to talk about unburdening developers. The video is below, followed by the transcript.

    Alan Shimel: Hey, everyone. Welcome to another episode of “DevOps Unbound,” sponsored by our friends at Tricentis. We have a good, nice topic I want to talk to today, and you know, I refer to it as the straw on the camel’s back, but it’s about the ever-increasing load that developers seem to be taking on with technologies and frameworks such as DevOps and Agile and so forth that we’re seeing out here. And we’ve got a great panel to explore this. Let me introduce you to them before we go any further.

    Let me first of all introduce you to my friend Justin Hutchings. Justin is with GitHub and he’s gonna tell you a little bit about himself. Justin, welcome.

    Justin Hutchings: Thanks, Alan. Yeah, I’m Justin Hutchings. I’m a director of product here at GitHub. I work on some of our security features for developers, you know, whether that’s things like static analysis, security testing, or supply chain kind of features for developers in opensource and the enterprise. Glad to be here.

    Shimel: Nice to have you here, Justin. Welcome. Secondly, she’s a frequent guest here on “DevOps Unbound” and other MediaOps videos, my friend Tracy Ragan, CEO of DeployHub. Tracy, welcome, maybe a little bit about DeployHub and you for the audience.

    Tracy Ragan: Absolutely. Thank you, Alan, and thank you, Tricentis, for having these and always welcoming me on these panels. I like doing them. So yeah, I’m Tracy Ragan, CEO of DeployHub. DeployHub is a hub of metadata for deploying and configuring microservices. So we do automated configuration management so you know what your blast radius looks like for a microservice before you deploy. I’m also on the board of the CD Foundation, and you might see me oftentimes evangelizing around microservice usage.

    Shimel: Yes, we do. And then – welcome, Tracy. And then last but not least as a panel member today is Adam Kalsey. Is that pronounced right, Adam?

    Adam Kalsey: It is, absolutely, yes.

    Shimel: And Adam’s with Tricentis, but why don’t you tell us a little bit, Adam?

    Kalsey: Yeah, so I lead developer relations at Tricentis, and we make software to help people make better software, to test it and make sure they have higher-quality software. And my role is to help make developers more awesome by helping them make better software.

    Shimel: Thank you and welcome. And then last but certainly not least is my cohost for “DevOps Unbound,” Mitch Ashley, CEO of Accelerated Strategies Group, CTO here at MediaOps. Mitchell, welcome. Great to have you on.

    Mitch Ashley: Always good to be here, and having been part of many development teams, I’m excited to talk about this great topic.

    Shimel: Great. Let’s dive into it, guys. You know, when I started devopsy.kinsta.cloud about eight years ago, there was this constant push and pull. Was DevOps too developer-centric? It was all about the developers, the ops said. This DevOps thing is just – it’s all about the developers; we’re not getting our fair share. And you spoke to developers and it was, “You know what? DevOps is too ops-centric. It’s not about the ops. It can’t be everything ops. It’s got to be about developers.” And so there was this, you know, friction about was it too developer-centric or not.

    Over the years, though, what I’ve seen is an increasing amount of responsibility seems to have shifted left, as we say, right? And we shift left, and when we shift it left, we’re primarily – we’re shifting it to the developers. So things like testing, for instance, right, have become – developers are probably more involved in testing, or at least kicking off testing and this stuff, than they ever were. Security – certainly the whole rise of the DevSecOps movement has been about shifting security left, and in fact many of the most successful security companies in the DevSecOps space have become successful by making security tools for developers. We’re making testing tools for developers. We’re making tools to look at your blast radius for microservices for developers. Developers are deploying, right, as part of their DevOps focus.

    When is enough? When do we break the developers’ back? Not to mention the developers are the highest-paid people in the food chain, right? So by giving them everything, are we giving them nothing, right? Are we stunting their productivity? Adam, being that you’re the new guy here and you actually are in charge of developer relations at Tricentis, we’re gonna ask you to kick it off. Are we putting too much on the backs of our developers?

    Kalsey: I don’t think so. I think that the promise here is that we make things easier for the developers. I mean, sure, you have more tasks. There’s more things that you’re responsible for. But the overall effort and the amount of work that has to be done ends up shrinking. If you don’t find out about a bug in your software or a security problem or such until you’re in production and customers are using it, now all of a sudden you’ve got way more work to do. It’s harder. It’s more expensive. It’s more difficult. There’s more involved in doing that. And so by moving a lot of these things forward, we’re letting the developers be more proactive in taking care of them. We’re helping them get things fixed sooner. We’re reducing the amount of toil that developers have to do. Yes, there’s more upfront work, but that long-term toil starts to fade away and disappear.

    Shimel: Fair enough. I don’t know if you – you know, I don’t know if I’ve ever heard someone say developers are – you know, it’s making it easier or less for them. Justin, what do you think?

    Hutchings: You know, I’ve talked to a lot of companies that are the early stages of their DevOps transformation, and I think one of the most common mistakes that these companies make is they fail to recognize that adopting DevOps requires both technical changes as well as cultural changes. You can’t just get rid of the testers and say engineering owns tests and expect the same velocity. You’ve got to build out the infrastructure to support that, you have to do the training, and you also have to recognize your throughput is going to be less while you’re paying down that sort of debt on getting that infrastructure and getting the automation and getting all of those things.

    Companies that fail at the DevOps transformation, they go through sort of the motions without understanding the culture and talking about it. You know, years ago when I worked at Microsoft, the Windows team sort of famously had a one-to-one ratio between engineers and – software development engineers and test. These were folks that wrote test automation. And there was a big layoff, thousands of testers got laid off, and they said, “We don’t need them anymore. We have observability tools. This will be great.” And that was the most naïve statement I had ever heard, and it took a year for the organization to fully rebound, to figure out what the right set of responsibilities were for engineering, and how to support those folks effectively on it.

    Shimel: Fair. Tracy, in your roles, both at DeployHub and CDF, you’re dealing with both constituencies here, right, the traditional DevOps teams. But let’s face it: You’ve got dev and you’ve got ops in there, and you deal with both. What’s your take from the battlefront?

    Ragan: Oh, my goodness. I could write like a 20-page blog on this. I guess that wouldn’t be a blog. It would be a research project. [Laughter]

     Shimel: Or a book.

    [Crosstalk]

    Ragan: Yes! So I think that in my discussions with folks over the last six months, eight months, I am seeing a lot of SREs really stressed out. So I don’t know if it’s the development teams that are really taking the brunt of this, but if we think about our history and how we got here, we’ve always had somebody really important on a development team who always worked in hand with the operations side of the house to find out what happened, to help with the deployments. Even if they’re sitting there watching the operation first and hit the button, they’re the person that’s always taken this responsibility. And I think the DevOps movement was an effort to push more operations tasks to that trusted partner on the development team, and now that role has turned into an SRE.

    I would say five years ago we wouldn’t have seen this kind of stress, but because we’re going through this massive tsunami moving from monolithic to microservices, and we’re in a transition phase, we are putting a lot – what I see is we’re putting a lot more stress on the SRE role. Developers are going to the SRE, operations are going to the SRE, and the SRE is just trying to keep up with the underlying technology that’s wobbling and moving. You know, they’re trying to figure out how to stand up environments easier. They’re trying to implement Terraform or Rancher. They’re doing everything that they can right now to try to keep up, but they may be underwater for a bit longer.

    So when we think about where the stress point is right now, I think that developers have pretty much automated a lot. You know, we have tools like Tricentis to really improve the testing, but now we’re int his weird phase where we have these SREs that are trying to straddle both worlds. And they’re struggling.

    Shimel: Justin, you know, in your role there – and, guys, I don’t mean to call. If you want to say something, feel free to obviously jump on. But, Justin, I’m wondering – you know, GitHub has sort of a unique view with this.

    Hutchings: We’ve been trying to push folks towards more automation, more DevOps, you know, DevSecOps with all the security features we have. You know, again I think culture is the key. I look at anytime you have an unfunded mandate, you know, it’s gonna fail. A lot of times organizations will say we’re going to microservices or they’ll say we’re gonna adopt all these security tools, and then they don’t think about how that actually gets done and they don’t recognize the sort of pain and training and all of the things that have to happen to get folks there.

    You know, and I think there’s been a lot of advancement here. You look at the state of observability. You look at the state of CI/CD. Things are getting better, but I think, you know, we in the industry that sort of work int his space sometimes paint such a rosy picture that our customers aren’t prepared for the hardness of the journey that lies in front of them. And they’re looking at how do I get to the magical garden of DevSecOps, and the magic garden is there, but it is not a free entry, you know?

    Ashley: You know, Justin, to what you were saying, I think along with culture, part of is a role change that’s happening across the whole organization, right? A couple things are happening. We’re doing not just automation that the developers are doing, clearly SREs. Other test automation, infrastructure as code, you know, those are all development that’s happening to support those. It doesn’t say that every person is an expert developer, but there’s some development, scripting, other kinds of skills that come with it.

    So I don’t know if we’re so much loading it on the developer as much as we’re elevating our level of automation and kind of interconnected of the process, and we’re helping people evolve and growing their strengths – let’s put it that way – to also include some software development, or more closely working with people that can. I think that’s part of that cultural change, too.

    [Crosstalk]

    Kalsey: One of the things that’s actually happening there is as things become more development-centric and, oh, now it’s Toad and now it’s – the teams are making exactly the wrong lesson out of this and they’re learning the wrong thing out of it. You know, one of the things that Justin said earlier is, “Well, we got rid of all the software testers because the developers are doing the testing now,” and that’s one of the dumbest things that you can do as an organization, is say, “Well, now that my developers can do this, let’s get rid of all the experts.” And instead of saying, “What is the new role of this expert and how does their role change?” whether, okay, now they learn to code so that they can expose more of this as code, or do they become consultants to the developers and help them do this right and help them understand how to do this right? Could I remove a lot of those pieces of toil and a lot of that extra stuff from them and let them focus on the things that they’re good at – writing the code, building the code, thinking through the problems – and let me focus on the things that I’m good at – thinking about the infrastructure, designing the infrastructure, designing test plans, thinking about the non-happy path?

    And so companies – I talk to companies all the time that say, “Well, we’ve moved – all our developers are doing the testing now, so we got rid of our QA department!” And that is – that’s just frankly dumb. Don’t do that.

    Ragan: I think it was an outcome of the Agile movement, right? Because we started preaching this idea of bringing everybody into the same room together to do these tasks. So we broke up our testing departments and we spread them out across all of the teams, as well as some of the operations, which is how the SRE title came about. So, you know, first we siloed and then we tried not to silo. But ultimately it is how do you come up with a strong automation standard across the organization? And how are you gonna implement it? If there’s a testing team that has a group of people and each one is assigned to an application team, or if you have a siloed testing team and a siloed operation team, ultimately we’re still pushing the same product through the lifecycle. So how well do we do that? And maybe Agile confused things for us for a while and kind of broke things up and disrupted what we were doing. So now the task is how do we move forward with where we’re at to make it continue to be easier to get things across the pipeline?

    And I have to say that one of the biggest challenges I hear from people is that continuous integration works well; continuous delivery from dev, test, through prod doesn’t work so well.

    Hutchings: Yeah, and I think, you know, what you hit on there, Tracy, is really important because, you know, when you have an organization where the engineers are the only thing and engineers are undifferentiated and treated as some sort of fungible resource, I think things fall apart. You know, what I’ve seen in successful organizations is they have some subject matter experts, whether that’s SRE or a data team or an infra team, that are building out things that make the rest of the organization able to scale. And that’s a really good, healthy blend where you’ve got experts that you can lean on, but then engineers are empowered to do sort of the last-mile delivery there.

    Kalsey: Yeah. When a company says they’re gonna create a cross-functional team and then they eliminate most of the functions, that’s a problem. I mean, you don’t say I’m gonna have a cross-functional team, so we’re going to bring product managers and designers in and, oh, by – now we just don’t need product managers and designers. So why do we do that with operations, with testing, with all of these other things that are important for software creation? You know, eliminating those and just saying, “Well, the developers will do it,” of course that makes for a lot more work for the developer. The way that this needs to work is keep those cross-functional teams and change their role and bring them further – bring them earlier into the developer cycle. Have them involved in design. Have them involved in figuring out what the product is going to do and how it’s going to do it, not just let’s get rid of them. The options aren’t they happen at the very end of the process or we don’t have them at all. It’s let’s bring them up further along in this process.

    Shimel: You know, part of it, though – and I don’t know if anyone wants to admit it – is that there’s sort of this bias that everyone else on the IT team aspires to be a developer ’cause that is the ultimate kind of thing. So, for instance, it was this way certainly in testing, that being a tester was a waystation on the way to being a full-blown developer, right? Or maybe a developer who wasn’t that good, well, he could do testing, right, and that testing in and of itself wasn’t a “profession.” It was really just like a junior developer did testing. And, you know, security people, well, they were always the rebels, right? Half of them didn’t have formal training. But you know, operations, the SRE folks, right, how much of a developer heritage or pedigree is there in what you need to be able to do from an SRE perspective? And so when we put together these “cross-functional” teams, it’s almost with the idea that, well, you’re all gonna be developers now, right? You’re gonna reach your lifelong ambition by being in this DevOps team as part of a developer. And we lose out on the professional tester, on the professional SRE, on the professional security person, right, in this rush to all be developers. What do you think about this?

    Ashley: Well, I think we did this to ourselves in the DevOps movement. You know, I remember when I first wrote my first article on devopsy.kinsta.cloud about what is DevOps and I was sort of grappling with it myself, the mantra was, “We don’t need operations, we don’t need test, we just need developers. Code or developers writing code will eat the world.” And it wasn’t outsiders that said that; we said that, or subsets of us said that. And I think we recognized after we got into it, no, as Adam points out, those are exceptional skills. Frankly some of the worst testers I’ve worked with were developers. They were terrible at testing their own stuff. They were great developers, right? But some of it is elevating maybe too much the role of the developer to be the rockstar beyond the platform, if you will – and there are fantastic developers. I don’t mean there aren’t. But there are amazing, amazing test people.

    And so let me put it to you this way. When I was running product development at StillSecure with you, who did I listen to? The testers. I listened to them and I asked them, “What problems are we finding?” and I could tell if we were ready to ship, not just by the numbers but by their opinion. And that’s why I really relied on, because they saw it from a different perspective than a developer does. So that’s my opinion about it. Now feel free to disagree. Anybody can take me on and say I’m full of baloney.

    Hutchings: So I was gonna say, Mitch, you know, have folks heard the story about – what is it – the IBM Black Team that they developed back in the ’80s for testing where they – basically testing was a sort of poorly-regarded function in the organization? And they ended up creating sort of a hit squad that famously would go and just destroy people’s code. And they created a culture around that, and they created sort of an ethos of that being a special place to work. And I think that’s something we need to find with our developers. Like, if we only celebrate the developers that make the shiny features, we’re not gonna be in a good state. We’ve got to celebrate the developers that can destroy other people’s code with tests or can build something that scales really well or that build great observability things. Like, it can’t all be how many features did you ship; it has to be how much you contributed to the whole.

    Ragan: Yeah, and I – you know, I think, Justin, that the cultural discussion is one that any team that’s going through this experience right now that we’re describing, that the developers do feel burdened in some way, they should be looking at how they have built that team. And kind of each role should be a specialist role, and they all have to be an equal role. And if you don’t have that, you really haven’t created an Agile team and that team’s not gonna become a high-performance computing team, because it is about equality on the team and the ability for every single person to stand up – tester, the SRE, the junior developer – and be able to communicate problems as they see them in an equitable way and not feel that they are being judged.

    And I have learned that from working in an opensource community. I’m really amazed how well the opensource communities work together, ’cause you have people with all kinds of different backgrounds, and it fascinates me to see how much they can accomplish and how well they accomplish it when they’re not all working for the same company and they’re there because they want to be. So how do you create that opensource kind of nurturing culture within a particular team if it’s built especially around Agile, where we’ve taken operations and testing and developers and, you know, other specialists and put them on the team – documentation, requirements gathering – and how do you make it an equal team? That I think is the challenge to keep the burden off of the developers’ backs.

    Shimel: You know, and that – paradoxically, that’s also the big attraction to like cloud-native communities, to these opensource communities, because I think people recognize the – and I don’t mean it in a bad way – the kumbaya kind of spirit that these opensource communities foster. GitHub, quite frankly, Justin, right, if you look at the history of GitHub, that’s probably been one of the huge drivers of 52 or whatever it is million accounts on GitHub, is that sense of community, right? How do you build that sense of community interdisciplinary across your teams within an organization? Adam, you know, though the role says DevRel, it’s really TeamRel, right? And you know, it’s got to be part of your mantra there, part of your job description, isn’t it?

    Kalsey: Yeah. One of the things that is interesting about when you look at opensource is the person who wrote the documentation is a hero, because nobody wanted to write the documentation. The person who wrote the tests is a hero because, wow, they’re writing the tests, and that was a lot of work and I didn’t want to do that amount of work. But then when we go into a company we say, “Well, we’re gonna hire a couple of QA people to do the testing because they’re cheaper than the developers.” And, well, yeah, maybe if you’re hiring bad QA people they’re cheaper than the developers, but if you’re hiring good testers, they’re as expensive or more expensive than the developers.

    And so in the opensource world we look at it and we go, “These people are peers and equals,” and then we come into a company and we say, “They’re second-class citizens, and we’re gonna hire a couple of tech writers ’cause they’re a lot cheaper than having the developers write the documentation, or we’re gonna hire some testers, or we’re gonna hire some ops people ’cause the person to watch the dashboard is way cheaper than having a developer do it.” And we’ve seen it happen with the SRE role where, when we elevate that and that becomes part of the development team, the other – SREs are expensive and hard to find. That same sort of thing I think needs to happen in other roles on a development team in order for them to stop being that second-class – and also to stop having developers be the ones that have to do all of this work. If you look at it and say, “Well, the test writer or the doc writer is a cheaper person and we’ll just hire a couple of them,” it’s more likely to fall on the developer to do the hard work than to hire the good people and have them do the hard work.

    Shimel: Fair enough. Mitch, what do you think on that?

    Ashley: You know, it’s a really good point, and I think part of what you’re saying, Adam, is it’s a specialty. You think differently to be a fantastic tester, not just testing but the whole test strategy and how to do all the different kinds of testing that’s involved, and then of course how do you automate that and do you do that yourself? Do you work with part of the dev team to do that? Same thing for SRE, right? It takes a different – someone who thinks about it differently. And it’s sort of that cognitive diversity of teams that we value from a diversity standpoint. We value that also because those roles also require specialty skills. You know, someone who’s designing – and, Tracy, you could explain this better than I could, but someone who’s designing a cloud-native architecture and thinking about the microservices and what’s gonna constitute a microservice, how we’re gonna communicate between them and how we’re gonna secure them, that’s a different kind of thinker than how do I break all that stuff. That’s really nice that you did that, but watch how fast I can break that. That’s fun, and that’s where people really enjoy working together. But I think that’s part of where you’re elevating, too, Adam, is you’ve got to value all the skills, and they may be expensive, they may be not quite as much, but they’re needed. They’re part of the process.

    Shimel: Interesting. You know, Justin, we’re talking about testers. We’re talking about SREs. We’re talking about developers. Once again, no one’s talking security. Are we just sentenced to be forever the outsiders here? What’s it gonna take?

    Hutchings: Most of the security people that I talk to take that as a challenge, you know? We obviously want developers to go and embrace security as part of, you know, their everyday job descriptions, but folks in AppSec and especially in the security research community, they’ve always felt like kind of scrappy outsiders that are going to shine a light on things that other people didn’t notice. And so I think even when we have very security-minded, security-motivated engineering teams, security is a discipline that’s got to stand apart, because we want to have that sort of trusted auditor role or that, you know, lookout for – whether it’s bug bounty reports or stack analysis findings that no one looked at. Like, someone’s got to be watching those, ’cause developers, especially in the world of microservices, they might work on a thing, finish it, and then go somewhere else. But the security world changes all the time. If you walk away from that microservice and all of a sudden we learn about a new category of security problems and no one’s watching it, well, that’s a problem now. And so security has a really special role in terms of being the stewards of all the things, even when they’re not directly accountable for the functionality of it. And I think that’s a special thing that we should celebrate.

    Shimel: Okay, we’re special. But you know, as special as we are, yet we’re still seeing security tools for developers, right? That is a bona fide trend in our industry, and at the same time we’re also seeing – when we talk about the load on developers, we’re still seeing an extreme need for more security people, right? We just can’t produce enough qualified security folks, it seems. If that’s the facts, right, there’s no getting around it. What else is there to do but put this load on the developers? How else do we deal with it, automation? I don’t know.

    Hutchings: You’re absolutely right, and I think the key for tool spenders like GitHub is to figure out how to give developers enough information that they can be successful but not overwhelm them, because security tools, you know, there’s a risk of false positives. If you give them too many, they will ignore them. And so, like, as a tool vendor, I have to be extremely careful to make sure that I don’t burn out developers on the things I think are important, ’cause they might not find them as important as I do.

    Kalsey: The other thing those vendors have to do is make less work, eliminate work for the developer, not cause more, not give them more things to pay attention to, more work to do, more administration to do, but look for ways that you can remove that work through the tools.

    Ragan: Yeah, so we have a challenge facing us when it comes to automation right now, and the challenge has to do with these imperative pipelines that we’ve been running for the last ten years. Sometimes you have a Jenkinsfile that is pretty complicated, and we’ve been running them, we copy them, and we use them. It’s imperative.

    The problem with it is because it’s imperative. We are seeing a shift now to moving away from these imperative pipelines to where it’s more declarative and event-driven, which means that it should be easier then to take these older – if you had a purely declarative pipeline based on events, think about how easy it would be to say, “Okay, we’ve decided on this set of security requirements to add to sort of the workflow steps for the testing workflow, for the development workflow, and we’re gonna plug those events in.” The reason why we don’t do that now is because it’s too hard. [Laughter] It’s just hard, because we have to take these old imperative pipelines and try to modernize them. And without having that declarative framework, these kinds of tools, even adding continuous testing, even adding continuous deployments all the way to production, it’s hard and it takes a lot of work, and you have to change the tires as you’re going down the freeway in an imperative model. The faster we can get to an event-driven process in our CD pipeline where we can declare them and we can automatically generate what we need to do in a workflow, the sooner we’ll be alleviating some of the pain that the developers might be seeing, the sooner we can bring in better testing, the sooner we can bring in the DevSecOps conversation, and in our case automated configuration management.

    This has always been a problem for any of the tools in the CD pipeline to start being plugged in, because the imperative pipelines that we are dealing with on a daily basis, nobody wants to touch them. So we’re gonna have to disrupt that first, and when that gets disrupted and people start moving to something more declarative, we are gonna see an increase in adding all of this kind of automation into the CD pipeline.

    Ashley: I’m curious, Tracy. Is it the complexity of the pipelines that – the way they’re defined, is that why people don’t watch to touch them, or –

    Ragan: It’s the number.

    Ashley: The number, okay.

    Ragan: You’ve got – literally I’ve seen people with thousands and thousands of workflows ’cause they’re running one for every single application version. And to look in that and say, “Oh, we’re gonna change all of these,” because it’s not templated so you can’t just change it in one place and it’s just gonna trickle down, because they’re all these very statically scripted processes. And for whatever reason on the distributed side of the house – when I say distributed, I’m talking about everything except the mainframe – we have relied on heavily scripted processes, and we’ve scripted ourselves into a box that we cannot – we’re not Agile. We cannot easily update these pipelines to include security in them.

    We talk about it at the CD Foundation often, trying to elevate security as a first-class citizen in the CD pipeline. But that means that everybody’s got to start updating all those CD pipelines, and they’re not templated. They’re all statically scripted so you have to address one at a time. And as I think Justin might’ve said, you’ve got to plan to pay for that. So we’re in a box, we’re in a corner, and we have to somehow get ourselves out of that corner in order to alleviate these kinds of problems. And being Agile at the CD pipeline level means that we’re gonna have to dump these imperative processes.

    Hutchings: And I think you’re exactly right there, Tracy. One of the challenges we also see with security is this desire to start slow so that you don’t overwhelm people with too much, and if you don’t have a centralized control plane that everyone pulls from, you know, as you start to introduce these security tools, you can’t dial up the difficult level as you go. You have to hit those distributed CI pipelines every single time you want to go and update the difficulty, and that’s not tenable. I mean, you know, there are services out there – I think GitHub with Actions is doing a pretty okay job with allowing some centralized management, but it’s a spot that we all have to invest in because, you know, that control plane for specialists like security to go and help inject things is just not as mature as it needs to be.

    Ragan: And the CD Foundation has started an events working group to start having this discussion. Right now they’re talking about just vocabulary, but I believe that will grow into a bigger project in the future so that we can start thinking about how you can have that event-driven process so that you can dial it as you need to, right, as oppose to having them statically scripted in all of these imperative pipeline processes.

    Shimel: So, guys, we’re running low on time. Just one other topic I wanted to bring up. You know, in looking at this problem, though, I’m reminded of when I read The Goal, right, which is kind of the book upon which Gene Kim based his Phoenix Project on. The Goal is about more manufacturing; The Phoenix Project was IT. But really it talks about bottlenecks, resource constraints. And the story of The Goal – and I forgot if it was the first rule, the second rule, whatever it was – is as soon as you fix one or get rid of one problem, the next problem down the line shows itself that maybe you didn’t see because the problem in front of it was hiding it camouflaging it. In trying to make life easier for our developers or take the strain off of that point, are we really just going through this goal process of discovering the next bottleneck? And maybe that’s what – maybe that’s the secret to life. Life is just about going from one bottleneck to the next, right, and discovering what’s downstream from there. There’s something Zen about that. But is that what we are sentenced to for sure, or is there a way out of that?

    Kalsey: I like to say that when designing large-scale distributed systems you can’t remove your scalability or your failover problems; you just move them to a different part of the stack. And we do that a lot with development teams as well, is we don’t remove the problem; we just move it to a different part of the process and move it around.

    I think one of the ways out of that is one of the tenets of Agile is let the teams make the decisions. Hand them the problem and let them decide how to organize, how to do these things, how to make stuff work. You know, if management is pushing down on development and saying, “You’re now going to be the testers,” of course we’re causing more work and more problems and more things for them, and they’re going to become the bottleneck. But if we let the teams figure out – they’re the ones close to the work, doing the work. Let them make the decisions about how we’re gonna do this and what they need to make it happen.

    Shimel: Fair enough. All right –

    Hutchings: Yeah, I was gonna say I like the term incrementally correct. You know, Alan, your thinking about bottlenecks is absolutely true. I don’t think there’s ever a world where we will get to 100 percent panacea, but we can hope to get a little bit better all the time, and that’s the journey that we’re all on, right?

    Ragan: And failing fast.

    Shimel: _____ continuous improvement, and failing fast – like get to know –

    Ragan: And allow your developers to fail and not – or your testers or your security. It’s okay to fail, because then you learn what you need to do. Failing fast is part of the learning process.

    Shimel: Fantastic. All right, guys, we are out of time. I want to thank all three of you for joining Mitchell and I on this episode of ” DevOps Unbound.” Thanks to Tricentis for sponsoring ” DevOps Unbound,” as always. We will be back in – not next week, the week after with a new, fresh episode, as well as check out – we’ll have a new ” DevOps Unbound Roundtable” open to the public for questions, and you can find out about that at DevOpsUnbound.com or on our Digital Anarchist site or devopsy.kinsta.cloud frankly. Look under – it’ll be under webinars and you’ll find the Roundtable there.

    Until then, though, Tracy Ragan, as always, it’s a pleasure to have you on. You bring such enlightenment to the whole discussion. Thank you.

    Ragan: Thank you, Alan.

    Shimel: Thank you. Justin, again, always nice to have you on one of our panels and discussions here. Many thanks for coming. And, Adam, thank you and good luck in – you know, I know you’re relatively new in your position there at Tricentis but it looks like they made a hell of a hire. Good luck, and come back and visit us again.

    Kalsey: Would love to. Thanks a lot.

    Shimel: All right. Mitch, you want to take us home?

    Ashley: I just wanted to thank our panel as well, and I love the incremental progress idea, and it’s always getting outside perspectives sometimes, too, that’s helpful. So I think we’re here to help each other in this process and not one of us has the answers.

    Shimel: Right on. All right, this Alan Shimel for “DevOps Unbound.” We’ll see you on the next show. Bye-bye, everyone.

    [Outro music playing]

  • EP 10: Observability & Continuous Improvement

    EP 10: Observability & Continuous Improvement

    Observability at enterprise scale brings with it additional application life cycle management requirements. Success requires knowing which changes result in improvements and which don’t produce positive results and how that information must make it back to the DevOps team through feedback loops. In this episode of DevOps Unbound, Alan Shimel and Mitch Ashley talk with Kurt Chase, senior director, global release management at Tricentis, Charity Majors, co-founder at Honeycomb and Ravyn Manuel, senior application manager at the Smithsonian as they discuss observability and continuous improvement. The video is below, followed by a transcript of the conversation.

    Alan Shimel: Hey, everyone. I’m Alan Shimel and welcome to another DevOps Unbound. We have a great panel in store for you today here on DevOps Unbound. Our topic is observability at a broad level. We’re going to jump into some of this. Let me first of all introduce you, though.

    First I want to introduce you, of course, to my cohost of DevOps Unbound. He’s the CEO of Accelerated Strategies Group, CTO here at MediaOps, my friend Mitchell Ashley. Hey, Mitch. Welcome.

    Mitch Ashley: Alan, thanks. Great to be here.

    Shimel: All righty. Let me introduce you to our panel for today. We have a great panel. I was so happy that this came together. First, coming at us from the mountains of Virginia by way of the Bronx, Ravyn Manuel. Ravyn, why don’t you introduce yourself and where you work?

    Ravyn Manuel: Absolutely. My name is Ravyn Manuel and I work for the National Museum of African American History and Culture, which is part of the Smithsonian. I am the Senior Applications Developer and DevOps Engineer. And thanks for not putting me in West Virginia. I appreciate that.

    [Laughter]

    Shimel: Okay. I don’t blame you. Next up we have the one and only Charity Majors, CTO and Co-founder at Honeycomb. Charity, a little bit about yourself, maybe introduce to the audience?

    Charity Majors: I am an ops nerd. I have been on call since I was 17 racking hardware. I no longer rack hardware anymore. Hardware doesn’t exist, as far as I’m concerned. Instead, I’m trying to save the world through better observability.

    Shimel: Excellent. And then, last but not least, we have Kurt Chase of Tricentis, Tricentis Releasing. Kurt, why don’t you introduce yourself?

    Kurt Chase: Hi, everyone. My name is Kurt Chase. I’m currently Head of Global Release Management at Tricentis, based in Northern California. Nice to join you all today.

    Shimel: Nice to have you here, Kurt. All right. So, team, panel, our topic this week is observability. And given that is the topic, I feel compelled to start with Charity because, Charity, in many ways you and the Honeycomb team are responsible for all this buzz around observability. Tell us about it.

    Majors: Yeah, a little bit. When we started the company a little over five years ago it was not a term that was really in use – used in tech. Now – which is not to say that we invented it. Far from it. But it has this long and impressive pedigree in mechanical engineering, specifically control theory. And in control theory observability is the mathematical tool of controllability.

    So, we started building this startup, Honeycomb, and we knew that what we were doing wasn’t monitoring. We knew that we weren’t reactively monitoring. We knew that we were – it was about instrumenting the code, getting at it from the inside. But for the first five, six months we couldn’t figure out what to call it. It was really hard to figure out how to talk about what we were doing. And then it was mid-July, midway through the first year when I remember Googling “What is the definition of observability?” And when I read it it’s all about “Can you understand what’s happening on the inside of the system just by looking at it from the outside with no prior knowledge?”

    And a lightbulb just started going off. It was like “Ding, ding, ding. That’s what we’re trying to build. That’s exactly –” if you translate that into software terms, what it means is can you explain any system state that – any state that your system can get into without shipping new code to handle that state because shipping that code to handle that state implies that you had prior knowledge. So, it’s all about the unknown unknowns instead of the known unknowns. So, yeah, that’s my story.

    Shimel: And you’re sticking with it. So –

    Majors: Yeah. I mean, it really encapsulates a lot of the problems that people are increasingly having, that there’s a lot that precedes from that definition of “unknown unknowns,” like you need to have high cardinality, high dimensionality, blah, blah, blah, all this stuff. But those are the things that speak to the problems of microservices and multiple storage systems, et cetera.

    Shimel: I get it. So, Ravyn, this is your life. How does this observability and what Charity has describe, the fact pattern or the problem pattern that she came to call observability, how does that in your life, day to day of what you’re doing, how does that kind of manifest itself?

    Manuel: Thanks, Charity, for actually providing a definition because I was like “Okay, are we supposed to define our own meaning of observability?” So, you’ve given a baseline. And I like that you said it’s not monitoring because I can actually feel the nuance. There’s a nuance between monitoring and observability. And it’s – what’s really interesting is that that’s a problem that I’m trying to solve today at work because we’ve got – and – because we’ve got the black boxes. So, you’ve got observability but when you have software there’s a lot of black boxes. You’re not supposed to be asking what’s going on inside the code because you’re not supposed to know what’s going on inside the code. But when you get a – you put a signal in – I was in the military, so I did electronic repair – so, you put the signal in and you don’t get the right signal out but you’ve got a black box. How do you know what went wrong there if you can’t actually observe what’s going on inside of there?

    It’s one thing to know the state of the software when you are the developer. So, as a developer, yes, I know. But when it comes to being the product owner or the project manager or a stakeholder and you’re trying to figure out what – “Why is this doing this?” or “This is not what I wanted,” actually is how that would come from that end, is “That’s not what I wanted.” So, how to get the stakeholders to get what they want when you can’t actually tell – I can’t tell what the code from my coworker is doing? So, in a way observability is a little bit – it is abstracted from monitoring because monitoring is telling you what it’s doing but it isn’t telling you the state. And so, it’s a problem that I’m trying to solve actually today.

    Chase: I was going to jump in here and say from my experience although monitoring, logging, reporting, alerting, they’re not observability, I think they are fundamental foundational pieces that you have to have in place. You can start observability without any of them, but I’ve found that the more you can get your monitoring and reporting and even get some alerting going, it allows you to then start observing the system. And for me, I know at Splunk and now here again at Tricentis I’m really trying to connect all the pieces because it’s not just about the applications, but I find that some of the DevOps engineers, they really help with observability, especially the ones that are super inquisitive, and they don’t just – when a result appears or something happens they don’t just take it at face value. They’re inquisitive. They dig in. They try and find the root cause.

    And I think that’s key with observability, is taking all the monitoring, reporting, alerting you have, taking the feedback from your customers, all of that comes together, I think, to really help you start to define those unknown unknowns that Charity brought up. I think it becomes very complicated. And then I think I’d love to talk about how AI and machine learning now can start to learn some of these things, because I think we get really good at repeatable incidences, observing those and then accounting for those in our systems, but it’s the unknown unknowns, how do we deal with those? That’s the real interesting part to me nowadays for sure.

    Majors: It is, I think, the interesting part. And I also think that AI ops is mostly bullshit and it will be for the foreseeable future.

    Chase: For a while. I agree, yeah.

    Majors: But I wanted to circle back to what you said about logging and everything, which is – so, there’s a technical definition for observability which has to do with high cardinality, all this stuff, and then there is just understanding your systems. And I absolutely agree: You need some alerting, you need some monitoring. I think there’s a question is – of – it log files? Is it metrics? That’s kind of irrelevant for just data. What’s important is can you understand what’s happening in your system when you need to understand it?

    And I do think it’s important to sort of differentiate the technical definition of observability from just the tendency that we have to, say, observing things because there’s a very rich and mature and well-established set of best practices for monitoring, which are in many cases completely mirror opposite from the best practices for observability.

    For example, with monitoring it’s like for years we’ve been saying, “You should not have to stare at graphs all day. The system should inform you when you need to – when there’s something wrong.” Super canonical best practice. With observability it’s exactly the opposite. It’s – we’re saying that most problems that happen are so subtle that you need to be looking for them. You don’t – you can’t page everyone at the threshold – you would drive them nuts if you were like “Oh, every little thing is going wrong. Bing, bing, bing.” You’re just – you would drive people nuts and they would quit. But when you’re an engineer, when you’re working on this endpoint or when you’re trying to solve this problem you should absolutely be looking through, asking questions, iterating on them, and looking for the trails in your observability tool at that very fine grain level.

    Chase: I agree.

    Shimel: So, I hear what all three of you said and it’s funny how everyone brings their own baggage to this issue.

    Majors: Oh, sorry.

    Shimel: No, no, it’s not – don’t be sorry. I love it. Here’s, I think, fundamentally – for those people out here who are watching this whole – I’ve got a lot of people out here who are DevOps people, who are ops folks, SREs, cyber folks, and their heads are spinning because I think there’s a little bit of what Kurt said to them, which is they don’t do – they do a shitty job monitoring, quite frankly. We don’t do a great job of it. People started throwing this AI ops word around, and there are a lot of companies raising a –

    Majors: Yeah, there are.

    Shimel: – crap ton of money around their AI ops stuff. And I never really understood what was real about it and many times it just sounded like another word for monitoring to me. But whatever. There is no AI in it.

    But – and now, look, over the last year, year and a half, two years we’ve seen observability come up here and they don’t get the difference. Ravyn, I think you do because quite frankly your black box analogy with electronic in the military, that is – you’ve got to figure out what the unknowns are from the unknowns. It’s not just getting all these signals that are known and then recognizing patterns and putting some automation behind it. That’s not observability. I’m sorry. Not in my mind, anyway.

    So, I think number one is we need to clearly define it. And Charity, you guys, you are a major kind of evangelist for this: “What is observability versus AI ops versus ALM,” which is before AI ops, and so forth. And there are SREs who are living this and DevOps teams who are living this every single day out here who haven’t got their heads around it. Ravyn, I always look to you as someone who gets it. Where do you fit on the – where do you kind of see it on the – let’s say there’s a scale of ALM, AI ops, blah, blah, blah, observability. What do you think?

    Manuel: I feel like I would be very – most close to observability because, again, all – anything with ops in it, when you start doing DevSecOps and DevOps, all of those ops just become marketing terms after a while. But observability is – because it’s not quite tangible it’s actually more real, because it’s real – because it speaks to exactly what’s coming, what’s going on when you’re trying to get continuous improvement, because you need metrics to show and prove that you’re doing continuous improvement. But how do you get there? What is it – what are the steps to get you there? How are you alerted that you are not improving or that you are going backwards?

    And so, when – I feel for me as far as observability I’m at the cusp, because I didn’t actually know that the word existed until I found out about the talk. I didn’t know that that had been defined. So, it’s really cool to know that I can now call it observability. It’s because it’s that thing that I can’t – there isn’t a tool to actually help me – actually help me know what it is that I’m looking at all the time. Not all the time. There are some tools that help me some of the time but not all the time. And it’s the times that I don’t know that’s when we are stuck, because it could be impacting the way – the system performance or the team’s performance.

    Shimel: Charity, I think you might have a customer there. It sounds like they need a tool.

    Majors: I feel like one of the key differentiators here between observability and AI ops and stuff is what it tries to center. With observability we are not – AI ops are like “Eh, we’ll tell you what to look at. You don’t need to understand your system. We’ll understand your system for you. We’ll tell you what to look at. We’ll tell you what it means. We’ll tell you what’s important.” With observability it’s the opposite. I think that we need to look to solutions that let computers do what computers are good at and let humans do what humans are good at. Computers are good at crunching lots of numbers but they can attach meaning to something. Only human beings can attach meaning to something. If I see a big old spike of red that could be good, that could be bad. You don’t know. There is no meaning until a human has attached them to it.

    And with AI ops, AI ops only really works if the corpus of data that you’re training it on doesn’t change. So, if you’re actually shipping software every day you’re fucking up your corpus. This – it’s kind of incompatible with modern software development. I have many thoughts and feelings on AI ops. God bless them, but mostly I think that what they’re trying to do is take the humans out of the driver’s seat. And I understand why, because the C-level, CTOs, CIOs, whatever – there’s something that kind of blew my mind when I realized it a couple years ago: They trust vendors over their own people. Their employees come and go; vendors are forever. So, whenever a vendor comes along it’s like you give them tens of millions of dollars; your people don’t have to hold all of the wisdom in their heads. You can replace them. They’re fungible. The tool will tell you; the tool will be the source of truth.

    And I just fundamentally reject – I’ve never seen that work well. I think it’s a shitty way to treat your people. And I would prefer to take the –

    Chase: And I would not agree with that statement, quite honestly. I’ve had leads that are –

    [Crosstalk]

    Shimel: All right. “Mr. Vice President, I’m talking.”

    [Laughter]

    Sorry.

    [Crosstalk]

    Majors: – and then using our tools to make them better, to impress them, to give them a better sense of where they sit in time and space in the history and what’s happened before and what they’re – they should be wearing grooves in the system as they wear – as they use it in the [inaudible].

    So, I think that it should – if you’re centering a person it’s observability and if you’re centering the – it’s AI ops. Sorry. Go ahead, Kurt.

    Shimel: It’s okay. Kurt, your turn.

    Chase: No, I was just – in my experience the leads, I’ve had – I’m a senior level director now; it was the same at Splunk – I did not encounter that where my leads trusted vendors more than myself or the people on my team. I was surprised to hear that, quite honestly, Charity. I have not experienced that.

    [Crosstalk]

    Majors: It’s not universal. But it’s – there – it exists quite a lot.

    Chase: Yeah, that’s too bad to hear that. That is seriously wrong and that’s going to go against everything we need to accomplish internally.

    Majors: Yeah.

    Chase: Yeah, if –

    Ashley: Have fun attracting great people with that mental model.

    Chase: Yeah, yeah, yeah. And the other thing – I’d love to hear your opinion on this, Charity – we have very complicated systems we’re running. The source code management, the build systems, the agents. I’ve found that it always is very helpful to distill it down into discrete parts, try not to blow the ocean at once. Let’s start with the source code management system. How are we observing that? What are we doing here? And would you suggest that’s a great way for people to get going? I mean, when you try and look at everything – you have to look at everything for sure, but to get started it seems like find some of the most important pieces. Source code management is a great one. The crown jewels. What’s your suggestion there for getting started and –?

    Majors: Source code management is important but it’s never – it’s almost – it shouldn’t almost ever be in the critical production path. And when people are rolling something out I always advise them to find something that’s – don’t waste your time instrumenting _____ observability, lights, and backwater to the system. Find the thing that you’re trying to understand and fix now. Find the thing that’s broken. Find the thing that’s causing you pain. Because it should be an order of magnitude better at answering your question, observability should, even than monitoring. I don’t think you can look someone in the eye and ask them to switch up what they’re doing and to use something else unless you can tell them it’s going to be an order of magnitude better than what they’ve got now because the costs of transition are so high.

    But with observability you should be able to go from instead of just the aggregate where it’s like “Well, I see a spike but I can’t tell you what it means or how they’re different from –” with observability you should be able to go exactly those rows, in which ways are those events different from all the baseline events, and very quickly go “Oh, I have a much richer view of my system now.” And if – once you’ve got that you should be able to explain way more about what’s going – so, we see this all the time when people are running out – when they’re rolling out Honeycomb. They start rolling – they roll it out to the service and they’re like “Oh, God, there are problems there. Did you know that this is broken? Oh, there –” and we’re like “Yeah, yeah, yeah, but you’re just picking up the rug. It’s been there – it’s been that way for as long as you know.” And they’ll pick up another service and the problems – I’m like “Yeah, but these problems have existed – you just had no idea because we were dealing with [inaudible].”

    So, I feel like the way to pick up momentum, the way to incentivize people to get excited about this is to look for the biggest pain point in your system and –

    Chase: That’s awesome.

    Majors: – then patch that with observability.

    Chase: That’s great advice. I agree.

    Manuel: Charity, a question. Does – can observability actually take in account process? Because you’re talking about if there’s something wrong in the system itself, but sometimes the thing that’s wrong with the system is the process.

    [Crosstalk]

    Majors: Well, everybody is not about process. And you’re totally right. That’s often – that is not something that you should ever ignore. A lot of the biggest problems are process problems. But observability is not the tool for that.

    Shimel: And that’s good to know too because quite frankly – and Mitchell knows this too – we live in a silver bullet world where people think the latest shiny trinket is the cure-all.

    [Crosstalk]

    Majors: – everything, you should –

    [Crosstalk]

    Shimel: No, observability, yeah, it’s not going to cure Covid either.

    Majors: No.

    Shimel: But –

    Chase: And that was the point I was trying to make initially. I think I said it wrong. It’s not that monitoring and reporting, logging aren’t foundational; they’re complementary. You kind of need them all. If you’re running modern stacks – I said that incorrectly at the start – it’s not foundational. There’s – you need them alongside each other.

    Shimel: They’re adjacent. They’re not –

    Chase: Yeah, absolutely. Absolutely.

    Shimel: They’re not – it’s not a pyramid per se.

    Chase: Right. Exactly.

    Shimel: I think it’s part of your stack horizontally.

    Chase: Yes. Yes. And I’ve found –

    Shimel: Can I – we haven’t’ – go ahead, Kurt, I’m sorry.

    Chase: I was going to say I’ve found with especially new individuals and new people to the DevOps team and the DevOps world, getting them involved in the monitoring and saying, “Hey, this is how we start monitoring,” that’s a great place to start. It’s almost entry level for observability, if you – I’d love your opinion on that, Charity, too.

    Majors: Well, I really think that everyone who writes and ships software should be on call for their code, no matter how –

    [Laughter]

    Chase: Yeah, me too.

    [Crosstalk]

    Majors: Software ownership. And so, yes, that’s very empowering, I think, to show them how to find the trail, the alert that’s paging them, trace it all the way to the system and fix it. That’s something that as engineers, we feed on that. That’s exciting to get to know how to run your ship better. Yes, absolutely.

    Shimel: Well, but – so, you know what? Mitchell and I started a company – or, were two cofounders of a company called StillSecure 20 years ago. And that was one of the things. Mitchell ran the engineering team and that was one of the things he instituted, I remember, was that every developer had to take a turn on the help support desk, level one, answer the phone. “Hello, Mr. Customer.”

    Majors: It builds empathy.

    Shimel: And try to explain it because they had to answer the alert. And even when they weren’t on that level one our escalation procedure was if it went to level two or three it was the developer who did the level two and three support.

    Majors: I will say that, yes, and I do think that every engineer should be on call for their work, but you have to couple that with it’s management’s job to make sure that that doesn’t suck, that it isn’t _____ for them, but it doesn’t just kill you with [inaudible]. It is management’s absolute fucking responsibility to make sure that they’re given the time to – away from project work to fix these problems so that they don’t recur, so that they get enough sleep. I think it’s reasonable to ask any engineer to be woken up two or three times a year for their code. That’s it. Because more than that, you’re burning people out hardcore.

    Manuel: Been there, done that.

    Shimel: You know, Charity, Ravyn –

    [Crosstalk]

    M : I have a question. I have a question I’d love to ask all of you. I’m thinking about observability has been elevated because of, in part, the world that we’re living in. Software architecture is changing. We’re dealing with microservices, all these much smaller things that are interconnected to make software. And at the same time as we’re changing the pace at which we release software, not only is it unknown unknowns, it’s like a river – Riven –

    Shimel: Ravyn.

    Ashley: – we’re in the river of the changing software. So, you’re trying to understand all of these things at the same time. It seems like it’s the right time for observability to be the thing to be working on because ops has to be elevated to the same level of the same kind of architecture and processes that we’re using across the – in the life cycle of software. Do you agree with that or not? It seems to me we’re in the right place, right time.

    Majors: Absolutely. I mean, I feel like the first wave of DevOps transformation was all about “Ops people, learn to write code.” And we’re all like “Eh, okay.” But I feel like the pendulum has swung. I think now it’s about “Okay, software engineers, your turn.”

    Ashley: You’ve got to do ops.

    Majors: I have to learn to write operable services and to learn to maintain them and get called for them and – because what microservices has done, all of that complexity and logic has to be bundled up in the app. The app.

    Manuel: Exactly.

    Majors: And now it’s like we’ve been thrown to the four directions of the map. And what that means is that so much of understanding and operating your application has been pushed into the realm of operations and systems. It used to be that if all else failed you could attach a debugger to your app and just step through, see what was happening. Well, you can’t do that anymore now because the process died and jumped to another service, and another service. And part – the way that we instrument for observability is all about packing up the context of the application and shipping it along with it from hot to hot, one event per request per service, so that you can slice and dice and reason about your systems in a way that you used to be able to.

    Ashley: Doing that really changes the design. I’m thinking about Alan’s story of what I did back at StillSecure. What prompted that was when a customer called in and said, “I’m sitting in – we’re using your project and this dialogue box popped up and it says ‘An unknown error occurred’ and that’s all it says. What do I do?” Well, nobody knows what to do with that. So, we all just said, “Look, everybody does support in that case. Everybody does ops.” And that changed: “Okay, we have to figure this out.” And suddenly that was the problem of “How do we make this easier to support and easier to resolve issues with?” So, it does affect behavior and design or product.

    Majors: Yeah, absolutely.

    Manuel: I think microservices is – will actually do good for observability because if you do microservices correctly then each service is atomic. It does one thing and one thing only. It does that thing good. So, if the unknown is not taken out of it because you know exactly what this thing is supposed to do –

    [Crosstalk]

    Majors: Oh, no, honey, the unknown is never taken out of it. The unknown is never –

    [Crosstalk]

    Manuel: In my ideal world it is.

    [Laughter]

    There are no more unknowns –

    Shimel: In Ravyn’s world, yeah.

    Manuel: – in Ravyn’s world. Exactly.

    Shimel: Yeah. But I’m going to tell you something. The flipside to this, though, too with microservices, and I think we’re starting to see this now, is can you have too many microservices running? Does it – is the complexity load in there such that observability almost becomes meaningless or impossible?

    [Crosstalk]

    Majors: I don’t know that complexity can every really be created – no, it typically is not meaningless. It’s your only hope to understand this shit if that’s what you’ve done to yourself. But complexity can only be moved around. It’s just a question of tradeoffs, like which set of tradeoffs – some folks have gone whole hog on microservices and then they’ve found the edges to those design _____. But –

    [Crosstalk]

    Chase: What I find – I was going to say what I find challenging is both at Splunk – Autodesk was interesting. So, to your point, Alan, we used to make engineers buy bagels. You break things; you have to buy bagels. And so, we had a lot of bagels brought in. But both at Splunk and here at Tricentis we have a world where we’re supporting large enterprise applications and delivery of enterprise apps. We’re also – obviously all the microservices – and trying to apply these techniques across the board is very interesting, very challenging.

    [Crosstalk]

    Majors: Oh, yeah. There’s no one-size-fits-all.

    Chase: There’s not. There’s not. And almost to the point you made, Ravyn, observability almost has to be customized for what you’re observing. It’s – I haven’t had a chance to run Honeycomb yet, but for me my experience has been there’s always those little idiosyncrasies about how we run our ops, how we –

    [Crosstalk]

    Majors: There’s no such thing as a perfect _____. No one else can do it for you. It can be – it can get you started. It can give you a boost. But at the end of the day somebody’s got to fucking understand your software and roll that into your instrumentation. Nobody else can do that for you, let alone _____.

    Chase: And that’s where with AI ops, I won’t say it’s complete shit. I think there is some value there. Some of it is just about automating common occurrences. And maybe that’s not valuable but –

    [Crosstalk]

    Majors: – it’s an AI but they’re just using that to make – to raise lots of _____.

    Chase: Oh, sure. Okay. Yeah.

    Manuel: Didn’t work.

    Majors: Like, “Oh, I have an AI too.”

    Shimel: No, but we – and you’re right, AI is a money term. But ML ops is something that’s caught on a bit, more than, I think, than AI ops. And I think that’s really at the heart of it, which was to recognize repeatable patterns or recognize patterns that we can respond to.

    [Crosstalk]

    Majors: Although, I would still challenge – I think in far too many cases people are reaching for the complicated solution instead of fixing it at the start. They’re like “Ooh, I’ve got 50 bazillion e-mails so I – and all of that disk space so I need AI to solve it” instead of turning off the fucking e-mails and setting up a different kind of alert or some automatic _____. Just – is this really a problem we need to solve? Or could we solve it better by just not having it?

    Shimel: There is that.

    Majors: Sorry. That’s my last bitch.

    Shimel: Do we need to solve every – and I think Ravyn – or, not Ravyn – Charity, you were getting at it before. Do we need to solve every problem?

    Majors: Is it the most important problem? Is this going to be the biggest bang for our buck?

    Shimel: Yep. I mean, we used to have a –

    [Crosstalk]

    Majors: – or the _____. Like, senior engineers write software but very senior engineers don’t need software.

    Shimel: Yeah, no, I mean, look, when Mitchell and I were doing the security company we had a product, “Vulnerability Assessment of Management.” VAMP. Internally we called it the Bad News Generator because that’s what it was.

    [Laughter]

    It was the Bad News Generator. And the problem was we would go to an organization like Ravyn’s and it would pop up a few thousand vulnerabilities, and the security or the ops people would be like “What am I going to do?” And “Don’t worry about 95 percent of them. Let’s just worry about the top five percent.” And it was like – it was employment insurance, was what it was, because there would always be more vulnerabilities for us to find next year.

    But that being said, it really was the case where you’re not going to fix everything. We don’t have the time to fix everything even if we wanted to.

    [Crosstalk]

    Majors: And it’s not really doing a great job of giving you differentiation, letting you know what’s really important and what’s just noise. So much of these tools, they just give you so much noise and it’s almost worse than nothing at all.

    Shimel: Well, that’s why with the Bad News Generator people used to – so, Mitchell got the lucky part of designing it. I had to go sell it. That was much harder.

    Ashley: I remember the –

    Shimel: Much harder.

    Ashley: – guy from the federal government called and said, “This thing is spamming everybody in the Defense Department.”

    Shimel: Yes, “We have all these vulnerabilities.”

    Ashley: “How do I turn it off?”

    Shimel: Because we had this automated workflow before we had terms like AI and ML. But it is hard.

    Hey, guys, we’re coming down the home stretch here. We probably only have five minutes or so left. I wanted to – let’s look forward now. I’m big into looking forward these days. I’m hoping we’re going to do conferences in person again; we’re going to – I don’t know if we’ll go back to our offices but…

    What’s next for observability? How does this continue to evolve?

    Majors: What’s next is I think really wrapping traces in as a first, best tool so that – right now too many people are like “I have one tool for metric, one tool for logs, one tool for servability, another tool for –” they’re spending just ____ data again, every time. And it’s worse than that because you can’t actually seamlessly break down a chain of events, so you’re just copy/pasting this idea into that tool or hoping despite – because it seems to line up timewise, it’s actually bees in the logs – you should be paying to store this data once and you should be able to flip back and forth between loads. Are you slicing and dicing? Are you doing aggregations at read time? Are you zooming in? Are you zooming out? Or are you slipping back so you can view it as a logger file by time?

    I think that observability tools like us and Lightstep – which are the only two observability tools out there by my technical definition – although, I will say I do think that this might be the year that that begins to change. I know that so many of the big players have been working as fast as they can for years on the back end. They’re trying to catch up to where we sit technically faster than we can get catch up to where they sit in terms of the business. So…

    Chase: And I –

    [Crosstalk]

    Manuel: I like that you said that. Sorry, Kurt. That –

    Chase: No, no, go ahead, Ravyn.

    Manuel: – Charity – I just wanted to say to Charity –

    Chase: No, no, Ravyn, go ahead.

    Manuel: – about tracing, because that’s actually the solution that I am actually looking for, that I’m looking for –

    [Crosstalk]

    Majors: It’s got a lot of rough edges.

    Manuel: – for organizations. Yes, to be able to follow –

    [Crosstalk]

    Majors: But there are lots of problems we can’t solve any other way.

    Manuel: Exactly. So, I feel good that I’m doing it inherently, like I know what I’m supposed to be doing.

    [Crosstalk]

    Majors: You’re on the right path.

    Manuel: I think I’ve actually found a way to do that. But yeah, tracing I also think is the way to go. That is the only way you’re going to be able to know, because it’s taking you from point A to point B to point C to point D and you’ll be able to see that all. And there will be no unknowns. [Laughs]

    Majors: Oh, honey. You keep saying that.

    [Crosstalk]

    Manuel: It’s my dream. That’s – let me live my little dream.

    [Laughter]

    Shimel: Kurt, what do you got?

    Chase: Yeah, well, where mind – excuse me – where my mind goes to in the future is what are we doing in the education system to really disseminate this information, how monitoring software is developed, how we monitor it. And then also “observability” is such a loaded term because I know at Splunk they would consider observability something much different, for running a SOC and things like that.

    [Crosstalk]

    Majors: Oh, no.

    Chase: So, I think it – I mean, at its core observability is what it is. But how it’s implemented for different disciplines and how they use it, I think companies would definitely take exceptions with some of the things we’ve said here –

    Majors: For sure.

    Chase: – and what observability means to them. And I would just say keep that in mind, that it is a huge field and I think we’re going to see further improvements. I love the tracing. And being able to have that in your tool set would be fantastic.

    Shimel: Charity, final thoughts before we wrap?

    Majors: Oh, I am just enjoying the fact that some people are so interested in this that they’ll show up and argue about it all the time. So…

    [Laughter]

    Shimel: It’s all good. Hey, you know what? It’s a living. Mitchell, as usual, I’m going to give you the last word.

    Ashley: Well, I’ve learned two things today. Don’t call my tool an observability tool or an AI tool unless it really meets the definition, or I’m going to get crucified.

    [Laughter]

    No. No, what – I mean, I love this conversation. I learned a ton. I always do when we have these – what’s so cool to me is that we’re talking about operations and we’re talking about this part of our world and we’re not talking about better ticketing systems. We’re talking about really meaty, interesting things that help us do our jobs better, do a better job for the company, for the customer. That’s exciting to me. It’s just really cool. I enjoy it very much.

    Shimel: Join us for our next show where we’ll be talking about better ticketing systems.

    [Laughter]

    No.

    Chase: And what argument did I miss? I was –

    [Crosstalk]

    Shimel: No, no, no, no. It’s all good. You know what? I enjoy having really bright, smart people who are willing to express their opinions. And when I knew we had this panel, it was the lineup, I knew there was going to be no shortage of opinions, nor any backing down. So –

    Ashley: We’re going to call the next one “The observability mix-up.”

    Shimel: Right.

    Majors: We’re going to have to call it “Observability AI.”

    Chase: I still want to see that sticker –

     Shimel: “AI Observability.” All right. Hey –

    Chase: We need to see the sticker Charity was holding up. We need to see that.

    Majors: Oh.

    Shimel: Oh, we never got to that. Yes.

    Chase: We have to see that.

    Majors: I’ve got a few of those. I’ve got “Release := deploy.”

    Shimel: You’ve got a lot of them here.

    Majors: I’ve got “Ship dangerously.”

    Chase: Yeah, I love that one.

    Majors: “Deploy on Fridays.”

    Shimel: You know what? You used to be able to get these things on conferences. Now we’re reduced to showing them on Zoom.

    Majors: Yeah, you have to.

    Chase: Yeah. Exactly.

    [Crosstalk]

    Majors: “Perhaps this is a good day to deploy.”

    Chase: Maybe.

    Shimel: Okay, yeah. Perhaps.

    Chase: It’s Friday. It’s not a good day.

    Manuel: No, Friday is not a good day.

    Chase: That’s the one, right there.

    Shimel: And there it is: “I deploy from Cron.”

    Ashley: That’s the one to end on right there.

    Shimel: That’s is. We’re going to wrap it. Hey, you’ve watched devopsy.kinsta.cloud. It’s sponsored by Tricentis. Many thanks to them for sponsoring. Just wanted to quickly mention Kurt is from Tricentis. Charity is from Honeycomb, and it’s Honeycomb.io. Go check that out.

    Majors: We have a very generous ____ here.

    Shimel: A very free _____. Ravyn, you can start playing with it now and see if it’s something that gives you tracing and so forth. Mitchell, thanks for joining us.

    Ashley: You bet.

    Shimel: We are back – actually, we are back with a roundtable next, which will be open to the public. Looking forward to having you on for that. But until then, this is Alan Shimel for DevOps Unbound. Have a great day, everyone. We’ll see you soon.

    [End of Audio]

  • EP 9: The Road to GitOps

    EP 9: The Road to GitOps

    GitOps takes DevOps best practices for development and applies them to infrastructure automation. In short, GitOps delivers a hermetic, immutable deployment. So, is GitOps replacing DevOps?

    Managing infrastructure as code through GitOps can be a game changer for organizations. But, when is a GitOps approach best used or not a fit? In this DevOps Unbound episode, I’m joined by Tracy Ragan of DeployHub, Parag Doshi of Tricentis, Brendan O’Leary of GitLab and Mitch Ashley of Accelerated Strategies Group to discuss these questions, the impact of GitOps on the CI/CD market and where the future of GitOps is heading in 2021.

    The video is immediately below, followed by the transcript of the conversation. Enjoy!

    Transcript

    Alan Shimel: Hello, everyone. This is Alan Shimel, CEO at MediaOps. And you’re watching another episode of DevOps Unbound. Let me introduce you to our panel for this week’s episode, and we’ll jump right into our subject matter. First of all, we have the newcomer to DevOps Unbound, but he’s not a newcomer to our audience, my good friend Brendan O’Leary, senior DevOps evangelist at GitLab, a governing board member for CNCF. Hey, Brendan. Welcome.

    Brendan O’Leary: Alan, nice to see you, as always, and happy to be here.

    Shimel: Thank you for being here, Brendan. Next up we have our good friend and a semi regular here on many of our video segments at MediaOps, Tracy Ragan. Tracy is CEO of DeployHub, as well as the community-elected board member of the CD Foundation. Hey, Tracy. Welcome.

    Tracy Ragan: Thank you. Thank you so much, Alan, for having me here today. I always love doing these.

    Shimel: Absolutely. We love having you. Our third panel member today comes to us from Tricentis, who’s also the sponsor for DevOps Unbound, and it’s Dr. Parag Doshi. Parag runs engineering, VP engineering at Tricentis. Parag, welcome.

    Parag Doshi: Hello, Alan, everyone. Nice to be here. Thanks for having me.

    Shimel: Thank you. Thanks for being on. And then last but not least, my cohost for DevOps Unbound, Mitch Ashley. Mitchell is the CEO/founder of Accelerated Strategies Group as well as CTO at MediaOps. Hey, Mitchell, thanks for coming on today.

    Mitch Ashley: Absolutely, Alan. And thank you for all of our panelists for joining us. You are all fantastic. We enjoy having you.

    Shimel: You know, just before we jump into it, the continuing evolution of COVID times, we’ve done so much with our backgrounds, [Laughter] on our videos, right? Looking here at Tracy’s snazzy DeployHub background and Mitchell’s background and Parag’s – and Brendan’s old-school, man. Brendan’s giving us – if I’m not mistaken, he used to be down in the basement and now he moved up. I think he displaced one of the kids or something.

    O’Leary: Yeah, I moved upstairs.

    Shimel: Yeah, yeah. And that’s a real background, so good for Brendan.

    Ashley: And he’s got an MV7 microphone there. Nice job there, Brendan, on the mic.

    O’Leary: Oh, thanks. Yeah.

    Shimel: Yeah.

    O’Leary: All, you know, post COVID things to make it work, Alan. I wanted to have the background, the real background to make it work. But that was also a COVID change.

    Shimel: It’s authentic. Yeah. [Laughter] Crazy stuff. Anyway, guys, today’s show is around one of the hottest topics in DevOps – GitOps. Right? And I’ve actually heard from people, you know, that GitOps is the new DevOps or GitOps is somehow replacing DevOps, and I think DevOps has outgrown the – it’s going to be replaced by something.

    It’s transcended to a different level of existence, if you will. But certainly GitOps is on a lot of people’s lips. It’s not only on their lips, it’s in their development plans and how they are delivering software to the cloud, to cloud native, and all over. But is the right move for every situation? Is it a panacea?

    When is GitOps a good thing to use? When is it maybe not a good thing to use? Right? How much does it change sort of the classic CI/CD pipeline that we’ve started to finally wrap our heads around in DevOps? Stuff like that. So I am going to – Brendan, of course, GitOps, GitLab, they both have Git in it.

    So we’re going to make you – I’d like you to start off. Let’s start with some definitions. What’s GitOps mean to you?

    O’Leary: That’s a great question, and I think one that’s still probably [Laughter] unsettled, right? Much like defining DevOps can sometimes be seen as unsettled. GitOps came out of the cloud native community, and so a lot of folks maybe restrict the concepts of GitOps to say it only exists in a Kubernetes world. Because that’s kind of where this approach came from. But we’ve seen folks employ GitOps principles to all kinds of different infrastructure, automation, from old-school VMs to containers to Kubernetes clusters as well.

    So when I think of GitOps, I think it kind of requires three things. One, infrastructure as code. Right? You said that in the beginning. That’s kind of like table stakes to getting in. It’s something we’ve been working on for a long time. But really defining as code in Git – the Git part of GitOps – what our infrastructure’s going to look like, and then keeping that configuration stored in that code.

    And maybe the desired state is stored as code or not, but at least the way we get to that desired state is. Second, I think it’s merge request. So we call it merge request. You’ll hear other folks call them pull requests. But the concept of using the point where someone is proposing a change as the central place where teams collaborate on.

    Is this the change we want to do? Is this going to help solve the problem we’re trying to solve for? Right? Bringing that concept to the world of infrastructure is hugely beneficial, because it’s how our developers have already been working for years and years. And making that merge request, kind of that central source of truth for approvals and security checks and all those other things is really critical.

    And then last, I think it’s – the third thing is CI/CD, right? Of course. So the idea of GitOps is automating that infrastructure, update with a very simple Git workflow. And so you really do have to have embraced and adopted continuous integration and continuous delivery really in order for the whole package of GitOps to make sense for you.

    Shimel: Pretty darn good. Comments, add-ons, thoughts? Parag, Tracy?

    Ragan: I would only add one thing here. If you say what is GitOps, I like to shorten it down. I think what Brendan just defined is all accurate, but it’s operations by pull request. The goal of GitOps, what GitOps delivers is a hermetic, airtight, immutable deployment. And that is in essence what we’re trying to accomplish by using Git as the place where we declare and define what we’re going to push out to or have pulled out to the cluster.

    So it’s the concept of a hermetic deployment, something airtight that no human touched. Don’t you dare touch that and then deploy it out, because of we don’t know what you did. [Laughter] So the whole idea is to create a hermetic process.

    Shimel: I love that. That was concise and right on.

    Doshi: I have a similar viewpoint. I think of GitOps as a combination of infrastructure as code plus event-driven architecture. Right? And in this case we’re talking about merge requests or pull requests or whatever terminology you want to use, depending on the flavor of Git you love. But the way I think of this as a former physicist is entropy is there. It’s too hard to keep track of everything. Humans can’t remember everything.

    We need to be able to describe, as application developers have been doing for the past couple decades, in code the versions of things, the documentation associated with everything. And then the automation that we’ve had in CI/CD, which people think of, oh okay, that’s developers pushing their code out, well there’s no reason why we have to stop at application level. It needs to be the whole thing, because application and infrastructure must stay in sync at all times. So by putting a description of both the application, the infrastructure, and within the surrounding environment, all three of those into Git, you’re bringing the best practices of AppDev into the whole world together so they’re all synchronized.

    Ashley: Yeah. I like that description too, Parag, because in a way that’s breaking down silos that we still have around the code build and deployment process. And it’s almost like if you think back when we started using code repositories and, okay, everybody put their source code in one place, okay, let’s expand that to artifacts and other things. Well, now we’re doing the same thing of let’s abstract at one more level and make the whole thing as cradle to grave, if you will, for getting code out into product. Whether it’s any part of that stack, it’s a GitOps process.

    So to your point, Tracy, about it’s an immutable object, it’s something that we know from beginning to end, it’s all been in one environment and we happen to have manual processes that have just been automated that potentially are weak or could be broken.

    Doshi: I’ll add one more comment on top of Branden’s about – I think it was around – it came out of cloud native computing foundation, but really the way I look at containers is it doesn’t matter that’s a container or VM. We’ve just moved a control plane up to a higher level, but the same principle’s apply. So there’s no reason why you cannot use these same principles in a container type of environment or a non-container environment. The only difference I would say with containers is we can be very surgical, fine grain, down to each individual pot. So there’s a little advantage with cloud native architectures to be very fine grained.

    O’Leary: Yeah, I agree. And I think that’s important for folks to separate the concept of GitOps, the principles that we’ve all talked about. And I agree with the other panelists and how they’ve talked about it. But separate those principles from the technology, right? Because it’s not always true that Kubernetes is going to be the right technology for you to deploy every workload you have in, but still this concept of GitOps.

    And I really liked Tracy’s sealed container – well, overloading the word container there. [Laughter] But that sealed deployment that doesn’t have a lot of human – or doesn’t have any human interaction. That is what gets us to what Mitch was talking about, which is we want to take this isolated, people working in isolation, the kind of cave-like nature that operations typically used to have where you had to have this specialized knowledge that one person knew. Oh, wait. How do we deploy that service?

    Oh, we’ve got to call up Alan. He’s the one that knows how to do that. [Laughter] Right? You want to get rid of that and make it all, what Tracy said, which is like a hermetically-sealed deployment that we know we can reproduce every time.

    Ragan: Yeah. So GitOps was a brilliant way to leverage existing tools and habits to create Chef and Puppet. That is basically what was done. I mean, it has a Puppet kind of master architecture. You have a GitOps operator that’s running on your cluster. It does a pull based on what’s in Git. It very much took the basic concept of Chef and Puppet and leveraged existing tools that people already had, some open source, GitOps operators out there, and they were off and running. And that is the brilliance and beauty of GitOps. I mean, I have a lot of issues with GitOps, and I’m sure we’ll share them, but its brilliance is in that simplicity.

    Shimel: The irony though, Tracy, is that many people will tell you that Kubernetes killed Chef and Puppet, right? And we’ve seen Chef get sold maybe for less than money raises in valuation previously.

    Ragan: No, I’m just talking about the basic concepts.

    Shimel: No, no, I get it. But if we look at the concepts behind what Chef and Puppet did, which was automate that deployment, deployment automation like that, and then with Kubernetes it sort of negated the need for that, but yet we kind of snuck that in the back door. Except we put it in Git to use in Kubernetes. So the irony of that is pretty profound, right?

    Ragan: Well, it’s all about the container.

    Ashley: Right, right.

    Shimel: Yeah. You’re right. Maybe it’s because Chef and Puppet – [Crosstalk]

    Ragan: The containers simplified, yes.

    Shimel: – didn’t figure out how to work in the container. Look, for that matter Jenkins too. Right? We went to Jenkins X because of all of that and everything else.

    Ashley: That’s a really great example, yeah.

    Shimel: But what I’m reminded is of the old Who song, right? “Meet the new boss, same as the old boss.”

    Ragan: Exactly.

    Shimel: And you still have that old boss. With that being said, here’s another thing, and Parag, I’m going to ask you to kick off as I take us a direction here, and that is GitOps, yes, it’s for deployment. What about testing? I said this is all about testing. We’re doing our testing in Git. Is that the – that stops, right? Is that better? Worse? Is that the way it should be, always, sometimes, never?

    Doshi: So I don’t know if I’d call it testing in Git, but I would say now Git becomes a source of truth. So I think what Tracy said is right, that it’s just that same sort of automation of infrastructure but now moved into making Git the centerpiece of where you define this. So the Git part is unchanged, but the testing is now event driven. Right? So because you’ve merged in code, you’ve committed code or gone to do a pull request, that can trigger testing.

    And we call this continuous testing. And I think the evolution of this can even go as far as our test definitions themselves should also be put into Git. That’s the next evolution that we’ll have. I don’t believe it’s really commonplace just yet, but when that happens then, we are trying to describe as much as possible into Git as a repository and use the principles of version control added with the event-driven concepts.

    So when a developer does X or when an operator is in environment Y and something needs to change, that whole Git workflow can invite continuous testing to say do I allow that to merge back in? If you want to have an approval, you could do those kinds of things. So to me, incorporating continuous testing, and the day that we put test definitions into Git as well, we’ve gone quite a bit further of completing this vision and really making DevOps real. Right? Because DevOps isn’t just releasing really fast, deploying really fast. It’s deploying fast with confidence and ease. That’s what we need.

    Shimel: Thoughts on that, panel?

    Ashley: It sure seems like a natural evolution to include the test environment. And as you say, Parag, it’s probably not commonplace yet today. A question for you about that; do you think that there’s incentive with the folks that are taking care of the testing, whether they be the QA team or developers writing tests, things like that? Do you think they have the right incentives to move it into Git or will it be something else that causes it to happen?

    Doshi: I think as long as people have the incentive of delivering value as quickly as possible with the best meantime to recover, the lowest defect leakage rate, as long as we do break down those silos, as you said. If the testing team is, okay, well, I don’t understand what the developers do, just throw it over the wall and then I do my test, that’s not going to work. This is talking about dev testers, the full stack developers. And as long as everybody’s motivation is right, that we’re trying to deliver value faster and faster, that we will not have confidence – that a VP will not say let my applications go out – you know, they’re only going to look at portfolios of apps and say what amount of testing has been done? What amount of security checks have been done?

    That’s another thing. The environment. Okay? That’s the biggest entropy of all. We have the least control over the environment. The same code, the same infrastructure in different environments behaves differently. Until we get that environment description also into Git, coupled with the testing model themselves that says here’s how we test it in that environment or that application or this infrastructure pattern, then DevOps becomes real. Until then, this is all talk.

    O’Leary: Yeah, I agree. I think it’s critical, and it’s something that GitOps, again, this concept of GitOps, I think is exciting to a lot of people that have been trying to make DevOps real for so long, because it enables that in a way. Right? We see kind of the light at the end of the tunnel, I would say. And if that is all brought into Git and all made into something that can deploy independent of any human interaction, well now you have the ability to do continuous testing. You have the ability to stand up an identical environment, the golden goose or [Laughter] golden egg of a, hey, we want an environment that’s exactly like production to really test it and really hit with security tests and know that when we do deploy to production we’re going to have that confidence.

    So if you’re able to continue to iterate on the environment, the infrastructure, just like you’re iterating on the code, it enables you to then say, okay, now we can not only have the code to review and maybe some static code analysis that happens and some testing that happens, and then maybe some human testing that happens, now we’ve also got an entire environment spun up automatically that mirrors production, where we can have a high level of confidence that it’s going to work when it really ships.

    Shimel: So guys, you’re telling me DevOps hasn’t been real quite yet. I feel like I’m living in the Matrix, kind of living in a simulation. Tracy, I sense you’re Agent Smith here, though. You have a different view. Maybe GitOps isn’t the panacea it is or it’s been projected here. What’s your view?

    Ragan: So no hate mail, okay? No hate mail. [Laughter]

    Because I know there’s a lot of enthusiasts out there, and rightfully so. But let me just level set the way I see where we’re headed and where GitOps can’t take us. GitOps is imperative. It’s scripted. And it works really well – so think about how most people use GitOps.

    You have a code repository that you keep all your source code in. You make a change to your source code. You check that in just the same as you always did. You also have an environment repository, and what lives in your environment repository is your Kubernetes deployment YAML file. And that is where you define all of the stuff that we’ve been talking about and that’s what the GitOps operator looks at and pulls across.

    Now if you’re in a Kubernetes environment and you have containerized your application – this works great, it really does – and you don’t have a whole lot of environments – you have three environments dev, test, and prod – because remember, in a Kubernetes YAML file there’s a couple of things that are important to the GitOps operator. One is the tag of the container. So once you register your container image you get a SHA, and that makes it a unique identifier. And you have to update your YAML script with that SHA.

    Now dev, test and prod may have different values, configuration values. So you have to branch it. So you branch dev, test, and prod. So now you have three versions of that YAML file to manage your container deployment. And that’s pretty doable for most organizations today, but it is still imperative. Everything’s being defined by the script for each of those environments.

    Now let’s go and expand it and scale it. Let’s scale it to a microservice environment. Every microservice has its own YAML file because it should be independently deployed. And they should be shared, because that’s the beauty of a service-oriented architecture. They should be shared across teams. So what you do is as an application team, you’re going to make your coding changes in your coding repository and then you’re going to have different YAML files for the different services.

    Now let’s say you’re a store. I use the candy store and hipster store and the clothing store. They all use the card service. Well, they’re all going to put their card service YAML file into their environment repository, and that’s going to get deployed to their own clusters and name spaces. So you have a scaling issue, and it’s because of the imperative nature of GitOps.

    We are starting to move and have more conversations about declarative and events and catalogs, where this stuff is going to be stored and generated at runtime. So for example, instead of having all of these scripts, you’re going to have central places to go to say what’s the key value pair for this environment? I’m going to pull this registry information that has the SHA, I’m going to go get my key value pairs, and that way you don’t have to have so many scripts and you’re not managing – it’s onerous.

    It really can become onerous. We have customers who have 200 microservice and 20 clusters. That’s a lot of scripts. And if you’re an SRE and you want to update your microservice and you want to provide it to everybody, you’re going to have to figure out every single application environment repository that has it in there for every single environment and make those corrections. So it doesn’t scale as well as it should. Now I know that their CNCF has a group, a working group, around GitOps, and they’re starting to think about GitOps version two, and they’re going to have to address these kinds of core problems around an imperative process.

    Shimel: Love it. Brendan?

    O’Leary: Yeah. I mean, I like that concept and I think you’re right, Tracy, that the ability to manage the scale is definitely something you have to be prepared for if you’re thinking about GitOps, because if you just take it at its face value you end up with all those scripts and it could make the problems you have worse rather than fixing some of the problems you hope it would come into and solve. And so I think in a cloud native environment, again, it maybe pairs a little bit more simply, but I think that’s why again it’s great to think about the concept of focusing on that developer-centric approach and the experience that they’re going to have when it comes to shipping something out, to your point of if I want to ship an update to my microservice that impacts everyone, I don’t want to have to go through 78 repositories and update that everywhere.

    And so having GitOps do the infrastructure management in the same version control system as application development is great, but you also have to have a plan in place for how does that scale to the scale that you’re really going to build to? If that the scale of developers, if that’s the scale of services, if that’s the scale of environments. And so I think it’s important to have tooling and an approach in place that accounts for that as well.

    Shimel: Parag, you were going to say something I think before we –

    Doshi: Yeah. Sure. So I love what Tracy described there, and getting into the specifics of the proliferation of YAML files, and especially as we break down microservices. So this is the whole concern with microservices. What you took as monolith and you described as one big black box, now you’ve broken it down. And so now we have the proliferation of all these things. Right?

    So I like things like Helm to help to reduce that and parameterize all these things. But fundamentally with GitOps, the concepts are there. Like I said, infrastructure as code with an event-driven type of approach version control. What I like about CNCF and containerization is the purpose of containers inherently – and Branden can keep me honest on this – is really to make the environment completely separated from your solution, your application, your infrastructure. Right? So today’s industry, the best approach we have is containers or serverless, which is also part of CNCF, so that we have things like Docker files and YAMLs that allow us to reduce the entropy of the environment as we can as much as possible and describe them declaratively in things like GAML files.

    And I do agree with Tracy 100%, that now it becomes, okay, well now I’ve got all these different configs, pulled that out of my code. Even with service mesh technology and CNCF we’re pulling out things like security and rate limiters between every single microservice. All that’s taken out of the logic, the business logic, on everybody doing security different ways. Now it becomes a configuration issue. How do I – if I want to change a configuration, do I need to change 100 different YAML files or config maps? And I think the technology’s evolving.

    Help is just one example. And then I’ll associate that with all the continuous delivery. You all know Spinnaker and a bunch of different technologies in this area, Octopus and so forth, that can help.

    Shimel: Yep. Mitch, did you want to say something? Otherwise, I want to – I’ve got another –

    Ashley: All I can add to the conversation is version control across all of this also gets very complex. [Laughter] I think you all –

    Shimel: But isn’t that what Git and Repositories are supposed to help us with anyway?

    Ashley: It is, but now you’re versioning all of your scripts along with all the environments and all of the variables of what you’re trying to script.

    Ragan: And it’s not relational.

    Ashley: Yeah.

    Ragan: You know, when you have – what’s the blast radius of my microservice? I’m going to push it out because my hipster store needs the new card service. If you’re using an SOA architecture that means that you have one card service and everybody’s using that version and that’s the best way to move forward because you eliminate the sprawl. If you put it all in its own namespace, you have multiple versions of the card service. So now you have a problem with the card service and you have to go update all the namespaces that’s using that card service.

    So you have to have a relational model to be able to track what applications or what namespaces are using what microservices. And unfortunately, Git is not relational. We create relations using tags, using different repositories, but that becomes redundant.

    Ashley: Great example.

    Shimel: Fair enough. So let me –

    Doshi: Tracy, you talked about the structure.

    Shimel: Oh, go ahead, Parag.

    Doshi: I was just going to follow up and ask a question to Tracy. I think what you’re saying there is Git is just a big version control repository. If we can provide some extra structure and relationships around all these artifacts that we’re storing there we might have better control.

    Ragan: And that’s what you call catalog.

    Doshi: Yeah.

    Ragan: Right? So I think we’re starting – when we really look at a service-oriented architecture and we look at – let’s say, for example – let’s push ourselves farther into the future. And Brendan brought this up around service mesh. And I believe this can happen and will happen. I believe service mesh will be enhanced on.

    Right now you can say do a deployment and deploy out to 10% of my users. I think service mesh will start looking at active directory and say deploy out to my developers. So now we have one cluster and we have immutable services out there. We put a new service out there, it gets requests routed to the developers, they do their testing on it, once it’s good it’s rerouted to their testing community.

    Then it’s routed to a certain group of their production community. Which means that we don’t have deployments across multiple clusters. We’re going to start pushing into a one big cluster, which sounds a lot like the mainframe. [Laughter] But we’ve come full circle. And as Alan said, the song, right? Meet the new boss, same as the old boss. [Laughter]

    Shimel: Right. We won’t get fooled again. That is true. There is certainly some truth to that. I wanted to spend a little time talking about the impact of GitOps on the CI/CD market. We’ve written in devopsy.kinsta.cloud several articles, the gist of which was DevOps is the symptom of disease. CI/CD is the cure, if you will. Right? And we’ve built this whole DevOps industry around CI/CD solutions.

    And I mean look, GitLab’s a great example. They had a great Git product to begin with. But it was their CI/CD solution that kind of moved them into that end-to-end DevOps, if you will. Right? GitOps I think has profoundly changed that market because it’s profoundly changed the way we do CI/CD. Well, that and Kubernetes, right?

    Kubernetes I think was the initiator of it. What does it mean for the market? What does it mean for our audience out here? And we have a technical audience, 60% of which are practitioners, 30% are managers or higher, and 10% are just, I don’t know, vendors. But what does it mean for them out there?

    What does it mean? I mean, these CI/CD tools that they’ve gotten used to, that they’ve grown up with a bit over these last years. What does it mean for them?

    O’Leary: Well, Yeah. I think that we love to say CI/CD together. I mean, I love to say CI/CD together, right? That’s now we name our product. But those concerns have always really been separate and never really been completed merged and married. Like it’s great to try and think about them as a single unit – CI slash CD, right?

    But I think the reality is that CI is something that has been around for a really long time, probably 20-plus years if not more, but CD is something that a lot of organizations still struggle with for any number of reasons, whether that’s a technical reason, whether that’s an organizational structure reason, whether that’s a risk aversion reason. The idea of doing continuous deployment is something that really is very dependent on your organizational structure, who your end users are, and the, yes, to some degree like you said, Alan, the tooling that you choose. And what we’ve seen in traditional CI/CD tooling is this concept of applying what we do in CI, which is scripting based on an event, running through a number of scripts.

    That is what then becomes CD. Well, now we’re going to push with scripts out to the environment. And so GitOps, you noticed in my definition I didn’t say that a pull was necessary. I think you can do push-based GitOps if you have infrastructure as code, you have MRs at the point of change control, and you have the ability to do CI/CD. But I think most people when they hear GitOps think about this another new concept, which is this concept of pulling. Right? We’ve heard Tracy talk about that.

    And so having an agent, an active agent inside of your infrastructure that is constantly ensuring that your desired state is the actual state in the world – that’s what Kubernetes brought to us, that’s what – and then that’s what pull-based GitOps brings to us. And so that’s why for us we’ve been doing CD for years, like you said, Alan, and we’re doing mostly push-based. But as our customers’ needs expanded in GitOps we’ve adopted a Kubernetes operator and now we have our own Kubernetes operator, and you’re seeing this more and more in all the tools, that runs inside of the cluster and pulls changes in.

    And that methodology, while – again, credit Tracy – sounds a lot like Puppet, [Laughter] it still is something that was the alure of Kubernetes for a lot of people. Hey, I want to describe my desired state and have something else worry about that desired state always being true regardless of if I push something wrong once. I want this desired state to always be correct. And so I think that’s how we’re going to see a huge change in the tool space. Right?

    To Parag’s point, we’re talking about Spinnaker. That’s something that Netflix has been using for a long time, but no one ever thought that they would be deploying like Netflix. Well, now it’s a huge deal and lots of people are talking about it.

    Shimel: We are.

    O’Leary: And they are, right? And so it’s very interesting.

    Shimel: Mitchell, it sounds like an analysis question.

    Ashley: Well, I was thinking about that very much, and I appreciate Brendan’s perspective on it. Because any time you have a major paradigm change, you have early adopters and then you have a long tail of how that adopts out. And you’re talking about the Netflix. People are now starting – how long have we been talking about Netflix as the example? As long as we’ve had DevOps and continuous deployment.

    And I think we have a bit of the same challenge here of instead of still having layers of our stack and different responsibilities or processes or things that go into creating environments, whether it’s from code or not, when we say it’s all going to be based on a pull and it’s all going to happen in its own environment, if you will, that’s a bit of a big pill to swallow for a lot of organizations, especially in complex applications. I’m not saying it’s not going to happen, but I think it’s going to be slow to adopt. And I’m sorry if I’m going to get a bunch of hate mail.

    It’s a great concept, but I do think it’s going to be more difficult to adopt than even containers were for breaking down applications. Not that it’s not a good idea or the right idea, it’s just instead of software architectures, modern software architectures being something the developers now get their mind around with containers and microservices and fabrics, meshes, now you’re talking about different parts of the organizations going into infrastructure and ops. And that’s all getting compacted together and you’ve got multiple parts of the organization getting behind that paradigm shift. So that’s my view of it.

    Will we see things in the market around GitOps? Of course we will. But I don’t think we’re going to see this tipping point that will happen rapidly. That’s my assessment.

    Shimel: Okay. So it seems like you and Tracy have formed some sort of coalition here, and –

    Ragan: [Laughter]

    Ashley: I always go to Tracy when I need something _____.

    Shimel: Right. Send the hate mail that way.

    Ashley: _____ Brendan and Parag, too. [Laughter]

    Shimel: Right.

    Ragan: I want to say that the CI/CD pipeline can adopt GitOps quite efficiently. Think what Brendan pointed out. When you think about CI/CD you think everything’s a push. Right? And you add a script that you’ve executed that your CI/CD server, your orchestration server, your job scheduler said, “Hey, there’s a step here.” Then that step goes out and pushes an update to production environment.

    How that’s going to – because GitOps is a pull methodology it doesn’t have a promotion methodology. And what really we’re going to see is for folks using GitOps is we’re going to see the CI/CD process do the – create the pull request. And there will be an approval. If you want a pull request to go into production, there’s going to have to be probably a manual step to approve that pull request, and then once it gets there the CI/CD pipeline creates it. Now the challenge will be having the CI/CD pipeline automatically update all of those declarative scripts. [Laughter]

    Because there will have to be a different one based on the environment. But that is totally doable and it doesn’t change that. But what it does do, it says, hey, CI/CD. You need to have a hermetic process. It needs to be airtight. You need to have a single source of truth.

    What that is ultimately will still be called GitOps, even if it’s not Git that is that single source of truth. It’ll be like we reach for a Kleenex, not a tissue. [Laughter]

    Doshi: Let me back up what Tracy just said, and maybe take the view of – I think you said 30% of the listeners are looking at this from a business angle. And your question also sounded like what does this mean as our industry, to our industry? So today we’ve got, I don’t know, 170 different products, if you will, and tools around – and Brendan can probably say, no, it’s now 250 or something [Laughter] – around DevOps and all the new different concepts.

    Shimel: Closer to 700.

    Doshi: Oh, okay. My bad. [Laughter]

    I was a little behind. So we have so many things here, and there’s a reason for that too, right? So we can’t just say, hey, let me take a cloud provider’s full CI/CD DevOps vision and hope that we’re going to impose one way of doing things, because this is not all worked out. The moment you bring the developer mindset to other layers of the computer stack – infrastructure, environment, operations – it becomes so complex. And I think at an industry what it’s going to do is it’s going to actually spur a lot of opportunity, a lot more innovation.

    I don’t know if that means that 750 will go to 1,050, but there’s so much room for different companies that will do things differently – push, pull, I need an approval before production due to a segregation of duties. No, no, no. I want to approve before I even commit the code or at least run the security static analysis, the dynamic analysis, the container image scanning. Everybody will have different ways of doing things, and I think it’s going to spur on lots of opportunities for a lot of companies.

    Shimel: Fair enough. A giant petri dish. Guys, I’m going to need to pull the plug on us here because we’re up against our time limit. But what a great conversation. For our audience, in a couple of weeks – and I don’t have the date in front of me, I apologize – we’re actually going to do an interact roundtable on this subject. Some of our panel members will be back for that.

    And we’re going to allow you to come online and ask questions and comment and join the conversation on this. I think it’s a great conversation. So be on the lookout for that and come check us out. But in the meantime, Tracy, as always, you know, you bring so much to this. Thank you so much. Thank you so, so, much.

    Ragan: Oh, it’s my pleasure. Absolutely my pleasure.

    Shimel: Yes. Brendan, always a pleasure to have you on, my friend.

    O’Leary: Yeah.

    Shimel: Look forward – also, Brendan does a show with us here on TechStrong TV every month. It’s called The Lab. And he discusses – you know, the 22nd of every month is a new GitLab release and Brendan gives us the lowdown on each month’s release. It comes out once a month. It’s called The Lab, and it’s available here on TechStrong TV. So Brendan, thanks so much for that.

    O’Leary: Yeah. Thanks, Alan, for having me. I always learn so much from these panels. So hopefully we all learned something today, but I really enjoy doing them.

    Shimel: Always a pleasure. And you add as much as you learn, Brendan. Thank you. Parag, one question for you. You mentioned earlier that you were a former physicist. Is there such a thing as a former physicist? Isn’t it more like I think, therefore I am?

    Doshi: Yes.

    Shimel: Once a physicist, always a physicist?

    Doshi: It certainly is Hotel California. You’re absolutely right. [Laughter]

    Shimel: Yep. But thank you so much for joining us. Always great to have you here and bringing some great perspective to everything. I appreciate it.

    Doshi: Thank you.

    Shimel: Mitchell, what can I say? We wrapped another one, Mitch. Good stuff.

    Ashley: Yeah, we did. And I’m just so glad that Parag didn’t bring quantum physics into this, because I’d be in trouble.

    Shimel: That could be another show we’ll do.

    Doshi: [Inaudible comment]

    Shimel: Quantum computing. But, no, anyway, that’s going to wrap up this episode of DevOps Unbound. We hope you’ve enjoyed it. This is every other week we do a fresh DevOps Unbound, so be on the lookout. Every month we do the roundtable with the audience, so be on the lookout for that as well. This is Alan Shimel for MediaOps. You’ve – oh, before we go, many thanks to Tricentis for sponsoring DevOps Unbound. We couldn’t do it without them. So thank you all very much. We’ll see you on another episode.

  • EP 8: Testing Is Not a Monolith

    EP 8: Testing Is Not a Monolith

    With DevOps comes implementation of CI/CD, automation and testing. Is this sufficient to achieve “shift left testing”? Or does testing need to shift further left? Do we need new or additional tests for acceptance (ATDD) or behavioral testing (BDD)?

    In this episode of DevOps Unbound, we are joined by Christine Fisher of NAIC, Leandro Melendez (aka Señor Performo) of Qualitest, Ken Pugh of Ken Pugh Inc., and Mitch Ashley of Accelerated Strategies Group to explore the state of testing in DevOps and CI/CD pipelines, and where testing can evolve to keep pace with software development and delivery.

    The video is immediately below, followed by the transcript of the conversation. Enjoy!

    Transcript

    Alan Shimel: Hey, everyone. Thanks for joining us on another edition of DevOps Unbound. We have a really great DevOps Unbound topic to explore today, and that is that testing is not a monolith. A lot of people, especially people who aren’t familiar with testing, just say testing—QA, testing—and we think of, oh, it’s a test. And we know there’s different kinds of tests, but do we really know all the different kinds of tests that need to be done, as we’re developing and deploying and managing and monitoring software applications and so forth? I don’t think so. 

    I think, really, we could cater this show to those of you out there who do know, but I think today, we want to talk a little bit to those who don’t know as well and let’s try to get you educated on what some of the various aspects of testing are that you may not be familiar with. They’re important, nevertheless, and how they influence what you see and the apps you use and what we may see going forward.

    I’ve got a great panel to introduce you to today. I’m gonna allow them each to introduce themselves. Let me first start off with Leandro Melendez, I can’t say it with that Spanish roll of the tongue that you can, Leandro, I apologize. And Leandro is known in the industry as well as a name—I’m gonna let, I don’t wanna steal your thunder. Leandro, introduce yourself.

    Leandro Melendez: Thank you very much, and don’t worry, you made a great pronunciation of my name, way better than what I’m used to, so that was pretty good.

    Shimel: Okay.

    Melendez: Yeah, repeating, I’m Leandro Melendez, a performance test manager from Qualitest Group, and as well, I’m known on the internets as Señor Performo, as you all said, Performo with strong R’s.

    And well, we provide several services to—my specialty is performance testing, integrating it right now with full continuous integration DevOps and agile methodologies. But as well—and you mentioned it very well earlier—it starts to permeate in other areas of testing when you start to do it holistically and at a large scale, and thinking on all of the steps on the SDLC. So, we will talk a little bit more about it.

    The last thing about me, as I said, Señor Performo, on the internets, I have a YouTube channel, I try to help educate people on especially performance testing, but anything that concerns testing and methodologies, agile, DevOps, and all that, I’m very happy to help provide information as well as hear whoever gives me a chance to speak and share the knowledge, I’m very happy to.

    Shimel: We’re honored to have you here, Leandro, thank you. Next, we’re gonna introduce Ken Pugh. Ken is—well, Ken, you introduce yourself. Go ahead, I’m sorry.

    Ken Pugh: That’s okay. Hi, I’m Ken Pugh. I’ve been in the programming software development field for about two-fifths of a century, and in agile for about a fifth of a century, and doing everything from gathering requirements to final testing.

    I’ve got a book out called “Lean-Agile Acceptance Test-Driven Development: Better Software Through Collaboration,” and I’ve been teaching, training, and emphasizing acceptance test-driven development-slash-behavior driven development for the past 15 years.

    Shimel: Fantastic. And for our fraction challenged friends in the audience, a fifth of a century is about 20 years, so that’ll give you a little idea.

    Next up, we have Christine Fisher. Christine, welcome, introduce yourself, please.

    Christine Fisher: Thank you. My name is Christine Fisher, I manage a team of BAs, QAs, and UX at the National Association of Insurance Commissioners. My team and I have been on a journey with behavior-driven development over the last two and a half years, and as we get ready to talk about testing here, my big secret is, I’ve actually never been a tester, I just have managed some. But with our jump into DevOps, I felt very strongly about advocating for what our role should be and how the work should change to keep up with the other changes that were happening with DevOps, which helped lead us to BDD.

    Shimel: Fantastic. Pre-COVID times, we’d say, “But I did stay in a Holiday Inn Express last night,” but we can’t even say that any more.

    Last but not least is my co-host and anchor on our show, Mitchell Ashley. Mitchell, why don’t you—quick introduction?

    Mitch Ashley: I don’t know what fractions I’ve worked, but I do know that I used that joke last night and my family had never heard it, so—so much for the Holiday Inn Express joke. [Laughter] 

    But, no, I’m an old software person, started in software, and have done lots of things around both cloud as well as, I’ve also been on the vendor side, so network security and SaaS services. So, testing people are some of the most unique and, in my world, beloved people, because those are the folks I really look to to say, “How are we doing? Where are we?” And I think even more so in the DevOps time, so I’m excited to explore this with you all. So, thanks for joining us.

    Shimel: Fantastic. So, first of all, let’s assume that our whole audience aren’t test experts, they’re more DevOps generalists, there’s a good smattering of cybersecurity folks, cloud native, infrastructure, ops, and we’re throwing out some ADD—behavior-driven, BDD—you know that they may not be familiar with.

    So, why don’t we do a quick kinda definition? And we’re gonna ask the non-tester, if you will, Christine, if you wouldn’t mind leading off with what are these references we’ve made to these types of testing?

    Fisher: Sure. So, when we’re talking about behavior-driven development, we’re talking about understanding the behavior of the end user and understanding what the workflows are, why they are trying to accomplish that task, and working on testing, understanding the requirements, testing those requirements in that way, not just writing a requirement, developing a requirement, testing a requirement without any true understanding of what the person who’s going to use the software on the end does.

    And when I talk about not being a tester, more on the functional side with requirements as a BA, things like that, that was always the interesting part to me. And then sometimes, we would test something and it would be tested correctly, but we still missed the mark. And so, having the whole team understand what the end user wants to do, putting it in the common language, that’s really important for behavior-driven development.

    Shimel: Agreed, agreed. Ken, do you want to add anything?

    Pugh: Yeah. So, one of the big things in behavior-driven development or acceptance test driven development is having the triad, and Christine sort of made a reference to it. The customer, developer, and tester get together prior to implementation, create the scenarios, the scenarios become the tests, and the developers are given those tests to run against their code, and those tests are the agreed upon, shared understanding of how the system should work.

    Shimel: Got it. Señor Performo—is that correct, yeah? Sí?

    Melendez: Very well said, yeah. [Laughter]

    Shimel: Señor Performo, how does acceptance-driven, behavior-driven development figure into your performance testing kind of regimen, if you will?

    Melendez: Well, as I mentioned earlier, these type of concepts permeate in all the testing practices, if I could say, and very well as it was said here, I like to call it the three amigos, that you put them together and even before you start rolling anything, drafting anything, you get the requirements well together with what you are going to be testing and what has to be marked as passed before you even—or a developer—can mark a task as completed. And I might have said it wrong, a developer, because in general, you’re supposed to be a team, and everyone is responsible for each element.

    And this comes together with performance metrics, where, in general, most of the people, when they think about performance, their mind goes right away to load tests, when I have to put hundreds of users to slam a system, where, if you see it from the beginning as well as some of these requirements when you generate them that, I don’t know, I’ll give an example, that the text field has to just allow a certain given of characters or be this color, rounded—little definitions like that, it should have included performance metrics as well inside of it. So that, when you are generating any piece of software or functionality, it’s measured there and then. 

    I have to say it’s an issue that I found often in the old waterfall days. I would arrive to do a load test after six months of development and start to automate some things that I’m like—this, hey, everybody, this is visibly slow. Just, I’m a single guy. I don’t need to load test it, why no one caught this before? 

    And those are the most general problems, in terms—I think, as well, in functionality, some things that come from even unit tests, low level tiers where you could catch many of those bugs and performance SLIs that are not met and that’s how it integrates a lot with performance. I always preach that you need to start to think about it as early as possible. And as Christine mentioned, getting the people together, what are the goals, what is the user gonna require, and what are the tasks? Because not everything should respond super fast and not everything should or can have a good response. I mean, we all wish that a—I don’t know, monthly billing period can be closed in three seconds, but that’s just for that response time from a click.

    So, we need to filter that out depending on what is the user needing, willing to endure, to call it in a way, and put it together, and this permeates as well. It’s some sort of functionality like—yeah, I need this to respond in this period of time for me to be comfortable using it, for it to be useful, functional.

    Shimel: Comments, thoughts from the team?

    Pugh: So, as you were mentioning that, I don’t know if you’re familiar with healthcare.gov.

    Melendez: [Laughter] Oh, yeah.

    Pugh: I think they should’ve had a few performance tests done well before they released it. It seems like—I don’t know, that it was like, maybe the day before, they went, “I guess we’re gonna have a lot of people on this.” [Laughter] 

    Melendez: Yeah, and I think, and to paint and explain what I was saying, with a single element that doesn’t perform well, that doesn’t work well, even from the initial tier, they should have created these requirements, saying, I don’t know, “When I log in and enroll, healthcare starts the process when I click this. It should respond this fast, it should not do, I don’t know, this many full table scans, connections to the database,” things that you can go way, way low level in the IT tier, and others and it’s just like, “Yeah, the user should not wait more than five seconds on that click”—a single user, one person.

    I am almost sure that most of the problems that they had was that they didn’t start to tune that, and they allowed the developers to check in all that awesome code, to call it euphemistically. And that’s when you start to scale up problematic things is when everything derails. And yeah, healthcare.gov, aside from not doing good load testing, they had multiple issues at the single piece level, and that’s where it is, push it left. Start to think at a unit level, single item requirements, when you have the three amigos together talking about these things, take everything into account and don’t let your little Post-its to be marked as done and move to the next area of your board without covering some of those basic requirements, which most people doesn’t think about or include them. Or whenever, and this is a little biddity or tiddity, when the developer is working on it, should have in mind all those requirements—functional, performance, security. 

    And that’s where I say, all this permeates to all the testing areas and other metrics when other areas of testing are doing their tests—manual, functional, automated, even security—my goal is to start to gather performance metrics so that everything happens together and we don’t have to wait until the end for big load tests to figure out that healthcare.gov will have what happened, sadly. [Laughter] 

    Pugh: So actually [Cross talk]—no, so, actually, you were talking about something that I’ve, in fact, I’ve done a few blogs on this, but it’s been around for a while is the testing matrix. I.e., that shows, since we’re talking about testing and it’s not just about functionality, it describes all the different sorts of tests, from the functionality tests which are on one side of the matrix, to the quality tests which are on the other side, including performance, security, usability and so forth. And that you’re testing—I mean, ATDD and BDD tend to concentrate on the functionality, because we’re gonna be talking with the customers, that’s what you want.

    But you ought to have all those other tests, the performance tests as you were mentioning, already established ahead of time—100,000 users, how fast should it be, and so forth. Oh, and in fact, just the usability you were talking about—how long should it be after I click that I get to the next page? And those things could be established ahead of time, and if a developer goes up and it’s not meeting it, he knows to fix it. That’s, we don’t have to—

    Melendez: And I would say here, not only established, but worked on from day one. Because as you mentioned, even some usability, security—those are to be checked when everything is assembled, and there are many techniques that we can start to embrace, starting out with automations at different tiers.

    As I said, I’m a big proponent or supporter of—yes, have unit testing, automated everywhere, have the coverage according to the pyramid. Don’t focus so much on manual, front end, or after the fact, leaving everything for the second Friday of the sprint when everyone wants to leave and here, tester, there you go—start our meeting. That’s where everyone has to start to work together and pushing it left.

    Since day one, start thinking about performance, security, functionals. And even some have told me, “Yeah, but there are things that, as you said, usability, that cannot be done until the end.” Well, you can start creating mocks, you can start figuring how things should work and start to work them. And, again, I think the mindset of keeping testing phased, waterfall ways—we need to start to work everything on par and get it rolling, yeah, I totally agree.

    Fisher: I’d like to speak to that point a little bit with DevOps and with the testing. We’ve been talking about a team and we’ve been talking about getting people involved, and what I was seeing in my organization when we first started talking about DevOps is, everybody is an engineer. We can all do these jobs, things like that, right? And jobs might change, there’s room for everybody, but what you’re doing might change a little bit. But that can be really scary to hear, and especially if you are a manual tester who really doesn’t have an inclination or desire to learn automation—and that’s okay. Like, that’s a different conversation, but I am always a proponent of manual testers.

    So, one of the reasons that really pushed me toward that is hearing that conversation, seeing people on my team being told that their job might change, but we don’t know how, you’re an engineer, you can do what everybody else on this team does, but that’s not true. Not everybody has those skills.

    And so, making sure that the team is involved, and when you can have these conversations, BDD, all of these things that we’re talking about now, right, are getting the testers involved in the conversation earlier, and that makes them part of the team. And we have taken our BAs, we’ve taken manual QA, we’ve taken our automation QA—we get them all involved in that conversation. We make sure the developers know where they are in the process, we make sure the developers are adding to the conversation and part of that process.

    And it was really important to me in that DevOps environment to get out in front of that and help define that role when somebody is saying, “We don’t”—you know, again, your role might change, but we’re not quite sure how—I wanted to help my team define that and put us in a good position so we weren’t just sitting there to have, God forbid, a developer come down a few years later and tell us, “No, you do it like this.” We wanted to put ourselves into that position and having those conversations, I think, is such an important part of that and changes some of that dialogue a little bit about we can all do the job. We can’t, but we all have important jobs to do to make it work.

    Ashley: You know, Christine, I think about just an analogy—robotics for surgery. I still want that doctor in there guiding what’s happening, right? We don’t need any bad things happening. [Laughter] Well, same with software. You know, some of the worst folks at testing software are developers, right? You’re just too close to it, even if you’re writing the automated tests.

    To your point, and I think several of you have made this, is, it’s an opportunity for us to (a) collaborate much more closely together rather than testing to be the thing right before documentation at the very, very, very end of the release, right, which is what it used to be. But also, what do we automate? It doesn’t help to automate the wrong tests—let’s get the right things in there. And where is the user in, the customer in performance, in functionality, in speed?

    By the way, one of the things that kind of baffled some development teams is when I would say, “Speed is quality.” They’re like, “What do you mean, speed is quality?” I’m like—well, if Netflix takes three seconds to start your video, okay, that’s good. If it’s pausing for three seconds every five minutes, that’s bad, right?

    So, speed makes a difference in terms of the perception of the experience. So, it is really kind of a harmonious effort where we have to bring all of that together.

    Melendez: And now that you mention it, I’m gonna play a little bit devil’s advocate towards and against at the same time manual. Some forums that I participate in here in Mexico talk about that a lot, like—hey, too much automation. Are we manual testers gonna be out of a job and the machines will replace us, and all those paranoid ways of speaking.

    And I generally explain to them with analogies—I like, a lot, to use analogies. In New York City, before there were any automobiles, cars, there were lots of horses, and horses produce a lot of stuff that was dropped on the streets, and there was a job needed for that, to pick up some of the horse. And I’m sorry if this is an analogy of manual to what the horse produces, but the point that I’m trying to do is that once cars became available, that job decreased considerably. But we still have places where there’s people that work with the horses, maintain them, brush them, and do all those tasks which, as many cars as we may have, we won’t ever have a horse polishing machine or anything like that. There are things that, truly, a human being is the only person that can do it really well—manual testers are very good for those tasks.

    I think, on the other hand, there are too many things that are tried to be done with manual testing. I have seen in many organizations that there are tasks and tests that could be pushed left, that could be started to be done before automated programmatically and leave whatever is truly necessary and where the manual testers are going to be the rock stars and the only ways to do it allow them to.

    So, I think—yes, I would suggest most manual testers to start to pick up a little bit on technical and developing, yadda yadda. I think in the modern days and the upcoming times, everyone should know some sort of development, that should be in schools. And we’re moving into a technological world at a pace that whoever doesn’t pick it up might be a bit handicapped. But, on the other hand, the skills of a good manual testers, when you have that clinical eye to say, “Hey, I see the error” or you don’t even have to touch the application; let’s say, most probably, it accepts fields that it shouldn’t in that field. And most of the times they are right, and you need that input.

    So, on both sides, they won’t be replaced, but they should get used to using the tools as they are. Technology is not here to replace them but to empower them, and they should be able to use it, I think.

    Fisher: Skills can be—excuse me. Skills can be enhanced, absolutely, and I agree with what you say. Nobody wants another meeting on their schedule, but on my team, we have added what we call a test strategy meeting and we get  the BA and the manual and the automation QAs in the room and we talk about each of our stories, and should we automate it, what are we looking for manually? And they took that further than when we first started, and they came up with a scoring guide to say, you know, what is our level of effort with this, what’s the repeatability for the user?

    Those types of things, and they’ve realized that those conversations are so important and you’re exactly right—the manual testers aren’t doing the same job, but now that we’re able to really give them the time to pull those skills out, the critical thinking and what you were mentioning, you know, looking at this field, we are getting so much more quality from our tests, from both sides, and it’s really been a fantastic change.

    Melendez: Yeah, that’s great, and optimizing and, in a way, calling it where you get the best bang for your buck, where to use those efforts, how to use them, prioritizing. And even some things that—hey, this is not a big impact if we get a defect here, we won’t even pay attention to it manually, whoever made it, or some others that this is critical if we get a problem that has to be done manually with two pairs of human eyes, capable eyes, to identify it, or we can let the machine do it.

    I mean, there are balancing on testing, and I think falling into the cognition mental fallacy of, it’s called man with a hammer—someone learns how to use a hammer well and will see nails everywhere and try to hammer them. There are multiple other tools that we can use when it’s needed, when it’s more optimal, and I think it’s, as you say, prioritize, distribute, and make the best effort with each one of them.

    Pugh: So, just getting into that, one of the things in the matrix and one thing I always suggest is that exploratory testing. You take your manual testers and turn them into exploratory testers—finding those things that the functionality tests are not gonna cover.

    I always give an example, for those who don’t know exploratory testing, of—you’re on the web, you’re ordering an item. You press the submit button and the screen comes up and says, “Do not hit the back button. Do not refresh this page.” And the exploratory tester goes, “Yeah, back, forward, back, forward, refresh, refresh—maybe I’ll get it for free. I don’t know!”

    Ashley: [Laughter]

    Pugh: There’s no way of telling. [Laughter]

    Shimel: We live for those moments—we get it.

    Pugh: [Laughter] 

    Ashley: Yeah, don’t make any buttons red, they’ll be pressed, for sure.

    Shimel: Right, yeah. But let me kinda take our conversation a little bit of a way, here. You know, we’re 25, 30 minutes in. We haven’t spoken a lot about DevOps, which is interesting, right? Especially in light of our original conversation off camera.

    You know, when we talk about behavioral-driven testing and ADD testing and performance testing, these testing disciplines all existed before DevOps, right? Ken, you’re doing them for a fifth of a century or more, right?

    Pugh: [Laughter] 

    Shimel: That certainly predates what we call DevOps. And I was here when I started devopsy.kinsta.cloud back in 2013-’14. There were a lot of testers who were running around like, you know, Henny Penny, “The sky is falling,” that they were gonna be out of a job, they were gonna be obsolete overnight. And, of course, that hasn’t happened.

    Christine, you said that DevOps was kind of a driving factor in why you took the baton, here, why you took this position, why you feel it’s important. I’d like to bring it back, our conversation, a little bit to DevOps. How has DevOps changed BDD, ADD, right? Automation? Absolutely, right, but automation is not necessarily DevOps, right? We automated. We’ve mentioned a little shift left, you know, pushing it further, not pushing it further on the developers’ shoulders, because as, Ken, you said, we don’t meet the new boss same as the old boss, right? We don’t need that. 

    But how can we be more efficient, better at testing? Is it just a matter of automation, or is there something else there? Christine, I’m gonna ask you first, because it’s something that I think is near and dear to your mission.

    Fisher: Sure. And I think for me, really, it is the conversations, how long has QA sat outside of the development organization, right? I mean, we can bring them in if we talk about agile and scrum and things like that—even, again, before DevOps, we can have a tester embedded in that team, but we still have lots of organizations that don’t do that.

    Realizing that quality, not testing, that quality is the responsibility of the entire team, and that everybody needs to contribute to that conversation, we talk about breaking down the silos and everything with DevOps and we’re all in this together, and that includes testing. And for me, that’s been the biggest part. We can talk about BDD or whatever we want to talk about, however we want to test something. The most important part to me is that the testers are at the table and that they’re part of that conversation.

    Shimel: And I think that’s inherently part of the DevOps cultural kinda mantra is that everyone should have a seat at the table. Ken?

    Pugh: So, one of the things, getting back to the DevOps, is the fact that every time you have a test failure after something has been actually developed and put into the pipeline, it means you’ve gotta loop back. It means that you are slowing down the flow of business value through that pipeline.

    So, the reason we want to create all these tests first is so that we pass them, and when it goes into deployment or staging, wherever you put it, that you don’t get a test failure. You don’t have to triage everything. And so, that’s why creating all of the tests first that the developers can be running while they’re developing their code or in their development environment is so important.

    Now, I’d just like to add one more little phrase that I always use or talk about is—requirements should have a test for it, right? Pretty straightforward. How do you know whether the requirement is actually being met? But every test is a requirement. If you cannot ship a system with a failing test, then that test is a requirement the system must meet.

    One of the things that developers always complain about is not having enough requirements, unclear requirements. The test that you create prior to implementation—BDD, ATDD or however you get ‘em—are the requirements. And now the developers have the test that they can go against those requirements, make it past, and then the flow through the pipeline doesn’t stop. It doesn’t, you don’t have a blockage because of failure later on.

    Shimel: Fair. Comments on that?

    Melendez: I think catching those errors, defining them, and being a bit more synergistic, to call it, in a way, it’s crucial. You very well mentioned all the testing practices, areas, and disciplines that exist come from waterfall and even before.

    But I think a shift that was forced by DevOps and the agile methodology, continuous releases forced us to think in a different way. And I don’t know if it was the chicken or the egg where we started to see that we needed to throw down these silos and as well that the communication channels and capabilities to observe what was happening. Because as a tester, 15 years ago, I remember, you would just receive something finished, you had no idea, and somehow, you had some peculiarly written requirements that you had to write tests for and try to figure out, but everything was already packed up, backed up, ready to ship. And you were just trying to stop, like, a meteorite that was about to hit, and you were like—I don’t even have control. I detect something, I send it before a production release, and I have this box that I detected. I’m sending them somewhere, probably the developers were even gone. 

    All those situations that we experienced before on any testing area that now that everything is happening continuously, fast, we have feedback, we have—we don’t own only the development side, the testing side, the operations side, but we own all the loop, we’re involved, and hopefully, we have communication with each one of those areas. And I would say not communication that the lines that divided us are blurry now. We are just multi-capped T-shaped people that can jump into, “Hey, now, this is a deal with development on Ops, I understand that this is happening, we have logs. We have different release methodologies.”

    I think DevOps and the openness that is happening as well as, from my perspective performance that I have some tools now that allow me to see into the code, to monitor it, telemetry—all these fun things that we can work with have allowed us to evolve and to integrate as, it was very well said, from clear requirements, clearly knowing what is needed. If we detect something wherever, not only before releasing to production, but now it’s in Ops, there’s a bug that was not caught and we catch it right away, we roll back or we release, quickly, a fix—those things were forced, given those things. Or I don’t know if forced—again, I don’t know if it’s a chicken and an egg situation, what came first. If now we have more visibility and capabilities, we start to release more often and communicate development and operations.

    But all this synergy has to happen and is needed for us to truly embrace DevOps, have quality in it, and keep releasing often with quality.

    Ashley: Alan, I have a question I’d like to pose to the team about DevOps. We don’t do DevOps just for DevOps’ sake, right, there’s usually some drivers behind it. And when you think about the conditions we’re in today, economic conditions, changing markets, rebuilding our supply chains, contactless services—there’s a great example—in days and a few weeks, businesses had to respond. Point being, one of the things businesses are looking for from their technology, from their software, is agility—the ability respond quickly, experiment, go after opportunity, defensive, whatever it might be.

    From a testing standpoint, how do you think that’s changed how you respond and how you do the work that you do, knowing that there are situations you have to react fast, and how has that changed how you work? Any thoughts on that?

    Melendez: Well—sorry, go on. I have played too much today. [Laughter]

    Pugh: Well, let me just give an example of a current situation. There is one place that I was consulting with—their manual testing effort took 5,000 hours to release a product. You’re not gonna be very agile if it takes you 5,000 hours, that’s 50 testers working over a month, and I don’t even know what they did, if they found a defect, whether they restarted again.

    So, the whole concept in being agile is, you need, as we talked about all the automation around everything, because if I’m gonna make a little change to something, I wanna make sure I haven’t broken anything else. So, I need the automation that matches exactly what the requirements are so that, then, I can run it through the pipeline. If I don’t have the automation, I have to pause for three days for manual testing, I’m not gonna get things out pretty quickly.

    Fisher: And to build onto that point with BDD, you can see so clearly where you have a failure in your test. When I joined my current organization, they had just really started with automation, and there wasn’t a lot of direction there—which is fine, that is not any kind of a criticism. But those tests got so complicated and only the people who were writing the tests knew what was happening in them and where those failures were and troubleshooting a failure could take just as long as troubleshooting the code.

    So, taking something like BDD, we’re gonna build on the agility, we wanna make it open to the team, the manual tester can find out where that failure was, a developer can find out where that failure was, and then we can very easily test to see—test the test to find out if it was a problem with the test or if it’s a problem in the code and then send it to the appropriate place to get it addressed. I think that that piece has just been a huge improvement for what’s been happening.

    Melendez: And I want to add, as well, from what you mentioned, what’s changed from the old waterfall days to how we are working now with the new trends and everything—I think the first problem that I personally experienced, and I fought against this agile B stuff that started to happen. “Why don’t you allow me to still do automated, big-ass load tests every, before every release? How am I going to be able to keep up with this if I have constant releases every two weeks?”

    And here, I think the biggest thing is a change of mindset, because many of us—and again, I said this myself, I was indoctrinated into how the waterfall days and silo-based release cycles happened. And I cannot even call it cycles, it was just like the big bang release and that was it and you’re out. And you used to think that way. You had to do big cycles of automation that you could execute that took hundreds and hundreds of hours, people involved. And now you need to think about, how can I tackle this now that it’s supposed to happen so often? 

    But a big change is that it’s not so massive any more. We are not doing a whole full release that we need to do multiple regressions here and there and everywhere to make sure. Now we can just say, “Hey, this sprint, I’m just gonna release this tiny, little, little feature that we can just quickly test. Something breaks, something happens, we are sure that our team, ourselves included, can switch direction, detect where is the issue, and implement the fix. And probably tomorrow, if we are super efficient, super quick, and doing things differently, we can recover from it.

    As you mentioned earlier, when there’s tons of tests that you need to execute and there’s an error that you detect, it’s there. There’s a bug, but we want to release every week, every two sprints—sometimes even modern mindsets can be, “Well, let it go to production. It’s gonna pester us for a day or two, but we know that we can quickly apply a fix, release it. Let it pass. It will cause a tiny bit of problems, and even change the course, change the direction if you need it, like, hey, that’s a feature we don’t need, we can take it off.”

    So, all that mindset changing on how you approach testing with this has to change. It’s very different, and I work with lots of customers where I jump in and I’m like, “Yeah, why are you still doing these things that are a decade, two decades old where all this DevOps, continuous, agile is already happening and you’re not even trying to do agile, but you have this big bang release, huge pieces of functionality that you want to push, that’s not gonna help you. And you need to be paying attention constantly and enable that you can recover. Your testing needs to be aimed at enabling that tiny functionality tests everywhere and just relevant to what you are doing.” It’s a complete switch of mind of what was testing before and what it is today.

    Ashley: Fascinating.

    Shimel: Nice. Go ahead, Mitchell, I’m sorry.

    Ashley: Just that idea of being able to release software quickly, right, instead of 6 months or 12 months—that’s a mind boggling shift, right there. Sorry, Alan, you were taking—

    Shimel: No, no, I’m actually saying I think we’re about out of time. I was gonna ask us to wrap up—I was gonna wrap up, but you know what, Mitchell, I gave you the last word, that’s great.

    Hey, guys, as I said earlier on, the time does go really quick. We’re out of time for this episode. I’d love to have you all back, though, and maybe we can continue this conversation. You know, I find it fascinating as someone who doesn’t come from the testing world, right, that testing in its infinite variety has been so profoundly impacted by DevOps and agile and these technologies. But rather than being left behind, it’s been accelerated, right? Through automation and speed and, quite frankly, more focus, in many ways, DevOps has been one of the best things that’s ever happened to testing, right?

    And that’s the thought I want to leave you with out there or DevOps Unbound. This is Alan Shimel, we’ll see you on our next show. We have a great roundtable coming up, by the way. Check DevOpsUnbound.com for all the latest. Thanks, everyone. Thank you to our panel. Mitchell, as always, thank you. Have a great day.

    Pugh: Bye.

    Fisher: Thank you.

    Melendez: Gracias.

  • Celebrating the One-Year Anniversary of TechStrong TV

    Celebrating the One-Year Anniversary of TechStrong TV

    A year ago today, we started a new streaming project called “TechStrong TV” to provide the audience with an alternative source of information and entertainment, focused on delivering great tech content, during the unusual times of the COVID-19 pandemic. Little did we know back then what this would mean for all of us.

    In less than a year, TechStrong TV became an award-winning broadcast with thousands of videos, hundreds of thousands of views and more than 600 guest appearances by tech thought leaders, business leaders and industry experts. Our mission is to provide the best in-depth analysis on current industry issues and to deliver the most relevant tech news and the latest information on software development, DevOps, cloud-native, digital transformation and cybersecurity. Most importantly, we started doing this to help our community stay tech strong in times of uncertainty. We are committed to our community and we believe it is our duty to keep everyone informed and updated on everything that’s buzzing in the IT industry.

    TechStrong TV features a variety of video series that make up our daily show, including:

    • DevOps Unbound: A bi-weekly/monthly roundtable sponsored by Tricentis, providing a deep dive into DevOps, with an emphasis on automation, continuous delivery, accelerating transformation, testing and quality.
    • Analyst Corner: Hosted by Mitch Ashley and seasoned industry veterans, focusing on the latest trends and opportunities businesses see during these unprecedented times.
    • CISO Talk: A bi-weekly video series that explores the issues and topics that CISOs are dealing with today and how they prepare for the future.
    • The Lab, by GitLab: This monthly segment features GitLab Sr. Developer Evangelist Brendan O’Leary as he shares the latest GitLab updates.
    • The H4unt3d Hacker: A weekly podcast hosted by cybersecurity researcher and ethical hacker Mike Jones, one of the founders of Anonymous, and featuring like-minded cybersecurity professionals who discuss ideas and topics relevant to the industry.
    • Ambassador Insights: A monthly panel discussion featuring members of the DevOps Institute Ambassadors sharing their expertise and insights on various topics in the DevOps space.
    • WFH Fitness with Jeremy Jones: Jeremy, a member of the MediaOps sales team as well as a certified personal trainer, brings his knowledge of fitness to TechStrong TV with a 20-minute home workout for any level of fitness, from beginner to advanced.
    • Something Old: Replays of some of the most memorable presentations by top industry analysts and IT practitioners from past in-person and online events and virtual summits.

    We’ve had the pleasure to conduct executive-level discussions with outstanding thought leaders such as Sid Sijbrandij of GitLab, Shlomi Ben Haim of JFrog, Sacha Labourey and Stephen DeWitt of CloudBees, Ashok Reddy of Digital.ai, Sandeep Johri of Tricentis, Emmet B. Keeffe III of Insight Ignite and many more.

    Today, we not only celebrate the show, but we also celebrate each and every one of our hosts, guests, sponsors and, of course, our viewers, for being tech strong and supporting our community. We wouldn’t have made it this far without you. So, thank you for being a part of TechStrong TV and stay tuned because we have a lot of great content coming your way. We are only getting started.

    All the episodes of TechStrong TV are available on demand. You can watch our weekly TechStrong TV livestream on Monday, Tuesday and Thursday at 9:30 a.m. ET on the web, or on YouTube at DevOpsTV Channel, Facebook Live, LinkedIn Live, Twitter or on Roku, Apple TV and Amazon Fire TV via the devopsy.kinsta.cloud TV app. Also on Android and iOS devices via the devopsy.kinsta.cloud mobile app.

  • MediaOps Video Productions Wins 2020 dotCOMM Awards

    MediaOps Video Productions Wins 2020 dotCOMM Awards

    We are pleased to announce that MediaOps is the recipient of not one, not two, but three 2020 dotCOMM Awards for excellence, in multiple video categories: TechStrong TV in the category of video series, DevOps Unbound for video podcast and CISO Talk in video news and information.

    The dotCOMM Awards are an international competition honoring excellence in web creativity and digital communication. They are administered and judged by the Association of Marketing and Communication Professionals (AMCP), an international organization that oversees awards and recognition programs and honors outstanding achievement and service to the profession. AMCP judges are industry professionals who look for companies and individuals whose talent exceeds a high standard of excellence and whose work serves as a benchmark for the industry.

    At MediaOps we are committed to creating and producing high-quality content to tell your story in the most powerful way, pushing the bounds of broadcast technology and creativity—and having fun while doing it.

    We are proud of everything we have accomplished so far, and these awards reflect the hard work and dedication of our talented and skilled team members, who strive for perfection to exceed the expectations of our audience.

    MediaOps Productions Take Top Awards

    Platinum Award for Video Series:

    TechStrong TV, a streamed broadcast featuring fresh video news and information three days a week and replays of prior shows two days a week, on the Digital Anarchist network. Covering DevOps, cybersecurity, cloud native and digital transformation, TechStrong TV keeps its viewers up to date on the latest news and features  interviews with thought leaders and education in the hottest IT areas.

    Gold Award for Video News and Information:

    CISO Talks, a bi-weekly series that explores the latest in cyberspace, featuring industry experts and newsmakers in the field. Hosted by MediaOps editor in chief Alan Shimel and Unisys CISO Matthew Newfield.

    Gold Award for Video Podcast:

    DevOps Unbound, a bi-weekly/monthly roundtable sponsored by Tricentis, which provides a deep dive into DevOps, with an emphasis on automation, continuous delivery, accelerating transformation, testing and quality.

    The MediaOps team would like to thank the dotCOMM Awards for recognizing the content we publish and the hard work that goes into it. Most of all, we would like to thank you, our audience, for all the support you have given us throughout the years.

    These three series, along with more than 1,500 other videos, podcasts and webinars, are available on MediaOps’ Digital Anarchist video platform and streamed via TechStrong TV.

  • EP 6: How to Lead a DevOps Transformation

    EP 6: How to Lead a DevOps Transformation

    Is C-level support required to have a successful digital transformation? In the sixth episode of DevOps Unbound streaming broadcast on TechStrong TV and devopsy.kinsta.cloud’s sister site Digital Anarchist, Mitchell Ashley of ASG and Alan Shimel are joined by Eveline Oehrlich of the DevOps Institute, Louise McCarthy of Bain & Company and Mark Settle, author of “Truth from the Valley, A Practical Primer on IT Management for the Next Decade,” to discuss DevOps and digital transformation at the C level.

    The video is immediately below, followed by the transcript of the conversation. Enjoy!

    Transcript

    Alan Shimel: Hi, everyone. Welcome to another edition of DevOps Unbound. DevOps Unbound is brought to us by our friends at Tricentis. So, thanks for their sponsorship. But, you know, they sponsor but we pick the topics. We pick the guests. And we have a lot of fun here talking about relevant topics around DevOps. Today’s topic centers around DevOps and digital transformation at the C level. And let me introduce you to our panel. First of all, we have Louise McCarthy. And, Louise, I’m gonna ask you to kinda introduce yourself with a little background for our audience.

    Louise McCarthy: Yes. Thank you, Alan, and hi, everybody. I’m Louise McCarthy. My background more recently is doing large, complex digital transformations mainly for the financial services. And mainly through the eyes of the business rather than the technology, although I have held roles as CFO and I’ve held roles COO and CIO as well.

    Shimel: Excellent. Next, we have Mark Settle. Mark, welcome.

    Mark Settle: Thank you. So I am a seven-time CIO and I most recently left Okta about a year ago and have been advising startup companies since then. I’m based here in Silicon Valley. And probably my encounters with DevOps are focused on supporting DevOps communities in terms of infrastructure requirements if they have, and also introducing the concept in actually business application support within a conventional kind of an IT group.

    Shimel: Thank you and welcome. And then Eveline Oehrlich, Eveline, please.

    Eveline Oehrlich: Yes, hello there. Eveline Oehrlich. I’m the chief research director at the DevOps Institute. Before that I spent 13 years as vice president at Forrester Research studying a variety of topics, and DevOps of course was one of them, working with many enterprises and C levels and others to explore the challenges and the fun of DevOps.

    Shimel: Very good. I’ve never heard anyone talk about the fun of DevOps but I’m looking forward to discussing that. And then, last but not least, of course is my cohost here on DevOps Unbound, Mitch Ashley of Accelerated Strategies Group. Mitchell? 

    Mitch Ashley: Good to be here. I’m Mitch Ashley, CEO of Accelerated Strategies. We focus on digital transformation, DevOps, cloud native, and cybersecurity. I’m also a former CIO. Not nearly as experienced as Mark is, but have led transformations and also implementation of DevOps as well as been a CTO, CEO of product companies. So I’ve lived on both sides of DevOps. 

    Shimel: Great. What a great panel we have today. I’m really looking forward to it. So we’re talking about DevOps at the C level. As I mentioned to you all before we started today’s show, our friend Gary Gruver wrote a book, “Leading the Transformation.” He wrote several books. One of ’em was “Leading the Transformation.” And Gary is a big proponent of what he calls the top-down approach to DevOps and digital transformation. And in Gary’s view – and I’m not saying right or wrong. In Gary’s view, you cannot have a successful digital transformation or DevOps transformation without sponsorship, support, air cover, if you will, from the C level, including the CIO or CTO, depending on the organization. CEO, et cetera. 

    Let’s start there. Is C-level support absolutely positively required to have a successful transformation? Anybody?

    [Crosstalk] 

    McCarthy: Do you mind if I go first, Alan?

    Shimel: Sure.

    McCarthy: I would actually say, my recent – I’ve done about five or six transformations and tried all sorts of ways to actually get them going. There’s always blockers on the way and it’s usually the blockers that slows the whole problem down. And the blockers either come from the ground up, from the employees or the people that run the processes today, or you get the blocker in terms of the C-level-suite people who tend to wanna own things, and it’s a big of ego that actually blocks things going that way.

    And the most recent transformation was successfully owned by the C-suite. So they drove it. They owned it. They were the stakeholders. But most of the engagement actually came from the employees, from the process owners. So we ran the whole transformation from the process owners actually owning and identifying where the transformation needs to take place. And that really made it hugely successful because you didn’t have people fearing for their own jobs. ‘Cause with digital transformation it always means or often means that there’s gonna be heads that unfortunately are lost in various areas of the – in the transformation. But mainly doing transactional-type work. But if it’s the transactional people that are running the processes, they highlight their pain points and then we work with them to actually change those pain points into something positive. 

    So, I would arguably say both from top-down, but also if you don’t do it with engagement of the people running the processes today, it won’t work.

    Settle: I’ll chime in. I think I have the same answer but I’m gonna state it in a slightly different way. I think the way the question gets asked, it sounds as if the CTO or the CIO’s gonna come down from the mountain with the DevOps tablets and then ____ employees and team members _____.  “I’ve been converted and now it’s your turn. We’re all gonna go do this together.” [Laughs]. Most of the time that doesn’t work. For one person to come in – well, take an example where a startup company here that’s been reasonably successful. Maybe they get up to a product team of, I don’t know, a generic team of 500 people or something like that. They hire a new chief product officer or a chief technology officer who says, “We’re gonna do this completely different. I have a vision.” Et cetera. Well, they’re gonna do it but that’s gonna be a slog to kinda get there.

    What I’ve seen be more successful is almost like – what’s the right term in a battle when you send the beach guy out? The beach master that’s moving people around. So you really want almost like a fifth column movement down at the grassroots level of people who are genuinely interested in exploring these ____ ways of doing business. And then I think what the C-level person adds are the methodological resources to drive scale. And so many DevOps initiatives fail because they sound interesting; they sound contemporary; people think, “Other people do it so it must be beneficial.” 

    But then after like 18 months, everybody scratches their head; “Where are the benefits? We thought this was gonna be transformational.” It’s not. The technical people are having fun. They’ve developed this new terminology, et cetera. And if you scratch below the surface, well, guess what? You’re doing DevOps in like five different ways because the little C-groups have all picked the tool they wanted and decided that they’re gonna have a daily scrum twice a week or whatever. They’ve got their own little process set up. And then people say, “Where’s the benefit? This was supposed to be transformational.” So at some point in the early stage of the journey, it’s needed to drive scale and ____ of endorsement. But I think it can almost backfire if it’s launched from the brain of Mark Settle that, “Yea, and verily, I’m gonna lead you to the promised land.”

    Shimel: Sort of a Charlton Heston beard I’m picturing on you there, Mark. Eveline, how about you?

    Oehrlich: Yeah. I actually would say it should be outcome-driven DevOps. It doesn’t really matter if it is from the C level, from the individual, from the inside-out, from the outside-in, from the top to the bottom, the bottom to the top, from the middle to the whatever. It needs to be outcome-driven. What I mean by that is: Only metrics will make us change. Just like I drive through my town here – this is a little analogy. I drive through my town. They installed one of those things where they measure the speed and if you go over 50 kmh you get a ticket. Well, my husband, even though that thing has been there for two years, my husband manages to get a ticket every three months. But what he does is he intercepts the mail and then he doesn’t tell me that he has gotten that ticket. 

    So now what I have done to stop those 15-euro tickets every two months – because if you add it up you can go for a nice dinner – I am going to go through the mail before he gets home so I see how many tickets he gets. And he gets little lines. And that metric is on the refrigerator – I should’ve brought a picture of it – and that has actually reduced how he is driving through town.

    And so if you go back to the DevOps teams and the digital transformation and you ask the individuals at C level or VP level or practitioner level, “How successful have you been or what’s the challenges around?” It’s easy to point to somebody. But data, if you have data which shows where you are and it maps to where you want to go and you share that amongst all these different individuals, there is no argument. It’s not the guy with the long beard, as Mark would come in, or it is not somebody at the lowest level who could argue with that. We could huddle around it and figure out: What do we need to do?

    So I think it’s not really about who – of course we do need some individuals who pays for it. We need some kind of a fund and budget and all of that. But I really think it’s outcome-driven rather than organizational-level-driven.

    Settle: Can I just chime in on that one, too? So I would agree 100%. And outside of maybe the CTO or CPO or IT organization, bringing evidence of improved sophistication, operational metrics around the process to almost any other C-level executive – they don’t really care. The CFO – if you show that, I don’t know, the year throughput, the story whatever – in one of my books, it’s like reading a Bible to the cat. The cat will look at you and feign interest. But it has absolutely no idea what you’re talking about. And that’s sorta what you get outside the technical functions, everybody – “But that’s your job. You figure out what needs to get done.”

    And, again to your point, it’s more of a business outcome. Like, are we actually getting customer request enhancements through in greater quantity or are we able to respond to a competitor’s new feature set faster than we did at their last result cycle? Or whatever those things are. That’s what people wanna talk about.

    McCarthy: Yeah. And – [Crosstalk]

    At the end of the day, the outcomes is aligned to the strategy of the organization. So you’ve gotta be doing a transformation for a reason. And there’s usually three or four reasons why you’re doing a transformation. It’s around the customer journey so the customer needs to improve the satisfaction. You’ve gotta costs. You’re trying to grow your revenue. And then the one that’s usually an outliner that’s become ____ at the moment is carbon emissions. So for every one of these paint points that I mentioned earlier, there should be a business case that shows measurement of success against each of those four measures. And that’s what you – bottom-up, you report at top level to the C suite to say, “This is why we’re doing it. This is the measure of success of what we’re doing it.” And even breaking some of the pain points and the business cases down to quick wins. So ones that you can be getting on with relatively quickly that free up cash that then can pay for the more strategy-type things.

    Shimel: Yeah. So I think this brings up – all three of you have touched on it. And it brings up what I think is really sort of an entry question, which is – it’s the genesis of digital transformation. Why and how does any organization decide to go through the potential pain, heartache, and change of digitally transforming, of adopting DevOps or agile? Louise, I’m pretty sure we spoke about this – was it at an Emmet Keeffe Insight IGNITE in Iceland that you were at?

    McCarthy: Yes.

    Shimel: I was there with you and I remember talking to you about this. You know, Eveline, in your day, someone like Mark might go to a Forrester conference and come back and say, “Wow, Eveline Oehrlich from Forrester just presented this presentation study on the benefits of digital transformation and DevOps adoption. And, god darn it, she described us to the T. We really need to do that here.” And maybe that worked then, right, seven years ago, ten years ago? I don’t know if that’s the genesis of digital transformation today. I think a lotta times digital transformation today does start with technical champions lower down whispering in Mark’s ear that, “If we were doing DevOps or agile or whatever, we could really make better customer experiences. We can give customers what they want. We could do it better, cheaper, faster.”

    [Crosstalk] 

    Ashley: I think we have a chasm that we have to cross, and that is: DevOps can be sort of a vanity project for the IT or the development organization, right? It can be a purely self-interest: “We’re doing what we do better.” Which is always a good thing, but at the end of the day does it move the needle for the business? You have to be able to translate that into what Eveline said was the why. Louise also said the why. But what is the real benefit we’re trying to get out of it? And when you have a purpose for doing it, now you have metrics you can put around that. Is it revenue? Is it competitiveness? Is it responsiveness to the market? Is it changing customer expectations and behaviors? What is it? That’s truly – then the development or the IT organization knows that they’re making a difference. 

    Otherwise how do you know whether you should be working on more releases per hour, per day, or you should be working on just fixing the backlog? How do you know? You don’t other than just sort of your own internal metrics. And I guess it kinda reminds me of that phrase of the – what was it? Belly-button gazing, right? You’re sorta looking at yourself and what you think’s important. But I think that connection – you have to cross that chasm, whether the business is coming to you or you have an idea of what we can do better and how it might help, and then let’s then make that connection. 

    Shimel: That’s my point. Someone like Mark – Mark, what does it take to push you over the edge and say, “God darn it, we gotta do this; we’re committed”?

    Settle: Yeah. Let me _____. One thing’s funny about this whole line of conversation is of course, in the world that I live in out here, there’s no question about doing it. It’s like: Who is the most sophisticated – [Crosstalk] or more sophisticated? So, in the war for talent, that same 500-person organization I referenced – they might look at each other and say, “Who do we know at Google or Facebook, in their engineering group? We know we should be doing this better. We’ve kind of played around with the concept. We’ve hired some lower-level people who’ve said, “You guys are just behind the times here. So we need some real leadership inserted.” So that’s the other side of the coin. In parts of the country where maybe it’s like an accepted practice, there’s almost a competition to be the most sophisticated or get the most benefit. 

    But the spark plug, the question you’ve asked – I’m thinking about some second-tier markets – and I really hate to call out specific locales, but what the hell? As a consultant, you can talk like that. So if you’re in a place like St. Louis and you’re in an organization that just has done business the same way forever, all the IT management, all the technical management has come up through the ranks kinda doing things the old-fashioned way, quarterly releases, and they don’t keep the same kinda metrics that you would in a DevOps environment, to blow a place like that up – there’d have to be some kind of competitive imperative.

    Or, you know, the white knight does show up from time to time, right? So if you think about it, sometimes when the new CPO or the CTO comes in – and I’ve experienced this in my own career – there’ll be a cause or a initiative that I promoted during my entire tenure – the new guy or gal comes in and they get it done like in a year. And I think, “What the heck happened here?” 

    There was one company where I was trying to get them off of Microsoft Dynamics, get ’em onto Salesforce. There was another company, I was trying to get production systems up into the cloud. And we did every kinda seed activity you can imagine. The cloud one, we sent people up to Redmond for some AWS instruction. We did some prototyping, et cetera. New CIO comes in and says, “We’re going to the cloud,” 12 months later like half the production systems are in the cloud. Like, “How did that happen?”

    So sometimes change at the top – which gets us back to where this kinda started – maybe that is the seminal spark plug. And especially if that person’s been brought in because there’s a broader C-level recognition that, “We’re not keeping up with the times; we need to make some kinda change.” So you have that broader support. When people start to whine, they know that the whining’s not gonna get them out of the change that’s about to come. 

    But for just self-generated change for people that’ve – then I go back to, you know, Mitch, where you said: then you can always have a vanity project which you can point to as evolutionary. Like: “We’ve got a small group. They’re putting their toe in the water. They’re doing some interesting things. So we are keeping up with the times.” But then you just don’t get the scale benefits at the end of the day. 

    Oehrlich: I think there was – just to add to something to what Mark said, as the ecosystem of our organizations has expanded, we have to think of – well, the travel industry doesn’t exist at this point in time, but think of maybe manufacturing, right? In the area where I am in, I’m in Stuttgart, we have large car manufacturers, and they’re connected to Bosch and others, and the ecosystem is rather broad. And these folks at all levels are collaborating, connecting. Not as much now with where we are, but they have exchanged thoughts and ideas, they go to events, and they learn from each other. At all the different levels. And so I think there is that – as Mark said, to some extent there is this – not really a competition, but the exchange of ideas, which has brought additional adoption of DevOps at all levels, right? 

    So if I am the C level of Bosch and I go to a genomic car-driving event and I meet the CF C level of the CF industry down in Friedrichshafen and they are telling me about, “Wow, we really improved our reliability scores and we have really punched up our cadence around the product X, Y, and Z,” I go back and I say to my team, “Hey, I just met this team over there. They’re doing something fantastic. Can we start?” It’s that spark, which to some extent happens to cross over in this ecosystem as we start to be much more connected and dependent. I think that’s one point.

    The other one is: if you look at the individuals who are today in IT, they don’t look like this anymore. I’m a Cobol, Pascal, HP 3000, JCL person. That’s when I grew up. That’s my heritage in operations. The guys and the girls today in these teams – they are completely different. They want Python. They wanna do sexy things. They wanna do fun things. They wanna show what they can do. And they’re looking for inspirations from their leaders as well, and they want to see that they can make a difference. I think that is also, from a cultural perspective, I think – of course it’s important but I think that’s also a driving force. And that’s not just the individual contributors but also the consultants and the C levels who are – I call them the flip-flop-wearing, chino-looking guys who go to the conferences, which we’re seeing them; I’m like, “Oh, I think I’m overdressed with my suit.” That’s the people who actually make DevOps happen, and they wanna have fun. They wanna do things. They don’t wanna do JCL and things like I did in a boring ops group dying of boredom.

    Ashley: I think you’re talking about a couple of things, Eveline. One is the attracting talent, right? People have more selection, economic conditions aside, more selectivity about the kind of work that they wanna do, the companies that they wanna work for. There’s also just: how do you learn to develop software? If DevOps is what you’re coming into, a way of developing software, you’re looking for organizations and you expect that approach. So I think your point is right on. It’s also the audience of the people who are gonna be the adopters or the embracers or the champions of doing this. So that all makes a big difference. The command from on high, as Mark was talking about, the tablets – there’s an expression for that: “This too shall pass,” right? That’s the reaction, usually, of those kinds of initiatives. You have to have an option. And I think you spoke to that really well.

    Shimel: Look, if you’re a Silicon Valley cool kid or you work at one of these organizations where flip-flops and jeans are the rule and you do the hair thing and all of that – I don’t do that so well anymore – that’s cool. But, Louise, you’ve done transformations at what we may think of as large, stodgy financial organizations, right? And they’re not Silicon Valley-based and they’re not a jeans and flip-flop culture. So how does it play there?

    McCarthy: Actually, funny you were talking about flip-flops, high fives and cappuccino. I worked in government actually for a little while, the tax authority, and that was a time when the government was setting up its ____ global digital authority. And everybody in the government, all of a sudden they change from suits to wearing flip-flops and high fives and cappuccinos, and it was like a world away from the starchy government.

    But, anyway, moving on to the financial services, yeah, the financial services – I’ve been lucky enough actually to do transformation in legacy financial services, and the big boys like the HSBCs, for example, which is complex. It’s like turning the Titanic around. And I’ve often written articles around: it’s like moving deck chairs around. The reason why I say that is because automation is the way forward. We talk about automation in many guises. Automation takes out people. It takes out transactional-type activities. But the legacy banks just struggle to do it. So I say it’s like moving the deck chairs around the Titanic because of the legacy system they’ve got. Transformation – they talk about it. They move things around. But nothing real and concrete actually comes out of their transformation, which is really sad. Because there’s great opportunities there in the legacy banks. 

    And on the other side of the fence, I’m working currently with a contender bank, a digital bank, which is new. It’s new. It’s fresh. It’s green. It’s almost as green as your screen there, Alan. It’s a green ____. And it’s great to be able to take the whole end-to-end customer journey and see it digitalized. And how quickly you can change and transform. And developing and changing technology with that suite, the same thing end to end, it’s just awesome to be able to see how quickly it happens. Whereas the legacy banks are still thinking about planning it, talking about it, cogitating over it, when the small guys are out with a new technology. 

    And one of the things that I’m often transforming whenever I do my transformation – it’s not transformation, it’s Christmas; it’s for life in my mindset. So it’s around continuously thinking about the innovation and it’s about encouraging these legacy banks to have innovation departments that are constantly thinking about the new technology that’s out there to take them ahead of their competitors. So like these digital banks, if the legacy banks are doing this, they’re actually seeing a way of making it happen quickly. And I think that’s the problem that we’re constantly battling: the bureaucratic slowness of moving Titanic.

    Shimel: So clearly the kind of organization you’re at determines, or will have a huge impact on this. Guys, we’re coming on the back side of our time limit here. I wanted to talk a little bit about: okay, we’ve made the decision. We are moving forward with our transformation. We are adopting DevOps and agile and these new ways. How at the sea level do we – short of coming down from the mountain with the two tablets in God’s own writing, how do we translate that to the troops? How do we effect the organization? That this isn’t some passing fancy of the CIO and it’s not gonna pass in the next quarter. This is really the way we’re doing it. How do you make that change down the ranks, get people adopting as champions and being successful with it? Mark?

    Settle: You know, it’s not unlike an initiative around security. When you talk about cultural change within an organization, I think leaders don’t always appreciate what a huge impact they have on the people that they lead. You know, people take cues from the way you use your time, the things that you show interest in, things you follow up on. Your time management sends tons of signals to the organization. And some of the operational metrics that I poo-pooed before as being of no interest whatsoever to people outside the technical areas are a great way to kind of keep score. You go back to what Eveline said: If there’s a sense we’re making progress, some of those ____ celebrations can be really important.

    I’ll just leave you with a thought. I worked with a guys several years ago who used to say, “What interests my boss fascinates me.” As long as there’s some sustained interest – and to go back to, Alan, what you said before: I can just come back from the Forrester meeting all jazzed up, and then two months later I go to a Gartner meeting and now I’m on a whole different tangent. Now I think it’s automation; we gotta get RP robots in here. That’s gonna blow the business up. And then people in the trenches are like, “This too shall pass. He’ll go to another meeting. But I’m not gonna get my –

    [Crosstalk] 

    Shimel: Come back with some other toy, yeah. 

    [Crosstalk] 

    Settle: “He’s so crazy.”

    Shimel: Yeah. I used to feel it was whatever was the last book I read. That was the next greatest thing to me, right? ‘Cause I just read that book. But, Eveline, fundamentally – and this is something the DevOps Institute is deeply ingrained in – it also becomes a question of: how do we upskill our workforce? How do we prepare – do we just go out and hire new people? That’s hard. Do we upskill our existing people for this? At the C level, how do we effect that?

    Oehrlich: Yeah. So, from our research at the DevOps Institute, we know that most organizations are actually preferring to leverage their existing resources to train them and to upskill them. Now, upskilling of course has its challenges because you don’t just upskill around processes of learning a new way of doing continuous delivery, or it’s not just about upskilling new technical skills. It’s also about human skills. That’s I think the challenge. A lot of organizations are biting themselves into that – or pushing themselves, or actually locking themselves into the corner. They think, “Yeah, let’s give them AWS training. Let’s let them understand what the latest DevOps platform is and give them some language skills around whatever the latest hotshot technology programming language is.” 

    But it’s also soft skills or human skills which are necessary. People need to understand how to work empathetic, how to collaborate, how to connect, how to cross functional borders, how to understand when a security individual tells me something. So having skills around these different categories is important. And there is investment needed. We see that, unfortunately, 7% of survey participants we had last year said that they have no idea what their upskilling programs are. We know 37% of these individuals – a very large sample size of almost 1,200 – said that, “We don’t have a program in upskilling.” And the rest of them either are planning one or have one. So that’s really unfortunately poor and not enough. So, anybody listening in, get ready to upskill your people. Start thinking about training. Start thinking about exchanging knowledge and allowing them to learn. Give time.

    I, for myself – and we’re doing that at the DevOps Institute a little more, and our CEO does that a little as well. I call Friday my learning day. And it doesn’t matter what happens. Unless the CEO wants me there, Friday is my learning day. I learn French. I learn about design thinking. And I’m learning about metrics. That’s it. And we all have to do that. It’s very important. 

    Shimel: Agreed. Louise, you go in as a consultant. In terms of the skill level of the workforce, do you try to upskill them? Do you supplement it with fresh talent? It’s hard getting fresh talent in. Mark, you know in the Valley they cut each other’s throats for this. How do you do that?

    McCarthy: It’s an interesting thing because you’re trying to fly an aircraft while changing the engine in some cases. And the same people _____ transform are the same people that need to drive the aircraft. And also if you call in too much fresh talent, then you would probably put the noise in the joint of the people that are supposed to be helping you run the process anyway. 

    So the way I’ve done it is I’ve gone in and we’ve identified some highly skilled people that know the processes really well and then supplement them with some more transactional process mappers and people like that. So that those people that run the processes can also see things like: how do they do the process mapping and how do they identify the paint points? How do they convert it into business cases? How do they use it and then convert it into technology?

    So on that journey, the people that are running their processes are also being upskilled at the same time into continuous improvement and transformation. But I’d say that there’s also – it’s not about upskilling necessarily on all sorts of things. Because as technology’s changing, there’s less the need for upskilling because a lot of technology is self-serve-type technology now. A lot of the RPA touring now. People can do it like they learn Excel, like they learn Word and things like that. so the upskilling like it used to be, about spending months and months programming and that type of thing – there’s less the need for that. It’s more about the upskilling in terms of continuous improvement. And it’s a cultural change, I think somebody mentioned earlier. So it’s going in and using the resources that’re there, upskilling those people, and slightly supplementing them and doing hands-on job training.

    Shimel: Excellent. Mark, Mitchell, I’m gonna give you each a chance to kinda close it out here, and then I think we’re about outta time. Mark, final thoughts?

    Settle: Let me just make a final comment along the lines of this last topic. I’ve gone through many of these reskilling things, and seeding that group with new talent I think is essential. I mean, if somebody came into me and said, “We’re gonna go to DevOps and you can have consultant money; the consultants will come in; they’ll be here 90 days, 120 days” – this is an acquired skill. It’s almost an art form at its finest. And the devil is in the details. And the day the consultants leave, everybody’s left to their own devices, and it’d be just like saying, “Let’s just shut down the data center and move everything in the data center up on AWS, and we’ll get some AWS consulting in here, and then they’ll leave after 90 days, and you guys run all the production systems up there in that whole new environment after 90 days of familiarization.” I don’t think too many companies would take that kind of a risk.

    So I think people get so carried away with thinking that reskilling can be effective, that people will come to embrace it. And, again, I hate to say this, but in my personal experience, if you reskill a population of people, 20% will be superstars, 20% won’t get it, and 60% will be good enough. But if one of the 60% left, you’d recruit somebody in with a higher skill level than the person that left. So they make forward progress. I’m not denigrating people’s commitment to new things. But you’ve gotta bring in that fresh talent that’s been there and done that. They know what it’s supposed to look like, right? And they can look around a corner and they can see the big fuzzy hole in the road that we’re all gonna fall into here in the next two months. 

    So that’s my thing.

    Shimel: Mitchell, you wanna bring it home?

    Ashley: Yeah. I’d like to just wrap with the human element, but maybe from a little different perspective. You know, people react to change in different ways. Your advocates – great, they’re all about it. Your resisters – love them ’cause you can actually work on that. You can help. You can help bring them along. It’s that passive unspoken middle ground, the folks that’re waiting to see: “Before I commit myself – I’m not gonna put myself, my job, my career at risk for this next thing. I don’t know if I can do it.” And the idea of bringing people in – I think one of the main purposes is to show the team, A, it can be done, and, B, they can learn it. So it isn’t: bring the consultants in for 30 days, hand over what they did, and now everybody goes, “Now what do I do?” Right? 

    So I think if you can de-risk, address the fear of what this means, that: “You’re gonna be able to do it and we’re gonna stick with you to help you get there, help everybody get there. And if there’s some folks that choose not to go along the journey, that’s okay too. But we’re all in this together.” I think you’ve gotta address the human element from a very personal: how does each person feel about this and whether they’re signed on to do it? And that’s gonna guide your success. That’s been my experience. 

    Shimel: Absolutely. Well, guys, we’re about outta time. Mark, Eveline, Louise, and of course Mitchell, thanks for joining us on this episode of DevOps Unbound. Many thanks to our friends at Tricentis for their sponsorship. Until next time, this is Alan Shimel for DevOps Unbound. Be well, be safe, and we’ll see you soon. Bye-bye.

  • EP 5: Outsourcing DevOps, Oxymoron or Truth

    EP 5: Outsourcing DevOps, Oxymoron or Truth

    Can you outsource DevOps? And if you can, what are the keys to doing it successfully? In the fifth episode of DevOps Unbound streaming broadcast on TechStrong TV and devopsy.kinsta.cloud’s sister site Digital Anarchist, Mitchell Ashley of ASG and Alan Shimel are joined by Ming Gong of UST Global, Chris Rolls of TTC and Robina Laughlin of Guardian Life for a discussion on outsourcing DevOps.

    The video is immediately below, followed by the transcript of the conversation. Enjoy!

    Transcript

    Alan Shimel: Hey, everyone. I’m Alan Shimel, and welcome to another episode of DevOps Unbound. DevOps Unbound is a series, sponsored by our friends at Tricentis, that explores different topics around DevOps every other week, as well as having a monthly roundtable open to the public. Today’s episode is “Outsourcing DevOps: Oxymoron or Truth?” I’m joined, as usually, by my co-host, Mitchell Ashley, CEO, founder of Accelerated Strategies. Mitchell, welcome. Thanks for coming on.

    Mitch Ashley: It’s always awesome to be here. I’m excited about our guest today.

    Shimel: So am I. Let me introduce you to our guests. We have Robina. And, Robina, I’m gonna ask you to give your full name, title, company, background. And we’re gonna ask you to kick it off.

    Robina Laughlin: Sure. Hi. I’m happy to be here. Thank you. My name’s Robina Laughlin, I work for Guardian Life insurance. Actually Guardian Life and I have been working in the quality assurance space now for about 25 years. I’ve been working for Guardian for eight years. We have a great enterprise quality assurance journey. Most recently my department, my quality assurance department’s been working with integration into a DevOps model. So we’re starting that journey. We started about a year ago. And really happy to be part of the conversation.

    Shimel: Thank you, and thanks for joining us, Robina. Secondly, I’m gonna introduce my friend, Ming Gong. Ming, a little background?

    Ming Gong: Hey, Alan. How are you? It’s always good to be here. My name is Ming Gong and I work for UST Global, I’m vice president. I run a practice called Digital Agility Platform Solutions. So what we do is we provide all kinds of services and even product to our enterprise customers, things such as DevOps transformation, DevSecOps, digital, cloud transformation, as well as latency modelization. So, we have tons of battle scars as we’re implementing DevOps for our customers.

    Shimel: Absolutely. And then, last but certainly not least, Chris?

    Chris Rolls: Hi, nice to meet everyone. So my name’s Chris Rolls. I’m from a company called TTC. I’m CEO of Americas. And what we do is we help organizations with quality engineering, continuous testing and also Agile and DevOps transformation. So really happy to be here and excited to hear what everyone else has to say.

    Shimel: Absolutely. So, guys, when I started – so we launched devopsy.kinsta.cloud in March 2014. Working on it all through the second half of 2013. At that time it was sorta dogma in DevOps that DevOps wasn’t about the tools; DevOps was about people; DevOps was about culture. And that therefore, to be successful in your DevOps journey, outsourcing was a no-no. You couldn’t be successful and outsource your DevOps because it would destroy – you never got to the nitty-gritty of the culture. 

    Now, that was seven, eight years ago. A lot has changed. I think we’ve seen some very successful – the world is full of DevOps consultants, large, small and in between, who are helping organizations along their DevOps journey. So I think we have kinda moved beyond the dogma. But have we moved to truth? Can you successfully outsource DevOps? And if you can, what are the keys to doing it successfully? And I’m gonna throw that out to our panel today, and we’re gonna start that as our discussion. Ming, not to pick on you, but you already mentioned you have a lotta scars to prove it.

    Gong: Absolutely [laughs].

    Shimel: Tell us a little bit about your journey or UST’s journey in this space.

    Gong: Yeah. I think you mentioned a couple of things that’s really important, which is, ultimately, I think to do DevOps correctly the entire delivery team needs to live and breathe the DevOps – not only the automation, the tool set, but also the processes as well as how you do things or the whole mindset thing. So that’s the absolutely ultimate goal. I think even over the past few years, even though all the companies all moving towards DevOps, but they are still having a lotta challenges in terms how to take some isolated success in certain areas, trying to cascade that throughout the entire organization. And I think this is where, when we talk about, “Hey, is outsourcing a myth or a reality?” I would say it’s actually somewhere in between. 

    Because it really depends on where the continuum – when I think about DevOps, I think about DevOps continuum, ___ maturity, where they are. For the company who’s really mature, they are less likely to benefit from outsourcing before the folks who’s just starting the journey or middle of the journey – they definitely can use some help. And not only outsourcing in general but also what part of DevOps to outsource as well. So typically when I work with enterprise customers, they have a centralized organization, like some kind of DevOps COE. But they also have each individual team that needs to be enabled. So where we found there tends to be more success is when we help the COE to – infuse them with the DevOps expertise and help them kinda build up the practice around DevOps.

    So I definitely think it’s somewhere in between.

    Shimel: Fair. Chris, your organization is similar to Ming’s in that you are helping organizations with their transformation. Has your experience been similar, different?

    Rolls: Yeah. I think I’m not gonna shock the world by being a consultancy who sees consultants can help with DevOps transformation, right? I would be outta business if I thought that was the case.

    But if I was to answer your direct question, can you outsource DevOps? I would say no. Because DevOps is about a cultural change within the organization as well as the technical practices. Now, similar to what Ming is saying, it’s sort of in the middle because outsourcing and consultancies and other vendors can be a part of the solution. They can make some things more challenging in certain ways because you are introducing certain barriers, as in contractual sort of challenges around it. But it definitely can be part of it and it definitely can help, particularly when organizations are trying to figure out how to do things better. 

    Shimel: Fair. So, Robina, you look at this sort of 180 degrees different than Ming and Chris do, right? You’re not providing consulting to organizations. You are the organization. What’s your view on this?

    Laughlin: Yeah, thanks for having me. This is a really interesting conversation. Some of my thoughts around this is: I think the important thing to understand is: what’s your driver to DevOps? Why are you moving to that model? Why is that model gonna be important to you as an organization or as an enterprise? And when you start to answer that question, you get to different models. For us, we adopted SAFe. We started that journey two or three years ago. So DevOps was not the first thing we tried to conquer out of that transformation. It’s on the tail end of it. And it was always on the strategic road map. However, what we found is that it grew organically based on the improvements from adoption of SAFe and agile. So for the teams to get to the velocity that they wanted to do, it became a necessity as opposed to an aspirational goal, right?

    So for us when it became that driver to success, it took on a whole different model. And then when we started figuring out how do we wanna do this with our partners, the vendors that we work with, one of the things that we always hold true to in Guardian is that frameworks, guardrails, models our Guardian culture, and we developed those. We developed them in conjunction with our partners. We’ll seek for collaboration. We’ll seek for guidance. But the model has to come back to fit our culture and how our folks work.

    And then once we have the guardrails in place and the operating model, inclusion of an outsourcing model is very successful, I find. But I speak from a QA perspective, and I’ve been on an outsourcing model now for 15 years, right? So I always kinda take the same approach to things in that if you have the operating, the guardrails, and people know what they need and why they’re doing it then outsourcing is a good solution. But you have to have a strong backbone for the company that you’re working for and with to be able to represent that model and the culture. 

    Shimel: Mitch – oh, Ming, go ahead? Whoever, Chris.

    Rolls: Oh, sorry. I think just to drill into that as well, Robina mentioned you’ve gotta understand your drivers for DevOps; what are you actually trying to achieve? I think that a lot of times organizations – they want to do DevOps because that’s what the conferences and the experts say they should do. But also you need to understand: what’s your driver for outsourcing or engaging partners and other vendors, right? So if it’s a cost-saving mechanism, which often it is in this economic climate, is something that people are looking at, right? That can be one component. That can be one reason for outsourcing. You could also be outsourcing to get additional expertise that you don’t have internally. You could be outsourcing ’cause you’re scaling up with a whole another set of products and there are sort of HR reasons for wanting to do that. But you need to understand those drivers. 

    And I think another thing that Robina said crucially which I see organizations get wrong is: the organization who’s – the business, the incline for us needs to own the cultural change and needs to own the methodology. I come back to: no, you cannot outsource DevOps. You can’t buy that on a platter. You have to invest. You have to make the changes yourself as well.

    Laughlin: Yeah. There’s some parallels to that conversation, right? ‘Cause a lot time ago this was the conversation for quality assurance. Like: outsource it; there’s an easy button; all your problems will be solved. I think that, from the experience of that, for me there was never an easy button. It was a lotta work and it was a big partnership. But what we did was, through that partnership, we started bringing in technology that my team hadn’t had a lot of exposure to so our options grew, and I found that there were some easy buttons along the way to build, to run tests against that build. So we’re moving into a model now where the assets of quality assurance can be augmenting what is your DevOps model. And that model has to work for your company and it has to be part of your culture. It is not something that just kinda develop out of a box.

    Ashley: We probably need some precision around the term “outsourcing” too. So I think in this context – 

    Laughlin: That’s a good idea [laughs].

    Ashley: – we’re not talking about externalizing it. In other words, put it in a box, ship it somewhere, have someone else do it; give it to us when it’s done. Right? Because we’re transforming the organization. I think it can happen a couple of ways. It can happen early in the journey; I think it also can happen – organizations typically get stuck at some point where we’ve gotten 2, 3 teams there but man-scaling it to a 5,000 or 10,000-person IT organization – that’s hard. It’s easy to do it on a startup basis.

    So everything to me is always driven by what the company is about, what its DNA is like. Some companies are very data-drive: We don’t make a decision unless it’s got a graph attached to it or a financial analysis attached to it. Or tied to a strategy. Or whatever it is. And different companies often taken on the personality of the founders if it’s a younger company. But it gets established with it. And if you don’t have that figured out and aligned with how you’re implementing anything – agile, DevOps, SAFe, whatever it might be – you either go against the flow and fight it all the way and fail multiple times and never succeed or you figure out what fits into the flow and the momentum, the DNA of the organization. 

    That takes knowing people. It takes knowing the organization. It takes commitment by people in the company to do it. So it’s not an outsourced give away the problem. It’s a: I need help because I need expertise, because I’m stuck, because there’s other – we don’t know what we don’t know. And we’re looking to get smart from other people. And we want you to leave someday and help us operate on our own. Maybe help us with a different problem someday. But that’s kind of our goal as an organization.

    Gong: Yeah. Mitch, I fully agree with that. And we certainly have – a couple of points you point out is pretty interesting. One is the challenge that we seeing for large enterprise customers: they usually have problem with cascading kinda DevOps excellence across the organization, right? But there’re so many hurdles, I would say. One of them is organization siloes. We have seen so many times where you have one division, usually on the digital side, front end – they have great success because technology stacks tend to be more modern so it’s easier to get on the DevOps train. But then once you start trying to cascade to a legacy side, it just doesn’t work. Either because they don’t share very well because there’s organization siloes, or because the technology stack they develop doesn’t really work on the other side.

    So where we see, again – I know you have term about outsourcing can mean many different things. But where we see a lot of support or at least success is when we help kind of the organization where they have a COE, where they establish standards – and I think Robina kind of mentioned this too. It’s very important for company to really establish their true North, the compass, right? The guardrails and things like that. But it’s also important to not have a very heavy central organization either to trying to drive DevOps. Because then you’re missing out on all the distributed innovation happening on the ground level so you can never respond fast enough. 

    So this is why when we created our model, we usually have a team, or a very small team, help with the COE side of it to help them kinda develop their whole community, the culture, things like that. But then we have very nimble – we call it deep pod. It’s like a five-member crew. They have – consists of DevOps architect and couple engineers. And what they do is they will be kinda parachuted into an area within the enterprise where they need a lotta help or the application that they using is very critical to the business. Will drop in there. Not only helping with engineering, figure out the tech stacks and figure out the DevOps – all the nuances of it. But we also do a lot of coaching to make sure we can train the team to be self-reliant. Once they are, we lift the team up then we drop the deep pod into the next area where they need help. So this is kind of the hybrid model is where we find more success. 

    Ashley: I’m really curious: Who typically brings in your firm, Ming, your firm, Chris? Maybe, Robina, who brought in someone to bring in help with DevOps. Was that at a very high level? Is it a development team level? I’m thinking larger organizations here. What’s the –

    [Crosstalk] 

    Gong: I think Chris and I probably will share the same answer, which is: all of the above. We have a large DevOps engagement to where the CIO invites in. And we operate starting from the strategy level all the way down to the individual team level. But then we also have, through relationships or whatever case might be, where we insert ourselves into a particular team to help and then grow from there. 

    Rolls: Yeah. Exactly the same. And if it’s okay I wanna go back to one thing you guys said before, which is having a bit of precision around what we mean by outsourcing. Because I think when I see this topic, I jump to full, functional outsourcing of QA or dev or opportunities. But the reality is: outsourcing also exists on a spectrum. 

    You know, when you hire a maid to clean your house or to service your car or anything like that, you are outsourcing that function of your personal life. And it’s the same with software development, right? So there’s the really far down this end where it’s just you have a consultant who’s embedded in a project team, and then there’s all the way down to the far end where you do that full-scale outsourcing of a function or a department. 

    And what I want to be clear on is: the further you get along that continuum, the harder it is. You have to be far more careful about it. And so that’s something that’s really important. And to go back to the question that was just asked: completely the same. Sometimes – and you’re very happy when the CIO or the CEO says, “Come in and help me do this transformation across the organization.” Sometimes it is a QA or dev manager has a specific problem that they want to solve. But I’d also be really interested to hear Robina’s thoughts.

    Laughlin: So how did we bring – I’m sorry. Can we –?

    Ashley: What level did you bring? Was it the CIO brought in somebody to help you with the ____ or was it on a QA development team?

    [Crosstalk] 

    Laughlin: Oh, sure.

    Ashley: How did you start down the getting external help, outsourcing help?

    Laughlin: Yeah. So this is a little bit of a parallel run to a DevOps model. So from a QA perspective, what we did was we decided to centralize our enterprise quality assurance organization. And when we did that, certainly we got economies of scale, but I needed a partner or a vendor that would come and work with me. And when I say partner, I truly mean it. Like we have team meetings. They’re all folks that work for me. I don’t distinguish. So you have to be able to have that relationship I think to be able to get success out of outsourcing, if you wanna call it that. Because it’s really partner shipping, in my mind.

    So that was the journey that we took. And that’s been underway now for almost eight years. So we have an incredible wealth of assets behind us. And I started stopping and looking at what my partners were doing on the other side of building and deploying, and how are they verifying that building? We’ve been moving this shift-left journey of discovery of quality issues for a long time now, and we’re at the point where we’re in the build stage. And I’m like, “Well, we have great assets that could help verify that a build’s gonna work. What’s the next solution to that?”

    So I reached out to my Cognizant folks under my QA umbrella and said, “Hey, if we were to think about extending our assets use, what would we do?” And they were like, “Turn to your DevOps team. Turn to your build and deployment team. Let’s understand what they’re using. They’re using Jenkins. They’re using Bitbucket, example for us. So when we started looking at being able to scale our assets and use them across the enterprise, we built them in Jenkins. We built our actual Selenium code in Bitbucket. So now we have the hooks there and we can – as these teams start to catch up or we start to catch up and we meet in the middle, we then have a problem we’re trying to solve. We are getting builds. They are broken, or when they pass, there’s quality issues. Can we discover them through automation? So that’s the easy button.

    And in this case I actually do have the easy button. I have this regression suite. I can slim it down to a smoke test or something, and say, “If we can deploy this and do all of this then, yes, we can get those results.” And then the next phase of it is accountability of teams of what they’re gonna do with those results.

    So none of that is technical. That’s all cultural. Except for the hooks in what we built. So that’s kinda been our journey and that’s where I’m looking to go strategically.

    Shimel: Excellent. So, guys, I want to bring this down or – we touched on it already but I wanna clarify it. You know, Ming and Chris, you’re in a unique position in that you guys get to see dozens of organizations and how they approach this problem. Where, Robina, your view is Guardian-based, right? This is what you guys have done at Guardian.

    Here at devopsy.kinsta.cloud I’m also – I’m in a catbird seat in that I get to speak to many people like Ming and Chris, but I also get to speak to many people like Robina. I get to speak to people like Mitchell. I literally get hundreds of views on this. And I recognize patterns. And what do I do? What’s my superpower, superhero power? I’m good at recognizing patterns. I guess I’m a machine learner. But anyway, there usually is a pattern along DevOps adoption. And it’s similar to what Robina mentioned, which is – when I first launched devopsy.kinsta.cloud, our tagline was “DevOps picks up where agile leaves off.” Right?

    And, yeah, because what happened was people were moving the agile development processes probably going on 20 years now. Agile’s been around 20 years. And it was great. It makes you feel old. I’m sorry, Robina. But, yeah, it’s 20 years [laughs]. Don’t feel bad. I watched this “Halt and Catch Fire” about the birth of the PC industry. Yes, that’s what it is. Einstein’s theory of relativity [laughs]. 

    Laughlin: I remember my agile training with Ken. I can’t imagine 20 years –

    Shimel: Yeah. Ken, who now of course is Scrum.org, right? Versus Scrum – the other one. Not here to get into that one. That’s another rat’s nest.

    Gong: Different podcast [laughs]. 

    Shimel: Yeah. But the thing is: the normal course, if you will, is: yeah, we do some agile. Whether it’s Scrum or SAFe or whatever we’re seeing out there, scale. We wanna start getting into some lean IT stuff. And of course when you start marrying agile and lean, it’s DevOps, right? That’s kinda what DevOps is. And now we’re gonna get into CI/CD pipelines. And of course it’s grown since then. We’ve added SRE on. Continuous testing has become huge. Right? It’s a huge piece of this. So we’ve seen the sprawl, the urban sprawl of DevOps and agile over the last 20 years. Along with it, I think it’s become all but impossible to do at a large organizational scale, at a large enterprise scale, without some outside help. 

    I think we’ve recognized the enemy. It’s us. We’ve created the need in our large organizations, the way we go about adopting these things, that we can’t do it without outside help. 

    Laughlin: That’s very true, Alan. I think that’s why you really need the outside help and you need to go to the experts. Because no one size fits all. No one tool solves everything. That’s how I got involved with Tricentis: I went out really early looking for a vendor that would grow with me and was on the same aspirational journey that I was, right? So that’s where I think it really helps in terms of consulting. You need to pick the partner that’s gonna work with you and grow with you. And sees you for your uniqueness, not an industry standard.

    Gong: That’s right.

    Shimel: Chris, Ming? 

    Rolls: I think you can’t take a single ___ of technical practices or cultural adoption and apply it to every single organization. So that point, Robina, about making sure that you tailor it for the organizations that you’re working with – or even within an organization, the different departments, the different products that you’re working with, right? There’s a different sort of cultural mode within the digital section versus the enterprise technology section, right? So that’s really important. 

    And I think that also comes to a thing that I see that often people get wrong when they do outsourcing is that they don’t align the incentives properly. Because ____, we all have different incentives. Even, Robina, if I was partnering with you and we want to work as really good partners, then I have a slightly different set of incentives to grow my company as Guardian does, right? And so we have to find ways to align those incentives. Otherwise you will create a cultural conflict which prevents you from really going as fast as you can. So that’s just something that I see often people get wrong about moving to DevOps, because they have to use outsourcing in particular, engaging firms to help them with that.

    Gong: I wanna go back to the point Alan was talking about in terms of the massive talent shortage in industry. And it’s not just DevOps. It’s cloud, everything else, right? Just in general I think we all wish there’s more qualified folks who has those technical skills. And I think that’s one of the reason why a lot of our customers want some help from us. Because they simply cannot find enough talent out there that not only knows the DevOps technology but also has the ability to keep up with a crazy changing industry, right? I mean, you see a massive change even within the last couple years where used to be all the siloed best-in-breed product like Jenkins or whatever else, and then artifactory, whatever. 

    But now you see a trend where industry’s moving towards more of a kinda end to end all in one type of tools, right? For example, you have the Azure DevOps, GitLab, and the whole – they start offering the whole suite of things. Because they recognize the massive talent short. You can’t take care of the problem until you can also solve the problem on technology side as well. So that’s kind of approach that we’re taking as well, where not only we have on people side we have our deep pods kind of coaching the team so we can get lots and lots of teams to train up to be self-reliant. But on the other side we also develop on platform to kind of try to extract all the complexity of DevOps from the user so the user doesn’t have to be an expert. So we call it democratizing DevOps for everyone, right?

    So I think for a company to be successful they need to kinda take approach of kinda both people and the tools combination. 

    [Crosstalk] 

    Ashley: ___ kinda just share a personal story in my additional adoption of DevOps when I was a CIO at a company. And it was initiated by me ’cause actually Alan had reached out to me and said, “Hey, Mitchell, there’s this thing called DevOps. You gotta go read about.” I’m like, “Okay, what is it? I’ll go figure it out.” I got hooked onto it.

    But the rest of the team hadn’t really caught fire yet of getting onto DevOps. And so as a leader of an organization, it’s tough to say, “Okay, I want us to go this direction; I think this would really be helpful for us” when the team’s not there yet. And really understanding what it’s gonna take to get the organization going and get behind it and how to be successful at it. This was earlier, so you reach out more to individuals that’ve started to build some brand and some experience in doing things like DevOps.

    Today I would go to a different kind of a team to say, “Here’s where we are. Here’s the projects that we have going on. Here’s kinda what we’re being asked to do,” right? I think every – maybe not true, but it seems like most IT organizations are always being asked to transform some way, somehow. And sometimes pretty radically. And if you can sort of set where we’re headed and tie it to the why, as you talked about, Robina, the why for the business though, not for IT, that seemed to me to be the biggest thing that everybody could rally around. Not that it was DevOps or agile or it was this. It was: “We wanna go after this market. And our ability to get there is really constrained today. And let’s figure out some ways we can go after that.” And that tended to rally around.

    So I think today – I guess my point is: Today we’re at a point where we can hire more expertise. And we wanna de-risk our journey and learn from others. We don’t have to figure it all out ourselves and be the smartest person in the room. Certainly I don’t. And that’s a great environment to be able to bring in help.

    Shimel: Robina, I’d like to throw out – there was a time when we used to look at quote/unquote “outsourcing” and consultants, and one of the terms that was thrown around was “body shop,” right? Like, “Bring in some bodies. I’m gonna rent some bodies.” I remember when Mitchell and I were at StillSecure. We’d go down to – we had a big federal practice, and we’d go to a federal facility, whether it’s a lab or a knock or what have you. Eighty percent of the people there were not federal employees. They worked for Grumman Northrop or SAIC – take your pick of the beltway bandits. But it was all body shop. And when you’d speak to the salespeople at these consultants, you’d say, “How’s business?” “I got 50 people placed.” Not what the mission was, what the tools were. They judged their success by how many people they had placed.

    I like to think – and maybe I’m naïve; Robina, I’m gonna ask you – that we don’t judge the success of our DevOps outsourcing by how many bodies I’ve got buried at a given location. ‘Cause I think that’s a terrible metric to determine the success of a transformation.

    Laughlin: Yeah. That’s a great observation, Alan. You just kinda gave me shivers when you talked about number of bodies. I remember those days. They’re painful to look back on, honestly. There was a time when you needed an army of folks to do things and I don’t necessarily think that’s the case now. For me, our journey was: I needed a partner and I needed someone that was gonna come here and work with me. And through that partnership I also needed to know that I was gonna have a 24-7 shop, and that’s gonna necessitate overlap on both sides, right? Your onshore and your offshore. So I don’t think you can ever just kinda set it, forget it, and throw it away to an offshore team. That’s just not how it works.

    And I think the other piece of it is: at the very source of it, you have to remember that these are human beings. They have families. They have lives. They wanna do good work just as much as we wanna do good work. And the way that they’re gonna feel that contribution is being part of the team. And the way they’re gonna feel that sense of that is by being present. And we actually flipped the dynamics. So we’re no longer a headcount shop. We’re an outcome shop. So I measure the success of my organization by the outcome of our testing. And for me, with my partner, if they do it with 2 people or 200, that’s their discretion. So I don’t have to get into any more of these conversations of: “We need two more bodies here. We need eight more bodies there. I’m anticipating 12 bodies.” That just turns into I think an empty use of really valuable strategic time that you have with your partner. And you should be using it a little bit more productively, right? 

    So that’s how I flipped that dynamic. And I’d be very curious to see how Mitch and Ming feel about it. And Chris.

    Ashley: Well, my first reaction was I thought you were gonna talk about “Sopranos” or something. A whole different kind of body [laughing].

    Shimel: Bada bing.

    [Laughter] 

    Ashley: You know, I really like how Robina described it. Because it isn’t about budget size and all of those kind of backwards metrics. And I’m sure they’re still used today. To me that’s a measure of how aligned you are with the business. If you’ve shed the financial size, the IT-only-centric metrics to “What are we making an impact?” – there’re a lot of ways we can do a digital transformation project. We could get the contact list services let’s say. Something very relevant today. And it doesn’t have to be with hiring 50 more people ’cause we’re probably never gonna find 50 people to hire anyway. So we’ve gotta find other ways to do it. 

    But there’s also – there are times where I need these people to fill these roles. And I’m sure the body shop approach still applies in some situations. I doubt it on strategic projects though. That would be my supposition.

    Shimel: Chris and Ming, I’d like to hear from you guys on it though. Because you’re on the other side of the equation here. Chris?

    Rolls: I hate the term “body shopping.” It’s a terrible, terrible term. And I talk to the team and I say, “We have to have stamped on our forehead, ‘We are not a body shop.’” Because if you’re going in there and your goal as a account manager is to get 50 people on an engagement, you’re not thinking about what that organization needs. You’re not thinking about what the business outcomes are. You’re just thinking, “I can make $10.00, $15.00,” whatever how many dollars it is off each person, “and what’s my commission for that?” That’s a terrible way to think about it. And what’s more, it shows an outdated way of thinking about the people who are going to do this work. People, process, technology – people, in my mind, being the most important part. 

    If you’re thinking of them and you’re calling them “resources,” which sometimes we all slip into, or you’re calling them “bodies” – that’s not just a warm body in a seat typing some code or testing some software or monitoring the systems. They’re people who have skills who are thinking about things who are trying to do the best work they can to deliver outcomes for the company. And so I hate that term “body shop.” I hope that no one associates that with me and my company. And I think it’s a terrible way to think about delivering software.

    Gong: Yeah. I definitely second that. I mean, what Robina just articulated pretty much echoes what pretty much all of our enterprise customers have said. They should absolutely transition from where it’s just TNM type of model before now to it’s all about outcome-based. And that’s what we prefer as well. To Robina’s point, why the customer should care how we deliver it as long the outcome is what they want, right? 

    We actually created a digital agility transformation manifesto [laughs] in honor of agile manifesto. And one of the top one is actually called “Value over volume,” which is exactly what, Alan, you just talked about in terms of, hey, you should not be measuring success with transformation by the volume of things got done. But it’s more about the value, right? So in this case, instead of measuring, for example, how many DevOps ____ did we create – that’s not important. What’s important is: how much faster are we able to help the team to deliver software to the production faster? What’s the frequency increase? So those things are what matters. So that’s what we absolutely focus on.

    Shimel: Excellent. Guys, we’ve got maybe seven or eight minutes and there’s one area we haven’t hit on yet that we’d be kinda negligent if we didn’t hit on it, and that is: what effect has COVID had on all of this? On one level, we could say, “Well, look, everyone’s looking remotely anyway. What difference does it make if they’re an employee or an outsourcer? We’re all remote. We’re all equal in that regard.” The other way is: “How do I graft these people into our culture? How do we make them part of the team when we’ve never shook hands in person, when the only way I ever see you is on a “Brady Bunch“ Zoom window here and you take the top left?” Right? “Can we really integrate in just remote-only settings?”

    Ming, Chris, you guys deal with it. You’re dealing with it over and over again. Robina, you are too. Right? Everyone’s remote. How has COVID helped, hurt, hindered, accelerated – how’s it affected this?

    Rolls: So, I think one thing is that if we asked people five years ago, “How do you do agile? How do you do DevOps?” you’d say, “Everyone has to be in the same room. They have to be collocated. You’ve gotta have stickies up on the wall.” 

    Shimel: Chris is kinda sticking on us here. Okay. Go ahead, Chris, I’m sorry. You kinda hung on us. We got stickies on the wall.

    Rolls: Yeah. So I was saying in the past people would say, “You have to have everyone in the same room, stickies on the wall, and that’s the only way you can do agile and DevOps.” And I think one thing that has been good with COVID is that it has dissuaded us of that illusion that that is the only way to do things because we have been forced to do it differently. That being said, it is so much harder to create culture, whether it’s in-house or whether it’s outsourced, when you don’t have that face-to-face collaboration. There’s only so many times people can do a virtual happy hour and still really get into it. So you have to be – I’m sure first time everyone’s like, “We’re having five happy hours a week. I’ve got my bottle right next to me.” And you’re two months in and you’re saying, “Geez, I cannot do this anymore. I just wanna go to bed or watch “Sopranos,” right? 

    But I think that we really need to focus on building that culture and come up with creative ways to create connections between people. 

    Shimel: Agreed. Ming? 

    Gong: Well, let me see. Hold on. Give me a sec. 

    Shimel: Okay [laughs]. You going to your happy hour background?

    Gong: Absolutely.

    [Laughter] 

    What you’re seeing here is the – my family and I, we took a hike recently to a Malibu beach, and I took a 30-second video of Malibu and use that as my background. So this is one of the things that I started asking my team to do: trying to personalize this kinda virtual experience. I’m a absolutely people person. So I miss the in-person bonding dearly. But in lieu of that, we basically, every time we have team meetings with our customers or with our own team, we pretty much strongly encourage everyone to get on the video so at least we can see each other. But to Chris’ point, there’s always a silver lining to everything. Because the COVID certainly forced or speed up a lotta things that was gonna happen anyways. So, to that, I think it’s a positive thing. Robina? I’d love to hear your thoughts [laughs]. 

    Laughlin: Sure. What a year we’re all having, huh? Surprised. So, I think in terms of working with your partners through COVID – and we’ve been talking a lot about culture – I think one of the foundation things is to pick a company or a partner that has a very similar culture to you. So then you’re not trying to find middle ground in that. And that should really be a big part of your selection process. You need to be comfortable with the folks that you work with and you need to be living kinda to the same standards I think. 

    So for me, how COVID affected me was: while we were all scrambling to get ourselves home and reaping the benefits of a long-term plan to be able to have a remote workforce – we learned that through Sandy a long time ago and we had done a lotta changes – I was also working really closely with Cognizant in helping to get all the resources that they needed to get my folks home at offshore, right? So I was as concerned about offshore as I was concerned about onshore. 

    And now to this day my job is actually pretty high-touch now. And the reason being that we’re so far along, I have people that’re really overworking themselves. And I think that – and I don’t know that it’s deadlines as it is: take pride in craftsmanship, and they’re home and they wanna – this is something for them to do. Or it’s a stress release in a really challenging time where everything’s unpredictable. But I spend more of my time saying, “When was the last time you took a day off? When was the last time you took an afternoon off? You need to recharge. You need to gather yourself.” And that’s for offshore too. So that’s been my challenge this year.

    Shimel: Fair. Mitchell, I know you guys at Accelerated Strategies Group did a study on the whole remote thing and COVID. Thoughts? 

    Ashley: Boy, I could talk for an hour on this. But I’ll just point out a couple things and I’ll point folks to the report. We looked at – software developers already know how to work remotely, right? A lot of them do. And so how has that affected them? How has COVID and the work from home affected them and how have they kind of affected the organization?

    So, interestingly enough, across the board – there’s about 350 participants. Across the board, everyone is above 60 percent of who have accelerated digital transformation projects, contact – new forms the delivery and automation. But what I really found interesting was how influential DevOps practices, whether you called it DevOps or not, had started to infiltrate into the organization. So I’m talking about things like doing daily standup meetings or more cross-functional teams, increased use of that, asynchronous communications like a Slack or a team as opposed to being on a phone call or in a meeting. So there’s all these ways of working that, as we were talking before, sort of forced everybody into it. And the teams that had really good software teams working remotely jumped on board. And you saw an increase in the use of that kind of style of work, sometimes facilitated by tools, sometimes just process. 

    So if you wanna read the whole report – and reading is minimal; it’s all infographics; it’s super easy to consume – go to ACCELST.com. And it’s free to download. And enjoy. And let me know if you have questions. Love to talk to you about it.

    Gong: Awesome. 

    Shimel: Excellent. Guys, we are outta time. We’re actually over time. Robina, Ming, Chris, I wanna thank all of you for joining with us today. This was a great discussion. In the show notes, production notes, we will have links to your websites and any other links you wanna put in there. But all three of you are dealing in the real world with real problems that we’re seeing today and helping organizations solve ’em, whether it’s your own organization or other organizations. So keep up the great work. We may revisit this topic on DevOps Unbound someday, and we’d love to have you back on here. Okay?

    Gong: Pleasure.

    Shimel: Thank you so much. 

    [Crosstalk] 

    Laughlin: Nice meeting you guys. Good luck. Thank you.

    Shimel: All right. Mitch, thanks as always, man. This is Alan Shimel for DevOps Unbound. Thanks for joining us. We’ll see you on another DevOps Unbound real soon.