Tag: devops culture

  • REP SPOTLIGHT: TaUB Solutions

    REP SPOTLIGHT: TaUB Solutions

    DevOps Institute: Tell us about your organization.

    TaUB Solutions: TaUB Solutions is a consulting-cum-training organization based in Bangalore India. Our vision is to take the customers beyond the existing state of maturity to envisioned business outcomes.

    We serve a lot of customers in southeast Asian region by delivering consulting assignments on ITSM, IT governance, project and program management and business relationship management. This also includes delivering business simulations on the respective domains and make our customers gain benefit from learning by doing.

    DOI: What other topics do you teach or consult?

    TaUB Solutions: ITSM, IT governance, agile, DevOps, business relationship management, cybersecurity, project and program management and ISO standards (20000,27001, 22301)

    DOI: What type of interest in DevOps are you seeing in your region?

    TaUB Solutions: At the moment, we have successfully delivered around 11 batches of DevOps Foundation and Certified Agile Service Manager courses. We appeal to our customers because of the practitioner focus that we bring to the table and take them through case studies to understand the end-to-end value chain. Our current run rate indicates a strong pipeline of interest in southeast Asian countries who want to apply the DevOps principles and philosophy in their workplace. We also see great traction from Indian corporates to plunge in to the DevOps journey to serve their respective customers better.

    DOI: How do you think DevOps contributes to the business’ value stream?

    TaUB Solutions: One of the things that appeal most to me is the ability to articulate the end-to-end value chain. Business today does not care about which framework or methodology you adopt for the customers. All that matters is to deliver an end-to-end value chain and get a common understanding among different functions and leverage the best across the enterprise. I see tremendous value of leveraging agile, ITSM and lean principles with culture and tool chain to demonstrate key business value.

    DOI: What topic area in DevOps excites you the most?

    TaUB Solutions: There are three things:

    • Culture change
    • Power of automation using tool chain
    • Business KPIs and Common Metrics across the organization

    DOI: Why should enterprises and individuals consider formal DevOps Training?

    TaUB Solutions: Today, DevOps is still at its infant stage and has not yet been codified. So people have their own perspectives, thoughts and misconceptions. So in order to be certain with the path they traverse, it is increasingly important to step in the right direction. This is where a formal DevOps training from DOI can help people to understand fundamentals and DevOps trends from practitioners.

  • Continuous Delivery Dependent on Who, What, Where

    Continuous Delivery Dependent on Who, What, Where

    Without the right people, positions and talents, it is difficult for a business to engender a DevOps culture. It is even more frustrating to facilitate a continuous delivery pipeline successfully producing quick bursts of innovative genius, without a full complement of qualified souls harmonizing on the same DevOps theme song as they toil away on the company’s next release.

    Some enterprises have a handle on the go-to people or hired guns they need to help spread a DevOps mindset—and exactly where to plug them into the organizational hierarchy. Other organizations have progressed to cloning these folks across Dev, Ops and the rest of the business. Some of those have laid some pipe as they extend a conduit from build to production. Those that are, by now, the “old guard” of DevOps have well-run pipelines brimming with fresh, robust software goodness.

    No one company has a “secret sauce” that works across all industries and organizations. How your company should connect the dots depends on who you ask. This time devopsy.kinsta.cloud has asked Renato Quedas, vice president of Solutions and Enablement at Micro Focus.

    Wrong People, Wrong Result

    The right people will produce significant changes to code, creating new value that is worthy of promotion to production. The right people will ensure that the release is ready, reliable and fit to go live anytime the business wants to give its blessing.

    “If a continuous feedback loop doesn’t exist between everyone involved in defining, building, testing, releasing and operating an application, the right people will not understand or feel enabled to pull the trigger in a release. Essentially that ‘any time’ will turn into ‘sometimes,’” says Quedas.

    The company must maintain business continuity/disaster recovery (BC/DR) while accelerating continuous delivery; if continuous delivery moves too fast, it will push BC/DR off the rails and into disaster. Testing is an important ingredient in ensuring BC/DR remains once the software reaches the end of the development pipeline. “Customers will not care if applications are delivered faster if they don’t perform or function properly on their platform and devices of choice. Not having the right people involved will turn continuous delivery into an unreliable minefield and create an uncertain application delivery pipeline, which businesses will never accept as part of any improvement initiative,” he says.

    The Right Stuff

    According to Quedas, the following positions or profiles are examples of people who would have the communications skills, ruthless negotiation tactics, sound decision-making processes and customer-first mentality—with little tolerance for poor quality—that are necessary to make a DevOps culture and continuous delivery work:

    • Product Managers who own responsibility for product quality can keep software product focus and development on track. They can communicate the business needs for the software, the capabilities it must have, and mediate the sometimes chaotic process that comes with continuous delivery. “Product Managers are used to prioritizing the work based on market trends, competitive landscape, customer requests and other internal/external pressures. Product Managers are accustomed to making decisions based on trade-offs, which helps CD focus in delivering the right outcomes to the business faster,” says Quedas.
    • QA Managers who readily communicate to test, development and operations teams as well as nontechnical folks about what is necessary to maintain software reliability. They also can bring development to a halt and send innovations back to the drawing board when validity and reliability are at risk.

    Creating the DevOps Culture

    A thriving DevOps culture will build a software delivery pipeline that can duplicate quality results—as any truly repeatable business endeavor should be able to do. To bring this culture to life, the company must demolish team and departmental silos to get everyone on the same page regarding what the organization must do and when it should do it. “Companies will need to streamline production via automation in order to make decisions faster,” says Quedas.

    A working, vibrant DevOps culture should give everyone a voice and ownership of a certain amount of control of their part of the process. “There is always pressure on information technology but there needs to be an understanding that it should be acceptable to put pressure back on the business,” says Quedas. “The business expectations need to be realistic or it won’t work. All sides need to be responsive.”

    A healthy DevOps culture and mindset includes a shared understanding that scope with value must be achievable in a reasonable amount of time. “The faster you demonstrate value, the easier it becomes to earn the right to continue in the journey and on to the next phase of development,” he says.

    Right People + Right Careers + Right Culture = Continuous Delivery

    Having the right people in positions such as the aforementioned product manager and QA Manager gives an organization the ability to hone its continuous delivery pipeline. The right culture ensures that everyone will follow these and other leaders and stakeholders so that each new innovation comes as quickly and smoothly as it can.

  • MTTR: The Magic Metric

    MTTR: The Magic Metric

    How do you improve with one metric quality, cost, performance, employee and, most importantly, customer satisfaction?  I think MTTR is one to consider, but with a DevOps twist (agile+lean+ITSM). The thing I love about DevOps is that it allows for people to think differently. DevOps is the movement driving organizations to find new ways of collaborating, communicating, cooperating and improving the way they use technology to create and support services.

    While many agree that MTT stands for “Mean Time To,” there is no common agreement on the R.  I like using 5 Rs, as they cover the life cycle of idea to realization (in the hands of the customers in a way they like).

    So what are the 5 Rs? Well, let’s work backward (shift-left thinking):

    • Review: What happened? How can we stop this in the future? How can we shorten the cycle?
    • Return: Do customers agree that all is well? How satisfied are they with not only our performance but the fact the event occurred?
    • Restore: The time and effort to get servers, network, applications, data, passwords back as they should be.
    • Repair: The time and effort to resolve the issue.
    • Respond: The time to notice, decide if we can fix or get others involved, and their reactions to begin getting things sorted.

    MTTR is a cycle of events. Breaking them down and understanding the value of each step enables you to reduce time, effort, waste and cost. How often do things break and why? Are they self-inflicted because we test poorly? How can you apply automation or self-healing? How good is your monitoring and alerting and response mechanisms? How great is your documentation? Do you rely on a certain person to fix things or can anyone? Knowing the answers to these questions can make issues become less frequent—or, at least, reduce the effort to address them when they do occur, as things will break.

    Knowing these answers also helps clarify priority of issues. Working back from the customer drives the flow of work to highlight faults. Why treat all issues as P1 all month? For example, payroll is only a P1 when you are getting paid, but the rest of the month it can be a P2. Working with customers will help ensure you are fixing the important things, not something someone wrote in a service level agreement that is rarely updated.

    MTTR is also a fabulous learning measure. DevOps is all about collaboration and that begins when people talk to each other, repair things or introduce a better test or monitor or alert to capture issues and customers are minimally impacted. Let your service desk own MTTR and see how issues get resolved better, faster and more safely.

    MTTR helps drive movement to virtual or cloud. MTTR can also help you improve your A/B use of infrastructure or services.  Have an issue? We’ll flip a switch.

    But the overall goal of any metric is to drive actions, decisions and improvement. MTTR is such a measure. Be brave, throw away your SLAs, get people involved for issues and use MTTR to make things better across the life cycle. Then celebrate the success of your journey!

    Let us know. Do you use MTTR? Can you measure each step and perform a retrospective?

    About the Author / Daniel Breston

    dDaniel Breston is the Chief of DevOps Transformation for Ranger4. Daniel has 30+years leading IT Service, Operations, Applications, Data Center and service partners in management of technology enabling business processes and functions. He has also spent 15 years of consulting and coaching leadership teams across the EU and UK in developing their people, processes and use of technology to deliver technology services better, faster, safer. Daniel has qualifications in IT Service Management (ITIL, COBIT,etc.), Lean and DevOPS.

  • Rep Spotlight: Global Lynx

    Rep Spotlight: Global Lynx

    DevOps Institute: Tell us a little about your organization:

    Global Lynx: Global Lynx is a leading and fast-growing IT consulting and training company that assists companies and government agencies improve the competence and skills of their IT organization, enhance the maturity of their IT governance and improve the quality and effectiveness of their IT operations, services and processes.

    Since 1996, Global Lynx experts have helped organizations in five different countries, improving—and often transforming—their IT operations through the implementation of effective frameworks for IT governance, ITSM (IT services management), PMO (project management office) and information security.

    As an Accredited Training Organization (ATO), Global Lynx also offers a wide variety of IT courseware covering different areas, standards, frameworks and methodologies, and at various levels of expertise.

    Global Lynx trainers are experienced consultants, certified in multiple IT disciplines. They have actual firsthand experience in their areas of IT expertise, as well as experience in delivering training programs.

    DOI: What other topics do you teach or consult on?

    Global Lynx: IT service management, IT corporate governance, IT audit, information security, cyber resilience, IT risk management, cloud computing, project management, SCRUM, business continuity, process design and implementation, and enterprise value creation.

    DOI: What type of interest in DevOps are you seeing in your region?

    Global Lynx: Companies are interested in obtaining a common understanding of DevOps concepts and best practices, and they are focusing on deploying these practices organization-wide.

    DOI: How do you think that DevOps contributes to the business’s value stream?

    Global Lynx: The digital disruption all industries are experiencing, has created the need for IT to be embedded in every single business unit. Solid DevOps practices will help IT organizations deliver higher value to their customers, as value is delivered through operations, but it is defined and enabled in the development stages. Value should be managed not only in operations, but rather from the early stages of the service life cycle. A mature IT organization cannot have a poor collaboration and communication culture; without this, value creation will be limited to technical value instead of real business value.

    DOI: What topic area in DevOps excites you the most?

    Global Lynx: How DevOps interfaces other frameworks and how all of them can work together toward creating value to the customer.

    DOI: Why should enterprises and individuals consider formal DevOps training?

    Global Lynx: DevOps is all about people, and it is enabled by people. If a person is not committed, that person will do little to support the DevOps initiative. People need to go through formal DevOps training to learn what DevOps is, and how their role impacts the initiative and how they contribute to value creation. Certification is a plus, as it gives people a personal benefit. People will naturally react positively to something they own, because they will believe in it.

  • The Persistence of Enterprise Tech Failure Rates

    The Persistence of Enterprise Tech Failure Rates

    During a recent dinner conversion with a CIO friend, I was surprised to learn that his organization was having challenges delivering the applications and IT services on a timely enough manner that the business needs. The business is taking too long to approve the budget for major tech projects to start, then develop and deploy, and the CIO expressed frustration how it is always behind the demand curve and following where it should likely be in the market. His level of frustration as he described the situation was painted all over his brow.

    Hearing this was surprising to me; after all, we’ve been writing about how such problems delivering with speed and agility are challenges that are designed to be solved by DevOps, agile development methods, microservices and all of the things we focus on here at devopsy.kinsta.cloud and Container Journal.

    The discussion we had got me wondering how common this situation remains. How many companies are still struggling with their ability to retool themselves into more agile developers? In the late ’90s it was common for tech projects to fail. I recall surveys I reported on that found 60 percent, or higher, failure rates of large projects. But back then software rollouts were truly big bangs. There were years of development time and hundreds of physical servers and thousands of endpoints that had to all be managed. There existed layers and layers of committees and bureaucracies between the developers, IT admins and business leadership. IT is supposed to have moved beyond all of that.

    Unfortunately, however, if recent surveys are any indication, it still seems very common.

    A survey conducted last year by portfolio management provider Innotas found that more than half of tech projects are not well aligned with the goals of the business. The survey, the annual “Project and Portfolio Management Landscape survey,” also found that more than 61 percent of IT professionals questioned did not think that they have adequate resources to manage demand for tech projects in their organization.

    Part of the challenge may be that there’s inadequate project management in place at many organizations. The survey found that 38.7 percent of respondents didn’t have a project management office at their organization; however, 16 percent are building such offices. Additionally, 25 percent of those surveyed said they don’t have a formal methodology to prioritize projects.

    Other areas of concern ranged from project prioritization (26 percent) and alignment (13.8 percent). Attaining benefits and finding the appropriate budget were also challenges at 12 percent or fewer of organizations surveyed.

    This is concerning, as more enterprises are doing everything they can to move more swiftly (or, at least say that they are). As we covered in “Digital Transformation Strains Traditional IT,” according to a recent report published by Salesforce’s “2016 State of IT,” IT leaders are focusing on mobile apps, migration to the cloud, building adequate cybersecurity/incident response, customer-facing digital apps and productivity apps.

    The Salesforce report found that 68 percent of respondents are increasing their tech budgets on mobile apps, cloud and security. The majority (63 percent) of respondents also said they plan to increase their budgets allocated to cybersecurity, while 62 percent will spend more on employee productivity apps.

    Some of the things that has come up, repeatedly, in my conversations with other CIOs is that those companies that are struggling have poor business-to-IT relationships and ongoing feedback. This creates a lot of distrust and poorly aligned priorities.

    We covered a lot of this earlier in a number of posts, which are available here:

    Five often expressed obstacles to enterprise IT innovation

    Enterprises still struggle to leverage IT as a tool to innovate

    The IT mandate: Be a catalyst of business innovation

    Driving Innovation with DevOps

  • What is a DevOps ‘Best Practice’?

    What is a DevOps ‘Best Practice’?

    In IT, we love our frameworks. Whether agile, ITIL, lean, cobit, six sigma or others, our thirst for “best practice” guidance seems to be unquenchable.

    The concept of a “best practice” is an enigma. Who decides if a practice is actually the best? And best for whom? While an “adopt and adapt” mentality is advocated in most frameworks, there is still a tendency to benchmark efforts against and conform to published best practices. Whether promoting “best in breed,” “world-class,” or “best practices,” many organizations swing these terms around as some form of competitive advantage.

    Is it really? Shouldn’t business outcomes be the real competitive advantage and measure whether IT’s practices are really the “best” to meet customer requirements?

    The DevOps Institute was founded in 2015 as a global learning community for emerging DevOps practices. Since our launch, we have intentionally avoided any reference to DevOps “best practices.”

    We believe that DevOps practices are constantly emerging and, in many cases, being proven in the wild.

    Through research, interviews, conferences and the experience of our Regents and partners, DOI’s goal is to identify, capture and share emerging DevOps practices through knowledge, education and certification models that best serve the learning community and enterprise IT. We feel it is premature to certify an individual as an “Expert” or “Master” when the expertise and mastery needed for successful DevOps is not clear and may not be appropriate in a single person.

    DevOps is fairly young. It does not have a single body of knowledge. There is disagreement on whether it is a philosophy, movement or framework. Despite that, DevOps is crossing the chasm from innovators to the early majority faster than any other IT framework. Why? Perhaps it is because DevOps speaks to many of the cultural and technical challenges that IT has been amassing for years.

    So instead of focusing on best practices, let’s agree on DevOps’ core principles:

    • Go faster
    • Shorten feedback loops
    • Experiment and learn
    • Cultural transformation
    • Deliver business and customer value constantly and consistently

    No doubt, some practices have clearly risen as being critical to the realization of DevOps’ core principles:

    • Agile software development
    • Continuous integration
    • Continuous delivery pipelines
    • Automated and continuous testing
    • Proactive monitoring
    • Improved communication and collaboration

    Still, over the past year, DOI has seen additional practices gain interest

    • DevSecOps/rugged DevOps
    • ChatOps
    • Agile service management
    • Lean
    • Immersion practices (Garage, Lofts, Dojos)
    • DevOps teams

    What will emerge next year? Who knows—but that’s the exciting part of DevOps. As time passes, there is less contradiction and more supplementation. Each emerging practice seems to complement and fine tune what came before.

    Even without a standard definition, DevOps is already encouraging organizations to examine their proprietary practices, identify gaps, assess their automation and, most importantly, engage in collaborative discussions. Transformations have taken seed without defined best practices. That’s awesome! Let’s not quell the momentum by attaching a static set of best practices.

    Will DevOps’ best practices eventually be agreed? Maybe. DevOps touches almost every aspect of IT management—people, practices and automation. That’s a tall order for a set best practices. Certainly some will try to publish their version of a “definitive” DevOps body of knowledge. Even “The DevOps Handbook,” an important book publishing later this year, was built as a collaborative effort between many of the early founders of the DevOps movement. Their perspective and insight will be awesome but not finite.

    I understand the frustration by the lack of a single body of knowledge and prescribed best practices. In past frameworks, the body of knowledge was both a enabling tool and constraining limitation. Bodies of knowledge are difficult to keep current. For DevOps, let’s embrace the concepts of spirit of sharing, collaboration and continuous innovation by promoting an inclusive and collective body of knowledge of emerging practices.

    If we settle on a set of DevOps best practices, are we actually inhibiting the very values that we are trying to instill? I hope not.

  • Tales of DevOps Discovery Part 2: Definitions Matter

    Tales of DevOps Discovery Part 2: Definitions Matter

    Definitions Matter: Step Two in a DevOps Transformation

    The first post in this series on DevOps Discovery discussed the importance of asking fundamental questions of stakeholders to facilitate alignment on priorities and establish a mission statement when beginning a DevOps transformation. Part 2, below, reviews definitions of common DevOps-related terms and provides examples of how failure to agree on such terms can hinder your transformation.

    The industry is full of terms such as continuous integration, agile, continuous delivery, DevOps, etc. The practices described by these terms often are defined differently by various industry “experts,” resulting in stakeholders in the software delivery process having different understandings of what constitutes these practices. Some will state they are already following the practices; others will state they do not. Some will believe the objectives unachievable, while others will be bullish on the prospects; differing interpretations blocking agreement on the organization’s current and target states. If stakeholders cannot agree on the current state (or the start point) and the target state (or the destination), it is impossible to “map a route” for the journey to DevOps.

    For example, let’s look at how some define continuous delivery:

    Continuous Delivery – Definition 1:

    A software engineering approach in which teams produce software in short cycles, ensuring that the software can be reliably released at any time. It aims at building, testing and releasing software faster and more frequently.

    The approach helps reduce the cost, time and risk of delivering changes by allowing for more incremental updates to applications in production. A straightforward and repeatable deployment process is important for continuous delivery.

    Source: Wikipedia


    Continuous Delivery – Definition 2:

    Continuous Delivery is a software development discipline where you build software in such a way that the software can be released to production at any time.

    [Continuous Delivery Blog Post by Martin Fowler]


    You may read the above and initially think there is no difference in the definitions but, note that the first definition addresses deployment of software with the statement: “A straightforward and repeatable deployment process is important for continuous delivery,” whereas the second definition addresses deployment of software with the statement: “Build software in such a way that the software can be released to production at any time.”

    This distinction may seem trivial, but it is the often the source of confusion between the practices of continuous delivery and the practice that is commonly called continuous deployment. In contrast to continuous delivery, which states that every software build “could be released,” continuous deployment is loosely defined as “the practice of releasing every good build to users.”

    When establishing your target state for the DevOps transformation a seemly slight confusion such as this can result in pushback from stakeholders concerned that continuous deployment is unachievable or too disruptive. These sentiments include:

    • Business: “We cannot gather, spec and track our requirements at that rate.”
    • Operations: “There is no way we can support daily delivery into production, ensure security, uptimes and perform our day-to-day work. It takes us an entire weekend and multiple attempts to deploy today.”
    • Customers: “Our compliance team needs three months to review and approve every new version of our accounting system.”

    The confusion and potential pushback exemplify the need for establishing baseline definitions and alignment at the start of a DevOps transformation, and doing so in the specific context of your organization. The importance of points such as how far it deploys varies with the organization—some organizations can support continuous deployment to production multiple times a week or even multiple times a day, such as Netflix does. Other organizations, such as providers of critical financial systems, may never pursue this cadence of deployment. Be sure to apply these industry practices pragmatically as fit for your organization, not dogmatically based on generic industry definitions.

    Let’s look at a couple of definitions of DevOps:

    DevOps – Definition 1:

    “DevOps (development and operations) is an enterprise software development phrase used to mean a type of agile relationship between Development and IT Operations. The goal of DevOps is to change and improve the relationship by advocating better communication and collaboration between the two business units.”

    [Webopedia]


    DevOps Definition 2:

    “DevOps (a clipped compound of “development” and “operations”) is a culture, movement or practice that emphasizes the collaboration and communication of both software developers and other information-technology (IT) professionals while automating the process of software delivery and infrastructure changes. It aims at establishing a culture and environment where building, testing, and releasing software, can happen rapidly, frequently, and more reliably.”

    [Wikipedia]


    Like the example with continuous delivery, these two definitions also are very close. Yet on detailed observation, it is clear the first definition describes DevOps as being focused on relationships (i.e., culture and collaboration). The second definition extends this to include the “automating the process of software delivery and infrastructure changes,” giving consideration to tools and technical practices such as continuous delivery.

    Does this matter? Yes. Often if the executive sponsors and key stakeholders do not account for the need to establish tools and technical practices and only focus on relationships, there is a high chance for unrealistic expectations for timeline, budgets and results. Conversely, if the need for changes in culture and process are not considered and the DevOps transformation focuses only on tools and technical practices, the efforts are also unlikely to yield the expected results. A DevOps transformation must account for the trinity of “People, Process and Tools.”

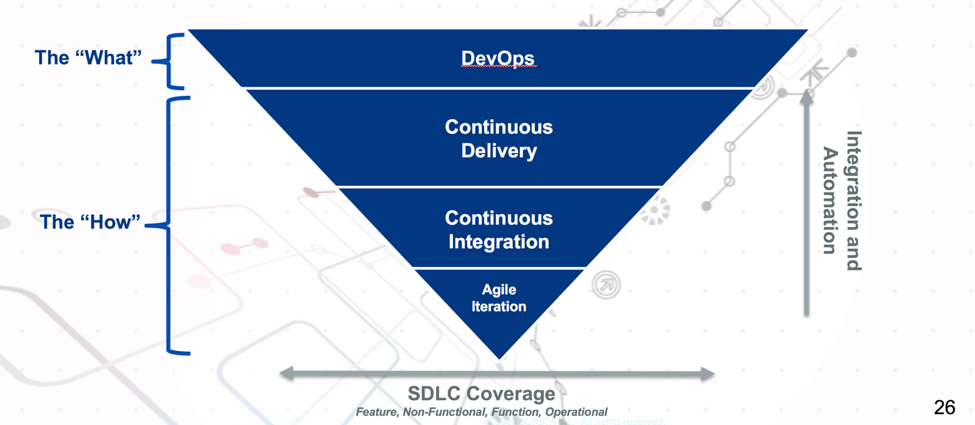
    When considering DevOps, it objectives and the objective of its component practices it is useful to establish a clear idea of the relationships between theses practices. It is often useful to visualize them as below:


    DevOps Transformation Triangle
    The DevOps Transformation Triangle


    DevOps is the “What,” the target state as defined by a set of guiding principles. Agile development, continuous integration and continuous delivery are the “How,” a collection of process, practices and tools that together build the foundation for a sustainable DevOps implementation.

    In the next section, we will review some of the initial discovery questions asked when beginning on a DevOps transformation, provide real-world examples of answers from various stakeholders in real organizations, and analyze those answer to better understand the journey to DevOps.

  • Enterprise Cassandra Deployments

    Enterprise Cassandra Deployments

    Successful Cassandra deployment in the cloud takes a certain amount of skill and knowledge. In this blog I will share best practices for a successful Cassandra deployment in the cloud such as Amazon Web Services (AWS) and Google Cloud Platform (GCP). I will also discuss how you can protect and recover the data in your Cassandra cluster when deployed in the public cloud.

    Cassandra Deployments in the Public Cloud

    There are two main ways to have successful enterprise Cassandra deployments in AWS:

    • Use a ‘managed’ Cassandra deployment. This is a reasonable approach; the only downside is the inability to customize data placement beyond what is typically provided by the vendor.
    • Manage the cluster yourself, if you want to have full control over your Cassandra deployment and customize it to scale and perform according your business needs.

    Please refer documentation from Datastax or Apache Cassandra for detailed best practices for Cassandra deployments. The following best practices are reiterated here to simplify deployment of a scalable Cassandra cluster in AWS.

    Storage

    Both AWS and GCP offer two types of local storage options for their compute instances. For AWS, the options are Elastic Block Storage (EBS) and Ephemeral Storage. In GCP, the options are Persistent Disks and Local SSD. Both options have their own trade-offs. Pick the one that best suits your deployment.

    Persistent Storage

    EBS volumes have performance characteristics similar to network storage such as a NAS or SAN. Because storage from EBS volumes is multitenant in nature, it is not suitable for distributed, log structured databases such as Cassandra. If you want to ensure reliable performance through EBS volumes, use “EBS optimized instances” with “provisioned IOPS.” Since the IO traffic to EBS volumes goes over the instance network, EBS optimized will provide reliable performance, but does not guarantee any increased performance. To get the most performance out of EBS volumes, use instances with multiple disks and separate the volumes used for “Data” and “Commitlog.”

    If you have to use EBS Volumes, go with “EBS Optimized Instances,” with “Provisioned IOPS” and split data and Commit Log on different volumes.

    Ephemeral Storage

    Ephemeral storage is a great option to use for downstream Cassandra environments such as test/dev and staging. Since ephemeral volumes are typically SSDs, there is no need to separate the data and commitlog into separate drives. To optimize performance, choose EC2 instances with multiple ephemeral storage drives and stripe them together into one logical volume. Send data and commitlog to the logical volume. Remember that when you stop the EC2 instance, the data in Ephemeral storage will be deleted.

    Stripe all Ephemeral drives into a single volume to get maximum performance.

    Data Distribution

    Cassandra uses Snitch to determine the topology of the cluster. The Snitch is also used to determine the data center and rack for each node in the cluster. Replication strategy is used to determine the placement of data across the different nodes in the cluster.

    AWS

    1. EC2Snitch works well for single region deployments.
    1. Ec2MultiRegionSnitch works well for cluster distributed across multiple AWS regions. Please note, Multi-DC, Active-Active configuration makes your cluster resilient to region failures and for multi-dc cluster, use “local quorum” to improve performance.

    Google Cloud Platform (GCP)

    1. Use GoogleCloudSnitch for Cassandra deployments in GCP.
    1. GoogleCloudSnitch treats regions as Cassandra data centers and availability zones as racks.

    Other Features

    Both AWS and GCP offer a series of operational capabilities that seem to make it easier to maintain high uptime on Apache Cassandra cluster. These capabilities have to be chosen carefully depending your deployment needs.

    1. Load Balancing: Network-level load balancing service is offered by both AWS (Elastic Load Balancer) and GCP. It is not recommended to put a load balancer in front of Cassandra. It is better to use a client connector that can handle this, consider open source utilities such Presto and Astyanax
    1. Autoscaling: Both AWS and GCP offer Autoscaling facility for compute instances. However, although this functionality looks very enticing, putting all C* nodes in an autoscaling group will not produce the desired result. Instead, create a separate autoscaling group of ‘1 node’ for every node in your cluster. This will ensure that anytime a node goes down, it is automatically brought back up. This will ensure the cluster data placement is not disturbed when nodes go down and nodes coming up do not cause excessive data movement.

    Scalable Backups and Reliable Point-in-Time Recovery

    Backing up your data is a must-have for enterprise organizations. The impact of data loss is so high that no enterprise wants to risk relying alone on replication. Protecting data in a public cloud environment may seem daunting, but there are several options available that can make this easier compared to an on-premise deployment. A simple option may look like one of the native snapshots:

    Storage Snapshots

    I have seen few customers use snapshots of EBS volumes as a way to protect the data in their cluster against logical and/or operational errors. This solution will work but with some severe limitations. On top of the overhead of maintaining the scripts to take snapshots, there is a large overhead in storage costs. Taking a snapshot of volumes does not allow for incremental backups of your data. This causes an exponential bloat in the amount of data stored in snapshots, leading to high cost of the backup solution.

    Amazon S3 or Google Cloud Storage

    Using an S3 bucket as the secondary storage enables enterprises to use low-cost, highthroughput storage, while reducing overall operating costs for storing backup data. Here are a few recommendations when using S3:

    1. S3 Region: Amazon S3 buckets are region-specific. A bucket created in one region will provide better performance characteristics to other infrastructure in the same region. Subsequently, it is important to ensure the S3 bucket used as the secondary storage is in the same region as the production database being protected and the Datos IO cluster.
    1. Storage Class and Lifecycle Policy: Amazon S3 allows users to create lifecycle policies on buckets. These policies dictate the performance and response time characteristics of objects in the bucket. STANDARD_1A is more suitable for longer lived and less frequently access data, and is not suitable as secondary storage. Additionally, do not turn on any lifecycle policies on the buckets used for the secondary storage. All buckets should be in the standard storage class.

    Conclusion

    As enterprises leverage the agility provided by public cloud environments, it’s important to understand the various facets of Cassandra deployments to ensure the efficient use of your money and time.

  • The War with Human Nature

    The War with Human Nature

    What is the difference between “leading” edge and “bleeding” edge? Being the first human being to advocate change.

    It is a virtual war with human nature to accept change. For all the innovation introduced into our society, most of it is a product of invention over evolution. Don’t get me wrong: Once we find something that works, we inherently work tirelessly to make it better, thus evolving it over time. But the genesis of the “new” is easier to accept as creation—a new idea, a new innovation of our own—than a change in direction, a forced acceptance of the ideas or creations that were “not invented here.”

    In the workplace, most employees are looking for personal security, for a feeling derived from consistency and predictability in the day-to-day work activities. Anything that threatens an employee’s ability to continue to secure compensation becomes something that inherently meets our resistance. The No. 1 culprit: you guessed it … “change.” As long as what I do remains the same, over time I will get better and better at it. Practice makes perfect. But when something “new” is introduced in the actions I am supposed to perform, there is a risk that my value, my expertise, will be reset to zero and perhaps I will not be valued as I once was. This threat to my compensation is real; therefore, my resistance to it is equally real.

    Programmers Found Guilty

    You would think that engineers and those working in the software industry would be exempt from this phenomenon. But most are not. Finding an ex-Cobol, ex-Clipper, ex-Windows, current mobile Apple iOS programmer is like finding a unicorn in Central Park. Most successful Cobol programmers are still Cobol programmers, looking for jobs in mainframe shops, content to see the new generation of programmers not competing for their declining job markets. The early generation of programmers minted after the adoption of the PC computer tend to know less about Cobol and RPG-3 and more about PC-based programming languages such as GW-Basic and Pascal (at least the older ones). Programmers minted after the Windows graphical adoption know more about that generation of coding languages, and so on, and so on.

    The basics of coding have remained the same since the advent of this discipline. We create a list of instructions, in sequential order, that the computer must execute to produce a desired result. There are nuances to this, and an explosion of capability in this, but the basic principles remain much the same. Yet, programmers well-versed in a particular language are shy about learning a new one, unless the platform is similar, the features are similar (albeit improved) and the belief is high that they will be successful in the new language quickly. There is no reason why a Cobol programmer could not be successful creating mobile apps. Or, for that matter, a mobile app developer could try his hand at Cobol. But it seems neither do, at least not very often.

    What happens instead is that each programmer begins to establish his/her own ecosystem of support: simulation models that imitate the platform responses, highly evolved text entry tools that auto-format code and check for omissions such as missing parenthesis and scripted tools that perform the mundane tasks we need to build (or construct) new versions of code or deploy a build into a new environment. This same ecosystem of support will exist for database, network and middleware engineers as well. The tools will be decidedly different, but the reasoning for them tends to be identical: to make things easier to do.

    Looking for a Magic Bullet

    There is no cure for breaking down the resistance to change, except constant exposure to it. However, forcing employees to face perceived threats to their value—and their compensation—will, at a minimum, produce exorbitant stress at work—or, worse, an employee turnover rate that would rival donuts next to a police station. The goal is to introduce change that will ultimately increase the value of an employee, as well as potentially increase the compensation they worry about. This is where the DevOps value proposition must be created for each impacted audience. A generic value statement is not enough, nor is a mandate by top company executives. You cannot “force” people to adopt something new, anything new.

    Creating the right value proposition must be specific to the audience you seek to adopt the “new” system, tooling or process. DevOps is a continuum of all three (people, process, technology). So for the database team, for example, changing out the ecosystem it has evolved into a new set of tools and processes, may seem like a hard sell at first. The advocate of DevOps (whether the exec teams or the service teams delivering it) must be able to articulate the value proposition clearly to the database teams.

    “Why” should they move to a newer ecosystem? A stubborn engineer can always point out the holes in your tool and the beauty of his own. He/she will likely have evolved his/her own support ecosystem to a state of near utopia … but only for himself. Usually the processes and tooling engineers use to make their own lives better do not scale to others in the department. And God forbid some other engineer updates “their” scripts or makes changes to “their” process. While this is wonderful for the engineer who creates it, it is miserable for anyone else attempting to use it.

    Constructing a Value Proposition

    The value statement must trade prima donna utopia for scale. Using common DevOps tooling, it is possible to support many more task requests than most individually constructed ecosystems can handle in a given day. And believe me, those task request increases in volume are coming. For example, an Ops engineer may be able to handle provisioning five systems a day with his own tooling, but when requests come in to provision 50 or 100, he is dead in the water. Having the Ops engineer help manage the deployment template or framework allows users to self-serve on provisioning requests and keeps him from having to do everything for everybody. His job is different but every bit as important.

    The value statement must trade current skills proficiency for next-generation, market-valued skills. In effect, a database guy is valuable, but a DevOps database guy is considerably more valuable, or a “big data” database guy, or a IoT database guy … pick your poison. Whatever you are today, whatever skill set you have, the jobs that pay more money are the jobs that fewer people know how to do. At some point, a lack of DevOps proficiency will relegate an engineer to the pages of history. On the other hand, adopting and embracing DevOps will allow engineers to get the training they so desperately need to keep their career “fresh.”

    Finally, the value statement must trade today’s earnings for tomorrow’s increase in earnings. Companies that embrace DevOps are going to either save extreme amounts of overhead by staff reduction remaining at the same level of innovation productivity. Or, they are going to increase innovation productivity levels radically, making them leaders in their respective space by meeting customer demand much faster with higher quality (the path most taken). Either option should translate into higher compensation for employees who embrace DevOps. If companies do nothing to increase employee comp, choosing only to increase profits, competing firms will be happy to poach them and pay them more instead. This forces more costs in recruiting, training and employee turnover when it happens again.

    A Human Strategy that Works

    Your strategy for training employees to embrace change should be particular to the kind of work they do, and reflect the things that will matter to them. If you need help crafting a strategy let me know, I am looking at the moment 🙂 . Not every team will be as critical to the overall success of DevOps as perhaps your engineers are, but the value proposition should adjust for this fact. Keep in mind, if the change is less, then the resistance will be less as well. Your accounting, HR and legal teams, for example, may not feel the impact of DevOps as rapidly or as severely (in terms of change); thus, their resistance may be less, but it is likely more than zero.

    DevOps is about people, process and technology. It is in that order, with a heavy emphasis on people and a relatively light impact from tooling. And it will succeed or fail based on the embrace of people, process and technology. Process and technology do not care about change. People do. Since people are the largest priority or component of DevOps, it is their fears that must be addressed and their value that must be enumerated to succeed.

    To continue the conversation, feel free to contact me.

  • Data Protection for Operational Reporting Platforms

    Data Protection for Operational Reporting Platforms

    Making real-time business decisions based on data from social, mobile and cloud platforms is a requirement in today’s world. That’s why an ecosystem of next-generation operational reporting platforms such as Spark, Apache Cassandra, Kafka, Docker, Mesos, Marathon and more have come to life. Enterprises are using these technologies to re-architect their data storage and processing frameworks to achieve lower costs, scalability and faster response times. However, as enterprises onboard business-critical applications on this next-generation technology stack, they need to prepare for failures or errors that may disrupt customer-facing applications.

    One of the key benefits that operational reporting platforms provide is real-time visibility, which allows businesses to make strategic decisions based on actionable insights. However, the new applications generate a large amount of data and archaic operational reporting platforms (those based on traditional data warehouses, data marts and ETL logic) are unable to catch up and, as a result:

    • Business decisions are based on stale data
    • Fragmented data increases the risk of errors
    • Multiple copies of data increase storage costs

    These issues have driven many progressive, data-centric enterprises to re-architect their operational reporting platforms. In this new architecture, Kafka serves as a persistent message bus that ingests data from relational stores and provides failure resiliency and message buffering. Spark or Spark Streaming may be used for transformation, aggregation and other lightweight stream processing. These processing nodes may be deployed in Docker containers. Finally, Apache Cassandra serves as a distributed data storage layer that provides linear scalability and high-availability. Kafka also enables the ability to add multiple data consumers such as Hadoop/HBase through Flafka.

    Datos IO - operational reporting platforms

    However, as enterprises adopt operational reporting platforms, they want to ensure that bad data feeds and human error do not result in data loss. Apache Cassandra natively replicates data but that does not provide the capability to go back in time to recover data efficiently and at scale.

    As enterprises onboard their critical applications to achieve development agility, scalability and lower operating costs, they must also explore data protection solutions that are specifically dedicated for scale-out databases.