Tag: developers

  • Software Assurance Takes Center Stage at Developer Day

    Software Assurance Takes Center Stage at Developer Day

    Cloud Security Alliance and SAFECode Develop Training for Improved Software Security Using Cloud and DevOps Practices

    Software assurance is one of the most important and possibly one of the least understood areas of software development today. Software assurance is a comprehensive process that encompasses a set of design, coding and testing methods for ensuring that software functions as intended without introducing vulnerabilities, malicious code or defects that can bring harm to the end user. This approach is especially important in the cloud because increasingly the tools for developing applications are coming from cloud providers. The architecture for applications is changing rapidly and requires developers to understand the risks and vulnerabilities when developing applications in the cloud environment.

    As we continue to see vulnerabilities within applications that lead to exploitation and theft of data, there exists a lack of acknowledgement in how to properly define and address these issues. With increased expectations on reducing time to market, development teams are pressured to work in sprint cycles using agile methodology thinking. New feature development is put first and developing secure code can become an afterthought.

    While individual companies do implement effective methods for developing and delivering more secure and reliable software, except for a small number of organizations such as Software Assurance Forum for Excellence in Code (SAFECode) and the Cloud Security Alliance (CSA), there have been limited coordinated, industry-led efforts to build upon this positive work and promote best practices to advance software assurance more broadly, especially in cloud technology.

    Inaugural Developer Day Planned for Sept. 12

    The inaugural Developer Day event launched by the Cloud Security Alliance and SAFECode is a workshop developed to address these issues by educating software professionals on the challenges of improving software security using cloud and DevOps practices. A unique curriculum was developed by CSA and SAFECode to address the challenge of improved security using cloud and DevOps practices. The event is free but pre-registration is encouraged:

    WHAT:  SAFECode/CSA Developer Day

    WHEN:  Monday, Sept. 12; 1-6 p.m. PDT             

    WHERE:  Adobe Systems Incorporated Corporate Headquarters
    345 Park Avenue, San Jose, California
    Park Room, East Tower

    Event Fee:  Free          

    Registration:  https://www.eventbank.com/event/777/register/

    Developers play a critical role in secure software assurance, and in today’s IT landscape, this role has never been more important. The application of effective software assurance methods is a proven way of enhancing and preserving trust and reliability of software.

    A Practical Primer on Software Assurance

    The half-day Developer Day event provides software developers with an important general primer on the core principles and applications of software assurance, and how to build in security utilizing cloud and DevOps practices. Attendees also will be provided with insight on state-of-the-art software assurance trends and learn how they can deepen their knowledge of software assurance. The event agenda includes three sessions:

    • SAFECode: Driving Software Assurance among Software Professionals
      • Fundamental Practices for Software Assurance
    • CSA: Cloud + Dev = Security Awesome
    • Putting Theory into Practice: Software Assurance Case Studies

    SAFECode and CSA created the Developer Day with two goals in mind. The first was to share recent developments and trends in the practice of software assurance across a number of different domains. The second was to demonstrate the top ways to combine development practices such as DevOps with cloud deployments to increase security without slowing things down.

    Online Software Assurance Training Available

    If you can’t make Developer Day, SAFECode and CSA also recently launched a jointly developed free, online, on-demand cloud security training program called, “Basic Practices for Service Development of Cloud Applications.”  The two-part training program teaches students about different cloud models as well as basic practices and aspects of secure development of cloud applications. It is part of a broader security engineering curriculum made available for free by SAFECode.

    About the Author / John Yeoh

    john_yeohJohn Yeoh is the Senior Research Analyst for the Cloud Security Alliance (CSA) working within industry working groups, SDOs and strategic relationships in the development of cloud security standards, tools and solutions and strategy development. With over 15 years in research, John has authored reports on IT, cybersecurity, cloud and new technologies. His thought leadership has been presented in SC Magazine, USA today, Information Week and others, and he currently sits on numerous technology committees in government and industry. John’s graduate studies include Massachusetts Institute of Technology and University of Southern California with undergraduate work at Eastern Washington University and University of Washington. Connect with him on Twitter and LinkedIn.

  • DevOpsDays and Diogenes: Thoughts from a First-Timer

    DevOpsDays and Diogenes: Thoughts from a First-Timer

    I went seeking honesty at a DevOps conference and met Diogenes.

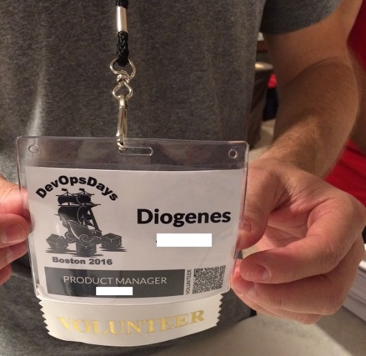
    Diogenes of Sinope was a controversial figure in ancient Athens who was known for walking around the famed ancient city—some say in the nude— during daytime with a lamp in his hand. He parried inquisitors who questioned his strange habit of using a lamp by day by insisting that he was looking for an honest man. At the recent DevOpsDays Boston, I actually met Diogenes. True story. See picture below. (Thankfully, he was wearing clothes.) But, as you probably guessed, this was not the man with the lamp, but rather one of the many conference organizers looking to help less-acquainted individuals find their way around the many meetings and speakers that filled the two-day conclave. Indeed, my Diogenes was instrumental in organizing the conversations and lectures that proved both honest and helpful.  Rather than a self-congratulatory summit, the two-day meeting was an honest conversation highlighting the advantages as well as many of the stresses befalling organizations that have adopted DevOps.

    DiogenesI found the most honest discussions were a floor up and a bit removed from the topics discussed in the main ballroom. These discussions were given the informal title of “Open Spaces” and were run in a typical un-conference format. These conversations were the real opportunities to learn about the stresses of implementing the modern portmanteau of DevOps.

    Tensions Between Dev and Ops: Why Can’t We All Get Along?

    One of the most interesting discussions in the Open Spaces looked at the dynamics between Devs and Ops. Like with any two groups that need to work together to accomplish larger organizational goals (think Sales and Marketing or Design and Engineering), there are inherent tensions that need to be overcome. The tensions between Dev and Ops are based on the different mission each pursues. Dev is striving to get software out the door as quickly as possible and push software updates forward. Ops is guided by the need to keep the ship as steady as possible, which often means limiting updates, as every update opens the door to potential bugs and deployment challenges. Starting with this premise of conflicting motivations, issues of trust and respect further complicate the relationship as each sees the other as trying to control the process.

    Yet, participants in this Open Spaces discussion were hopeful that tensions could be dissolved if management played an active role in creating cross-functional teams and managing workloads better. It was suggested that by essentially seeding Ops with Devs and vice versa, a greater community of understanding could be created. By promoting this cross-pollination, there would be greater understanding on both sides the implications (from the Dev side) of pushing software over the wall to Ops too quickly. From the Ops side, there would be greater understanding that 100 percent uptime is incompatible with dynamic product cycles that encourage innovation. A common and acceptable level of uptime needs to be agreed upon by both sides.

    For example, creating demos and code walk-throughs so both Dev and Ops can comment on potential problems and issues allows both Dev and Ops to see issues at the beginning rather than at the time of deployment.

    Blameless Post-Mortems in DevOps: Can They Exist?

    Another fascinating discussion in the Open Spaces focused on blameless post-mortems. Postmortems first and foremost suffer from an image problem. I believe it starts with the root word “mort” and it doesn’t get much better. To be clear, there was a lot of back and forth during this Open Space about the difference between a “postmortem” and a “retrospective.” Retrospectives are usually a weekly or bi-weekly event that bring to light the multiple root causes that are leading to defects or causing success through a review of RCA. In typical DevOps, one-week sprints are followed by a retrospective. Usually, the more data you can bring to a retrospective, the better. Post-mortems, on the other hand, result from an incendiary incident that was unexpected and undesired.

    Since post-mortems inevitably occur due to human oversight or lack of planning, there is no amount of thinking or planning that can prevent a crisis and thus prevent a post-mortem. As such, effective management will make post-mortems as painless as possible. The goal is to have blameless post-mortems balanced with accountability. According to one participant,

    “No one wants central casting to send in a screaming manager in a time of crisis who is only interested in assigning blame. That doesn’t help anything.”

    Importantly, you cannot fire yourself out of a post-mortem. Post-mortems are a necessary instrument to get at the root causes of issues. And while several different events can cause one issue, the post-mortem will at least begin to look at the process which caused the chaos. By not making the goal of post-mortems to find a scapegoat, the participants in one of these sessions can actually work on effective problem-solving.

    The goal of post-mortems needs to be effective problem-solving with the intent of committing the lessons learned to an actual document. It is not enough to let the lessons learned remain as an informal corpus that lives only in the heads of the engineers involved. Instead, documentation is required and it has to be in accessible place. Furthermore, it needs to be summarized and presented to management in either a lunch-and-learn or seminar so that the lessons learned then become actionable.

    Furthermore—and this was perhaps the most interesting part of the discussion on post-mortems—effective post-mortems are about getting Dev and Ops out of silos. There is no automation tool that will make Dev and Ops work together. Dev and Ops cannot just be about finding another automation tool. Instead, management needs to step in to help the process. Management needs to take engineers out of their silos and get them to work together if post-mortems are going to be really effective.

    Are You Feeling the Burnout Yet?

    After so many hours of interesting discussion in the DevOpsDays Open Spaces, I too was beginning to tire a bit. So perhaps it was well-planned to move on to a discussion on avoiding burnout.

    The artifacts of burnout are seen throughout the DevOps world as engineers constantly change jobs. This might be the phenomena of the “shiny orb,” where engineers always feel that there is a better, higher-paying job on the other side of the fence. However, as much as that might be true, it is equally the case that engineers are trying to escape burnout.

    According to the kanban methodology, which is woven into DevOps, you only pick up work as you can process it. Yet, DevOps practitioners often pick up work because they want to feel like they are team players or invincible or because they underestimate the work’s demands. They also fear the “imposter syndrome,” whereby colleagues seem less genuine if they don’t accept a piece of work offered to them. Inevitably, because the work is more than the engineer can handle, he or she becomes overwhelmed and is too proud to reach out for help.

    In a well-managed workplace, admitting overwork would not be an admission of failure. Instead, there would be a supportive culture to help the engineer or better mentoring on how to get through a challenging issue. “One-on-ones,” where the manager and individual contributor sit down together, would effectively solve the issue.

    But given the idiosyncrasies of workplaces, good management is not a given and engineers are often left to find their own coping techniques to help avoid burnout. The participants in this particular Open Space came up with the following gems:

    • Brain dumping. Empty your brain by putting all the thoughts and tasks that remain on your list and in your brain at the end of the day onto post-it notes. This helps avoid burnout because you are able to clear your brain prior to leaving work.
    • Create a Slack-based or bullet journal as a way to write yourself notes and create a list of priorities.
    • Follow the Pomodoro technique. Take a five-minute break every 25 minutes and a 15-minute break every two hours to better monitor how much time you are devoting to an issue and also to ensure you don’t forget to get a bit of movement into your day.
    • Learn how to say ‘no’ to requests. It’s a very simple word, but uttering ‘no’ once in a while will ensure that you mark boundaries and don’t take on more responsibility than you can handle.
    • Enlist management to make them aware of time you are spending beyond the normal working day and try to figure out ways to better manage the schedule and avoid burnout.

    The participants of this Open Space left with some new techniques to consider in avoiding engineer burnout. Hopefully, they will be implemented to practical advantage.

    Conclusion

    My first DevOpsDays conference was a true eye-opener.  I was lucky to get my education among such thoughtful and well-spoken individuals. I look forward to future opportunities to learn at the foot of Diogenes.

    About the Author / Orlee Berlove

    orlee_berloveOrlee Berlove is the Marketing director at OnPage Corporation located in Waltham, Massachusetts. OnPage is a cloud base incident alert and management system that elevates notifications so they continue to “ALERT-UNTIL-READ” so it’s not confused with email, SMS or phone calls. Incidents can be programmed to arrive to the person On-Call and can be escalated if they are not attended to promptly. Follow OnPage on Twitter and LinkedIn.
  • Private Practice: Encryption Exposed

    Private Practice: Encryption Exposed

    In September 2014, Apple made encryption a default with the introduction of the iPhone 6. Then, in February 2016, a Los Angeles judge issued an order to force Apple to help break into the encrypted iPhone belonging to a terrorist involved in a mass shooting.

    Apple had used some of the strongest encryption technologies and practices to protect its users and their data. The encryption technology did not discriminate between lawful and unlawful users. While there were many sides to this issue, it surfaced many important debates on security, privacy and civil rights.

    Peekaboo

    For developers wanting to add cryptographic libraries to their applications, a number of open-source components are available to them. Of course, anyone seeking to add encryption to an application has an important requirement for the privacy and security it provides.

    One of the more popular choices for encryption is known as the Legion of Bouncy Castle Java Cryptography library. According to the “2016 State of the Software Supply Chain” report, records reveal that 17.4 million Bouncy Castle components across all versions were downloaded last year. Of these, 5.8 million (33 percent) were known vulnerable versions of Bouncy Castle.

    peekabo

    It’s a sobering fact, but it’s true. Last year alone, organizations downloaded vulnerable versions of the Bouncy Castle cryptography library 5.8 million times. The defective components downloads occurred across 93,253 unique IP addresses from 13,824 organizations in 197 countries.

    Think Different

    Think about it. The Bouncy Castle project is developed by experts in cryptography. Occasionally, their crypto library is discovered to have a flaw and the project owners rapidly fix and release a new version. If you use the latest versions without known vulnerabilities, your application, your users and your data are protected. If you use the versions that include known vulnerabilities, you have electively declined those protections.

    Two of the critical principles of using open-source components are to use the highest quality components and to select them from the best suppliers. In this case, the Bouncy Castle project does an excellent job of releasing new and improved versions. While flawed versions are still available, those seeking to protect applications, users and data need to use the highest quality versions.

    Which Version Are You Using?

    Determining which versions of Bouncy Castle or any other open-source component you are using is simple. A number of free and paid services are available to help you analyze your application and report a full list of the components, including dependencies, that are used.

    Some of the free services require you to upload your application for analysis while other services are performed on-premises. One example of a free on-premises tool used to create a software Bill of Materials is the Application Health Check app from Sonatype. Another example is the OWASP Dependency Check app. Precision of these tools may vary, but regardless of the tool you use, you should use one.

    More insights on the quality, security, and integrity of open source components used to build modern applications can be found in the “2016 State of the Software Supply Chain” report.

  • DevOps: Achieving Process Without Too Much ‘Process’

    DevOps: Achieving Process Without Too Much ‘Process’

    While there’s no fundamental conflict between IT service management (ITSM) and DevOps, DevOps does bring new and different techniques for getting work done and interacting with the rest of the organization.

    ITSM people who are used to frameworks such as ITIL and COBIT tend to regard the IT department as a “service provider” and the rest of the organization as “the customer.” But DevOps has come from web-scale organizations “where IT is the business,” and that means the prevailing view is more like the Toyota Production System mentality, wherein the aim is to move things along a production line with maximum speed and maximum quality, says Matt Hooper, product evangelist at LANDESK.

    DevOps thus has already broken down some of the barriers between “IT” and “business”—practitioners realize they have to determine what the business needs, and then provide it. But Agile or Agile-like practices also are part of this approach, so there’s lots of experimentation, learning and redeployment in “lots of tiny little steps,” and, consequently, there’s not much risk of going very far wrong with any of them.

    An issue is that this conflicts with ITSM’s view of life cycles, partly because the whole idea is to merge development and operations—for instance, by automatically spinning up software-defined infrastructure as needed.

    What’s needed, Hooper suggests, is “service management with a digital mindset” rather than ITIL’s “human mindset.” It’s all about feedback, he says, but for ITSM and DevOps to sit comfortably together there must be a realization that feedback can come from humans or systems.

    And even though the command and control mindset tried to avoid failures, systems still failed. So a better approach is to accept that “stuff breaks” and make small changes at a time, respond to issues as they arise and keep learning. In the longer term, this will lead to more durable systems, he says.

    It’s a myth that you’ll be able to stop bad things happening, because people and systems aren’t perfect. DevOps, in contrast, accepts that things will go wrong but aims to respond quickly—for example, by keeping developers close to operations so they can see problems occurring, realize what mistakes they made, and put them right.

    “That’s challenging to a traditional ITSM person,” Hooper says. It is important to accept that failure is an option, even though massive failure isn’t.

    (Before you ask, he accepts that certain systems need to be extremely reliable. But others provide room for a somewhat experimental approach, in which case DevOps helps avoid overengineering.)

    While some ITIL practitioners see value in DevOps’ continuous deployment approach, their premise is still that IT is a “service provider” rather than a “partner,” but the business side of the organization wants the latter. You don’t get home from a business trip and tell your spouse you were 99.98 percent faithful while you were away, he observes, and that sort of SLA-based thinking works against becoming a learning organization, achieving good demand management and so on.

    ITIL v2 served a good purpose, but ITIL v3 arrived too late, Hooper suggests. The growing influence of the Lean movement means systems are going through rapid change cycles, and too much “process” leads to waste and lower performance. DevOps and software-defined technologies provide ways to better handle rapid change—infrastructure can be spun up and back down in seconds, providing opportunities for self-healing systems with better scalability and reliability.

    Where ITIL focuses on meetings and human processes, DevOps prefers to use analytics to determine the right time to release and then whether then release was successful. “The feedback loop is an essential part of DevOps strategy,” just as it is with ITIL, but ITIL has a more human-centric idea of feedback.

    “ITSMers tend to hide in the back closet” waiting for the business to tell them what to do, but DevOps takes a more active approach, he suggests.

  • Let’s Talk About Ops: An ITSM Crowd Special

    Let’s Talk About Ops: An ITSM Crowd Special

    The ITSM Crowd is a regular hangout hosted by DevOps training provider ITSM Zone that covers many different IT and management topics. On Aug. 11, host Claire Agutter was joined by IT Skeptic Rob England and James Gander from Gander Service Management to take a deeper dive into the impact that DevOps is having on operational roles.

    Gander comes from an operational background and wanted to discuss how the role of ops is changing, and England works with many clients who are evolving to work in more agile ways, embracing DevOps principles.

    DevOps Needs Ops

    All agreed that DevOps doesn’t mean No-Ops.  The traditional “build” and “run” phases are no longer clearly demarcated. Dev will work with Ops to improve and fix live services, and Ops will provide Dev with feedback that will help them to improve.

    Ops also needs to embrace the role of “toolsmith” or “toolmaker.” It can support Dev by creating environments that make it easy for Dev to do its job. This could include providing fast, automated access to virtual servers or providing input on monitoring and event management.

    Elements of Ops such as the service desk are essential and will never disappear. Customers always will need to be able to contact IT, so this part of the operational role will be present in some form, perhaps moving toward a greater focus on self-service.

    Ops Processes Won’t Disappear

    Traditional operations processes also still have a place. Change management, for example, is still essential, but it needs to “get out of the way” and enable change to happen, rather than acting as a barrier.

    Ops staff need to treat DevOps as an opportunity to learn and improve, not as something to be resisted. There are many great blogs to get started with, and this is an exciting time to be working in IT.

    You can view the video here, and I’d love to get your feedback and comments on how you think DevOps is changing the role of operations.


  • What the Auto Industry Can Teach IT Development

    What the Auto Industry Can Teach IT Development

    The latest and greatest advances in technology often draw the spotlight, but the truly great changes in business aren’t driven by technology alone. They’re enabled by a change in culture that’s supported and accelerated by technology.

    Consider the assembly line in the auto industry. Automation, specialized tooling and robotics have provided a boost to quality and efficiency, but these advances only mattered because of a change in U.S. culture that emphasized speed, acceleration and economies of scale. Henry Ford capitalized on these cultural constructs to implement an innovative set of tools that revolutionized auto production. Toyota led the next evolution in auto manufacturing with its implementation of the Andon cord and Kaizen continuous improvement (CI) but similarly, these tools depend on a culture of trust and respect for the workers to be useful.

    In the field of software development, a similar shift is taking place through the DevOps movement that’s leading to faster, more efficient and higher quality application development. Technology has made DevOps easier to implement, but these new tools only add value when they are accompanied or even implemented via a change in culture across the entire organization and all technology areas. This includes items such as visualizing the delivery value stream to identify areas for improvement, increased trust and collaboration across silos and a CI mindset.

    A key aspect of DevOps is automation, and automation is only possible when patterns can be created, which requires eliminating any variances in practices and capabilities in all aspects of the organizations that don’t add value. For example, if every application is a snowflake in terms of its architecture and configuration, infrastructure automation won’t be possible. If release planning, management and deployment don’t have standard work associated with them, then again, an integrated delivery pipeline capability cannot be implemented.

    Nationwide’s Journey to DevOps

    At Nationwide, we began a change in how we developed applications almost a decade ago. At the time, the term was “agile.” We shifted application development to focus on smaller iterations of work with automated build and testing practices. While this proved valuable, we realized this was only part of the journey of accelerating our lead time from customer concept through delivery of business value.

    We started the journey to implement a Lean-based DevOps model that encompasses the entire development value stream, from the incoming business request to application deployment and monitoring. Our goal was to work more closely with the business units to continuously plan, design, develop, test and deploy incremental improvements in our application-based products.

    Nationwide has seen demonstrable benefits on this journey. Critical defects have declined by 80 percent, system availability is up 70 percent and on-time delivery of applications has risen to 90 percent from 60 percent. More importantly, we’re starting to see results in our business as we refine our ability to test business hypotheses and measure the results in terms of increased revenues.

    Infrastructure to Support the Cultural Shift

    Just as Ford’s auto assembly line utilized advanced technology to be successful (e.g. electricity enabled optimal placement of machines versus steam power), accelerated delivery is utilizing the development of new technologies. To advance DevOps, we use IBM Rational and UrbanCode software to manage and deploy applications. The new technology, though, has only worked because we have committed to both a technology and cultural change across our entire organization. We have more than 5,000 IT professionals on 200 different teams. Every team—whether it’s responsible for the mainframe, distributed, web or mobile— needs to utilize the same standard work approach to application development.

    Let me give you one example of how that works: Biweekly show-and-tells are a core part of our approach. For new mobile applications, the changes after two weeks might be dramatic, but even for the larger applications running on our IBM z Systems mainframes, the teams have something to share. They break the mainframe application work into smaller units and demonstrate updates they’ve made that fit into more long-term initiatives.

    The Autobahn for Application Development

    While applications and products are not all developed at the same speed (e.g. a change to a mobile app versus a regulated change to back-end banking system), there is a need for these systems to utilize similar approaches and a common delivery pipeline with visibility of dependent changes, to be implemented as quickly as possible.

    An example of this is a highway like the Autobahn accommodating different types of drivers and vehicles, such as a Porsche built for speed and a semi-truck built to carry cargo. The rules of the highway allow vehicles to drive at different speeds safely without having stoplights by providing exit and entrance ramps, speed limit minimums and visibility of other vehicles along with “standard rules of the road.”

    Likewise, we want our IT delivery capability to accommodate variable speeds of IT based on the business needs and the development teams’ abilities to go faster by implementing practices such as smaller batch sizes, APIs and microservices, feature flags and performing automated testing and readiness validation. While distributed and mobile applications might be the Porsches on the road, they can only go as fast as the mainframe and legacy applications, or semi-trucks and other traffic will allow.

    Consequences of Resisting Change

    No company will get through the next decade without being disrupted, either externally or internally via a continuous improvement and innovation mindset.  Those that embrace Lean and DevOps practices across the entire IT organization will have a steady stream of new services and improvements that outpaces the competition and transforms their business. Those who don’t will join former Fortune 500 companies that waited too long to realize that their competitor’s Porsches and semi-trucks were too far along to catch up with.

    About the Authors / Carmen DeArdo and Jason Patterson

    Carmen-DeArdo-sqCarmen DeArdo is the director of Build Technologies at Nationwide Insurance. He is responsible for helping drive accelerated delivery utilizing Lean and DevOps techniques across the end-to-end delivery value stream.  One current focus area is the creation of an integrated delivery pipeline capability.


    Jason PattersonJason Patterson is a Lean and Agile coach at Nationwide Insurance. He works with development and support teams across the company to help recognize process gaps and opportunities in their delivery stream. His background in development fuels that energy, while he resists the urge to automate every broken or unnecessary process. After nearly a decade at Nationwide and seven years experimenting with extreme programming, scrum and agile methods in a software development department at Indiana University, Jason is still learning.

  • The ‘Continuous’ Illusion

    The ‘Continuous’ Illusion

    Continuous delivery is an illusion. That doesn’t make it insubstantial—illusions can have a tremendous impact. Like the first motion picture: the locomotive felt so real to first audiences that they fell from their chairs, screaming. But of course, the locomotive was an illusion, merely rushing past on screen.

    A good magician, like a good inventor, will tell you that the secret to a powerful illusion is hard work on top of a good idea. Indeed, good magicians and inspired technologists have a lot in common. Each is always on the hunt for the next big insight, the transformative angle, building on existing industry techniques to create something even greater. But each knows the secret to truly wowing their audience, whether for a one-night-only show, or an ongoing relationship. What really gets the job done is the vast, complicated, hard-won machinery ticking away behind the scenes.

    Today’s No. 1 magic trick for making great applications, a directive now pervasive across every industry, is continuous delivery. Right now, continuous delivery provides that wow. It takes app updates from a customer stumbling block to a seamless benefit. It takes feature delivery from “maybe in a year” to “is tomorrow soon enough?” It allows Dev teams to wave their magic wands and transform the impossible into the effortless.

    And, of course, continuous delivery is an illusion. Remember that movie locomotive, leaping out of the screen? Every instant of its motion was its own little frame of celluloid. And the true magic was the process that bound each and every frame together, delivering them onto the screen with perfect timing.

    Continuous delivery is the very same sort of illusion. The steady stream of new features, new capabilities and bug fixes must be created one by one by a vast army of talented developers—not unlike the thousands of talented stencilers who first brought color to motion pictures. And the true heart of the process is the automated systems that support this army, and which ensure the coordinated delivery of its products to the end user.

    The heart of continuous delivery is the machinery of automated testing and deployment. The approach behind continuous delivery encourages teams to produce software in short cycles, ensuring that the software can be reliably released at any time. For these releases to be reliable, continuous testing is integrated into the software delivery pipeline, for immediate feedback on any bugs an update would generate. Then, when a proposed change has passed the automated tests, it is deployed to production automatically. This software development life cycle (SDLC) allows companies to achieve the business goal of truly responsive development. The team sees an opportunity, confirms the solution and then delivers that solution to customers extremely rapidly.

    Each stage of continuous delivery—develop, test, deploy—has its own technical challenges, but the testing step in particular poses a unique bottleneck.

    In the development stage, developers primarily require code. Code is relatively lightweight, and can be managed through industry-standard tools such as Github. Developers need their laptops, but in general code management poses a limited operations support challenge.

    The deployment stage can be more challenging for ops. The newest version of the code must be deployed to a wide population of final platforms, which may vary in hardware, software, location, permissions and so on. However, the target systems are at least those in ordinary use. The server the new page runs on or the smartphone that installs the application update are pre-existing systems, and they are managed by their users. So Ops teams are not required to support specialized hardware to deploy. Furthermore, in the past few years a number of innovative technologies, such as Ansible and Docker, have emerged to simplify this process further.

    Testing, on the other hand, combines the challenges of both of these stages. Continuous testing requires dedicated resources for developers and QA. But these resources are full-scale application environments, including not just code but data, operating systems and even appropriate hardware. And because best practices encourage developers to write new tests for all new code, the amount of regression testing required for every code change can only grow. That means that testing must grow ever more parallel, or suffer increasing delays—and any delay in testing can undermine overall continuous delivery.

    To preserve the Continuous Illusion, a development team needs on-demand access to scalable testing environments, including their data. Data in particular is often overlooked in test environment creation, but it must be delivered to every test instance. That means test data management (TDM) is an inescapable part of any successful continuous strategy.

    TDM is relatively self-explanatory: it refers to the process of creating, managing and delivering production (or production-like) data to non-production data environments. Every organization does some TDM, though many do not consider it a separate practice. But to achieve the sort of seamless efficiency that can support the Continuous Illusion, teams must adopt a modern TDM practice.

    Legacy TDM relies on multi-stage, manual delivery chains. Developers and testers file tickets, and then they wait. Storage admins, DBAs, backup admins, security personnel and other staff each have to spend a huge portion of their time servicing the ever-growing stream of tickets, handing off environment creation from one function to another. Meanwhile, developers and testers are left in the lurch, and continuous delivery grinds to a halt.

    Once, this process might have been unfortunate but necessary, imposed by technological restrictions. But modern solutions can tackle these challenges and overcome them. Too often, teams with poor TDM have simply neglected to implement the solutions that they need.

    The most effective TDM practices will use a data management solution on par with other continuous delivery pipeline tools. The TDM solution will be able to stand up data environments in minutes and at massively parallel scale. It will rely on production data and automatic security, rather than synthetic data generation or data subsets (both of which requires substantial upfront planning and cannot hit the full suite of edge cases). It will integrate readily with existing continuous delivery workflow tools, allowing data to be automatically provided whenever a test job runs.

    There are some solutions in the market today that meet these criteria. Adopting one can represent your opportunity to tighten test cycles and deliver code faster—regardless of how fast your software timelines are today.

    To deliver the Continuous Illusion, every component of the continuous delivery pipeline must be operating at peak efficiency. A powerful TDM solution is a key requirement for allowing your customers to sit back, relax, and enjoy the magic of your product.

    About the Author / Louis Evans

    Louis Evans HeadshotLouis Evans is a DevOps evangelist with Delphix. He’s excited about the potential for superior TDM to enhance overall software quality. He is a huge Alan Turing fan, and partial to a well-placed semicolon.

  • 4 n00b MySQL Mistakes Every Programmer Makes

    4 n00b MySQL Mistakes Every Programmer Makes

    Even experienced programmers can sometimes be thrown for an infinite loop–or other code failure–with these common MySQL mistakes.

    When a database application goes belly up, the cause often can be traced to sloppy coding. Every now and then, the reason for a misbehaving app is an idiosyncrasy in the platform itself. Here’s how to prevent your database from tripping over one of these common MySQL mistakes.

    Handling Numeric Value Overflows

    In an Aug. 11, 2014, article in the Database Journal, Rob Gravelle describes a “gotcha” (not a bug) in the way MySQL handles numeric value overflows. When a value supplied by an automated script or application is outside the range of a column data type, MySQL truncates the value to an entry within the acceptable range.

    Generally, a database system will respond to an invalid value by generating an error instructing the script to proceed or abort, or it will substitute the invalid error with its best guess as to which valid entry was intended. Of course, truncating or substituting the entered value is almost certainly going to introduce an error into the table. Gravelle explains how to override MySQL’s default handling of overflow conditions to ensure it generates an error, which is the standard response to invalid entries in most other databases.

    Misuse of Primary Keys

    According to Justin James on the Tech Republic site, the most common database programming no-no is the misuse of primary keys.

    MySQL-Mistakes

    James insists that primary keys should have nothing at all to do with the application data in a row. If they’re not system values managed by the system, you’re likely to encounter problems when you change the underlying data or migrate the data to another system.

    Using Stored Procedures as a Crutch

    Another frequent cause of program problems is overuse of stored procedures, which James describes as a “maintenance disaster.” There’s no easy way to determine which applications are using a particular stored procedure, so you end up writing a new one when you make a significant change to an app rather than adapting an existing stored procedure. Instead, James recommends that you use advanced object-relational mappers (ORMs).

    Not every developer is sold on ORMs, however. On his Experimental Thoughts blog, Jeff Davis explains why he shies away from ORMs. Because ORMs add more lines of code between the application and the data, they invite more semantic errors. Davis points out that debugging in SQL is simpler when you can query the database as if you were an application. The more lines of code between the application error and the database, the more difficult it is to find the glitch.

    Overuse of BIGINT

    One of the common database errors identified by Thomas Larock on the SQL Rockstar site is playing it safe by overusing the BIGINT data type. If you’re certain no value in a column will exceed 100,000, there’s no need to use the 8-byte BIGINT data type when the 4-byte INT data type will suffice. You may not think a mere 4 bytes is significant, but what if the table ends up with 2 million rows? Then your app is wasting 7.8MB of storage. Similarly, if you know you won’t need calendar dates before the year 1900 or after 2079, using SMALLDATETIME will make our app much more efficient.

    Misuse of GUIDs

    On the SQL Skills site, Kimberly Tripp highlights another common database design error: use of non-sequential globally unique identifiers, or GUIDs. In addition to creating fragmentation in the base table, non-sequential GUIDs are four times wider than an INT-based identity.

    Is your app’s failure to launch due to poor typing skills?

    Maybe the best way to start your hunt for a coding error is via a printout rather than with a debugger. That’s the advice of fpweb.net’s tutorial on troubleshooting SQL errors. The problem could be due to a missing single quote mark, or misuse of double quotes inside a string. If you get the “No value given for one or more required parameters” error message, make sure your column and table names are spelled correctly

    Likewise, if the error states “Data type mismatch in criteria expression,” you may have inserted letters or symbols in a column set for numeric values only (or vice versa). The FromDual site provides a complete list of MySQL error codes and messages, including explanations for many of the codes, possible sources for the errors, and instructions for correcting many of the errors.

    MySQL Error Codes

    The FromDual site explains how to find sources of information about MySQL error messages.

    MySQL error message

    For many of the MySQL error messages, the FromDual index provides an explanation, reasons for the error message’s appearance, and potential fixes.

    With a little work and a lot of sticky notes, these common MySQL mistakes are fairly easy fixes. There’s nothing worse than looking like a nOObie programmer and damaging the integrity of your application. So stay sharp, and take a second look at your MySQL queries.

  • Why Your Organization Needs DevOps

    Why Your Organization Needs DevOps

    The recently released fifth annual “State of DevOps Report” by Puppet has once again brought with it fresh insights into what drives high-performance teams. The report, which comes at a time when DevOps has ceased to be a buzzword, provides proof of why more and more businesses across the world are adopting DevOps to improve their organization’s performance, revenues and profitability. DevOps has truly come of age and this year’s “State of DevOps Report” clears any doubts fence-sitters may have about the effectiveness of the DevOps approach.

    The 2016 report reasserts that unparalleled IT and organizational performance is a result of a team effort spanning development and operations. The report also highlights the importance of improving the entire product life cycle—from initial product planning, to quality and security assurance, to customer feedback—to speed up delivery while improving quality, security and business outcomes. You can read the full report here.

    In today’s competitive business environment, DevOps has emerged as a vital solution that helps organizations meet ever-growing industry demands. The “2016 State of DevOps Report” helps us understand how the practices associated with DevOps affect IT performance and organizational performance. Let us examine the findings of the report to ascertain how DevOps can benefit your organization.

    Why Does Your Organization Need DevOps?

    The “2016 State of DevOps Report” makes it plain and simple that companies that incorporate DevOps practices get more done. According to the report, high-performing IT organizations deploy 200 times more frequently than low performers, with 2,555 times faster lead times. They have 24 times faster recovery times and three times lower change failure rates. High-performing IT teams spend 50 percent less time remediating security issues and they spend 22 percent less time on unplanned work and rework, the report states.

    Performance

    If we boil down the report findings into actual benefits of adopting DevOps, we could say that DevOps enables continuous software delivery with less complex problems to fix and faster resolution of problems. This essentially means that you can deploy faster and more effectively in more stable operating environments and add value rather than just fixing or maintaining.

    DevOps can revolutionize the performance levels of organizations and allow them to deploy at a rate never seen before. It has certainly enabled organizations such as Etsy, Netflix, Facebook, Amazon, Twitter and Google deploy hundreds and thousands of code per day while delivering world-class stability, reliability and security. You can find out how different organizations have implemented DevOps to their benefit in this YouTube video.

    Security

    Higher performance is not the only payoff in the DevOps culture. Organizations that adopt DevOps practices are known to have better information security. The “2016 State of DevOps Report” clearly states that organizations that integrate information security objectives into daily work spend 50 percent less time remediating security issues than low performers. This has a positive impact on IT performance and security outcomes.

    Any organization, irrespective of size, can employ DevOps to achieve high performance levels and meet business goals while cutting down on costs related to fixes and remediation security issues.

    How DevOps Transforms Teams

    Consider this scenario: In an organization that does not apply the DevOps methodology, the development team writes code and develops a product, which is then sent to the testing team that verifies if the code meets the requirements. The operations team steps in to run the product only after this process is complete. The DevOps philosophy was created to break the silos that teams operate in and effect better collaboration and performance.

    The culture shift DevOps brings about in organizations is substantial, and since culture is a key factor responsible for a company’s performance, application of the DevOps philosophy provides measurable and non-measurable results. A few of them are:

    Employee Engagement

    DevOps is neither a method nor a tool, it’s a culture! In organizations that observe the DevOps culture, the development and operations teams work outside silos, releasing products faster, thereby increasing operational efficiency. This is made possible by the operations team giving the developers constant feedback about the code and troubleshooting problems with the user experience in mind. This continuous learning and delivery practice allows cross-functional teams collaborate as one team with one goal, thus facilitating higher performance levels. The improved organizational culture and enhanced employee engagement can help organizations not only in retaining great talent but also in recruitment.

    Organizational Success

    The “2016 State of DevOps Report” effectively explores the relationship between employee engagement and organizational success and goes on to show that there is a strong correlation between these two factors. The report states that employees in high-performing organizations are more than twice as likely to recommend their organization to a friend as a great place to work.

    Organizations can greatly benefit from adopting the DevOps culture. The “2016 State of DevOps Report” shows that high-performing organizations are widening their lead against lower-performing organizations. This can be attributed to the increased productivity and creativity of highly engaged employees that helps them provide better experiences to customers.

    Organizations can achieve great business results by reinvesting the human time, creativity and energy saved by reducing rework and downtime through DevOps. Herein lies the ROI of DevOps—the competitive advantage that organizations get by investing in a philosophy that positively affects bottom-line results!

    About the Author/ Pallavi Poojary

    Pallavi Poojary1Pallavi Poojaryis a writer with Edureka, an online learning company with more than 250,000 learners spread across the globe. She writes on hot technologies and skills that are in demand today, including DevOps, Big Data and Project Management, to name a few. She is a believer in transformation of careers through learning
  • Pokémon Go Shows DevOps Changes Human Behavior

    Pokémon Go Shows DevOps Changes Human Behavior

    Everywhere you go lately, you can see people acting strangely. They’re walking streets they never walked before. They’re waving their smartphones around in odd ways. And they’re high-fiving each other for no apparent reason.

    And they’re doing it because of DevOps.

    Of course, not everyone immediately thinks about Pokémon Go as an artifact of DevOps—but that’s what it is. It is code written, continuously modified and continuously promoted to production based on changes in workload performance and user feedback, implicit and explicit. It is also the most downloaded app on iTunes ever.

    More importantly, Pokémon Go is visibly changing human behavior. That’s something worth considering as organizations seek to survive and thrive in the application economy.

    Doing Things Differently vs. Doing Different Things

    Most development is done so that customers or employees can do things differently. There are lots of apps that make shopping easier or deliver better analytic insight for decision-making. And those apps certainly provide business value by removing obstacles to revenue or by helping companies optimize allocation of resources.

    image003_v1But Pokémon Go doesn’t merely allow people to do something differently. It drives them to do something entirely different—location-based and augmented reality gaming.

    Pokémon Go isn’t the first or only app that changes human behavior. Uber and Zipcar changes how we get from place to place. Square changes how we do retail. Pokémon Go, however, is an especially dramatic manifestation of how apps change behaviors. People are doing something they’ve never done before because of some software—and because that software “went viral.”

    That’s an important concept to bear in mind as organizations seek to optimize the effectiveness with which they leverage technology in their businesses. Are you just trying to write apps that help your users do something a little better? Or can your apps enable and inspire entirely new behaviors that people will find worth embracing—and therefore will also promote across their social networks?

    The Role of DevOps

    DevOps is central to this endeavor in several ways. First, when you’re doing something new, you by definition don’t know what you’re doing. So you have to keep going through cycles of testing to get things right. If those cycles are slow and you don’t take the time to test all possible use cases—such as geolocations, devices, operating systems, hardware, diverse transaction, etc.—because you have trouble putting the right test data together or it takes too long to provision the necessary environments, you will either be late to market or release something nobody likes.

    To avoid these types of pitfalls, you need a streamlined and automated end-to-end DevOps pipeline that optimizes your delivery value chain and eliminates constraints and dependencies across the software development life cycle. Implementing this type of continuous delivery tool chain will allow your DevOps teams to continually improve the quality of your applications in a shorter time frame.

    Second, even once you get things right, they won’t stay right for long. The folks at Niantic were most certainly surprised by just how viral their app went, so they had to scramble to overcome performance issues in the field. They also are dealing with some negative feedback from true Pokémon aficionados who are not so smitten with how gameplay diverges from their long-beloved Nintendo brand.

    Niantic’s ability to keep riding its initial viral download success will be closely tied to its ability to address these issues. And that’s also best done with an automated DevOps process—along with Agile disciplines—that allow the company to keep refining both its code and the way that code runs in production and ensuring the performance of the IT infrastructure that supports the user experience of the app.

    Luring the Wild ‘Customon’

    Perhaps the most powerful lesson from Pokémon Go isn’t for developers. It’s for business leaders. Unfortunately, many non-IT executives still view DevOps and related investments in digital capability as an operational issue for technologists—rather than as an existential issue for the business itself.

    But it is decidedly the latter. Pokémon Go isn’t just about having a good idea for a game—any more than Dollar Shave Club, which Unilever just bought for $1 billion—it’s about having a good idea for a company. You have to be able to execute. And in the application economy, you can’t have execution with speed and quality without DevOps.

    So if you’re still struggling to get upper management to invest in funding your DevOps initiative, maybe it’s time to put away the PowerPoints and pull out the Pokémon instead. We’ve rarely had a more dramatic example of how applications can impact human behavior—and how the ability to get code into production quickly and successfully can impact your business.

    About the Author / Aruna Ravichandran

    Aruna_CAAruna Ravichandran is vice president of DevOps Solution Marketing and Management at CA Technologies, responsible for cross-portfolio solution marketing for DevOps across the Application Performance Management, Infrastructure Management and Continuous Delivery product lines. Before joining CA Technologies, Aruna held several management positions in product marketing and engineering at Juniper Networks and HP. Aruna earned an MBA and master’s degree in Computer Engineering from Santa Clara University and holds a Bachelor of Science degree in computer science from Bangalore Institute of Technology.