Tag: dba

  • Database Observability: How to Circumvent your Weakest Link

    Database Observability: How to Circumvent your Weakest Link

    Today, IT pros field an increasing number of assets they need to monitor to secure systems and understand what’s happening in their database and applications. This is further complicated as organizations adopt hybrid IT strategies and IT pros are tasked with managing tech stacks that span across on-premises and public clouds. 

    To cut through complexity and create end-to-end visibility into their IT systems, organizations must enact an observability approach.

    Monitoring Vs. Observability

    When it comes to observability, many think it means the same as monitoring. Whereas monitoring is a verb; observability is a measure of how well the internal states and conditions of a system can be inferred from its external outputs. 

    When monitoring systems are set up, dashboards are built around certain assumptions that an IT pro may expect will happen. When monitoring databases, teams are building multi-level component IP systems. The algorithms must process that data, and the user interface must interact with it. 

    However, to make that system highly observable, performance information and other kinds of metrics across all kinds of different endpoints must be incorporated. Especially since IT pros must deal with microservices, mesh, IoT or containers orchestrated through Kubernetes.

    How to Monitor Effectively 

    In the past, IT pros would typically monitor a SQL Server or even other database platforms like PostgreSQL or MySQL. In this new era of observability, on the other hand, IT pros need to do something different with the front-end code with regard to the different kinds of algorithms processed against that data set. Typically, developer teams would write the code, but there wasn’t anything written in that code to send out debug signals.

    Today that has changed. To make sure our systems are fully observable (because we can’t anticipate all possible problems!), we must log different steps to keep track of the many moving pieces. Organizations must collect as much of everything as possible. The more data, the more information organizations have about what’s happening in their application, from the database through the virtualization or containerization layer to the virtualization host or the orchestration to the bare metal. If organizations can get visibility into those elements, we can enable our systems to be fully observable and more easily diagnose any problem or anomaly that happens.

    An Observability Approach

    When using the observability approach, high-level dashboards are handy. They can help IT pros roll up everything that’s happening and get to a root cause analysis if there is a problem. However, sometimes there’s not a specific problem; there’s just a general performance issue. With observability platforms, teams can quickly discover, map and understand dependencies in ways that make it easier to achieve and maintain service level objectives (SLOs). 

    As IT teams increasingly distinguish between merely monitoring IT environments and achieving observability, they can proactively surface anomalies using machine learning algorithms and other forms of data science. And the depth and insight that can be applied to managing IT is increasing dramatically. Observability is quickly becoming table stakes for any modern IT organization. 

  • DevOps: Role Clarity is Important

    DevOps: Role Clarity is Important

    Those who talk a lot about DevOps, particularly those who talk a lot about culture change, sometimes gloss over or “think it is obvious” that some roles change more than others when moving from Dev and Ops to DevOps.

    I was having a lighthearted chat with a friend who works for Compuware and realized that, even though several of us have mentioned it before, it bears repeating for those who have not yet dipped their toe into the DevOps pool too deeply.

    The driver for DevOps is increased agility, and the belief is that Dev and Ops will merge. What is often left unclear is that they may well merge into one team, but every team member will not become an expert at every role. Pundits seem to think this self-evident. I’m not so certain it is, if you read a lot about DevOps.

    By way of example, your Cisco ACI specialist (or ios specialist) will not suddenly become an expert in the intricacies of your development toolset and environment so they can contribute code. Granted, that is an extreme example, but there are two reasons why someone is a specialist in what they do: 1. They know/prefer it, and 2. The company had a need for their specialty. Don’t lose sight of those facts while moving to DevOps.

    A better example is DBAs. They’re not going to become network engineers just because they were put on a DevOps team. They’re still going to be DBAs … because you need DBAs. You need network engineers also, but if you need them, you already have them.

    Remember that increased communications and increased latitude are the social aspects of DevOps. The DBA is still a DBA, but faster access to queries and those people writing the queries means more optimization of some of the busiest sections of code. If your EMC specialist has access to the entire team, conversations along the lines of, “We’re running low on disk on LUN X, and it will cost us a billion dollars to upgrade, what are our options?” can happen quickly and include views from across the DevOps team (normally across the application or application portfolio).

    One of the most thankless jobs in IT is being the single/small shop. Anyone who has been IT for an entire org—particularly one with in-house apps—knows the struggle. My time as a developer hired to work on list serv software but who also inherited the entirety of systems administration (the sys admin quit and changed all the root passwords the day before I started) was not optimal. I learned a ton, which was cool, and I never mastered most of it, which was not.

    The goal of DevOps is not to re-create that environment in a team. It is to optimize team interaction, and make things go more smoothly. Make sure you are not on an implementation plan that leads to burnout or lack of accountability. Keep your eye on the real prize: increased responsiveness to business needs.

    And as always, keep kicking it. I have yet to walk into an environment that wasn’t unique, or one that didn’t have cool stuff to learn about. And you keep that running.

    — Don Macvittie

  • Of DevOps, Databases and DBAs

    Of DevOps, Databases and DBAs

    If you’re on a DevOps team looking for additional efficiencies, you are likely to find them in the realm of database management. The arrival of DevOps did nothing to diminish the responsibilities traditionally associated with database administrators (DBAs). Rather, some of those duties have been redistributed across the team—sometimes explicitly, but more often implicitly. For example, site reliability engineers (SREs) and even full-stack engineers have taken on many of the responsibilities that once belonged to DBAs. And in these roles, DBAs often hold the keys to unlocking a new dimension of efficiency through consistency, repeatability and operational efficiency.

    Enter the “DevOps DBA.” This confluence of roles makes a lot of sense. As with application DevOps, it’s logical to assume that the person who architected the platform and wrote the database code also should have a role in deploying and operating it. DBAs manage every aspect of data infrastructure, from capacity planning, installation, configuration, database design and migration to operational duties such as performance monitoring, security and troubleshooting, as well as backup and data recovery. As a result, the DBA’s responsibility for maintaining existing workloads sometimes conflicts with the need to plan and provision workloads for the next generation of applications. Reconciling these responsibilities can speed up the software development life cycle as a whole.

    On the operational side, DBAs are responsible for monitoring database behavior under peak application workloads, ensuring they’re performing according to expectations, and working with Operations to resolve bottlenecks and outages. They manage data access and the overall security of the platform. They also perform release activities in support of the application and troubleshoot any errors that happen during that process or during day-to-day operation.

    With all this in mind, we can propose a DevOps DBA checklist:

    • Establish a microservices plan with regard to data services.
    • Set up integration environments, and provision databases for new projects.
    • Dynamically extract, transform and load data from one silo to others, employing TTL strategies to reduce the data or enrich some of it.
    • Continuously monitor and optimize performance: Strive for low and consistent tail latency and a joint view of the app and the database.
    • Expert zone: Automate scale out and automate schema changes.
    • Backup and recovery: Backup to cold storage and restore.
    • Plan for downtime and high availability using multiple data center disaster recovery capabilities.

    Characteristics of a DevOps-friendly Database

    We’ve looked at some of the DBA responsibilities as they apply to DevOps. Now we’ll discuss some of the technical aspects of database technologies that can help, or hinder, this hybrid role. To keep up with applications as they migrate through lifecycle stages, there are a number of organizational and team cultural challenges to be addressed. It’s also important to remember that not all databases are created equal—some databases lend themselves more readily to the DevOps toolchain than others.

    It takes a combination of elements for a database to be DevOps-friendly. The ultimate goal is to minimize the fear of change by mitigating risk. Relational databases do not conform particularly well to modern software development practices, since changes to schemas can be time-consuming. NoSQL databases, in contrast, have proved to be more life cycle-friendly because they don’t impose rigid schema management during application development. Over time, however, this free-wheeling approach to data modeling can create headaches. The ideal database strikes a balance between strict schema enforcement and decentralized data-model changes.

    A key consideration for a DevOps-friendly database is operational simplicity. Traditional SQL databases, such as Postgres and MySQL, are well-understood and have lots of support, but can be difficult and expensive to scale. The rise of NoSQL databases enabled larger datasets to be managed in a more flexible and scalable manner than relational databases. But even among NoSQL databases, there are some significant differences. The first generation of NoSQL databases—in particular the widely adopted Apache Cassandra—can impose significant operational burdens in their own way.

    Additionally, modern cloud-native databases have their limits. They can be opaque to operators, and have been known to scale up and down unpredictably. Operators often lack visibility into the distribution of datasets. In many cases, cloud databases also prove to grow at a rate that’s disproportional to the workload supported by the database. Database instances can proliferate to the point where DevOps has to deal with “node sprawl.” You can think of this problem as the false promise of elastic scale, wherein the solution to increased traffic is, “Just add more nodes!” Lots of small nodes are not necessarily better than a few large ones. (For more on this, I’d encourage you to watch this talk on mythbusting the advantages of small nodes.) In any case, the biggest overall cost isn’t necessarily capacity, though that can be significant. The biggest cost, it turns out, is often administering all those nodes.

    Node sprawl can result from an overabundance of caution; overprovisioning is a natural response to scaling challenges. Look for a database architecture that uses resources efficiently and autonomously, ideally one that can dynamically tune itself according to varying workloads. An autonomous database monitors operations and adjusts internal processors to achieve a balance. Not only does an autonomous database greatly reduce administrative burden, it also means DevOps can always push the database to the limits of the underlying hardware resources, ensuring availability and SLA compliance. This again reduces the need to tailor database configurations and topologies to specific applications.

    Flexible deployment options are also important for DevOps. Who knows what your footprint will look like in 12 or 18 months? A database needs to be fairly agnostic as to topology on which it is deployed, whether that’s on-premises, a cloud platform or a hybrid configuration across both local and cloud environments. In some deployments, databases may be required to run across two different commercial cloud platforms—for example Azure and AWS—simultaneously. There are a couple of reasons for considering this: The first and more obvious is to maximize availability. Geographical outages are more common than you might expect. The second benefit are the financial advantages to the business using the hybrid framework, as it prevents infrastructure-as-a-service (IaaS) vendor lock-in, while also providing tax benefits for the on-premises expenses. Forward-thinking DevOps groups will keep these potential requirements in mind when designing data platforms today.

    Conclusion

    Trends in application development and IT infrastructure are pushing traditional DBAs into DevOps, while DevOps (including SREs and full-stack engineers) are often taking on responsibilities traditionally associated with the DBA. By adopting data infrastructure that emphasizes operational simplicity, ease of scale and deployment flexibility, IT organizations can more easily reconcile these roles while building a cloud-friendly infrastructure that extends the DevOps toolchain to the database.

    — Eyal Gutkind

  • Quest Software Aims to Mend DevOps Fences for DBAs

    Quest Software Aims to Mend DevOps Fences for DBAs

    It’s no secret there’s been a lot of contention between application developers, who are under pressure to build applications faster, and database administrators (DBAs), who are charged with providing those developers with access to data. Historically, developers have been dependent on DBAs to create schemas that would allow them to access data. But it takes time to build schemas, which is why many developers as of late have opted to employ a NoSQL database that don’t require a schema to access data. While that provides developers with some much-needed flexibility, most of the data stored in an enterprise today is still inside a relational database.

    To make it possible for DBAs to respond faster to developer demands, Quest Software has unveiled the Toad for DevOps toolkit, which makes it easier to include relational databases such as Oracle within a larger continuous integration/continuous development (CI/CD) process managed by frameworks such as Jenkins, Bamboo and Maven.

    Greg Davoll, executive director for product management and marketing for Quest database management solutions, notes the DBA traditionally has been the last holdout in embracing DevOps—DBAs didn’t really have access to tools that would enable them to participate in an agile development environment. The Toad for DevOps Toolkit address that issue by enabling them to test PL and SQL code during the application build process and ensure schema, data and database integrity with the context of a DevOps pipeline process, Davoll says, adding DBAs participating in a DevOps process can now also perform static code reviews and promote artifacts into a target environment to see how they perform in a production environment.

    The arrival of Toad for DevOps Toolkit is scheduled to coincide with the release of Toad for Oracle 2017 R2, which will add pass/fail status notifications within the Code Analysis code review process, a redesigned multi-schema compare and sync function, and an enhanced REST API as part of the Benchmark Factory testing tool to help automate performance testing within a CI/CD workflow. Over time, Quest Software will add similar capabilities across the full range of databases it supports, Davoll says. Quest Software just announced a Toad for MySQL offering to complement its existing support for Oracle and Postgres databases.

    Many of the decisions over the years concerning what database to employ have come down to which platform incurs the least amount of friction for developers to deploy. That hasn’t always resulted in the right database decision being made. In fact, it’s usually not too long before a developer wants to offload the management of the database back to the IT organization. Invariably, that results in DBAs having to manage multiple database platforms. While there may be a perfectly rational reason to employ something other than a relational database, that decision should be based on the attributes of the database rather than internal IT politics and purchasing processes. The challenge facing DBAs now is how to re-engage developers who have developed a bias against specific classes of databases, no matter how much critical data they may hold.

    — Mike Vizard

  • 5 Ways to Keep DBAs Happy, Alive and Efficient

    5 Ways to Keep DBAs Happy, Alive and Efficient

    As DevOps adoption continues to grow, organizations are competing to find the best and brightest application developers available. Meanwhile, database administrators (DBAs) are hard at work in the background to keep up with the burgeoning number of databases platforms developers deploy.

    DBAs have it rough. If developers are the James Bonds of the IT world, then DBAs are the Qs who quietly toil away to create the next big toy that Bond will destroy.

    The average DBA in a large enterprise can be tasked to manage 40 or more databases spread across various development stages. These disparate and sometimes rogue databases compete for the same compute and storage resources. Nearly all come with their own reporting and management tools. And when they break or fail, any number or combination of factors can be blamed.

    Database growth is especially difficult to control when companies such Amazon Web Services make it easy for any developer to create one. The AWS site, for example, provides just five easy steps to create a MongoDB database. Compare that to the time and work that goes into hiring, training and retaining more DBAs.

    Overloaded DBAs can overlook issues that lead to data loss or missed insights that affect revenue and productivity. If you can’t establish policies that control database growth, then think about ways to help your DBAs keep up and stay ahead of the game. Here are five possible tips:

    Focus and eliminate distractions

    DBAs can sometimes be lumped into general, overarching IT roles including help desk, backup and recovery or system upgrades. You probably wouldn’t want your developer to multitask, so why ask the DBA on the back end to do that? Give DBAs the opportunity to move beyond the firefighting role to focus more on proactively improving application performance. In the long run, this approach will eliminate fires before they occur.

    Give DBAs time to train on new databases

    By eliminating outside distractions, DBAs have more time to spread their knowledge across traditional databases including MySQL, Oracle or Microsoft SQL, and develop their expertise on more modern open-source databases such as Couchbase, Cassandra or PostgreSQL.

    Centralize monitoring tools

    The management tools that come with most databases provide a limited view of their broader environment. Centralized tools can provide visibility across the entire application stack. They show how databases interact with shared resources and unveil interdependent factors that lead to failures and performance issues. A centralized tool allows DBAs that “Monday morning coffee” view of all databases on one screen to determine which one needs the greatest or more immediate attention.

    Deputize your DBAs to enforce database policies

    Give your DBAs the power to evaluate and regulate new databases. This role is difficult to maintain if you confine DBAs to a traditional operations team. If databases can cross boundaries, so should your DBA. They should be empowered to seek out and evaluate databases that might be redundant, resource-intensive or unused. This means giving them the ability to say no to new databases unless they have a clear and compelling argument to be created. DBAs also deserve the authority to create a common set of goals, metrics and SLAs that must be met by all databases.

    Hire and treat your DBAs like rock stars

    It is becoming increasing more challenging to find and hire talented DBAs—especially the ones who can multitask across multiple database platforms. According to a survey in 2015, “The Vanishing Database Administrator,” more than 41 percent of database professionals surveyed said they intended to leave the data management field within the next 10 years. Possibly because of the impending shortage, the DBA profession is now seen as one of the hottest IT careers over the next several years. CNN Money ranks it as No. 9 in its 2017 Best Jobs in America. Employers should give particular consideration to these candidates and do everything they can to retain them.

    If you want your data to continue playing a central role in your business, give your DBAs as much recognition and credit as your developers. Behind every  developer, there’s a DBA keeping applications and data running at top speed. Remember Bond could never be successful with his Q.

    About the Author / Cameron Jones

    Cameron Jones is the Principal Product Manager at Blue Medora. Based in Grand Rapids, MI, he has been with Blue Medora for over 5 years working with partners and customers to ensure the highest value of Blue Medora products. This has involved initial investigation, feature planning and ensuring customer satisfaction. Connect with him on LinkedIn and Twitter.

  • Shouldn’t DBAs Be Part of the DevOps Inner Circle?

    Shouldn’t DBAs Be Part of the DevOps Inner Circle?

    DevOps is changing the culture of IT.  This movement is bringing application development and operations teams to the same table and the same time, working to understand and overcome the challenges facing the entire application delivery process—not just their piece. Development and operations teams are forging new bonds and alliances in the spirit of accelerating software release cycles.

    However, while quickness to market is paramount to success, businesses can’t forget about the internal implications of accelerated release cycles. With that in mind, there is one conspicuously empty seat within the “DevOps Inner Circle,” and that’s the database administrator’s (DBA).

    DBAs hold the keys to one of businesses’ most important assets: the database. But database change innovation has not kept pace with agile development methodologies and DevOps tooling that enable continuous delivery of software updates and changes. The vast majority of enterprises are still updating databases the same way they have been for the better part of the last three decades: through manual script review, validation, execution and individual heroics. As a result, application release cycles ultimately slow down at the last mile—the database.

    It’s time for a better approach. It’s time databases and their stewards, DBAs, be part of the DevOps Inner Circle. Including DBAs can create better, more efficient teams; save time and money; and even help companies create better solutions for their customers’ needs or their own.

    Shattering Silos

    One of the founding principles behind DevOps is the breakdown of silos between development and operations teams. Product managers can easily translate customer needs and communicate that feedback to developers in a way they understand—using epics and themes, for example. This helps bring everyone on the same page so that application updates or changes can be quickly coded, tested and delivered. But before application updates can be released to users safely and effectively, they have to be translated into the changes that will update the database. This is where the DevOps breakdown occurs. DBAs often have to rely on manually intensive, timeworn, error-prone processes and tools to make sure the right changes are made to the database.

    By inviting DBAs into the DevOps Inner Circle, database updates that go against business policy and will ultimately lock the database or “break the build” (think inserting a new column with a default value when the row count exceeds a million) can be found faster and addressed by the development team well before that change reaches the database. Having DBAs involved in release cycles sooner can help ensure developers are coding with corporate compliance in mind, ultimately making changes to the database smoother while adhering to guidelines that DBAs have typically policed.

    There was a time when databases needed protection from changes made by creative problem-solving in development, but DBAs simply cannot stand against the deluge of changes necessitated by accelerated cycles. Inviting DBAs into the DevOps Inner Circle enables teams to consider the implications of new changes and updates across the entire technology stack. Breaking down silos and making teams more aware of catchpoints in the last mile of the release process lets them anticipate and avoid database issues—which means faster releases and fewer headaches for everyone.

    Saving Time (and Time is Money)

    Faster release cycles are good for business, and not just because they get applications in front of end users sooner. Continuous delivery cycles are designed to cut costs associated with application development considerably by saving man-hours. Still, while development timelines keep getting shorter, the workload and time to deploy database changes gets longer.

    Enterprises can have multiple database configurations, so each change needs to be checked for compatibility. As the complexity of data repositories grows, so too does the time it takes to review and approve changes. In a 2015 IOUG survey on database manageability, 41 percent of respondents said changes took a week or more to approve. With multiple change requests coming to DBAs each month, each week or maybe even daily, it’s clear that sheer manpower can’t keep up with continuous delivery forever. Relief for DBAs is nonexistent without automation.

    Remember our earlier example, where we ran the risk of locking the database by inserting a new column with a default value when the row count exceeded a million?  Database automation software protects against outcomes like this by forecasting the impact application changes will have on the database. DBAs can use forecast reports generated by automation software to pinpoint any issues without expensive hours or days of searching.

    As part of a DevOps team, the DBA equipped with automation can do more than save time and headaches for themselves. Protecting against errors that could break the build saves teams from spending time to find and fix the source of a breakdown, and also saves a business from losing revenue while the fix is made. If so much time, money and potential frustration ride on DBAs’ ability to implement changes at the speed of continuous delivery, why are they still on the outside of the DevOps Inner Circle?

    Freeing Up Time for Innovation

    Flashes of inspiration rarely come about when you’re just trying to keep your head above water, and for so many DBAs, that’s the reality of work. Today, enterprises fight a war of attrition with the database, throwing manpower at the final hurdle of the release cycle. In addition to the attractive benefit of saving money on man-hours, bringing DBAs into the DevOps inner circle and automating some of their tasks also creates time and space for innovation.

    The relational database is nearly a 50-year-old innovation, one that changed the way people and computers interface through data. After so much time, and with so much on the horizon, the next innovation seems imminent or perhaps even overdue. The advent of quantum computing may bring with it a fundamental change to the way databases interact with one another. It’s certain to bring a shift in the way data is stored and retrieved, though at this point experts expect only the most complex business processes will benefit from quantum computing. So, while future tech remains out of reach, DBAs will be vital in the effort to innovate faster, more streamlined ways for dealing with zeros and ones.

    The first step to innovation, then, is addressing the needs of DBAs alongside those of customers and developers. Breaking down walls and increasing efficiencies between existing DevOps teams and DBAs will give teams more opportunity to create novel solutions to both their users’ problems and their own. Add another seat to the Inner Circle, save time and money, get quality applications to market even faster, and create innovative solutions to the problems of today and tomorrow.

    About the Author

    Derek Hutson HeadshotDerek Hutson joined Datical as CEO in 2015, bringing more than 15 years of leadership experience in enterprise software. Before joining Datical, he led multiple companies through extended periods of rapid growth and also held several executive roles at IBM. There he served on the leadership team for IBM’s acquisition of Telelogic, and was responsible for due diligence and integration of the acquired sales functions globally. He currently serves on the board of Hart InterCivic and Charity Dynamics. Other board or advisor positions have included CoreTrace (acquired by Lumension), Innography, StreamStep (acquired by BMC) and Phurnace (acquired by BMC).

  • Where is the DBA in the DevOps conversation?

    Where is the DBA in the DevOps conversation?

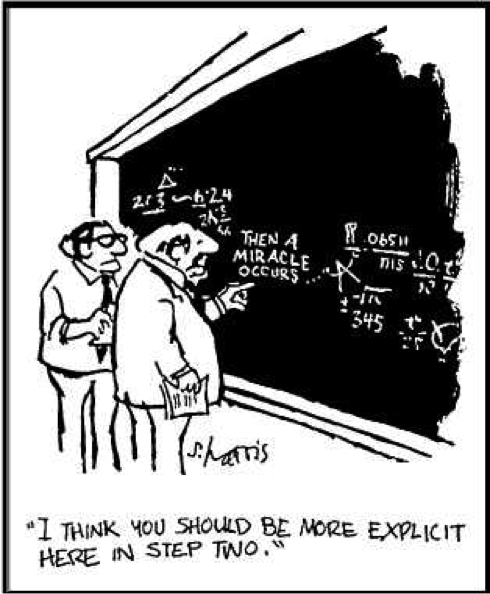
    dbapicIn reading case studies, surveys, and research articles on DevOps I am reminded of a cartoon I saw taped to my high school physics teacher’s file cabinet. Two scientists stand in front of a complex proof scrawled on a chalkboard. Separating steps 1 and 3 of the proof is the statement, “Then a Miracle Occurs.” One of the scientists points to the statement and says, “I think you should be more explicit here in step 2.”

    This is an apt metaphor for the DevOps zeitgeist’s avoidance of the database. ISVs and analysts spend a lot of time talking about how to streamline, accelerate, and automate application development and testing (Step 1) and how to monitor and automate the deployment of those applications (Step 3). But when it comes to managing the database change necessary to support the application and its release processes, it seems that everyone is waiting for that miracle to occur.

    This oversight is unfortunate. DBAs have a lot to offer when it comes to correlating the development of technology with the management of the environment in which it’s hosted. In a sense, DBAs have been DevOps all along.

    On the ‘Dev’ side, DBAs carefully evaluate each change request to ensure that it is well thought out, is compliant with organizational best practices and won’t have unintended consequences on database performance or the validity of dependent objects. They have developed and tested all of the SQL that has materially changed the database and crafted it into what it is today.

    On the ‘Ops’ side, DBAs have designed and provisioned the data platform. They are in charge of monitoring their databases and keeping them available and high-performing. They manage access to and the overall security of the platform. They perform release activities in support of the application and troubleshoot any errors that happen during that process or during day to day operation.

    So why isn’t the larger DevOps community including the data platform in the conversation? Why aren’t DBAs a crucial part of every DevOps team? Why are we relying on a miracle like the scientist in the cartoon?

    Every decision a DBA makes, every process or standard they put in place is influenced by the dual nature of their role. They are used to thinking about the impact of any task, requirement, or problem from both sides. It is deeply ingrained in them. They are deliberate and meticulous in their approach to change management because they understand that what they do has impact beyond what’s directly in front of them. They rely heavily on their expertise and their deep understanding of their organization’s data strategy to ensure they are making safe, future proof decisions to the best of their ability.

    This also explains why we haven’t seen the same proliferation of automation and orchestration solutions for the database that we have seen for other domains in the SDLC. True database automation has to be more than “run this script after that one” or “make this object look like that object over there.” To have a meaningful impact on your release throughput and staff productivity your database automation has to make use of your team’s intelligence. Any solution you implement has to harness the collective experience and knowledge of your DBAs and apply that knowledge to the evaluation of changes as they’re introduced in development. It has to be…miraculous.

    This is the whole reason we started Datical. When it comes to completing your DevOps vision, we wanted Datical to provide a real answer to Step 2 from that comic that has stuck with me all these years. Our flagship product Datical DB was designed and implemented to address the unique challenges associated with automating database changes in support of application releases. It automates and accelerates the propagation of database changes without sacrificing safety. We provide a highly customizable automation framework that is fueled by your experts. It allows you to define standards specific to your organization that are incorporated in our pre-deployment analysis. This greatly reduces the time spent manually reviewing SQL and checking the logic of your SQL scripts for errors that will cause application failures and downtime.

    About the Author/ Pete Pickerill

    High-Res-Peter-Pickerill-6571-150x150Pete Pickerill is Vice President of Products and Co-founder of Datical. Pete is a software industry veteran who has built his career in Austin’s technology sector. Prior to co-founding Datical, he was employee number one at Phurnace Software and helped lead the company to a high profile acquisition by BMC Software, Inc. His ability to understand product demands from a customer’s perspective and translate those demands into actionable product and development plans has led to expanded duties at every company for which he’s worked. In his time at Symantec, Pete worked directly with large financial services companies and online retailers to implement and improve online fraud prevention solutions that were used daily by millions of people worldwide. In addition to managing a development team and product schedule at BMC, Pete worked directly with large financial services institutions to provide the features they needed to achieve greater efficiency and cost savings in their application deployment processes.

  • Financial Sector Leading the Way with CD for the database

    Financial Sector Leading the Way with CD for the database

    The financial industry, especially banks, are still using a programming language that is over 50 years old. However, this doesn’t necessarily mean they are out of date, rather these giant institutions have found in some cases that their ancient systems just work. They are stable and secure software programs. But databases are not like static source code; they are always moving and changing. With the most important client information sitting in the database, it’s no surprise that banks and other financial institutions lead all other industries in adoption of Continuous Delivery methodologies for the database.

    A recent survey we conducted revealed that the banking and finance industry DBAs far outpace non-financial companies in terms of database Continuous Delivery adoption. Of the 55% of respondents not in the finance space practicing Continuous Delivery, only 49% said they practiced CD on their databases. When we asked banking and finance DBAs and managers, we found that over 70% utilize database automation for software and 64% of those also practiced CD for the database.

    These institutions are required to be agile in their database methodologies due to having such a large number of applications to deal with on a daily basis. Moreover, database errors that cause downtime are incredibly costly and financial institutions cannot afford to have any. Aside from the peace of mind that your database can run itself and adapt on the fly, proper database automation and version control can save financial institutions 80%-95% of time it would normally take to manually process changes and there is clear ROI when implementing Continuous Delivery.

    The economic effects of unplanned outages are prohibitive. According to a report by Gartner research, unplanned outages, on average, cost $42K per hour. When it comes to financial services companies, research shows the cost are much higher at about $110K per hour, the bigger the footprint that a company has, the more money it will lose when it fails.

    These statistics are one of the main reasons that we’re starting to see mainstream adoption of Agile and DevOps practices in finance companies. DevOps favors automating as many processes as possible and automation removes the potential for human error. By automating our processes, we allow machines to handle the redundant tasks freeing up the time and resources of skilled database professionals for more valuable and cost effective responsibilities.

    DevOps for Database, automation, control and enforced change management, provide confidence in the integrity and quality of the database code and virtually eliminates the potential that harmful database changes will find their way into production.

    About the Author/ Yaniv Yehuda

    Yaniv Yehuda, CTO, DBmaestro (http://www.dbmaestro.com/)

    Yaniv is the Co-Founder and CTO of DBmaestro, the leading provider of DevOps for Database solutions which enable control of database development and deployment. Yaniv is also the Co-Founder and the head of development for the Extreme group, a leading IT services solutions provider group.


  • MongoDB Replication Pro-tips: Reporting Instances

    MongoDB Replication Pro-tips: Reporting Instances

    Any shop that has a DevOps culture, and that has MongoDB backed applications, uses replica sets… not just for production applications, but for those still in the prototyping phase. Replication is critical for uptime, so your Ops team has been working with your Devs all through the development of your project, and you didn’t defer a replication strategy until after you had a working app.

    Nor did you neglect to plan for your reporting needs. It is a given that beyond running your app, you need to get analytics on user behavior, general use, and other business-specific metrics. You can’t just run reports against your live database, (for reasons I detail below, in case they are not yet obvious to you). In your DevOps shop, developers and admins discussed, at the inception of the project, the plan for sequestering reporting tasks so that they do not interfere with production tasks.

    Keeping Reporting Reads Away From Production

    Limiting reporting queries to dedicated nodes is a canonical example, used all over the MongoDB replication documentation. Reporting does not require writes, and permits eventually consistent data. Daily summaries do not suffer if they are derived from data which is seconds or minutes stale. It does not change the fundamental meaning of user behavior reports if your counts are missing a few actions, and some tallies are slightly misaligned.

    But why is it so important to take advantage of this?

    Aside: The Problem With Mingling Production and Analytics

    Skip this section if this is already a no-brainer for you. If you want some background, read on.

    Consider the working set, the subset of your entire database that MongoDB reads from and writes to over any given time span. Your production environment will have a set of active users, and the documents pertaining to their data will be what the OS attempts to keep in physical memory.

    (Do not let your working set grow larger than RAM! If it’s heading there, you need to shard, so capacity planning is critical. But that’s a separate lesson. Monitor your instances with MongoDB’s free monitoring servicee, and maybe take an upcoming webinar in capacity planning.)

    Even if your database is hundreds or thousands of times the size of your available memory, if you have planned your schema and indices well, MongoDB will run efficiently because the data outside the working set can remain untouched on disk. As users become idle, their documents will fall out of use, and the RAM they occupy will become available to contain documents for new active users.

    Reporting jobs, though, read a wide range of data, do not visit the same data repeatedly, and each reporting task may address completely different data sets. On any database of decent size, this means these jobs require constant ejection of recently used documents from RAM to make room for new documents to be read. If you run these jobs on the same instance that is backing your production work load, your reporting jobs will fight with your production apps for RAM footprint, continuously ejecting your live users’ data, while your app continuously reloads it. Congratulations, you have built a thrashing machine.

    Replica Sets With Dedicated Reporting Instances

    You can build dedicated reporting nodes atop MongoDB replication by taking advantage of hidden replica set members, or tag sets in concert with read preferences. The first method is simpler, the second is more flexible.

    Reviewing MongoDB Replica Sets

    MongoDB Replica Sets create uptime durability by replicating data to all the nodes in a set, and providing seamless fail-over to clients. They contain one primary node that allows writes, while the rest are read-only secondaries. They manage among themselves which is primary, holding elections to determine which node should be primary when conditions require. Replica sets should contain an odd number of members to facilitate rapid elections without ties.

    It is fundamentally not knowable whether unreachable machines are down or if the network has been partitioned, so if a majority of the nodes in a replica set go offline (say, 2 out of a 3-member set), even if a healthy primary remains, it will step down to a read-only secondary. Not doing so could lead to multiple machines declaring themselves primary in the case of a network partition, and horrific data inconsistencies.

    Thus a replica set contains a minimum of 3 members, providing a fault tolerance of one machine failure.

    Reporting Instance, Hidden Member

    Hidden members of a replica set are configured to be priority: 0, to prevent them from ever being elected primary, and to be hidden: true, which prevents clients connected to the replica set from routing reads to it, even if they specify a read preference of secondary.

    To read from this hidden member, you will use a standalone connection, rather than the MongoReplicaSetClient type, and specify slave_ok.

    Hidden Member Setup

    We can use the mongo shell to hide a member of an existing replica set:

    # connect to primary directly
    Kusanagi:~ avery$ mongo --port 29019
    MongoDB shell version: 2.4.3
    connecting to: 127.0.0.1:29019/test
    
    // using my local replica set playground
    PRIMARY> conf = rs.config()
    {
        "_id" : "test",
        "version" : 21,
        "members" : [
            {
                "_id" : 0,
                "host" : "Kusanagi.local:29017",
            },
            {
                "_id" : 1,
                "host" : "Kusanagi.local:29018",
            },
            {
                "_id" : 2,
                "host" : "Kusanagi.local:29019",
            }
        ]
    }
    
    // we'll use members[1], the instance on port 29018
    PRIMARY> conf.members[1].priority = 0
    PRIMARY> conf.members[1].hidden = true
    PRIMARY> conf.version += 1
    PRIMARY> rs.reconfig(conf)
    Tue Apr  1 12:24:34.045 DBClientCursor::init call() failed
    Tue Apr  1 12:24:34.046 trying reconnect to 127.0.0.1:29019
    Tue Apr  1 12:24:34.047 reconnect 127.0.0.1:29019 ok
    reconnected to server after rs command (which is normal)

    Kusanagi.local:29018 is now hidden. It will continue to replicate and vote in elections as usual, but clients connecting to the replica set will never read from it, even if Kusanagi.local:29019 is taken down:

    irb(main):012:0> rs = Mongo::MongoReplicaSetClient.new(["Kusanagi.local:29017", "Kusanagi.local:29018", "Kusanagi.local:29019"])
    => <Mongo::MongoReplicaSetClient:0x3fe06e4fe564 @seeds=[["Kusanagi.local", 29017], ["Kusanagi.local", 29018], ["Kusanagi.local", 29019]] @connected=true>
    irb(main):013:0> rs.primary
    => ["Kusanagi.local", 29017]
    irb(main):014:0> rs.secondaries
    => #<Set: {}>
    # an empty set -- as far as this connection is concerned, there are no secondaries.

    Reporting code would look like this (in Ruby):

    require 'mongo'
    reporting = Mongo::MongoClient.new("Kusanagi.local", "29018", slave_ok: true)
    
    # error checking goes here
    
    reporting['my_application']['users'].aggregate(...)

    Considerations

    Using a hidden member is the simplest way to set up an instance for a dedicated workload such as reporting, however:

    Hidden Members Cannot Be Read From In Case of Emergency

    With 2 ordinary and one hidden member in a replica set, fault tolerance for writing is identical to a regular 3-member set. However, should you lose two nodes, your production application will not be able to gracefully degrade to read-only mode, because your hidden member will not allow replica set client reads. If you just like the simplicity of a hidden member, and cost is not an issue, use a 5-member set (with one member hidden) instead.

    Wrapper Code for Replica Sets Cannot Be Used

    Many teams create application-specific wrappers to add infrastructure knowledge to the clients provided by MongoDB drivers. Since you need to address your reporting instance with a stand-alone connection, you will not be able to reuse this investment, which will make you sad.

    Reporting Instance, Tagged Member

    The more complex, but flexible, method for routing reporting queries to a dedicated node is to use tagging and read preferences.

    As with the hidden member, set one member to priority: 0, but do not set it to be hidden. Instead, assign a tag of use: reporting:

    PRIMARY> conf = rs.config()
    {
        "_id" : "test",
        "version" : 21,
        "members" : [
            {
                "_id" : 0,
                "host" : "Kusanagi.local:29017",
            },
            {
                "_id" : 1,
                "host" : "Kusanagi.local:29018",
            },
            {
                "_id" : 2,
                "host" : "Kusanagi.local:29019",
            }
        ]
    }
    
    // we'll use members[1], the instance on port 29018
    PRIMARY> conf.members[1].priority = 0
    PRIMARY> conf.members[1].tags = { "use": "reporting" }
    PRIMARY> conf.version += 1
    PRIMARY> rs.reconfig(conf)
    [...]

    As before, Kusanagi.local:29018 will never become primary; however, in the case that the other two machines become unreachable, your application will be able to issue reads to the reporting server. It should go without saying that your reporting should be suspended during such an event.

    Your reporting code will look something like this (in Python, this time):

    from pymongo import MongoReplicaSetClient
    from pymongo.read_preferences import ReadPreference
    
    rep_set = MongoReplicaSetClient(
        'Kusanagi.local:29017,Kusanagi.local:29018,Kusanagi.local:29019',
        replicaSet = 'test',
        read_preference = ReadPreference.SECONDARY,
        tag_sets = [{'use':'reporting'}]
    )
    # check to ensure we're not running reporting against the sole remaining secondary
    if rep_set.primary is not None:
        rep_set.my_application.users.aggregate(...)

    The above will only send reporting queries to secondaries tagged use: reporting, and it guards against running at all if there is no available primary. In practice, you should throw exceptions and handle them in your escalation code if you find no primaries! Better still, your monitoring could set runtime-available values so you can branch on, for example, reporting_system.ok().

    Benefits and Considerations

    Using tags and read preferences allows a few degrees of flexibility that are not possible with hidden members.

    Reporting Instances Can Be Easily Added

    Because your connection code is declarative, rather than specific to a particular host, to add more nodes for reporting jobs, just add them and tag them, like so:

    PRIMARY> rs.add({_id:3, host:"Kusanagi.local:29020", priority:0, tags:{'use':'reporting'}})

    Your existing code will make use of the new capacity, and the replica set will continue operating without triggering an election and disconnecting your clients.

    Reporting Instances Can Be Shifted or Dropped

    The reporting tag can be moved, or even removed if you need to offer read bandwidth to other jobs in a pinch. A reconfiguration like this will trigger an election and disconnect all your clients, but this is no worse than any other option. Note: It is an anti-pattern to increase your general capacity by distributing production reads to secondaries. This is only an emergency measure.

    Some Drivers Require Manual Sync

    The Ruby driver (as of 1.9.2), for example, does not refresh its view of the replica set unless the client is initialized explicitly to do so with refresh_mode: :sync. Check your driver documentation.

    Conclusion

    Simple replication setup has been one of my favorite operational aspects of MongoDB since its introduction pre–1.0, when it made MySQL replication look like something out of the stone age. It was a little rough around the edges back then, but has truly come into its own. Whether you use tag sets or hidden members, building a reporting infrastructure atop MongoDB’s replication features simplifies operations, letting you focus on building a great application.

  • MasterCard Israel 85% More Productive in Promoting Changes after Implementing DevOps for Database from DBmaestro

    Mastercard Israel renews contract with DBmaestro to provide its Database Enforced Change Management Solution for a third year 

    Tel Aviv, February 18, 2014  – DBmaestro, the pioneer and leading provider of DevOps for Database solutions has announced that Isracard, Israel’s leading credit card company and member of the worldwide MasterCard group, will be renewing their contract with DBmaestro for a third year. DBmaestro streamlined Isracard’s development process by providing Database Enforced Change Management capabilities (DECM) which enforce best practices and prevent accidental code overwrites.

    In 2011 Isracard was struggling with a number of challenges including failures during production deployments and frequent unintentional code overwrites which forced developers to spend time backtracking and re-implementing changes. Isracard’s problems were a lack of insight into change histories, difficulty undoing changes and rolling back to previous versions, an inability to properly prioritize developers’ work, and a lack of formal documentation of planned and completed changes. The company wanted to enforce consistency and coordination for database development in the same way that its tools and methodologies did for native application code. These issues were draining valuable time and resources from the company.

    After evaluating a number of solutions, Isracard chose DBmaestro and quickly experienced an eightfold increase in its productivity in promoting changes. A deployment script that took as much as two hours to be developed before DBmaestro was now completed in just 15 minutes. DBmaestro also provided a full audit trail of all changes, which made it easier for the change manager to control all projects throughout their lifecycle – from development through pre-production, to production. This drastic improvement was achieved with the help of DBmaestro’s Database Enforced Change Management capabilities (enforcement of version control best practices), which prevent accidental code overwrites and eliminates the rework associated with such errors. Developers at Isracard were now able to see if someone else was already working on the same object, improving communication and minimizing the risk of redundancies and conflicts.

    “Our development processes were inefficient, and we often found ourselves working on versions that were different from production versions,” said Ronen Zaretsky, CIO of Isracard. “DBmaestro changed all that. It has helped us streamline and coordinate our activities across code and database development. Now, we can work smarter and faster, and everything runs smoothly, from start to finish.”

    “We are delighted to continue supporting Isracard for the 3rd year in a row, following an already successful two year partnership,” Said Yaniv Yehuda, CTO of DBmaestro. “This is the perfect demonstration of the value our solution provides our partners. Isracard approached us in 2011 seeking a way to improve development processes, maintain stability and promote changes to production daily instead of monthly. To ensure the availability of production systems, they also needed to ensure separation between development and production environments. After evaluating a number of solutions Isracard chose DBmaestro because it integrated seamlessly with the company’s existing proprietary deployment tool, and helped to rapidly and effectively bridge the gap between code and database development methodologies.”

    To learn more about TeamWork from DBmaestro, visit our blog or Request a Free Evaluation.

    About Isracard

    Isracard is a fully-owned subsidiary of Bank Hapoalim, Israel’s largest banking group. Isracard was founded in 1975 and is Israel’s leading Credit Card Company. Isracard has some 100 thousand merchant agreements and approximately 2 million credit card holders.

    Isracard is continually developing and implementing advanced technologies to widen the variety of its products, and to improve customer service. The company is developing new activities in various areas, including P2P and B2B, which the current partnership is a major basis for its further development.