Tag: DataOps

  • Database Virtualization – Driving the Next Big Transformation

    Database Virtualization – Driving the Next Big Transformation

    Data is both the most important asset and the biggest challenge for most corporations. It impacts every aspect of the business from financial considerations to AI/ML training. Data is used by development and DevOps teams, engineering teams, quality assurance, business intelligence teams and database administrators. Despite its central role in operations, traditional forms of database delivery remain complex, costly and time-consuming.

    In many cases, enterprise data is growing exponentially, increasing management challenges and driving up the cost of data storage. Duplicating data to each new environment as use cases arise is overwhelming DBA teams and incurring a significant storage footprint. This has resulted in data becoming a significant bottleneck for DevOps teams, highlighting the importance of finding a quick and automated solution for the replication process across non-production environments.

    What’s Changed?

    In the past, development teams would work with the same dataset for upwards of six months. This left DBA teams with plenty of time to meet all database delivery needs. However, as technology became more sophisticated and consumers grew more demanding, the data delivery life cycle was cut down dramatically. Today, with agile development, new features may be added every few days, if not hours. Coupled with QA teams’ requirement for testing data continuously, AI/ML teams requiring millions of data points for accurate training, and data analysts constantly needing fresh data for organizational growth, this means DBA teams are flooded with demands they are incapable of managing.

    What Now?

    Database virtualization is an automated and easy solution to the dataset bottleneck. By simplifying the creation and distribution of database replicas, DevOps teams will be able to create fully functioning virtual environments via a self-service process–allowing DBA teams to focus on more critical duties relating to production databases.

    Speed Up

    The first—and most obvious—advantage of this approach is the increased speed at which data is delivered. To keep DevOps teams productive and avoid the use of old, stale data, new environments need to be produced on demand. By integrating the production of new environments into the CI/CD pipeline, enterprises will be able to automate the process and provide DevOps teams with full autonomy. By cutting out the dependency on the DBA, teams will be able to access the data they need, when they need it.

    Scale

    Agility is fundamental to the success of database management. Each team requires an independent environment, unaffected by other use cases. The creation and supply of virtual databases allow for quick provisioning. Once created, these databases look identical to the original physical database and function completely independently of each other. Any changes made to a vDB remain unique to the environment it’s in.

    Save

    As the need for data grows, so does the cost of storage. Creating a physical copy for each team and use case results in a significant storage footprint. This means that these datasets come with a hefty cost. However, the creation of virtual databases led to a dramatic decrease in storage needs. Where traditionally, physical datasets can weigh upward of several TB, vDBs only weigh a few hundred megabytes. Further, virtualization solutions also compress the weight of physical copies – such as the golden copy – actively decreasing the weight and cost of storage across all fields.

    Secure the Database

    Even after the database delivery problem has been solved, enterprises are faced with another major issue – security. With so many different teams accessing data in virtual and low-level testing environments, the risk of ransomware and other cyberattacks increases dramatically. Generally, the investment in securing non-production environments is significantly weaker than in production.

    A common approach to address this issue is masking sensitive data so it is rendered useless to outside sources. However, traditional masking requires a data expert to manually sift through all existing data and implement data masking algorithms on any sensitive information found. This time-consuming solution creates a new data bottleneck. By automating the process and applying it to the golden copy, corporations can be confident that all vDBs created are completely secure and privacy compliant.

    Looking Ahead

    Database virtualization is the future of database replica management. Virtual databases are delivered in a matter of minutes, significantly accelerating the speed of delivery. These environments are easy to use, independent, and can be maintained via a self-service portal. The ongoing sync between the original database and the vDB ensures continuous access to the latest data without the need for timely or expensive processes.

    Effective database virtualization will allow well-established enterprises to more easily compete against those agile startups that face significantly fewer barriers to entry.

    Image Source: joshua-sortino-LqKhnDzSF-8-unsplash
  • The Benefits of a Streaming Database

    The Benefits of a Streaming Database

    Streaming databases offer an innovative approach to data processing that combines the familiarity of traditional models with a powerful data transformation engine. This hybrid system provides DevOps and DataOps teams with extremely fast results for complex SQL queries, aggregations and transformations that are impossible or take hours to process in the traditional batch computation model.

    By pre-specifying query results upfront (in materialized views) and then incrementally updating them as new data comes in, streaming databases offer a valuable alternative to traditional databases that require complex ETL pipelines or overnight batch processing.

    As the demand for faster results continues to rise, streaming databases are emerging as a fundamental new building block for data-driven organizations.

    streaming database

    History

    Streaming database concepts originated in capital markets, where fast computation over continuous data is highly valued. The first products were basic event processing frameworks that addressed specific needs within hedge funds and trading desks. However, their creators quickly recognized that SQL works as the declarative language for streaming data just as well as it does for traditional static databases.

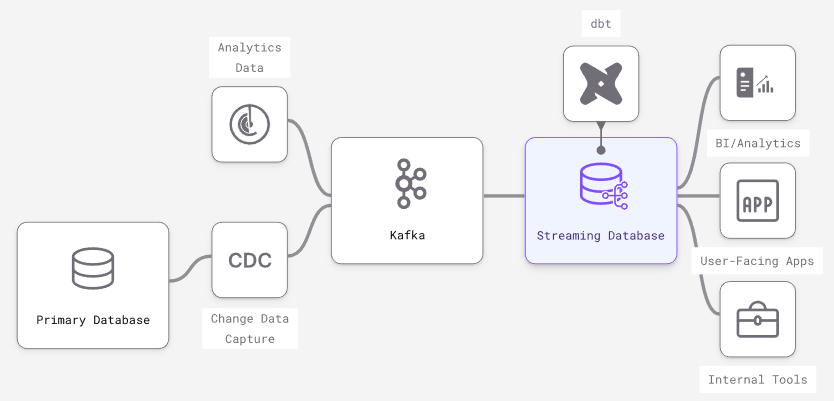
    Today, modern streaming databases are most often used downstream of primary transactional databases and/or message brokers, similar to how a Redis cache or a data warehouse might be used.

    Trade-Offs

    Experienced engineers understand that no software stack or tooling is perfect and comes with a series of trade-offs for each specific use case. With that in mind, let’s examine the particular trade-offs inherent to streaming databases to understand better the use cases they align best with.

    Unique Features

    • Incrementally updated materialized views – Streaming databases build on different dataflow paradigms that shift limitations elsewhere and efficiently handle incremental view maintenance on a broader SQL vocabulary. Other databases like Oracle, SQLServer and Redshift have varying levels of support for incrementally updating a materialized view. They could expand support, but will hit walls on fundamental issues of consistency and throughput.
    • True streaming inputs – Because they are built on stream processors, streaming databases are optimized to individually process continuous streams of input data (e.g., messages from Kafka). Scaling streaming inputs involves batching them into larger transactions, slowing down data and losing granularity. In traditional databases (especially OLAP data warehouses), larger, less frequent batch updates are more performant.
    • Streaming outputs on queries – Many databases have some form of streaming output (e.g., the Postgres WAL), but what’s missing is output streams involving any kind of data transformation. Streaming databases allow for streaming output of complex joins, aggregations and computations expressed in SQL.
    • Subscribe to changes in a query – As a side effect of streaming outputs, streaming databases can efficiently support subscriptions to complex queries: Updates can be pushed to connected clients instead of forcing inefficient polling. This is a key building block for pure event-driven architectures.

    Missing Features

    • Columnar optimization – OLAP databases have advanced optimization techniques to speed up batch computation across millions of rows of data. Streaming databases have no equivalent because the focus is on fast incremental updates to results prompted by a change to a single row.
    • Non-deterministic SQL functions – Non-deterministic functions like “RANDOM()” are common and straightforward in traditional databases. But imagine running a non-deterministic function continuously, resulting in chaotic noise. Therefore, streaming databases don’t support non-deterministic SQL functions like “RANDOM().”

    Performance Gained

    • Minimized time from input update to output update – The time between when data first arrives in the streaming database (input) and when changes to results reflect the change (output) is sub-second. Additionally, it keeps up as the dataset scales because results are incrementally updated.
    • Repeated read query response times – When a query or query pattern is known and pre-computed as a persistent transformation, reads are fast because they require no computation: You’re just doing key-value lookups in memory, similar to a cache like Redis.
    • Aggregations – The resources needed to handle persistent transformations are often proportionate to the number of rows in the output, not the scale of the input. This can lead to dramatic improvements in performance in aggregations in a streaming DB versus a traditional DB.

    Performance Sacrifices

    • Ad-hoc query response times – While running ad-hoc queries in a streaming database is possible, response times will be much slower because the computation plan is optimized for continuously maintaining results, not answering point-in-time results.
    • Window functions – A window function performs calculations across table rows that are related to the current row. They are less performant in streaming databases because updating a single input row requires updating every output row. Consider a “RANK()” window function that ranks output by a computation. A single update can force an update to every row in the output.

    Factors Impacting Scalability

    • Throughput of changes – The changes or updates to input data are what triggers work in the system, so changing data will often require more CPU than data that changes rarely.
    • Cardinality of the dataset – The total number of unique keys will slow down read queries in traditional databases. In streaming databases, high cardinality increases the initial “cold-start” time when a persistent SQL transformation is first created and requires more memory on an ongoing basis.
    • Complexity of transformations – Unlike the on-request model in a traditional DB, SQL transformations are always running in a streaming database in scale in two ways:
      • Memory required to maintain intermediate state – Imagine how you would incrementally maintain a join between two datasets: You never know what new keys will appear on each side, so you must keep the entirety of each dataset in memory. This means that joins over large datasets can take a significant amount of memory.
      • Quantity and complexity of transformations – When a single change in inputs needs to trigger a change in outputs in many views, or when many layers of views depend on each other, more CPU is required for each update.

    Use Cases

    Like any software primitive, there are many use cases. Here are some categories of products and services particularly well-suited to streaming databases:

    • Real-time analytics – Use the same ANSI SQL from data warehouses to build real-time views that serve internal and customer-facing dashboards, APIs and apps.
    • Automation and alerting – Build user-facing notifications, fraud and risk models, and automated services using event-driven SQL primitives in a streaming database.
    • Segmentation and personalization – Build engaging experiences with customer data aggregations that are always up-to-date: personalization, recommendations, dynamic pricing and more.
    • Machine learning in production – Power online feature stores with continually updated data, monitor and react to changes in ML effectiveness – all in standard SQL.

    Conclusion

    Streaming databases offer a powerful yet accessible way for data and software teams to leverage stream processing capabilities. By using familiar SQL DB concepts and a stream processor to compute SQL transformations, data and software teams can focus on shipping complex data-driven products quickly, with improved performance and scalability. With a streaming database, organizations have the power to transform data in real-time and build the applications of tomorrow.

  • How to Maximize Telemetry Data Value With Observability Pipelines

    How to Maximize Telemetry Data Value With Observability Pipelines

    The software landscape has shifted significantly in recent years as companies digitize their operations and adopt cloud and microservices technologies. The complexity of modern software systems has led to an increasing need for real-time visibility into their performance—resulting in an explosion of telemetry data that is stretching IT budgets and outpacing engineering teams’ ability to find value in that data. In fact, data volume is growing at 23% yearly, while IT budgets are only growing at 5%.

    Managing all this data at increasing cost is further compounded by unpredictable software failures and ever-evolving security threats. As a result, companies are forced to pick which parts of their software to instrument and monitor. To overcome this challenge, a different approach to managing data is required.

    Observability pipelines are emerging as a way to address this problem. They centralize telemetry data (i.e., logs, metrics and traces) from many sources, transform that data to fit downstream needs, and route it to various destinations for analysis. With complete control of the data, companies can sort through large amounts and prioritize what is essential, allowing them to act swiftly to avoid disruptions while reducing costs by only storing the data they need.

    Research indicates 62% of organizations currently have an observability practice. This means 38% operate with limited awareness of what’s happening in their software. Even those with an observability practice can only afford to store some data and have to choose which applications to instrument. This leads to blind spots and, ultimately, issues that are time-consuming to fix due to a lack of data.

    Managing Limited Resources With Observability Pipelines

    Engineers face more demands in today’s fast-paced business environment than ever before. Despite an increase in their responsibilities, the size of engineering teams has yet to grow accordingly. Given this, there has been a rise in full-stack engineers responsible for technologies from the front end to the back end. Short on time and resources, it’s difficult for these engineers to instrument and monitor software.

    Observability pipelines help control the amount of telemetry data using various processors such as sampling, throttling, filtering and parsing, and only forward valuable data to the downstream systems. The rest of the data can either be discarded or stored in a low-cost system, such as Amazon S3. This reduces costs and lets engineers focus on analyzing relevant data to identify issues.

    Engineers can also use observability pipelines to consolidate data from various tools. Many teams use different platforms or open source tools, like Prometheus or Jaeger. The fragmented data makes it hard to solve issues and understand application health. Observability pipelines combine all this data to make it easier to act on.

    It’s also important to remember that real people work on these technical challenges. Engineers face burnout working long hours to keep up with software development demands. Constantly switching between tools and manually moving data adds to the pressure. Moreover, the number of data sources, observability tools, and platforms that need that data are constantly increasing. Embracing open standards such as OpenTelemetry can ease this integration burden. Engineers can swap out tools without extensive testing and integration. The increased control and easy integration enable engineers to focus on delivering business value.

    Making Data More Usable

    Teams across organizations want access to data but struggle to use it effectively. The difficulty stems from the lack of data usability: Telemetry data is unstructured; varying formats make it hard to use; data preparation is time-consuming and sensitive data in logs may lead to compliance violations.

    By most estimates, 80%-90% of data is unstructured, which makes it hard to store and analyze because it doesn’t adhere to traditional data models. Observability pipelines make sense of unstructured data before it reaches its final destination. This is achieved using data processors that shape and transform data to make it more actionable. These processors include advanced parsers that identify and extract relevant information, transforming data into consumable formats that make it easier to work with and analyze.

    The advantage of performing these operations within the pipeline is that the same data can be prepared to fit different use cases downstream. For instance, while one team may require data optimized for visualization and trend analysis, another may require complete data for threat hunting. These transformations are managed from a single control point, eliminating the need to maintain separate data streams.

    Observability pipelines can also help companies meet data compliance requirements. For example, teams can scrub, mask or redact PII data based on a defined key structure before the data reaches a SIEM or audit platform.

    Taking Immediate Steps to Make the Most of Telemetry Data

    Organizations can take immediate action to make the most of their telemetry data. First, they need to adopt a visibility-first rather than a cost-first approach. They should assess what software they’ve instrumented. This will identify gaps in telemetry, which can be used to develop a plan to instrument all software. Next, they need to create a strategy for managing their telemetry data, being particularly thoughtful about how and why the data is stored and analyzed.

    Once a company has taken these two steps, it can decide which tools to use. One of the great things about OpenTelemetry is that it provides flexibility for future decisions about what tools to use.

    As companies invest more resources into building observability practices, they’ll encounter problems processing an extraordinary amount of telemetry data for any meaningful action. Observability pipelines provide a competitive advantage of prioritizing the essential data that will enable companies to make better decisions faster.

  • How Database DevOps Fuels Digital Transformation

    How Database DevOps Fuels Digital Transformation

    In today’s real-time, hyperconnected reality, data is a core driver behind most digital strategies. User data is constantly gathered and shared across various technology backends and platforms—as is system performance data to inform engineers. Data is pivotal for everything, from generating machine learning models, refining user experiences and even supporting new data-centric services. But although data is a clear backbone to many enterprises, there is no clear winner regarding which database to use.

    Large organizations often find themselves supporting different database styles, from relational databases to NoSQL and distributed SQL. And as organizations continue to adopt multiple databases, safely managing the processing and storage of data becomes more challenging to enact at scale.

    I recently met with Jakub Lamik, CEO, Redgate Software, to understand the role DevOps, specifically database DevOps, is playing in advancing data-driven digital transformations. According to Lamik, applying DevOps practices for database management can improve performance, increase productivity and help organizations stay compliant. Below, we’ll consider the state of today’s data-driven digital transformations and highlight ways to improve how DevOps is applied to database management.

    State of Data-Driven Digital Transformations

    The 2022 StackOverflow Developer Survey found the most popular databases to be MySQL, PostgreSQL, SQLite, MongoDB and Microsoft SQL Server. But most often than not, businesses deploy more than one of these in production. Redgate’s 2021 State of Database DevOps report found that 70% of businesses had more than one DBMS in use, and 48% had teams working on three or more different databases.

    Engineers operate in increasingly hybrid and distributed technology environments. This isn’t for no reason—in fact, 90% of organizations said multi-cloud is helping them achieve their business goals. Lamik also notes a diverse array of software technologies in practice today, from multiple clouds to decoupled microservices architectures and database types. But the desire to work with diverse toolsets causes fragmentation, which could hinder software delivery efforts. For example, organizations want to deploy the same framework and similar methodologies across different databases, said Lamik, and have it be database- and cloud-agnostic.

    Tips to Improve Database DevOps Operations

    To increase the pace of software delivery, infrastructure automation is often needed. And like other roles, database professionals are increasingly trying to automate operations and free themselves from mundane tasks. So, what are some ways to streamline database DevOps? First off, Lamik encourages adopting a common approach across multi-database environments, using standard toolsets that are flexible and portable. “The organizations that standardize deployments across different database environments can increase the frequency and reliability of deployments,” he said.

    Catching and resolving errors quickly is also becoming increasingly essential to meet objectives. And although DevOps brings many advantages, the CI/CD pipeline has gaps. “Observability supported by intelligent automation is key to closing those security gaps,” said Lamik.

    Thus, he encouraged additional oversight and tracking of changes to ensure stability throughout the database deployment pipeline. Also helpful is encouraging collaboration with security professionals (also known as DevSecOps) and integrating security principles into the DevOps workflow to ensure the process is secure by design.

    Another element of database security involves the proper observability and classification of sensitive data. As Lamik describes, organizations must be careful to distinguish between data used for production purposes and data used for development purposes. Ensuring sensitive data is cataloged correctly is imperative to avoid production data from being breached or accidentally publicly exposed.

    Final Thoughts

    In summary, applying DevOps ideals to database management could be a boon for development efforts. For those who haven’t yet considered it, a DevOps transformation will pay dividends, says Lamik. Furthermore, a common management layer could help wrangle multiple database types and help adopt new emerging database types, such as Snowflake and Postgres. Yet, when acquiring new database toolsets, Lamik admitted it may not be a quick transition. He recommends a land-and-expand strategy rather than a top-down approach (which typically isn’t as effective in empowering individual developers).

    Commenting on the industry’s recent move toward platform engineering, Lamik sees it as the next evolution of DevOps. Whereas DevOps brought helpful toolsets to streamline deployment and digitization, platform engineering is taking these practices and productizing them to be reusable at scale across teams and departments, he explained.

    Also, in the new cloud-native stack, containers are designed to be ephemeral, causing engineers to craft workaround solutions to enable stateful storage on platforms like Kubernetes. Regardless of deployment, data must have proper backup and recovery controls as well. In this new cloud-native paradigm, the role of database professionals is changing, explained Lamik, and “APIs are becoming the focal point of communication.”

  • New-Age Tech and Culture Driving Data Democratization

    New-Age Tech and Culture Driving Data Democratization

    Data democratization has become critical for organizations to leverage data’s true value and fully realize its benefits. Making data available across the organization helps companies to serve customers better and make data-driven decisions that align with their goals and objectives. It essentially means enabling access to a company’s data resources to employees, bound by reasonable limitations on legal confidentiality and security.

    As a means to remove data silos in organizations, the indispensability of data democratization is clear. It allows more widespread access to and use of data within an organization. This can lead to more informed decision-making, increased collaboration and innovation and more efficient use of resources.

    Breaking down data silos can help reduce the risk of data breaches and improve data security. While the jury may be out on whether data democratization is beneficial in preventing security breaches, silos between networks or security systems make it difficult to identify large-scale attacks as they tend to represent disjointed security protocols. There is less likelihood of robust security protocols between non-communicating teams.

    New-Age Tech as an Enabler of Data Democracy

    New-age technology such as cloud computing, blockchain, and advanced analytics are aiding data democratization. For example, 5G enables more significant volumes of data to be moved faster and more securely in the form of big data. Blockchain provides higher-quality data and improves the operation of cyber and physical systems. In addition, IoT allows for exchanging data between devices, where processes can be established between devices without intermediaries.

    A hybrid cloud adoption survey conducted in March 2022 of IT professionals primarily based in North America and Europe revealed 93% of the IT industry would adopt a hybrid of cloud and on-premises solutions or migrate fully to the cloud within five years, using it to store and manage data. Gartner estimated that 85% of enterprises would embrace a cloud-first principle by 2025 and that it will be essential to execute digital strategies in business.

    This suggests that new-age technologies play a significant role in breaking down data silos and enabling organization-wide access to data. By leveraging these technologies, organizations can easily store, process and share data, leading to better decision-making, increased collaboration and improved business outcomes.

    Data creation, development, and utilization directly relate to Industry 4.0 applications. In practice, data democratization is seamlessly transferable to Industry 4.0 applications. The question arises: Do industrial companies have the capabilities today to apply the concept of data democratization? And to what extent?

    As new-age tech drives the emergence of new business models, companies that will lead a cultural shift as well as a technology evolution will be successful. This is possible via a business-centric data strategy, along with the democratization of analytical tools and platforms to enable stakeholders to help build better insights into their business processes.

    Culture as a Prerequisite for Data Democracy

    A Google Cloud and Harvard Business Review survey of industry leaders revealed 97% believe organization-wide access to data and analytics is critical to the success of their business. However, only 60% of respondents believed that their organizations effectively distribute that access today.

    What are the prerequisites for data democracy? First, companies should inculcate a culture change to create a pull from inside the organization rather than first developing the technology. Second, decision-making in companies is based on experience and intuition than on data; they should compulsorily begin to use data as a baseline for business decisions. Third, leaders should encourage a data-driven culture to grow from within.

    Formalizing and sharing knowledge can remove roadblocks to the democratization of data. Therefore, one form of action is to set specific incentives to foster a mindset of knowledge sharing. For instance, existing practices to incentivize participation in the suggestion or lessons-learned programs can be used as a reference.

    Many companies have procedures to involve employees in the continuous improvement process. But while employees can use the existing IT systems to perform their day-to-day work, they need more capabilities to cover their individual information needs. Thus, as a way forward, capability building within is critical. Another strategy is decentralizing decision-making; if employees can gain insights independently, they should be able to act on these insights independently.

    Organizational culture is vital to data democratization, as it determines the attitudes, behaviors and values that guide how data is shared and used. On the other hand, a culture that values secrecy or hierarchical control over data can lead to resistance to data democratization efforts and perpetuate data silos. A culture that lacks trust and transparency can also lead to reluctance to share data, which can impede collaboration and hinder data-driven decision-making.

    Data Democratization – The Way Ahead

    Organizations need to assess and work on their tech stack and internal culture to promote a data-friendly culture supporting data democratization. To foster a data-friendly culture, organizations should encourage open communication and collaboration among employees and provide training and resources for employees to access, understand, and analyze data.

    Open communication, collaboration, innovation and trust are essential attributes for breaking data silos. A corporate culture that values data-driven decision-making will lead to more widespread access to and use of data and support the implementation of new-age technologies. Finally, there is a need to establish clear data governance policies and procedures that support data democratization and build a continuous improvement process by encouraging experimentation and learning from failures.

    Image Source: Joshua Sortino, Unsplash

  • How to Achieve Data Mesh With Four Key Principles

    How to Achieve Data Mesh With Four Key Principles

    Today’s world is becoming increasingly data-driven, which means businesses need to refine their practices and decision-making processes with the use of trustworthy data. However, this has proven challenging as organizations often don’t know what to do with the abundance of data available to them. According to a recent survey from Snow Software, 89% of IT leaders receive actionable data, yet 60% feel overwhelmed by the volume at their fingertips. These companies are both thriving in data collection and are bogged down by the sheer quantity available. While traditional data strategies have not yet adapted to meet modern business needs as the amount of data continues to grow, there’s a strong opportunity for companies to transform their data warehouses and data lakes and optimize the flow of data to consumers through an emergent approach called data mesh. Data mesh forges a path for companies to improve their business strategy and make better, faster decisions by leveraging the insights buried within their data.

    Data Mesh and its Benefits

    At its core, data mesh is an approach to data management that enables organizations to evolve from the pitfalls of legacy, centralized data architecture toward a decentralized, domain-driven design at scale. Breaking that down, data mesh is designed to help companies manage complex data networks by focusing on decentralized data ownership, treating data as a product, and providing a uniform infrastructure capable of sharing data across the company landscape. It improves upon legacy data management, which is often time-consuming, error-prone, unsustainable and unscalable. Unlike these traditional methods, data mesh gives domain-driven ownership to experts who strategize how it can best serve the company, as opposed to just dumping all data in one place and waiting for a centralized function to process it and make it available to the business.

    A data mesh approach also enables organizations to democratize their data by allowing users to acquire trusted data when they need it, all while automating the complexity and being shielded by security and governance guardrails. It removes bottlenecks and helps businesses glean the data-driven insights they need at the scale and speed of their organization. This way, organizations can maximize the value of their data by ensuring it is clean, vetted and readily available to support business initiatives.

    The Four Principles of Implementation

    So how can organizations embrace this approach? The framework of data mesh is centered on four guiding principles to help organizations get the most out of their data. Leveraging these principles will help your organization unlock the benefits of a data mesh.

    ● Domain-driven ownership: As opposed to separating data from your organization’s subject matter experts, the first pillar of data mesh implementation involves putting domain experts in charge of their data ecosystem. This way, data will be cleaned and enriched at the source before it’s made available throughout the organization. Domain owners will maintain the quality of the data and keep all necessary facts and documentation available for audits, effectively combining data with business talent.
    ● Data as a product: The job of the data team is to provide the data that the company needs for whatever purpose, be it making decisions, building personalized products, or detecting fraud. By treating data as a product, the company is giving its data a vision, strategy and product roadmap, ensuring its value is executable.
    ● Self-service data infrastructure: A business is made up of logically autonomous domains; each domain not only supports a business function, product or process but also produces data products and therefore requires a data infrastructure. Self-service infrastructure ensures business domains don’t have to deal with the underlying complexity of networking, security, compute and storage requirements.
    ● Federated computational governance: Standards for data governance are defined centrally, but local domain teams are empowered and equipped to apply to these standards however is most suitable for their specific environment within predefined guardrails. The key to achieving this for policy, security, quality and definition at scale is automation and integration throughout the landscape of the data infrastructure.

    By enacting these principles within your organization, your data mesh architecture is sure to provide the most value for your data.

    Data mesh is an optimal solution for any business currently struggling to find value in its data. Traditional methods are time-consuming, unsustainable, unscalable and error-prone. Data mesh is an approach designed to transcend these barriers, decentralizing much of the IT team’s heavy lifting and putting the responsibility of managing data on individual business domains. With clear ownership, domain experts can develop deep data knowledge and expertise and ensure that it’s trustworthy and valuable to your organization before making it available for consumption. This way, enterprises can prioritize self-service and empower data consumers with access to accurate, high-quality data when needed.

  • Why You Need to Break the Observability Data Silo

    Why You Need to Break the Observability Data Silo

    In my role as a developer advocate for Coralogix, I speak with organizations across almost every conceivable industry, and there is a pattern across almost all of them. In the world of observability, the challenge is battling scale. At scale, observability becomes a complex problem to solve. Surprisingly, the most common pattern for handling observability data is also holding people back from unlocking the true power of their data.

    What is the Data Silo in the World of Observability?

    To understand the data silo, we first need to understand the typical architecture of an observability solution, whether it’s homegrown or SaaS. Observability data can be divided into three types: Logs, metrics and traces. These three types come together to give engineers a complete picture of the health and performance of their system.

    These three data types are typically held in different storage mechanisms. A popular solution for logs is open search, while Prometheus holds the mindshare for metrics, and Jaeger is a very popular tracing solution. This means three solutions, three interfaces and, subsequently, three problem-solving workflows.

    What’s wrong with separating data like this? Even though there are three types of data, there is still only one goal: To understand the health and performance of the system. This is the only use case. The data silo is the dominant trend for observability solutions to provide a fragmented view of the data. It requires engineers to piece together stories as they go, rather than correlating across all of this data at once, to provide a complete picture of system performance.

    This slows down troubleshooting. If there is an issue, an engineer will first review one of the data types. Then, they will run different queries against other data types to confirm. So they may detect a 500 error in the logs, then move to the traces to see the impact on traffic, and finally, review the application metrics. This means three minimum queries when attempting to assess only one problem.

    Breaking the Data Silo

    Breaking the data silo can be a daunting challenge. There are some key points to focus on when a company starts out and some finishing touches that make for an excellent developer experience.

    Unify data storage as much as possible. For example, traces can be stored in Prometheus rather than in a separate solution. This will enable engineers to query, for example, trace latencies alongside CPU metrics. It will also minimize the UI work necessary to join together data. If an organization has the expertise, it’s possible to store everything inside an OpenSearch cluster. This means a single interface, with a single query language, to query all available observability data. Anyone assessing this option should simply decide what their company can maintain and what skills they have in-house.

    Present observability data as one. If storage unification isn’t an option, then focus on the presentation layer. Tools like Grafana can consume most observability solutions as external data sources and render them all on the same dashboard. While an engineer will still have to query them using the specific language of the tool, it means that they can render things alongside one another, making for an insightful dashboard.

    Correlate data in one user interface. This means metrics are rendered in a single dashboard alongside logging and tracing data. This will give users a static view of the data at once, even if there is a limit to how queryable the data is.

    Create universal values. If it’s impossible to make any of the previous recommendations, then this is an easy, quick win that will at least make querying observability data more consistent. An easy way to do this without making your code messy is to use a library like MDC (or your tech stack’s equivalent). Add some tags or values that will exist in all logs, metrics, and traces. For example, the name of the application and the feature it belongs to, i.e. application is credit-card-service and feature is payments. This means that if something goes wrong, there is already a set of key-value pairs that translate across every data type.

    At the very least, this will mean an engineer can issue consistent queries across the three solutions, albeit in different syntaxes. This represents the least value, but also the least rework and effort, and will lower the cognitive load of engineers who are already trying to debug a potentially serious outage.

    The Data Silo Can be Beaten

    A siloed observability strategy drives waste and inefficiency in engineering teams, precisely when they need efficiency the most. By breaking the data silo, observability data can be queried, analyzed, and correlated together to form a single, cohesive and complete picture of your system health.

  • How to Modernize a Data Warehouse in Months, Not Years

    How to Modernize a Data Warehouse in Months, Not Years

    Modernizing a data warehouse ranks among the worst imaginable tasks for IT. The end result is immensely desirable. The benefits of moving from an on-premises to a cloud data warehouse are well-documented. But database migrations require huge efforts and the stakes are high. What makes it so difficult? All applications, including ETL, BI, analytics and reporting, are designed to work with a specific legacy system. Hence, moving these applications to a different system requires extensive rewrites.

    Database migrations may well be the world’s most underestimated problem. In particular, data warehouse migrations are notorious for their horrendous cost overruns. Even when organizations plan for these projects to take several years, they tend to miss even the most generous deadlines. Worse, the vast majority fail to meet their objectives.

    In this article, we report on the exceptional success one major enterprise had migrating its systems. They managed to modernize their system in record time with little to no downtime at all. We’ll take a look at their journey and what sets this organization apart from their peers.

    The Big Challenge

    They don’t get much bigger. The system in question was long regarded as one of the largest, most complex data warehouses in EMEA. It is the backbone of a market-leading integrated container logistics and shipping company.

    The company’s 165TB of highly compressed data is used to track goods and shipping vessels around the world. Uninterrupted availability 24×7 is critical for this kind of operation, of course. As the central data hub, this system connects thousands of users that execute over one million queries every day.

    Migrating the workloads off an aging Teradata system to Microsoft Azure Synapse was key to modernizing the data estate. IT leadership found itself faced with the question of whether it would be possible to move without disrupting their business users.

    Database Virtualization is the Game Changer

    Database virtualization (DBV) is the extension of server virtualization to the database stack. Over the past two decades, we’ve seen a similar development in other spaces too. For example, networking and storage have been completely transformed by virtualization.

    The principle of DBV is as simple as it is powerful. At its core, it is software that sits between the applications and the database and translating between the two in real-time. Applications connect to the DBV component instead of the database and DBV provides the same language surface and APIs as the legacy system. DBV converts and optimizes all queries and data formats for the new cloud database. Applications can’t tell the difference between the original system and the virtualized one.

    Viewed in the context of migrations, DBV eliminates the most labor-intensive tasks. Instead of rewriting applications over the course of years, point them to DBV.

    Planning the Implementation—There is no ‘Easy’ Button

    If DBV eliminates the need for a rewrite, doesn’t that make database migrations easy? Indeed, it makes it simple. But easy it is not. Remember, DBV is only the runtime. As with other kinds of virtualization, the implementation requires extra effort.

    DBV, in this case, had over 99.75% coverage. In theory, there is no limit to what DBV can emulate. In practice, developers of DBV systems have to weigh each feature request. In our case, of the 0.25%, the customer decided to redesign the application that was outside of the current coverage.

    Another decision criterion is the choice of the destination system. For DBV to be successful, the new destination must be powerful enough to stomach the incoming workloads. This seems obvious, yet the failure of the Hadoop craze of the past decade showed it isn’t. In our case, the customer chose Azure Synapse, which was perfectly capable of processing these workloads.

    The biggest task during an implementation, though, is the data transfer itself. As a runtime, DBV relies on the data transfer to the new system being complete.

    People and Processes Are Your Biggest Obstacle

    Conventional migrations are the open heart surgery of the IT world. In contrast, DBV is a non-invasive procedure, but heart surgery, nonetheless. Implementing DBV is a team sport.

    To be successful, everybody must pull in the same direction. Executives must set the course and, once underway, relentlessly cheer on the team. Developers must refrain from wanting to rewrite code “just because.” Everybody else must execute in their clearly defined roles.

    Divide and conquer is the key principle. By structuring the implementation in tranches, the scope remains manageable at all times. Moving a limited number of applications at one time reduces distraction and keeps the team focused.

    Then, there are the naysayers. These are members of the organization who want to preserve the status quo. And finally, there is the legacy vendor. To them, DBV is a clear threat and they will do anything in their power to stop your project.

    Upfront alignment across the organization keeps the team on course even when there’s pushback.

    Move Fast to be Successful

    Because a data warehouse is constantly under development, it remains a moving target throughout the project. The longer the project takes, the more complex things tend to get.

    For each workload tranche, the team needs to execute two distinct steps. Check for functional correctness, then tune the performance of the workload. The latter concerns physical design choices such as indexes or table geometries.

    Rarely do queries need to be adjusted.

    At the end of the project, the team needs to catch up the data transfer so the new system is fully equivalent. Catching up on data transfer between tranches reduces the load in the home stretch.

    The time needed to implement the full virtualization of a system varies. For a mid-range system, this can be a calendar quarter; for a large system, it could take six to 12 months. In our case, the full implementation took 10 months.

    A New Way of Modernizing Data Estates Emerges

    What is most remarkable was the final cutover from the old to the new system. Our customer made the transition without telling their thousands of business users. Instead, they flipped the switch on a weekend, repointing all business users to the new stack.

    Business users coming back on Monday noticed their applications mysteriously running faster. But they had no idea of the magnitude of the change. That is unheard of. Even simple database upgrades cause more downtime.

    Looking back, how does this new way of modernizing a data estate compare to the conventional approach?

    Instead of 10 months, a conventional approach would have taken years. Instead of a small agile team of about 20, it would have required hundreds or even thousands of people to make changes. Coordination alone would have made the cutover a project for several calendar quarters.

    In the end, the customer saved an estimated nine figures on their five-year TCO over a conventional approach, assuming that a conventional approach would have succeeded at all. Given the high failure rate of conventional migrations, this is a very optimistic assumption.

    This project can serve as a blueprint for data warehouse migrations. Whenever time, cost and risk are of the essence, DBV is a strong contender.

  • Data Mobility: Why it’s a Must and How to Achieve It

    Data Mobility: Why it’s a Must and How to Achieve It

    The workplace has undergone a drastic change, and so has the way companies need to move their data. Wondering how those two points are connected? Let’s dig in.

    It’s clear that remote work is here to stay: Just over a quarter (26%) of U.S. employees are currently working remotely, and a staggering 36.2 million Americans will work remotely by 2025. Naturally, this huge influx of remote (and hybrid) workers has necessitated changes in IT infrastructure. It has changed how people work, engage with their corporate databases and applications and what they expect from their corporate technology infrastructure.

    In the past, companies migrated their data every four or five years when they refreshed their storage infrastructure. CIOs and storage experts now think differently about how data centers are built and optimized. Important questions all companies should consider are: Does it make sense to build out storage capacity ahead of the need? Do we really plan to have our databases and applications hosted on-premises over the next five years? One CIO recently told me, “If you aren’t talking about your future in the cloud, you aren’t paying attention.”

    The Need to Migrate Data More Frequently

    The shift toward a more flexible storage architecture, even in a hybrid cloud environment, has created the need to migrate data much more frequently, fueling the demand for data mobility. Robust data mobility is essential in today’s world: Companies need to securely and efficiently move their data to accommodate a strategy that accommodates both on-premises and cloud; even multiples of these. Data mobility constraints can’t dictate the success of an organization’s digital transformation. Moving data to the best location based on an organization’s goals—whether they’re related to cost, manageability, performance or some other factor—is critical.

    Another critical factor to consider regarding data mobility: The data must always be accessible to the end user, regardless of when or where it’s moving. In the age of remote work, people are working based on their own unique schedules, so data must be accessible at all times.

    In fact, data from Microsoft recently revealed that 30% of its employees choose to work at night. Gone are the days when systems could be offline for data migration during “non-working hours.” Remote work demands continuous data access so employees can stay productive and work at their convenience.

    With this in mind, here are three key steps companies can take to achieve data mobility.

    1. Strategy
    When determining where to store data, consider who will need access to the data, what performance level will be required and what the cost will be for each data storage location. Is everything best contained in a single public cloud? Is a multi-cloud strategy or a hybrid cloud storage environment a better approach? We often talk about data mobility and data migration interchangeably, but not all data migration solutions can continuously move data between storage environments.

    Organizations must also determine how they will move their database and applications to the new environment. If this step isn’t addressed during the strategy stage, it can become an afterthought and create problems down the road.

    2. Deployment
    Once an organization has determined which storage environment best fits its needs, it’s time to move the data from its source to its destination. A single, one-time migration involves moving the data from its current location to a new location and stepping away until the next migration. Data mobility solutions are ideal when data needs to move back and forth, requiring data mobility solutions (e.g., moving from on-premises to a multi-cloud environment).

    During this step, organizations must ask the following questions and plan accordingly to minimize any negative impact: How long will this migration take? How secure is the data in transit from source to destination? How disruptive will the transition be to end users? What will the impact on the organization be? How much manual effort is required?

    Sometimes moving data can make applications sluggish, affecting productivity and resulting in workers overloading the help desk with inquiries about what’s happening. Data migration tools can help organizations tackle deployment efficiently, securely and without disruption to end users (again, continuous data access is vital).

    3. Assessment and cutover
    After the data has arrived at its new destination, it’s time for the cutover process (i.e., running the application in its new location and removing the old storage). Cutover is when problems can arise if everything isn’t mapped correctly. Organizations need protections in place to ensure there is no risk to their operations should something go awry during the process. Additionally, minimizing the impact of this transition for end users is vital, so organizations should also be doing whatever they can to reduce downtime.

    Companies can consider leveraging a data mobility tool that can synchronize in the background without impacting users. So, while users are still working on the old site, new infrastructure can be updated simultaneously, requiring just seconds to minutes of cutover. This time can be planned for off hours so that it’s minimally disruptive and doesn’t require notifying employees.

    The technology landscape is constantly changing, and so are storage vendors’ offerings. Companies need solid data mobility to pivot at a moment’s notice to take advantage of newer, better and more cost-effective capabilities. Data mobility gives companies the flexibility to stay competitive, and data migration tools that allow continuous data access keep workers productive.

  • The Database of the Future: Seven Key Principles

    The Database of the Future: Seven Key Principles

    The database of the future will be more than just a database. Instead, it will be a platform that focuses on the user experience and abstracts the technology. Looking at the evolution of application development, an enormous amount of effort has made it easier to build and deploy applications. Similarly, databases need to evolve for ease of use with a delightful developer experience and an exemplary user interface that surfaces features and functionalities that engineers will actually use.

    Here are seven principal features needed to chart the development of the future database.

    1. Serverless by Default

    Serverless is unquestionably the most significant paradigm shift in software engineering in the last five years and the one that’s been realized the least. There aren’t that many people at this point that are all in on serverless. It’s the shift away from buying a server to a service that does what you need and scales with your growth.

    Serverless by default is the only way to ensure the database of the future will be easy to operate while being consistently reliable. Serverless is evolving from running functions in the cloud to becoming the standard for fast-paced development teams that don’t want to worry about vCPUs or node pools but focus on outcomes.

    The companies that are doing it the best still deploy servers, but they are leveraging products that scale independently, regardless of how many servers they have. Their component vendors can increase the number of resources allotted to them, and they only pay for what they use, and the architecture of the solution scales in that way. They’re not buying a single server and pushing it as hard as they can. They’re telling one platform, ‘here’s my code,’ they’re telling another, ‘here’s my data,’ and then that scales up based on usage much, much farther than buying a single server.

    When people think serverless, they think JavaScript and Lambda, but there’s serverless PHP out there, too. It’s not just the JavaScript community. Other software paradigms are going for this. We will see more and more people pulling this out when they need to do some quick code and they want to ship to production as quickly as possible and scale as quickly as possible.

    2. Easy to Operate

    The most significant advancements in DevOps have been freeing developers from complex operations that overwhelm their day-to-day operations. Engineering teams today are organized around product and business goals, not maintenance and servicing. But databases have yet to catch up. Product teams still rely on experts to perform overly complicated database operations tasks.

    The database of the future must fit into everyone’s DevOps workflows. It must be usable for any developer and leveraged by every team within a technical organization. The database needs to be operable by everyone and no longer require database admins to manage backups and capacity planning or worry about disaster recovery.

    Developer-centric features like database branching, database developer environments, autoscaling and usage-based billing will be commonplace.

    3. Reliable

    Reliable simply means it’s harder to hit the scaling limits. Not only does it mean that the database is there, but that you get the right information when something is going wrong, and you can collaboratively help scale.

    Nothing scales infinitely. There are not enough computers in the world to scale something to infinity. You’ll always be able to query a database and pull too much information out of it too fast. No matter how many cars you get or how much horsepower you have, you can’t go a million miles an hour. A good database must let you know when you’re hitting those limitations and help you move past them, whether at a small scale, medium scale or large scale.

    4. Interoperable

    Future databases will be accessible to every imaginable client–from smart refrigerators to fleets of autonomous delivery vehicles. But this client-agnostic approach requires planning for many more transactions and connections than most current databases could ever manage simultaneously.

    In the future, databases can handle unlimited connections through smart connection pooling, query replication and intelligent query routing. Databases will also need to serve a wide set of connections and clients. Although we are already seeing many databases offering web APIs and new connection types, as these get tested at scale, we will begin to see them adopted and used to power the next generation of applications.

    5. Globally Distributed, Locally Available

    Today, most businesses and applications don’t need a global database, which often introduces unnecessary complexity and operating costs. However, there are many reasons the future database will need to be globally distributed, as they must be located where you need them the most.

    The key to this is knowing what your requirements are. Many people look at multi-region and think it’s faster reads, failover, scaling and breaking the speed of light. Ultimately, it’s all a series of tradeoffs. For example, when you read from a local replica, you trade off consistency because you have asynchronous replication. But this is really leveraging the global internet to deliver a better outcome where it’s necessary.

    Being compliance-ready with regionally stored data enables you to scale rapidly to a new region and provides a great user experience by quickly serving locally available data. High-transaction, low-latency applications such as mobile games already need this capability.

    But there’s one caveat: Global data distribution cannot break principle number two—being easy to operate. Tools will need to be elegant and have straightforward interfaces as their main goal is to make operations easier, not harder.

    6. Intelligent

    The future database is intended to be used by people and will be able to tell them how it needs to be used and how to make it better. All the tools you buy today can only give you the data you need to make some educated guesses. The future database will replace that with concrete recommendations, then self-healing actions.

    This starts with basic data collection and observability and moves to, “let’s record every query that someone makes and use some decision engines and some AI and recommend how they can shard automatically.” It will be able to say, “I’ve recorded your database use for the last 30 days; this is how you should shard for optimal performance. Click the button, and we’ll do it.”

    The future database will say, “You’re scaling too far for the single machine at a per-user level. You must break it down into two or break it down into four, and we figured out how to do it for you, so you don’t have to figure that out. We’ve sharded your data on your behalf.”

    7. Linearly Horizontally Scalable

    Future databases will also need to be designed for future scale. Only a handful of companies on the planet have hit a scale that tests the limits of current technologies, but as information grows, more companies will get there. The next databases will do that by automatically scaling both vertically and horizontally within seconds. Many existing databases require a maintenance window, replication and a failover before they can be scaled up or out. But downtime is unacceptable, and scale should not come at the cost of performance. And it doesn’t have to. The database of the future will scale intelligently and without a blip on the status page.

    In short, the consumer should be able to get what they need when they need it, with no risks. It should be easy to say, “I’ve doubled the number of servers, I’ve doubled the amount of throughput. I’ve quadrupled the number of servers and the amount of throughput.” This is what sharding provides. Good sharding happens automatically at a super high scale, and you’ll only pay for what you use as you go along. The future database will do all of this without users having to turn a knob.

    In conclusion

    It will take the entire database industry to agree on these principal features, adopt a user-focused approach and build future database platforms designed to make engineers more successful by delivering superior products and services to their customers. I envision a day where every company no longer worries about its infrastructure and can simply focus on its business. I want development teams to take back control over their development workflow. Using a database should be as easy as writing code.