I had the chance to catch up with Jeff Sussna (@JeffSussna), founder and principal of Ingineering.IT, ahead of his keynote address on continuous design, scheduled for DevOps Days Atlanta, April 26-27. He discussed the importance of designing for service, responding to the unexpected, and the importance of building empathy across teams.
Derek Weeks (@weekstweets): Today I’m really happy that we have Jeff Sussna joining us for the latest in this series. Jeff, why don’t you introduce yourself?
Sussna: Sure. Thanks for having me. I’m an independent consultant. I’ve been around, since rocks were young or the 80s, whichever is older. My particular background is that I have built systems and led organizations across the entire development, QA and operations spectrum. So, I’m a little unique in that respect.
My current focus is on helping IT organizations and digital businesses really bring together their ops and design thinking so they can not only go faster and not only be more resilient, but provide more customer value at the same time.
Weeks: Let’s talk about that a little. How is continuous design—a subject you have written a lot about—coming into play? How can it help us be more resilient.
Sussna: Just to explain a little about what we mean by continuous design. It’s basically bringing together the entire organization and a unifying design in operations. It’s taking what we are doing in DevOps and expanding it to include product, design and support. It lets the whole organization really have an agile conversation with a market and with its customers.
The issue that we face is that we live in a service world now. The point is no longer delivering products like cars coming off an assembly line. It’s much more about responding to our customers and having relationships with them. This is happening in a world that is more and more complex while less and less is in your control. We can’t figure everything out in advance. We have to have the ability to respond to the unexpected. We have to be able to do that at every level.
“This is happening in a world that is more and more complex, while less and less is in your control.”
I will give you a couple of examples of things that are perfect illustrations of this:
I recently wished a friend of mine happy birthday. The reason I did that was that because there was a notice on my calendar that said it was her birthday. It was wrong. It wasn’t her birthday. I had no idea where that notice came from. Did it come from Skype? Did it come from LinkedIn? Did it come from email? I had no idea.
We face that in IT, too. Systems are becoming more complex. We develop microservices. We use public and private clouds at multiple levels. We’re no longer in a situation where we can control things. We have to be able to respond and respond at all levels.
When we make design and operations unified and continuous, we are able to say, “Where did we think we were going? Where would we need to go? and what do we do next?”
What I talk about in my book, in my workshops, and all my work is that this needs to happen at every level. It’s not just a matter of designing for failure inside the data center or inside the infrastructure. We also have to do it at other levels.
Here is another example:
I was trying to get paid recently by a large enterprise client in Europe. They were trying to wire money internationally and my bank wasn’t really set up for it and they were having problems. They just kind of gave up. I kept getting these messages saying, “Sorry, we tried paying you and it didn’t work.” That was the end of it.
I started to get frustrated and my client within the enterprise started to get frustrated to the point where they sent a scathing email to our AP department which they CC’d me on, saying, “Why can’t we take the lead to get his guy paid?”
That’s an approach that is based on resilience in the sense of assuming that something can go wrong and figuring out what he can do to fix it when it can go wrong. As opposed to the traditional approach where we’ve been trained to push certain buttons and take certain actions. If those actions don’t work the way they are supposed to, well, I guess that is someone else’s problem.
https://www.youtube.com/watch?v=ISSMHmwIMtA
Weeks: This brings to light some recent conversations I was having with Paula Thrasher at CSRA. She was talking about developing systems and how to make them more resilient. She is using pictures as part of her conversations with people to help visual their work. What work steps are there? What work is flowing? What is communicating with what?
Are you taking similar approaches with continuous design in how you work with clients to pursue it?
Sussna: Well, I try to introduce them to the principles and I also try to introduce them to a set of practices which actually comes out of Mark Burgess‘s work on promise theory. It is really a conceptual model for how we think about success and failure and how do we think about service. For example, Amazon helps you get everything you need in your life from shaving cream to batteries to snow tires to books as quickly and easily as possible. In order to keep that promise they make a whole variety of other promises. Some of which filter all the way down to a promise to be able to go over and make a change to production as quickly as possible.
Once you take that mindset. The interesting thing about a promise and the reason we use that word is because it is very intuitive. We all know what a promise is. We all make promises to each other every day. On the other hand, when we think about it in terms of service, IT, or whatever it may seem a little odd. The thing about promises is that on the one hand we are making commitments to do things and on the other hand promises sometimes get broken. That is actually good because it forces us to think. If I promised to pay my vendor. What do i do if I’m not succeeding in paying my vendor?
The thing about promises is that on the one hand we are making commitments to do things and on the other hand promises sometimes get broken. That is actually good because it forces us to think.
It’s sort of flipping our mind. Again, we are doing this in DevOps world where you start thinking about things like mean time to repair (MTTR) instead of mean time between failure (MTBF). We shift from how do we create a situation to how do we create a situation from where nothing will ever break—which becomes less and less possible. When then need to shift to a situation where we can respond more and more quickly.
We go to executives and say, “We don’t want to worry about how often stuff breaks anymore,” and they freak out. We have to teach them and we have to teach ourselves that we can’t prevent things from breaking. Instead, let’s be able to fix them so quickly that maybe no one notices. My focus is on really helping people shift their mindset from thinking about ourselves to thinking about who we are helping. And from thinking about what we are doing to thinking about how well it succeeds and how well it overcomes problems.
We have to teach them and we have to teach ourselves that we can’t prevent things from breaking. Instead let’s be able to fix them so quickly that maybe no one notices.
Weeks: You talked about delivering on promises as quickly as possible. How does continuous design account for doing things as quickly as possible but making sure the quality is there at the same time?
Sussna: In two ways—one way is that when you do things in small increments you are able to find problems more quickly. This is classic; it comes out of lean. It comes out of integration. It’s pretty basic stuff for our community now that it’s much easier to find and fix a bug five minutes after you change a code than five weeks after you change the code.
When you put things like Linux, agile, DevOps, and design all together, they all focus on incremental feedback loops where you discover the gap between what you think you’re accomplishing and what you’re actually accomplishing very quickly. Secondly, when you take this all to the way to the marketplace and you make it part of the relationship with your customer, you can reduce a tremendous amount of waste.
The way to think about continuous design is: it’s all about steering. Think about a boat and you’re trying to sail across a bay. You can’t just point the boat at the other side and say go because the winds are changing and you’re going to be able to respond to things that you can’t predict. If you sail for 20 minutes then discover you had pointed in the wrong direction, you’re going to be way off-course. You’re then going to generate a tremendous amount of energy getting back on course.
What continuous design says is just an extension of continuous integration and continuous delivery taken all the way though the business. When we steer continuously we steer efficiently.
What continuous design is really just an extension of continuous integration and continuous delivery taken all the way though the business. When we steer continuously we steer efficiently.
Weeks: I know you’re going to be keynoting DevOps Days Atlanta coming up in April. Chris Corriere, one of the guys on the organizing committee, tells me that you’re leading a full day workshop on continuous design before that. Maybe you could tell some of the people that are attending DevOps Days Atlanta why they should be there a day earlier for your workshop and what things you’re going to address during that time.
Sussna: To some degree what I am going to address is everything we have been talking about for the last 10 minutes or so—relative to DevOps. I think the key thing is, and we need to think about it. We need to think about more than just going fast. One of the big misunderstandings that I see with DevOps is this notion that it is primarily about delivering application changes to production faster. That’s only half of it. We really need to think about from the perspective of providing service.
One of the big misunderstandings that I see with DevOps is this notion that it is primarily about delivering application changes to production faster. That’s only half of it. We really need to think about from the perspective of providing service.
You know what we are talking about is essentially developers and operations people providing better service to each other. As a result, they can deliver better service to the business.
Where we talk about microservices. You know that word service is in there for a reason. If all you do is you kind of shatter your organization and shatter your architecture into a bunch of little pieces, you still have to figure out how those pieces come back together into something coherent. The answer to that is taking a really deep service-oriented approach. That is very much what my workshop is about. What does that word even mean and how do we do it?
Weeks: You mentioned thinking about interactions as delivering better service to one another within the organization. How does empathy come into your thinking around DevOps and Continuous Design?
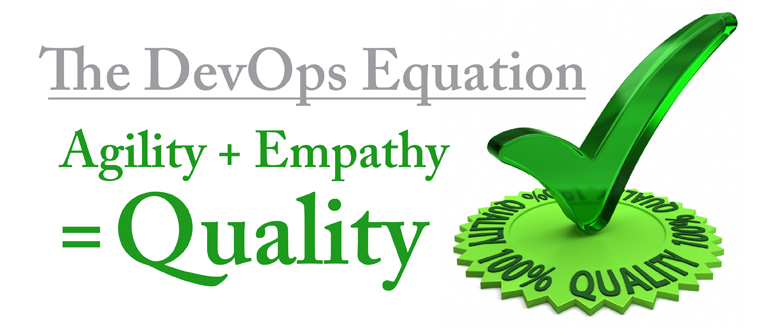
Sussna: I’d like to say agility plus empathy equals quality. What I mean by that, in particularly empathy, I think it’s important to take a minute and clarify. When we talk about empathy we are not talking about wallowing in someone else’s pain. We’re not even necessarily talking about things on an emotion or feeling level. It’s very simply the ability to see things as if from an other’s perspective. I will give you a prime example of where that comes into play and how it’s important and how it helps.
Agility + Empathy = Quality
When I work with clients, I tend to look at their process using their organization from the product beginning to the support end. Often times I see support getting the short end of the stick. I see places where they get phone calls from customers with features that they don’t even know exist yet. They sometimes get talked down to by development or product or even operations. They say things like, “Well you’re just supposed to support the stuff. You’re the young people. You’re the less experienced people.”
When we have the ability to see things from their perspective, we can think about how support is actually experiencing our delivery process. If we don’t think about them when we go through the process of delivering new features, they will be lost. Them being lost will show when customers call for help. That will significantly affect customer satisfaction and then even beyond.
The reason we need to empathize with support is so we can empathize with the customer. Often times when we build things and we don’t think about the notion that our customers might have trouble with it. On the one hand we have the illusion that if we design it and we build it really well, they won’t have trouble. We can’t perfectly predict who they are, what they need or what they will encounter. There’s an inevitability to the idea that they are going to need some amount of help.
Weeks: I think that is probably the best description of empathy within a DevOps environment that I have heard anyone talk about. Jeff it has been a great conversation. Thank you very much. I really appreciate it and we look forward to seeing you at DevOps Days Atlanta coming up.
Sussna: Thanks. It has been great talking to you and I am really looking forward to the conference. It will be fun.
If you want to learn more about continuous design from Jeff, be sure to join us at DevOps Days Atlanta. I will also be at the event giving an Ignite Talk, titled, “Real Heroes Draw Pictures,” focusing on lessons learned from the 31 DevOps and continuous delivery reference architectures I assembled.