Tag: cloudify

  • Solving the Speed Paradox With Open Source PaaS

    Solving the Speed Paradox With Open Source PaaS

    The number of DevOps tools keeps growing, as does the number of cloud resources and options to manage those resources. On EC2 alone, AWS offers nearly 400 instance types across storage, networking and operating systems. Complicating this further is that users can choose from machines located in 24 regions and 77 availability zones.

    This proliferation is driving a ‘speed paradox’ wherein the faster you grow the more fragmented and complex your ecosystem becomes which, in turn, slows everything down. Most DevOps teams struggle to keep up with the demand for more environments from developers.

    The Speed Paradox

    The Rise of the Internal Developer Platform (IDP)

    One intriguing solution to the speed paradox is the internal developer platform (IDP). As its name suggests, an IDP provides a single place where developers can find all the resources needed to run their environments. An IDP allows developers to speed development processes by offering improvements in:

    • Efficiency – Simplifying access to development and testing infrastructure through a self-service experience;
    • Consistency – Providing a consistent way to consume infrastructure resources across teams; and
    • Visibility – Providing a single place to see all the pipelines, workflows and states associated with each environment.

    Gartner sums it nicely: “Product teams often struggle due to disparate tools and disjointed workflows as they accelerate digital transformation. Software engineering leaders leading platform teams must establish internal, self-service developer portals to enable consistency and scale cloud, agile and DevOps initiatives.”

    Lessons From the ‘PaaS-t’

    The idea of a developer platform isn’t new. Previous-generation PaaS—Google App Engine, Heroku Cloud Foundry, for instance—provided a simple interface to write applications by abstracting cloud resources. But early PaaS failed, perhaps mostly due to the long tail of developer needs. Back in 2013, I observed: 

    “Every Access project will eventually fail because, while 80% of what the user wants is fast and easy to create and the next 10% is possible with difficulty, ultimately the last 10% is impossible because you can’t get far enough underneath the built-in abstractions and users always want 100% of what they want.”

    You can sum up the failures of early PaaS in three points:

    • Too opinionated: It is hard (impossible?) to control the way the platforms run their infrastructure resources. You’re dependent on the platform vendor for customization.
    • Limited to simple web applications and language choices: Modern SaaS applications are complex and include backend services that don’t fit that architecture.
    • Maturity: Early PaaS attempted to abstract cloud when it was a young, moving target.

    What’s Changed?

    With early PaaS, we traded simplicity for flexibility. Finding the right balance between the two is the heart of the challenge. Kubernetes and Docker, as well as IaC tools like Terraform, Cloud Formation and Azure ARM are a great substrate: They provide a consistent framework to manage applications across a wide range of infrastructure resources among clouds. Maturity and adoption of these tools reduces barriers to build a developer platform. This opens the opportunity to create a custom platform for each organization, allowing teams to control how their platform fits into their organization’s environments. It also offers balance between simplicity and flexibility, because each organization can choose where to draw the line—and even redraw that line without being dependent on an external vendor.

    The next-generation platform 

    Enter Backstage

    Backstage is an open source IDP project led by Spotify. Its three main parts are:

    • Service Definition—Based on the Kubernetes template format, it provides a service descriptor that fits into a range of services: monitoring, CI/CD and Git repositories
    • Backstage service catalog—Basically a web application with a database backend providing a single point of access to manage resources
    • Integrated tooling via plugins —A marketplace of integrated resources

    Here’s how an IDP based on Backstage can look:

    An example of an internal development platform based on backstage

    We can use Backstage to organize all development services and resources such as our squad KPI, the development pipeline, API and Git repositories, all in one place.

    Turning Backstage Into a Full-Blown PaaS

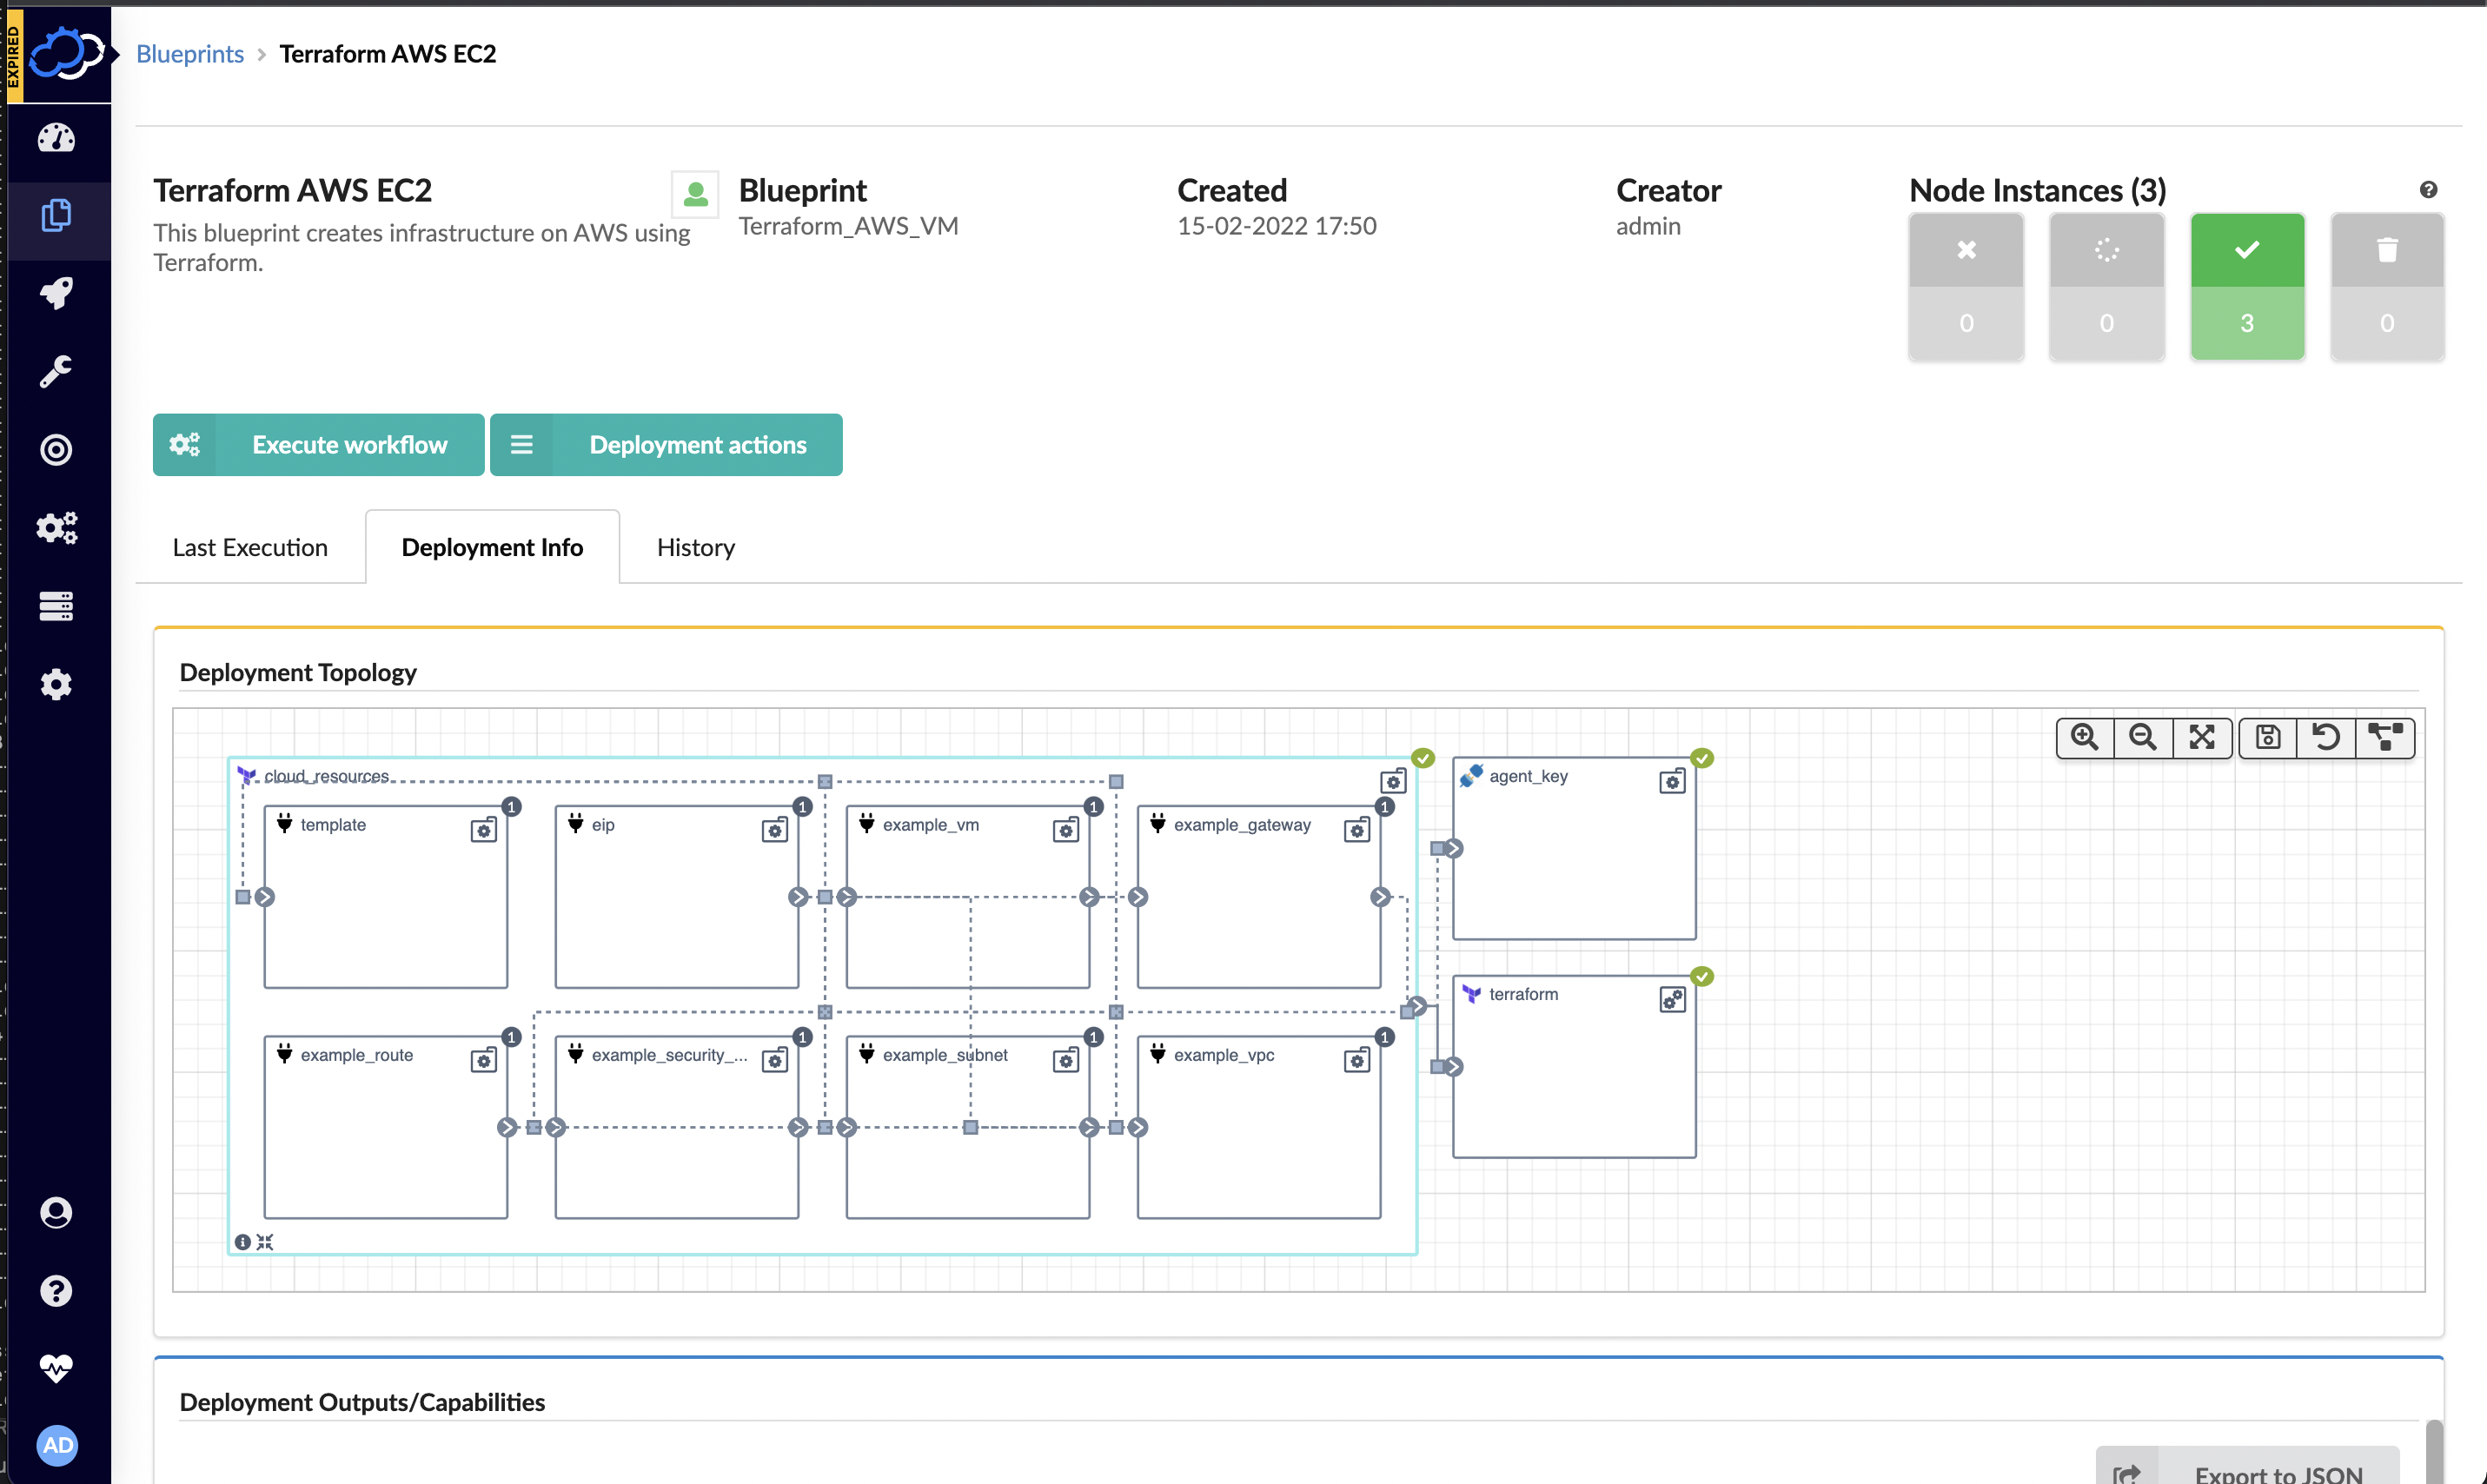
    One of the missing pieces in Backstage is infrastructure provisioning. Adding it turns Backstage into something closer to a full-blown PaaS. Cloudify provides a remote execution engine that integrates with a variety of infrastructure resources and allows users to organize them into a self-service development or production environment. The integration of Cloudify into Backstage includes synchronizing the development environments into the Backstage service catalog and allowing self-provisioning of those services through the Backstage portal or through GitOps.

    Integrating Cloudify as a remote execution engine to Backstage 

    You can watch a demo or get more information on the integration from the Cloudify Backstage Git repo.

    The End of ‘Growth At Any Cost’

    Last year, Sarah Wang and Marti Cassado analyzed the impact of cloud spending on hypergrowth companies. As tech companies trade away efficiency in pursuit of velocity, they face a non-sustainable growth model where cloud costs surpass 50% of total revenue. Wang and Cassado’s analysis illustrates how this condition directly impacts a company’s profitability—and valuation.

    In today’s market upheaval, it’s even easier to see how a “growth at any cost” policy is unsustainable. Today, DevOps teams have to find ways to support growth while controlling costs. This forces organizations to better control how development teams use cloud infrastructure. 

    IDPs can become a major tool in this effort. Unsurprisingly they’re becoming the next hot DevOps trend. Backstage provides a great framework and ecosystem to shorten the time a team needs to build its own internal platform and Cloudify provides the open, remote execution engine with a single place to organize infrastructure resources into a self-service environment. The integration turns Backstage into a full-blown PaaS.

    The current Cloudify-Backstage integration is only an MVP release. Next, we’ll deepen the integration, providing more monitoring within the Backstage portal. Here, you can find more information on our open source contribution to Backstage and offer feedback.

    An Open Source Solution to the Speed Paradox 

    The “speed paradox”—where the faster you grow the more fragmented and complex your ecosystem becomes, which in turn slows everything down—need not grind our DevOps agility goals into the ground. By using open source Cloudify integrated into the Backstage project, DevOps teams can avoid becoming the new bottleneck in software development agility goals. 


  • Cloudify Integrates DevOps Automation Platform With Terraform

    Cloudify Integrates DevOps Automation Platform With Terraform

    Cloudify this week announced a free user interface (UI) module that extends its infrastructure provisioning platform and enables DevOps professionals to integrate unlimited Terraform modules.

    Nati Shalom, Cloudify CTO, said Terraform UI provides a familiar construct for DevOps teams using the open source DevOps automation platform to provision infrastructure-as-code (IaC). The module enables DevOps professionals to seamlessly import Terraform modules to Cloudify without writing blueprints or any additional glue code, he said.

    Cloudify now automatically generates the wrapper required for each Terraform template to enable DevOps teams to collaboratively manage secrets, execute concurrent deployments, store states remotely and monitor deployments, users and versions via any Git repository. Those Terraform modules can then be integrated with application programming interfaces (APIs) and continuous integration/continuous delivery (CI/CD) platforms as DevOps teams require.

    DevOps teams can also import existing automation modules and scripts into Cloudify. Those modules and scripts can be automatically converted to environments that can be centrally managed via the Cloudify console or via export to ServiceNow’s IT service management (ITSM) platform as a software-as-a-service (SaaS) application.

    That approach provides the added benefit of enabling DevOps teams to centrally manage all Terraform modules and versions via a single console as part of an effort to reduce misconfigurations that lead to security breaches, he added.

    Cloudify enables DevOps teams to create a self-service catalog and portal through which infrastructure can be managed. Many DevOps teams have built their own portals to manage this process. However, Shalom noted those DevOps teams then need to devote resources to maintaining that portal when those resources could be allocated to other critical tasks.

    DevOps teams can not only use Cloudify to apply patches, change topologies, add security features, make configuration changes or make additional resources available, Shalom added, they can also now integrate Terraform tooling with platforms such as Kubernetes or other automation frameworks such as Ansible. Cloudify also makes available an enterprise-grade version of the platform with these integrations.

    It’s not clear how much time and effort IT organizations are investing in building and maintaining DevOps environments. In many cases, however, organizations should probably revisit decisions about building capabilities that, at the time, didn’t exist. That doesn’t necessarily mean that replacing custom DevOps tools makes sense across the board, but it is likely that, in the intervening years, the range of tooling made available via DevOps platforms has greatly expanded. Relative newcomers to DevOps, meanwhile, are enjoying the benefit of platforms they did not have to construct themselves.

    In fact, Shalom noted that, in terms of DevOps adoption, an inflection point has been reached as more organizations launch digital business transformation initiatives that require applications to be both built and deployed faster than ever. The challenge, of course, is enabling that to occur both safely and at a reasonable cost.

  • Why DevOps Needs Cloudified NPM

    Why DevOps Needs Cloudified NPM

    One of the three “ways”—or principles that DevOps guru Gene Kim articulates as defining DevOps—is amplifying feedback loops. One of the key ways that Ops contributes to this amplification is by implementing rich monitoring instrumentation of operational conditions. The move toward more automated configuration management and the rise of cloud-friendly application performance management suites have gone a long way to providing strong feedback loops. However, network performance monitoring (NPM) is sorely in need of cloudification to become relevant to DevOps.

    In one of my previous articles on devopsy.kinsta.cloud, I wrote about the impact of DevOps on IT operations management, and noted that infrastructure management tools have largely lagged behind APM in terms of becoming cloudified and API-friendly. NPM is a case in point. Just to be clear on terms, by network performance monitoring, I’m talking about monitoring that collects metrics such as latency, TCP retransmits and out-of-order and fragmented packets. These four metrics can tell a network engineer a lot about whether the network is the root cause or a major contributing cause to application performance issues. Other metrics and data points that are highly relevant to NPM are interface utilization percentage, traffic flow statistics and, for any apps or services that rely on internet communications, BGP paths. These latter metrics and data sets help engineers locate underlying causes in the network, such as congestion on an interface, large spikes in flows, internet path changes or correlation of performance issues with traffic traversing a particular ISP’s network. Sounds great, right?

    The problem is, the way these metrics have been collected is all wrong for DevOps practice. For the last two decades, NPM tools have fallen into two main buckets: free, manual tools such as TCPDUMP, MRTG and WireShark; and monolithic, siloed commercial tools. Nobody will ever dispute the value of free tools, but at a certain point, chasing problems around with manual tools just doesn’t scale, so sooner or later most NetOps organizations have to invest in commercial tools.

    Commercial NPM tools were primarily architected in a pre-cloud, pre-DevOps era, when data centers all were inside the WAN, applications were centralized and monolithic and all users were somewhere else on the WAN in a campus or branch office.  Metrics collection was performed by appliances via connecting to the span interfaces of major routers and switches at choke points—the junctures of LAN and WAN connectivity.

    That era is disappearing rapidly. Most new applications are being built on a distributed basis, leveraging hybrid cloud. With distributed application components, there is a much more complex mesh of communications at play, much of which will cross networks and the internet. Further, in most cloud environments, you simply can’t deploy an appliance—not even a virtual one, since in many cases there simply are no span ports.

    The problem with traditional NPM goes beyond a lack of fit with modern application architectures. NPM appliances are designed as vertically integrated systems with a GUI as the only real way to get data out of them. As a result, their APIs are usually at best second-class citizens. This is problematic for DevOps because amplifying the feedback loop means being able to serve meaningful real-world data up across different teams.

    The cloud and DevOps gap in NPM is pronounced enough that major analyst firms have taken notice. In May of this year, Gartner analyst Sanjit Ganguli published a research note titled, “Network Performance Monitoring Tools Leave Gaps in Cloud Monitoring.” It’s a fairly biting critique of the NPM space that says, essentially, that the vast majority of current NPM approaches were largely built for a pre-cloud era, and are unable to because the new complexities brought by decentralization and full-stack virtualization. As a result, network managers are left in the lurch when trying to adapt to the realities of digital operations.

    What is needed to cloudify NPM and make it DevOps-friendly?  First of all, with distributed, hybrid cloud applications, there need to be options to embed NPM metric collection agents in cloud server deployments, either directly on app servers or load balancers such as NGINX or HAProxy. With container management and configuration automation tools, deploying lightweight NPM agents to more distributed points is very doable. By collecting NPM metrics on or very close to application servers, you get the most accurate read on “is it the network?” when app performance issues arise.

    Another key aspect of cloudifying NPM is where the analytics happens. Appliances have severe compute and storage constraints. In the era of big data and cloud-scale compute economics, relying on appliances for NPM analytics is beyond outmoded. There are a plethora of open-source big data platforms as well as a growing number of  emerging commercial SaaS options for NPM analytics. Today, big data network analytics platforms allow engineers to perform deep ad-hoc analyses on billion-row datasets and get answers in seconds.

    DevOps’ mandate for amplifying the feedback loop plus the availability of copious cloud compute capacity means that there is no excuse to not aggressively measure everything, including network performance. Networking teams can and must go beyond config automation to change the way and the scale they gather and share metrics to server and app dev teams. Cloud-friendly NPM is a needed step to bring about Net DevOps as a lived reality in IT.

    About the Author / Alex Henthorn-Iwane

    AlexAlex Henthorn-Iwane is the vice president of Marketing at Kentik. He has more than 20 years of experience bringing new technologies in networking, security and software to global markets. Henthorn-Iwane leads the global marketing strategy for Kentik and helps the company bring its story and solutions to network-dependent organizations around the world. Connect with him on LinkedIn, Twitter or SlideShare.


  • The Hypocrisy of Vendor Neutrality

    The Hypocrisy of Vendor Neutrality

    Disclaimer: I’m going to name the product and company I work for in this article.  I assure you this does not mean this post is a product pitch.  Really, I promise.

    In my capacity as the open source community manager/dev relations/community evangelist/[Enter Alternate Title Here] at Cloudify, I’m a huge advocate of knowledge sharing. My personal credo is that the single most important element in a product’s success is spreading the wealth of knowledge — empowering your users to be autonomous, and even hopefully achieve a level of understanding that surpasses the original development team. Intelligence of the masses. Better code. Better product.

    To this end, I’ve been trying to cultivate a culture among our R&D to document document document everything you do.  I’m not talking about a product’s traditional documentation. I’m talking about those less formal processes of trial and error and learning that are never formally written down anywhere – and are lost when the person moves on to new endeavors, or even forgets after a time.

    I’m also a big fan of internal wikis…but that’s an even tougher culture to cultivate.  On top of toiling endlessly to write a great product, and then adding the necessary product tools to make sure people can actually use it – from docs to tutorials – the last thing devs want is the added overhead of actually having to document the technical aspects of the process.  So I relent.  But I have a dream, nonetheless.

    Backtracking to the actual topic at hand.  So in terms of interesting stuff my team is always doing – and working with excellent, awesome, interesting and cutting-edge open source tools – we write a lot of blog posts.  Really good ones (if I may say so myself) – technical, hands-on, useful…actionable posts.  Kind of like meta-documentation.  On top of these posts, and the existing tools we leverage in our daily work – we’ve actually discovered a lot of gaps with known tools, and have written additional open source tools that help us get the job we need done – not even as our primary work at hand, just as an added bonus.  And I’ve found a scathing irony/hypocrisy when it comes to propagating this knowledge to the masses.

    True story.  One of our devs did an excellent job of porting Vagrant .box files to AWS.  He wrote a really great post about it.  There was one caveat though, in the first line he had mentioned why he had needed to do so in the context of his work. He made the major faux pas of mentioning the product he did this for.

    I submitted the article to a prominent tech publication – and the response I received was:

    “Sorry your product is mentioned in the first paragraph of the post…we’ll need to pass”.  

    That was the only mention of the product in the entire post (btw, in this new post, we were actually asked to add a bit more info on the technologies mentioned in the article, hence the augmented intro. The initial post started with the pain point).  The entire post focused on Vagrant and AWS  – these products they had no issue with.  But the mention of our product in the first paragraph.  Tsk tsk tsk.

    Now, I truly and deeply understand that there are plenty of blog spammers out there.  Doing all kinds of SEO shenanigans to build traffic, and writing fluffernutter posts.

    But seriously just reading the article, and personally I felt this was one of the best written ones I’ve had, you can tell this one does not even remotely fall under the same category.

    So then I started to have a discussion with a team member who really likes to write posts.  And I love him for that.  And we asked the crazy question of… when do you reach that critical mass that you can freely mention your product and its values in the context of other technologies and technological needs without being perceived as pitchy?

    Why are certain technologies from the Vagrants to the Dockers (open source) and the AWS to VMwares and even Apples (not even remotely open source) given a stage to discuss the benefits of their products without being perceived as pitchy – while others are completely passed over or even scorned for their mention?

    Is it a critical mass thing? A tipping point? Is it what delivers traffic?  How can you know a product won’t deliver traffic if it’s not allowed to be mentioned? How can a product garner adoption if it isn’t known about?

    And let’s be honest, nearly all open source tooling these days has a monetization angle – people can’t work for free, it just isn’t a sustainable model.  So every single tool out there has what to gain.

    So who are those powers that be that decide which product is worthy of being mentioned, and those that are only possibly allowed to be mentioned (best case scenario) in the author’s bio?

    The even bigger irony is that these sites that are offered these technical posts, and are monetizing themselves off of these contributions, and building their own reputation and traffic and traction and SEO…

    I’m not intending to sound bitter. I know these sites receive A LOT of content, and have to be very strict with moderation.  I get it.  I also know that while pastures may seem green to us on this side of the keyboard – tech sites from the prominent GigaOms to the more niche Dr. Dobbs are shutting down left and right.

    And this is where I have to give a shout out to the DZones, devopsy.kinsta.cloud and Developer.coms of the world – who do understand the technical worthiness of posts that albeit mention a now esoteric product, but provide information of technical value to their readers, and publish them.

    Who knows – maybe the sites that have the foresight to give respect to new tooling will have gotten in on the ground floor of the next Docker.  (Because you just can’t have a technical post without mentioning Docker.)

  • Repex – Regex Management Simplified

    Repex – Regex Management Simplified

    Our Versioning Complexity

    Cloudify is a Python shop.

    Our REST service is Python.

    Our Workflow Engine is Python.

    Our Plugins are Python.

    We have different version formats and different dependencies across different types of files which need to be changed when a version is updated.

    This is complex, to say the least. We didn’t want to manage this manually having more than 60 repos to take care of when handling version updates.

    Why not sed?

    • sed is a bitch, isn’t it? It’s unmaintainable and unmanageable. While this is solely my opinion, handling hundreds of files, each change in a different context without any safety net, makes sed something you should walk away from.
    • sed isn’t configurable.

    Why not Jinja?

    Using Jinja templates, while safe, was out the windows pretty much instantly as we needed the repos to be usable out of the box or we’d be forcing users to change templates so that they can use our product.

    The Solution

    We turned to Regex. Yes, there is the regex problem. You’re probably familiar with the famous quote:

    –Some people, when confronted with a problem, think “I know, I’ll use regular expressions.” Now they have two problems.

    While this can be true, it also depends on how you use regex.

    I believe we’ve done this well.

    Repex

    We developed repex.

    repex allows you to specify the structure of changes you need to perform in YAML format:

    variables:
      replace: 3.1.0-m2
      version: 3.1.0-m4
    
    paths:
      - description: demo thing
        path: repex/tests/resources/mock_VERSION
        match: '"version": "3.1.0-m2"'
        replace: "{{ .replace }}"
        with: "{{ .version }}"
        to_file: repex/tests/resources/mock_VERSION.test
        validate_before: true
        must_include:
          - date
          - commit
          - version
      - description: handles core modules version in all core repositories
        type: setup.py
        path: cloudify-.*
        excluded:
          - my/excluded/path
        match: version=('|")(\d+)(\.\d+){1,2}(dev|(\w+\d+)?)('|")
        replace: (\d+)(\.\d+){1,2}(dev|(\w+\d+)?)
        with: "{{ .python_core_version }}"


    You define a list of paths you’d like to iterate over, provide it with what you’d like to search for, what you’d like to replace, what you’d like to replace with, and some more parameters and off you go.

    For example, the first object in the above configuration will:

    • Look for a file in the path repex/tests/resources/mock_VERSION (regex)
    • In the file, look for `”version”: “3.1.0-m2″` (regex)
    • Attempt to replace 3.1.0-m2 with 3.1.0-m3 only if the string was found during the matching stage and if the strings `date`, `commit` and `version` were found in the file.
    • Write to the output file repex/tests/resources/mock_VERSION.test

    The second object will:

    • Look for `setup.py`(regex) files under `cloudify-.*` (regex) and not under `my/excluded/path`.
    • Look for `version=(‘|”)(\d+)(\.\d+){1,2}(dev|(\w+\d+)?)(‘|”)`(regex) in the files found.
    • Replace `(‘|”)(\d+)(\.\d+){1,2}(dev|(\w+\d+)?)(‘|”)`(regex) with a variable which is not harcoded and therefore must be provided using the API.

    Layers of protection

    repex attempts to provide layers of protection and comfort:

    Safe!

    • You can first `match` whatever you want to match so that you’re sure you’re only replacing something in the exact context you wish to address. If `validate_before` is true, replacement will only occur if one or more matches were found.
    • You can verify that only files containing very specific strings will be addressed by listing them under `must_include`.
    • You can exclude files or directories you don’t want to search in by listing them under `excluded`.

    Don’t take this the wrong way though – regex is regex. You make a mistake, you pay for it. All repex grants you is the ability to have everything organized in one place, with some layers of protection to keep you from making some trivial mistakes.

    Comfortable

    You can declare every single directory or file you’d like to address in one manageable YAML.

    Of course, we needed to create some kind of naming convention so that we don’t have to configure each and every file separately.

    Accepts Variables, both hardcoded and via an API

    One of repex’s strongest features is that it supports using variables for string replacement. The above example contains a {{ .version }} variable.

    The API allows you to provide a dict of variables which will be placed in placeholders. You can either hardcode a variable in the variables section or use the API to send a dict of variables to be used. If a variable is hardcoded in the YAML and you use the API to send a variable with the same name, it will overwrite the hardcoded one. In addition, validation will occur upon variable replacement to make sure it was replaced.

    Functional API

    The API provides three basic functions. I’d rather not rewrite repex’s documentation.. so just refer to this.

    Basically, the three functions allow you to decide the level of granularity in which you’d like to handle the changes. It will allow you to perform actions in different stages of the replacement process.

    For example, we don’t really use the highest level of the API which just iterates over all objects in the YAML. We wrote a Cloudify specific wrapper which can be used as a reference implementation. It enables validation after every replacement. So, for instance, after every blueprint specific replacement, we run a validation that the blueprint is valid vs. our DSL-parser.

    Repex is available on PyPI. You can install it by running:

    pip install repex

    We might, at some point, provide a CLI for repex. Also a logging feature might be implemented to allow for JSON formatted log messages to be generated so that they can be transported for analysis.

    After using repex throughout our entire build process for the last five months or so, it has proven to be extremely useful. We can now follow our entire version update process and easily identify problems by looking at one YAML file and one execution log file. We’re planning on using repex to replace additional types of data (not only versions).

    We would appreciate feedback and, even better, pull requests.

    Hope you find this useful.

  • devopsy.kinsta.cloud is Now an Official Media Sponsor of MongoDB World

    mongodbworlddevopsy.kinsta.cloud, the place where the world meets DevOps is happy to report that we will be an official media sponsor of the upcoming MongoDB World conference. The event is in NYC at the Sheraton New York Times Square, 811 7th Ave, New York, NY 10019 on June 23-25, 2014.

    devopsy.kinsta.cloud will be providing live coverage of the event throughout the conference. We will also have some interviews with speakers leading up to the event. Some of the headliners for MongoDB World are:

    mongoworldspeakers


    MongoDB World promises to be the best and biggest MongoDB event yet. devopsy.kinsta.cloud will be there to give you a bird’s eye view.