Tag: cdn

  • Akamai Launches Gecko Edge Computing Services

    Akamai Launches Gecko Edge Computing Services

    Akamai Technologies today launched an initiative that promises to make it simpler to centrally manage and deploy application workloads on edge computing platforms.

    Shawn Michels, vice president for product management for cloud computing Akamai, said a Generalized Edge Compute (Gecko) offering leverages the global points of presence (PoPs) that Akamai uses for its content delivery network (CDN) to now deploy application workload managed via the Linode cloud service the company acquired in 2022.

    At the core of this offering is a set of virtual machines that enable a full stack of application software to be deployed in an edge computing environment to eliminate latency that would otherwise be encountered when transferring data to a cloud computing environment. The ultimate goal is to provide IT organizations with a federated set of services they can employ to process data where it makes the most sense based on performance requirements, said Michels.

    For example, applications infused with artificial intelligence (AI) will need to be able to invoke enough compute resources to run inference engines at the edge, while other less compute-intensive application workloads are best deployed in cloud computing environments, he noted.

    Michels added that rather than locking IT teams into a specific architecture, Akamai is committing to meeting IT organizations where they are, including adding support for containers running on Kubernetes clusters in its PoPs later this year.

    Akamai has more than 4,100 points of presence around the globe. With the acquisition of Linode, Akamai added a set of cloud computing services to compete directly against hyperscalers such as Amazon Web Services (AWS), Microsoft and Google by making cloud services available at a lower cost at a time when more organizations than ever are concerned about the total cost of IT.

    In its first phase of Gecko, Akamai will provide access to virtual machines in 100 locations by the end of the year. Akamai has already deployed Gecko servers in Hong Kong SAR; Kuala Lumpur, Malaysia; Querétaro, Mexico; and Johannesburg, South Africa, as well as in cities without a concentrated hyperscaler presence, including Bogotá, Colombia; Denver, Colorado; Houston, Texas; Hamburg, Germany; and Marseille, France. Deployment of a tenth Gecko region this quarter is planned for Santiago, Chile. Akamai is committing to adding hundreds of cities to its global cloud computing footprint over the next several years.

    In the longer term, Akamai also plans to add automated workload orchestration to make it easier for developers to build applications across hundreds of distributed locations.

    More workloads than ever are being deployed at the network edge as IT teams look to deploy software closer to the point where data is being created and consumed. That will require extending the reach of existing DevOps workflows to edge computing environments that will be based on everything from x86 and Arm processors to graphical processor units (GPUs).

    The challenge, as always, will be finding a way to effectively manage those workloads when the IT teams responsible for them are often physically located thousands of miles away.

  • Akamai Makes Case For Next Era of Cloud Computing

    Akamai Makes Case For Next Era of Cloud Computing

    Akamai Technologies today unveiled a cloud computing service that combines its ability to deploy applications at the edge with the cloud platform it gained via its acquisition of Linode.

    Shawn Michels, vice president of product management for compute and apps at Akamai, said Akamai Connected Cloud will provide the foundation for running a new generation of modern applications that require access to both core infrastructure resources in the cloud alongside highly distributed edge computing services.

    As part of the effort to deliver that combination of services, in the second quarter Akamai is adding three sites in the U.S. to the 11 it already provides. In addition, Akamai revealed it had identified 10 additional cloud sites and 50 distributed edge computing sites that it will add throughout the rest of this year.

    As a long-time provider of a content delivery network, Akamai manages a massive distributed computing environment that spans 4,100 locations across 135 countries. The acquisition of Linode added a set of cloud computing services that enable Akamai to offer the same set of services, including CDN services, as cloud service providers.

    Akamai is now signaling it will compete more aggressively by discounting the egress fees charged whenever data is moved off a cloud platform. One of the most expensive and unpredictable costs is the egress fees cloud service providers charge whenever data is moved off their platforms, noted Michels.

    Finally, Akamai also revealed it has achieved ISO, SOC2 and HIPAA standards compliance for its services.

    Akamai is making a case for an alternative approach to cloud computing that it said will be optimized for both existing monolithic applications running on virtual machines and cloud-native applications based on containers and serverless computing frameworks. A recent survey of 458 development professionals, managers and senior leaders conducted by Techstrong Research, a sister entity of devopsy.kinsta.cloud, found 43% of respondents are considering adding additional cloud service providers in the next 12 months. Nearly two-thirds said they are at least considering, evaluating or are ready to buy from a trusted alternative cloud vendor, with 20% reporting they have already contracted with one.

    It’s not clear whether IT organizations might actually migrate existing applications from one cloud service provider to another. At the very least, Akamai expects that as new applications are developed, the company will be able to gain a larger share of the overall market.

    There’s no doubt that a new era of cloud computing is dawning as organizations look to deploy distributed applications that process and analyze data closer to the point where it is created and consumed. These applications will then share the results of the data processed at the edge with, for example, centralized data lakes that make it possible to analyze data collected across a distributed computing environment.

    The one thing DevOps teams can count on is that as this next era of cloud computing evolves, the management of IT environments will become much more challenging for all concerned.

  • Cloudflare Adds Digital Experience Monitoring to CDN Portfolio

    Cloudflare Adds Digital Experience Monitoring to CDN Portfolio

    At an online CIO Week event, Cloudflare today added a digital experience monitoring capability to a portfolio of services layered on top of its core content delivery network (CDN).

    Corey Mahan, director of product management for Cloudflare, said the Cloudflare Digital Experience Monitoring service extends a Cloudflare Zero Trust platform based on agent software dubbed Cloudflare WARP. The solutions delivers a wide range of software-as-a-service (SaaS) offerings spanning everything from data loss prevention (DLP) to email security.

    He added that the overall goal is to reduce the total cost of IT by delivering SaaS application services more efficiently using a single agent rather than having to deploy multiple agents for each service.

    The Cloudflare Digital Experience Monitoring service, available as a private beta, will enable IT teams to leverage the Cloudflare CDN to measure and analyze controlled data flows to public or private resources by emulating traffic flows using synthetic data. Via integration with the Cloudflare Zero Trust platform, IT teams can also access real-time data visualizations highlighting anomalies in connectivity or performance that might, for example, be indicative of a security breach, noted Mahan.

    While there’s no doubt IT organizations are looking to streamline the number of IT vendors they need to manage, it’s not clear what the center of gravity will be for achieving that goal. Cloudflare is making a case for using the same global CDN that many organizations already rely on for networking services.

    The Cloudflare Digital Experience Monitoring service leverages the company’s CDN to make it simpler to understand, for example, why users in one geography experience sub-optimal application experiences compared to another, said Mahan. That’s especially critical when more organizations than ever have employees working from home across multiple geographies, he added.

    In the longer term, more networking and security functions will be consumed as a service. The challenge then becomes integrating those services into the DevOps workflows that are employed to deploy applications across a highly distributed computing environment. In many cases, what might initially appear to be an application performance issue winds up being a network connectivity problem that is more easily solved.

    One way or another, the management of IT services in the months and years ahead will continue to converge. Organizations of all sizes will need to determine whether it makes economic sense to acquire platforms they need to manage versus consuming a service that is managed on their behalf. Most of the time, a service will be easier to consume and free up resources that can be applied to other IT functions, such as application development.

    Of course, organizations will also need to take care to avoid locking themselves into a specific services provider. Ultimately, however, the question is whether managing a specific IT function provides enough differentiated value to be worth the time and effort when there is so much more to do.

  • Fastly Adds Observability Tools for Edge Computing Environments

    Fastly Adds Observability Tools for Edge Computing Environments

    Fastly, Inc. this week added a set of observability tools to its portfolio that are optimized for edge computing platforms connected to its content delivery network (CDN).

    Laura Thomson, senior vice president of engineering at Fastly, said the company is now providing a set of tools that enable DevOps teams to capture logging data and metrics in real-time via a single console.

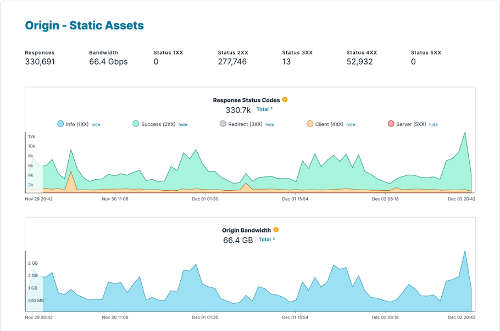
    The first two available tools are Origin Inspector—to observe network traffic flows including HTTPS response codes—and Domain Inspector—to access metrics based on both historical and real-time data. In total, Fastly is now providing access to more than 200 metrics spanning client, origin, cache, web application firewall (WAF), Compute@Edge, Image Optimization services and others that cover 100% of the data generated since the service was spun up.

    There is no sampling of data, and the company is also providing integrations with 33 storage and analysis services provided by either Fastly or a third party, noted Thomson. IT teams can now log any aspect of HTTP requests and responses through a large variety of logging formats, including the Common Log Format, JSON or as a key/value store. IT teams can also store their own logs to make sure they retain complete control over access.

    Over the next several months, Fastly will continue to expand this portfolio of observability tools, including an Edge Observer dashboard it is providing to customers that are deploying applications at the edge, added Thomson.

    In general, observability tools are being used to not only improve processes and overall customer experience but also identify and block suspicious activity. Fastly is making a case for observability tools that enable DevOps teams to achieve those goals without necessarily having to deploy a separate observability platform.

    Of course, most DevOps teams have been continuously tracking various pre-defined metrics for years. Observability tools, in contrast, are designed to make it feasible to interrogate logs, metrics and traces so that IT teams can discover issues before there is a disruption to services. The challenge, of course, is that not every IT team necessarily knows how to shape the queries required to discover the root cause of a potential issue.

    One way or another, DevOps teams will need to be able to remotely diagnose edge computing issues as the number of workloads deployed on these platforms expands. IT teams are not going to be able to travel to the physical location of every edge computing platform every time an issue arises. In many ways, the rise of edge computing will force a transition to observability tools that will enable IT teams to more proactively manage IT environments rather than respond after a metric has already exceeded its threshold.

    It’s not clear to what degree that approach will prevent IT issues from occurring, but the amount of time required to detect and remediate issues should dramatically decline as more visibility into IT environments, including edge computing platforms, is gained.

  • The Benefits of a Distributed Cloud

    The Benefits of a Distributed Cloud

    The way applications are created has changed dramatically in just a few short years. It’s now all about rapid assembly and integration; applications built using microservices and containerized. Containers and the cloud have certainly been the catalyst for this progress and will continue to be the infrastructure on which developers create new and innovative applications. 

    As workloads are moving to the cloud, however, more and more businesses are realizing they need a cloud that can be rapidly adapted to their specific needs. Computing environments may be a blend of server types: On-premises, bare metal, colocated and distributed across multiple continents. No single cloud architecture can offer consistently exceptional application performance for all users.  

    Between hybrid, on-premises, multi-cloud, colocated, centralized and distributed clouds, it can be hard to keep all the terminology straight. What are the differences between these cloud architectures? Why use one rather than the other? In this article, we’ll focus on just one of these: The distributed cloud. 

    What is a Distributed Cloud?

    As opposed to the large public cloud where all computing is done in a central location, a distributed cloud consists of a system of servers that are not all in the same place—even though they are managed through a single cloud provider. The servers in a distributed cloud can be actually anywhere in the world. This allows for computing to be done closer to the end user, which improves the user experience in a multitude of ways.

    What Are the Advantages of Using a Distributed Cloud?

    Below are six of the key benefits of using a distributed, rather than a centralized, cloud.

    One Size Does Not Fit All

    Computing environments may be a blend of server types: On-premises, bare-metal, colocated and distributed across multiple continents. Cloud providers need to offer flexibility to customize a cloud for their end users and their business needs.

    Data Regulation Compliance

    Many countries have specific compliance requirements for their citizens’ data and do not allow for personal/financial data to be hosted outside of their borders. Thus, having a distributed server within those countries alleviates that issue. 

    Reduced Latency

    In a distributed cloud model, servers can be placed in a wide array of locations, including in an edge cloud. When servers are placed closer to end users as opposed to in a centralized location, data does not need to travel as far to get back to the server. 

    Improved CDNs

    A distributed cloud can be used to deploy content delivery networks, or CDNs, to speed up content and service delivery. Heavy content (e.g. videos) can be stored and delivered by the distributed cloud closer to end users, which enhances the user experience.

    Network Resilience

    Network connectivity is always a worry for cloud providers. If their system goes down, none of the user’s workloads will run. In a distributed cloud system, however, the network is at a reduced risk of failure because if the system crashes, cloud services can reside in a local subnet.

    Location Flexibility

    A distributed cloud can always become more distributed. More locations can be added to the network, broadening the global compute zones available within that cloud. Companies that want to reach users in specific locations around the world can use a distributed cloud to reach them.

    Changing How People Think About Cloud Computing

    To address the demand for versatility, a new type of cloud has emerged: The unified distributed cloud (UDC), in which workloads can run in thousands of locations anywhere on earth. Such a cloud connects to existing infrastructure around the world via one API. Businesses can enjoy the benefit of running workloads in multiple locations without needing to maintain any of the distributed infrastructure. From a single UI, users pick an existing data center to send their workloads to and, within minutes, begin deploying. 

    A UDC transforms heterogeneous infrastructure into a homogeneous cloud computing platform, which can then be leveraged to support the delivery of cloud services in proximity to end users. It is designed to be interoperable with any private, hybrid cloud or multi-cloud architecture. As a result, enterprises can create an optimized cloud computing strategy, taking advantage of existing and available infrastructure in the location—or locations—of their choosing.  And because it sits on existing infrastructure, it doesn’t require any additional capital expenditure.

    As opposed to the traditional cloud model, the UDC can change the way people think about the public cloud. While the large public cloud providers benefit from economies of scale, a distributed cloud takes advantage of the economies of locality and distribution and thus has the flexibility to handle emerging location-dependent apps, such as the new wave of internet-of-things applications.

  • Edge Computing: Tech’s Next Trillion-Dollar Opportunity 

    Edge Computing: Tech’s Next Trillion-Dollar Opportunity 

    Even as technology continues to move into the cloud, a simultaneous shift is already underway in the opposite direction as computing increasingly moves to the edge. One key reason: by 2025, the number of connected devices in use is expected to exceed 56 billion units, according to IDC. Edge computing is not a successor to the cloud, but another expansion of technology’s reach that represents an exceptional opportunity for investment and growth.

    As edge-device and computing adoption continues to skyrocket, organizations need to process the proliferating data from these devices locally so they can act on it in real-time. This will require investments in edge-adapted infrastructure and related tools and platforms. Enterprise technology is about to be transformed yet again — the need to process and analyze some data at the point where it is both created and consumed is becoming a business requirement as mandatory as moving other parts of the technology stack into central locations in the cloud.

    Organizations already must deliver compelling customer experiences with edge devices based on data that must be continuously refreshed. The alternative—uploading and downloading data to and from a cloud service or local data center—often takes too long. Whether the data is on a consumer’s smartphone or a manufacturing floor, organizations need to process and analyze data as near as possible to the point where a real-time data-driven response is required.

    The competition to provide these capabilities is already intense. Many vendors—ranging from cloud service providers to telecommunications carriers to longtime providers of server and storage infrastructure—view edge computing as their next trillion-dollar opportunity.

    Why We Compute at the Edge

    Edge computing has been around for decades in various forms. There are countless examples of standalone software being deployed on, for example, devices used on factory floors that automate various aspects of a manufacturing process. In recent years, many of those systems have been connected to the Internet to enable organizations to collect and share data more easily. The challenge now is that the amount of data being generated at the edge often exceeds the point where it is practical to transfer that volume of raw data across a wide area network (WAN). Platforms that can process and analyze large amounts of data at the network edge are required. The aggregated results of data processed on an edge platform can then be shared more efficiently with other applications running in the cloud, in an on-premises IT environment or even on the network itself.

    Low-latency requirements are today’s biggest challenge. In many scenarios, an application running on a gateway at the edge of a telecommunications network needs to be able to respond in a fraction of a second to a mobile computing application’s request for data. In other circumstances, an edge application is driving an automated factory operation that needs to dynamically adjust to analytics processed at the edge of an extended enterprise.

    There are even more advanced use cases, some of which are described below. These include in-car computers that process computer-vision data in real-time for driverless vehicles and robotics applications that promise to transform manufacturing.

    Hardware Advances Enable Edge Computing

    The often competing demands of low-latency network connections, high-power computing and large storage requirements are driving innovations in edge hardware.  Electric carmaker Tesla, for example, has added custom-made devices to its processors capable of pre-processing massive amounts of data, performing machine learning inference to make quick driving decisions and predictions and even do some deep learning model training on the vehicle itself–before sending a subset of the data to central systems to do even more training.

    Earlier this year, Tesla unveiled a processor with six billion transistors. According to the company, its device boosts performance by 21 times compared to the Nvidia GPU it replaced in its Tesla Model S, Model 3 and Model X models. These powerful devices are used in addition to CPUs from traditional providers such as AMD and Intel for workhorse applications like infotainment.
    With this computing power at the edge, a Tesla car can process sensor data that allow it to recognize and self-pilot around pedestrians, other cars on the road, emergency roadside signage and potentially hazardous moving objects. This sensor data is also processed with pre-loaded mapping data and GPS connectivity. Additionally, Tesla’s in-car computers relay information over Tesla’s network to massive storage facilities where the data is analyzed to improve Tesla vehicles’ self-driving and other functions. Improvements to the vehicle’s software stack are then downloaded to it over the network.

    Healthcare is an example of a sector with similar needs for advanced machine learning-taught devices and software. Images from MRI and other scanning devices with inference-computing capabilities deployed at numerous locations would also require computing power and network infrastructure similar to that which Tesla’s cars need. Most hospitals, however, don’t have the interest or wherewithal to build their own powerful edge computing hardware and will need to consume this capability from technology vendors.

    As advances in semiconductor circuits approach seven nanometers and smaller, the ability to run applications at the edge in an energy-efficient manner becomes more realistic for a wider range of organizations. With each new iteration of processors, the total cost of edge platforms will continue to decline while the amount of horsepower available to run applications steadily increases.

    Networking at the Edge

    Regardless of how much data is processed and analyzed at the edge, the sheer volume of data creates more demand for network bandwidth and, consequently, the potential for bottlenecks. One main bottleneck is at the backhaul—the stretch between the edge towers and central servers and network. Whether tomorrow’s edge network infrastructure will consist of 5G, more ultra-powerful WiFi connections and devices, low-latency daisy chain systems, fiber systems such as those that Google is developing, satellite connectivity, yet-to-be-created technology or a combination of these is still unclear–but one thing is certain: Data volumes are increasing faster than network bandwidth.

    Today, organizations have a choice of connecting edge platforms among several available wired and wireless network alternatives. The number of use cases involving edge computing is expanding in part because wireless 5G networks make it possible to share data across multiple interconnected edge platforms. For example, manufacturing employees wearing augmented reality headsets that can share data and analytics in near-real-time not only with their coworkers on the floor but with colleagues hundreds of miles away.

    As telecom carriers continue to virtualize the network infrastructure they employ to deliver 5G services, the cost of delivering them should steadily decline across a widening range of geographic areas. Today, a 4G network can support roughly 4,000 devices per square mile. A 5G network could pack up to three million devices in the same area.

    It’s still early days as far as 5G is concerned. A Capgemini survey of 1,000 industrial organizations that plan to incorporate 5G into their operations finds less than a third (30%) have progressed to trials and real-world implementations. Yet, carriers are already at work defining the next generation of 6G wireless standards that promise to deliver another giant leap for wireless networks in another decade.

    Regardless of the network employed, organizations will still need to strike a balance between how much data needs to be processed, stored and eventually disposed of at the edge versus the amount of aggregated data that needs to be transferred over a WAN and incorporated within various other platforms that process data centrally or function as systems of record.

    Factoring in Security

    Arguably, the biggest obstacle to edge computing is security. Each time an organization deploys an edge platform, the attack surface they need to defend grows. Many of these edge platforms are also managed by operational technology (OT) teams that don’t have as much cybersecurity expertise as does, say, the data center security team at Google. Most organizations are trying to meld their OT and traditional information technology (IT) teams in an effort to deploy, manage and secure edge platforms. However, the cultures of these two teams are significantly different. It takes time for organizations to harmonize the efforts of these two groups.

    More challenging still, cybersecurity expertise is hard to find and retain. Cybercriminals have discovered how vulnerable OT environments are. Attackers affiliated with various nation-states have already demonstrated that industrial control systems controlling electricity grids and other critical infrastructure systems are primary targets should war erupt. From their perspective, each edge computing platform connected to a network is yet another vehicle through which malware can be introduced into an IT environment. It only takes a few minutes for malware to propagate laterally across an entire platform.

    Ultimately, organizations will soon spend billions of dollars securing edge platforms. Once the edge systems are locked down and secure, edge processing can improve overall cyberdefense—processing more data at the edge without moving it around as much can dramatically reduce the attack surface.

    How the Edge Computing Ecosystem is Evolving

    Once the right level of infrastructure is in place, the next challenge is building applications. The widespread adoption of container technologies has allowed developers to build applications using artifacts that require much less memory and storage. Most container environments today, like those based on Docker and Kubernetes, are decentralized, in a sense, but are run in centralized environments like data centers. But work is progressing on even smaller container formats that make it even easier to deploy application software on, for example, an oil rig hundreds of miles from any server or gateway.

    Lighter-weight instances of the open source Kubernetes container orchestration engine are starting to gain traction. Kubernetes, by surfacing a consistent set of application programming interfaces (APIs) regardless of what platform it is deployed on, provides an opportunity to centralize the deployment and management of modern microservices-based applications across highly distributed computing environments.

    Industry API specifications and frameworks are also beginning to emerge for machine learning, data science and other technologies that empower edge computing. An example is oneAPI, supported by Intel and others, which provides a framework for developing edge applications.

    Providers of development platforms are also racing to create frameworks that make it simpler to build applications within edge architectures that seamlessly invoke backend application services running in the cloud. Distributed event-streaming platforms like Apache Airflow and Kafka can play a role in allowing edge computing platforms to share data with those backend platforms at scale. Some organizations will also invoke the services of content delivery networks (CDNs) to improve the performance of applications deployed across a global network of points-of-presence (PoPs) that have already been constructed.

    Finally, stateful applications deployed at the edge can require local databases that provide access to persistent forms of data. The bulk of container applications deployed today are stateless—they store data on an external storage system. Building stateful applications that access data in containers on a local Kubernetes cluster is more challenging.

    There are already millions of developers familiar with container platforms who are standing by until improved hardware and software simplifies and secures deployment of highly portable applications as far out on the edge as possible.

    The Coming AI and Data Management Challenge

    The most exciting edge innovations ahead will likely be driven by the rise of machine learning and AI. Today, AI models are typically trained within centrally located cloud computing platforms. An AI and machine learning inference engine can then be created and deployed in a production environment, where a trained AI engine deduces what actions to take as new data is discovered.

    Over time, those inference engines are subject to drift as the amount of new data collected exceeds the parameters on which the original AI model was based. Data science teams working in collaboration with IT and OT teams then need to train a new AI model to replace the inference engines at the edge. Advances in new AI and machine learning capabilities, in conjunction with lower-power and higher-performance processors and other components to help lower costs, can improve the accuracy and performance of prediction systems, but typically doesn’t reduce the degree to which this drift happens.

    If AI models can be at least partially retrained at the edge, this can help to reduce prediction accuracy drift. However the software and hardware infrastructure required to retrain an AI model efficiently within an edge platform is still very early-stage. That said, as the cost of increasingly high-powered hardware declines and edge machine learning software systems improve, the ability to train at the edge will become more feasible.

    The Economic Impact and Investment Opportunity

    The global edge computing market was valued at approximately $3.6 billion in 2020 by Markets and Markets. The research firm forecasts this market will reach $15.7 billion by 2025, representing an astounding 34.1% compound annual growth rate (CAGR).
    McKinsey forecasts that the economic value generated by use cases involving internet of things (IoT) applications alone will be somewhere between $3.9 trillion and $11.1 trillion per year by 2025. Add in all the other use cases for edge platforms and the potential for positive economic impact becomes enormous.

    Increased computing at the edge will be a huge technology market in its own right and will also drive increased demand for centralized cloud computing. Gartner notes that by year-end 2023, 20% of installed edge computing platforms will be delivered and managed by hyperscale cloud providers. The other 80% of this massive emerging market opportunity is up for grabs.


    Lonne Jaffe co-authored this article.
  • Akamai Adds Service to Optimize API Traffic

    Akamai Adds Service to Optimize API Traffic

    Akamai today launched an API Acceleration service specifically designed to accelerate application programming interface (API) calls using special purpose hardware, reserved capacity and prioritized routing.

    At the same time, the company is also making available a globally distributed key-value store dubbed EdgeKV that enables stateful applications to be deployed on its EdgeWorker nodes.

    Finally, Akamai is also making available free tiers of services that provide access to a combined 60 million serverless EdgeWorker events per month with a limit of up to 30 million EdgeWorker events per tier. The two tiers are made up of a basic compute service for applications requiring lower CPU and memory consumption and a dynamic compute service for those applications demanding additional resources.

    Josh Johnson, an enterprise architect for Akamai, said Akamai is expanding its offering at a time when many organizations are starting to deploy microservices-based applications across an extended enterprise using serverless EdgeWorker nodes deployed at the network edge. EdgeKV provides access to a low latency data store that also enables those edge computing applications to process data closer to the point where it is being created and consumed.

    In general, Akamai reported that, in 2020, its platforms processed more than 300 trillion API requests, a 53% year-over-year increase. Much of the increased activity is being driven by distributed applications that are deployed directly on the Akamai CDN, rather than being deployed in a local data center to take advantage of a global network of data centers that allow IT organizations to take advantage of caching. In effect, the CDN becomes the target platform when an application developed using DevOps best practices is being deployed. The rise of edge computing has increased the number of use cases where DevOps teams are relying on CDNs to deploy applications.

    Naturally, competition among providers of CDNs has increased considerably as the number of applications deployed at the edge continues to increase. There may even come a day when there are more applications deployed at the network edge than there are in the cloud as more organization deploy applications that need to process and analyze data in near-real time as part of a larger digital business transformation initiative.

    Akamai, of course, as the provider of the largest global CDN, is betting it will be able to leverage the size of its CDN to convince developers to deploy applications on its platforms rather than smaller rivals.

    Regardless of the approach to edge computing, the applications being deployed will be more latency sensitive than ever. Each IT organization will need to decide to what degree they want to count on infrastructure to optimize API calls those applications make before they time out or need to be redirected to another microservice. One way or another, the laws of physics still apply. No edge computing application is an island. It depends on a complex web of infrastructure ranging from routers and switches to servers running back end services in the cloud. The challenge is finding a way to optimize all those interactions in a way that developers never have to be concerned about.

  • More and More Enterprises Go Headless

    More and More Enterprises Go Headless

    IT faces high expectations for building and supporting omnichannel digital experiences. Simultaneously, web developers hold an evolving toolkit of architectural approaches to deliver content. One such framework gaining mindshare is headless, a style that decouples front end user experiences from back end application logic.

    Legacy options for content delivery can be somewhat cumbersome in that they don’t apply well to scenarios beyond websites. On the other hand, a headless framework uses web APIs to communicate with clients, making it a more adaptive model to support new devices and use cases.

    WPEngine recently released global research on the state of headless. Below, we’ll review the top findings from The State of Headless: A Global Research Report. I also met with Matt Landers, developer relations manager, and Jason Bahl, principal software engineer at WPEngine to discuss the evolution of headless and its future implications for developers.

    What is Headless?

    First off, what is headless? Headless decouples the front end from the back end, thus separating the user interface (UI) from the data and code that powers it. The headless movement represents a shift from traditional content management systems (CMSs) such as WordPress, Squarespace and Wix.com. These platforms are less extensible, as they intrinsically unite the back end with user-facing representations. Traditional CMS is “typically not that easy to scale,” noted Landers.

    Headless challenges the status quo by offering more flexibility. As headless adopts API-based content negotiation, it could essentially deliver highly personalized experiences to any connected device. This could help support emerging platforms, like mobile, voice assistants or augmented reality (AR).

    Simply put, headless is “a CMS that is not responsible for rendering the site,” Landers explained. “What attracts people to headless is component-based architecture and the ability to build isolated components,” he added. For example, a headless framework could include an author bio component that is reused in any custom style across devices. By deploying to a CDN, headless could enable high-speed performance, as well.

    Headless Adoption Surges

    Interest in headless is increasing across the board. Currently, 64% of enterprises surveyed adopt a headless approach, representing about a 25% increase from 2019. Furthermore, headless use is expected to grow: over 90% of organizations not currently using a headless setup plan to evaluate a headless option in the coming year.

    The strong interest in headless likely represents a growing necessity for large enterprises to support various digital channels in a consistent manner. In fact, 92% of organizations credit headless with delivering a more consistent content experience, the report found.

    Benefits of Headless

    A key benefit to introducing headless is the decoupled nature of the approach. This makes it possible to support multiple platforms, such as websites, mobile apps, IoT devices, connected kiosks, smartwatches, voice assistants, AR and virtual reality (VR) from the same source.

    Respondents also cited additional benefits to adopting headless such as increased performance, quicker time to market and rapid innovation. These positive attributes make sense because, with headless, applications only request the data they need. Therefore, headless could certainly facilitate more dynamic applications and custom-tailored user experiences. If used effectively, headless setups reduce bloat to create fast-loading digital experiences that further the SRE agenda.

    Tech Choices and Use Cases

    An average organization is spending $2.6 million on their headless implementation, found the report. So, what are they spending it on? Well, some common headless frameworks and SaaS platforms include Contentful, GraphCMS, Atlas, DatoCMS, Cosmic, Netlify, Sanity.io and Prismic, among others.

    While the report didn’t query respondents on their exact headless stack, it revealed a general satisfaction with headless solutions, with relatively high net promoter scores (NPS). When selecting a headless provider, respondents tend to consider performance (41%), e-commerce (35%), scalability (33%) and APIs and extensibility (30%).

    Though headless spans many use cases, e-commerce is clearly a primary use case for the headless stack, with 51% of respondents adopting headless to support e-commerce. Other top use cases for a headless approach include a website (52%), IoT (47%) and progressive web apps (40%).

    Drawbacks of Headless

    Though headless provides impressive malleability, it does require a shift in thinking, and implementors must inevitably overcome certain drawbacks. API security, for example, is at stake as API attacks and threats increase.

    Headless could also require additional administrative burden in terms of data integration and upkeep. With headless, instead of using plugins, IT must enlist front-end developers to integrate data and build front-end behaviors. Debugging a decoupled front end and back end can also be an added development burden. “There is an opportunity in the headless ecosystem in general to mature the experience for the content publisher,” describes Bahl.

    Future of Headless

    Within today’s remote economy, most acknowledge that digital experiences are now crucial to supporting business at large. In fact, 92% of organizations believe digital experiences are vital to their organization’s success, found the report.

    Headless architecture promises to retain a stable back end to support these escalating digital demands — especially useful considering the ever-changing nature of front end clients. On that note, the report found that 32% and 31% of respondents adopt headless for VR and AR experiences, respectively. Therefore, the headless approach appears to be a valuable technique to future-proof current investment against emerging digital trends.

    The State of Headless: A Global Research Report, conducted by Vanson Bourne between January and February 2021, surveyed 400 IT/technical employees with knowledge of headless. For more insights, you can read it in full here.

  • Cloudflare Lays Out GitOps Ambitions for CDN Platform

    Cloudflare Lays Out GitOps Ambitions for CDN Platform

    Cloudflare’s acquisition of Linc is the latest move in the hosting provider’s move to better align its content delivery network (CDN) service with the tools and frameworks organizations rely on to build modern applications using GitOps processes, according to CEO Matthew Prince. Cloudflare also announced other updates and automation-related features, including a way to automatically deploy JavaScript applications using Linc’s technology.

    Prince said these latest moves are part of an ongoing effort to simplify integration of front-end applications with back-end services.

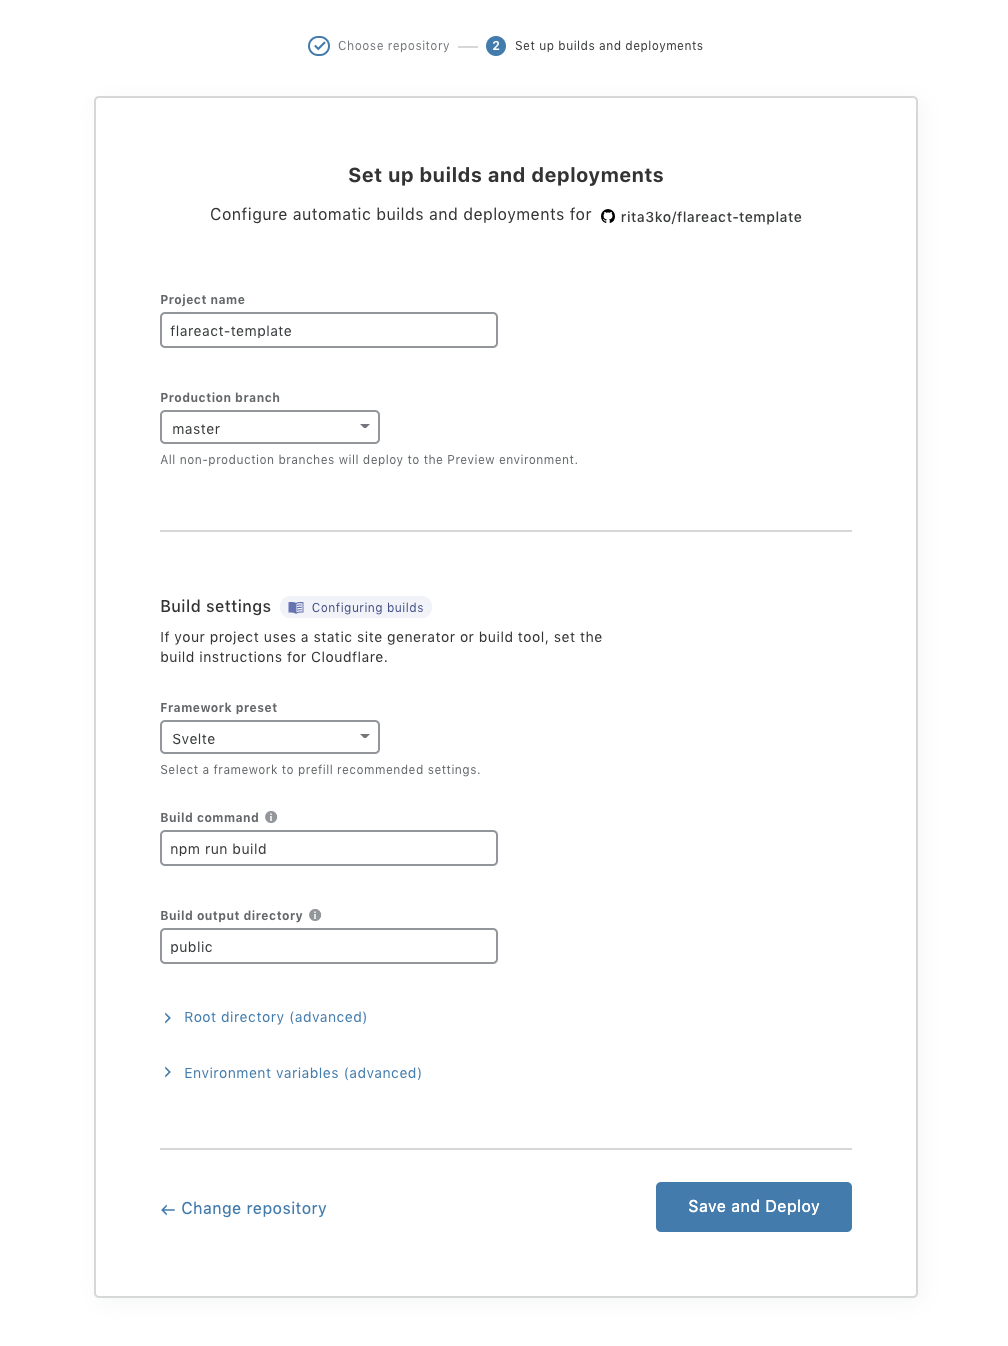
    Cloudflare Pages, for example, enables developers to select their preferred repository, identify what types of frameworks they are using, and then automatically deploy their applications on the Cloudflare CDN. The goal is to automate the continuous integration process in a way that enables developers to focus more of their time and effort on developing code, said Prince.

    Linc’s technology, meanwhile, will make back-end services more accessible to front-end applications using Front-end Application Bundles (FABs) that accelerate server-side rendering by combining front-end and back-end logic. The result is better performance across any type of application that relies on JavaScript, application programming interfaces (APIs) and markup languages, otherwise known as JAMstack, a framework for building complex applications.

    Prince said JAMstack adoption is accelerating because it allows developers to continuously modify the user experience (UX) without the need to modify back-end services. The CDN, meanwhile, has emerged as a platform for continuously deploying applications closer to the point where they are consumed by the end user, said Prince.

    That’s become especially critical at a time when digital business processes require data to be processed in near-time, and as closely as possible to the point where it is generated, said Prince. That’s not possible when application logic runs on a public cloud, Prince added.

    Cloudflare currently has points of presence in 200 cities worldwide, and is actively courting developers as part of an effort to usurp CDN rivals. Most recently, Cloudflare added a Durable Objects capability that makes it possible to run stateful applications across a distributed, serverless Cloudflare Workers service.

    Ultimately, Prince said the goal is to automate the majority of the DevOps process, as code moves from a Git repository to the network edge. A CDN will also provide the means to monitor and secure applications running at the network edge, Prince added.

    It’s not clear how much application logic will be pushed to the network edge via CDNs; however, it’s apparent CDNs are emerging as an important deployment platform that should be incorporated with DevOps processes. How providers achieve that goal is, in part, dictated by the framework used to build an application.

    Cloudflare’s moves are indicative of the larger trends of automating DevOps processes, a development that should make DevOps best practices more widely accessible to many more developers.