Tag: build automation

  • Is it Time to Reconsider CI?

    Is it Time to Reconsider CI?

    DevOps is old, in technology terms, at this point. Many of you have never developed under a waterfall and have no idea what tools like Visual Test were, and that’s actually very cool. While knowing other processes and tools does help make informed decisions, being immersed in the tools that matter today is more important. We have entire DevOps stacks built up that allow for the development, building, testing and, increasingly, deployment of apps in an agile environment.

    As always happens, market leaders and those who compete with them, complement them or serve a subset of the market have grown up and become standards. Indeed, application release orchestration (ARO) was a phrase coined in the early days of DevOps that fell away completely; I heard it recently and thought, “Oh, are we bringing that name back?” Vendors have come and gone; some merged into other products, and some are just plain gone. Again, that is a good thing as the market, its needs and the customer base are all mature. While it is terribly painful to be the user of a product that just goes away one day, the prevalence of open source in the CI/CD landscape does buffer that pain a bit. And the market gets better as tools fall away and new ones take their place.

    But sometimes, the movement is slow, just simply due to inertia. Most of us – and by us, I mean IT shops, and by most I mean a lot – use Jenkins. The number seems to be on a steady downward trend, and the tool’s maintainers have definitely taken steps to improve the parts that make organizations consider other solutions, but the trend is there.

    And I, personally, think that is a good thing. Stagnation is what made waterfall such a weakness in enterprise IT. Everyone did it, so that makes it good. Same is true for the old phrases we’ve all heard at least one variant of – “No one ever got fired for buying IBM”, or “No one ever got fired for buying Oracle”, “…Cisco”, etc. The obvious answer to those statements then, as now, was, “Well, maybe they should have.”

    The same is true for Jenkins. It is a great system that can do everything. And that’s part of the problem. If you have small projects or are a team using it standalone with light requirements that all revolve around getting a quality product out the door quickly, Jenkins just might be too much for you. In the early days, Jenkins wasn’t, but the plug-in architecture and years of competition and changing market needs have made it huge. And while there is arguably better documentation than any other CI, and inarguably the largest user base to ask questions of, it’s still weighty to use in place of a SaaS that comes pre-configured and you can just hand it a repository with build files in it.

    There are a lot of enterprises that need what Jenkins has grown into–it did not expand in a vacuum. But there are many, particularly new, small, agile orgs or standalone teams that just don’t.

    There are a lot of options out there, and it is worth taking stock of what you are trying to do with your build/test process, and build a list of things required, then look seriously at what’s available. For some, lightweight is good.

    Of course, as much as one can be in our technological age, I am a minimalist. I like my D&D to be a rules-light variant, my dev tools to have enough functionality but not bury me in extraneous stuff, laugh at Excel for including abstract functions and then selling to consumers, etc.

    At my company that does development, we do indeed use Jenkins. But our projects range from simple knock-it-out one-offs to complex systems with multiple servers and clients, so we feel it is best for that range of variation. And like many others, the investment to move old projects would be questionable without a driving need. Not that I get to do much development these days myself, but I do stay in it just enough to be dangerous. But we have asked the question and determined the answer. For now.

    If you have issues with Jenkins, look around. There are options. They are not for everyone, but your org isn’t everyone. Find the best tool, not the most convenient, and keep kicking rear.

  • We Are Living in an Ephemeral World

    We Are Living in an Ephemeral World

    We are lucky to live and work in the times that we do. Oh, we have our challenges, and I talk about them a fair amount here on these pages. But the things we can do in IT today have not been possible in the past, and the change isn’t over. Soon you will be able to relegate pretty much all of the busywork of IT to automated systems, Note that I did not say “AI/ML”–some of that automation will be, but we throw the term around too much right now, and not all automation will be based on AI/ML. In fact, quite a bit of the best automation is simply rule-based systems that we finally have things standardized enough to write up. And I intend to talk specifically about automation that is not AI/ML today.

    We have reached the point in DevOps where we can automate the entire build/release process using containers. The CI tool, running in a container, can spawn a container that performs the build. Then, when it is done, if it passed, it can spawn another container to run tests, do security scans, etc. Finally, the product can be promoted and released … in a container. Human involvement is only required for approvals and then only for organizations that want checkpoints on the way to production (which is definitely most but not all of us).

    If you take the totality of what is going on out there in DevOps, it is finally catching up to DevOps. The biggest issue will be making it efficient and doable for the DevOps team. To date, by focusing on DevOps, teams have been able to avoid the simple fact that complex deployments on infrastructure that spans environments and uses external resources is hard. By keeping the DevOps side simple (or not part of the DevOps process), developers can crank out code faster, facilitated by DevOps tools and Agile methodologies, and operations can continue to wrangle the beasts of networking, storage, etc. to get the app running in production. Once ops has completed the process, then it can be automated based on steps taken.

    But we now have Software-Defined Everything ™ combined with containers. That means that for many–though not anywhere near all–applications, a commit that updated a constant in a single source file can spawn the entire process in iterative containers all the way through release. That is very cool, and we should take a second to appreciate how far we’ve come in a short time.

    Then we need to talk about those worker containers. They need a ton of centralized logging and reporting. Spinning them up, letting them run and then automatically destroying them is fine—as long as the organization has access to the information it needs to review and analyze the results. In-application tooling will cover the released product and even the test environment, but not an ephemeral build process. By not keeping a ton of build tools running all of the time, the enterprise is, by definition, more secure—the blast radius is reduced if build tools are only available when they’re active, and logging of who/what kicked of a build is kept. But don’t forget the reporting. At build time, our tools know exactly which error failed a build; the container needs to submit a ticket before being destroyed or log heavily. I say, “Always create a ticket,” but I’ve worked in enough environments to know that your reality may not make that possible. As long as notifications occur, it doesn’t really matter how they occur.

    So crank it up; start super-automating. Tool up those build environments, then make them into disposable container instances. Others have been doing this for a while, so there is help available for setting it up, but it is just now taking off, so it is a good time to dive in. And keep rocking it. How the apps are built and deployed is only important in the sense that you are driving the company forward. Keep doing it.

  • Lock Down Your Toolchain

    Lock Down Your Toolchain

    We have done amazing things with Agile and DevOps, increasing IT responsiveness to levels that most people would not have believed and our business counterparts only dreamed of even a decade ago. Think about it—we can check in a single source file and kick off a chain of events that involves half a dozen or a dozen software tools that collectively shepherd an entire application through the development process to deployment. Through all of that, only deployment might require human interaction, depending upon corporate policy. In many places, even deployment does not require a person. Just development.

    We didn’t get to this point by moving slowly, and sadly, we did not get to this point by acting in a security-first manner. Thanks to the security-toxic mentality that DevOps was born in, we have had to go back and try to bolt on security where it was ignored initially. But we’ve largely managed that process. We have tools that handle privileges, monitor connections, scan source, look for vulnerabilities in support software, even scan entire container definitions before the build.

    Know what most of you still don’t have? A truly secure toolchain. This is bad policy. A knowledgeable attacker is going to go after one of the aggregate locations. Places like container management servers that give them access to a lot of resources. Or the toolchain, which gives them access to every bit of software the organization develops. If an attacker wants to do code injection without detection, the toolchain in charge of builds and deploys is it.

    And yet, for ease of use and keeping up with iterations, many of you have credentials for the toolchain stored in easily accessible places so that whichever tool is running the show has access to credentials for each piece of the toolchain. I wish I could say “No one keeps that data in flat files anymore,” But alas, I cannot.

    One of the reasons it is not sufficiently secured is that build toolchains fall somewhere between Dev security and Ops security. That means our teams that came from a development background are not focused on security for the build chain, and our teams/team members that came from an ops background are not focused on the toolchain selected and often initially deployed by developers.

    Which brings me to my recommendation. Put security professionals on the toolchain to verify it is locked down at every step. There are a lot of places for the toolchain to be insecure, not just poorly stored credentials. And the toolchain touches all of IT’s crown jewels.  So make sure it isn’t wide open. If your organization doesn’t have dedicated security staff, bring in consultants to review the toolchain and make recommendations. There are some great security teams for hire out there that will be happy to lend a hand.

    And keep rocking it. Your teams are building and deploying at a rate never seen before—even if DevOps is “slow” at your org, it is still likely faster than its predecessors—for doing anything. So keep working miracles, and lock down your castle’s the inner keep.

  • Meet the New(ish) Pipeline

    Meet the New(ish) Pipeline

    My company keeps a sample project running pretty much all of the time. Our current project (multi-target web/Android app using Java and Spring built with Gradle and Ant that we’ll call “Finder” here) is getting a bit long in the tooth, so we have been casting about for a new one over the last several months. From non-work sources, we came upon the idea of multi-targeted Godot with C# as a viable side project. Moving to a completely different set of tools is kind of the point; it makes us stretch, and that is the idea of our ongoing projects. The stated goals for these projects are:

    1. Stretch knowledge about different languages, DevOps tools and platforms.
    2. Keep doing what you all are doing. Too many pundits have “grown out of” hands-on work, and it shows.
    3. Try out new ideas/architectures.
    4. Avoid “kitchen sink.” We can’t have a current test app that includes all available technologies, so keep it streamlined. Approach this as a production app that we use for testing, not as a test app.

    That’s why we’re looking to replace our Java/Spring project. We’ve got that pipeline down, we’ve tweaked the app until we are happy with the core and it hasn’t changed in a good while. But change is a part of DevOps, so we’re off.

    The Obvious

    Let’s take care of the obvious elements in our toolchain right away:

    1. Git. We’ll use GitHub, but it was a given that some form of Git would be holding our code.
    2. Visual Studio Code. We’re doing C#, so this is going to be the most useful option for code editing. The built-in Godot editor is good and will be used, but VS-Code offers C# functionality add-ons.
    3. Antsle is the deployment tool of choice, though this has changed over the years. We’ll use it to set up install sets for clients.
    4. Jenkins or Hudson. We’re going to use this only for test management.

    The Less Obvious

    There are several constraints we want to (or have to) meet. First, we want to avoid using Jenkins or Ant to control the entire build process, mostly because we’ve done both in previous projects, and most DevOps teams are no longer using these methods for new projects. Second, this is a sample we keep, not an investment, so we want to use open source technology if at all possible, to keep expenses down. Third, we’re using a game engine to do app development. This has some impacts–like most game engines, it is in control at runtime and we need to bundle the engine in the final application.

    1. The Godot Engine. Godot is written as a game platform, but its graphics/cross-platform abilities make it useful for graphics-heavy apps like ours. But we have to include the engine and its config files in the pipeline.
    2. Code Scanning. Static analysis was a late addition to Finder, and it’s in Java. This project is in C# and Godot Script. We have not yet found a tool that supports Godot Script, but C# we can get; it just adds restrictions. So we will use a static analysis tool, but we’re still deciding which.
    3. Build Automation. We’ve used Jenkins, Gradle, Maven and Ant to handle this step at different times in the past, but something newer would be a good idea. We are still evaluating this step. We will likely end up back on one of those tools because they are still used today. Godot is a new element to us, so we are also evaluating what is required to hook into it and make functioning apps in a repeatable process.

    Fueled Innovation

    We’re having fun—first couple sprints have us running a working prototype, so we’re happy with that. There’s still a lot to implement in the app and in the pipeline, so we’ll no doubt have more to say here soon. We’re talking about putting a server component in—not because the original concept needs it, but because our outgoing app—Finder—had server and client sides, and our need for things like Postman go away without this architecture. And yet, API security, testing, etc. is an important part of the DevOps architecture. As you can see, we’re still iterating.

    As to Finder, we normally take down the pipeline for a previous playground project when the new one goes up, but Finder costs us little. There are five containers (three permanent for the app hosting; two for build/test) and some processing power, so we’ll probably keep it since it is using a different set of pipeline tools (and languages—it is mostly Java/JavaScript).

    Meanwhile, you all keep rocking it. We’re building an(other) app that no one but us will ever see—but you are keeping the enterprise humming. Kudos to you!

  • 6 Big, Bad Mistakes in Configuration Management, Part 2

    6 Big, Bad Mistakes in Configuration Management, Part 2

    In Part One of my article on big, bad mistakes in configuration management, I reviewed the dangers of using the wrong tools for the configuration management job. Provisioning management tools, application release automation tools and continuous integration tools each have their place in your DevOps toolchain. But they should not be used as a substitute for ongoing configuration management. In this article I am focused less on misusing tools and more on bad practices, limited thinking and short-sightedness that should be avoided.

    Mistake No. 4: Direct Server Access to Production

    This one may not bite you … until it does. I’ve worked with many companies where developers have direct access to Production. This is not good. And, in many cases, it is a violation of compliance policies. Please don’t take offense, my developer friends. You shouldn’t want direct access to Production. I find that 9 times out of 10, your code is not the problem—the configuration is the problem. However, you’re being asked to log directly into the server to do comparisons between your environment (where it worked just fine) and Production. This leads to the, “How did he fix it?” problem, and it leads to the dreaded typos and other manual errors. I’ve witnessed companies lose millions of dollars in a matter of minutes because someone logged directly into a server and made an incorrect configuration change.

    The question is, How do you cut off direct access to Production? How do you quickly find configuration differences between environments without logging into the server? The answer is a good configuration management solution that quickly shows differences between the environments for all your tiers. This is easy when you’re doing file-to-file comparisons, but what about registry key comparisons, or WebSphere comparisons? Find a configuration management tool that gives you visibility fast, exactly when you need it, for the important parts of the stack that keep your applications running. And insist on a configuration management solution with robust RBAC (role-based access control) over what changes can be made, where and when they can be made, who can make them and even who can approve them.

    Mistake No. 5: Leaving Your DBAs Out of the Picture

    The majority of companies I work with have completely disconnected database and middleware teams—the DBAs don’t really know what the middleware team is doing and the middleware team has no visibility into what the DBAs are doing. I believe there are a couple reasons for this: people and technology. We won’t worry about the people aspect today, other than to say that each team thinks the other team is “quirky” J. From the technology aspect, traditional tools simply do not provide configuration visibility into both the middleware and the database tier. So the DBAs end up having one toolset, and the middleware team a completely different toolset. This prevents collaboration, orchestrated releases, and the complete configuration picture that’s needed to make sure your application is fully configured, performing, and running correctly.

    This is a big problem. In fact 37 percent of survey respondents admitted that they relied on scripting and manual processes to determine which databases were used by which applications in their ecosystems. And another 38 percent admitted they don’t even have a way to determine this information. Talk about blindfolds! My advice is to find a solution that both middleware and database teams can use. That doesn’t necessarily mean the DBAs will replace their favorite tools, but they’re now involved in the process, allowing that collaboration and orchestration that was missing.

    Also, if you use a single, integrated configuration management solution your management, middleware, OS and DBA teams will all have visibility into every aspect that makes the application run. The middleware team can see if there are schema changes that may be causing an application issue as opposed to spending hours looking for a middleware configuration issue they’ll never find, or vice versa. Having one unified tool cuts down on the mean time to diagnose because you can see all the tiers in one place.

    Mistake No. 6: Focusing Only a Single Part of the Stack

    The previous “big, bad mistake” segues nicely into this one: focusing on just a single part of the stack. There are many tiers supporting your application, and we’ve touched on several in this series—namely middleware, database and OS. Within each tier you may be supporting different technologies. Some applications may be running on IIS with a SQL Server back end while others run on WebSphere with an Oracle back end. Then you have the operating system settings to worry about: making sure registry keys are set, system services have the right accounts, filesystem permissions are accurate, all the correct versions of Linux packages are installed, etc.

    Based on a lack of comprehensive coverage up and down the application stack, many companies have chosen to explore configuration management tools for just a single part of it. These point tools tend to focus on the most business-critical applications, the one where they hit the most configuration issues or simply the one that’s most difficult to manage. This is not necessarily a bad thing to do, but take care not to be too single-minded. Try not to choose a configuration management solution that works well for one part of the stack but not others, or that works very well in one environment (Linux/Unix), but not very well in another (Windows). Managing these disparate point solutions, with maddening gaps and overlaps in coverage, can be exhausting.

    Choose a tool that’s extensible to other parts of the stack, business or other teams. My suggestion is to make a list of all present and future technologies you use that need configuration management support. Divide them into different parts of the stack and then rank them from “most onerous to manage and/or most business critical” to “nice to have.” Refer to this list when evaluating configuration management tools so you don’t lose sight of the forest from the trees. Make sure the tool can support all your top items and ask about their road map for your “nice to haves.”

    Tune into our upcoming webinar, which will touch on these topics as well.

    About the Author / Kristy McDougal

    Kristy McDougal leads Product and Sales Engineering for Orca, an application release and configuration automation solution for DevOps teams. Prior to launching Orca, Kristy was a Senior Pre-Sales Consultant within BMC Software’s worldwide DevOps specialist team. Before BMC, Kristy held technical positions at VaraLogix, Virtual Bridges, Global Foundries and Advanced Micro Devices. Her experience includes Unix systems administration, systems engineering, pre-sales consulting and post-sales services. Kristy is ITIL Foundation-certified and is an electrical engineering graduate of the University of Texas at Austin.
  • 6 Big, Bad Mistakes in Configuration Management, Part 1

    6 Big, Bad Mistakes in Configuration Management, Part 1

    Configuration problems come in many flavors. Some are mere nuisances. Often though, configuration errors can lead to more serious mishaps like application performance problems, policy compliance violations or even security vulnerabilities. They can often go undetected, quietly doing their damage in the background while everyone’s attention is focused elsewhere.

    Unfortunately, I find that configuration management is an area where many companies either 1) put it as a “last to solve” on their priority list (when arguably it’s quite important), or 2) try to solve it with a do-it-yourself fix, but in a way that’s not always extensible or that doesn’t end up working with their DevOps toolchain.

    Usually, I find configuration issues stemming from the age old problem: using the wrong tool for the job. In this blog I’ll address six big, bad mistakes of configuration management. (For the sake of brevity, three will be addressed here and three in an upcoming blog.)

    Before I get into it, though, there are so many definitions of configuration management that it warrants a brief summary so we’re all on the same page. I’m talking about the ongoing configuration management of the infrastructure tiers supporting your applications—the middleware, database and OS-level configurations that keep your applications’ lights on and everyone happy.

    Mistake No. 1: Only Considering Provisioning

    Notice I just mentioned the word “ongoing” in my definition of configuration management. I find that so often people forget to take the ever-important “ongoing” into consideration. I have many conversations with folks wanting to implement a “provisioning tool.” On the surface, they think they need just that: a tool that provisions infrastructure including all the tiers of the application. But when I probe further, what they’re really wanting is something that provisions and then continues to monitor, manage and fix. There’s a big difference there.

    Some tools do great at provisioning but lack the visibility and “ongoing” configuration management needs. Think of a provisioning tool as waving a bat at a piñata. Yes, you can “blow away your environment” and start over, but that blindfold prevents true visibility and ongoing interaction.

    When looking for configuration management, be sure to focus on your current and future needs. Do you just need a provisioning tool? Or do you need an ongoing configuration management tool? Or both? Most tools that tout doing both do one much better than the other, so be sure to do your research.

    Mistake No. 2: Using an ARA Tool to Manage Configurations

    In a previous position I spent quite a bit of time onsite with clients helping them automate their application deployment processes. What I found is that around 80 percent of “application deployment” tasks are actually configuration tasks. The application deployment is the easy part; it’s the configuration management aspect that causes all of the headaches. I would spend the majority of my time onsite hurriedly writing little scripts that would be hurriedly inserted into the deployment process that would set the application pool, restart the service, change a heap size, etc. I had to write the scripts because application deployment products are workflow automation engines with process wrapped around them. They are not meant to be infrastructure configuration management products.

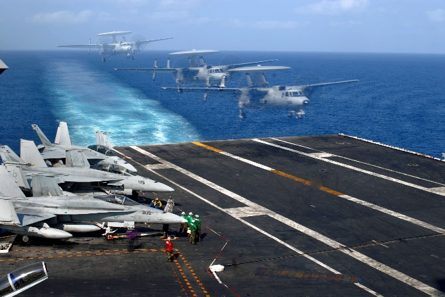
    It bears repeating: Traditional application deployment solutions are not meant to be infrastructure configuration management products. They can get you part of the way there, but 1) you’ll need to script it all, which is not extensible and defeats the true purpose of a tool, and 2) they simply catapult your application (one way only!) into the next environment (i.e. Test to Staging, Staging to Prod), so you can forget about the “ongoing” piece we discussed above. Compare that one-way catapult launch to the complexity of routinely engineering one safe launch (and landing!!!) after another on an aircraft carrier on the open seas. A mission-critical task like this requires advanced technologies, visibility, communication and coordination to account for constantly changing environmental factors.

    Mistake No. 3: Using a CI or Build Automation Tool When You Need Configuration Management

    As bad as misusing an application release tool when you really needed a configuration management solution, it’s even worse using a continuous integration tool for this. Like many DevOps solutions, CI tools are particularly helpful for developers. CI tools like Jenkins and Bamboo require Dev teams to share or check in their updated code into a repository. The CI tool then detects potential problems early by automatically verifying builds for the developer. From the Dev team’s perspective, there is no more wondering if their code is going to work, and they spend less time debugging and redoing. The financial benefits of CI and the early warning system they provide should be obvious and considered a must-have for developers.

    But while detecting coding errors early saves a lot of hassle for the Dev and Test teams, Ops teams do not directly benefit from CI. Here’s why: Operations teams are concerned with the application release into Production environments and then the ongoing configuration management of the entire application stack including the application, middleware, database and operating system. Once the (application) baton is passed to them, they require visibility into and intelligence about the application’s operating environments—well after Dev and UAT. As good as they are for Dev teams, CI tools are simply not equipped to provide ongoing operations support, visibility and coordination in Production that modern Configuration Management solutions provide.

    These are just a few big, bad mistakes in configuration management and they focus largely on misusing tools beyond their intended scope. I will follow up with a Part II companion article that addresses configuration management practices to be avoided.

    Tune into our upcoming webinar, which will touch on these topics as well.

    About the Author / Kristy McDougal

    Kristy McDougal leads Product and Sales Engineering for Orca, an application release and configuration automation solution for DevOps teams. Prior to launching Orca, Kristy was a Senior Pre-Sales Consultant within BMC Software’s worldwide DevOps specialist team. Before BMC, Kristy held technical positions at VaraLogix, Virtual Bridges, Global Foundries and Advanced Micro Devices. Her experience includes Unix systems administration, systems engineering, pre-sales consulting and post-sales services. Kristy is ITIL Foundation-certified and is an electrical engineering graduate of the University of Texas at Austin.