Tag: algorithm

  • AIOps: Managing the Second Law of IT Ops

    AIOps: Managing the Second Law of IT Ops

    Or, why IT systems keep breaking

    The tension between the two halves of DevOps is long-standing, going back long before the term was even invented. What underlies the split between Development and Operations is a fundamental difference, like an actual physical law. Let’s explore that analogy together.

    IT Ops is fundamentally a constant fight against entropy, meaning disorder. Sysadmins expend significant energy trying to keep everything up and running, in a process which can sometimes feel like trying to shore up a sandcastle while the tide is coming in. Systems are constantly breaking down; users need changes made that introduce risk; and, as if that wasn’t enough, the whole shebang is constantly under attack from malicious outsiders. It’s no wonder that sysadmins have a reputation for being a bit grumpy!
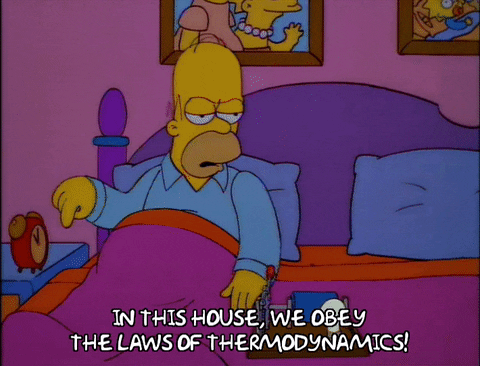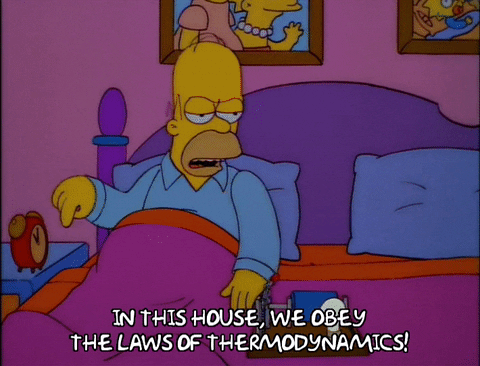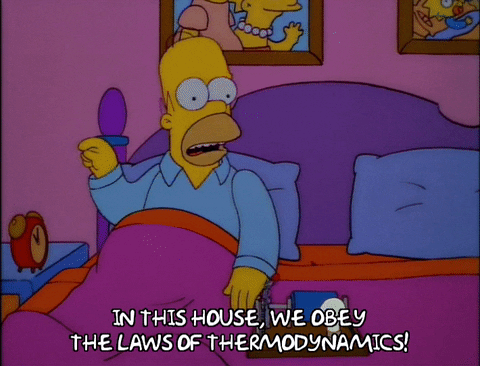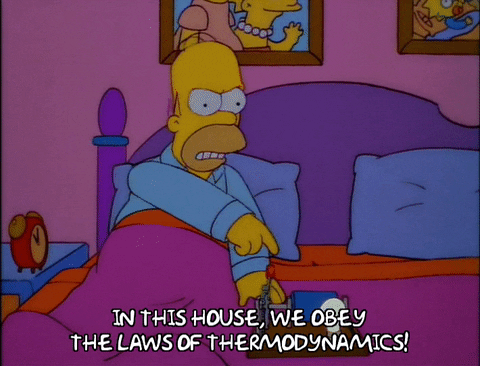
    Homer: In this house, we obey the laws of thermodynamics!
    It’s not just a good idea, it’s the law.

    In contrast, Dev actually increases the level of entropy. Every new release, be it as small as a one-line fix or finding that errant semicolon, is a change that has to be made, reducing the order that Ops fights so hard to maintain. Dev is entropogenic, embracing change as a positive force.

    The interaction between Dev and Ops is analogous to the second law of thermodynamics: Entropy can only increase over time, unless energy is introduced to the system from outside. In other words, unmanaged change will eventually cause something to break, unless people put in continuous effort to prevent those breaks.

    Thermodynamics: Lots of Heat, not Much Light

    These conflicting goals, taken to extremes, can get unhealthy, with Ops actively fighting change or Dev going around Ops to increase their velocity of change. Left unchecked, this tension can turn into a vicious cycle, as frustration with the “Department of No” drives developers into unmanaged “shadow IT.”

    The good news is that the analogy with hard laws of physics is not perfect. The process of increasing entropy is not irreversible, and does not require constant inputs of energy to prevent. New agile approaches to IT Ops are emerging that are light and flexible, taking their structure from that tension. In the physical world, this is called “tensegrity,” and was originally formulated by Buckminster Fuller, one of those annoying polymaths who seem to make breakthroughs in every field they touch.

    Tensegrity structure
    Tensegrity structure

    IT Ops needs its own equivalent to tensegrity, a flexible, holistic structure that is able to embrace change while maintaining its shape. Structures that try to resist change through rigidity are brittle and ultimately fragile.

    Today, this flexible strength is enabled by AIOps, a term coined by Gartner to describe a new way of operating IT, based on augmenting human skills with automated analysis enabled by modern algorithmic and machine-learning approaches.

    Complexity Breeds Complexity

    Modern IT is too complex for any single person or even team to keep track of, instead requiring multiple specializations. In turn, each of these functions requires its own specific support tools that enable that particular role. Beyond a certain point, it becomes very difficult to combine these partial views to gain a holistic understanding of what is actually happening in the environment.

    Because of the scale of modern IT environments and the sheer rate of change that businesses require, old-style rules-based “Managers of Managers” can no longer keep up, requiring more effort to build and maintain their worth. Especially as infrastructure becomes more and more self-modifying in response to changing conditions and demand, IT Operations needs to accelerate just to keep up.

    AIOps brings developing issues to the attention of sysadmins before they become visible to customers and end users, and gives them the tools to collaborate effectively between different teams and specialist roles to avoid outages or restore service quickly and efficiently. In this world, automation is used to augment the capabilities of the human operators to make them more effective, letting people concentrate on adding value, not just fighting fires.

    This is how Ops can get out of the business of fighting Dev, and instead become a supportive partner. AIOps can catch issues that are affecting services and flag them to the right people early on, including the DevOps engineers that are responsible for production support.

    For developers, one of the fears around DevOps is that in “picking up the pager,” they are opening themselves up to a constant stream of irrelevant alerts. Old Ops hands nod wryly at this, or maybe try to share their personal approach to filtering the noise. Instead, AIOps ensures that only valid, actionable alerts get as far as being shown to a human being and taking up their valuable time.

    Eyes on the Prize

    It’s not all roses. As the AIOps market begins to mature, there is a certain amount of “algorithm-washing” going on, with more and more vendors trying to claim that either their legacy tool was AIOps all along, or that their one-trick pony is actually a whole three-ring circus. What gets lost in the excitement is what all of those algorithms are actually supposed to achieve.
    Me too!
    Me too!

    In considering a shift toward AIOps, the goal should not be simply to build a better mouse trap, meaning a smarter filter for monitoring events. The success of the project can be measured not so much in the mathematical results of the algorithms, but in the smoother exchange between the human users. This easier collaboration is especially important across team boundaries, whether these be different specialist units within the Ops function or developers and software engineers who need to work with Ops to understand the performance of their code in production.

    The benefit of transforming operations this way—moving from sequential, waterfall Ops to abile, collaborative Ops—is to turn DevOps-enabled teams into a sort of perpetual-motion machine, able to continue operating without requiring constant massive inputs of energy from outside the system. Modern applications and the complex infrastructures that support them cannot be managed with the sorts of rigid, cobbled-together, industrial approaches that were appropriate in the mainframe days. AIOps is the agile, flexible approach that can not only accomodate that complexity, but thrive on it.
    — Dominic Wellington

  • Dev & Ops: These Are Reconcilable Differences

    Dev & Ops: These Are Reconcilable Differences

    The new world of IT requires a different approach from what worked in the past. As usual, the technology is the easy part, but without people and processes being aligned, it won’t deliver value. When evaluating how data science and machine learning can help manage highly dynamic IT environments, old reflexes may be actively harmful.

    By their nature and due to their experiences, Ops people tend to be a pretty (small-C) conservative bunch. Rule No. 1 of Ops is “If it ain’t broke, DON’T TOUCH IT!” and if we’re honest with ourselves, most of the rest of the rulebook is just variations and commentaries on that theme.

    One of the ways in which Ops people try to control their world is through automation. DevOps mostly looks to the moment of release and deployment, as that is where the handover to Ops typically occurs—and this is a big focus of the drive to automate. However, there is another part of Ops where automation is key, something that Dev is not always nearly as involved in; namely, day-to-day operations. Which alerts should even be sent, whom they should be routed to, what are the valid responses and so on—all these have been automated over the years, to a greater or lesser extent.

    Ops people have laboriously documented their architecture and spent a long time in meetings planning which information is relevant to share and who should respond to alarms. Much of this is implemented in various pieces of software, whether commercial, open-source, home-grown or that special grey area, where something that started out as a standard component has been so customized that it is effectively bespoke. Rules, filters and thresholds determine what action to take in which case.

    These approaches have been in place for years or even decades, but now they are starting to fail. Simply put, IT’s increased complexity and the ever-accelerating rate of change are outpacing administrators’ ability to keep up and reconfigure their management systems.

    The Coming ‘New Normal’

    New approaches are emerging to deal with the new normal, but as ever, the technology is the easy part. For new technology to be a success, people and processes need to be in sync.

    Right now, the emerging approach is to use data science and machine learning to process events, instead of the old deterministic rulesets and databases. The results speak for themselves, especially at scale and in highly dynamic environments. People building container-based or SDN architectures no longer assume that there will be a database of configurations that will always be up to date; quite the opposite.

    The new way is to throw out all the filters and rules, feed all the alerts into a single place, and then use data science and machine learning techniques to sift them and identify relationships with them. The result will be a shift in focus from individual alerts to the business problems those alerts are the symptoms of.

    Algorithms are great at these sorts of repetitive, high-volume tasks. They can look at massive volumes of events and figure out which are even relevant and worth taking a second look at, and then identify how those events relate to each other and what they really mean. This is where the humans come in, with their strengths in low-volume and unpredictable situations. Because they are not constantly drowning in irrelevant noise, they can work together effectively to understand the actual problem and get it fixed quickly.

    Where’s the Catch?

    The difficulty is that for many Ops people, there is a big cultural change required to adopt this model. The old deterministic systems may have required laborious maintenance, but at least it was possible to model them and understand why a specific result was achieved. New algorithmic techniques take a radically different approach, and while the results are impressive, they come from a black box. This does not inspire confidence for people who are very comfortable with the old approaches.

    Often, the response of Ops people coming from legacy tools is to get stuck into the minutiae of what is going on inside the black box and to look for traditional failure modes. The problem is that these approaches are no longer valid in the new world, as I discussed in my last post about getting to SRE.

    For instance, while it is indeed important to make sure that no issues are missed due to over-aggressive filtering, this does not mean that we need to see every single alert. As long as we know about the actual business problem, we don’t actually care about the single alerts, except insofar as they help us debug the underlying issue and resolve it.

    The other direction is even more insidious, where people spend a lot of time chasing down “extraneous” events that they think they should not be seeing. The risk is, of course, that the Ops team ends right back up in the same place that they were trying to escape, where they are only able to identify expected problems, but are getting blindsided on a regular basis by the “unknown unknowns,” the conditions that simply should not happen.

    Ultimately, Ops needs to let go of reflexes that were good in the old world, and focus on the goal: ensuring the uptime and stability of business-supporting systems. The how is less relevant than the what and the why; the algorithmic black box might as well be full of magic leprechauns, as long as they are telling Ops what they need to know, when they need to know it. Call it the “Chinese Room” theory of Ops: For as long as the results are useful to Ops, it does not matter what is inside the room.

    The benefit for Ops is precisely that they no longer need to focus on the minutiae of individual alerts, but can concentrate on solving actual business problems. That is how IT can make itself a value generator and avoid being viewed as another undifferentiated cost center.

    Pay no attention to the algorithm behind the curtain.

    — Dominic Wellington