Tag: Agile Security

  • The Real Pipeline

    The Real Pipeline

    I’ve made no secret of the fact that DevOps was a game-changing advance in how the business of IT was done. But people tend to get religious about the methodology and forget the point. That’s okay, DevOps has its roots in that mentality. After years of thinking bad things about the authors of The Phoenix Project for portraying anything that slows the process–you know, like code quality or security–as bad, I have come to accept that absolutes were required to drive forward motion in the market. “We’ve always done it this way!” was king in IT, but the rest of the business was fed up. That book got the ball rolling and we’ve slowly but surely pushed back against the mentality that adding milliseconds (or even a week) to build times in the average enterprise has any impact worth mentioning. Oh, some people still claim it does, but we can convincingly make the code quality/security argument.

    It is funny to me that the first few years of DevOps were focused on “We’re gonna change your religion!”—wanting to force upheaval of the entire IT org chart without a thought to the fact that you still needed specialists in storage, ops, etc. to keep the lights on. The mentality was that development issues were a people problem. To a large extent, they were right; they just missed one people problem in the set of equations. Let’s look at the real pipeline that we all don’t talk about, but really should:
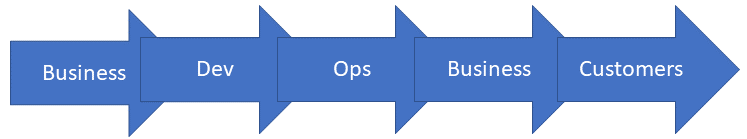
    Notice there aren’t tools in this chain; instead, there are groups of people. It is sad but true that the last two–representing acceptance testing and customer rollout–are almost always merged these days in all but a few organizations.

    This isn’t controversial; we still do the dev bit largely before the ops bit; the business has to decide what we want to offer the customer and customers are at the end of the line. And that is the key. Customers are at the end of the line. Now, I get to make you uncomfortable. Nothing in the above diagram matters except the first and last arrows. Think of it like this:
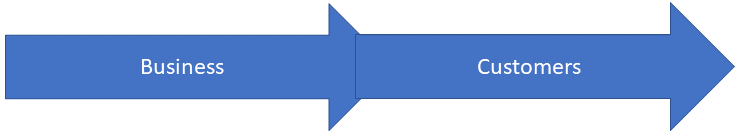
    What’s important in what we do comes down to two questions: “What does the business unit want to offer customers?” and “What do the customers expect of the business unit?” In this sense, “business unit” might be IT and “customers” might be co-workers. That changes nothing. What the business unit offers and what customers want is all that matters. The rest is implementation detail.

    Don’t believe me? It is an easy case to prove. Let’s try this one, with or without IT involvement, depending upon the problem being solved and the organization:
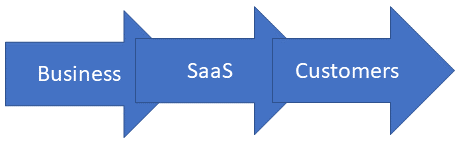
    The business unit determines what they want to offer, customers let their demands be known (one way or another) and the business offers the solution they think fits for the customers. As I said above, the rest is implementation details.

    What is your point?

    This leads me to the inevitable observation. Testing and security are:

    • Completely expected by users. They don’t want buggy software, and they don’t want to enter information assuming it will get nicked by hackers. There is no compromise here; users don’t “kind of want a product that works” nor do they want a product that “might be secure, but we’re not sure.”
    • Desired by the business. They have constraints on what is reasonable–the old meme of a server with the network cable cut is only funny because it shows extremes. But they absolutely do want the product or service they are offering customers to be stable and secure. “We can just spin out a new version” only works so often and for so long.

    So, your toolchains need to include stability and security tools—I would argue at every step of the process, but where and how much is really a business call. My security peeps will get upset that I called security a business call, but it is. You can choose to be non-compliant and insecure; the impact of those decisions on your organization is all on you. OTOH, of all the things that the organization (both the business generally and IT specifically) are focused on, you can afford to drop a few and get security and stability right the first time.

    Meanwhile, you’re keeping things running while we debate things like this. While I repeatedly refer to a large portion of my target audience as “implementation detail,” I’m sure you all know how much I (and many others) appreciate the rockstar job you’re doing keeping the IT org supporting the greater org.

  • Quick! Define DevSecOps: Let’s Call it Development Security

    Quick! Define DevSecOps: Let’s Call it Development Security

    For a good long while, DevSecOps referred specifically to vendors like Veracode that did static application security scanning, dynamic application security scanning, software composition analysis and some form of runtime monitoring (usually interactive scanning). Then we realized that DevSecOps was potentially a lot more than that and, like DevOps, we drove the word to encompass all things that shift security left.

    That’s where we are now. But that leaves the DevSecOps market confusing to a lot of people. I propose we rename the tools that specifically focus on code quality to Development Security—even though that name is not perfect and all-encompassing. It’s a better fit than terms in other spaces, like Password Management, which includes two-factor authentication (2FA), multifactor authentication (MFA) and, increasingly, passwordless and secrets management, none of which actually use passwords for the focus of their functionality.

    This way, we can all understand that DevSecOps is the mindset and methodology and Development Security is one piece of implementing DevSecOps.

    There are probably people smarter than I am who have come to this (or alternate) conclusions, and I’m happy to run with their solutions, too—this is just an attempt to make it less confusing for those who don’t live and breathe the security and DevOps markets. If a new person says, “I think we need DevSecOps,” they are in for a journey to actually figure out what they meant and if what they need is actually DevSecOps. We should strive to clarify that so, at the beginning of their research, it is clear that DevSecOps is like DevOps—an overarching term for policies, procedures, mindset and products while the tools that can help with DevSecOps, like those that make up the overarching DevOps toolchain, belong to a market segment named X. In my case, I proposed Development Security because it’s a close fit. What we actually call it is irrelevant, as long as new people understand it is a subset of DevSecOps.

    While you continue to keep the systems spinning and the organization online, when you research these products, use phrases like, “I’m looking for Development Security tools that fit with a DevOps environment.” Markets are largely named by vendors and pundits but, in the end, all these people want to talk in terms their customer base recognizes. So, if enough of you ask for Development Security, that’s what they’ll all start calling it. Effective immediately, that’s what I’m calling it. It is a distinctive set of functionality that all orgs who do internal development need, so let’s give it a distinctive name. And yeah, drop me a line if you have a better name. I’m tied to making it easier, not to a specific term.

  • Security Debt: Speed vs. Common Sense

    Security Debt: Speed vs. Common Sense

    A couple years ago, we had some spectacular security events that involved DevOps and Kubernetes, where the managing team simply redeployed containers whenever one crashed. It turned out that many organizations were doing the same thing, and, what’s worse, they were not talking about it because they knew it was not a long-term solution to crashing issues.

    At the time, I thought these high-profile lessons would teach people to actually fix code issues, even in high-throughput Agile-meets-DevOps shops. I admit I also laughed, yet again, at The Phoenix Project’s expense, thinking, “Yeah, but the CISO isn’t holding things up by demanding that get fixed!” I wish that would ever get old, but it won’t.

    It seems I was wrong. Or at least partially so. Some—perhaps many—shops seem to have missed the message that these issues sent. Anecdotally, we heard this was still happening, so we started asking questions. Yep. There are shops out there (since we started with ‘anecdotally,’ I won’t pretend to put numbers around it) that still take an “If it isn’t causing disruption in core systems, don’t fix it” mentality.

    Ouch. We’ll be revisiting some of those in the future, I’m sure—when it’s listed as a vulnerability or breach somewhere.

    I’m not a security professional. Because the vast majority of enterprises do not have dedicated security and even more don’t have anything close to enough security staff, I have done security as a part of almost every job I’ve taken—because it was what needed doing the most. Many, if not most of you, are in the same boat.

    That said, I can tell when you are blatantly asking for a security incident. And running code known to be faulty or misconfigured to the point that it repeatedly crashes is deliberately asking for a security incident. “But it isn’t exposed to the Internet!” is only a valid rebuttal until an attacker gets inside the perimeter and uses your fault for something like privilege escalation. Then no one cares if it’s connected to the internet or not; they want to know how the attacker did it. And that’s on you.

    So for those organizations in which speed has overridden common sense, let’s be very clear and to the point.

    It is a best practice not to run crash-level faulty software.

    Since you must not have one, write a policy that explains this and lays out a process and/or timeline to fix these problems. Then drive it home. Make certain it is known that this policy will be enforced. For that huge majority of my readers that don’t have the level of authority that “create and promulgate a policy” implies, convince those who do. Point out the issues to them in writing. “Notified in writing of faulty practices that could bite the company in the rear,” tends to get even the most unfriendly management to click into CYA mode and do something about it.

    When we all watched those spectacular failures back in the day, I assumed that this was all about growing pains; you can do so much more with Agile/DevOps/cloud and/or Kubernetes that this type of thing would crop up and, eventually, get addressed. I still believe that. You all are still testing the boundaries and pushing the limits and making all of IT look good. It’s just going to hurt getting there sometimes. Fix the apps, make the policy, keep kicking butt and know you are killing it (as an industry. If you aren’t, stop laughing at my blanket compliment and fix yourself).