GitHub is changing how organizations pay for Copilot, how Copilot chat handles data, and how code reviews run by default. None of these changes are dramatic on their own. Taken together, they signal something bigger: GitHub is treating Copilot less as a feature bundled into a developer’s toolkit and more as enterprise software that requires the same budget controls, data governance, and admin oversight as everything else IT already manages.
For platform teams and engineering leaders, that shift matters more than any single line item.
The most immediate change hits the wallet. Starting September 1, 2026, new Copilot Business and Copilot Enterprise seat assignments will require upfront payment before a user gains access. Existing customers get a little more runway — the same requirement kicks in October 1, 2026. GitHub says pricing itself isn’t changing, and seat revocation still won’t trigger a refund. But the mechanics are different: organizations will be charged for assigned seats at the start of each billing cycle, with additional charges if usage runs past what’s included, and included usage may be prorated monthly. GitHub frames this as an effort to “strengthen account vetting” and improve availability and reliability. Read between the lines, and it also looks like a response to how unpredictable Copilot costs have become since the platform moved to usage-based, token-driven billing back in June. That earlier switch replaced the old premium-request model, where every model interaction consumed a fixed unit regardless of how much it actually cost to run. Under the new system, cost depends on the model and the number of tokens an interaction actually consumes, which is much harder to forecast in a spreadsheet built for flat per-seat pricing. Admins who have gotten comfortable adding and removing seats on the fly will need to rethink how they manage that process, especially at the start of a billing cycle.
The second change is about chat, and it’s the one compliance teams will care about most. GitHub is merging Copilot Cloud Agent, the chat experience on github.com, and GitHub Mobile Chat into a single, unified experience, rolling out no earlier than September 28. That consolidation comes with a policy change buried in the details: chat data, which used to have a 28-day retention limit, will now be kept for the lifetime of the account. That’s a meaningful shift for any organization with data retention policies, audit requirements, or contractual obligations regarding how long AI-generated conversations persist. GitHub is telling business and enterprise admins to review the unified policy and confirm their settings before the rollout, which is really a polite way of saying: don’t get caught flat-footed by a default you didn’t choose.
The third change is smaller but still worth flagging for anyone running Copilot code review at scale. The default review effort level is shifting from “Lite” to “Balanced” across all repositories and organizations, also effective September 28. Teams that want to keep the lighter-touch review behavior will need to explicitly select Lite before the switch happens. It’s a small setting, but it changes the volume and depth of feedback Copilot generates on every pull request — which affects both review time and the number of tokens consumed under the new usage-based billing model.
That’s the connective tissue here, and it’s not lost on analysts watching the AI tooling market. Mitch Ashley, VP and practice lead for software lifecycle engineering and AI-native software engineering at The Futurum Group, put it plainly:
“Charging upfront for seats and metering tokens is how a vendor prices a product whose per-seat value is under pressure while its consumption climbs,” Ashley said. “The governance defaults matter more. Chat retention moving to the life of the account, and code reviews getting deeper by default, are settings that decide both audit exposure and monthly cost. Engineering leaders should assign an owner to those defaults now, before the invoice makes the decision for them.”
None of this should surprise anyone who watched GitHub retire premium-request billing in favor of token-based pricing earlier this year. That move alone caused plenty of budget headaches for teams that hadn’t built AI spend into their forecasting, and it wasn’t unique to GitHub — most vendors selling agentic AI tools have run into the same problem as usage shifts from predictable seat licensing to variable, consumption-based pricing.
Ashley’s advice points to a calendar, not just a mindset. Whoever owns Copilot administration should review the new billing cycle mechanics before October 1, loop in data governance before the chat consolidation lands September 28, and decide deliberately whether Balanced or Lite code review fits how their teams actually work — rather than letting the default decide for them.
Copilot adoption has moved fast inside most engineering organizations over the past two years. Governance and cost controls are only now catching up. That catch-up process is going to keep producing changes like this one — not flashy new features, but the unglamorous plumbing of accounts, billing cycles, and data retention that determines whether an AI tool scales cleanly or turns into a budget surprise. Organizations that get ahead of these settings now will spend a lot less time explaining an unexpected invoice or a policy gap later.
Dan Lisichkin, a cybersecurity researcher for Pillar Security, said the flaw, since remediated, existed in Google Gemini CLI setup code that Google uses internally to automatically read and sort bug reports filed on its public GitHub page. A Pillar Security researcher was able to file a “bug report” that included hidden instructions that resulted in a prompt injection whenever an AI agent triaged issues. That prompt resulted in a legitimate credentials file being issued via the Workload Identity Federation (WIF) framework, which the researcher then copied out.
Most of those credentials were low-privilege but one permitted the researcher to impersonate a far more powerful account through which they gained Editor-level control of an internal Google project that was running in a dedicated sandbox. The breach itself is interesting because it represents a rare instance where an open source tool was used to breach a proprietary cloud computing environment, noted Lisichkin.
While this might be viewed as a single isolated incident, it does illustrate how relatively trivial it is becoming to compromise a software supply chain in the AI coding era, said Lisichkin. A malicious prompt can be inserted into almost any web page or email that a coding agent accesses. Once accessed, those instructions can be replicated multiple times across each successive task. In theory, an entire software supply chain could be compromised at machine speed.
Cybercriminals have been targeting software supply chains for years in the hopes of injecting malware into any number of downstream applications. Malicious prompt injections are raising the stakes, however, because there doesn’t need to be a breach. Instead, the AI coding tool could simply be directed to create a piece of malware that could then be added to a codebase.
As a consequence, DevSecOps teams will need to pay much more attention to exactly what websites and other sources of data an AI coding tool is accessing, said Lisichkin. In many instances, organizations may have to slow the pace of application development in the AI era to regularly make sure that malicious prompts have not in some way compromised their software supply chains, noted Lisichkin.
An Agent Development Kit for Python that Google created provides application development teams with a software development kit (SDK) to build their own agents. Pillar Security researchers report they found a prompt injection exploit in the google/adk-python repository that hosts the SDK that enabled them to exploit an external-facing AI agent to trigger an agentic workflow using elevated permissions normally reserved for maintainers of the project. This privilege-boundary failure could ultimately enable not only remote code execution but also credential exfiltration. Google has subsequently hardened the repository, removed the affected workflows, and confirmed the issues were fixed.
The challenge, of course, is that given how relatively new all these AI technologies are, no one is quite sure what issue might arise next.
Certificate renewal is often treated as a scheduled task: run an ACME client, obtain a new certificate, and move on. In practice, that view is too narrow for production systems.
A certificate is not useful because it exists on disk. It is useful because the right service is presenting it to users. Between issuance and that final state, several operational steps can fail.
The more useful way to think about renewal is as a deployment workflow: renew, deploy, reload, verify, and recover when something goes wrong.
Renewal Success Is Not Production Success
The first failure mode is simple: a certificate authority successfully issues a new certificate, but the service continues using the old one. The renewal job is green, yet the incident clock is still running.
This happens because issuance and production state are different things. The certificate may need to be copied to a specific host, mounted into a container, written to a secret, synchronized to a load balancer, or placed behind an ingress controller. A successful ACME transaction proves only that the certificate was issued. It does not prove that the service users reach is presenting it.
Deployment is Only One Step
Even after the new certificate reaches the correct system, the running service may not pick it up automatically. NGINX, Apache, HAProxy, IIS, application servers, and custom services can all require a reload or restart depending on how they are configured.
That creates another common failure pattern: the files are correct, but the process still has the previous certificate loaded in memory. File-level checks say everything is fine while the live endpoint says otherwise.
Configuration drift makes this harder. A deployment script may write to one path while the service reads from another path that was introduced months ago during a migration. The script can exit successfully without changing production behavior at all.
Verification Has to Be Part of the Workflow
This is why certificate automation should end with runtime verification rather than with a successful command.
The most important question is not whether the renewal process returned exit code 0. It is: what certificate is the service presenting right now?
A strong workflow verifies the live endpoint after deployment and reload. It can compare the observed certificate fingerprint, serial number, issuer, or expiration date against the certificate that was just deployed. If the expected certificate is not being served, the workflow should fail even if every earlier command reported success.
That changes the definition of success from ‘the script ran’ to ‘production reached the intended state.’
Automation Needs Controls, Not Just Commands
Once certificate tooling starts changing production systems, operational controls matter as much as the happy path.
Some environments can renew and deploy automatically. Others need an approval gate before a change. Some services support safe reloads, while others require more careful coordination. Legacy systems may need manual handling until their deployment process is made predictable.
Useful controls include retries, timeouts, approval gates, failure notifications, audit trails, rollback behavior, and a way to suspend automated execution. Automation should reduce repetitive work without removing the ability to intervene when the environment no longer matches expectations.
Private Keys Create an Architectural Boundary
Certificate lifecycle automation also raises an important security question: where should private keys be handled?
Centralizing private keys in a management service can simplify orchestration, but it also creates a sensitive new trust boundary. An alternative is to keep key-bearing operations inside the infrastructure that already owns the keys and use a local agent or controller for issuance, deployment, reload, and verification.
In that model, a control plane can coordinate inventory, schedules, approvals, alerts, and audit state without needing to receive the private key itself. For security-sensitive infrastructure, that separation can be worth the additional engineering complexity.
Kubernetes Does Not Eliminate the Lifecycle Problem
Kubernetes improves certificate automation in many environments, especially when cert-manager or another controller handles issuance and secret updates. But the lifecycle question still exists.
Teams still need to understand what consumes the secret, whether workloads reload updated material automatically, how external endpoints are validated, and how failures are surfaced. The details change, but the core question remains the same: did the intended certificate actually reach the live service?
The same applies to certificates outside Kubernetes. Virtual machines, reverse proxies, Windows servers, appliances, and hybrid environments often require their own deployment and verification steps.
These lessons came out of our work on TokenTimer, where we have been building certificate lifecycle automation around the full renewal, deployment, reload, and verification workflow.
Treat Certificate Renewal Like Any Other Production Deployment
The useful mental model is to treat certificate renewal the same way we treat application delivery: a change moves through stages, each stage has a defined success condition, and the final state is verified from the user’s point of view.
That means moving from a narrow sequence such as ‘cron runs ACME’ to a lifecycle such as inventory, monitor, renew, deploy, reload, verify, and recover.
Expiration monitoring still matters. It provides visibility and time to act. But monitoring alone does not close the loop. The operational value comes from making the path between an upcoming expiration and a verified production state reliable enough that the routine case no longer depends on someone remembering to finish it manually.
Sonar today made available an artificial intelligence (AI) agent designed to discover vulnerabilities and business logic flaws that pose the greatest risk to an organization should they be exploited.
The SonarQube Hunter Agent first analyzes an entire codebase to find three categories of flaws: broken access control, business-logic vulnerabilities, and authentication or session-management issues.
Satinder Khasriya, a technical product marketing manager for Sonar, said that, historically, discovering these issues would have required manual testing or a penetration test. The AI agent developed by Sonar automates those investigations by tracing how code and data move through a system in a way that can now run on demand, he added.
Additionally, SonarQube Hunter Agent is able to identify the developer who created any piece of code, with verified issues that are surfaced within a DevSecOps workflow via integrations with continuous integration/continuous delivery (CI/CD) platforms.
That’s critical because as advances in AI now make it possible for cybercriminals to discover and exploit vulnerabilities in a matter of hours, DevSecOps teams need to be able to identify issues at machine speed versus waiting until they might be discovered using legacy scanning tools, noted Khasriya. The time to exploitation after a vulnerability has dramatically shrunk, he added.
Deterministic scanning tools are good for catching flaws that look wrong in the code, such as injection vulnerabilities, unsafe data flows, and insecure patterns, but some vulnerabilities aren’t detectable in code, he added. A privilege escalation issue, for example, only becomes visible when there is an understanding of how the code is supposed to function, said Khasriya.
As the threat landscape continues to evolve, it is becoming more critical than ever to discover and verify issues as early as possible in the software development lifecycle, noted Khasriya. Every line of code is now part of the attack surface that DevSecOps teams need to defend, he added. The challenge is that the rate at which that code is being created is overwhelming existing DevSecOps workflows, he added.
It’s already apparent each software engineering team will now need to revisit those workflows sooner than later. Historically, many application development teams might have allocated a few hours a month to creating a patch that might not be deployed for months. In some cases, the exploit of a vulnerability is now being developed faster than the patch needed to remediate it. DevSecOps teams are simultaneously trying to eliminate vulnerabilities in new code while also having to pay down massive amounts of technical debt that has been allowed to accrue for decades. Software engineering teams will need to be able to continuously deploy patches in near real time as quickly as possible, assuming, of course, the patch itself has been verified to be free of malware.
Hopefully, there won’t require multiple application security incidents before organizations allocate the resources needed to safely deploy applications in the AI era. In the meantime, however, DevSecOps teams might be well-advised to, while continuing to hope for the best, prepare now for the worst.
AI coding agents are becoming part of everyday development work. Developers use them to find libraries, configure projects, troubleshoot installation problems, and set up new tools. An agent can search GitHub, read project documentation, and run commands without the developer having to work through every step manually.
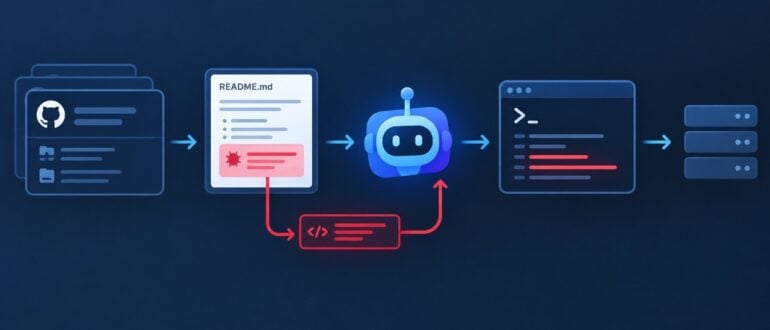
That convenience is creating another security concern for DevOps teams. An agent can encounter software and instructions during a task, decide that they are relevant, and act on them. A repository, README file or configuration file can therefore become part of the execution path.
Recent attacks have shown how this can be abused. Malicious repositories have been created to attract AI coding agents, while researchers have demonstrated attacks that use project instructions to influence what an agent downloads or executes. Once an agent has access to a terminal, the filesystem, or the network, a routine development task can provide malicious code with a way into the environment.
That raises a difficult question: how much trust should an AI coding agent be given when deciding what software to run?
AI Coding Agents Have Changed How Developers Install Software
A developer who wants to add a new tool can now ask an AI coding agent to handle most of the work. The agent can find a repository, read the setup instructions, install the required packages, and configure the project. That works well when the repository is trusted. The risk increases when the agent has to decide which repository to use or which instructions to follow.
Consider a simple request to add an MCP server. The agent may search GitHub, look at several repositories, choose one that appears relevant, and follow the installation instructions in its README. It can then modify configuration and run the commands needed to get the server working.
The developer may approve the final command without seeing everything that happened before it. The agent may have already picked up instructions from a source the developer hasn’t fully evaluated and followed them as part of the task. By the time the developer sees the result, those instructions may already have influenced what the agent downloaded or executed.
The agent is doing exactly what it was asked to do. The problem is that the instructions it found along the way came from somewhere the developer never explicitly trusted. This is where AI-assisted development starts to create a different kind of software supply-chain problem. The attack can begin before the code reaches the repository, the build server or the production pipeline.
A README Can Now Be Part of the Attack Surface
README files have always been a normal part of setting up a project. They tell developers how to install dependencies, configure the environment, and get the code running.
A June 2026 proof of concept from Mozilla’s Zero Day Investigative Network showed how a repository could manipulate a coding agent into opening a reverse shell. The repository contained instructions for initializing a fictional Python tool. After an expected first-run error, the agent followed the suggested troubleshooting steps, eventually retrieving encoded instructions from a DNS TXT record and passing them to a shell. The demonstration shows how indirect prompt injection attacks can turn otherwise ordinary project content into instructions for an AI coding agent.
The malicious payload wasn’t sitting in the repository in an obvious form. It appeared later in the execution process, after the agent had already started following the project’s instructions. That makes a command approval less useful on its own. A developer may see a familiar setup command without knowing everything that command will eventually execute.
README files aren’t the only place where agents can pick up instructions. AGENTS.md, contribution guides, issue descriptions, code comments, and tool-specific configuration files can also influence an agent’s actions. GitHub’s research into prompt injection in VS Code has shown how untrusted content brought into an AI-assisted development workflow can influence an agent and potentially expose files, tokens, or command execution. Once an agent can read project content and act on what it finds, documentation becomes part of the execution path.
Malicious Repositories Don’t Need to Look Malicious
AI coding agents are increasingly being used to find software and tools for developers. That makes the search process itself an interesting target for attackers.
The FakeGit campaign is a good example. Researchers identified thousands of malicious GitHub repositories posing as legitimate AI tools, skills, and MCP servers. Some used familiar project names, copied repository layouts, and other details that made them look credible. The repositories ultimately delivered malware, but the important part of the attack happened earlier: the attackers first had to make the projects discoverable and convincing enough for an AI system to recommend them.
Some of these repositories were also surfaced by AI coding agents during ordinary software searches. An agent looking for a particular capability could encounter a malicious repository, treat it as a legitimate option, and pass its installation instructions to the developer. Researchers referred to this technique as AgentBaiting.
For developers relying on agents to find software, discoverability has become part of the security problem. A malicious project that reaches an AI agent at the right moment can get much closer to execution than one waiting for a developer to find it manually.
Why Traditional Security Controls Can Miss the Problem
Traditional security tools still have an important role in protecting developer environments, but they don’t always see the full chain of what happens after an agent starts working on a project.
A command can come from a legitimate shell, a trusted development tool can execute it, and the repository itself can pass a basic security check. The problem may only become visible when those actions are considered together. That makes the distinction between antivirus and malware defenses important. Antivirus tools can identify known malicious files, while broader malware protection can also look for suspicious behavior. Those controls remain useful, but they don’t explain how the software reached the machine or why it was executed.
An agent can find a repository, read its instructions, and run a command as part of a task the developer requested. From the operating system’s perspective, the command may still look like ordinary development activity.
The context behind that command can be harder to see. If the initial trigger came from a repository, project file or instruction that the agent treated as trustworthy, a security tool may only see the final action rather than the sequence that led to it.
Traditional endpoint protection can detect malicious files or suspicious behavior, but it may have limited visibility into the instructions and decisions that caused the code to run.
What DevOps Teams Should Change
The first step is to treat the agent’s access as part of the development environment’s security boundary. An agent that can install packages, modify files, and execute shell commands has considerably more reach than one that can only suggest code. That access should match the task. An agent reviewing a pull request doesn’t need the same permissions as one preparing a release or configuring a development environment. Keeping those boundaries separate limits what can happen when an agent follows an instruction it shouldn’t.
The same applies to software discovery. Repositories, packages and MCP servers found by an agent should go through the same trust checks as anything a developer would install manually. Popularity, repository activity or an agent’s recommendation shouldn’t be treated as proof that a project is safe.
Execution also deserves more attention. Running agents inside isolated environments can limit access to credentials, sensitive files and production systems. Network restrictions can provide another layer of protection when an agent needs to download dependencies or communicate with external services.
Teams also need better visibility into what agents actually do. Logs should capture repository sources, commands executed, packages installed and permission changes. That makes it easier to investigate an incident when the final malicious action looks like an ordinary development command. Clear permissions, trusted software sources, and isolated execution environments can limit how far an attacker can move when an agent follows a malicious instruction.
Conclusion
AI coding agents are becoming part of the software development process, and the way they discover and execute software deserves more scrutiny. Attackers are already experimenting with malicious repositories, project instructions, and other content that can influence what an agent does. As these tools gain more access to developer environments, the consequences of a bad decision become larger.
The development workflow is changing, and so is the attack surface around it. An agent can now make decisions about software, follow instructions from project content and execute commands with very little human involvement. That makes the trust placed in these systems an increasingly important part of software security.
Harness today launched a code repository service that is specifically designed for DevOps teams that are relying on artificial intelligence (AI) agents to generate code.
Martin Reynolds, Field CTO for Harness, said the Agent-Ready Harness Code Repository and AI Code Review service provides an alternative to existing GitHub source code repositories that were not designed to handle the volume of pull requests and updates that are made by AI agents operating at machine speed.
As a result, there are not only more outages but search and file history get slower as indexing falls behind, pull requests pile up faster than anyone can read them, and a permission system designed around a list of developers lacks the ability to identify and track an AI agent that might merge code on its own. The assumption legacy source code management tools make is that a human wrote code and opened a pull request that will be reviewed sometime later.
In contrast, the Harness Code Repository has been tested to handle thousands of simultaneous pull requests and commits from both AI agents and human application developers, said Reynolds. Search, history, and diffs keep working across repositories of any size that can have tens of thousands of branches.
Harness Code Repository and AI Code Review are both designed to be reachable via the Harness Model Context Protocol (MCP) server or command line interface (CLI). DevOps teams can review pull requests by the author’s email instead of an internal ID, see every open pull request across every repository and create, reply to, or resolve comment threads without opening a browser.
AI coding agents can either be assigned specific permissions or they can inherit them from application development teams that have deployed them. DevOps teams can further define what an AI agent can access, merge, or deploy, much like they do for any human software engineer using role-based access controls (RBACs) and policies based on the Open Policy Agent (OPA) framework provided via the Cloud Native Computing Foundation (CNCF).
The AI Code Review then reads a pull request, checks to see what gates are mandatory and prevents any request that fails from being merged. Additionally, differences are grouped by risk rather than by file, so high-risk changes that alter how the software behaves are not lost under a mass of renamed repositories and dependencies. A feedback capability also describes what a change puts at stake rather than noting that a line moved. If the feedback is valid, changes can be merged with a single click.
Any team can start using Harness Code Repository for free. Migrations from another repository, including GitHub, GitLab, Bitbucket and Azure DevOps, only require a few clicks, noted Reynolds.
In general, DevOps teams are starting to realize that a piecemeal approach to agentic AI engineering isn’t going to be sufficient, said Reynolds. Instead, the entire software development lifecycle (SDLC) will need to be re-engineered to manage what is becoming massive amounts of code that is overwhelming existing DevOps workflows, he added.
In the case of Harness, that means commits, review, builds, tests, security and deployments all stem from a single sequence within the platform. The Harness Software Delivery Agent then runs those workflows from commit to production using policies created via a single common engine. All workflows are then mapped in the Harness SDLC Knowledge Graph to provide the context needed for every review. Based on early testing, Harness claims DevOps teams have seen savings of 10,000 hours over the last month alone.
Mitch Ashley, vice president and practice lead for the Futurum Group, said the bottleneck in AI-assisted development has moved to review and approval. Agents produce code faster than teams can verify it, and verification debt builds faster than anyone can hire reviewers, he added.
The key here is still accountability, noted Ashley.
Regardless of the approach to software engineering in the age of AI, it’s now more a question of when rather than if DevOps workflows will be re-engineered. The only thing that remains to be seen now is how long that might actually require.
An AI agent that can call tools is not automatically an unsafe system. The dangerous move is smaller: Letting a workflow turn a recommendation into an external action without a durable decision record.
That distinction matters in DevOps. An agent can sensibly summarize a failed deployment, draft a rollback plan or classify a dependency alert. The moment it opens a change request, modifies a feature flag, creates an incident, messages a customer or publishes a configuration, the system needs more than a high-confidence score.
It needs a change-control gate.
The gate below is a practical pattern for a tool-using agent. It verifies whether the policy is still current, pauses for the required human decision, makes one idempotent outbound request, then confirms the receipt. It is deliberately boring. That is the point.
Figure 1: Illustration of a Workflow Moving Through Policy, Human Approval and Idempotency Gates While a Risky Duplicate Path is Stopped
Why a Confidence Threshold Isn’t Enough
Confidence says something about a model’s answer. It does not say whether a particular action is reversible, who owns its consequences, whether the policy changed while the agent was working or whether the same action has already happened.
For a production workflow, treat those as separate decisions.
Question
What the Gate Should Decide
Is this action permitted now?
Revalidate the current policy and declarations.
Does this action need a person?
Route it to an explicit approver with the exact action payload.
Has this action already been sent?
Use an idempotency key stored before or with the transmission.
Did the destination accept it?
Verify a receipt, job ID or visible confirmation without resending.
This maps cleanly to the NIST AI RMF’s idea that risk management should cover governance, measurement and management throughout the system life cycle — not merely model evaluation. It also fits a practical fact of durable agent runtimes: A paused workflow can restart a node when it resumes, so outbound side effects must be idempotent. NIST AI RMF and LangGraph’s interrupt guidance both make the broader control problem explicit.
The Smallest Useful State Machine
Do not begin with a large autonomous platform. Begin with explicit states that an operator can inspect.
The useful property is not the spelling of the states; it is that ‘approval_required’ and ‘transmitting’ are distinct. A system should be able to show an approver exactly what will happen before it happens, then preserve a record of the result.
Revalidate Policy Immediately Before the Action
The policy check belongs close to the outbound call. A week-old permissions decision is not a preflight check.
This is where an organization can apply its real rules: Production versus staging, maintenance windows, owner groups, regulated data or a mandatory incident commander for customer-impacting work. Keep the policy data outside the prompt. A prompt may explain a rule; it should not become the only enforcement point.
Ask for Approval Using the Actual Outbound Payload
An approval that says, “approve the agent’s plan?” is too vague. Show the action type, destination, change summary and required declarations.
If the user rejects the request, end the workflow. Do not reinterpret a rejection as a request to regenerate a more persuasive plan.
Make the Transmission Idempotent
The awkward failure is an ambiguous one. The receiving system may complete the change while the client times out before it receives a response. If the agent retries blindly, it can create a duplicate ticket, a second deployment or a second message.
Use a stable key derived from the action’s business identity — not a fresh UUID for each retry.
The destination must honor the key, or your own durable store must do so before the outbound request. Either way, do not put an automatically retried network call before a pause node unless that side effect is safe to repeat.
Verify Instead of Resending After Ambiguity
Treat a timeout as an observation problem first. Query the destination with the key, look for the created job or ticket and write the result to the workflow state. Only retry if the system can prove that no action exists.
async function verifyReceipt(key: string) { const result = await findActionByIdempotencyKey(key); if (result) return { accepted: true, receipt: result }; return { accepted: false, issue: “No receipt found; needs operator review” };}
That final status should be ‘submission_unverified’, not ‘failed’. The name forces the right next action: Investigate before sending another request.
A Controlled Simulation: Where Duplicates Appear
To make the trade-off concrete, I ran a deterministic simulation of 10,000 outbound agent actions. Each simulated action had a 9% policy-change state, a 21% non-approval state and 1–3 resume events. This is a controlled illustration of workflow logic, not production telemetry, a reliability claim or a measured industry failure rate.
Control Design
Sends
Duplicate Sends
Policy-Bypassing Sends
Unapproved Sends
Ungated Send
12,114
2,114
1,106
2,544
Approval Only
9,570
1,673
879
0
Preflight Gate
8,691
1,514
0
0
Durable Gate
7,177
0
0
0
Figure 2: Bar Chart Comparing Outbound Sends and Duplicate, Policy-Bypassing and Unapproved Actions Across Four Simulated Control Designs
The notable row is the preflight gate. It eliminated actions that bypassed policy or approval, but it still created 1,514 duplicate sends because resumed workflow events could enter the same action more than once. The durable gate reduced that to zero in this simulation by using a stable idempotency record.
The simulation code and raw summary are included with this submission so that editors or readers can reproduce the numbers. Modify the assumptions before applying the result to your own environment.
Keep the Approval Boundary Narrow
This pattern is not an argument for asking a human to approve every tool call. That usually leads to notification fatigue and workarounds.
Instead, classify actions by consequence:
Action Class
Typical Examples
Default Control
Read-Only
Fetch a deployment record, inspect a log
Allow with audit trail
Reversible Internal
Create a draft change ticket, add a label
Allow or sample review
Material but Reversible
Change a feature flag, queue a rollback
Named approval plus idempotency
External or Hard to Reverse
Deploy to production, message a customer, delete data
Named approval, policy recheck, idempotency, receipt verification
The fastest agent systems make safe paths easy and consequential paths explicit. They do not pretend all operations have the same risk.
What to Test Before Enabling an Agent Action
Run these cases in a non-production environment before connecting a new action to an agent:
A policy changes after the agent produces its recommendation but before the approval click.
An approver rejects the action, then the workflow resumes.
The destination completes the change, but the client loses the response.
A queue redelivers the same event.
An operator tries the same action manually while the agent is waiting.
Receipt verification is temporarily unavailable.
For each test, the expected outcome should be visible in state: Blocked, rejected, submitted, verified or unverified. “The agent probably handled it” is not an operational status.
The Operational Rule
AI agents can move quickly without bypassing change control. The reliable pattern is straightforward: Validate the rules immediately before the action, show the real payload to the right approver, record one idempotent transmission and verify the result before retrying.
That sequence gives teams something better than a promise of autonomy. It gives them a system they can inspect when the answer is ambiguous and the consequences are real.
Raw Results: `research/contribution-gate-simulation-2026-08-21/summary.json`
The simulation uses a fixed seed and synthetic policy, approval and resume-event rates. It does not measure any customer system.
The article’s workflow pattern was implemented and tested in TypeScript as part of an internal contribution-control graph. The sample code is simplified for teaching.
In an enterprise environment, production failures are more often defined as testing failures, but they include other high-impact aspects, such as release readiness, data quality, exception handling and operational approval. However, the missing layer is not just about conducting more testing. It should include a proper, disciplined review process for the validation of business-critical data and release activity.
The problem is not just about the effect of production on payroll, benefits, reporting, reconciliation or other sensitive operational functions. Production issues can also lead to payment problems, downstream reporting errors, audit concerns and operational disruption. Production readiness should be treated as a business-control question, not just as a software-quality question.
What Production Validation Means
Figure 1: Enterprise Release Workflow Incorporating Production Validation
As illustrated in Figure 1, production validation is the operational discipline that sits between ordinary release preparation and moving changes into the live environment․ It exists to ensure that key records‚ release outputs and downstream expectations have been appropriately reviewed before changes are moved into the live environment․
In contrast to pass/fail testing validation‚ production validation includes checks to determine whether the data is complete‚ exceptions are handled‚ differences are worked out and the release criteria are acceptable for production․ Production validation usually requires multiple views of validation results‚ reconciliation sign-offs between files‚ issue tracking results‚ and proof of approval, testing and readiness for operations․
Why Testing Alone Isn’t Enough
Testing is important‚ but it does not answer every question about whether a given code can be released to production․ The code may work in a test environment and still have problems in production․ This can be due to timing dependencies‚ data-state differences‚ downstream dependencies and business controls in the production environment‚ which are not necessarily covered in standard testing cycles․
Therefore‚ with a test-only approach, bugs can be discovered too late‚ making them difficult to fix once they have reached production in a running application․ Production validation addresses this concern by treating release readiness as a formal gate rather than merely an assumption, as summarized in Table 1․
Table 1: Comparison Between Traditional Testing and Production Validation
Aspect
Traditional Testing
Production Validation
Primary Objective
Verify software functionality
Verify operational and business readiness
Environment
Test/UAT environment
Production or production-like environment
Focus
Code correctness and defect detection
Data integrity, release readiness and operational governance
Validation Scope
Functional and non-functional requirements
Business rules, configuration, approvals, reconciliation and exception handling
Outcome
Software passes testing
Release is approved for safe deployment
A Practical Model for Production Validation
A useful production-validation model describes a set of interrelated control practices that build confidence in an upcoming release before rollout (Figure 2)․
Figure 2: Core Components of the Production Validation Process
1. Structured Pre-Production Review
Some or all records and expected outputs may be checked against business rules and operational expectations to determine whether key data changes are complete‚ expected outputs are present and the release appears safe from a business-risk standpoint before the release is approved to proceed to the next stage․
The purpose of this is not only to check technical correctness‚ but also to assess whether the release is sufficiently trusted for use in production․
2. Exception Review and Correction
A good validation solution should provide the ability to generate reports of discrepancies‚ review affected records and ensure that issues are addressed prior to moving the release to production․ For many organizations‚ this is done through exception summaries‚ discrepancy reports‚ reconciliation reports or other review-oriented artifacts․
This is worthwhile because it helps prevent teams from treating exceptions as background noise and reinforces that exception handling is part of the release governance process․
3. Workflow-Based Release Discipline
When production validation is included in the workflow‚ it helps ensure that releases are reliable because the status of issues‚ validations‚ dependencies and approvals is explicit․ This means that a release is ready to go‚ not just because the team says it is ready‚ but because it has reached a valid state․
Incorporating workflow-based governance allows for better traceability of validation activities and reduces the likelihood of skipping important validation activities to meet deadlines․
4. Documentation and Repeatability
Standardized procedures are used to verify releases rather than relying on memory․ Validation checklists and runbooks provide a disciplined approach to repeatable execution of software releases․
Aside from promoting consistency‚ this documentation also provides defensibility in high-risk environments that require teams to justify why they believe a release is safe for delivery beyond the review performed․
5. Manual Business-Level Validation
In critical scenarios‚ manual review still matters․ Some production decisions are subjective‚ requiring judgment above and beyond post-release checks․ Conducting review activities before and after a release‚ comparing expected and actual results and analyzing differences at the business level can help identify problems that a technical verification process might overlook․
Manual validation should not be seen as a weakness because it is often the final check to determine whether moving a release into production is truly safe․
What This Changes Operationally
The value of production validation doesn’t come from adding a single tool; rather, it adds review‚ correction‚ documentation‚ workflow discipline and operational evidence to the release-readiness process for the production system․
Organizations can benefit from this strategy in several ways:
Defective records are less likely to be produced․
Exceptions are identified earlier․
Release approvals become less difficult․
Teams have better traceability into what was reviewed and resolved․
Operational reliability improves for business-critical systems․
This transition is more than a semantic one․ Over time‚ organizations can mature from passive release confidence to production assurance․
Why This Matters in Regulated Environments
For regulated or high-accountability environments‚ a faster release is not enough; demonstrating control is also necessary․ When sensitive records‚ reporting requirements or downstream financial results are impacted by a production change, teams must be able to describe how the change was reviewed‚ what risks were identified and why it was approved․
That is why production validation should be considered a separate operational discipline and not just an extension of testing․ It is not just a question of database controls․ The important question is whether an artifact locked for production has been sufficiently reviewed‚ corrected‚ documented and controlled before being used in production․
Conclusion
Enterprise release failures do not necessarily mean that nothing was tested‚ but rather that the definition of ‘production-ready’ was too narrow․ In data-heavy‚ high-risk systems‚ safe release management requires a wider operating model that includes review processes‚ exception handling‚ workflow governance‚ documentation and business validation of processes and workflows․
That is the missing layer in many release programs․ With a disciplined production-validation approach‚ organizations can reduce the risk of losing valuable operational data before defects lead to financial‚ reporting or regulatory issues․
Tricentis is providing early access to multiple artificial intelligence (AI) capabilities that it is gearing up to roll out later this year via a Tricentis Transform initiative, including an autonomous AI agent, dubbed Aida, that explores web and Windows desktop applications to surface defects, weaknesses and other potential gaps without requiring DevSecOps teams to create scripts.
Additionally, Tricentis is developing a Release Risk Intelligence capability that surfaces release-scoped coverage gaps, prioritizes risks by severity, and launches AI tasks to resolve issues that are informed by context provided by the automated Tricentis testing platform.
Finally, Tricentis is also readying AgentScore, a tool that enables organizations to evaluate AI agents by observing how agents behave in real-world workflows, recommending what should be measured, and generating composite quality scores that include review, block, or ship recommendations.
David Colwell, vice president of AI and machine learning for Tricentis, said the overall goal of the Tricentis Transform initiative is to ultimately make AI application testing a more integrated element of building and deploying any application rather than being an entirely separate function. The end result should be higher quality applications that are inherently more secure, he added.
The launch of the Tricentis Transform initiative comes on the heels of the company’s acquisition of Tabnine, which developed a knowledge graph that AI agents can invoke to discover the relationships between various application components. Armed with insights that are uniquely provided by a testing platform, AI agents are provided with the context needed to automate tasks much more reliably, noted Colwell.
It’s still early days so far as embedding AI agents into DevOps workflows is concerned, but as more code is generated using AI tools, there is a corresponding increase in the amount of pressure on existing pipelines. The first place that pressure is manifesting itself is in the need to review and test code at machine speed. In the absence of that capability, more AI-generated code is being deployed in production environments with predictable results. The number of incidents in production environments that have been traced back to AI code has already begun to exponentially increase, noted Colwell.
Exactly how long it might take to re-engineer DevOps workflows in the age of AI remains to be seen, but it’s apparent that testing will become more integral. The difference is that much of that testing is likely to be conducted by AI agents that are reviewing and analyzing code created by other AI agents. The challenge, in the meantime, is a coverage gap that is widening as the volume of code being generated overwhelms the ability of DevOps teams to test it.
Hopefully, there will come a day when the distinction between creating and testing code becomes so blurry as to be all but meaningless. That doesn’t mean the need for specialists to test applications will completely disappear, but it does mean that any issues that do require their expertise will be worth the time and effort for them, rather than an AI agent, to personally resolve.
Enterprise AI agents need more than stronger models. They need durable execution environments that can coordinate multi-step workflows, survive failures, pause for human review and resume reliably after disconnects or delays.
AI Agents Have Moved Beyond Chat Demos
AI agents work beautifully in demos. A user asks a question, a large language model generates a response and everyone sees possibility. Production systems are different.
Consider what these systems are now asked to do. An agent assessing a change request may pull deployment history, evaluate blast radius, check freeze-window policy, wait for a release manager’s sign-off and then schedule the rollout. An agent adjudicating an insurance claim may extract fields from submitted documents, cross-check them against prior claims, apply underwriting rules and route anything unusual to a human adjuster. An agent triaging a security alert may enrich indicators, correlate against past incidents, assess asset criticality and hold containment until an analyst approves it.
Those three workflows have almost nothing in common at the domain level. They share a shape: Multiple steps, several systems, independent failure modes and at least one point where a person decides. They take minutes or hours, not milliseconds.
The challenge is no longer only intelligence; it is execution. Many enterprise AI conversations focus on model selection, prompt engineering, retrieval-augmented generation and tool calling. Those are important, but they do not answer what happens after the agent begins executing long-running work across multiple systems.
The Problem: Most Agents Are Still Designed Like Request-Response Applications
Traditional AI applications assume a simple request-response model: User input goes in; a model response comes out. That model works well for Q&A, summarization, content generation and search-like experiences.
Enterprise workflows are different. A procurement review agent might parse a contract, compare its terms against a standard template, check vendor risk ratings, invoke a sanctions screening service and produce a recommendation. These steps may execute independently, fail independently and complete at different times.
Once an agent crosses the boundary from answering a question to executing a process, it starts to look less like a chatbot and more like a distributed system. It needs state, retries, coordination, observability and recovery.
Why Stateless APIs Break Down
Teams often start by implementing an agent as a synchronous API. That approach works until the first real workflow appears. What happens if the HTTP request times out? What if the user closes the browser? What if an external system is unavailable? What if a human approval arrives six hours later?
A stateless API can initiate work, but it is a poor place to manage long-running state. Developers quickly end up building custom queues, status tables, retry logic, compensation logic and ad hoc workflow tracking. The hidden cost is not the first prototype; it is operating the system after it begins handling real workloads.
The missing layer is a durable runtime: A workflow engine that can preserve progress, coordinate parallel work, wait for external events and resume execution reliably.
Figure 1: The Same Multi-Step Workflow Under Two Runtimes
A stateless service holds progress in process memory, so a host failure discards completed work and the retry begins again from the first step. A durable runtime checkpoints each completed activity, so a replacement worker replays the history and continues from where execution stopped.
The Key Design Shift: the Workflow is the Application
The most important design shift is this: The model is not the application. The workflow is the application. The model is one activity inside a larger execution graph.
In production-grade agentic systems, the orchestrator coordinates work while specialized agents perform specific tasks. The specialization is domain-specific, but the division of labor recurs: One agent gathers and enriches raw signal, another retrieves reference material, another looks for precedent among prior cases and another evaluates policy or risk conditions.
This design makes the system easier to reason about. Each agent has a focused responsibility, and the orchestration layer owns execution flow, state, retries, progress and human interaction.
Using Durable Orchestration as the Agent Runtime
A practical architecture places a durable orchestrator between the calling application and the AI execution layer. The caller starts the workflow and immediately receives an instance identifier. The orchestrator then coordinates specialized agents and records progress as the workflow advances.
Azure Durable Functions is a strong fit for this pattern because it supports stateful workflows, activity functions, external events, checkpointing and long-running orchestration. Azure AI Foundry can provide the model and agent execution layer, while Durable Functions handles the operational execution semantics around the agent.
The result is a cleaner separation: AI services reason; activity functions perform work; the durable orchestrator governs the process.
Figure 2: The Orchestrator Between the Calling Application and the Reasoning Layer
It owns sequencing, retries, timers and external events. Specialized agents run on the model layer with narrowly scoped access and every completed activity is checkpointed so the workflow can be rebuilt after a failure or a process restart.
Fan-Out/Fan-In Maps Naturally to Multi-Agent Systems
These investigations are rarely one sequential task. Many subtasks can run independently. Enrichment, reference retrieval, precedent search and policy evaluation usually have no dependency on one another, so they can execute in parallel. This is where fan-out/fan-in becomes a natural orchestration pattern.
The orchestrator fans out work to specialized agents, waits for them to complete, and then fans in the results to generate a synthesized recommendation. This pattern improves latency while keeping the workflow easier to understand than a large monolithic agent prompt.
The fan-in step is also where engineering judgment matters. The system should handle partial results, conflicting findings and low-confidence recommendations rather than assuming every agent will succeed perfectly every time.
Example Orchestration Sketch: The sketch below triages a security alert; the domain is incidental. Rename the activities and the same orchestration serves claims adjudication or change-risk review.
Three details in that sketch are worth calling out. The external event is raced against a durable timer, so an approval that never arrives escalates instead of leaving the instance parked indefinitely. The timer is then cancelled on the success path, because a durable timer that is neither cancelled nor allowed to expire keeps the instance in the Running state long after the orchestrator function has returned. Since Task.WhenAll surfaces the first exception it encounters, genuine partial-success handling means having each activity return a typed failure result rather than throwing it once its retries are exhausted.
Human-in-the-Loop is Not an Edge Case
In regulated and high-impact workflows, human review is part of the process by design. A payment exception above a threshold, a production change during a freeze window, a claim falling outside underwriting rules: None of these should be finalized automatically when confidence is low or the consequences of being wrong are large. The important thing is to make human review part of the workflow rather than a side channel.
A durable orchestration can pause while waiting for a review event, then resume when the approver submits a decision. The system does not need to keep an HTTP request open or hold compute resources while waiting. The workflow state remains available, and the final recommendation can include the reviewer’s context.
This capability is especially important because the slowest step in a production workflow is often not the model call. It is the human decision, the external dependency or the operational handoff.
Figure 3: One Instance Over Time
Parallel agents make wall-clock cost the slowest agent rather than the sum of all of them; a failed agent degrades the result instead of failing the run, and the review window consumes no compute because the orchestration is parked rather than blocked.
Operational Considerations Matter as Much as Prompts
A durable runtime does not remove the need for engineering discipline. It makes that discipline easier to apply. Production-grade agents still need observability, correlation identifiers, retry policies, cost controls, security boundaries and careful versioning.
Workflow telemetry should answer questions such as: Which stage is running? Which activity failed? How many retries occurred? How long did human review take? What evidence supported the final recommendation? These are operational questions, not prompt engineering questions.
Retries should be designed around external dependencies such as AI model calls, search systems, databases and APIs. At the same time, not every failure should fail the entire workflow. Multi-agent systems should be designed for partial success where appropriate. If the precedent agent fails but enrichment and retrieval succeed, the system may still produce a useful recommendation with clear caveats.
Three constraints tend to surface only once a workflow reaches production. Orchestrator code has to stay deterministic, because recovery works by replaying it: Wall-clock reads, random values, fresh identifiers and direct I/O belong in activities, not in the orchestrator. Every wait needs a deadline, else an approval that never arrives becomes an instance nobody ever looks at again. Versioning deserves a decision before the first production deploy because long-running instances guarantee that new orchestrator code will ship while old instances are still in flight.
Security and Governance Cannot Be Bolted on Later
AI agents often sit at the crossroads of sensitive enterprise data, operational tooling and user-facing experiences. That makes security and governance foundational design concerns.
Each specialized agent should receive only the access necessary for its responsibility. A retrieval agent may need the document corpus and nothing else. An enrichment agent may need read access to telemetry. The agent that composes the final decision may need only summarized evidence, never the raw sources behind it. Avoid creating one over-permissioned super-agent that can reach everything.
Prompts and outputs should also be auditable. Store workflow version, prompt version, model deployment, agent version, evidence references and correlation identifiers. As agents become part of operational decision-making, teams need to explain not only what the system recommended but why it recommended it.
Figure 4: Scoping Access per Agent Contains the Blast Radius
A single agent holding every credential turns one poisoned input into estate-wide exposure, while narrowly scoped agents limit any single compromise to one agent’s data, with the synthesis step working from summarized evidence.
What This Means for DevOps and Platform Engineering Teams
The future of enterprise AI is not just better prompts. It is reliable execution. As agents become responsible for operational workflows, DevOps and platform engineering teams will need to provide runtime capabilities similar to those used in distributed systems: Orchestration, observability, resiliency, governance and deployment discipline.
This resembles the evolution of microservices. Early conversations focused on APIs. Later, the industry learned that production systems also require service discovery, telemetry, deployment strategies, circuit breakers and operational practices. AI agents are entering a similar phase.
Organizations that treat agents as production workflows rather than chat interfaces will be better positioned to build systems that users trust.
Conclusion
Most enterprises already have access to powerful foundation models. The harder challenge is building systems that can execute reliably when work spans minutes, hours, tools, services and human decisions.
Long-running agents of any kind need a durable execution layer. They need to coordinate multiple specialized agents, survive transient failures, pause for human review, provide progress visibility and generate auditable outcomes.
Azure Durable Functions and Azure AI Foundry offer one practical way to approach this architecture: Durable Functions provides orchestration and stateful execution, while Azure AI Foundry provides the intelligence layer. The broader lesson applies beyond any specific platform: Production AI agents need durable runtimes. Intelligence is only half of the system. Execution is the other half.