Category: Features

  • IBM: DevOps, AI to Drive Digital Business Transformation

    IBM: DevOps, AI to Drive Digital Business Transformation

    Conventional wisdom holds that one of the biggest challenges organizations face today is a chronic shortage of application developers. But as artificial intelligence (AI) advances, the process of writing code will become more automated. But rather than there being not enough developers to write all the code necessary, the shortage will be in software engineers who can develop innovative systems.

    Bob Lord, chief digital officer for the Digital Business Group at IBM, says a glimpse of the future of application development is already being provided today. Instead of writing low-level code, most developers today simply combine modules to create new applications. Anytime new functionality is required, another module gets dropped into the application. The number of developers writing the low-level code needed to create those reusable modules is relatively few, says Lord.

    Over time, however, AI models will learn how to write that code. People will add value by providing the engineering expertise needed to combine modules to create an innovative application, Lord says. Naturally, most of the processes employed to deploy that software also will be automated. But IT operations teams will be needed to continuously train the AI systems being used to deploy that software. This is in much the same way that we need human pilots to fly a plane whenever something new or different occurs, despite the existence of autopilot technology.

    In general, Lord says, IT organizations would be well-advised to focus on three things:

    • They need to decide what architecture strategy is going to be employed to accelerate DevOps integration.
    • They need to develop a data strategy that drives digital business transformation.
    • They need to layer a cognitive computing strategy that employs advanced algorithms to maximize the business value of the data they’ve accumulated.

    While some organizations approach these issues in isolation, Lord says the reality is they’re all closely connected. Organizations are investing in DevOps not just to reduce costs—DevOps is about attaining a level of IT agility capable of driving digital business transformations. In fact, Lord believes the way IT organizations are measured will change: Rather than being rated on traditional IT metrics, they will be measured on how effective they were in attaining business goals—especially when to comes to velocity at which applications are rolled out and updated.

    In the meantime, Lord says, developers are starting to exercise more influence over the technologies organizations are employing to achieve those goals. Because of that issue, IBM is making an effort to get closer to the developer community. But as application development advances, many of those developers will be software engineers rather than people who write code, while IT operations teams will become teachers who train intelligent systems how to respond to the needs of deployed code.

    — Mike Vizard

  • Chef Applies IT Automation to Meet Compliance Mandates

    Chef Applies IT Automation to Meet Compliance Mandates

    Much of the productivity waste associated with compliance requirements stems from the fact that most developers and IT operations teams aren’t aware how an application might be non-compliant until it’s too late. Aiming to eliminate that fundamentally inefficient approach to meeting compliance mandates, Chef this week tightened the integration between its Automate continuous automation platform and InSpec, an open-source project lead by Chef for specifying compliance and security policies.

    At the same time, Chef enhanced support for Docker within InSpec and released InSpec-AWS, InSpec-Azure and InSpec-vSphere as incubation projects that IT operations teams can employ to test and audit for compliance. Chef also pledged to extend InSpec beyond operating systems to include support for middleware to address compliance issues across an entire platform. The announcements were made at the ChefConf 2017 conference.

    Chef CEO says Barry Crist says that in much the same way Chef automation software turns infrastructure into code, InSpec turns compliance into code. Tighter integration between the two platforms should enable IT operations teams to automate compliance testing before code gets deployed in a production environment. In effect, Crist says, compliance becomes just another continuous process automated by Chef. This approach not only leads to faster application deployments, it also reduces the amount of time auditors must spend checking on where production applications comply with a particular mandate, as all the documentation has already been generated.

    Compliance mandates are, in many ways, the enemy of innovation. In fact, it often takes longer these days to navigate compliance issues than it does to write a piece of code. Rewriting code to comply with multiple compliance requirements over several different manual tests is a waste of time and money. InSpec makes it possible to make compliance testing a part of an integrated DevOps process in much the same way security testing is fueling DevSecOps.

    As the number of platforms that IT operations teams now need to support has expanded, the compliance testing process has become even more complicated. Crist notes that for DevOps to be truly effective, it needs to encompass not just the deployment of code but also making it possible to make compliance and security testing an integrated component of the application deployment process. Of course, as an open-source project there’s no reason developers can’t incorporate InSpec into any continuous integration/continuous deployment (CI/CD) framework they choose. Chef is just moving to make InSpec a more natural extension of its IT automation framework.

    There’s a lot of commonality in the controls implemented across various compliance specifications. That creates opportunity to automate controls to reduce the need to rework an application, either before it gets deployed or, worse, after it has been deployed into production. Longer-term, the level of commonality across compliance controls also creates an opportunity to leverage machine-learning algorithms to automate implementing those controls.

    Of course, there will also be controls that will be unique to one compliance standard or another. But the days when IT organizations need to manually address those compliance controls one application at a time are coming to an end.

    — Mike Vizard

  • The Time Is Now for an IT Operations Revolution

    The Time Is Now for an IT Operations Revolution

    There’s a level of frustration starting to build inside IT operations teams that’s about to boil over. Lucas Carlson, vice president of strategy for Automic, a unit of CA Technologies that provides an IT automation platform, says developers are bullying IT operations teams by programmatically invoking application programming interfaces (APIs) exposed by public cloud service providers. As the number of application workloads running in those clouds increases, IT operations professionals are losing control.

    To ensure their continued relevance, IT operations teams need to leverage automation to inject levels of agility into local data center environments, he says. That would make it much less likely developers would feel the need to programmatically invoke IT infrastructure resources.

    Carlson says achieving that level of agility will require IT operations teams to rely more on machine- and deep-learning algorithms to automate low-level tasks. Instead of thinking in terms of managing silos of compute, storage and networking resources, Carlson contends IT operations professionals need to reinvent themselves.

    The artificial intelligence (AI) models based on advanced algorithms must be trained continuously. IT operation professionals could become the trainers of those AI models. In fact, Carlson says IT operations teams are approaching a critical moment in history: They can either wait for AI models to eventually replace them or they can leverage them to take back control of IT infrastructure.

    However, developers tend to make decisions based on what they prefer versus what’s best for the organization. Before too long, multiple duplicate operations management frameworks are in place. Rather than incur all those management headaches and associated technical debt, Carlson says organizations need a single framework that can more adroitly accommodate the multiple roles within the DevOps team. It’s already long past the time when IT teams should have modernized their operations, he says.

    The relationship between developers and IT operations teams has always been contentious. The more belligerent members of the developer community are even making a case for “NoOps.” In that context, all the IT dollars spent on operations are moved into developing applications because the management of IT infrastructure is completely automated. Given the amount of legacy infrastructure that isn’t likely changing anytime soon, achieving that level of automation inside the enterprise won’t happen for a while. But there’s no doubt that IT operations needs to get more agile. Because of that issue, investment in software-defined data center (SDDC) technologies is growing rapidly.

    Instead of resisting that trend, Carlson says teams need to demand that internal IT operations be brought into the 21st century. It’s true that SDDCs infused with AI models will automate most of the lower-level tasks associated with DevOps. But those members of that IT operations teams who become the masters of building and training those AI models will be among the most highly sought-after individuals in IT.

    — Mike Vizard

  • Automation: A Few Decades of Pain? Or, What Does Jack Ma Know That I Don’t?

    Automation: A Few Decades of Pain? Or, What Does Jack Ma Know That I Don’t?

    Recently I came across three articles that gave me pause. Each article was a bit disconcerting on its own merit, but when I considered them together, the result caused more than a momentary worry. One article was report in Bloomberg Technology quoting Jack Ma, head of Alibaba, the second richest man in China and a major player in the e-commerce space. He said:

    “In the next 30 years, the world will see much more pain than happiness.”

    Ma was referring the impending effects of automation and e-commerce on the economies and societies of the world .

    The second was from a piece written by Martin Neil Baily and published by the Brookings Institution in 2015. The article is titled, “U.S. manufacturing may depend on automation to survive and prosper.” Here is the quote, referring to U.S. manufacturing:

    “The manufacturing sector is still very much alive and reports of its demise are not just premature but wrong. … The sector will be revived not by blocking new technologies with restrictive labor practices or over-regulation but by installing them—even if that means putting robots in place instead of workers.”

    The last piece is by Joe McKendrick over at ZDNet. The subtitle to his article titled, “Containers, DevOps, IT automation seen as antidotes to complexity,” says it all:

    “Seven in 10 IT professionals agree: if we don’t automate, we die.”

    When I put the ideas in the articles together, I get a thought that goes like this: In the coming decades more automation will be put in place, a good many workers are going to be displaced by robots, and it’s going to be a world of pain.

    Do these notions seem far-fetched? Maybe not. The need is there, the will is there and the money has been allocated. The result is going to be great for the bottom line. For humans and workers, not so much.

    But, a thought is not reality. There are many people out there saying that automation is a blessing and in the short and long term, most of us will do well. Automation will create more jobs than it destroys.

    Predicating the Future is a Risky Business

    Predicating the future is a risky business. Could anybody have predicted that the underlying technology that powered Netscape back in the 1990s would produce today’s internet of things? Who would have thought that the first cell phones, selling for around $4,000 in 1984, would lead to mobile devices becoming the dominant computing device today? Not many. To quote Yogi Berra:

    “It’s tough to make predictions, especially about the future.”

    Yet, the three predictions I describe above bothered me. I wondered, Do these guys know something I don’t?

    So I decided to do take a look at some data.

    What the Data Says

    One of the metrics that I have found particularly interesting when considering automation is the relationship between the number of employees a company has and its revenue. This number is sometimes referred to as Revenue Per Employee (RPE). The simple assumption is that companies that have high revenue per employee are more productive because that productivity is realized via tools and machines; in other words, automation.

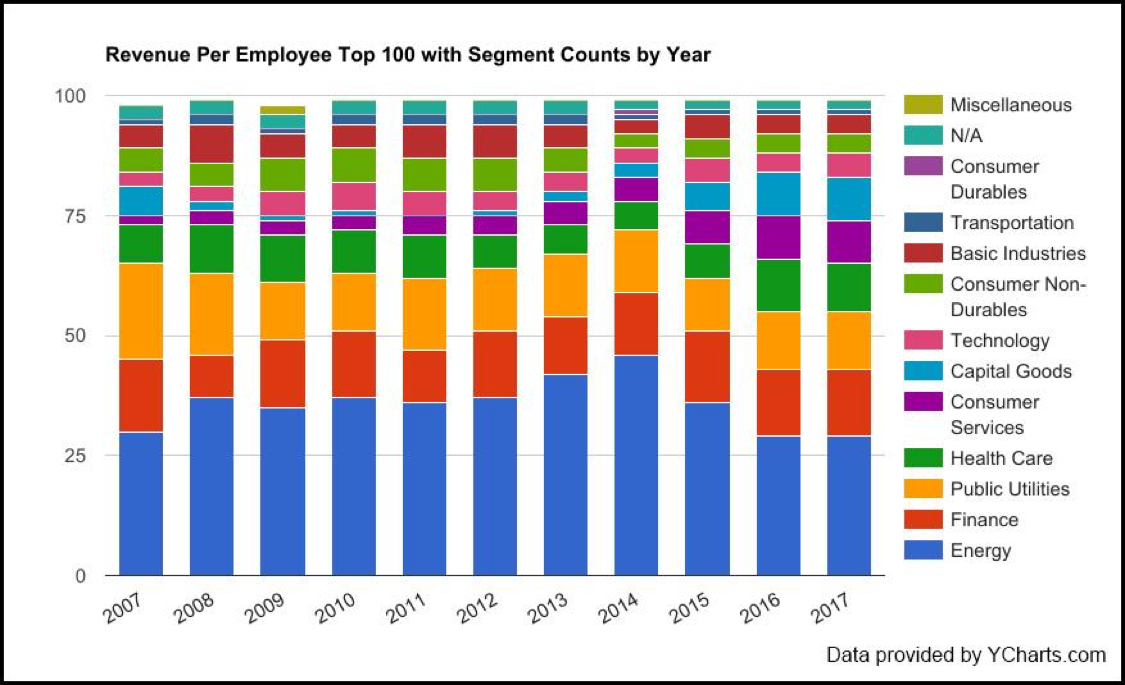
    Using data in both the NYSE and NASDAQ stock exchanges, I determined the Top 100 companies with the highest RPE in a given year. I excluded from consideration companies that had fewer than 1,000 employees. (A publicly listed trading company that deals in precious metals, with 30 employees generating revenue of $120 million will create a distortion that is atypical to the norm.) I looked at each year between 2007 and 2017. The result is shown in Figure 1, below.

    Figure 1: Top 100 Companies by Revenue Per Employee excluding companies with less than 1.000 employers

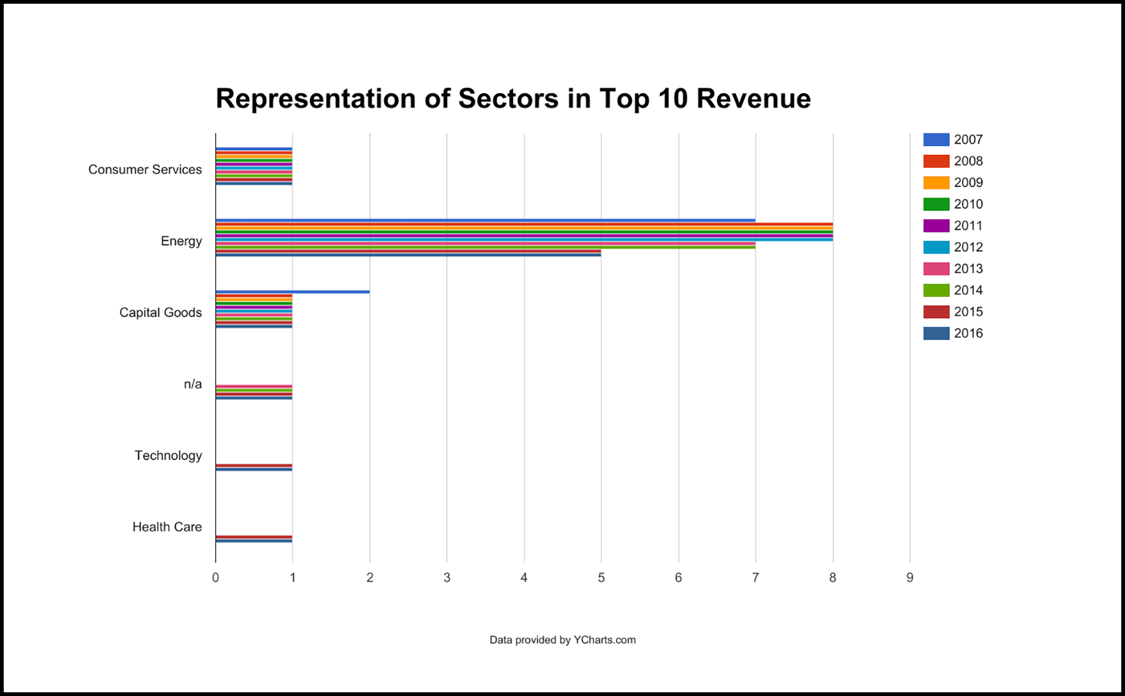
    Given the large representation of the Energy sector in RPE, I decided to look at the Top 10 companies in terms of revenue from 2007 to 2016 to see if there was any correlation. I grouped the Top 10 revenue earners into sectors. The result is shown below in Figure 2:

    Figure 2: Grouping of Top 10 Revenue Earners according to sector 2007 – 2016

    Notice that companies in the Energy sector have the largest representation in the Top 10 revenue earners throughout the years. This pattern is somewhat similar to that of representation of Energy shown Figure 1, in that Energy has the largest representation. There is a correlation.

    An Assumption Proved False

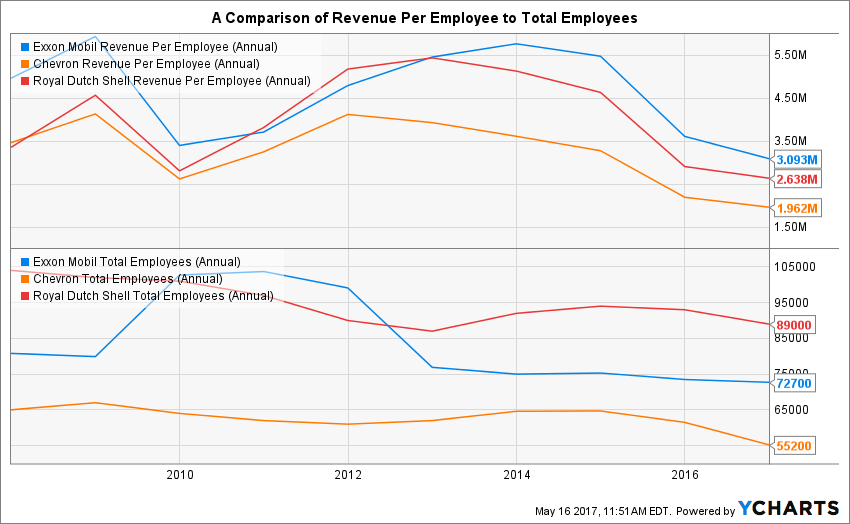
    My initial thinking was that there is something going on in the Energy sector that might be relevant to my simple assumption about RPE: The greater the RPE, the more automation in force. I looked that the individual RPE performance of Royal Dutch Shell (RDS.A), ExxonMobil (XOM) and Chevron (CHV), three companies in the Energy sector that always appeared in the Top 10 Revenue Earners from 2007-2017. I compared each company RPE to its Total Employees. Figure 3 below shows my findings:

    Figure 3: Revenue Per Employee and Total Employees for  ExxonMobil (XOM), Royal Dutch Shell (RDS.A) and Chevron (CHV)

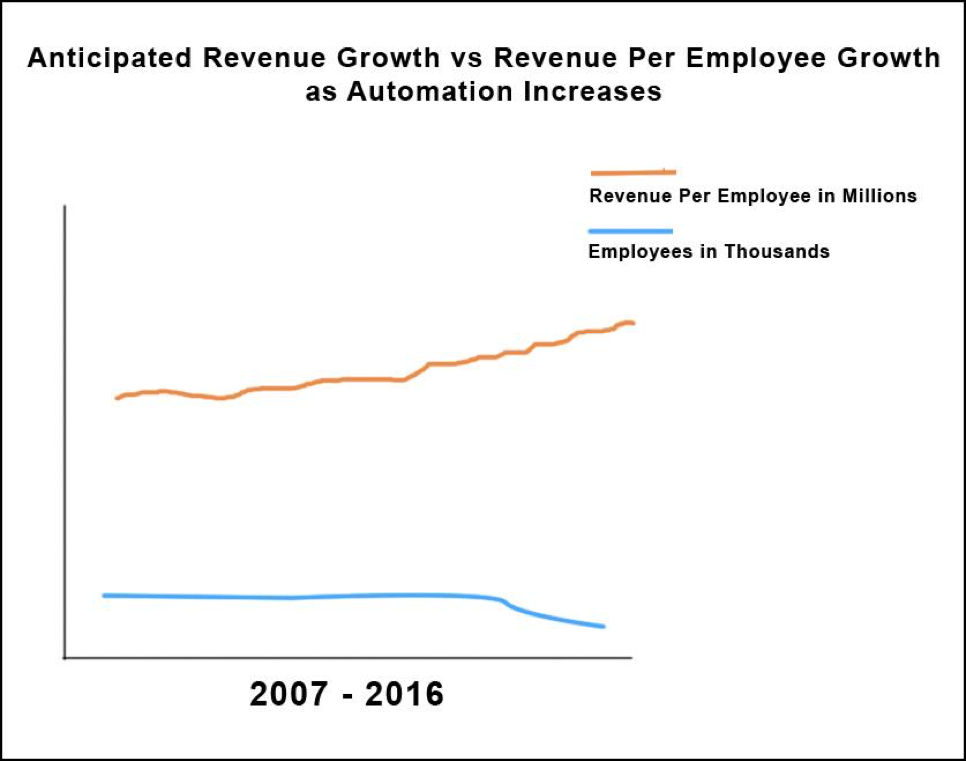
    As mentioned above, my initial assumption is that as automation increases, RPE should increase, while employee count remains steady or decreases. Figure 4 below illustrates the assumption.

    Figure 4: One might assume that as automation becomes more prevalent, fewer employees should produce more revenue per employee

    Yet, as you can see in Figure 3, the numbers did not confirm my assumption. We see a significant dip in RPE from all three companies around 2010, while ExxonMobil acquired more than 20,000 employees. Also, we see that Royal Dutch Shell and Chevron have a decline in the number of employees over the number of years. If the efficiency that automation might be attributed to RPE were in force, revenue numbers would at the least mirror employee numbers, or hopefully increase due to more productivity achieved through automation. But revenue does not continue to map to increased revenue versus the number of employees. Revenue is all over the place.

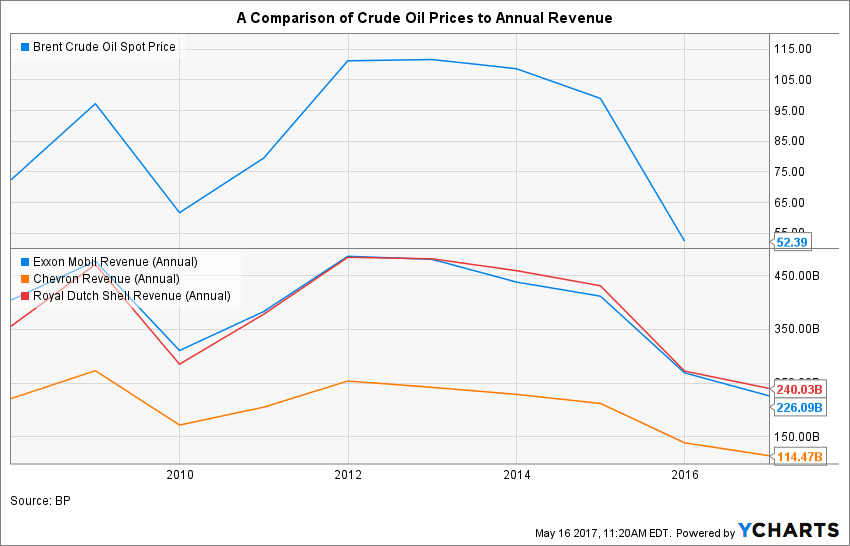
    I was stumped until I considered the impact of price of oil. When I compare revenue to the historical price of oil according to Brent Crude Spot Price to oil company revenue during the years in question, a similarity occurs, as shown in Figure 5, below.

    Figure 5: Oil Company Revenue compared to Price of Oil, 2007-2015

    The shape of the lines in the lower chart in Figure 5, Revenue in Billions and the shape of the line for oil price, in the top chart look similar.

    A reasonable inference can be made that the while oil companies enjoy a sizeable return per employee due to capital investments in tools, technology and automation (ExxonMobil returned more than $3 million per employee in 2016, for example), market price conditions have a more significant effect on revenue.

    So it seems that in terms of the Energy sector, for this admittedly small sample size, automation does allow for significant revenue, but does not increase revenue by way of increased efficiency in terms of operational production. I went back to being stumped. When Jack Ma was talking about decades of pain, was he talking about continuing slump in revenue from the Energy sector? Or was he talking about something else? I decided to look at some data about the world’s largest commercial employer, Wal-Mart.

    All Roads Lead to Wal-Mart

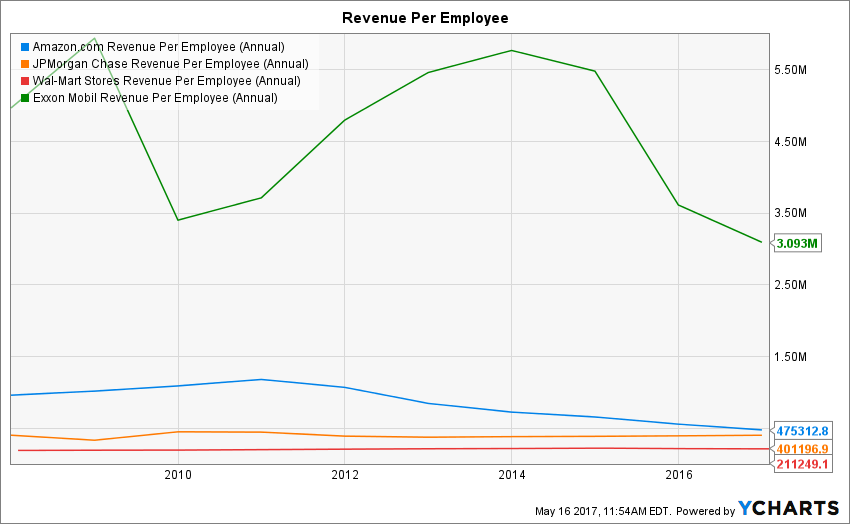
    Wal-Mart employs more than 2 million people and is the leading revenue earner for the years 2014-2017. Yet, when we look at its RPE compared to other companies, Wal-Mart is at the bottom of the stack, as shown in Figure 6, below. As mentioned above, in 2016 Exxon earned more than $3 million per employee. Amazon had an RPE of ~$475,000. JPMorgan Chase came in at ~$401,000. Wal-Mart? $211,000. To put it in perspective, ExxonMobil did more than ten times as much in terms of RPE.

    Figure 6: Wal-Mart’s Revenue Per Employee of $211,000 in 201y puts it well below others

    I could not help but wonder, why does ExxonMobil have a higher RPE than Wal-Mart? Or, for that matter, why so to for JPMorgan Chase and Amazon? I have a theory to propose to answer the question.

    Energy, Finance and Amazon have historically been heavily automated industries. The size of a land-based crew drilling oil is between four to six employees per eight-hour shift. These people are not out there with picks and shovels. They are operating big machines with each machine having some amount of automation built in.

    Once the well is drilled, there is some maintenance labor, but revenue is derived from what comes out of the ground. A lot of machinery is used to get the oil out of the ground, processed and delivered for end use. Hence, a large automation factor. Human labor is secondary.

    Same with Finance. Computers have been at the heart of Finance industry—banking, investments and insurance—since the first mainframes were put into action. Is the revenue of some companies in the Finance sector subject to the whims of the market? Most likely, yes, particularly as one considers the events of 2008. But again, one trader with a single Bloomberg terminal can do a lot of work.

    And Amazon? The company has been the poster child for automation since Jeff Bezos sold the first book online.

    Still, as noteworthy as the facts were, there seemed to be no historical precedent to justify Jack Ma’s prediction doom. But, the dreadfully low RPE of Amazon might give us a clue. So went back to the drawing board and spent another afternoon making charts using data from NYSE and NASDAQ.I came up with the two charts you see in Figure 7 below. Then, the plausible became possible.

    The Plausible Becomes Possible

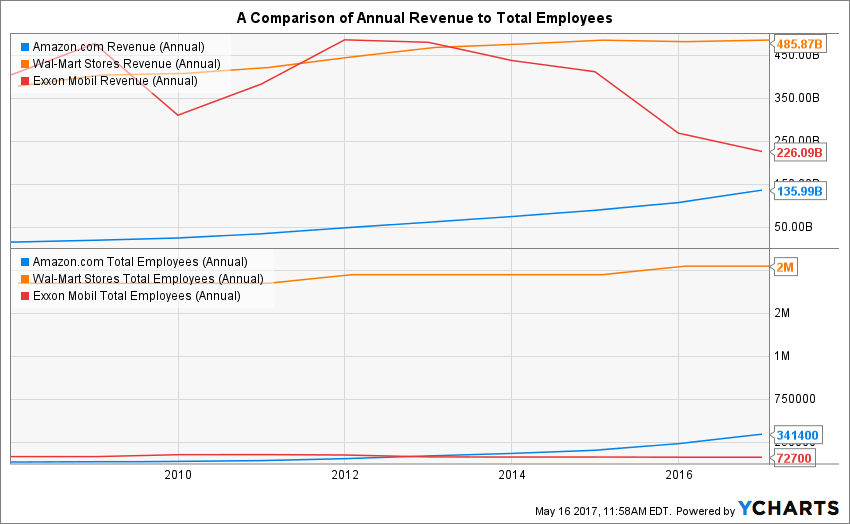
    The chart on on the top of Figure 7 below shows the annual revenue for Amazon, ExxonMobil and Wal-Mart. The chart on the bottom of the illustration shows the total employees for each company. The time span of each chart is 10 years. Wal-Mart shows a steady rise in revenue until 2016 when things start to go flat. ExxonMobile starts to lose revenue in 2012, while its total employee count remains relatively even. Amazon, on the other hand, shows a steady rise in revenue, as well as a rise in employee count. Both Amazon’s total employee count and revenue grows at a steeper growth trajectory than Wal-Mart.

    Figure 7: Total Employees and Revenue: As Wal-Mart hires more employees revenue begin to flatten; Amazon revenue increases

    Is there something going on?

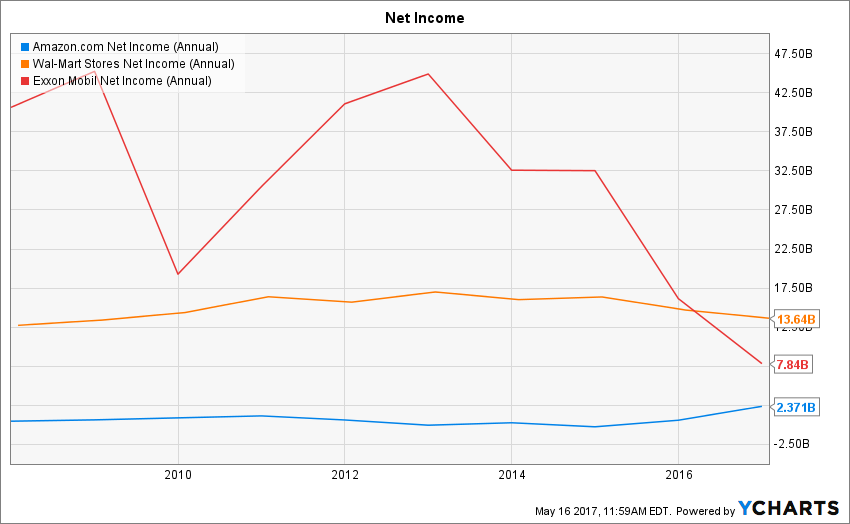
    Well, when we look at net income, there very well might be. Figure 8, below shows the net income of ExxonMobil, Wal-Mart and Amazon. This is where the rubber hits the road. Net income is the money that’s left over after all expenses and taxes have been paid. It all comes out in the wash when you look at net income. You can be a company doing $1 billion in revenue, but if your expenses are $999 million, your company is doing no better than one doing $10 million in revenue with $9 million in expenses. In terms of Amazon, Wal-Mart and ExxonMobil, as we move to the later years, 2016-2017, the numbers come into the same ballpark. And, in that ballpark Wal-Mart is showing some decline, ExxonMobil is showing a continuing big decline. Amazon is on the rise.

    Figure 8: Net Income: Wal-Mart and ExxonMobil show declining net income while Amazon is on on the rise

    So now is a good time to go back and review the assertions made at the beginning of the piece:

    • Jack Ma: “In the next 30 years, the world will see much more pain than happiness.”
    • Brookings Institution: “even if that means putting robots in place instead of workers.”
    • Joe McKendrick: “Seven in 10 IT professionals agree: if we don’t automate, we die.”

    Given that data presented, we see that industries that have a good deal of automation, Energy and Finance for example, have a high degree of employee efficiency as reflected in RPE. Also, we see that Energy is subject to the whims of market pricing. And lastly, we can see the country’s largest employer, Walmart, has poor RPE numbers, while Amazon, in many ways analogous to Wal-Mart in that Amazon has a significant presence in the retail space, albeit the online retail space, has very good RPE and increasing net income.

    Will Amazon continue to hire? A reasonable assumption is yes. Will Exxon continue to hire? If you go back to Figure 7, you will see that ExxonMobil employee count has been declining since 2010. Couple this fact with a continuing decline in revenue, we’re not going to get fired if we say that ExxonMobil is probably not going to increase employee count unless some sort of miraculous business pivot happens. But what about Wal-Mart?

    Wal-Mart has 2 million employees, a dreadful RPE number and declining net income. What will happen should Wal-Mart’s CxOs decide to more fully embrace automation? After all, hiring more people does not seem to help. It hired more and revenue declined. It’s a pretty good bet that Wal-Mart will go more toward the full automation end of things. How else will the company survive? So let’s play out this scenario.

    A Closing Hypothetical Scenario

    Let’s close with a hypothetical scenario. Let’s say that somehow Wal-Mart magically figures out a way to increase its RPE from the current $241,000 to $475,000 within the next five years.  ($475,000 is the current RPE of Amazon.) And, let’s say that Wal-Mart’s revenues continue to stay level at the current $482 billion a year. Thus, to calculate the number of employees required to achieve the desired RPE, we use the formula:

    $475K (RPE) = $482 bln/Number of Employees

    When we do the math, the number of employees that Wal-Mart needs to achieve $482 billion in revenue with an RPE of $475,000 is 101,4736,842—about half the size of its current workforce. Think about this. The implications are dramatic.

    Most likely, Wal-Mart will continue to automate. It must to survive. The question becomes, given its current dismal RPE, does the company somehow double its revenue to maintain the size of its current workforce. Or does, it accept current revenue trends and let 1 million people go.

    It seems that Jack Ma is predicting the latter. This might very well be but one of many examples in decades of pain he predicts, an outcome that is the result analysis offered by the Brookings Institution and 7 out of 10 IT professionals. Or, who knows? Maybe the future is one in which the Wal-Marts of the world double revenue and manage to keep the human workforce intact.

    As we have learned on the terrain, it’s easy to predict the future when it involves describing the outcome of writing a check for $100 when you have only $10 in the checking account. Predicting the impact of automation on future human employment is a more complicated terrain to travel. But no matter what, there will be a future and most likely, it will be more automated. What will happen to the employees at Wal-Mart? I’ll let you be the judge.

    A Special Thanks to YCharts.com

    Please allow me to extend a special thanks for the folks at YCharts.com for providing access to the data and charting tools used in this article. They were extremely helpful throughout the development of the ideas expressed herein which, by the way, are my own. — Bob Reselman

    — Bob Reselman

  • DevOps Chat: Value Stream Mapping with CollabNet’s Eric Robertson

    DevOps Chat: Value Stream Mapping with CollabNet’s Eric Robertson

    This DevOps Chat features Eric Robertson, VP of product and engineering at CollabNet. We discuss value stream mapping, which comes from Lean methodology and has been around for a while. But do you actually know what value stream mapping is? How can it help your DevOps transformation? Eric does a good job of explaining.

    As usual, the streaming audio of our conversation is immediately below, followed by a transcript of our chat. Enjoy!

     Streaming Audio

    Transcript of our Chat

    Alan Shimel: Hey, everyone. This is Alan Shimel of devopsy.kinsta.cloud here for another DevOps Chat and our guest on this chat is Eric Robertson, VP of product management and engineering at CollabNet. Eric, welcome to DevOps Chat.

    Eric Robertson: Thank you. Thank you, Alan. Glad to be here.

    Shimel: Yeah. We’re glad to have you here, Eric. I don’t think we’ve had anyone from CollabNet, actually, on DevOps Chat before, though I think we’ve done some video interviews over at DevOps Enterprise Summit—maybe it was San Francisco in October and November—but we’re—so we’re glad to have you here. We’re eager to find out about what’s going on with CollabNet and about some of the stuff you’ve been doing. Eric, if you don’t mind, though, there might be some people out in our audience who are not familiar with CollabNet, so, if you can, just—doesn’t have to be long, but maybe a quick elevator pitch on who CollabNet is, what you guys do.

    Robertson: Sure. Sure. So CollabNet’s been around since, I think, 1999, and it was one of the foundational on the open source, with our Subversion version control software. We since then moved into the ALM, application lifecycle management, platform. It’s our product offering called “TeamForge,” where we started linking in that planning, development, and testing life cycle, with integration to tools. And now, with me, we actually extended that life cycle all the way down into the operations—thus, the concept DevOps. And now we are launching—have launched, actually, a series of products and partnerships around DevOps for our customers.

    Shimel: Fantastic. Fantastic. So, Eric, one of the things that, when we spoke off mic earlier, we spoke about value stream mapping, and I know that’s something kinda, if not near and dear to your heart, something that you’ve been involved in with CollabNet. Why don’t you give our audience—let’s start off with this. There may be people out here who, just as they didn’t know CollabNet, maybe they’re not familiar with the term “value stream mapping.”

    Robertson: Yeah. It’s very interesting. Value stream mapping is actually an older concept. It’s part of the Lean management framework. For example, many may have heard about Toyota. It was started there, as far as best practices around mapping material and information flow and how could we apply to, for example, the value chain, and pretty predominant in the manufacturing domain. And it’s kinda of interesting because I have a background in software engineering and I have degrees in computer science and engineering, but my first job was actually in architecture—not in software architecture, but actually designing building. CAD design.

    And it was interesting that, during that time, they started talking about design patterns and best practices, as far as architecting and putting together systems and designing. And I said, “Wow, this is very similar concept to what I learned back in college, when I was doing software engineering, software design.” And, very soon, that started translating into object-oriented and design patterns and things of that nature. So it’s interesting how patterns and techniques that were very popular and used in other domains, like manufacturing and architecture, now being applied to software. In other words, software is maturing, right? The software development process is maturing. It’s starting to utilize these type of practices.

    And the value stream map is just an example of that, right? It’s Lean management method for really analyzing that current state and designing a future state, based upon a series of events that take a product, a service, from its beginning through to its customer. Right? And, again, like I mentioned, Toyota—this is known as that material and information flow mapping, and it can be applied to any value chain, for example, right? And what is a value chain? It’s just a set of activities that take, for example—that delivers a valuable product or service to the market, right? So you got, in the manufacturing world, this was machines that did it; in the software world, it’s now tools that we use to deliver a product from a planning all the way to its operations stage.

    Shimel: Yep. Got it. So, Eric, this is something, obviously, that you have written and you’re talking a lot about it. Can you tell our audience, if they want—maybe if they wanted to find out a little more, where can they go? Before we dive in more than that, maybe where can they get more information on this?

    Robertson: Yes. Actually, they could come out to our website, collab.net, but, also, I recently published an article around how value stream mapping delivers a better DevOps tool chain, and we can post those links—I believe it was also on devopsy.kinsta.cloud and we have one that was delivered through TEDxBeacon, so there’s a series of outlets, and we’ll post those links there on where they can get more information about this.

    Shimel: Excellent. You know what? We’ll, for sure, do that. And then, Eric, you had also mentioned that you guys were doing some sort of roadshow or a little city tour, where you’ll be talking about this, as well as other areas of interest around DevOps and what CollabNet’s doing. What’s going on with that?

    Robertson: Yeah, so we’re actually having a series—we’re also doing it through webinars, but we’re also doing it through seminars, and we’re gonna be having these seminars throughout the different series. And, basically, what we’re doing there, what’s really critical there, is that we’re going to be not only talking about the value stream as far as more of the how this applies into the DevOps—in DevOps world, but also we’ll have customers there talking about how they are leveraging value stream mapping and how they’re mapping that to their tool chains and how they’re able to, from bare, start applying measurement, which, to them, is what they’re calling “the last mile” of DevOps, right? And it’s really—they’re gonna talk about how that provides a window to allow them to monitor, measure, improve their workflow processes, all around a series of KPIs, both velocity KPIs and also quality KPIs.

    Shimel: Mm-hmm. Excellent. So, again, I think, Eric, what we wanna do is post a—maybe if you have a schedule of cities that we can post with the notes from today’s show.

    Robertson: Yes.

    Shimel: I think that’s the way to do that. So—

    Robertson: Yeah.

    Shimel: —let’s return, though, for a moment, to value stream mapping and kinda dig in here a bit. One of the things—and, again, as we spoke about off mic, I’ve had some experience with value stream mapping—one of the things, though, in speaking to potential customers of value stream mapping, is it’s easy to say, “Oh, yeah, that sounds good.” Right? “Oh, that’s something we wanna do.” Okay, well, let’s schedule some time and I’m gonna need the right people at the table because, if you don’t have the right people there, it’s very hard, number one, to truly map out the value stream and, number two—

    Robertson: Exactly.

    Shimel: Right? And harder than that is let’s get some consensus on what we’re gonna do to make it happen.

    Robertson: Exactly.

    Shimel: You know, unfortunately, it can’t be some developer who raises his hand and says, “I really wanna make a digital transformation here and I need to convince my CIO. Can you come in and give me a value stream mapping kind of session or workshop or can we discuss it?” It’s not a one-man show.

    Robertson: Exactly. Exactly. And it is very interesting you said that because, because value stream looks at the lifecycle from planning to operations, there’re different stakeholders, right? And what’s happening in, especially in enterprise, is these stakeholders now—they have implemented the tools or they have guys that work for them or folks that work for them that implemented these tools, and they’re starting to ask questions or they already started asking questions around value. What I mean by that—you have the executive and he’ll say, “You know, my folks are telling me we did four deployments today.” Great. What does that really mean for the business?

    Shimel: Yeah.

    Robertson: Did we get little features out to the business, where they get utilized? Are they utilizing that? Did I actually place the right emphasis on those features? Right? The last release that I deployed on time, at least from a developer perspective, said I deployed this, I deployed it on time, but I’m having this increase of service desk tickets. What’s going on here? Why am I being called? Right?

    Shimel: Yeah.

    Robertson: And I _____ –

    Shimel: Oh, yeah. Exactly.

    Robertson: Right? [Chuckles] And it means that the IT office guys, right? They have their own set of—type of metrics that they’re looking at, right, and they wanna understand, right, “Is there anything impacting this release?” and without having to chase down and talk to every other person or look into every tool, to try to gather this information, right? And then you’ve got the engineers, like the QA engineers, and now compliance, security’s coming into play as well, right?

    Shimel: Absolutely.

    Robertson: So now folks wanna know, “Before I deploy, did all this pass through the quality gates? Was this sufficient?” Right? “What about security and compliance checks? Can I automate that feedback? Can I get that feedback to the appropriate stakeholders?” Right? So they’re already involved in asking these questions, but they really don’t have any direction there on how to get that information. And this is where—this is the impetus to say, “Well, you know what? Now’s the time to start looking at these tools, where you’re gathering this information, what’s generating this information flow, and how we bring this together.” Right? So it kinda starts to endow that value stream mapping conversation pretty well.

    Shimel: Yep. Excellent. Excellent point. Because, like DevOps itself, value stream mapping is a team sport, right? And—

    Robertson: Yep.

    Shimel: And it’s cultural and you need that group kind of involvement to make it happen. So, Eric, I’m sure you probably have a few war stories around this, though. Can you share with us sort of—you know what I always say? You learn more from your failures than you do from your successes.

    Robertson: Oh, my God.

    Shimel: Can you share with us maybe some value stream mapping engagements that didn’t work out and, of course, only if you’ve learned something from it, and what was the valuable lesson you learned?

    Robertson: Exactly. I mean, that’s—it’s very interesting that you said that because we had one customer—and I can even use it from my experience. I mean, I worked at a company and I used to dread Wednesday mornings because Wednesday mornings was—wasn’t really a scrum meeting, but it was more of a meeting as far as, “What is the latest status of this release that went out the previous day?” because we did weekly deployments,  weekly deployments. And everybody would dread that because it was really no place to go to get a full understanding that, “Well, if this release actually was deployed, what was in that release? If it wasn’t deployed, what was the bottleneck in there?” Right? “Was it that it failed a certain testing that it didn’t get through or did we discover that, in this environment, we did some monitoring and it didn’t pass this stage?” We had no idea. I mean, did the builds fail? Why? There was no insight to anywhere in that chain, right, from the planning, ’cause it’s all kinds of activities that are happening in the coding, the building, the testing, the deploying a release.

    And so, if you don’t really have an idea, as far as that information flow in a place where you can go and view that information and quickly understand “What are my exceptions, right, that I need to quickly identify and quickly address?” everybody’s chasing their tails there. And I’ve been on so many projects where that transpired and happened. And so this was really impetus of why we wanted to start having—start putting—leveraging this best practice, leveraging these practices, and then the tooling becomes more secondary type of aspect, rather than primary goal for driving processes.

    Shimel: Yeah, I agree with you. The tooling then winds up taking sort of a backseat to it. So let’s—well, we’re almost out of time, unfortunately, Eric. As I mentioned to you, the 15 minutes goes quick. We do the best we can.

    Robertson: No worries.

    Shimel: Let’s put—

    Robertson: I’m enjoying it.

    Shimel: —value stream mapping to the side a little bit. What else is—

    Robertson: Sure.

    Shimel: What else is going on with CollabNet?

    Robertson: So CollabNet is also partnered with a company called “Clarive”—it’s release automation software—and what we’re doing is is that we’re linking the release automation capabilities into our value stream management platform. Now what’s nice about this is that this allows us, very quickly, to start getting metrics across different type of applications and projects. And what I mean by that is, if you go into a larger enterprise, for example, they – of course, they’re experimenting with container type technology and Web-scale IT technologies, but they’ve also got some legacy applications, right? There may be Java, right? There’s—or on WebSphere or a traditional type of applications or architecture. They may even have mainframes or they may even have package apps, right?

    So one of the things that we’re doing is that we’re getting—we’re creating this abstract _____ layer around all those tools, so customers can have, enterprises can have a common user experience around release automation, whether or not—so, again, we’re abstracting the tools, so you’re focused on the process, and it doesn’t matter what tooling is utilized underneath. If it’s Webscale IT technologies, container-based technology, it does not matter. You can basically have a common release process across your different type of applications—package, legacy, and traditional—so we’re very excited about that.

    Shimel: Excellent. Sounds very cool. Eric, we’d love to talk more to you about this, but we kind of are over time. What I’d like to do, though, is maybe invite you back and we can talk. You know, we’ll leave value stream mapping for a moment and we’ll talk about other stuff next time, but I think we’d like to hear what’s going on in the world of DevOps, obviously, and with the players in it, and CollabNet has certainly been on the scene here and lots to tell. Until then, though, it looks like we’ll call it a wrap on this version of DevOps Chat and we’ll speak to you soon, and I—Eric, we’ve gotta get those links over. There’ll be in the notes for people who are listening in. But until then—

    Robertson: Great _____.

    Shimel: Eric Robertson, VP of product management and engineering at CollabNet, thanks for being our guest on this episode of DevOps Chats.

    Robertson: Thank you, Alan. Glad to be part of this.

    Shimel: My pleasure. This is Alan Shimel for devopsy.kinsta.cloud and DevOps Chat. Thanks for listening in today and we hope to see you soon on another DevOps Chat. Buh-bye.

    — Alan Shimel

  • VMware CEO Stakes Out DevOps Position

    VMware CEO Stakes Out DevOps Position

    At the Dell EMC World 2017 conference this week, VMware CEO Pat Gelsinger waded into an increasingly heated DevOps debate by suggesting that most developers are too “lazy” to be really interested in IT operations.

    At a time when factions within the DevOps community are making the case for developers to be responsible for DevOps on an end-to-end basis, Gelsinger contends that most developers want to get out of being involved with IT operations as quickly as possible so they can spend more time developing applications.

    The VMware approach to DevOps is closely aligned with Pivotal, a sister company operating under the Dell Technologies umbrella that curates an instance of the platform-as-a-service (PaaS) environment developed by the Cloud Foundry Foundation.

    Gelsinger notes that the two primary reasons developers have shifted workloads to public clouds is perceived costs and the fact that invoking infrastructure as a service (IaaS) via an application programming interface (API) is simpler. To combat both those issues, Dell EMC has been rolling out preintegrated converged and hyperconverged infrastructure that, for certain classes of workloads, is less expensive to own over multiple years. Those systems are optimized to run either VMware or Microsoft virtualization software within a software-defined data center that exposes IT infrastructure resources via APIs. In effect, Dell EMC is applying a cloud operating model on top of IT infrastructure deployed inside the data center to close what Gelsinger describes as an “easy gap” between public clouds and internal IT operations. As those systems are more widely deployed, Dell EMC and VMware jointly contend that IT organizations will be in a better position to inject more agility into their DevOps processes.

    Many IT operations professionals have a vested interest in the outcome of those efforts because developers have been doing an end run around internal IT operations teams by deploying applications directly on to a public cloud. The challenge VMware recognizes, says Gelsinger, is that the entire DevOps space currently is chaotic. Each IT organization not only has a different view concerning to what level of DevOps integration it wants to achieve, but none of them are at the same point in making that DevOps journey. In fact, there’s a raging debate over the merits of PaaS environments versus lighter-weight container-as-a-service (CaaS) environments.

    Dell EMC, in collaboration with VMware and Pivotal, has invested heavily in a Cloud Foundry platform that it makes available as a Pivotal Cloud Foundry (PCF) offering is increasingly automated, from an IT operations perspective. The latest version includes a rolling update capability that requires no human intervention. Pivotal claims one financial services customer has deployed 10,000 application containers on an instance of PCF that is managed by only four IT operations people. Couple that level of automation with the automation that VMware and Dell EMC are driving into the underlying IT infrastructure, and it shows that DevOps will be profoundly different than today. Less clear is who inside the IT organization will be exactly managing what.

    — Mike Vizard

  • Puppet Solidifies Enterprise Provider Status With Bevy Of Announcements

    Puppet Solidifies Enterprise Provider Status With Bevy Of Announcements

    Puppet has been maturing from a company with an enthusiastic base of users of an open source tool, to a leading provider of enterprise DevOps solutions for the last few years. Things really accelerated with the appointment last year of Sanjay Mirchandani, as CEO and the group of experienced, A+ players he brought to the executive team. Today Puppet took another step towards solidifying their position as a leading provider of enterprise DevOps solutions with a string of news announcements highlighting new products, accelerated growth and new/expanded presence.

    Lets start with what for many of you will be the most important. Puppet today announced “the general availability of Puppet Enterprise 2017.2, and upcoming availability of Puppet 5 Platform, the latest version of Open Source Puppet.” I had a chance to chat with Puppet CTO Deepak Giridharagopal, Chief Product Officer, Omri Gazitt and VP of Marketing, Tim Zonca. In their considered opinion this new version of Puppet Enterprise, more than just another upgrade, may in fact be the most significant upgrade to Puppet ever.

    From the press release, the most significant of these new capabilities are:

    • Package inspection: Users get started with automation by quickly identifying packages that aren’t being automatically managed, but should be. With package inspection, Puppet Enterprise users report on unmanaged infrastructure, making it easy to see the systems that would benefit most from automation to ensure their most critical software has the right maintenance updates, security patches and licenses.
    • Visual orchestration workflows: Users orchestrate infrastructure and application deployments entirely from within the Puppet Enterprise web UI, without writing a single line of Puppet code. Enterprises can target specific infrastructure environments using drop-down menus and filters, define workflows, monitor deployment status in real-time, and start, stop or restart deployments as needed, all with the click of a button.

    Both of these are much deeper than the few words from the press release. In addition to these though, there are also even more new capabilities packed in to 2017.2. Additionally, the open source Puppet platform 5 has many new innovations and hooks that will continue to keep the large base of open Puppet users happy, if they don’t require or need the greater feature set of the enterprise version.

    Speaking of those many users, that is the lead in to the second announcement. Puppet is growing and growing fast. Over the last 12 months they have added more than 250 enterprise customers to the business. Today over 37,000 companies use Puppet, with over 75 of the Fortune 100 also relying on Puppet. To help satisfy this increasing demand, Puppet announced the opening of a new Asia-Pacific office in Singapore, a large expansion of their existing office in Sydney and the opening of a new R&D center in Seattle.

    Puppet also announced significant additions to its partner program and participants:

    • New AWS Marketplace offering: As enterprises continue to recognize the value of cloud-based environments, they are turning to AWS and other cloud platforms for efficiency, savings and scalability. To support cloud efforts, AWS and Puppet deepened their partnership, making Puppet Enterprise available on an hourly, pay-as-you-go basis. The new offering simplifies installation, provides secure configuration and delivers immediate ROI.
    • Extended Cisco partnership: As software defined networking continues to evolve as a key tenet of the modern data center, Cisco customers want the power of Puppet Enterprise as a unified way of defining, deploying and operating all the software they run. Joint customers can now buy and get support for Puppet Enterprise directly from Cisco and any Cisco VAR.
    • New partners for security and DevOps: Puppet has added a number of important partners as part of its inaugural class to the Technology Alliance Partner Program (TAPP). By collaborating with F5, Splunk, Cumulus Networks, CloudPassage, Conjur, CyberArk, Onyx Point, Intelliment and Sensu, Puppet and its partners collectively deliver a better architecture around security and DevOps.

    Again, all signs point to Puppet’s ascendence to enterprise provider status as it matures into its market leader position.

    The third and final announcement from Puppet is by no means the least of the three. In addition to the first two announcements, Puppet also announced two new offerings, Lumogon™ and Puppet Cloud Discovery™. With these the company expands its enterprise offerings beyond Puppet Enterprise, empowering companies to overcome challenges associated with modernizing infrastructure and application stacks.

    These are first offerings independent of Puppet Enterprise offered by the company. The represent significant new capabilities in two quickly growing markets, cloud and containers.

    Lumogon empowers “anyone involved in running containers, like site reliability engineers (SREs), release engineers, DevOps engineers, and the application developers themselves, now have a tool to gain operational insights into what makes up their containers with Lumogon. Lumogon provides a transparent window into each Docker image and running container, and offers a way to collect, query and report on container application metadata.”

    “Puppet Cloud Discovery collects and visualizes a rich set of system data to give users better awareness of the state of their infrastructure. Unlike other tools on the market that were built for traditional on-premise infrastructure, Puppet Cloud Discovery is cloud-first and is designed to model ephemeral cloud infrastructure. Puppet Cloud Discovery is delivered as a service, making it easy for users to see immediate time-to-value.”

    So Puppet has raised the bar and solidified its position in the marketplace. When taken together these three announcements illustrate that Puppet is accelerating in almost every facet. It will be interesting to see how they continue to build in the months and years to come.

    — Alan Shimel

  • Quali CloudShell Rises to Multi-Cloud DevOps Challenge

    Quali CloudShell Rises to Multi-Cloud DevOps Challenge

    Multi-cloud computing is now an everyday reality for most IT organizations. Because of that, most DevOps teams are trying to figure out how to apply a repeatable set of processes against multiple clouds; rather than having to manage a unique pipeline for each cloud, DevOps teams want to be able to deploy application workloads on any cloud as necessary.

    With that goal in mind, Quali has extended its CloudShell tools for modeling production environments in a sandbox to include support for both Azure and OpenStack environments. Previously, CloudShell only supported Amazon Web Services (AWS) and VMware.

    Shashi Kiran, chief marketing officer for Quali, says version 8.0 of CloudShell makes it possible for developer, test, QA and compliance teams to create a truly authentic replicas of a production environments. That replica can then be used to create a blueprint of an application spanning all the physical or virtual infrastructure, data, applications, tools and services in that environment.

    CloudShell 8.0 also includes support for application configuration management using either a custom script or playbook created using the open-source Ansible IT automation framework. In addition, DevOps teams now can edit some app details directly within blueprints.

    Via a CloudShell web portal, shells now can be centrally managed, updated and removed. The new version also offers enhanced single sign-on (SSO) support, enabling more SAML security features and integration with third-party identity management tools. Finally, CloudShell 8.0 includes increased control of blueprint max reservation time, advanced search improvements and access to new table views.

    Kiran says CloudShell is unique in that it gives DevOps teams access to a model that eliminates the surprises that commonly occur when developers attempt to move an application into a production environment. Given the level of scale involved in modern applications, it’s not possible for developers to effectively replicate a production environment on their own machines. The result is a lot of rolling back of applications after they’ve been deployed into production. CloudShell eliminates that problem, says Kiran, by giving developers and IT operations teams access to a sandbox in which to make sure that applications work as expected once they are deployed in production.

    Rolling back applications in a multi-cloud world has become especially problematic. IT organizations now need to deploy applications locally on a private cloud and in a public cloud. But from an IT operations perspective each of those clouds is becoming more complex, which means the opportunity is greater for something to go awry when it comes time to deploy an application into production. Include the number of target platforms in the age of the cloud and the probability  that an application will work seamlessly the first time it’s deployed is virtually nil. Multiply all the application deployments and updates an IT organization is trying to manage, and it quickly becomes apparent how much time and effort is being lost.

    Production environments need to be as pristine as possible. The only way to make sure they remain that way is to make sure that every application that runs on them doesn’t ever get the chance to adversely affect their condition.

    — Mike Vizard

  • DevOps Chat: Taking Care of Your People with Rob England, IT Skeptic, DOES Speaker

    DevOps Chat: Taking Care of Your People with Rob England, IT Skeptic, DOES Speaker

    In this DevOps Chat we speak with Rob England, the IT Skeptic. Rob joins us from New Zealand (you have to love the internet). Rob is going to speak at this year’s DevOps Enterprise Summit London, June 5-6, about the importance of taking care of your people in the DevOps transformation process. Rob is always an entertaining fellow and this chat is no different. If you are attending DOES London this year, you don’t want to miss his session!

    As usual, the streaming media of our conversation is immediately below and the transcript of our chat follows that:

    Transcript of the Chat

    Alan Shimel: Hey, everyone. This is Alan Shimel from devopsy.kinsta.cloud here for another DevOps Chat. We’re lucky to be joined on this DevOps Chat by a friend of mine and a person who’s actually appeared before on our DevOps Chat, all the way from New Zealand: Rob England, the IT Skeptic. Rob, welcome to DevOps Chat.

    Rob England: Hi, Alan, and, hi, everybody. It’s a pleasure to be here.

    Shimel: So, you know, Rob, actually, I didn’t ask, but are you back home in New Zealand right now?

    England: I am, so I’m about to have my breakfast. [Laughs]

    Shimel: Okay.

    England: Tomorrow. Your tomorrow. So –

    Shimel: Yep, it’s my tomorrow. You’re already living my tomorrow—that’s interesting. So, Rob, of course, I think you’re well known within the DevOps community and the IT community at large, but, for anyone who’s listening may not be familiar, why don’t you give us a quick little background?

    England: Okay, thank you. Yeah, so I come from a service management background, so I have a bit of a presence internationally with a small blog that got a service management following, so that’s how I sort of became internationally networked. And, originally, I was a bit of a skeptic of the whole DevOps thing, but I was gradually turned, by Gene Kim and by John Willis and by Jez Humble and others, into a bit of an enthusiast, and now my whole life is DevOps, really. I consult here in Wellington, New Zealand to the DevOps community and I’m working with a couple of the largest government departments here in New Zealand now, helping them on their DevOps journey.

    Shimel: That’s just great. And, Rob, you’re traveling from New Zealand to London, June 5th and 6th, for this year’s DevOps Enterprise Summit, DOES London. It’s at the –

    England: I am.

    Shimel: – QEII Conference Center. And you’ll be speaking there as well.

    England: I am. Oh, I’m really, really pleased and honored to be selected to speak; I think that’s fantastic.

    Shimel: I think it is too. So, Rob, we’re lucky enough to interview a few other speakers from DOES—not only from London but in past DOES events in San Francisco, but can you give our audience a little bit of a flavor for what it’s like or what’s the process like or what motivates one to go speak at a DOES event?

    England: [Chuckles] Oh, in this case, what motivated me was Gene Kim, so I was talking to him about some of the people stuff that I’m quite passionate about, and he said, “Hey, you should write that up and submit it,” so I did. And, from there, it was pretty straightforward—I put all the details in and had my proposal accepted—so that’s very exciting. As I say, I’m very passionate about the people side of things and the cultural change, and the focus for this presentation is around taking care of our people through that transformation.

    Shimel: Excellent. And so, Rob, when you mention people like that, I’m reminded or brought back to a—I think it was Adrian Cockcroft’s presentation in San Francisco this past—don’t remember if it was October or November, but you may remember. And Adrian’s presentation was very much that,“Hey, people are your most valuable asset and you gotta treat them right. And, when you think about the money you spend on tools and all of these other things, it pales in comparison to the importance of spending money on people.”

    England: Yeah. Absolutely. In the past, even before my DevOps life, I used to write about how, if you look at any project, when we’ve had projects, and how the money was allocated within that project, if it wasn’t sort of one-third people, one-third process, one-third tools, then you had a very strong indicator it wasn’t gonna be a successful project.

    Shimel: Mm-hmm. Repeat that again, though, ’cause you know how you New Zealanders are – you talk so fast. [Chuckles] That it was one-third, one-third, one-third?

    England: Yeah, yeah, yeah. So one-third people, one-third practices, one-third tools. If it’s not something like that, it’s very typical to see project proposals that are going to spend 50 percent of their money on installing the tools and 50 percent of their money on redesigning their processes—oh, and, by the way, there’s a day’s training. You know, and it’s like, well, there’s nothing else recognizably about workshopping with people or collaborating with people or, you know, coaching people or all the other people aspects. It’s very common to see projects that are not planning to spend any money on all that, and I think that’s a –

    Shimel: I agree.

    England: – a formula for failure, right?

    Shimel: Yeah, no, it is. I mean, we tend to take the people part of it for granted, and, just as you said, you don’t spend the money on it, will spend a ton of money on tools and infrastructure. Right?

    England: And I have to say, I think that’s one of the two primary reasons why service management initiatives were so often unsuccessful, was that, I thought, didn’t coach us enough to focus on the culture and the transformation, and we spent too much time on process, so DevOps—for me, the power of DevOps or a big part of its power is it’s focused on people and culture.

    Shimel: I have to agree with you. I have to—you know, Rob, I’m reminded of, back in my security days, the co-founder of StillSecure, I went to visit a rather large bank out in New York, and it was about vulnerability management. And we were talking about the vulnerability management program they had in place and I mentioned to ’em that the way they were doing things, it was forcing his security team not only just to scan at night, which is, you know, normal, but to actually only do remediations on weekends.

    England: Mm-hmm.

    Shimel: And I said, “You know, that means that your security team is working every weekend, in addition to working during the week, ’cause you don’t have enough people to stagger that.” And he said, “I don’t care. I pay them by the week; I don’t pay them by the hour. I don’t care if they work seven days a week.” And that –

    England: There’s a good boss, eh?

    Shimel: Yeah, no, that’s someone you’d wanna work for, right? But this, unfortunately—you know, we talk about culture and the whole “Kumbaya” thing that many people kinda try to say with DevOps, but it’s real. You gotta treat your people as your greatest asset, and that was Adrian’s message, right, at DOES San Francisco. They’re not –

    England: That’s powerful.

    Shimel: Yeah. And they—if you treat ’em like crap, crap is what you’re gonna get, I’m afraid.

    England: Absolutely. And my particular focus for this presentation is about the effect of the transition on people in your organization and, in particular, there’s this “Get on the bus” thing, but we don’t wanna actually throw people under the bus, so it’s giving people the opportunity and the time to grow and to make the transition. There’s very often a “revolution, not evolution” thinking in management’s mind: “Are we just going to change everything?” And, again, we’re very neglectful of the fact—the old bell curve—we’re very neglectful of the fact that just because a few people are coming along doesn’t mean we—we still have to allocate more time for the great masses to get their head around this thing and absorb some of these really quite challenging and radical concepts that underpin Agile and DevOps—it does people’s heads in, as we say down here.

    Shimel: Yeah. So, Rob, let’s talk about that a little bit, if we can. You know, you’ve now consulted, as you said, with a bunch of government departments and companies, both in New Zealand and in other parts of the world. What, from a people point of view, what is the hardest things that these guys or these people have to kinda wrap their heads around to make it successful?

    England: Oh, I’m sure the biggest challenge is getting—well, actually, one of the biggest challenges is getting away from that silo-ed thinking, and so the other power of DevOps, along with its focus on people, is its focus on systems and systems theory and systems thinking. And so I think that they struggle to get out of their silo and start thinking holistically and seeing the whole flow of value and understanding their role in that. That is a big challenge to just about everybody.

    Shimel: Agreed.

    England: Then there’s also—yeah. And then there’s also peculiar challenges to each organization as well, right? So I’m thinking of one where a particularly psychopathic CIO had moved on, and it was trying to teach people that, “It’s okay now. You can come out from under your rocks, you know? It’s gone.” So that’s –

    Shimel: “Out from under your rocks.”

    England: Yeah. That’s a—they all sort of crawled away into shelter, you know? And so that’s the peculiar problem in one situation. So there’s—you know, every place has its own challenges, but a universal one is that siloed thinking and another universal one is just the letting go of the—do you remember the Bastard Operator from Hell, BOFH, or –

    Shimel: Mm-hmm.

    England: – or Dilbert‘s Wally? You know, these characters that—it’s considered funny in IT that people have dysfunctional behaviors and are misanthropic, and part of the DevOps message is just we don’t tolerate that anymore. That negativity is not allowed—we just don’t tolerate it—and getting rid of some of that old cynical bitter and twisted IT thinking is also a common challenge.

    Shimel: I agree. I agree. And you know what? I think part of it is not only the negativity from whether it be a supervisor or peer; I think the other biggest thing that I personally see and when I talk to organizations around DevOps and stuff, and not just dev and ops—when I talk with QA and security and management and so forth—is the finger-pointing, is the—it’s almost like American politics, I’m sorry to say, in that “Yeah, I know this is screwed up, but blame the other guy,” or “If you think this is screwed up, you should see how screwed up the other guy is.”

    England: Absolutely.

    Shimel: You know? “And it’s not my fault; I inherited a mess,” and all of this kind of thing where one of the refreshing things about DevOps is it started with the blameless postmortem, but it’s more than just a blameless postmortem—it’s about “Stop pointing the finger and let’s work on solving this together, instead of just saying, ‘Hey, it’s this mate’s fault and it’s his problem.’”

    England: “I’ve got your back.”

    Shimel: Yep. I mean, and that –

    England: I’ve got your back, buddy.”

    Shimel: You know, and that may sound hokey and “Kumbaya-ry” and  all that, but, really, I think that’s when you start building a team.

    England: There’s a really good cartoon, that might be a Paul Wilkinson one, where the ops guys are at one end of the boat, looking down at the dev guys at the other end of the boat, trying to deal with a fountain of water and saying, “Not my problem, not my end of the boat.”

    Shimel: Right. Uh-huh. Exactly. And we’re all on the same boat, though. So –

    England: Yeah. Yeah.

    Shimel: So this is a real thing. Rob, other than DOES, have you been talking about this kind of subject at other events and so forth?

    England: Oh, for sure. So, actually, it’s been an interest of mine since before I was consulting. I used to work in—for my sins, for a vendor, and I used to do work on professional development there and trying not to let the technical people fall under the bus and trying to get them to skill up to be consultants, rather than just product jockeys. So I’ve worked and talked in this field for a long time, just as a personal passion. I hate to see good people lost, you know, just because their organization failed to make sure they were coming along and to take care of them.

    Shimel: Sure. Sure.

    England: So that’s a long-term passion, but this particular topic now I’m hatching especially for DOES, to put together a presentation specifically about the DevOps implications of—it’s called “Surviving DevOps,” so making sure everybody’s—it’s not just that you individually survive, but that “no person left behind,” you know, as well.

    Shimel: I agree with you. So, Rob, geez, I’ve met you—wasn’t this year’s San Francisco DOES; it was last year’s. So it wasn’t 2016; it was 2015 DOES San Francisco. And we’ve, of course, seen each other several times since, but –

    England: And, you know, I’m one of the few people in the world who’s been to every single DOES in both the U.S. and the UK.

    Shimel: So I think I’m one of them too, actually, but –

    England: Yep, you would be.

    Shimel: Yeah, which is interesting, when you think about it that way. But let’s—I mean, many in our audience may not have been lucky enough to even get to one, let alone five or six of these things. Can you give our audience a flavor of why? Why do you keep coming back? Why did you feel compelled to wanna speak at this one? What makes this a great event in your mind?

    England: Well, I think it’s the fount of knowledge for DevOps, especially DevOps enterprise, so my interest is DevOps for hoses, not DevOps for unicorns. And, very much, the focus of the enterprise conference is around DevOps in the real world, DevOps in the enterprise world, so that’s the first thing. The second thing is that Gene does a fantastic job of focusing and coaching presenters to make sure that their presentations are really short and pithy and full of value, and they also make sure that the presenters are practitioners, so there’s not a lot of talking heads, except for some really high-value experts like John Willis and Jez Humble and Adrian Cockcroft, the people who are up there purely because of their intellectual strengths. But most of the speakers are there because they’re reporting back from the coalface about their own experiences and learnings, and so that, to me, is gold.

    Shimel: Yes. Any—well, I guess that kinda says it all, Rob. If anyone had any doubts about whether they’d wanna go to this or not, that clears that up. Rob, anything else happening exciting around DevOps you think people should be on the lookout for?

    England: Oh, well, I’m not sure about _____ – the value for me is that I live on the last rock on the planet, so I actually get quite a different lens on DevOps than perhaps those, like yourself, immersed in the big economies and big societies, and, certainly, it’s going gangbusters here. There’s a huge wave of interest in the mainstream—in government, in the airline, the banks—and I’m gathering that that’s not necessarily the case everywhere in the world, so, you know, I think that –

    Shimel: No, I think it is. I really think it is.

    England: Yeah. Yeah. But they’re not just dabbling anymore, right? They’re actually transforming; they’re restructuring the way they go. And, to me, that’s the excitement of the moment, is that this thing is mainstream. You know, it’s bridged the chasm. Remember the Star Wars book about crossing the chasm? You know, the –

    Shimel: Yeah. Sure do.

    England: – DevOps has gone from the early adopters to mainstream now. It’s definitely –

    Shimel: Oh, it’s certainly mainstream, but I –

    England: – the majority.

    Shimel: So I think it’s in the early majority, though, not the later majority.

    England: That’s true. That’s true. It’s still not everyone; it’s still not—but, yeah, but it’s certainly jumped—it’s certainly bridged the chasm and it’s on its way up that curve.

    Shimel: Oh, no doubt about that. No doubt about it and, hey, we live it every day here at devopsy.kinsta.cloud, as we continue to kind of chronicle all this. Anyway, Rob, we’re about out of time. I wanna thank you for joining us all the way from New Zealand. Look forward to seeing you in London and your presentation and thanks for doing everything you do, Rob. I mean, you know, you’re a healthy IT skeptic. In IT, skepticism is healthy, right?

    England: It sure is and I love doing it. Thanks, Alan. It’s always a pleasure to talk to you, my friend.

    Shimel: All right, Rob. You be well. We’ll see you in just a couple—well, it’s about two months now, probably.

    England: See you there.

    Shimel: All right. Rob England, IT Skeptic, speaker at DOES London on June 5th and 6th at QE Conference Center. This is Alan Shimel for DevOps Chat. We’ll see you soon on the next DevOps Chat.

    — Alan Shimel

  • Seeking the Balance Between Federalism and States’ Rights

    Seeking the Balance Between Federalism and States’ Rights

    When you overhear someone talking about federalism versus states’ rights, you are bound to think they’re talking about national politics. In the meeting rooms of corporate America, however, it’s often a very different discussion going on.

    For product engineering teams in a medium to large corporate context, many topics and discussions boil down to federalism versus states’ rights wherein federalism relates to the interests of the corporate parent and the states in question are the business units or individual product teams. The representatives from each of these bodies often have distinct agendas and priorities which sometimes compete with each other and all too often leave employees and executives alike flummoxed and resigned to pain.

    The Federalist Perspective

    The people who are charged with driving unification and standardization may indeed use their process and policies as sword and shield, but this doesn’t mean they don’t have a well-reasoned position that drives them. Almost every employee is familiar with the drive to create revenue. Not nearly as many are familiar with the charge of “driving the spread.”

    A business could be viewed as healthy when revenue grows at a rate that exceeds the cost of capital (i.e., “investment in the business beats investment in the market”). Better yet, a business can be viewed as sustainably healthy when revenue grows at a rate that exceeds the cost of capital AND operational expense grows at a smaller rate. This is what is known as increasing “the spread.”

    When the spread grows year over year, it means the business is succeeding at increasing both effectiveness and efficiency at the same time (i.e., “doing the right things right”). In most cases that don’t have explosive market growth, driving the separation between revenue growth trend lines and operational expense growth trend lines is one of, if not the best, metrics for the sustainable health of an enterprise, because the increasing spread acts as a lever to fend off disruption and competition by raising barriers to entry or funding acquisition of potential disruptors.

    If your job within the company is to increase the spread for the entire enterprise, the best tools at your disposal are to drive standardization and consolidation in all things by default. In this context, “all things” really does mean “all things.” It includes—but is not limited to—tech stacks, support levels and processes, operating procedures, job descriptions, programming languages and frameworks, employee policies, employee tools, business process systems and core capabilities.

    This drive for rationalization often will come into conflict at the business unit because individuals at all levels within the business unit will many times be asked to drive change that could sacrifice the performance metrics and commitments that are measured at the business unit level.

    In the eyes of the federalist, sacrificing pennies for the sake of dollars is almost—if not—always the right thing to do for the enterprise.

    The States’ Rights Perspective

    The people who are charged with driving business unit performance may indeed voice their displeasure at corporate direction with an attitude that displays a lack of professionalism and respect, but this doesn’t mean they aren’t fighting for a just cause. Supporting the whole at the expense of piece is something that most people can understand. Not everybody, however, can see the cost that comes when unification erodes peoples’ sense of self-determination.

    Individuals and individual business units alike are extrinsically driven and rewarded by achievement of individualistic goals and commitments. Many of these same individuals are intrinsically driven by a sense of autonomy, mastery and purpose. Autonomy at its basic level is well-understood.

    When new directives for unification or standardization are rolled out, this introduces both direct and indirect cost at the business unit level. These costs aren’t always funded to the extent necessary to drive the required rationalization. Even in the case of reasonable funding, relief from existing commitments isn’t usually factored into corporate directives.

    Funding and wholistic concerns aside, what can be the hardest dynamic to work through is directed idleness while fully aligned decisions are being generated. From the practitioner perspective, this dynamic can be perceived as contemptuous because it simultaneously says, “Your concerns are not sufficient to warrant our attention,” and “Don’t take any action to address your concerns because that will warrant our attention.” In the most extreme cases, this is coupled with an unyielding expectation to meet or exceed performance goals.

    This approach breeds a combination of labor attrition, forced helplessness and a jaded attitude within teams that can take years to unwind and change.

    The Balanced Perspective

    Splitting the middle can be difficult in emotionally laden high-stakes areas. Add distrust and a high degree of power separation, and the degree of difficulty gets intense for this effort. Let’s start from the top because the onus is on leaders to go first when an impasse arises:

    Where federalists can give in efforts to support self determination:

    • Even the most ardent federalists agree that autonomy is the only path to achieve scale in a modern corporation. Central bodies of authority can go out of their way to demonstrate their commitment to this by endorsing explicit role-specific areas where experimentation and innovation is needed (i.e., a message of, “Don’t advance here just yet,” goes down easier if it’s coupled with a list of topic areas that have few or no guard rails).
    • Assuming current commitments are not in jeopardy, acknowledge that work done in excess of current commitments is a contribution and not a distraction, even if it has the localized possibility of deviating from to-be-set standards (i.e., a message of, “Don’t spend time on improving area x,” goes down a lot easier if it’s coupled with an acknowledgment that, “If a person is willing to dedicate their own personal time, that does not come at the expense of the company. We value that level of commitment”).
    • Find ways to recognize and reward individuals and teams for avoiding local optimization at the expense of the whole to compensate for locally defined goals and compensation systems.

    Where states’ rights activists can give in an effort to support a broader set of goals:

    • Even the most ardent localists acknowledge the pricicipal within a hierarchy of goals (enterprise goals > unit goals > team goals > personal goals). Local leaders and practitioners can go out of their way to demonstrate their faith in leadership by going the extra mile to find and generate goal alignment that drives benefits to more than one organizational unit (i.e., a stance of, “We’ve prioritized local remediation in this one area because it helps our business unit meet some secondary objectives,” invites less opposition if it’s demonstrably linked to the broader set of enterprise goals.
    • Assuming room for innovation and continuous improvement is met with tolerance, local leaders and practitioners can make themselves beyond reproach by ensuring goal priorities have been kept in mind and also focusing improvements that have limited to no impact outside of their local responsibility (i.e., a local development push to a microservice architecture can have deep impacts to a centralized operations unit without a diligent effort to manufacture a mature operational capability).
    • Find ways to drive local improvement communications up to broader system owners in an effort to facilitate collaboration and longer-term planning (i.e., a message of, “Business unit x has developed a new solution for y,” raises a lot less concern when it’s paired with a statement of, “… and the teams acted responsibly by collaborating with the enterprise team responsible for keeping our long-term efforts here aligned with a consensus road map.”

    When deference and forbearance meet, graceful and elegant solutions emerge and ultimately harmony is preserved. If only more people understood that the adversarial noise in between us is more harmful than either minor deviance, or momentary ambiguity.

    — Stephen Fishman