Category: Features

  • DevOps Chat: DevSecOps with Signal Sciences’ James Wickett

    DevOps Chat: DevSecOps with Signal Sciences’ James Wickett

    James Wickett is the man to go to for DevSecOps. The founder of the Rugged DevOps movement, which has merged into the DevSecOps group, James is one of the most knowledgeable people on the subject of DevSecOps.

    In this DevOps Chat, James shares his views on what’s on the horizon for DevSecOps and the most important things we can do to make our teams more secure. Have a listen as James gives us his take.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.


    Transcript

    Alan Shimel: Hey everyone, it’s Alan Shimel, DevOps.com, Security Boulevard and you’re listening to another DevOps Chat. I’m really happy to be joined on this DevOps chat by one of my friends from the Austin boys, James Wickett. James, welcome.

    James Wickett: Hey, thanks Alan. Really glad to be here.

    Shimel: It’s my pleasure to have you here. So for those of you who may not be familiar with James, you know, James is really one of the lynchpins in the, for my money, the best DevOps community in the world and it’s the folks over in Austin with Ernest Mueller and James and Karthik and Boyd and just a whole bunch of great people coming out of Austin. But when James isn’t busy building the best DevOps community around, he also works at Signal Sciences and of course James was also kind of the founder, prime mover behind Rugged DevOps and now DevSecOps, as well as with Shannon and those folks. So, I hope I didn’t make you blush, but –

    Wickett: That’s all right. We loved having you come down to Austin and we’re pretty proud of the – you know, it feels like the InfoTech community here in Austin is really close knit and there’s a real family dynamic to it, to a certain sense, the good kind of family. I know that can be different for different folks, but you know, it’s very nice that we’ve been able to do that for so many years and we’re excited for bringing DevOps days Austin, continuing to come back year after year, and your partnership with that has always been great, Alan, so we –

    Shimel: Yeah, no, it’s my pleasure. I don’t say it lightly, especially this past year and a half, two years, I have probably been to more DevOps days and DevOps events around the world, not just here in the US. And Austin’s a special, special place for it. James, as we were talking off camera a little bit, you know, over here at DevOps.com and the rest of the media op sites, we’re doing an event called Predict 2019 and it’s a virtual conference. It’s more than just kind of like a video like this where it’s actually a virtual conference where the sponsors have booths and there’s a whole session auditorium and everything, but the idea behind it is really to put on our crystal ball hats and take a look at, hey, what does the near term future look like? You know, if we’ve been in tech long enough, we know better than to make a long-term future guess.

    Wickett: That’s right, that’s right.

    Shimel: Right? Who knows? But, near term we’ll try. So, I wanted to spend a couple minutes with you and talk about what do you see 2019, the next 12 to 18 months. What’s factored in on the DevSecOps scene, on the DevOps scene, on AI Ops, on you know, just what we live in day to day, James?

    Wickett: Yeah, yeah, that’s right. Yeah. Well, that’s a good question because when you think about DevSecOps and where it is today, I think, I always hope that we’re further along than we are, and the data still shows that like we have some ways to go. There is a SANS survey on secure DevOps and kind of the joining of just security and DevOps and where it is in the current state of the world and Signal Sciences, along with several other sponsors, are happy to kind of be a part of that survey and that research, but one of the things that is pretty astounding out of that whole piece is that 95 percent of securities responsibilities or 95 percent of security people reported that their main kind of thing they were doing was supporting legacy applications.

    So, and it’s real telling that we see this – we’re seeing really in security and DevOps kind of the same problem we had with Dev and Ops, you know, ten years ago, right, this whole throw it over the wool mentality, you know, different groups value different things. Developers valued feature speed and deployment ability, I guess. Operations valued stability, reliability, things like that, and they always felt like they were at odds. Well, security comes in as sort of this third wheel here and what does that do to the mix?

    And I always – I’m really happy like to be spending time with some of our customers at some events and I get to hear stories of people doing things that are radically different than securities done over the last decade, but to say that that’s not – to say that that’s ubiquitous would be false. Like that is just not where we’re at right now and I think it goes back to that quote, right, and I think this helps us with this 12 to 18 month prediction piece. Like the future is here, it’s just not widely distributed. Right?

    So, I can see what leading high performing companies are doing and I can just say, next 12 to 18 months is like more people doing some of that stuff, and I’m excited about that.

    Shimel: I agree with you. You know, James, this is something that I, you know, I’ve always kind of felt is that, you know, we certainly suffer from shiny trinket syndrome and we always want to know what the next great thing is or what’s the next big thing. But what we often forget about is the whole world isn’t a green field. It would be so great if we only had green fields and new apps to work on.

    Wickett: That’s right.

    Shimel: But we live in a world of legacy apps, right? We’re going – no one’s throwing out their mainframes. No one’s going to just throw away all of these applications that have been built. Excuse me.

    Wickett: Yeah, we live in the brown field, Alan.

    Shimel: Right, we live in a very, very brown field and so to me, should we be focusing near term at modernization, right, and how are we – because at the same time we have these legacy apps, James, we have such new infrastructure possibilities with, you know, so how do you containerize and Cubernettisize and make servo lists, all of this brown field application and at the same time, I really think that’s an opportunity for security.

    Wickett: That’s right, yeah.

    Shimel: To come in and let’s do it right. Right?

    Wickett: Right.

    Shimel: Let’s fix something that really wasn’t set up right the first time.

    Wickett: Well, and the inverse or the – there’s another layer to that problem is that we’re seeing people in the security space that are almost cutting edge for like what we would call like DevSecOps and people that are doing great, but they’re all coming from like large enterprises, which is a really weird thing because innovation from the DevOps space came from like small, medium sized companies that were able to be nimble and be fast, but when you’re at a certain size, you don’t have security talent on hand. You don’t have anybody on staff and you’re also – you have a different set of concerns. Right? Your concerns are staying in business for the next several quarters.

    Shimel: Right, keeping the lights on.

    Wickett: Right, when we’re seeing people like Shannon Lietz over at Intuit or we’re seeing Topo over at Capital One, right, or Chitra Elango over at Fannie Mae, right, we’re seeing these stories and the way that people are piecing together pipelines and they’re tying all these security things into these DevOps movements. They’re all coming from big companies and I don’t think there’s – I think there’s definitely a connection there. We’re going to see some of that security wisdom and kind of learning of how to do DevSecOps come from the other end of the spectrum, which I think is a really cool thing.

    If you’d have asked me three years ago, I would not have predicted that at all.

    Shimel: No. So I’m going to tell you, along those same lines, James, to me, this may wind up being the hidden gem or the hidden legacy of DevOps. When I first launched DevOps.com and you were around, you remember, you know, besides everyone yelling about making a commercial, there was this huge argument raging between people about startup DevOps versus enterprise DevOps, you know, could enterprises do DevOps, was it a unicorn thing? And you know, some of the – I always felt that the right answer was, there’s only one DevOps. Right? There’s not a startup DevOps and an enterprise DevOps.

    But, different organizations have different things. I think what we’ve seen over the course of evolution is that yes, DevOps really kind of took hold in the small midsized businesses out of necessity, but enterprises shaped and molded it and made it work at these large enterprises, and in doing so, created opportunity for the security folks, the QA folks. Right? All of these other silos, right, that maybe you didn’t have in a small company, right, because everyone wears like seven hats.

    Wickett: That’s right, that’s right.

    Shimel: Right? But, at the enterprise level, it’s giving it a chance to flourish and to – it’s like a giant petri dish, right, and so it’s great and it’s giving security people a chance to get in here. So –

    Wickett: Well, and you look at, you know, you have a vision of like, hey, let’s put this for, this is not just for startups and west coast companies. This is something that can hit across – and I love that. I love going to middle of America, DevOps Days events like the Kansas City one was quite _____.

    Shimel: Kansas City was pretty cool, yeah. Right.

    Wickett: And I liked it because it’s people at larger companies wrestling with these problems, trying to make this happen and I’ve been lucky enough over the last several years of my career to do a lot of green field type stuff, but that’s not the yeoman’s work. The real tough work that we’ve got to do is DevOps transformations in these large enterprises. And you and Jean Kim through the DevOps Enterprise Summit we see stories of these types of transformations happening and seeing security being brought into that. I mean, it’s just–it’s really pretty cool.

    Shimel: Absolutely. So, now not to prod you along here, James, but –

    Wickett: Yeah, prod me. Prod away.

    Shimel: I see it, so we’ve had a chance to build a little bit of a foundation. Right? We see these things happening at the enterprise level. Kansas City, Chicago’s another great example. Big companies, right, talking about their DevOps and their DevSecOps. How do we build on this momentum, James? What shape does that take? As security people, what do we need to do to move that needle?

    Wickett: Yeah, that’s a good question. Let me – can I take two answer on that and –

    Shimel: Sure, take three if you want.

    Wickett: Sure, all right, good. Well, I think there’s – let’s start with the first answer. I think we’re still developing a mental model or some sort of platform of like how the delivery pipelines work. I mean, of course you can go to any number of talks, you can see how our people have assembled them, the tooling that they’ve put in place, but security has a lot of success whenever they can look across the – whatever the software delivery value chain and say, “All right, how are we delivering the software and where is our build system or our development process and then how do we deploy and deliver all the way to the customer?” And look across the broadly and find discreet tools that they can add in those places, and not just tools for like software, but like practices or ways to transform. Take the ISC squared, CISSP manual and rip out a good – a lot of the waterfall bits, but figure out like were does this change, like in the modern world? And I think that’s – I’d say that’s like the first approach that I would like to say.

    I think philosophically, I would – I’ll kind of answer you with a situation that I was posed with recently. A friend of mine, he works at a large enterprise company. They are not cloud, just now thinking, “Hey, maybe we should do this cloud thing.” And which I – some people that are listening to this are like, “What?” But that’s just the way it is. People are –

    They have so much investment in the data center that like now it’s like they finally kind of said, “All right, we have some new stuff that we’re building. We think the cloud is where we should do it and we’re hearing these things like Cubernettis and servals and containers and whatever.” Right? “So we’re trying to figure out what direction we take with all this.”

    So now some of these companies, legacy type companies, are putting resources towards it. Well, this guy is a security guy and he had them kind of come in and say, “You’re going to DevOps the thing and DevOps is going to be the way.” Right? Not really – this is a company where maybe they’re not even really sure what DevOps really means. Right? Which is okay. They’ve heard it. They’ve got some of the vision and they’re interested.

    He’s very concerned. He says, “James, what do I do about this? I know you like the DevOps and stuff like that, but you know, what do I do from a security perspective.” I give him an answer. I didn’t feel great about it. I gave him a, you know, I don’t know, find ways to inject stuff, I don’t know. I went home, thought about it, woke up the next morning and I was like, “I got to call him back.”

    So I gave him a call and I was like, “Hey, the real answer to your question is never say no ever again. Never say no ever again. Security has lived the world of no for so long and you have to throw that away. Like your new answer has to be yes, you can have yes with qualifiers, yes with whatever, but you’ve got to find ways, creative ways to say yes and kind of the cloak and dagger, blame it on compliance, slowing down things for whatever, you can’t do any of that stuff anymore and you’ve just got to throw out all the security gets to be a blocker.”

    And I said, “Because every organization that I see high performing, what we would now call like DevSecOps teams, but security and DevOps working together, they sort of rip tear up the security playbook and they say, if you are a blocker, everyone in the organization is going to route around you. But if you play ball, like you get to be a part of the solution. And security has to find a way to add value inside of that.”

    And so, and I said, “Every single one, you talk to any person who’s undergone the transformation and working in any of these companies to Hulu to Netflix to Inuit or whatever, you know, or all the ones that we see at DevOps Enterprise Summit, they’re always finding ways to say yes and be part of the solution and not to see themselves as a blocker. So I think that’s a fundamental like philosophical shift that security has to undergo.

    Shimel: Absolutely, and you know, just to turn it around on you a little bit, I’m going to be the Jewish guy spreading the good news too, right, the gospel. We started off this conversation early on and you said, “Well, we still have so much more to do and I wish we would be further along.”

    Wickett: Yeah.

    Shimel: You’re right, but someone much smarter than me once told me, James, change, especially in technology, is 99 percent of the time evolutionary, not revolutionary.

    Wickett: That’s right.

    Shimel: But, when we look back over a period of time, we’re often astonished what that evolution – how that evolutionary change adds up. So the fact, that little piece that you espouse right there about not saying no anymore, and yes, we can and you know, whether you qualify it, caveat it whatever, but yes, we can.

    Wickett: Yeah.

    Shimel: It’s so powerful. It really is. It’s so powerful. Look, I spent 2001, I’ve spent 18, 19 years hearing now from people, and – or being part of the no too, to be in all honesty.

    Wickett: Right, yeah. I mean, that’s –

    Shimel: You don’t want to wind up in jail, do you?

    Wickett: I got my ISC squared books up there. They look at me with an evil eye.

    Shimel: Yeah, so you know, it’s refreshing. It’s like liberating to take that attitude. How do we spread this gospel though? What more – what better way can we do it? I know you’re involved in DevSecOps.org and DevSecOps Days and I’m obviously too and at RSA this year, we’ll be doing our thing again. But what more could we do in 2019, James?

    Wickett: Oh man, that, I don’t know the answer. I don’t know the answer to that question yet. I mean, I think there’s some pragmatic things. I think we continue to say the story side. I relate to what’s going on with security right now to what happened with DevOps in the beginning and if you rewind to like 2009, 2010, or like let’s say the first three years, right, DevOps equaled chef or puppet, like straight up, like that’s what it was. And so what was that? That was operations was finally able to be developers, to act like developers, to shift left. Right?

    They participated in agile type practices with infrastructure, revolutionary, really cool, really great. But then there was also another movement that happened at the same time and that was the idea that like we needed the instrument a lot better. We need to do monitoring. Now, people talk about observability. There is a big push of understanding like what your systems are actually doing. So, and that was, then there’s kind of the whole like monitoring conference, there’s monitorama, there’s monitor movement and the monitorama in response to it.

    There’s some great products have come out of that space. We see things like Data Dog and before them Cloud Kick and other folks. Well, I relate all that to security because if you look in the first several years of this security and DevOps kind of joining forces, I know people have been talking about it for many years, but over the last couple years, what are the things that everybody has kind of gone around? It’s the whole idea of shift left. So you see great companies, _____ types, Nick, other folks like that, that are focusing on, you know, putting all of your development testing, you know, figuring out what binaries, talking about software supply chain, bill of materials, all that sort of stuff. We’re still missing the push right.

    Now, I mean, I work at a – or a shift right type thing and so like, Signal Sciences, we sit at that end of the spectrum, so this is a bit of a self-serving type statement, but I mean, you need to have sort of insight into sort of what your application is doing and when we started the company, we were singularly focused on one question and that question is, do you know right now if you’re under an attack with any degree of certainty, we’ll say. You don’t have to know 100 percent, but with any degree.

    I ask people that question like in conferences and whatever and almost zero, like I’d say just one or two people per, y, every six months or whatever, says yeah, they know. Most people have no idea, like what’s actually going on in their site. And we see this like when was the last time you read the headline that said, like, you know, we lost a million account credentials, but we stopped them. We’ve been following them through our system, we saw that they were starting to leak data and so we turned it off, but we didn’t get it off soon enough, but they didn’t get 100 million, but they got a million. Right? You never see that news story. Right? You see the news story of like _____ we lost it all and we lost it all three months ago. We had no idea until it started being traded on the market. Right?

    So, like we lack a critical insight and you know, operations had the same problem, right, didn’t understand what was going on with the systems, performance-wise, everything. Security is quite similar to that. So, being able to instrument and see and do monitoring and have that sort of security observability is like an important aspect to where I think we need to go. So, we’ve done a lot of the shifting left similar to ops in the early days, and I think we’re going to see some more movement on the shift right part.

    Shimel: It also sounds though like opportunity there for some better tooling.

    Wickett: Yeah.

    Shimel: Right? I mean, a lot of our security tools, you know, from vendors really aren’t made for that, right? I mean, you know, we have so much – so you know, the fighting point in the security vendor space is, should we put more focus on security response versus prevention? Right? Threat intelligence, all of these things, and you’re right. We don’t have that analog of a Data Dog, a Signal FX or that, for the most part, in securities.

    Wickett: Yeah, ’cause like I see that across like – so for Signal Sciences, like we provide that for web applications, but that’s also stretching across other boundaries that you need to look at, and a more fuller picture, and I remember whenever we were launching – when Ernest and I were doing cloud stuff at our first just kind of thing over at National Instruments, we were trying to find vendors and just straight up like operational monitoring vendors and I talked to like – that was my job. That was one of my first parts of the things.

    It’s like, okay we built the thing that – we have this whole thing we called Pie that spun up our system, much like Chef and Puppet, but then we said, all right, what are we going to monitor this stuff with? And I started calling and monitoring vendors and getting demos and stuff and it’s like, at the end of it, I was like, I just need one that has an API. Like just a good working API that can like admit _____  _____ and connect, you know, ’cause this is early days. Right? And we ended up finding a Cloud Kick and they ended up getting bought and sold and we moved later on to Data Dog, but it was so hard at the time to find that. And I feel like security vendors are similar in that space, that they struggle from where like when – and we’re not alone in this. There’s other people in our space that are doing thing that are helpful for people, but emitting data back to all the systems that you work with, like the Slack and JIRA and whatever, but also just being part of like the whole tool chain approach. And I think that’s a story we’re going to see continue to be developed and companies that are adopting that and embracing the idea that they’re a piece in the overall tool chain, like I think those companies are going to continue to do well.

    Shimel: I know that you can have like just standalone security monitoring and so I think security monitoring has to be part of your larger monitoring.

    Wickett: That’s right.

    Shimel: Two or three other points I wanted to hit on, get your opinion on. So, just like DevOps, same analogy, tools are important. Culture trumps tools in a lot of places and we can have the best tools in the world, but until the security people’s mindset is changed and we’ve touched on it in this talk, you know, not saying no anymore and all of that, so how do we go about changing that mindset? Well, one piece of it, James, is at the organizational level, right, we embrace security.

    We make them part of the team. Another part of it though is at the community and industry level and we mentioned it now a few times and a lot of my friends mention it, and this is the whole what are security people taught. And I’m not knocking ISC Squared or SANS or any – we’ve got some –

    Wickett: Let’s knock them. No, yeah.

    Shimel: I’ve got friends on the board there. You know, I got to be careful. But, I mean in all honesty, and again, I’m not singling any one of them out, but when security people are being taught to say no, it’s very hard for us to come in and say, “Don’t say no.”

    Wickett: Yeah.

    Shimel: Right? So, do we, you know, you know I’m part – I’m one of the cofounders of DevOps Institute and we have a DevSecOps class there that you know, some of my more enlightened friends have helped us with. You and Ernest have done the DevSecOps thing. You guys do _____ and stuff like that. But those messages, I don’t know if they’re finding their way into, let’s call is mainstream security training, ISC Squared, CISSB exam, the SANS certifications and not just those two. There’s a half a dozen other very well-known ones. How do we, you know, is 2019 the year we make a beachhead there?

    Wickett: I don’t know. I don’t know. I’m an optimist, Alan, so I would love to say yes to that question. I would love to say yes, but when you think about it, like it’s – security has a very tough job. They’ve worked themselves into a scenario that they’re beholden to compliance and standards and outside bodies of influence and then they also are inside of an organization trying to affect change, but they find themselves at a very like inequitable distribution of labor. So like you have a hundred developers. You have ten operations folks. You may have one security person. Right? That’s a recipe for a problem. They’re all going to have different values.

    So, I don’t know if we’re just going to automatically fix the culture in 2019. I will say tools influence – tools have an influence on culture and that you know, in the CANS model or CLAIMS model for DevOps—or CALMS, I guess people like to call it as well, but for the M, for measurement and sharing, I think those are the two pieces that can really help influence the culture in a more positive light.

    And so, you know, security has, you know, we have stocks and we have like we – we remit all the data and have people taking concern of this, but we’re not – if you’re not creating – this is something else that I try to influence among my security friends. It’s like, if you have any tooling that you’re buying and implementing whatever, but it’s not creating a feedback loop to developers, then it’s like worthless. You should _____. Right? If it’s just going to a sock and someone’s doing it like, that’s not good. Right? There’s no DevOp telemetry out of what’s actually happening.

    And so I think finding products that can help or whether it’s like open source testing tools or you know, instrumentation on the right or detection on the left or whatever, but like creating those like, I don’t know, able – we’re able to have a sort of virtuous cycle of feedback loops to development. I think that’s going to be key. But yeah, I’m going to say like no, 2019 is not going to be the year just because of – just because of the way humans are. I would like – but I think that it’s going to get better.

    Shimel: I think it will get better. Here’s what I think we need to do, James, and you have got to do in this.

    Wickett: All right.

    Shimel: You and I are both wired into this community. We know people on the ISC Squared board. We know SANS instructors. We know the folks at SANS. We know all of these places. If one of the missions of the DevSecOps.org group, team, community, DevSecOps Days, what I do with my stuff, is to make sure we reach those people and say, “Hey, we represent a very large piece of this community and you’ve got to listen to us. It’s like a voter registration drive then. And – but you’ve got to lead it, right? And so, I’m going to put the onus back on you, James, and say you can make this a reality. You –

    Wickett: All right. Well, Alan, let me tell you how I am working on that. So I do have somewhat of a plan here or an idea here. So, I’m working with several others, Shannon Lietz, Ernest Mueller, John Willis and we’re working on the DevSecOps handbook, which is going with IT Revolution, and we’re trying to tell those stories of like how DevSecOps is transforming at large companies, small companies, helping people see the new path forward. So hopefully yeah, that’s –

    Shimel: In 2019?

    Wickett: That’s – the – what is it called, the like the draft galley copy, like we’re hoping to have some of those available in 2019 at the DevOps Enterprise Summit _____ either in London or in Vegas, so yeah, it depends on – you know, it’s a – they run a real great shop over there, so it depends on the schedule for editing and all that stuff.

    Shimel: Well, that’s a revelation. Good stuff, man.

    Wickett: So hopefully 2020, 2021, like we’ll start to see the industry really shift. You know, I do hope that – I always hope that things happen sooner than they do, but –

    Shimel: It _____ before it’s time either, my friend, right?

    Wickett: That’s true.

    Shimel: So James, I told you this was only going to be 15 or 20 minutes. I’ve got a feeling we’re at like twice that already.

    Wickett: Yeah.

    Shimel: But, it’s okay. I think it was a great conversation. People will enjoy it. Predict 2019 folks, you can go to predict2019.com. James is, of course, with Signal Sciences and you should definitely check out their site and what they’ve got going on. And also just a quick reminder, RSA conference is here March 4 this year. And we are doing our DevOps Connect DevSecOps Days at RSA Monday March 4, so if you’re going to RSA, come a day early, come in at the Moscone Center, Shannon the whole crew _____.

    Wickett: Yeah, if people are listening to this and they haven’t been to that, like, you’ve got to go. Like, I think that’s a very valuable single day track that’s really helpful. And also, some of the sponsors and vendors back there, like some of the really forward-thinking folks, I mean, it’s the – it’s really like the part of RSA that I feel like has really kind of anchored that for me in my experience at RSA. It’s like “Oh, okay. Here’s the crew. Here’s what we’re trying to do.” I can see the message going out, and I love the fact that kind of the vision, did you decide to start that or is that –

    Shimel: That was me.

    Wickett: That’s – I think that was good because –

    Shimel: DevSecOps Days, I just – you know, I – so I have a relationship with RSA for 15, 20 years and I originally went to them with it. This is the fifth year we’re doing it. I’m really pumped. I mean –

    Wickett: Yeah, well, and thank you for that because basically like we – I’d say one of the ways we make the transition is by going to security events and kind of helping make this happen.

    Shimel: Yeah, raising the flag.

    Wickett: Yeah, and you – that is an outpost for DevOps over at RSA, RSA of all conferences. So –

    Shimel: Yeah, if we can do it there, we can do it anywhere.

    Wickett: I agree. I agree.

    Shimel: All right. Hey, James Wickett, Signal Sciences, thanks for being our guest on this DevOps Chat. James, thanks for all you do too for the community and everything else. Keep up the great work and we’ll speak to you soon.

    Wickett: All right, thanks Alan.

    Shimel: All right. This is Alan Shimel for DevOps.com Security Boulevard. You’ve just listened to another chat. Have a great day everyone.
    — Alan Shimel

  • DevOps Kids Holiday Gift Guide: Giving the Gift of Code

    DevOps Kids Holiday Gift Guide: Giving the Gift of Code

    Any DevOps professional worth their salt inherently understands how inextricably tied the future of work is with coding, scripts and automation. It’s already a development-oriented world out there and is increasingly growing so. As a result, today’s kids need to at least understand the fundamentals of programming if they want to succeed later on in life—even if they have no interest in becoming full-fledged developers themselves. This knowledge is what educational professionals call “computational thinking.”

    Learning this mode of thinking doesn’t have to be a drudge, though! Fortunately, there are tons of awesome STEM toys and games out there to get kids into the coding mindset from a very early age—all while having fun in the process. We’ve gone through the trouble of sifting through the offerings to give the DevOps community a good head start on their holiday gift giving, no matter the age of kids they’re hoping to bring into the fold.

    Preschool

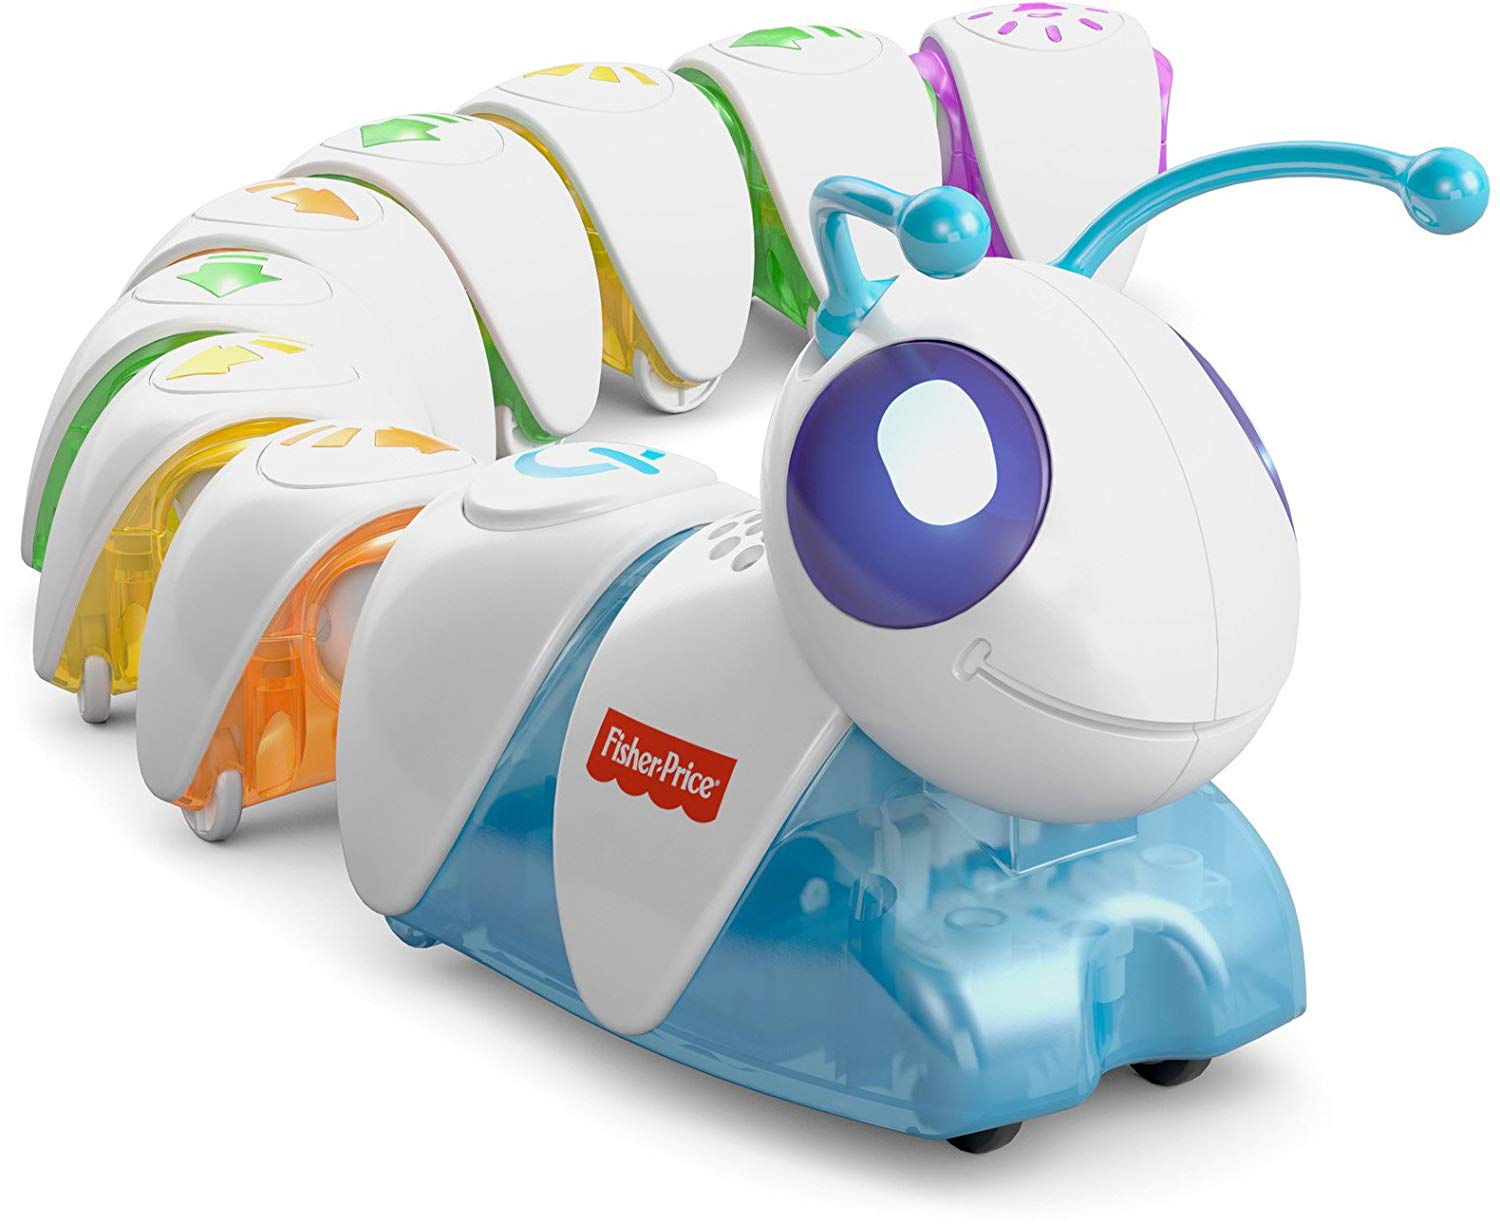
    Code-a-Pillar

    Price: $47

    What’s not to love about a programmable caterpillar? Very young children pick up planning and sequencing skills by experimenting with the way the Code-a-Pillar moves. Each segment of the toy controls its movements such that different segment sequences create a route for it to move.

    Cubetto

    Price: $224

    Inspired by the Montessori emphasis on the accessible simplicity of wooden toys, Cubetto gives little ones the chance to physically manipulate a programming language via a wooden robot. Putting wooden blocks on the Cubetto tells it where to go.

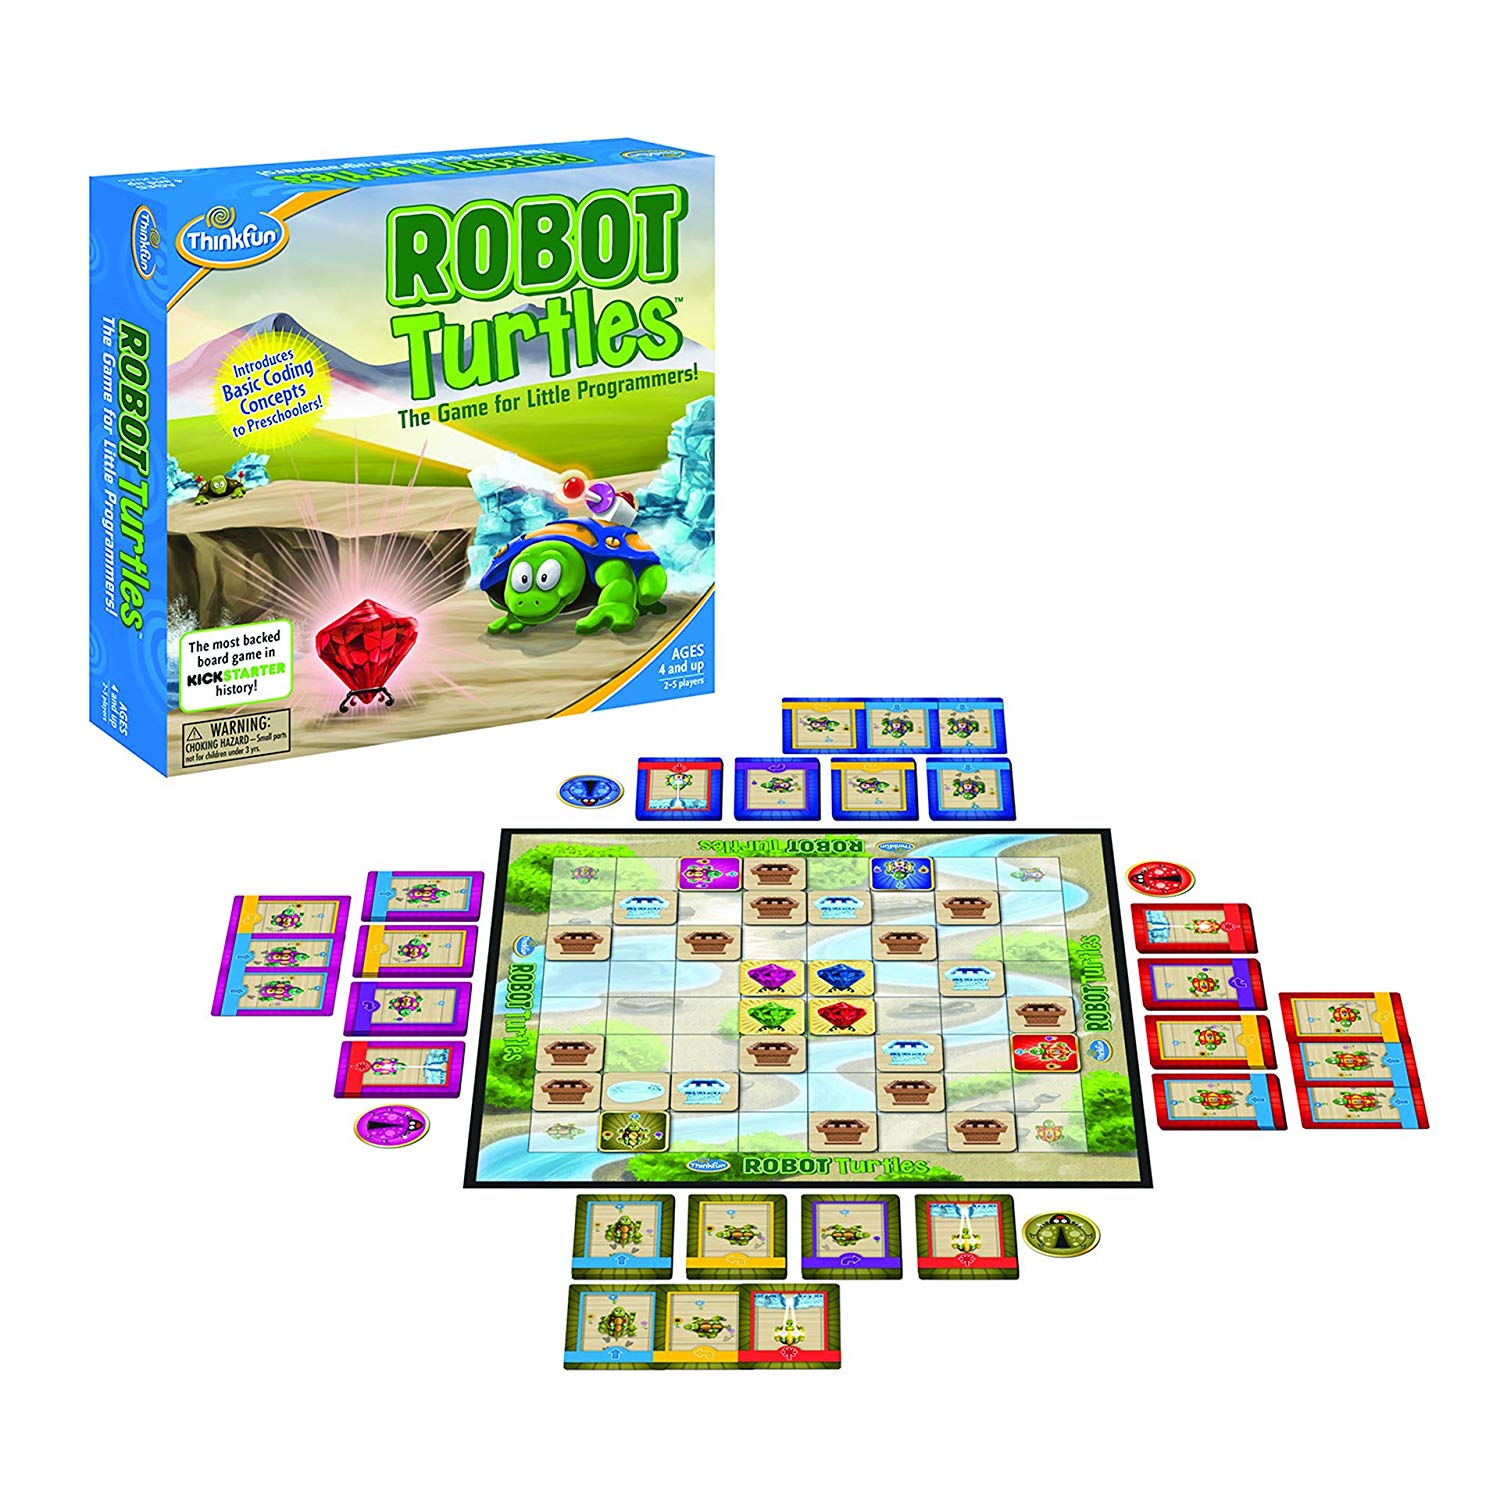
    Robot Turtles

    Price: $20

    Built from a massively popular Kickstarter campaign, Robot Turtles distills the basics of coding into a fun board game tailored for preschoolers on up through grade school kids. Kids learn sequencing and even subroutines by moving the robot turtles around on the board. It’s what the creators call ‘stealth learning.’

    Grade School

    Let’s Go Code

    Price: $27

    Believe it or not, the creators of Let’s Go Code have managed to figure out a way to teach programming principles in a kinetic activity that doesn’t even require a computer. This is a game that has kids use coding precepts to build mazes that they’ve got to hop, skip and jump through—perfect for bubbly young grade schoolers.


    Botley

    Price: $52

    Much like the Code-a-Pillar does for younger kids, Botley teaches screen-free coding by having kids create more advanced routing programming for a little robot. This adds more complicated challenges such as creating obstacle courses, looping commands and more to require a higher level of critical thinking for the grade school set.


    Kano Computer Kit

    Price: $100

    Get kids well and truly pumped to code with the Kano Computer Kit, a complete box kit that comes with everything they need—including detailed instructions—to build their very own computer and then code on it. The software platform comes built with over 100 coding challenges and teaching tools for kids to create their own games, websites, art and music.

    Middle and High School

    Circuit Playground

    Price: $34

    This handy starter kit comes built in with multicolored LEDs, environmental sensors and more to get kids into experimental embedded programming. The platform runs MakeCode, Circuit Python, Adruino and Code.org CS Discoveries, giving tons of runway to create unique projects. The Playground’s creator has a very extensive online knowledge base and maker community to give teens some ideas to get started.


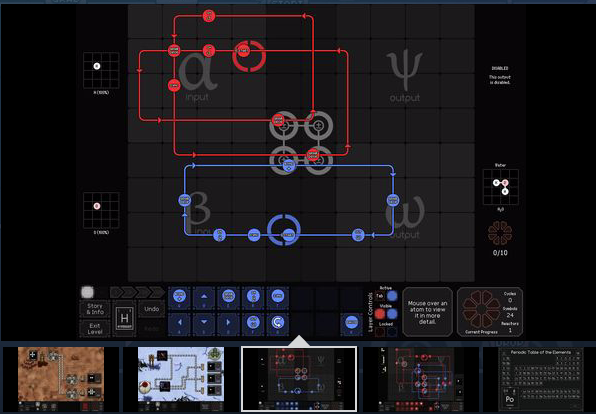
    Space Chem

    Price: $2

    Pick up this design-based puzzle game on Steam for cheap to get older kids into programming in a fun and engrossing format. The game has players acting as a “reactor engineer” in a sci-fi space colony building out chemical synthesizers to transform raw materials into chemical products. As they solve puzzles they start to learn about basics like sequencing, loops, branching and subroutines.


    MakeBlock Ultimate 2.0

    Price: $350

    One of the most versatile robot kits for teens on the market, this one comes with more than 160 parts that can be combined into more than 10+ forms that are then programmable via a number of methods. Beginners can use drag-and-drop function blocks, and as they learn more kids can program it using Python, Arduin IDE and NodeJS.

    — Ericka Chickowski

  • DevOps Chat: App Modernization and Service Virtualization with IBM’s Matt Tarnawsky

    DevOps Chat: App Modernization and Service Virtualization with IBM’s Matt Tarnawsky

    While everyone wants to focus on building a new app, the fact is there are many, many apps already out there. They need to be maintained, updated and modernized. How do you upgrade these legacy apps to new infrastructure, frameworks, languages and more? App modernization is a thing.

    In this DevOps Chat we speak with Matt Tarnawsky of IBM about app modernization and service virtualization, testing and more.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Transcript

    Alan Shimel: Hey everyone. Alan Shimel, DevOps.com, and you’re listening to another DevOps Chat. In this episode of DevOps Chat we’re going to spend time talking about app modernization, testing, service virtualization. We will see what else kind of gets dragged in within our time frame.

    Our guest, you know, who’s going to serve as the expert today, Matt Tarnawsky. Matt, hopefully I didn’t mess that up too bad. Matt is with IBM. And Matt, welcome to DevOps Chat.

    Matt Tarnawsky: Thank you, Alan. Good to be here.

    Shimel: Absolutely. Pleasure to have you here. So Matt, first of all, I did not mangle your name too badly, I hope.

    Tarnawsky: No, you got it pretty good.

    Shimel: Fantastic. So Matt, following our tradition here on DevOps Chat, we like our guests to introduce themselves. So why don’t you tell us a little bit about your current role at IBM and also a little bit about your own personal journey that led you to be here today.

    Tarnawsky: Sure thing. So I am the product manager for IBM’s Rational Test Workbench and Rational Test Virtualization Server, specializing in API testing and service specialization. In terms of how I got here, I have had an interesting journey, starting off with working with a lot of the circuit boards and SPGAs, working with those and then testing those as well.

    I ended up migrating across to working with a small company called Green Hat Software building, AGI testing and service specialization tools. We were acquired by IBM several years ago and I’ve been enjoying the journey ever since.

    Shimel: Good for you. That’s a great story met. And you know, it’s fairly – it’s more usual than unusual in the IT space when you see someone – when we look at the arc of our careers, five years from now who knows what we will be working on. It may not even exist or we even know about it today. So it’s kind of right par for the course.

    So Matt, as I mentioned earlier, I wanted to talk a little bit about app modernization. In my mind, anyway, it’s a loaded – that phrase is a loaded phrase. We hear it bandied out about a lot but when you talk to people – to some people they are talking about, “Well, I am modernizing my existing app. So I’m taking my legacy applications and modernizing them for new infrastructures, new delivery methods, new imports, what have you.” So really about modernizing your existing legacy applications.

    To other people, though, it’s more about modernizing the way you develop, deploy, and manage applications. So modern – application modernization. Of course, no matter how we are talking about it, testing plays a vital role in this. So why don’t we first do a little level set. You know, Matt, what you – when you hear app modernization, what does it mean to you?

    Tarnawsky: So to me, it encompasses a lot of things you mentioned _____ _____ _____ _____ people talk about is, how to do I _____ _____ my app to new markets, new interfaces. That can be things like mobile. It can be things like presenting apps _____ _____ _____. And that often does require _____ _____ _____ _____ their interfaces to actually bring them into the _____ away from our systems that they may have had in the past.

    But often, it also means they want to look at the faster methods of delivery, new development styles. These things often go hand in hand. You often can’t get those faster methods of development with rapid feedback and everything else without looking at, how do we change our entire development life cycle; trying to be stuck in a waterfall method doesn’t really get you that same acceleration that you can get when you start looking at, how do we automate everything and moved to DevOps.

    Shimel: Got it. Got it. Now you broke up there a little bit back on – and I’m hoping people listening will be able to catch all of that. But let’s – so we may fill in. But let’s talk a little bit about the role of testing and that framework of app modernization. Obviously, testing is important, but how so and in what context?

    Tarnawsky: So I actually see – you know, if we are taking older, monolithic applications and looking to migrate them towards micro-services, it’s a great opportunity for testing. You are putting things into small units that can be tested on their own. You get things like – let’s say you’re migrating to a _____  based _____ based service, you get the opportunity to describe it with _____ Swiger or _____ or open API. And you’ve got a contract there that you can then test against.This means that things now have the parameters, the what needs to be tested, how to test it, and it can be imported into many different test tools to help them start testing, but it’s smaller bits of functionality. So it’s a great opportunity to break things up and really look at how those can be worked with at a smaller level.

    At the same time though, it also introduces new opportunities for more complex interactions that we didn’t previously anticipate. So let’s just say you’ve taken that big monolith. You want to expose micro-services to the rest of the world or indeed to other teams in your organization well, suddenly the integration that you had relied on in the past might not be the same ones that you are looking at using in the future. You need to start looking at how we test not just those smaller levels of the micro-services, but also looking at how we test each of those integrations over time.

    One of my customers has a great analogy that they like to use in terms of the testing. They said when you’re testing a car, you don’t just test the car. You test little pieces of it. So you might start off by testing the spark plug. Then you might say we will integrate some pieces and see how those work together. We test the engine out. Then at some point in the future, we will put the engine in the car and we will test that as – you know taking it for a test drive, taking it for a spin, and make sure the entire end-to-end system works as well.

    Shimel: Excellent. Excellent. Actually, that’s a great analogy. Great analogy. So Matt, another phrase we hear, and we’ve all been hearing it, a lot of us, in IT for a long time now, is service virtualization. I think people have a better handle on what we mean when we talk about service virtualization. But again, let’s lay a foundation. When you talk about service virtualization, especially in terms of app modernization and testing, what does that mean to you?

    Tarnawsky: So service virtualization is where we take some sort of interface that we might have had that could be something silent rest. It could be something like Mqueue. It could be a legacy mainframe interface like Kicks. We provide some sort of mock that is going to handle the interactions with the interface. That can be coupled on the rest of the application. It starts to be providing us – I’m sorry.

    It starts providing us with the ability to look around and – I’m sorry about that. Got myself a little bit jumbled there.

    Shimel: No problem.

    Tarnawsky: Basically, it gives us the ability to remove restrictions from ourselves. So if we had legacy items in our environment that we might not have in the cloud yet, well actually, we can do is we can say, well, look, that mainframe connection, that SAP connection, whatever it might be that’s in our current on-prem environment, we can virtualize that, we can house something that sits in the cloud. And in fact, our developers can have an entire environment in the cloud that is no longer linked to those legacy systems.

    Shimel: Fair enough. So how does this all play out then, Matt? Right? So now we’ve got our little parts here and we’ve defined what we mean by this. In your world, where are you seeing sort of rubber meets the road, if you will, in terms of organizations deploying, employing, doing this kind of stuff? Make sense?

    Tarnawsky: So we see all sorts of things. We do see people looking at that – we want to do a migration. So we are going to record various pieces of environment and have them available to replay. Just very, very basic style of creating virtual services, but it can be effective. And indeed, they can do the same sort of thing for their API testing as well and just say, “Have we migrated this correctly? Does it still have the same functionality we had last week when we had it on-prem as we got on the cloud now?”

    That’s a very effective way to look at things. But equally, we see all sorts of interesting stories come up from customers, whether that’s looking to virtualize the way a third party – so we’ve seen customers look at things like Apple Pay or Experian or whatever, where they have to pay every time, they had that third-party service. Or indeed, that might just don’t have control over it and they want to simulate what happens if that third-party service responds or throws an error code or whatever.

    We see customers who do some really – one of my favorite stories comes from a customer who was looking at testing out their credit card issuing systems. Now, you can imagine that as you’re looking at issuing a credit card, at some point you’re going to print a credit card. Now, just imagine test automation for that sort of thing. Do you really want credit cards popping out of the machine? No you want to be able to test things effectively, but not have these physical dependencies.

    So what they did what they looked at the traffic that was going through that credit card machine, the issuing machine. They said, here we got a point where we can virtualize some things in our environment and remove this dependency that we currently have. We don’t want to print real credit cards. It’s a waste of time, waste of resources, and in fact, it slows that test automation down. So if we can virtualize that out, we can get faster feedback back to the development team. So that’s exactly what they did.

    Shimel: So Matt, we recently did a webinar over on DevOps.com you are probably aware of it, modernizing testing as apps re-architect. Is this the kind of stuff we are talking about?

    Tarnawsky: Very much so. You want to make sure that your testing stays in pace with that re-architecting of the apps. A lot of that does come down to developers delivering fast from the cloud. And tests more and more need to be automated. That doesn’t remove the value of exploratory manual testing or anything like that. But we do see that need for testing to become more and more automated in the future as well, as this change happens.

    Shimel: Absolutely. You know, another thing, and I get this a lot, Matt, when I’m traveling around the world. Is this a sort of – not to use the – abuse the term, but first world problems, right? Is this where… In terms of the market, is it sophisticated, large enterprises who already have legacy infrastructures, a history of service virtualization and so forth? Or is this something that’s really kind of more grassroots that’s happening across the board, across the globe, as organizations are starting to move to app modernization and dealing with the realities of having to test around this stuff?

    Tarnawsky: So we see all sorts. Actually, the example I gave you earlier, the bank that was looking at the credit cards, was a fairly new bank here in the UK.

    Shimel: It was? Okay.

    Tarnawsky: They were – that they are very much based on looking at how they can do things in the cloud, trying to keep things as modern as they can. They are looking for all the latest techniques, all the newest tools that can help speed up their development and their time-to-market. So yes, we do have a number of customers using this stuff for legacy enterprise systems. They are looking to virtualize the way a mainframe, for example.

    But equally, we see other customers come to us and say, “I want to accelerate my development and my testing as fast as we can. What can you do to help us?”

    Shimel: Good.  Interesting. You know, Matt, I mentioned when we started that the time goes pretty quick. We are coming up on the end of our time frame here. But for people who maybe want to get more information on this, where can they – where can we dig? I mean, I should mention that the webinar I referenced earlier is available on DevOps.com and YouTube, a recording of it along with the slides. So people who are interested there should absolutely head on over and get that. We will try to include the URL in our show notes for today’s podcast.

    But where else should they go, Matt? How do people get smart on this?

    Tarnawsky: So I would invite them to come on to IBM.com, searching for Rational Test Workbench or Rational Test Virtualization Server, depending on whether they are interested in test automation or service virtualization, as a starting point. And we’ve got loads of white papers. We’ve got customer stories. We’ve got all sorts of things you can look at for more information just to see how other people have been doing things.

    Shimel: Fantastic. Matt Tarnawsky, thanks for being our guest on DevOps Chat today. Pleasure to have you on. Hopefully we will have you on again soon.

    Tarnawsky: And thank you very much for having me.

    Shimel: All right Matt. Hey, this is Alan Shimel for DevOps.com. You just listen to another DevOps Chat. Have a great day, everyone.

    — Alan Shimel

  • Software Delivery: Shaking Loose of a Local Optimum

    Software Delivery: Shaking Loose of a Local Optimum

    This is an article about software delivery, that magical or onerous field between pushing code to version control and using it in production. Why does software delivery matter? Because software matters, and because software developers matter. I don’t want my software delivery to get out of the way; I want it to make me a stronger developer.

    The path from code to production is crucial because it determines the length of our feedback loop and, therefore, our rate of improvement and that all-important lead time.

    Our current tools think of delivery as generic—they take control, and we fill in the blanks. They let us build, test, deploy. But these words mean something different for every application, on every team and within every business. And there’s a lot more that goes on, or can go on, between the writing and the running of code. There’s often linting, approving and coordinating. There’s data to think about and security policies, business team structure and auditing. There are other steps we don’t bother with, because there’s no slot for them: updating libraries, fixing the code to meet standards, taking a different set of steps for a documentation-only change.

    What else have we not thought of, because it doesn’t fit inside the current set of tools? I want to think about delivery from the top. In doing so, I can gain a greater understanding of my work.

    We’ve seen major shifts in Operations technology: containers, log aggregation, observability, programmable infrastructure and Kubernetes. In my opinion, the killer feature of Kubernetes is its API—it is controllable by automation. It accepts instructions and sends out events.

    The potential here is even bigger than we have realized, for operations and for delivery.

    Modern options for operations have achieved new levels of abstraction and potential. Yet progress in delivery has only been incremental.

    Our tools are very configurable, with plugins and scriptable bits, and we can always fall back to running shell scripts of unlimited length. But are we stuck in a local optimum? Are we thinking big enough?

    What We Have

    Today’s popular software delivery tools are fill-in-the-blank. This is great for getting started, when you don’t know what you’re doing. What about when your business grows, when your delivery is no longer cookie-cutter? Let’s look at two examples.

    Travis CI is a favorite of mine because it’s so easy to get going. It will happily build any public GitHub repository, on its infrastructure, for free. If my repository fits a few simple profiles, such as a Rails app that deploys to Heroku, poof! Some very simple YAML in your repository:

    I like that YAML. It is declarative. It contains data. It fills in the blanks that Travis provides. But the real measure of a tool comes when you get off the happy path. You can do just about anything in Travis; just call out to a shell script. Here’s a small piece of one of my .travis.yml files:

    It has shell commands. Shell syntax for an if-condition. And that infinity of flexibility, a call to a shell script. That travis-build.bash script happens to contain four functions, eight conditionals and (if I’m reading it correctly) up to seven program calls.

    This is programming, OK? As soon as your YAML calls out to a shell, it is not declarative. It is imperative. Or a mix. 😕

    This is programming, but my YAML and Bash do not qualify as software. Bash is a scripting language. It is designed to glue programs together, not to construct programs; it lacks composable modules with encapsulation. I can live without types, but in Bash you don’t even declare function parameters! And it’s full of pitfalls. Use Bash for what it’s good at: calling other programs. As a fallback for flexibility that we lack at a higher level, Bash does not shine.

    YAML is not a programming language, although it does support variables and has its share of pitfalls. Until the YAML contains commands that get executed; then it becomes a program, with even fewer options for error-handling or clear naming than in Bash. Please use YAML for data, not for code.

    There is a gulf between programming and software. We have standards for software: it has design—domain-driven design that we’ve worked through with experts. It has automated tests. It has modularity. It uses libraries and abstractions. I want to use a language designed for all this.

    Skip ahead to Jenkins. This is more widely used than Travis for more extensive delivery flows. It can run on-prem. There are hundreds of plugins available. So many blanks to fill! So many options! And now, there’s pipeline as code. For one thing, you can write a piece of Groovy to define which repositories and branches get a pipeline. That makes Jenkins more responsive to new repositories and branches. It’s a step in the direction of responding to new projects.

    The people building Jenkins recognize that delivery needs to be controlled by the people who control the code. Instead of constructing each repository’s build in a GUI (hello, TeamCity), we put a Jenkinsfile in each repository. That file is in Groovy. Groovy is a programming language with all the modularity and libraries of the JVM behind it. Except, you don’t get all that in your Jenkinsfile. You’re limited to what is available when Groovy runs within Jenkins. If you want consistency from one repository to another, you can install custom-shared libraries in Jenkins and call them in each Jenkinsfile. Rolling out change is challenging; any of those disparate Jenkinsfiles can break after the shared library changes. It’s pretty fragile and still limited. It’s progress.

    This is a step up as programming, but I still wouldn’t call it software. When I write an application, I work in more than a programming language; I work in a language system. A language system includes dependency management, frameworks, linters, build systems, editors, community and the whole ecosystem of libraries available in the language. Great language systems exist around the JVM, Node and .NET, for instance. Groovy that you run can participate in the JVM language system, but Groovy running within Jenkins does not have this access. The Jenkinsfile DSL is still fill-in-the-blank.

    What We Need

    Conceiving delivery as software invites us, development team members, to sit down with the local experts on our deployment environment and security and other concerns. It invites us to have a conversation: What does delivery mean for this application, on this team, in this organization? Where do we want consistency and variability? Then we can create and encode a model—a model of the domain of software delivery, within the context of our business and our environment. We can brainstorm events such as a push or a new repository and what we want to always happen. We can divide the parts into team-specific, organization-specific and community-wide (open source).

    Instead of, “How do run the build? How do we run tests?” we can ask, “What needs to happen after a code push?” And we can think carefully about how we work, how our software works and how our business works with it. We are the domain experts in our own delivery.

    This is the top reason I want delivery as software from the top down. By thinking about delivery as software, we think rigorously about our work as software developers. And we get better at it.

    I want more than delivery-with-some-code. I want delivery as software. Controlled top-down by my team, with a rich ecosystem of libraries, with frameworks and services for the parts that are common in the community. I want delivery that’s event-driven, that’s testable and that communicates with me when it’s time for a decision.

    We’ve come a long way since the days before automated deployment. Our existing continuous integration/continuous deployment solutions have served us as far as they can. Incrementally better (fill-in-the-blank) won’t take us to the next level of software delivery, and it won’t help us reach the next level as software developers. It’s time to break out of this local optimum.

    Let’s Go

    To this end, we composed the Software Defined Delivery Manifesto. Say what you want about manifestos: They have a certain flair, a certain impact, a certain dramatic longing for a better world. That is what we are expressing here. Yes, it’s a better world only for development teams, and only for development teams in complex organizations. But we matter! Software has a huge impact on the world, and to make that software better, we need to get better at delivering it. Let’s push past what we’re used to. Accept that our job is not writing code, but running useful software in production. Let’s get better at delivery by modeling it in software.

    If you’re in, join the movement. Sign the manifesto.

    — Jessica Kerr

  • DevOps and Security: Focus on Importance

    DevOps and Security: Focus on Importance

    Why have I written “DevOps and Security” and not DevSecOps or one of the other names that floats around? Because this post is aimed to apply to everyone—not just those far enough along to have melded some of their security practices into DevOps.

    Note: After I wrote this article but before I posted it, Bill Doerrfeld wrote this excellent example/solution post. It’s worth a read.

    From the beginning, DevOps has struggled with a couple of touch points that don’t give themselves easily to the “frenetic movement” of DevOps. Security is one of those items. If your organization does manual vulnerability assessments, it is unlikely that this testing slips well into the DevOps process chain.

    Most organizations that are dead set on making DevOps their primary dev/test/deliver platform have simply put limitations on security—limiting what long-running processes can be part of DevOps or dropping unaccommodating processes altogether. Some spectacular failures have occurred because of this type of thinking—and more will come—but for many the benefits of DevOps outweigh the risks. Will I get flamed for this paragraph? No doubt. That doesn’t make it untrue.

    Given that IT has almost never given security the full leeway/authority that they want—and in shops where IT did, business often stepped in to say no—this really is not a massive change from how we have always done business. Just in the modern development environment, where a ton of libraries come from outside and configuration is software or data, there is a greater risk from running roughshod over the security team.

    So what can security do to minimize the risk? Start looking more at enterprisewide and architectural risk. Accept that app or app portfolio team X is not going to give you time/resources to thoroughly vet their product and focus on things such as configuration files and malicious code embedded in that external library “Bob’s Really Good GIF Drawer™” that the team insists on using. Focus on the database configuration being in GIT or a shared (public/private) repository and what mischief might come about should attackers get at that repository. Run some of the increasingly sophisticated checkers against external libraries and review the results. As has been the growing case for years now, use automation to at least minimally check apps for things such as SQL Injection, but focus actual man-hours in places that might impact more of the organization. It might be worth the fight to get a full-on security review for applications or an application portfolio that touches the customer database, but perhaps not so much for the app used to schedule a conference room, even if customers are using it (unless it touches the customer database, of course; then see the first part of that statement).

    Worry about network configuration as code, database configuration as code and the whole slew of unique security issues that come from public cloud. They’re manageable, and there are tools to help. Just make sure you have it down, because architecture is going to be the new target. A hacker doesn’t have to hack your DC if you left a public cloud storage bucket misconfigured and the data they want is in that bucket.

    In too many organizations, the CISO is increasingly treated as chief compliance officer (assuming compliance does not interfere with DevOps cycles) with less to do with security and more to do with legal protection should security fail. Don’t be that organization. Security doesn’t have to be perfect; it just has to make you a hard enough target that only someone who really has it in for your company will keep trying.

    As for Devs doing Agile and Ops doing DevOps, as has been true from the beginning, some of the security burden needs to fall to you. Security doesn’t have its hands in what you do every day, so ask them for guidance, learn from them; make it so they need to be active in every step, then include them in every step, because the security environment changes faster than almost anything else in IT. And when you are implementing monitoring, include security monitoring. In most DevOps shops, the question isn’t, “What can we monitor?” but rather, “In this wealth of data, what do we want to monitor?” Well, the answer should include, “What security thinks will help protect us and our customers’ data.”

    As automation continues to increase, this tension will continue to ease, and focus can increasingly shift to locking down the really important bits such as database configurations and repositories. Until then, keep fighting the good fight and protect your customers’ ass(ets).

    — Don Macvittie

  • Upskilling: The Enterprise DevOps Skills Survey and Report

    Upskilling: The Enterprise DevOps Skills Survey and Report

    There has been a lot of recent reference to “T-shaped” IT professionals—individuals whose core competence (the stem) is supplemented by a broad range of other knowledge including soft skills (top of the T). T-shaped talent is in such high demand with a limited supply that recruitment efforts have become very competitive for those with upskilled and cross-skilled transformational know-how.

    Unfortunately, the migration from a deeply skilled specialist to a T-shaped practitioner is leaving many confused about what skills they should be acquiring and hiring and when. That’s why DevOps Institute (DOI) recently launched the 2019 “Upskilling: Enterprise DevOps Skills Report” community survey to help individuals and enterprises better understand the current and future state of DevOps skilling across the global IT community. Using data science coupled with hiring manager interviews, DOI’s goal in fielding the report is to provide tangible insight into why and where IT practitioners, managers, leaders and business stakeholders should focus their efforts in growing personal and organizational skills portfolios.

    Eveline Oehrlich, a former vice president and research analyst at Forrester, is bringing her data science expertise as the lead analyst for the report. Founding Platinum sponsor Electric Cloud and founding Gold sponsor Cloudbees are also sponsoring this important project. The “Upskilling: Enterprise DevOps Skills Report” will be a year over year project, and the results will be published in Q1 2019.

    The global survey will remain open until Dec. 7 and can be accessed through the following link: https://www.research.net/r/K9WD2XC

    We encourage everyone in the DevOps community to complete the survey so that the data samples truly reflect the global state of DevOps skills.  Any organization that has at least 20 people complete the survey will get a personal snapshot of the data results. All respondents who complete the survey will be entered into a drawing for four $100 Amazon gift cards.

    — Jayne Groll

  • Survey Says: Digital Transformation is Hard

    Survey Says: Digital Transformation is Hard

    IDG and Insight Datalink recently conducted a survey into how companies were doing on their digital transformation journey. Like so much in technology these days, it is easy to feel as though you’ll be left behind if you aren’t well on your way with digital transformation.

    You’re not.

    Who Are You People, Anyway?

    The survey had decent industry distribution and was focused on director level and above in larger organizations, with more than a third of respondents in financial services or high tech. So in short, a third of respondents are the very organizations most motivated to implement a digital transformation project.

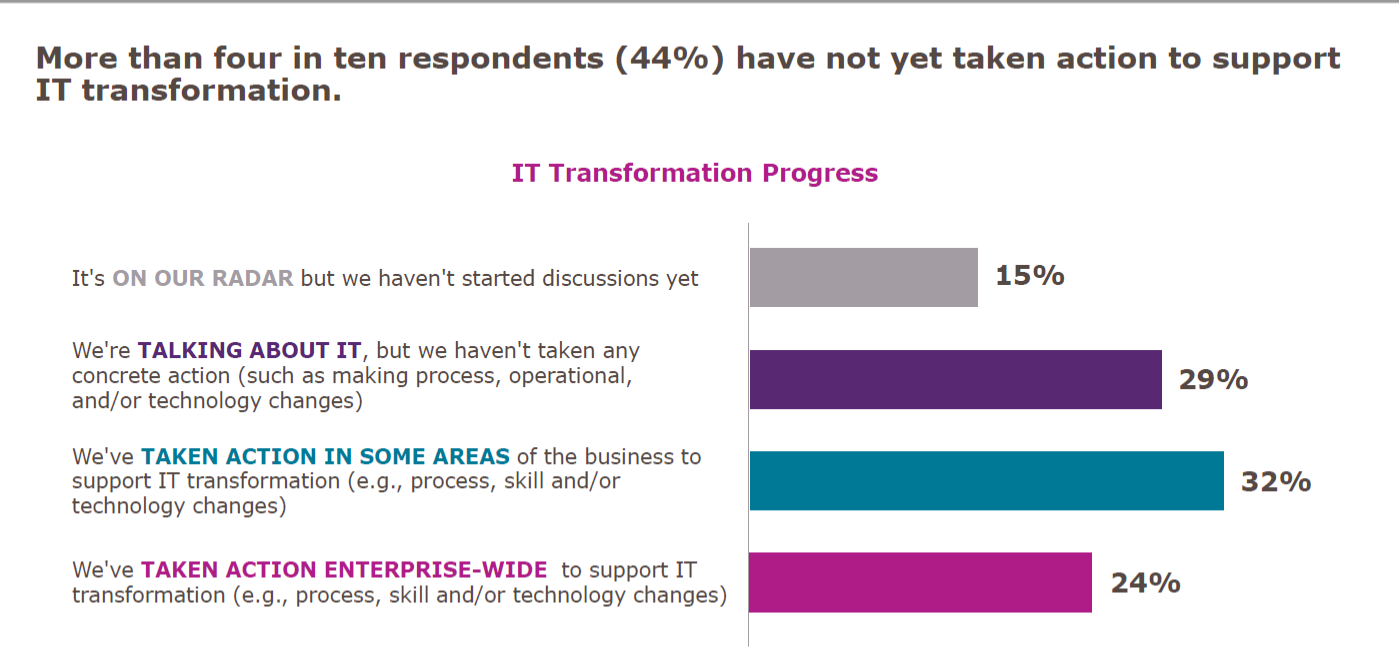
    Nearly Half of Respondents Haven’t Even Started

    Let’s get the easy one out of the way first: The survey showed that a significant proportion of companies had done nothing more than talk about digital transformation.

    Adding up “It’s on our radar” and “We’re talking about it,” we get to 44 percent of respondents who haven’t even started. In fact, due to the nature of digital transformation, I would argue that less than 1 in 4 are actually doing it. Then there is the 24 percent who are undertaking enterprise-wide transformation: You can convert projects, but that isn’t transforming the way you do business. It is a start, so I admit this is well and truly a debatable statement, but true transformation is cross-app, cross-team, agile and locale-mobile.

    Why So Small?

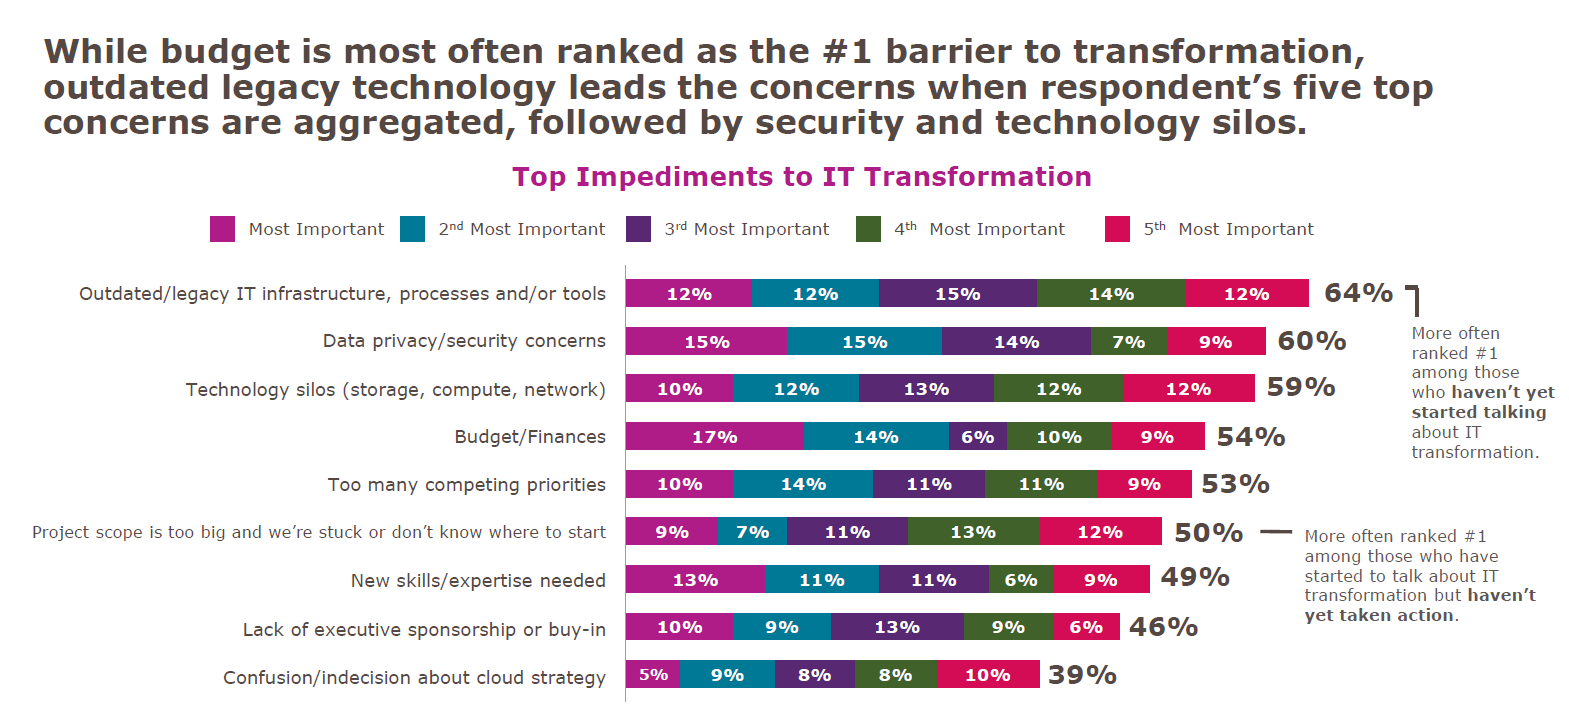
    Since we frequently hear about digital transformation and how important it is, “Why are the numbers so low?” is a valid question. The truth is that transformation of complex infrastructures is difficult. There just isn’t any way to get around that fact. When there is a mainframe with heaps of data and a midtier that often has replication of mainframe functionality on it, then separate apps that are doing web-based transactions in (insert language here, but normally Java in the above environment), there are many parts that are complex, and something as simple as moving and/or rationalizing data stores can be majorly complex.

    But I won’t go on and on here, I’ll simply show you what IDG found.

    Looking at mainframe toolsets in particular, there have been massive steps forward over the last several years to make them more compatible with modern development and deployment practices. But making use of those changes often requires updating systems that are not otherwise broken. And there is always the risk that such updates will break something. The more research an organization does into modernization tools, the more comfortable they are that there is a valid path—but that doesn’t make it easy when it is added work.

    Data privacy also ranks high, and that is because IT has been dealing with locking down data in a data center for ages. Additionally, some spectacular configuration mistakes in public cloud datastores have made us all gun-shy. There are solutions to data security in public cloud from a variety of companies, but that doesn’t change that we’ve all followed “due to bucket misconfiguration” stories while cringing.

    Technology silos are a fact of IT. There can be some breaking down of those silos, but they are unlikely to disappear completely. The EMC specialist or Cisco specialist are unlikely candidates for elimination in the quest for reduced silos. (I just picked two roles whose knowledge sometimes astounds me—both for the depth these people can have, and for the requirement that they need that depth.) Working your network and storage teams into the digital transformation without undermining the thing that makes them valuable—their silo-specific knowledge and insight—is a challenge that can be achieved, but not by “breaking silos”; more like, “increasing communications between silos while reducing silo behavior.”

    If You Dive Like That, You’ll Stall!

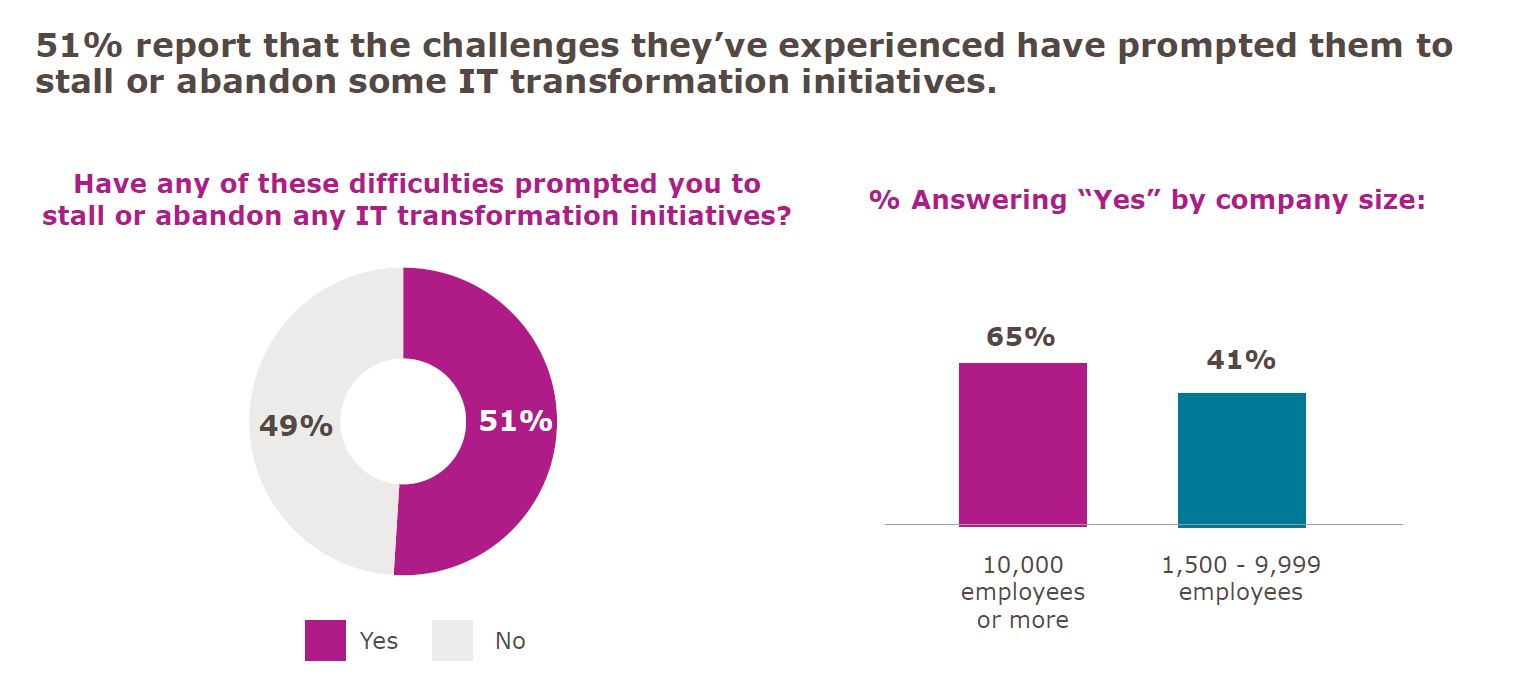
    The last point in this survey that I’d like to address is the “Stalled Digital Transformation Initiatives” slide. (There is a ton of good data in this survey, but these three fit together really well, so I pulled them out.) The fact is that if you are attempting to transform a complex system, you will have wins and losses. Some things will work out better than you planned, while others will not work out as you had hoped at all. I believe that, due to the question’s wording, that is what we are seeing here:

    Yes, 51 percent would be appalling in any other context, but the question was, “Have any of these difficulties prompted you to stall or abandon any IT transformation initiatives?”

    Any is a big word. In fact, any is the largest word in that question. If it were worded with “your” instead of “any,” I will guess the positive answers would be a limit approaching zero.

    If you pronounce a large reorganization and implementation of a slew of new processes, statements such as “that doesn’t fit our infrastructure” are going to shake out. That doesn’t spell doom and gloom for digital transformation; it is simply another obstacle to overcome. Dropping it for now, while focusing on the more viable portions of the plan is common sense, unless whatever isn’t working is core to the transformation. Then it still causes you to stall while figuring it out.

    Honorable Mention

    On average, respondents said they expected more than one-third of their digital transformation activities to be conducted by third parties. That’s a big chunk. Not “off-shoring” big, but still a large portion of work they expect to outsource to get the job done.

    So. Much. Typing.

    Okay, I’m about to shut up now. The takeaway is pretty straightforward. Contrary to hype, you’re not behind on your digital transformation. It’s a tough job, and knowing what you hope to get out of it before starting will help you to continue when things get rough. And they will get rough. The word “transformation” should tell you that. But keep going: There is better/faster/smarter/more mobile out there if you can stay on track, and because they are complex systems getting complex modifications, slow and steady does indeed win the race.

    And just remember, you’re responsible for those horribly complex, hard-to-transform systems doing what they do. Every day. Making them better and easier to manage is a no-brainer, but so is taking a moment to bask in the idea that you’re keeping things running in an environment that is complex.

    — Don Macvittie

  • DOES18 Las Vegas: Video Interviews, Day 2

    DOES18 Las Vegas: Video Interviews, Day 2

    DevOps Enterprise Summit 2018 (DOES18) in Las Vegas was a three-day bonanza of all things DevOps, with conversations spanning the entire DevOps ecosystem, from processes to tools to culture. In my two days at the Broadcast Booth (aka “The Fishbowl”), I had the pleasure of meeting with some very smart people and having some highly insightful conversations, all of which  are available for viewing on DevOpsTV.

    The second day’s conversations at DOES18 were as interesting as the first day’s, with topics ranging from DevOps culture to managing DevOps in highly regulated environments. Below is a recap of the Day 2 video interviews at DOES18 (Day 1’s recap is available for viewing here):

    Organizational Change

    Carmen DeArdo of Tasktop and Jon Smart, formerly of Barclays Group, stopped by to discuss tactics in ways to make change efforts possible in the enterprise.

    Capital One’s DevOps Update

    Jamie Specter, Aimee Bechtle and Abbie Gray of Capital One offered the latest updates from legal, tech leadership and product management in its DevOps journey.

    Work Management Systems

    Scott Prugh of CSG, Keanen Wold of Delta Airlines and Rosalind Radcliffe of IBM discussed how to break down inefficiencies for enterprise practitioners and management leaders who have multiple work management systems that their teams deal with every day.

    Project Management

    Laura Fay of TSIA discussed a product-led growth strategy where the buyer and customer journey is actively engineered into the product experience to deliver value and outcomes. She also explained how DevOps can benefit from expanding the definition of lead time from ’code to cloud’ to ‘concept to customer consumption’ and become a more integrated part of the business value flow.

    The Importance of Culture

    J. Paul Reed of Release Engineering Approaches and Dominica DeGrandis of Tasktop discuss what’s important about culture as part of a DevOps transformation journey, and why a DevOps culture should foster an attitude of open-mindedness, cross-pollination of skills and stepping out of comfort zones.

    DevOps in Regulated Industries

    Robin Yeman of Lockheed Martin and Ken Moser and Melinda Solomon of the U.S. Citizenship and Immigration Services discussed how DevOps can be applied in highly regulated environments and highlighted industry best practices.

    Transformational Leadership – Making Change Happen

    Christophe De Boeck of Kiwibank Ltd. and Steve Mayner of Scaled Agile highlighted considerations for the different ways to lead transformation in large enterprises.

    DevOps Trends – What Does the Future Hold?

    In this forward-looking discussion Eric Robertsonof CollabNet VersionOne, Robert Reeves of Datical and Derek Langone of XebiaLabs chatted about what the future holds for DevOps in the enterprise and what to be on the lookout for in the coming year.

    — Charlene O’Hanlon

  • The (Tool)Chains That Bind

    The (Tool)Chains That Bind

    As DevOps functionality continues to expand, we’re looking at a new vista for freedom of applications. Our apps can be moved around as we need them; we can build-test-deploy on the fly; and we have the ability to monitor whatever is needed. The price we pay is one we gladly take up: implementing new toolchains to drive the transition and getting those toolchains integrated into the entire development and operations process. Yes, we have an entire organizational side, too, but for this blog, we’ll talk about tools.

    Why Tools?

    Why are we going to discuss tools alone if this is about DevOps? Because it is a different set of problems to move from one organizational structure to another versus moving from one toolset to another. While DevOps is giving us independence from a lot of traditional infrastructure issues, the reality is that it is creating dependencies upon the very tools/toolchains we are using to gain that independence.

    Confusing? Let’s try looking at it differently. The new vendor lock-in will be DevOps tools. While they are freeing us from vendor lock-in on several fronts, you are unlikely to make a quick move from, say, Ansible to Puppet or vice versa. It can be done, and some organizations even do a little of both to make sure their options are open. But most shops will pick one and run with it, because that creates a single training and maintenance direction.

    Why Now?

    I (and others) have alluded to this issue in the past, but it is of growing importance as vendors start to take what should be cross-portable tools and customize them to limit portability. Container management, for example, is available on every major cloud vendor these days, but using the vendor’s bundled container service is convenient and more difficult to move away from. That is but one example of many.

    And the importance of these tools/toolchains is growing at the same time that their use is growing. Soon, in a DevOps-heavy shop they will be essential and locked-in as if they were cemented.

    So, What Are You Saying?

    Pick DevOps tools as if they will be there for decades. This is not how DevOps teams are encouraged to think, but you are building a DevOps infrastructure that, if adopted broadly in the organization, will be difficult to move away from to any significant degree. Just like these days you would need a driving reason to port thousands or hundreds of thousands of lines of code, DevOps scripts are growing and the number of DevOps scripts are multiplying. As you fold security, storage and networking into that environment, and build real-time reporting that you are going to rely on for years to come, make certain what you have is good, if not great. In many ways, DevOps thrives on “good enough” without thought to long-term futures, but the investment required to have a fully developed DevOps environment strongly implies that what an average enterprise is doing today will be what it is stuck with for a good long while. That’s not a place for “good enough” if you know there is better out there.

    It’s Not All Unchangeable

    Some bits of the environment can change over time, of course. Better data collation/integration technologies no doubt will take over for whatever you are using for reporting now, as well as AI-based solutions that can plow through the growing pile of machine-generated data to get a systemic view of what is happening. But for the most part, build it like you’ll be maintaining it for years to come, because much of the environment you will be.

    — Don Macvittie

  • American Express Uses DevOps for Better Breach Response

    American Express Uses DevOps for Better Breach Response

    It was 6 a.m. Saturday when the phone rang and awoke the American Express CIO. When the phone rings at 6 a.m., it is never good news. Never. This instance was no different: In this case, a third-party supplier just suffered a breach, and that breach would impact American Express cardholders.

    Immediately following that call, the CIO activated the company’s Cyber Crisis Response team. The job of the Cyber Crisis Response team is to help identify impacted cardmembers and prepare to reach out and assist any who have questions or need help regarding the breach.

    The need to respond swiftly to customers and provide them with the correct information is essential today, not only to stay on the right side of regulators, but to also help customers avoid fraudulent transactions and identity theft. When it comes to such effective data breach incident response, rarely does DevOps come into play—but the experience American Express shared at the most recent DevOps Enterprise Summit revealed just how better DevOps organizations can be when it comes to effective breach response.

    Within hours of the initial call between the CIO and the Cyber Crisis Response team, the primary breach response was divvied into three teams. The first team focused on what data breach bridge teams typically focus on: how to identify impacted customers. The second team was comprised of business and product owners, as well as customer care staff, whose objective was to take the findings from the response investigation and communicate them to American Express customers.

    The third team consisted of DBAs and system specialists, who understood all the systems, as well as enterprise architects, who might be able to quickly solve any technical challenges that arose.

    Getting to the Right Breach Information

    By 3 p.m. that Saturday, the first team determined that it could pull together all of the information it needed to identify affected cardholders. That was the good news. The bad news was that there would be tens of millions of production records that would need to be evaluated to make the final determination.

    If the team was to pull those tens of millions of records in production, the demand would start to slow those production systems. “How do we pull these records out of production without impacting our availability? That was the challenge,” said Aimee Cardwell, vice president of Engineering, Consumer Product Development at American Express.

    As the day moved forward and the teams worked to find a way to access those production records without impacting availability, one of the engineers on the team pitched an idea that would have been scoffed at in most organizations: Why don’t we clone production? But the novel idea wasn’t immediately rejected. The team on the call began to weigh the pros and cons of cloning production, and concluded that it could, in fact, clone production quickly, and all of the impacted card data could be aggregated without negatively impacting American Express’s servers and associated availability.

    After the team successfully cloned the production systems, it worked all night to identify the impacted card members, which required cross-referencing the cloned production system with other data stores, Cardwell explained.

    “What was really important here was the comfort level everyone had when it came to bringing up an idea that was really off the wall. And, in the end, they came together to make it happen because together the various teams had a string understanding of the people, technologies, and processes in place necessary to succeed,” said Chad Avery, director, DevOps implementation at American Express.

    It was now 6 a.m. Sunday and the teams had worked nonstop since the CIO’s phone rang Saturday morning. The teams managed to evaluate the relevant data from various systems and collected a list of potentially impacted card members. And after a careful analysis, they were able to determine who had been affected by the breach and who hadn’t.

    What made this success possible? Both Avery and Cardwell believe that it was the integration of business, product and technical teams. “The fact that we had business, product and technical teams working together in this incident was a huge win for us,” Cardwell said.

    Avery contended the ability for an organization to successfully integrate its technical, business and product teams makes the difference. If those teams hadn’t been working together from the beginning, he said, they may not have been able to find a solution and, if they had, it would have taken much more time to do so.

    Disclosure Day, and a Final Big Win

    It’s a good thing it worked out quickly. By Monday morning, the breached third-party was ready to go public with its data breach disclosure. That announcement would immediately impact not just American Express cardmembers, but those of most other credit card providers as well. Many customers would have pressing questions about whether their accounts were impacted, and, if so, what to do.

    Customer service lines had to be ready.

    That proved to be the final challenge that needed to be solved: How would customer service representatives know which customers calling were affected? Tight team integration and collaboration proved to be a deciding factor once again.

    The engineers on the product team had spent the previous 24 hours building a tool that they shared with American Express customer care professionals. When individuals called the customer care team, the tool could alert the team whether a customer was in the impacted group.

    The tool also came equipped with a data collection feature that would enable everyone to learn from the event and even prepare better for next time. “We want everyone to get better. We want ourselves to get better,” Cardwell said. “We want to know what percentage of customers who called were impacted, and what percentage of customers that called were not impacted. We wanted to know our response time on those customers. We wanted to know any other data that would help us to do better next time.”

    And it will have been that dedication to collaboration among technical teams, business units, developers, operations and security teams that enabled them to quickly and successfully manage a third-party data breach and prepare themselves to do even better next time. “They all were able to develop a solution quickly. They were able to identify the customer impact, design a solution, build it, test it and get it deployed. And, oh by the way, the teams did it in a weekend,” Avery said.

    — George V. Hulme