Category: Features

  • EraDB Launches Log Management Alternative

    EraDB Launches Log Management Alternative

    EraDB today launched EraSearch to provide IT teams with an alternative to open source ElasticSearch software for managing logs at scale.

    Todd Persen, EraDB’s CEO, said EraSearch is based on a modern database that decouples storage and compute. In this way, EraSearch can scale more efficiently than ElasticSearch, while providing IT teams with the same familiar construct for managing logs.

    Persen said EraDB also uses true zero-schema data representation, and an indexing engine based on machine learning algorithms, to enable EraSearch to scale better. This approach also cuts cloud and operational costs by as much as 30% and 70%, respectively, by relying, in part, on object-based storage systems to store log data.

    As IT environments become more complex and continue to scale, organizations that standardized on ElasticSearch are discovering that a platform based on decades-old search engine technology is not keeping pace with their needs.

    EraSearch provides an alternative, based on a commercial time-series database platform that EraDB created, to address such use cases as an alternative to database platforms such as InfluxDB.

    The question is whether IT organizations, that have relied on ElasticSearch for years, are ready to abandon an open source platform in favor of a proprietary platform, even if it provides a similar user experience. EraDB, however, is betting there are enough IT organizations willing to make that shift to justify its investment in EraSearch.

    Persen said one issue with ElasticSearch is that, as log volumes increase beyond a few terabytes, the platform becomes inefficient and difficult to efficiently scale. That leads to higher costs in terms of both raw storage, as well as all the manual effort on the part of software engineers, required to maintain the platform.

    EraDB, of course, is making a classic case for a proprietary platform over an open source platform: that open source, while free, often proves more expensive to support. Persen said EraDB decided to eschew the open source model altogether, because it is too difficult to prevent nullification of the benefits open source could bring to a small company by open source project forks.

    The ElasticSearch community, meanwhile, is roiled by Elastic’s decision to change the licensing terms under which it makes ElasticSearch available. Elastic is shifting away from an Apache license to a dual-license strategy that includes a Server-Side Public License, or SSPL, along with an Elastic License. That shift was made to help ensure more of the revenue generated by Elastic search winds up in the hands of Elastic, rather than cloud service providers, such as Amazon Web Services (AWS), that routinely launch paid services based on open source code. AWS responded to the Elastic move by announcing plans to fork ElasticSearch code that it will now curate.

    Regardless of how that battle ends, however, EraDB is making it clear it views its platforms as too critical to its customers’ IT operations to get caught up in a similar maelstrom over business models and associated licensing terms.

  • Dynatrace Extends Reach of Observability Platform

    Dynatrace Extends Reach of Observability Platform

    Dynatrace this week updated its observability and software intelligence platform as part of an effort to expand its reach across modern enterprise IT environments.

    Announced at the online Dynatrace Perform 2021 conference, the company’s namesake platform can now capture logs from Kubernetes and Red Hat OpenShift as well as Amazon Web Services, Google Cloud Platform and Microsoft Azure cloud platforms.

    In addition, Dynatrace is adding support for open source log data frameworks such as Fluentd and Logstash. Those logs can now be centrally viewed via a Dynatrace Log Viewer that enables IT teams to search, analyze and segment both real-time and historical log data.

    Dynatrace also added a Cloud Automation Module based on Keptn, an open source tool for automating configuration of observability tools, orchestrating code tests and quality checks. Keptn was created by Dynatrace and is being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    The company also launched a Software Intelligence Hub to make it easier to access more than 500 pre-configured integrations, as well as access tools for creating integrations without having to write code.

    Dynatrace also announced it has extended a previously launched Application Security Module to now include support for Node.js applications. In addition, the module includes the ability to enforce security policies against applications instrumented with its agent software, and offers extended capabilities to enable the detection of Kubernetes cluster vulnerabilities, as well.

    Finally, Dynatrace has added a Session Replay capability to its Digital Experience Module to enable IT teams to capture a mobile application experience.

    Steve Tack, senior vice president of product management at Dynatrace, said the company is moving quickly to add support for platforms and technologies widely employed within cloud-native applications to provide IT teams with a single platform through which they can manage monolithic and microservices-based applications.

    With the rise of microservices, IT environments are becoming too complex to manage without some type of observability platform. Historically, cost concerns limited IT teams to employing application performance management (APM) platforms, such as Dynatrace, only for their most mission-critical, monolithic applications. It’s now become apparent that observability platforms capable of correlating log and telemetry data captured from applications and infrastructure are required to effectively manage a modern IT environment.

    As part of that effort, Dynatrace is now collecting data from additional sources alongside the agent software it provides. That data is then fed into an observability platform, that Dynatrace has augmented with a Davis AI engine, to identify anomalies and other potential issues by employing machine learning algorithms.

    It’s not clear to what degree IT teams completely trust the recommendations surfaced by any AI engine. However, as platforms such as Dynatrace collect more data from an IT environment, the more accurate AI models tend to become. In fact,  IT teams that don’t have access to AI capabilities might soon be at a distinct disadvantage, compared to other IT teams that do.

    In the meantime, the battle for observability supremacy continues to intensify, as incumbent providers of APM platforms such as Dynatrace look to forestall a host of startup rivals, all promising greater visibility into IT environments at a lower cost. The challenge now is determining what level of visibility is achieved, and at what total cost.

  • New Relic Adds Visualization Tool to Observability Platform

    New Relic Adds Visualization Tool to Observability Platform

    New Relic announced today it has added a visualization tool, dubbed New Relic Explorer, to make it simpler for IT professionals to discover the root cause of issues that adversely affect application performance.

    Buddy Brewer, global vice president and field CTO for the Americas, New Relic, said the goal is to make it simpler for IT professionals to navigate and, ultimately, act on, all the metrics collected by the New Relic One observability platform.

    New Relic Explorer includes a New Relic Lookout capability that enables IT teams to drill down into telemetry data gathered from New Relic One, as well as other third-party sources, and a New Relic Navigator capability for determining the health of relationships between services, said Brewer. These capabilities make it possible to more easily identify correlations, abnormal history and traces that would be, for example, indicative of blind spots or unknown relationships between IT services, Brewer said.

    Just as importantly, IT professionals can more easily discover recent changes to an IT environment, which are most likely the cause of any new issue that is adversely affecting the IT environment, Brewer added.

    New Relic Explorer requires no configuration, and will be included as part of the existing New Relic Full-Stack Observability offering to give IT teams a single unified view of their IT environments, said Brewer.

    As IT environments become more complex, the amount of time spent looking for the root cause of an issue that might only take a few minutes to fix has substantially increased. As a result, organizations are allocating a significant amount of time to convene “war rooms” to identify the source of problems; those problems can now be more readily identified using New Relic Explorer.

    In general, Brewer said, New Relic remains committed to opening up the platform to external telemetry sources, including data collected using open source tools, such as Prometheus and OpenTelemetry agent software, both advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    New Relic, like providers of similar tools, has recently begun repositioning itself as a provider of an observability platform, rather than of application performance management (APM) tools, that provides insights into both applications and the infrastructure on which they depend. That approach promises to provide IT teams with more context any time an issue arises. As part of that shift, New Relic is making it clear that while it views its agent source as a richer source of telemetry data, its platform can consume relevant data wherever it can be found. New Relic will also remind customers that its agent software, and the other data collection tools it provides, are simpler to install and update.

    The tradeoff, of course, is cost. While open source software itself is free, the total cost of implementing and managing that open source software can be substantial. Regardless of approach, however, the days when IT teams only applied application monitoring tools to their most mission-critical applications because of cost concerns are coming to an end. It has become impossible to manage a modern IT environment made up of both monolithic and microservices-based applications without such capabilities.

  • How the SRE Role Is Evolving

    How the SRE Role Is Evolving

    In recent years, site reliability engineering (SRE) has garnered much interest. In 2019, LinkedIn listed site reliability engineer as the second most promising job in the United States. Now, in 2021, the role continues to grow and evolve within many organizations.

    Initially spearheaded at Google and credited to engineer Ben Treynor, the strategy seeks smarter accountability for application reliability. An SRE team sets service level indicators, makes error budgets for new features and uses tools like application performance monitoring (APM) to visualize performance insights, among other tasks. SREs are quickly becoming a key check to increase business output in response to new digital innovations.

    I recently met with AppDynamics Regional CTO Gregg Ostrowski to discuss the emergence of SRE and how the approach is evolving. In short, it appears SREs will only continue to grow in importance across more companies, adopting new tactics like chaos engineering, and diversifying their teams with new domain knowledge in response to increasing technological complexity.

    What is an SRE?

    Traditionally, organizations employed system administrators, or sysadmins, to maintain operations for large computing systems and services. However, this typically produced a dichotomy: product developers want to push new features, while operations teams (sysadmins) want to make sure the existing service doesn’t break. The split between developers and operations can be unhealthy and cause friction.

    Whereas sysadmin positions are detached from development and involve a lot of manual work, an SRE approach, on the other hand, takes a more engineering-focused approach to automate operations. Google’s SRE book, which has become a bible of sorts, defines the role as “What happens when you ask a software engineer to design an operations team.”

    So, what does an SRE do? Well, at Google, they are in charge of availability, latency, performance, efficiency, change management, monitoring, emergency response and capacity planning for the services they operate. At Google, they spend no more than 50% of their time on traditional “ops,” like tickets, on-call and manual tasks, and are encouraged to use the remaining 50% of their time to develop automation that will replace human operations labor.

    5 Ways the SRE Approach is Evolving

    It’s been a few years since Google introduced the SRE concept, and naturally, unique iterations have popped up within other enterprises. But, on the whole, where is the concept heading? Ostrowski sees SREs evolving in a few key areas: growth and maturity, increased diversification with domain-specific experts and new monitoring tactics.

    1. Increased Adoption

    First, not all companies have embraced an SRE model. A recent study by Blameless found “… 50% of respondents employ an SRE model with dedicated engineers focused on infrastructure and tooling, or an embedded model where full-time SREs are assigned to a service.”

    The SRE model is gaining momentum, but there is still room for greater adoption. There is also room for internal growth. Ostrowski sees a single SRE team as a single point of failure. “It needs to be a whole department,” he said.

    In addition, SREs are gaining a more prominent voice at the table, influencing feature rollout. “With proper and mature SRE involvement, teams can’t willy-nilly deploy,” he said. Ostrowski views these teams as maintaining a critical balance between business risk and introducing new technology.

    2. Larger, Diversified SRE Departments

    Many companies are experiencing rising user demands, and thus must rapidly scale their application networks. Simultaneously, there has been a Cambrian explosion of deployment types — systems could be using any assortment of legacy infrastructure, mainframe, microservices, cloud environments and multiple cloud vendors. “The complexity and topology of the IT space has grown substantially, with many interdependencies,” Ostrowski said.

    Due to increasingly complex technical stacks, SRE must now cover many domains. Thus, SRE departments will likely require a more diversified team of domain experts. Ostrowski likens SREs to “Navy SEALs of the IT team.” For example, assigning them with experience navigating the nuances behind Google Cloud Platform (GCP) or Microsoft Azure could maintain service reliability in respective clouds.

    Individuals’ personality matters for suitability to SRE, too, said Ostrowski. The role requires a specific type of innovator who considers the repercussions of code, and loves improving processes and performances.

    3. New Testing Tactics Will Emerge

    Ostrowski also foresees SRE departments introducing new monitoring and testing approaches to maintain reliability. One of these is chaos engineering, which champions the idea of intentionally breaking application systems. Different strategies will undoubtedly emerge to help drive user experience (UX) and ensure that performance is always top of mind.

    4. Businesses Rely on SREs to Mitigate Risk

    All things will inevitably fail, at some point. SREs accept failure and learn to manage it, designing repeatable operational mitigation structures. “As companies become reliant on the consumerization of IT, business is dependent on SREs to drive business,” said Ostrowski. This reliance will likely increase as businesses tap SREs to maintain stability.

    Whether it’s reducing mean time to repair (MTTR), programming service level indicators to monitor website load time, or forecasting error budgets for new feature introductions, SREs will be increasingly relied upon to maintain business stability and high performance.

    “The SRE mindset is about coming to terms with a blameless environment,” said Ostrowski. They can help “balance a risk between the business and application team,” described Ostrowski.

    5. SREs Steer UX

    In this digital-only environment, “The application has become the business,” described Ostrowski. If the application is core to the business, monitoring the user journey is necessary to improve it. Ostrowski believes SREs oversee a unique territory that could produce valuable business insights too.

    In addition to monitoring uptime to ensure URL response times meet SLAs, SREs could track UX-related insights, such as conversion rates or cart abandonment percentages. Tracking such analytics and setting standards baselines could help pinpoint problems affecting UX. It could also assist product development in designing better-performing software.

    Final Thoughts

    “Anything that you do more than twice has to be automated.”
    -Adam Stone, CEO, D-Tools

    Traditional operations teams are typically detached from product development and are culturally very different. However, within an SRE approach, operations instead aim to run systems that automate work typically performed manually by sysadmins.

    In this brief introduction, we barely scratched the surface of the topic. And of course, each company is unique in its approach to hybridizing product development and operations. DevOps tenants are closely aligned with SRE — often they are intermixed or one and the same.

    Ultimately, truly reaping business value from this approach will depend on breaking down silos and opening conversations — or at least automated notifications — between disparate units. Only then can operations and development coexist in the most productive way.
  • Survey Shows DevSecOps Progress in Larger Organizations

    Survey Shows DevSecOps Progress in Larger Organizations

    A survey of 250 U.S. and UK large enterprises with more $1 billion in revenue conducted by Security Compass, a provider of a platform for automating security tasks as application are developed, finds three-quarters (75%) have implemented DevSecOps processes on current application development projects.

    Rohit Sethi, CEO, Security Compass, said the State of DevSecOps Report published today makes it clear more organizations are starting to embrace security by design as they develop their applications. Nearly three-quarters of respondents (73%) said their organizations follow a “by design” approach that enables them to proactively address cybersecurity and regulatory compliance.

    The primary reasons respondents cited for embracing DevSecOps best practices were to improve security, quality and/or resilience (54%), followed by the ability to bring applications to market faster (30%). One of the misconceptions about DevSecOps is that it slows down application development and deployment. However, Sethi said, in practice, DevSecOps enables organizations to address security and compliance issues that would otherwise result in an application not being promoted into a production environment. Almost three-quarters of respondents (73%) noted that manual security and compliance processes slow down code releases. A full 96% said their organization would benefit from the automation of security and compliance processes.

    The biggest DevSecOps obstacles cited by survey respondents included technical challenges (60%), followed by cost (40%), insufficient time (39%), lack of education (38%), lack of skills (36%) and organizational inertia (35%).

    In terms of deploying applications, the biggest reasons cited by the 51 C-suite executives that participated in the survey were insufficient automation and lack of tooling, at 51% each. Organizational barriers came in a close third (50%).

    In the longer term, Sethi said it’s clear most organizations are shifting toward zero-trust architectures to make their application environments more secure. However, achieving that goal across a broad application portfolio will require more investment in both automation and, eventually, various forms of artificial intelligence (AI), said Sethi.

    It’s not clear to what degree smaller organizations will have the tools and resources required to fund adoption of the automation platforms needed to advance DevSecOps more broadly. There’s more awareness of DevSecOps than ever. The challenge is the tools and processes required to achieve it are not uniformly being pushed into the hands of the individual developer. In some cases, organizational leaders are encouraging developers to embrace DevSecOps without any practical guidance.

    Eventually, of course, every organization will embrace DevSecOps best practices, but the real question is, at what rate? The number of applications organizations are rolling out continues to accelerate, but reliance on DevSecOps best practices to ensure security and compliance remains uneven, at best. Larger organizations that have the resources required to fund these initiatives tend to be further along in their adoption journey. However, there is no correlation between organizational size and the ability to build and deploy secure applications. After all, a smaller organization may make up for what they lack in resources with a greater commitment to DevSecOps best practices.

  • BluBracket Community Edition of Secrets Discovery Tool now Available

    BluBracket Community Edition of Secrets Discovery Tool now Available

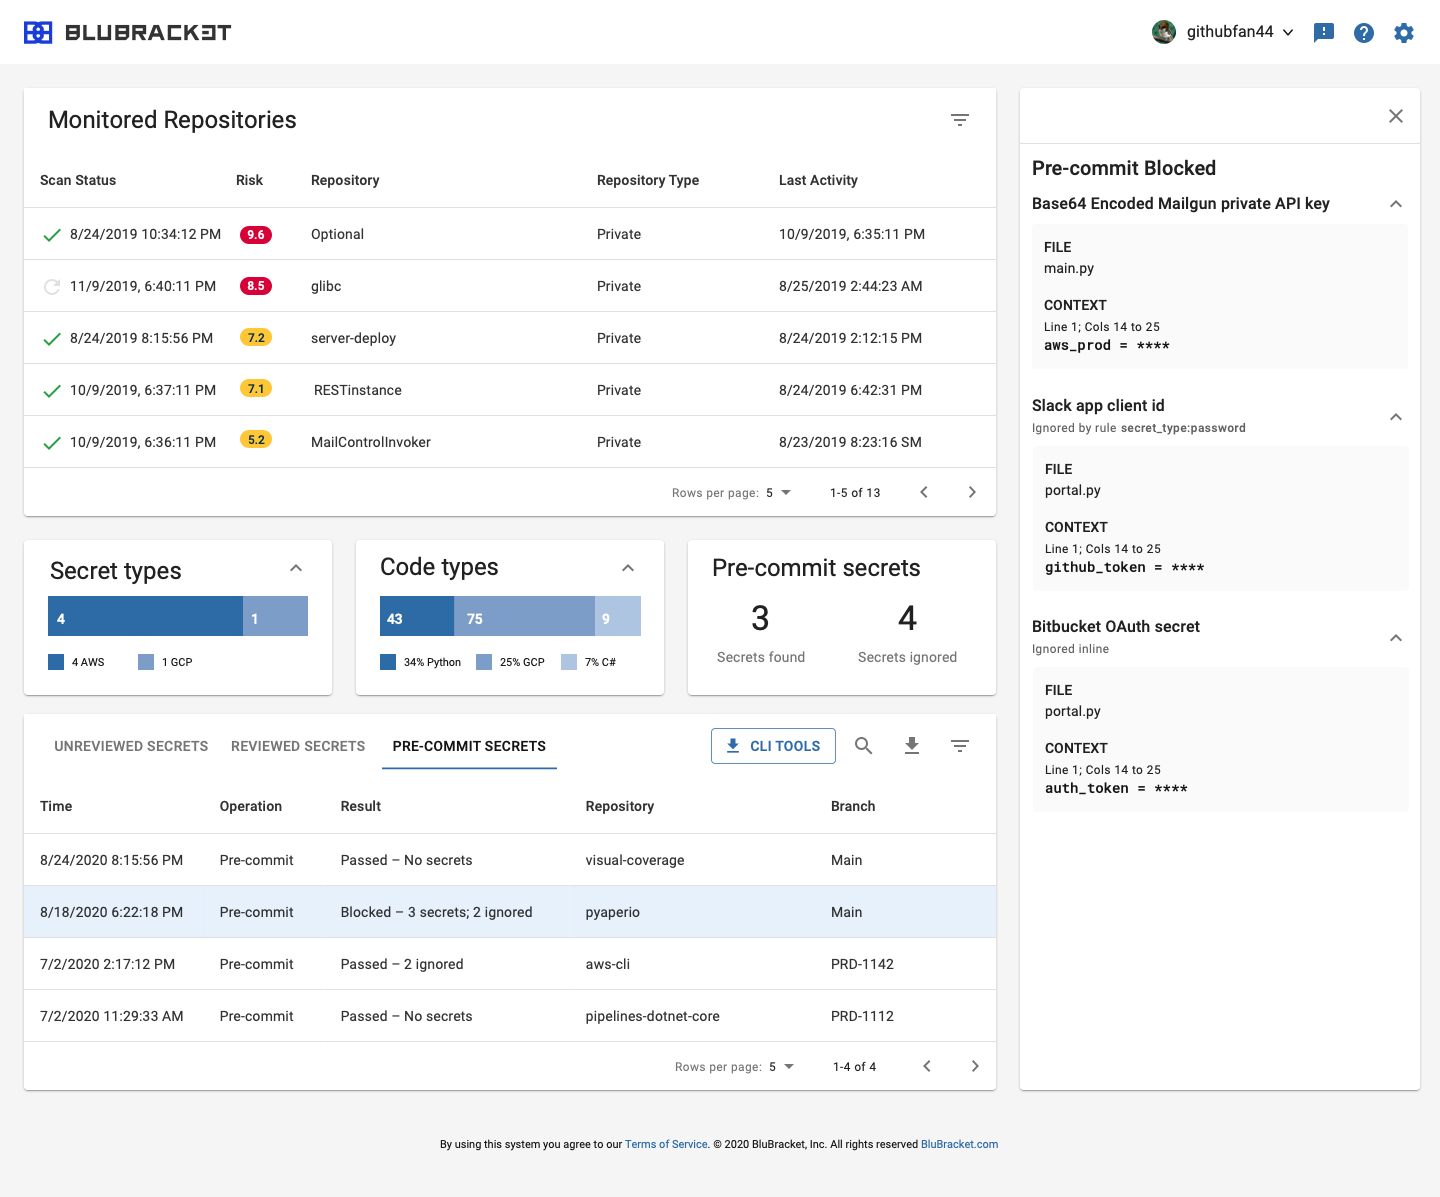
    BluBracket today announced general availability of a community edition of a tool that employs machine learning algorithms to discover passwords, tokens and other security vulnerabilities in code.

    Prakash Linga, BluBracket’s CEO, said application secrets stored in code enable cybercriminals to compromise applications in ways that can impact an entire software supply chain. The community edition of the company’s namesake tool scans commits to determine if any new risks were introduced, and will then block the staged files from being committed. It works with any continuous integration/continuous delivery (CI/CD) platform or integrated development environment (IDE) that supports pre-commit hooks, including VSCode, Jetbrains IntelliJ and PyCharm.

    Developers are then presented with a risk score based on the number of secrets discovered in their code. For example, an active token for Amazon Web Services (AWS) would receive a high score, while a a password in a test environment would be rated low.

    The Community Edition of BluBracket can be accessed via GitHub. The free version of BluBracket can be employed to scan up to 10 repositories and sharing reports in real-time, covering more than 50 types of secrets that might be employed using any programming language.

    Linga said BluBracket also cuts down on false positives by combining machine learning algorithms with a built-in rules engine. In contrast to open source tools, BlueBracket generates far fewer false positives, said Linga.

    Linga said the Community Edition is intended to help foster adoption of DevSecOps best practices among individual developers, in hopes that when those developers are hired, their organizations eventually license the full instance of BluBracket. The company views its tools as being complementary to both tools that surface vulnerabilities in code as well as secrets management platforms, which are often not employed as widely within an organization, Linga said.

    In the wake of recent high-profile breaches that embedded malware in widely-distributed applications, there’s increased focus on securing software supply chains. In some of those instances, Linga said, it’s probable cybercriminals discovered passwords and other secrets that were inadvertently exposed in code.

    However those breaches were enabled, it is apparent cybercriminals are becoming more adept at exploiting a weakness in one application to inflict maximum damage across an entire environment. It’s hard to say exactly what role secrets discovery is playing, but cybercriminals tend to prefer the path of least resistance when it comes to exploiting application vulnerabilities.

    Of course, the hope is that adoption of DevSecOps best processes will reduce the number of breaches by shifting responsibility for cybersecurity further left toward developers. However, that’s difficult to achieve without finding the simplest way possible of getting the security tools required into the hands of the developers that need them most.

  • Sauce Labs Acquires AutonomIQ to Advance App Testing

    Sauce Labs Acquires AutonomIQ to Advance App Testing

    Sauce Labs is acquiring AutonomIQ, a provider of a scriptless test automation platform based on machine learning (ML) algorithms.

    Matt Wyman, chief product officer for Sauce Labs, said the acquisition of AutonomIQ will play a critical role in enabling Sauce Labs to push testing further left toward developers and, ultimately, “citizen testers” that are becoming part of the DevOps testing tool chain.

    The acquisition of AutonomIQ comes on the heels of the company announcing its intent to acquire API Fortress, an application programming interface (API) testing platform provider. Terms of neither acquisition were disclosed.

    Wyman said the rise of DevOps coupled with an increase in the volume of applications being developed using low-code tools are the primary drivers of a need to shift testing further left. As more citizen developers are building applications, they require access to a testing platform that doesn’t require them to know how to write scripts to test applications, said Wyman.

    The AutonomIQ platform employs machine learning to understand, for example, natural language descriptions of test cases or captured mouse clicks. It then generates synthetic data and test cases that can self-heal when an application changes, said Wyman.

    That approach to testing is more feasible in software-as-a-service (SaaS) environments, where a custom application based on a platform such as Salesforce, ServiceNow, Workday, Oracle or SAP doesn’t tend to change as radically as an application being built from the ground up, Wyman said. Those classes of applications will still require either developers or a dedicated team of testers to build tests using scripts, said Wyman.

    In fact, Wyman said testing those applications is becoming more challenging in the age of microservices. The API Fortress acquisition addresses that issue, because microservices are dependent on APIs to communicate with other microservices, said Wyman. In general, Wyman said Sauce Labs is now moving beyond being focusing only on functional testing of user interfaces.

    It remains to be seen how quickly testing will move to the left. Developers are being held more accountable for the quality of their applications, so testing integration within the application development process has increased. This has led to application testing becoming more tightly integrated with continuous integration/continuous delivery (CI/CD) platforms. Less clear is to what degree those efforts might have reduced the burdens of a dedicated application testing team that typically evaluates applications after they have been constructed.

    Exactly where and how citizen testers are being incorporated into those processes is also unclear. In theory, citizen testers can bring more business process expertise to the testing process. Getting individuals with that level of expertise to make time to participate in application testing while an application is being built can be a challenge.

    Regardless of approach, however, it is already apparent that machine learning algorithms, along with other forms of artificial intelligence (AI), will play a much larger role in application testing in the coming months and years.

  • Amid COVID-19, Developers Struggle to Keep Pace

    Amid COVID-19, Developers Struggle to Keep Pace

    It’s been a wild ride for digital innovation. It’s also been a stressful year for developers. At most organizations, the pandemic has increased reliance on digital experiences (and its programmers) exponentially. IT spending is rising, and competition is skyrocketing. More than ever before, the pressure is placed on developers to meet rigorous demands.

    A recent study by Couchbase revealed how developers are revolutionizing digital transformation efforts throughout the COVID–19 crisis. Yet, this output may not be sustainable. The 2020 Tech Lead Survey, which surveyed 450 senior IT decision-makers worldwide, exposed stressors for development teams, which, if not mitigated, could easily result in fatigue and burnout.

    So Much To Do, So Little Time

    Some digital transformation efforts that were slated to take five years have had timelines reduced to a matter of months. In this unprecedented era, flexibility is an indispensable characteristic to adapt to change. In fact, 63% of respondents said that flexibility to change direction on a whim is critical to meeting digital transformation goals.

    But, extreme flexibility comes at a price. Forty-nine percent of respondents indicated their development teams have been asked to do too much in too little time. As a result, 40% of respondents said their development teams were behind schedule with their current projects.

    “In a year when organizations have had to struggle to adapt to new decentralized ways of working and rapidly evolving markets, developers have come under severe pressure to help their organizations adapt,” said Steve Yen, co-founder of Couchbase.

    It’s apparent that developers are under escalating pressure. If the weight continues to pile on, exhaustion could bring overall production to a grinding halt. At least leaders realize who is driving digital innovation — 92% acknowledge developers are the unsung heroes of current digital transformation initiatives.

    Lacking Clear Direction From On High

    Eighty-six percent of respondents experienced challenges with their development teams. However, this does not wholly reflect poorly on developer inabilities — managers have a responsibility to set more explicit guidelines.

    Another obstacle: goal setting. Forty percent of respondents reported that setting clear, measurable goals for their team is a serious challenge. In addition, ensuring developers use the right technology, and ensuring teams understand overarching strategic goals were oft-cited pain points, as well.

    Resolving these issues will be critical to reducing developer complaints and remediating the stressors outlined above. “There needs to be investment in not just people, but also in the technology, management and communication that will help individuals succeed,” said Yen.

    Solution: DevOps

    So, where should architects direct new investments? Well, of the 450 IT leaders surveyed, 92% believe DevOps could have a revolutionary impact on their digital transformation efforts.

    The report refrains from offering specific technical advice, but makes the following general recommendations:

    • Don’t rely on legacy technology ill-suited for the tasks at hand. Current investments must be future-proofed for tomorrow’s scalability and integration requirements.
    • Don’t assume onboarding new tech will be easy. As digital innovation matures, new technology becomes more refined and specialized. As I’ve covered, whether it’s Kubernetes, service mesh or multi-cloud strategies, all require time to learn, along with some pretty specialized skillsets.
    • Take time to communicate with developers and understand obstacles. Be realistic with timelines, and do not ask for too much. Plan out project goals strategically, because haste does not equate to overall speed.

    Under pressure to perform and maintain flexibility, it makes sense that engineers are feeling the pressure of an amplified development pace. As that pace is likely not to decrease in 2021, finding methods to better support developers is key for long-term sustainability.

    At many organizations, a greater DevOps investment equates to operationalizing and automating processes for areas like microservices CI/CD, and networking and zero-trust security. It could also mean supporting developer workflows with some-code tooling. Other institutions are even introducing low-code tools to democratize the development process, intending to relieve some burden from professional engineers.

    Invest in Developers, Invest in Smooth Operations

    On average, development teams grew by 20% in 2020. As expectations for developers rise, so will investment in developers and the processes that support them. As teams move forward, it will be critical to gather feedback and understand what’s causing gridlock so that developers maintain agility and avoid burnout.

    In this competitive climate, choosing the correct people and systems to support new digital advances will be a competitive advantage. “Investing in [developers] in the right way will help them play to win,” said Yen.

    Since 2017, Couchbase has surveyed IT decision-makers on the challenges they face throughout their digital transformation efforts. Here, I highlighted the major takeaways from the 2020 report. You can view the full findings here.

  • OpenAPI Specification: Perception vs. Reality

    OpenAPI Specification: Perception vs. Reality

    The OpenAPI Specification (OAS) (formerly known as the Swagger specification) provides a way to describe and document REST APIs and their components. It includes details on endpoints, their operations, parameters needed for the operations, expected responses for every operation, authentication methods and even annotations. OAS is an easy format to learn and read, and can be understood by both humans and machines. As you might imagine, this kind of “accessible” documentation is useful and beneficial in a number of different use cases for both development and security teams.

    Developer Relationships With OAS

    For developers, OAS can be used to generate documentation for APIs. Proper documentation can help other developers figure out how best to integrate and use these APIs with their own application.

    Even so, many developers have a love/hate relationship with OAS. Let’s face it, documenting is a far cry from developing. Although it is easy to learn, the actual act of documenting is tedious, manual and time consuming. Frankly, it’s probably one of the least glamorous parts of a developer’s job, and, therefore, many developers only do the absolute minimum. As a result, OAS can be incomplete or, in some cases, missing entirely. Not to mention, when the API is updated, how often is the OAS updated, too?

    In the case of incomplete or nonexistent documentation, developers will muddle through with trial and error, even though this can slow down the development process.

    If out-of-date OAS proves an annoyance for dev teams, what’s the impact on security?

    Security’s Relationship With OAS

    OAS can be consumed by both humans and machines, and both are critical for security’s use of OAS.

    OAS helps security teams (humans) become aware that the API exists, since its documentation is often part of the CI/CD process.

    By examining an OAS file, a security team can understand what the API is supposed to do and, from that, determine if it conforms to or violates the organization’s security policy. As an example, security teams might use the OAS to make sure that authentication and authorization are being implemented correctly, and that sensitive data, like PII, is not being exposed.

    Security teams might also deploy tools (machines) that use the OAS to enforce policy based on what’s in the documentation. As an example, the OAS may specify that, for a particular parameter, a string should be expected; it should be no more than four characters and it should contain only letters and numbers with no special characters. By validating input based on what is defined in the OAS, security tools can check that the API does what developers intend it to do.

    This plan sounds great on paper, but …

    Perception versus Reality

    Imagine a perfect world, in which every API is well-documented as part of the development process. As that API makes its way through the development pipeline, it does so hand-in-hand with an associated OAS. At the appropriate time, before production, security is made aware of the API and the OAS, the team evaluates the details, validates that the API matches policy, gives the thumbs up and the API goes into production. Security and development teams live in harmony and everyone is happy.

    We don’t live in a perfect world. Instead, we must deal with questions such as:

    • Does the OAS exist? In the most extreme cases, the OAS doesn’t even exist. It was never created as part of the development process, so it can’t be used for any sort of awareness. These misses happen more often than you think, giving rise to the problem known as shadow APIs. These APIs slip through the cracks, and make it into production with no documentation at all. While you might be saying to yourself, “Our company would never let this happen!” you should also consider that numerous APIs are stood up by development teams as a test, as part of a beta or as a quick-and-dirty way to get something done. There are more of them than you think, and these shadow APIs create unrealized risk.
    • Is the OAS complete? In slightly less-scary territory, let’s consider an incomplete OAS. You might be saying to yourself, “We have a top-notch development team, well-defined development processes and strict policies around documentation. No API makes it into production without an OAS!” Perhaps, but the devil is in the details, and those details are often missed. I’ve worked with countless customers who have happily and confidently produced an OAS in which critical details don’t match the reality of the API. Sometimes they’re not complete. Sometimes they’re missing all together. The industry calls these missing details shadow endpoints. Yes, someone did produce an OAS, and security was aware of the API, but a lot of critical detail is missing.
    • Is it being kept up-to-date? Development cycles seem to be moving faster and faster, and as documentation is one of the least glamorous parts of a developer’s job, updates can be missed, dismissed or, at the very least, lag behind. We commonly see multiple versions of an API, and the OAS does not reflect the new capabilities of the latest version.

    While a non-existent or outdated OAS presents a modest concern for API visibility, it creates a substantial concern when trying to serve as the foundation for API security.

    You take a huge risk if you depend solely on OAS for security. More often than not, an OAS is not accurate, lacks critical details and is only as useful as the data you feed into it. Gaps, including shadow APIs, leave out critical details, making enforcement impractical.

    The inaccuracy of OAS leaves customers with two choices. You can either enforce security policies based on strict adherence, and risk blocking legitimate traffic, or you can enforce based on loose adherence and risk letting attacks through. In either scenario, your organization is unduly vulnerable, and significantly less secure than your dev teams intended or your security teams would like.

    OAS is Only a Starting Point

    OAS provides a great starting point for documenting your APIs. Don’t make the mistake, however, of basing your API security strategy on what’s in your OAS. It’s simply not accurate enough. Taking that approach will leave your company’s vital data and services at the mercy of API attackers who will quickly know more about your APIs and what they expose than your OAS does.

  • CloudBees Appoints New CEO to Drive Next Level of DevOps Growth

    CloudBees Appoints New CEO to Drive Next Level of DevOps Growth

    CloudBees announced today the appointment of Stephen DeWitt as its new CEO, taking over from Sacha Labourey, who will become chief strategy officer.

    Labrourey said after leading the company for the past 10 years, and after a banner year that saw the company generate more than $100 million in revenue, the time was right to appoint a new CEO to take the company to next level. The move also allows Labourey more time to focus on product development.

    Stephen DeWitt
    Stephen DeWitt, CloudBees CEO

    DeWitt most recently served as chief strategy officer for Automation Anywhere, a provider of a robotic process automation (RPA) platform. DeWitt previously served as the CEO of WorkMarket, a labor automation platform for enterprises, Azul Systems, a provider of platform for running Java applications and Cobalt Networks, a provider of Linux servers.

    Without committing to a specific initial public offering (IPO) date, DeWitt said the ultimate goal is to put the processes in place that will enable CloudBees to grow to $200 million in revenues and beyond.

    Achieving that goal will also require tighter integration across what has become a diverse portfolio of DevOps platforms, DeWitt said. The challenge is providing IT organizations with all the benefits of that integration without locking them into any specific component, DeWitt added.

    Going forward, DeWitt said IT teams should expect to see CloudBees invest more in artificial intelligence (AI) to further automate DevOps processes. There are many low-level DevOps tasks that could be automated using machine learning algorithms to reduce the level of friction DevOps teams often encounter.

    Becoming a $200 million company, however, is more difficult than becoming a $100 million company, DeWitt said. Not only does the company have to put the processes in place to grow, but CloudBees today faces more viable competition than it did when it first pioneered the adoption of DevOps best practices.

    The number of organizations adopting DevOps best practices is not only increasing, but organizations that have implemented continuous integration/continuous delivery (CI/CD) platforms also are employing them more widely. Instead of only being employed by pockets of development teams, entire enterprises are now using DevOps best practices and standardizing on a CI/CD platform. Many of those decisions are being driven by the need to accelerate digital business transformation initiatives in the wake of the economic downturn brought on by the COVID-19 pandemic.

    As the application development stakes rise, C-level executives are also getting more involved in application development and deployment decisions, DeWitt said. Those executives not only want to accelerate the rate at which applications are built and deployed, they also want greater visibility into processes that now have a direct impact on revenue streams, DeWitt said.

    It remains to be seen just how quickly DevOps platform providers, as a whole, will grow, but with more venture capital pouring into the sector by the day, there is no shortage of fuel to throw on the proverbial DevOps fire.