Category: Features

  • New Relic Bolsters Observability Platform

    New Relic Bolsters Observability Platform

    New Relic has updated its observability platform to include the ability to better detect and track errors in addition to monitoring vulnerabilities.

    At the same time, an instance of the New Relic observability platform that runs natively on the Microsoft Azure cloud platform is now also generally available.

    Manav Khurana, general manager for observability product and chief growth office for New Relic, said the alliance will enable Microsoft Azure customers to consume New Relic as part of their existing Microsoft Azure services contract.

    New Relic already provides an errors inbox to track issues, but is now adding a tool to track the impact an error might have by correlating data across traces and logs. The company has also integrated its platform with Slack to make it simpler for IT teams to generate alerts when vulnerabilities are introduced into codebases and manage errors more collaboratively.

    Similarly, New Relic is also looking to foster greater collaboration between software engineering and cybersecurity teams. A New Relic Vulnerability Management tool with no additional configuration required captures security signals generated via the company’s Telemetry Data Platform in a way that can be analyzed using an interactive application security testing (IAST) tool that New Relic gained with its acquisition of K2 Cyber Security. Additional IAST capabilities available in preview include the ability to leverage a patented deterministic technique to identify and provide automated vulnerability validation that highlights a proof-of-exploit.

    The overall goal is to provide more visibility and context for organizations that are implementing best DevSecOps practices, said Khurana.

    It’s still relatively early days as far as the integration of observability platforms into DevOps workflows is concerned. A recent survey conducted by New Relic found most organizations don’t expect to have robust observability practices in place by 2025. While most organizations have tools to monitor predefined metrics today, there is a significant gap between observability platforms that enable IT teams to determine the root cause of an IT issue and monitoring platforms that generate an alert whenever a threshold is exceeded.

    In fact, many organizations have too many monitoring tools that often surface conflicting or redundant alerts, noted Khurana.

    One way or another, more codebases are being instrumented. As that process continues to evolve, the agents embedded in that code make it simpler to collect the logs and traces needed to advance observability. The challenge, as always, is that it takes time for the number of fully instrumented applications to exceed the number of legacy applications that are either partially instrumented or not instrumented at all.

    As IT environments become more complex, the need for observability is becoming much more pressing at a time when most IT teams are more short-handed than ever, noted Khurana.

    Regardless of approach, there’s no doubt that observability, with patience, will impact the management of IT for the better.

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted as part of an effort to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    LinkedIn

    SiriusXM
    Washington, D.C.
    Director – Client Build and Release Management
    $166,000 to $300,000

    SimplyHired

    Dataflix
    Remote
    DevOps Engineer
    $140,000 to $190,000

    ZipRecruiter

    Bay Systems
    Mountain View, California
    Senior Full Stack Developer
    $120,000 to $174,000

    Monster.com

    GlobalLogic
    Remote
    Senior DevOps Engineer
    $120,000 to $130,000

    Indeed.com

    Leidos
    Ashburn, Virginia
    DevSecOps Engineer
    $97,000 to $202,000

  • Atlassian Extends Automation Framework’s Reach

    Atlassian Extends Automation Framework’s Reach

    Atlassian this week extended its namesake automation framework to include its Confluence collaboration software. In addition, it’s now possible to automatically create bi-directional branches in Bitbucket, GitHub or GitLab platforms from within the company’s Jira project management application.

    At the same time, it’s now possible to automatically generate feature flags from within Jira through integration with the feature management platform created by LaunchDarkly and automate alert and incident responses stemming from the Amazon Web Services (AWS) cloud.

    Dilani Kahawala, head of product for the automation platform at Atlassian, said these extensions to the Atlassian Automation framework are part of a larger ongoing effort to remove the silos within software engineering teams and the rest of the business.

    DevOps teams, for example, will now be able to expand the number of those automated actions being taken because change requests can be automatically created. Atlassian estimated that IT teams will spend 25% less time managing change requests and save 115 hours per month.

    To save more time, templates that automatically create Wiki pages in Confluence can be spun up at the completion of every sprint.

    Since it first launched for Jira in 2020, Atlassian claims more than 10 billion automated actions have been executed across the Atlassian platform.

    Kahawala said as more organizations realize how dependent they are on software to drive revenue, the need to close the divide between software engineering teams becomes much more pressing. She noted that changes to the timetable for one project can have a cascading effect across the entire business. At a time when organizations are counting on digital business transformation initiatives to remain competitive, the speed at which organizations share updates across silos is critical, said Kahawala.

    At the same time, organizations are also striving to become more productive in an uncertain global economy. Automating rote tasks makes it possible for development teams to spend more time writing code, added Kahawala.

    Less clear right now is whether businesses can absorb the pace of change that is enabled by modern software development. Historically, business leaders complained that their dependency on IT was holding the business back because it took too long for IT teams to implement changes. Today, however, many organizations routinely deliver code updates to mission-critical applications daily. While not every delivery may involve a major new update, it’s apparent that the pace of innovation is now occurring at speeds many organizations find challenging to absorb.

    As organizations continue to adopt best DevOps practices, the pace of innovation is only going to accelerate further. The challenge—and the opportunity—is to ruthlessly eliminate as many manual tasks as possible to accelerate the pace of innovation. After all, software engineering pros have better ways to spend their time than manually creating yet another branch in a continuous integration/continuous delivery (CI/CD) platform or, worse yet, reenter data into a project management application.


    Join the makers of Jira for a brand-new (free) Agile & DevOps event. Atlassian Presents: Unleash is designed to help your team collaborate from discovery to delivery to running great software. Get first access and “cheat codes” to the newest Jira Software features and products from Atlassian; network with peers, industry experts, and Atlassian product leaders; and solve real-life challenges around your Jira and toolchain configuration and workflow. Live in Berlin or digitally on February 9. Register for free.

  • Software Supply Chain Security Debt is Increasing: Here’s How To Pay It Off

    Software Supply Chain Security Debt is Increasing: Here’s How To Pay It Off

    Last year, the world woke up to the software supply chain dilemma. We saw a spike in attacks as hackers sought to exploit known and unknown vulnerabilities within dependencies. There is also the chance of typosquatting, and malicious code commits to consider. Such supply chain attacks have increased by a shocking 742% over the past few years.

    It’s easy to let software security debt accumulate, as it’s cumbersome to stay on top of frequent updates — especially when new releases cause breaking change. Furthermore, companies might unknowingly collect security debt by hastily looping in projects whose origin is unknown. Plugging these gaps can bring a high burden down the road, which too often falls on the shoulders of developers to manage.

    I recently reconnected with Dan Lorenc, founder and CEO of Chainguard, to discover why risks in the software supply chain contribute to increased security debt and how organizations can proverbially pay it off. Lorenc is a key figure behind Sigstore, the open source utility built to verify the provenance of open source packages. Below, we’ll consider the state of software supply chain security and examine some modern solutions that lessen its severity.

    Why is Supply Chain Security Debt Rising?

    Modern software ecosystems are an intricate mosaic of dependencies, and supply chain security concerns often arise at the cracks between them. “It’s about the gaps and hand-off points between individuals in the software life cycle,” said Lorenc. Since these hand-off points can threaten systems at large, they can accumulate considerable security debt if left unguarded.

    Another reason why security debt is increasing, said Lorenc, is that fixing issues is rarely incentivized—it’s always thought of as “someone else’s problem.” Minimizing this debt will require organizations to change this mindset and follow modern security best practices, like implementing multifactor authentication infrastructure and more frequent code reviews. It will also take a coordinated effort from package managers to integrate tooling that helps verify the legitimacy of packages, said Lorenc.

    Solutions to Reduce Software Supply Chain Security Debt

    Automated Vulnerability Scanning

    In addition to advancing internal culture toward greater security awareness, organizations will benefit from automation that enhances the discovery of vulnerabilities. Because when a severe incident like Log4j hits the presses, it’s a mad scramble to respond. Even a year later, one in four downloads still possesses the infamous vulnerability.

    Integrating automated security scanning is the first step to knowing how these incidents impact your security posture. A tool like Snyk can do a great job of surfacing known vulnerabilities and finding where they lie within your software stack and provide remediation advice. Continually checking for updates can also help pay off security debt “as you go” instead of upgrading everything all at once, says Lorenc. But although scanning tools are essential for increasing visibility, they don’t address the root cause of why they are vulnerabilities in these packages in the first place, says Lorenc.

    Checking Transitive Dependencies

    Reports find that 95% of vulnerabilities stem from transitive dependencies. These are dependencies that are buried deep within the dependency tree of another package. And depending on the programming language, they’re not always that visible. The combinatory effect of transitive dependencies can lead to exponentially more vulnerabilities and issues if not carefully tracked. And since they’re running locally with the same privileges as your other packages, you shouldn’t treat these vulnerabilities any differently, said Lorenc. “You need to realize they can affect your application in the same way.”

    Validating The Source

    The link between the package manager and the source code is a frail area that warrants additional verification. Social engineering tricks can effectively trick users into downloading insecure packages that appear safe at the outset yet hide corrupt code. Or, account takeovers can result in attackers inserting malicious code into commonly used open libraries. Package managers often host built versions and forked versions of software produced by the community on GitHub, yet do not validate a clear link to the original repository. This gap heightens the chance for a malicious package to slip through the cracks, says Lorenc.

    This is something that Sigstore, the open standard for signing, verifying and protecting software, aims to accomplish. In mid-2022, Sigstore was implemented within Kubernetes, signaling the adoption of Sigstore as a standard throughout the open source ecosystem. It’s also been adopted by Npm and PyPI and Maven Central will soon support Sigstore as well, said Lorenc. Although some of these moves have received pushback from developers, Lorenc argued that such verification is necessary to help link packages to their source and increase credibility for open source dependencies.

    Chipping Away At Security Debt

    Like technical debt piles up over time, security debt can quickly rise if left unchecked. Chipping away at increasing software supply chain security debt will likely require a “pay as you go” approach wherein developers continuously scan and update their dependencies. One good sign is that people are paying more attention to risks latent within their code, and the industry is discovering and sharing more potential vulnerabilities before they are exploited.

    “Security has advanced, and there are common best practices across the industry,” said Lorenc. But if these practices aren’t followed, it could bring dire consequences for the organizations and the industry as a whole. And although Sigstore can help bridge the disconnect between the package managers and the source code, there are plenty of other techniques to help improve a security footprint for open source software and cloud-native infrastructure. For example, SLSA and greater use of SBOMs can help address security debt more holistically.

    The software supply chain security dilemma is an advanced topic that requires a coordinated effort from various stakeholders to remedy. The important takeaway is to stay positive, see the debt, and pay it off incrementally, says Lorenc.

  • GitLab Strengthens Remote DevOps Management

    GitLab Strengthens Remote DevOps Management

    GitLab this week moved to provide remote developers with access to a more secure continuous integration/continuous delivery (CI/CD) platform while at the same time adding a dashboard that makes it simpler to track the overall status of application development projects.

    David DeSanto, chief product officer for GitLab, said GitLab Remote Development takes advantage of an instance of the GitLab CI/CD platform running on a Kubernetes cluster. That cluster is accessed via a Web-based integrated development environment (IDE) to eliminate the need for developers to create development environments on their local desktops.

    That capability reduces developers’ time and effort on tasks other than code and gives organizations more centralized control over the intellectual property being created, noted DeSanto. Organizations will no longer have to worry, for example, about theft of a developer’s laptop that has sensitive data on it, he added. In addition, organizations will be able to more easily create “golden” images that can be consistently accessed by developers residing in multiple locations.

    In addition to making it easier to centrally manage a distributed team of developers, GitLab is also adding a GitLab Value Streams Dashboard that provides senior executives with access to metrics that assess the overall health of an application development project. While GitLab has always provided metrics to DevOps teams, DeSanto said this dashboard, available as a private beta, makes it possible to identify, for example, bottlenecks that might result in delayed delivery of an application.

    Value stream management (VSM) is, of course, not a new idea. The issue that DevOps teams are trying to come to terms with is whether they need to adopt a dedicated VSM platform. The other option is to simply provide a set of dashboards that enable senior IT and business executives to track projects’ progress without deciphering a set of much lower key performance indicators (KPIs). Previously, the GitLab platform surfaced a lot of nitty-gritty details that don’t provide the context senior executives required, noted DeSanto. The Value Streams Dashboard metric surfaces KPIs based on DevOps Readiness Assessments (DORA) metrics from Google alongside other flow metrics.

    These latest offerings are part of a larger case being made for an integrated DevOps platform that reduces the total cost of application development by eliminating the need for organizations to integrate various tools themselves. Each DevOps team can employ as many of the modules GitLab makes available as they need. Once invoked, they take advantage of the same data store as every other element of the GitLab platform. That capability is becoming more critical as organizations embrace platform engineering to reduce the cost of application development using DevOps best practices, said DeSanto.

    It’s not clear how much interest there is in replacing legacy CI/CD platforms that, in some instances, have been in place for nearly a decade. However, as the pace at which applications are being built and deployed continues to accelerate, there is no doubt that organizations of all sizes will need to modernize application development processes.

  • Microsoft Outage Outrage: Was it BGP or DNS?

    Microsoft Outage Outrage: Was it BGP or DNS?

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: All of Microsoft’s cloud services go down, everywhere except China. Redmond’s IaaS, PaaS and SaaS—including GitHub—were dead for several hours, and are still running unreliably—despite Microsoft saying it’s fixed the problem. (more…)

  • Harness Acquires Propelo to Surface Software Engineering Bottlenecks

    Harness Acquires Propelo to Surface Software Engineering Bottlenecks

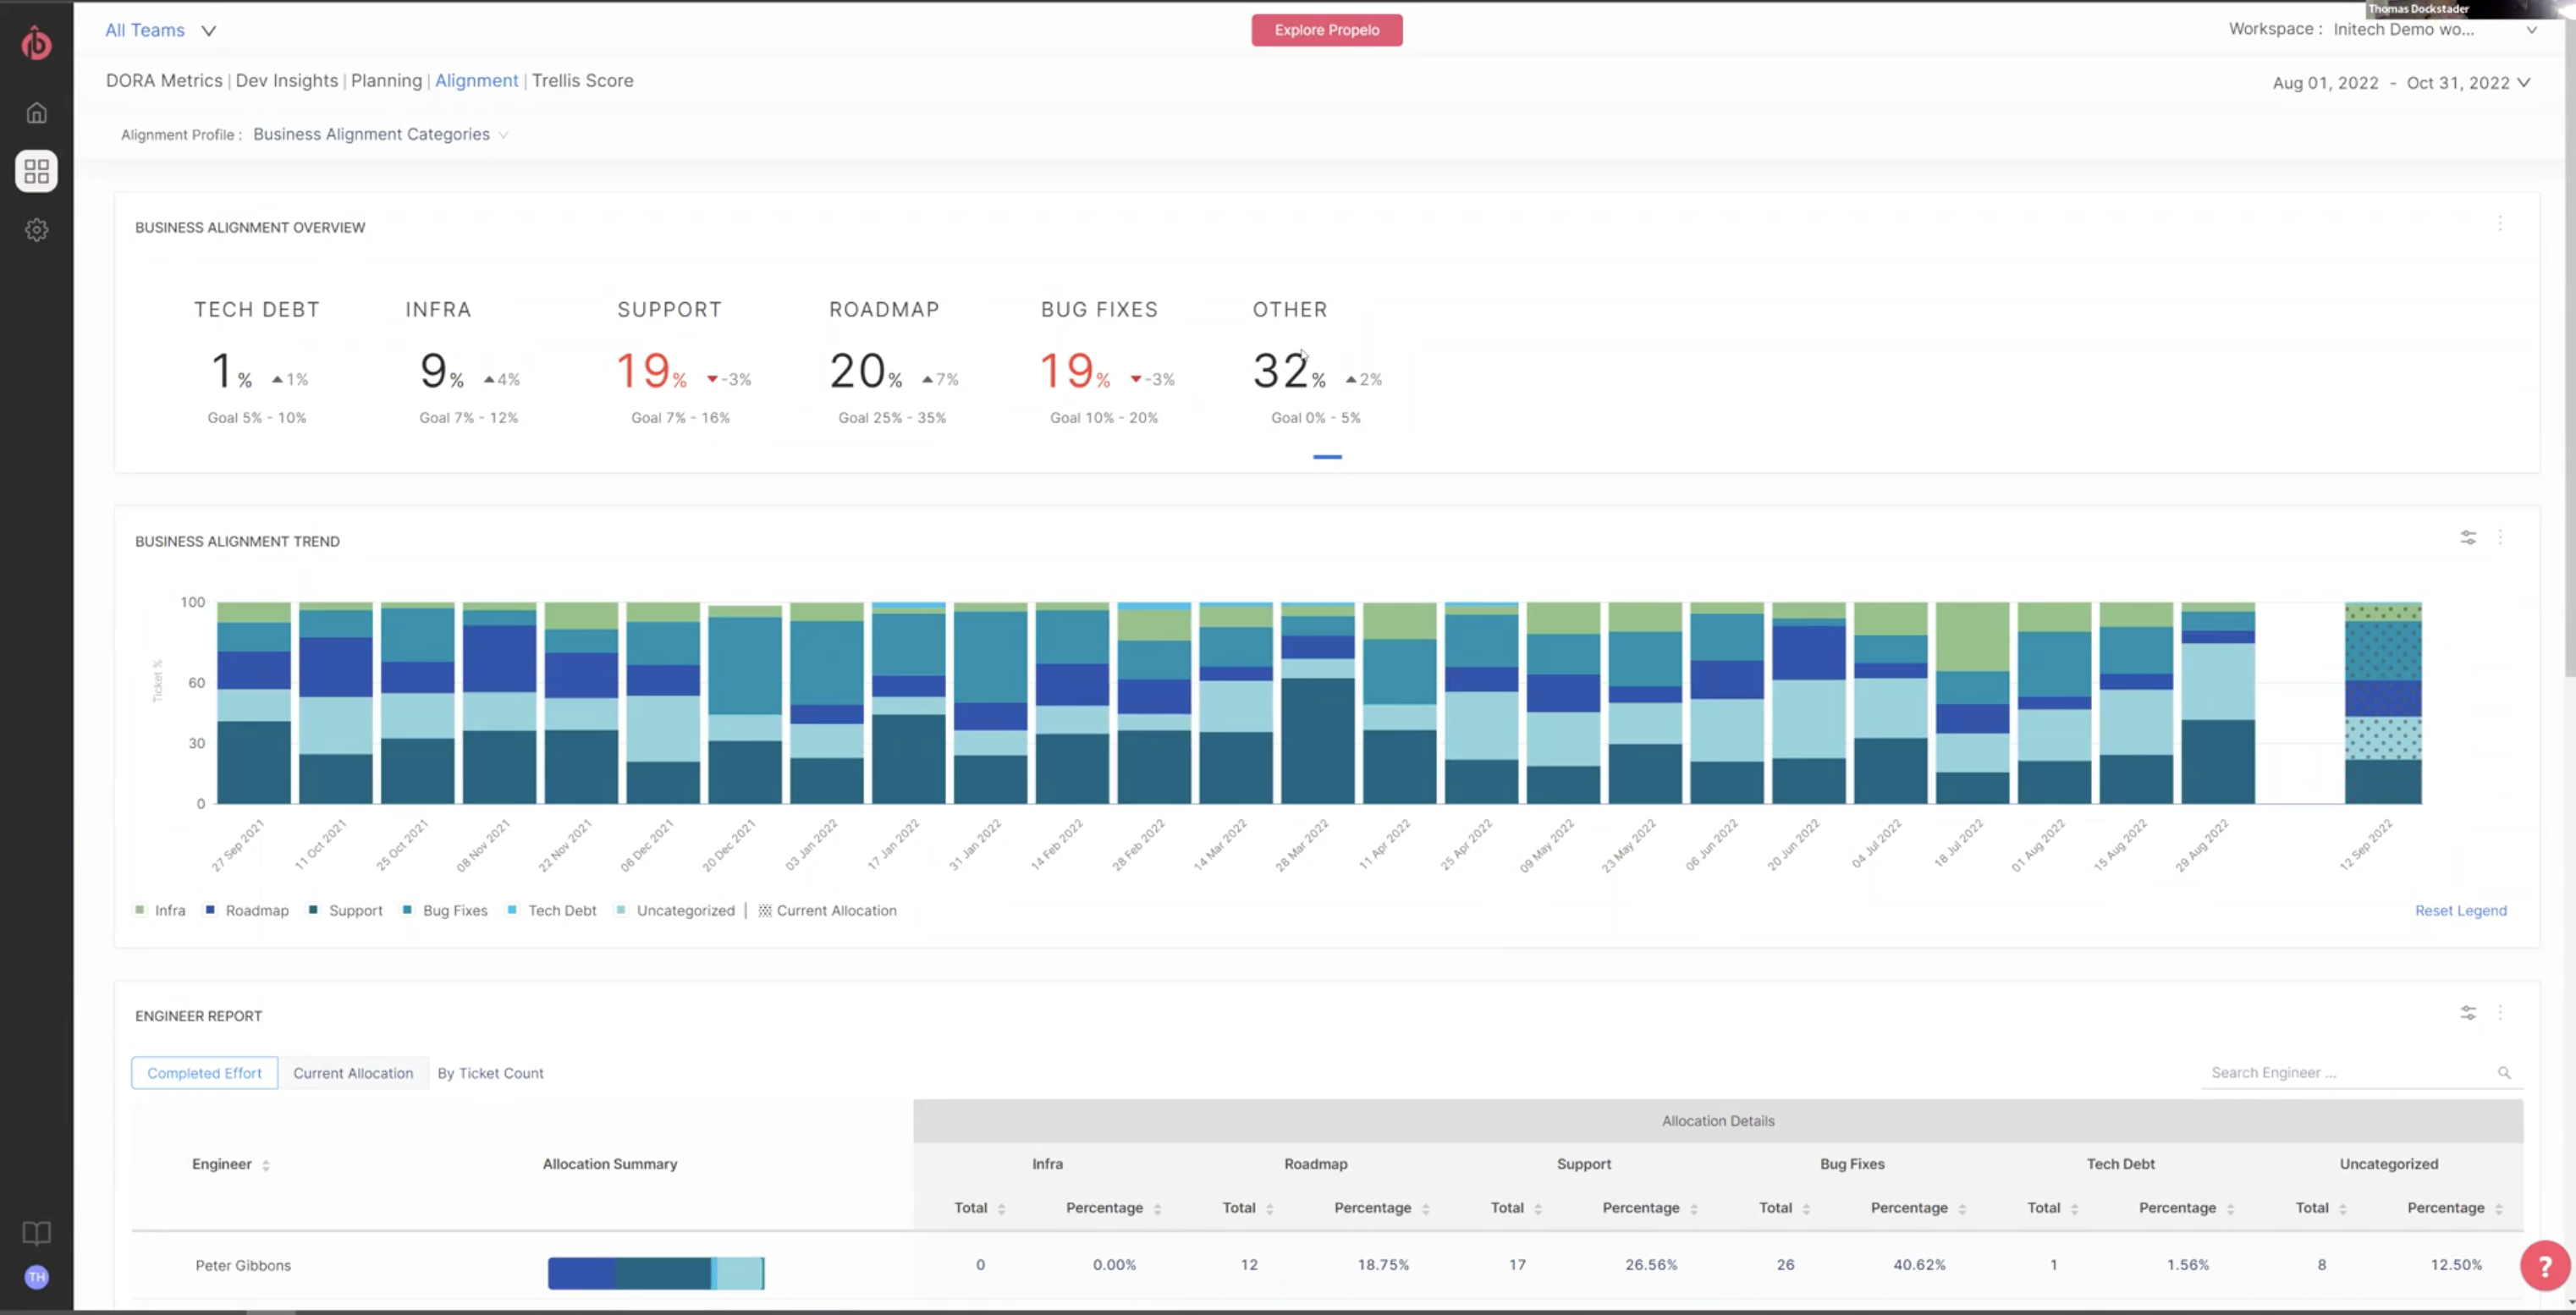
    Harness this week announced it has acquired Propelo, a provider of an analytics tool that identifies bottlenecks in software engineering processes. Terms of the acquisition were not disclosed.

    The Propelo offering will be made available as a module, dubbed Harness Software Engineering Insights, that organizations can choose within the company’s overall continuous integration/continuous delivery (CI/CD) platform.

    Scott Sanchez, chief marketing officer for Harness, said Propelo is unique in that all the integration required to collect data from a wide range of DevOps platforms is already baked into the tool. As a result, DevOps teams can instantly collect telemetry data from not just the Harness platform but also CI/CD platforms such as Jenkins, GitLab and Azure. In addition, there are integrations with more than 40 third-party tools, such as the Jira project management software from Atlassian.

    Those integrations enable the Harness Software Engineering Insights module to surface insights aligned with the DevOps Readiness Assessment (DORA) metrics from Google and the satisfaction, performance, activity, communication and efficiency (SPACE) frameworks.

    In an uncertain global economy, there is more focus than ever on increasing the productivity of DevOps teams, noted Sanchez. More organizations are going to be reluctant to hire as many full-time employees as they once did, so more attention is being paid to getting the most out of existing investments, he added.

    That focus on productivity will naturally lead to a re-examination of workflows to identify bottlenecks in DevOps workflows that, if eliminated, would help increase the pace at which software is being developed, said Sanchez. In some instances, the software development life cycle (SDLC) processes companies are using are as much as 20 years old, he noted.

    The acquisition of Propelo is the latest addition to a portfolio of DevOps tools designed to be deployed alongside existing platforms, noted Sanchez. Organizations that have been using platforms such as Jenkins are not going to rip and replace overnight, he added. The Harness portfolio is designed to be deployed alongside existing platforms to enable organizations to modernize their DevOps workflows in a much less disruptive way than rival DevOps platforms, said Sanchez.

    Harness initially developed a CD platform before acquiring Drone to add a complementary CI capability. It then acquired ChaosNative to add a chaos engineering tool, based on the LitmusChaos open source tool, that is now being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    It’s not clear how quickly organizations will modernize legacy DevOps platforms. Still, in many cases, workflows and pipelines that were designed for a different era of application development are not able to support the pace at which modern cloud-native applications are being developed. It will, of course, be up to each DevOps team to determine whether adding additional DevOps tools and platforms makes economic sense; application developers tend to naturally gravitate toward organizations that reduce as much development friction as possible.

    In an era where organizations are counting on developers to drive digital transformation initiatives, the underlying DevOps tools and platforms employed to build applications can easily make the difference between success and failure.

  • What DevOps Needs to Know About ChatGPT

    What DevOps Needs to Know About ChatGPT

    OpenAI’s generative pre-trained transformers (GPTs) bring powerful AI language models to every IT community. Within the past few months, ChatGPT has become an incredibly popular derivative of GPT. GPT also has the potential to shake up the DevOps and DevSecOps communities. This article will provide an overview of GPT, its history, current status and future effects on IT, especially DevOps. 

    Learning Overview

    Understanding the difference between supervised and unsupervised learning is essential before understanding GPT. Machine learning and artificial intelligence (AI) use unsupervised and supervised learning approaches. A supervised model uses labeled data to predict outcomes, while an unsupervised model does not. In general, supervised models have some limitations. They need a large amount of annotated data to learn a particular task, which is often unavailable, and they also need to generalize beyond the task for which they were trained. 

    A generative language model is a class of statistical models that differ from discriminative models. You can, for example, generate photos of animals that look like real ones using a generative model. Whereas with a discriminative model, you can determine whether an animal is a dog or a cat. Generative models can assign probabilities to a series of words, such as those that predict the next word or sentence. A generative pre-trained transformer is unique because it uses both unsupervised and supervised learning from unsupervised unlabeled text and follows up with discriminative supervised fine-tuning. 

    GPT-based models—ChatGPT, for example—always return the text “I am” when asked, “I think, therefore …” On the other hand, if you ask ChatGPT, “Why did the rabbit cross the road?” it may respond thusly: 

    “The age-old riddle still awaits an answer: Why did the rabbit cross the road? It’s a mystery that has stumped people for centuries and will likely remain an enigma for years to come.” 

    In this way, we can better understand how GPT-3 works. When asked, “Why did the rabbit cross the road?” most humans will answer, “To get to the other side.” A Google search for “Why did the rabbit cross the road?” mainly yields joke punchlines on the first page of the results. GPT doesn’t differentiate between humorous or cynical answers or specific matter-of-fact answers. The model makes only guesses based on the data. Since, in this example, most of the highest-ranked answers are jokes, GPT’s answer is enigmatic at best. GPT is not pixie dust; it doesn’t have a sense of humor, is not sentient, doesn’t understand juxtapositions and, most importantly, doesn’t evaluate context. As another example, I asked a GPT-3 tool to provide biographical information about two individuals. Abraham Lincon was the first. Approximately ten paragraphs of accurate facts were generated by the GPT-3 tool. Second, I used Gene Kim, the author of The Phoenix Project and The DevOps Handbook. GPT-3 began inventing facts about the companies he worked for by the second paragraph. Additionally, it suggested that he had spoken at TEDx. While a Dr. Gene Kim has spoken at TEDx, that Dr. Kim is an opthamologist.

    History of GPT

    GPT was released for the first time on June 11, 2018. Sometimes it is referred to as the  GPT-1 model. A large dataset of online books was used to train it. A database called BookCorpus also was used for training. There were 7,000 unpublished books in the original BookCorpus dataset at the time of training. 

    OpenAI’s GPT-2 model was created in 2019 as a direct scale-up of the original GPT model. There were ten times as many parameters and ten times as much data in that training set. The GPT-2 dataset was based on an internal OpenAI dataset called WebText. A focus was placed on the quality of the documents when scraping web pages for this tool. The authors scraped all Reddit outbound links receiving at least three upvotes. GPT-2 used about 40GB of Internet text, 8 million web pages, and 1.5 billion parameters. In neural networks, parameters are often used as synonyms for weights (found more often in statistics literature). Parameters in GPT are the weights and biases of the dataset and generally indicate the power. 

    As the third-generation language model, GPT-3 was introduced in May 2020. It has 175 billion parameters, making it more accurate than its predecessors—an increase of tenfold in capacity over the next largest NLP model available. Sixty percent of GPT-3’s weighted pre-training dataset is filtered Common Crawl. Common Crawl is a nonprofit organization that crawls the web and makes its archives and datasets freely available. Since 2011, Common Crawl has collected petabytes of data. About 37% of the GPT-3 sources were WebText2 and other sources, while about 3% came from Wikipedia. OpenAI Codex was also included with GPT-3, which generated code and served as the basis for GitHub’s Copilot. 

    As part of its training, GPT-3 used data available until November 2019. Thus, GPT-3 was unaware of events beyond January 2020. COVID-19, for instance, was unknown to it. Even so, it did have extensive knowledge of coronaviruses, pandemics, Wuhan and SARS. As of September 22, 2020, Microsoft, through a considerable investment, received exclusive permission to use GPT-3; others can still access GPT-3’s public API, but Microsoft is the only one with access to the underlying model. OpenAI developed DALL-E in January 2021, which generated images using GPT-3. OpenAI introduced models in the “GPT-3.5” series on November 30, 2022, including the now-famous ChatGPT, derived from a model from the GPT-3.5 series. Unlike GPT-3, GPT-3.5 includes data up until November 2022.

    Current Status

    I have used several AI language model tools in the past few years based on GPT-3. It is used by Grammarly and by some useful writing tools like Jasper.ai and Wordtune. I also have had great success with GPT-3 research tools like Frase.io and Genei.io. One of my more recent go-to tools is called QuillBot. In my experience, these tools are aids, not replacements for writing. When I first started using these tools, I was writing a book about Dr. W. Edwards Deming. I would get inaccurate information about Dr. Deming’s childhood from a GPT-3-based tool. One time, it said he had six siblings. In fact-checking, GPT-3 confused Dr. Edwards Deming with Dr. Richard Deming. With surgically precise input, the results could be more accurate. One of my findings was that if I used a GPT-3 on a well-known subject, the information was primarily precise; however, lesser-known topics produce fewer facts. Furthermore, I learned from the documentation that when people talk about training GPT-3 models, what they really mean is that you can input a maximum of 2,048 linguistic tokens, which is about 1,500 words. In GPT-3, content is predicted by analyzing past context, one word at a time. The content you input to GPT-3 significantly impacts its output. As a result, it pulls words from a shortlist and calculates their probability of being used. A great set of tutorials on using GPT-3 can be found on Jasper.ai. This figure shows how Jasper (which is based on GPT-3) word prediction works.

    Image source

    People have accomplished some remarkable things by using the 2,048 tokens creatively, but complex training still needs to be improved. Due to the Microsoft deal, the original GPT models were close sourced, and robust training of GPT-3 models is unlikely to happen any time soon. 

    Future Effects on IT

    Where does all the hype come from? Despite its limitations, GPT-3 has created some unique industry artifacts. DALL-E and Copilot by Github are excellent tools. On September 8, 2020, the Guardian published an article titled, “A robot wrote this entire article. Are you scared yet, human?” This article was written by GPT-3. Using GPT-3, some full-blown novels have also been written; they’re not horrible, but they could have been better. According to a study conducted by Drexel University in 2022, systems based on GPT-3 could be used to screen for Alzheimer’s disease at an early stage. Just five days after its launch, ChatGPT surpassed one million users. It took 41 months for Netflix to reach one million users and 10 months for Facebook to reach one million users. By the end of the first quarter of 2023, ChatGPT will have over one billion users. Based on GPT-3.5, ChatGPT is more robust and up-to-date. 

    How smart is ChatGPT? Using a verbal-linguistic IQ test and Raven’s ability test, ChatGPT has an IQ of 147. GPT-3.5 has passed the United States bar exam, CPA exam and U.S. medical licensing exam. People often ask if it is plagiarism to use GPT-3. Technically, the answer is no. The GPT datasets are estimated to represent 300 years of pre-training with a connection of trillions of words. However, using these tools for rewriting other people’s work is, from an ethical viewpoint, plain and straightforward plagiarism. A recent set of tweets by Greg Brockman, president and co-founder of OpenAI and Sam Altman, CEO of OpenAI, sums up the current status of ChatGPT.

    What Does This Mean for DevOps Practitioners?

    AI learning models based on GPT-3 are here to stay. From grammar correction to proposal writing to code generation, GPT-3 has revolutionized everything. In my opinion, GPT-3 still needs to solve some challenges before it is of actual value to DevOps and DevSecOps patterns and practices. For example, a great use case for GPT-3 is training it to deal with organizational incidents. If a GPT model could be trained this way, it would become an excellent tool for providing adaptive diagnostics. Based on the current GPT implementation, this is very difficult or impossible. Another example would be to train the model with the organization’s IT risk policies and enable predictive solutions. The opportunities are endless. 

    An alternative to GPT-3 is InstructGPT, which OpenAI describes as more truthful and less toxic. It has also been noted that GPT-3 can generate untruthful outputs. GPT models aren’t generally aligned with their users. InstructGPT models follow instructions much better than GPT-3. Furthermore, InstructGPT produces more truthful and less toxic outputs. Therefore, they generate fewer harmful outputs and more facts.  The InstructGPT models use human feedback as part of the training model. Some of the real power behind ChatGPT is that it uses InstructGPT along with GPT-3.5. Some of my upcoming research will focus on prototyping some of the complex opportunities DevOps and DevSecOps practitioners currently face using InstructGPT. 


  • Dynatrace Survey Surfaces State of DevOps in the Enterprise

    Dynatrace Survey Surfaces State of DevOps in the Enterprise

    A global survey of 1,300 CIOs and DevOps managers working for organizations with more than 1,000 employees published today finds more than three-quarters of respondents work for organizations (78%) that deploy software updates into production every 12 hours or less, with more than half (54%) say they do so at least once every two hours. A total of 20% report they are deploying updates every minute or less.

    Conducted by the market research firm Coleman Parkes on behalf of Dynatrace, the survey also finds 90% of respondents reporting that the pace of digital transformation within their organization has accelerated in the past 12 months. More than a quarter (26%) expect the pace of digital transformation to continue to accelerate, the survey found.

    However, 55% of respondents work for organizations that make tradeoffs between quality, security and user experience to meet the need for rapid transformation. A total of 41% of respondents said they must sacrifice code quality and user experience due to meet demands for faster innovation, while more third (34%) also need to sacrifice code security.

    Overall, DevOps teams, on average, spend nearly a third (31%) of their time on manual tasks involving detecting code quality issues and vulnerabilities that conspire to slow the pace of innovation, the survey found.

    To address these issues, organizations plan to increase their spending on automation across development, security and operations by 35% by 2024, as they invest more in continuously testing software quality (54%) and securing production environments (49%), automatic vulnerability detection and blocking (41%) and automating release validation (35%). The average budget allocated to these activities in these large organizations is $9.1 million, the survey finds.

    A full 88% of CIOs said the convergence of observability and security practices will be critical to building a DevSecOps culture, with 94% noting that extending a DevSecOps culture to more teams is key to accelerating digital transformation. Only 27% of respondents claimed to fully adhere to a DevSecOps culture today. The biggest obstacles to achieving that goal are that security teams don’t trust developers (55%), developers perceive security teams to be blockers of innovation (49%) and the silos that exist between teams (36%).

    Organizations expect to increase their annual investment in DevSecOps automation by 2024 an average of 35%, but only a quarter (25%) said applying artificial intelligence to security was a priority. At the same time, only 28% of respondents said they are fully confident applications are fully tested for vulnerabilities before they are deployed.

    A total of 90% said increasing the use of AI for IT operations (AIOps) will be key to scaling up these practices. However, 70% of respondents said they need to improve their trust in the accuracy of AI’s decisions before they can automate more of their continuous integration/continuous delivery (CI/CD) pipeline.

    Bob Wambach, vice president of product marketing for Dynatrace, said there is a clear correlation between that accelerated pace of digital transformation and a need to deliver more frequent software updates that is driving those investments. Most organizations, however, are going to find it difficult to achieve all their goals unless they break down the silos that prevent them from automating and observing modern DevSevOps workflows, he added. Achieving that goal will also require DevOps teams to reevaluate which platforms they are employing as they move to reduce the current level of friction encountered when building and deploying applications, he added.

    It’s too early to say just how soon DevSevOps workflows will define the next era of software development. One way or another, it’s certain that every organization that embraces DevOps will need to address lingering application security issues.

  • Optimizing Cloud Costs for DevOps With AI-Assisted Orchestration

    Optimizing Cloud Costs for DevOps With AI-Assisted Orchestration

    Kubernetes continues to grow as the leading container orchestrator for high-performance, cloud-native DevOps, DevSecOps and site reliability engineering (SRE) use cases. While Kubernetes offers excellent orchestration capabilities, it does not, by itself, assure cloud computing costs are optimized.

    The current state of cloud expenditures for many organizations indicates a lot of waste. So much so that there is a trend to replatform from the cloud to private infrastructures to save money—escalating cloud costs are too high and the deep level of real-time optimizations are too hard and too slow.

    According to an article from VentureBeat, Cloud computing: Cost at scale, “Large enterprises have started exploring cloud repatriation. What is worse, the forecasted trends are that “cloud spending could go up as high as 80% of the cost of the revenue for software companies. Moreover, the $100 billion market value among 50 software companies is lost due to the impact of the cloud on their margins.”

    An article by CAST AI indicated 60% of cloud costs could be eliminated by being smarter about the use of cloud resources and augment Kubernetes with AI tooling, no matter the size of the deployments. Given the large number of human and automated users associated with DevOps, DevSecOps and SRE use cases for enterprise cloud resources, the savings potential can equate to tens of thousands of dollars per month.

    However, typical optimization methods are not fast enough nor smart enough to process the resource changes quickly enough to achieve these optimizations at speed. An AI-assisted Kubernetes orchestration is needed to achieve this.

    Kubernetes Landscape

    According to 2021 State of Cloud Native Development Report, Kubernetes is used by 31% of all backend developers. Currently, 5.6 million developers use Kubernetes. The edge computing category has experienced rapid growth in the adoption of Kubernetes and has the highest usage rates of both containers and Kubernetes at 63%.

    A report from the Cloud Native Computing Foundation (CNCF) indicated that spending on Kubernetes, the primary means of orchestrating containerized applications, was up year-over-year from 2020 to 2021. Of those surveyed, 67% reported an increase of 20% or more over the last 12 months, and 10% spent more than $1 million per month on their deployments. Fewer than 25% accurately predicted how much they’d spend to within 5% of the actual cost. And over 20% could not predict their cloud bill. That’s no way to run an operation.

    Cloud Cost Use Cases for DevOps, DevSecOps and SRE

    DevOps, DevSecOps and SRE have many use cases for orchestrating cloud computing. The list of computing tasks below is only a partial set of computing resources that need to be orchestrated for every value stream.

    • Communication—emails, chats
    • Experimentation, planning and research-related computing tasks
    • Configuration tasks associated with infrastructure-as-a-service, platform-as-a-service, software-as-a-service and serverless.
    • Version and artifact repositories transactions
    • Application and microservice transactions
    • API transactions
    • DevOps administration tasks
    • Developer pre-commit builds and testing
    • Continuous integration commits, builds, scans, tests, and tools
    • Continuous delivery—pre-prod tests and deployment development
    • Continuous deployment automation and deployment strategies
    • Production operation, backups, rollbacks, production testing
    • Replication of hybrid cloud and multi-cloud instances
    • Software repositories, data lake transactions
    • Monitoring, logging, synthetic monitoring
    • Tracing, metrics, collectors, analytics and dashboards
    • Release and value steam management
    • Anti-fragility—Chaos engineering, disaster recovery, fire drills, security red/blue/purple teams
    • Diagnostics, issue reporting and tracking
    • On-call support and retrospectives
    • Documentation and training (computer-based) transactions

    Sources of Waste and Potential Savings

    According to the State of Kubernetes Report: Overprovisioning in Real-Life Containerized Applications, 37% of cloud compute capacity is not used. The primary reasons behind cloud waste are:

    • Lack of visibility into cloud usage and costs
    • Overprovisioning
    • Leaving cloud resources idle
    • Fragmentation of usage between teams and departments

    One of the major drivers of wasted cloud spend is the inability to scale back once application demand drops. By eliminating this sort of overprovisioning, organizations stand to reduce their monthly cloud spend by almost 50%. By adding spot instances to the mix, organizations could cut their cloud spend by 60% on average.

    Complexities Impacting Ability to Optimize

    According to the article Cloud Cost Management for DevOps, “When properly done, cloud cost management can truly save organizations significant amounts of money. But, there is a learning curve and traditional approaches cannot keep pace with the rapidly changing requirements for DevOps, DevSecOps and SRE use cases.”

    Trial and error are needed to identify optimization challenges that DevOps team members can anticipate. Before you can even begin planning around cost optimization, you need an accurate picture of your current infrastructure and spending landscape. Cost attribution cannot be done by simply opening your AWS bill. Cost data from monthly bills is not granular and cannot attribute costs to projects and teams. Furthermore, there are additional expenses that are included in your bill that are not tied to your cost of goods sold, such as research and development expenses.

    Accurately allocating costs requires accurate and disciplined tagging infrastructure. The act of tagging infrastructure requires a fair amount of manual work for each piece of infrastructure in each sub-account. Enforcing tag hygiene can be a challenge of its own.

    Opportunity for an AI-Assisted Kubernetes Orchestrator

    Overcoming the complexity of optimizing cloud compute resource orchestration for the many uses cases for DevOps, DevSecOps and SRE requires a smarter, more responsive approach than traditional approaches that require manual planning and implementation. There is an opportunity to save an average of 60% of cloud spend by using an AI-assisted Kubernetes orchestrator.

    What This Means

    While Kubernetes offers excellent orchestration capabilities, it does not, by itself, assure cloud computing costs are optimized for the many use cases required for DevOps, DevSecOps and SRE. An article by CAST AI indicated 60% of cloud costs could be eliminated by being smarter about the use of cloud resources, no matter the size of the deployments. Given the large number of human and automated users associated with DevOps, DevSecOps and SRE use cases for cloud resources in enterprises, the savings potential can equate to tens of thousands of dollars per month.

    An AI-assisted Kubernetes orchestration capability is needed to process cloud resource changes quickly enough to achieve optimizations at the speed needed for DevOps, DevSecOps and SRE use cases.

    This article explained the landscape of requirements for an AI-assisted Kubernetes orchestrator to optimize cloud costs for DevOps, DevSecOps and SRE use cases. Future articles will discuss a solution for such an orchestrator and detail specific applications of the AI-assisted Kubernetes orchestrator for DevOps, DevSecOps and SRE use cases.