Category: Features

  • Why GraphQL is a Better Choice for Building Microservices

    Why GraphQL is a Better Choice for Building Microservices

    There’s been a long debate about whether it’s better to use REST or GraphQL for building microservices. Both technologies have their proponents and critics, but when it comes to the specific needs of microservices architectures, GraphQL emerges as the clear front-runner. Here’s why.

    Understanding the RESTful Concerns

    While REST has been the go-to API style for many years, lauded for its simplicity and general applicability, its limitations become glaringly apparent in the context of microservices. These limitations include:

    • Over-fetching of data
    • Multiple HTTP requests for related data
    • Complex versioning strategies

    Such issues can impede microservices architectures’ performance and scalability.

    Over-fetching of data: REST APIs are designed to return a fixed set of data, which often results in over-fetching. This redundancy is particularly problematic in mobile networks, where every extra byte of data can lead to slower applications and degraded user experiences.

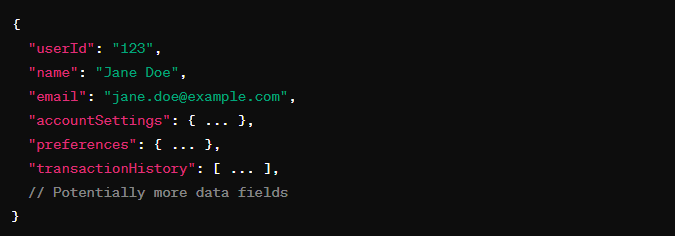
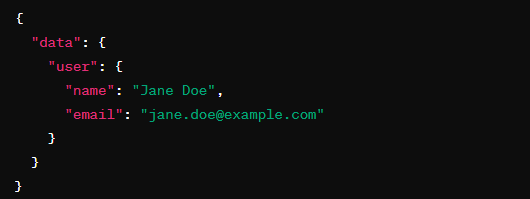
    For example, imagine we have a REST API endpoint /api/user/{userId}, which returns the following data for a user:


    In scenarios where mobile apps only require specific user details like name and email for a profile overview, fetching comprehensive user data means over-fetching.

    This excess data usage can be costly for users with limited data plans and result in slower app performance and degradation of user experience.

    Latency and the N+1 problem: Microservices often require data spread across multiple services.

    Suppose you have an ecommerce application where the order domain handles product, customer, order and return entities, and the stock domain manages product, stock, warehouse and delivery entities. A common operation might be to display order details along with the current stock status for each product.

    Let’s say we have an order microservice and a stock microservice to handle orders and stocks.

    In our scenario, a customer places three orders (N=3) and each order contains four different products. To display the order details with the stock status for each product, the application initially makes one request to fetch the orders. Then, for each product in each order, it makes additional requests to the stock microservice to retrieve stock information. This results in one initial request, plus 12 subsequent requests (three orders times four products per order), summing up to 13 API calls. This multiplicative increase in requests leads to higher latency due to multiple round-trip times (RTT) and increased load on the network and servers, embodying the N+1 problem.

    Versioning challenges: Maintaining REST APIs over time involves complex versioning strategies, such as introducing new endpoints or embedding version numbers in the API path. This can lead to bloat and confusion, complicating API development and consumption.

    The GraphQL Advantage

    GraphQL addresses many REST weaknesses.

    Domain-Driven Design: Microservices thrive on a domain-driven design, where each service is built around a specific business capability. GraphQL’s schema-centric approach aligns perfectly with this, enabling a more organized and coherent structure for microservices.

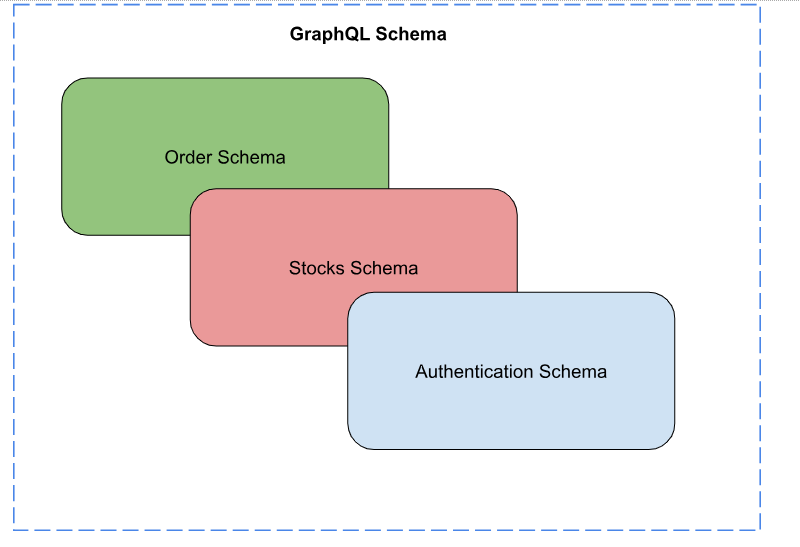
    Unified schema: In a microservices architecture, each service may have its schema, representing a portion of the business domain. GraphQL stands out by allowing these schemas to be combined or stitched together, presenting a unified interface to clients. This means that clients can query data from multiple services in a single request, drastically reducing the complexity and number of network calls.

    Solving the N+1 problem: GraphQL’s ability to fetch data with a single request, regardless of how many underlying services need to be called, directly addresses the N+1 problem inherent in REST architectures. This not only improves performance but also simplifies client-side data fetching logic.

    For the N + 1 problem described earlier, if the services support GraphQL, it can be used to fetch nested data in a single query, effectively solving the N+1 problem.

    Efficiency and performance: By allowing clients to specify exactly what data they need, GraphQL eliminates over-fetching and under-fetching issues common in REST APIs. This leads to more efficient data retrieval, reduced bandwidth usage, and faster applications, particularly noticeable in mobile environments.

    In the earlier scenario where mobile apps only require specific user details like name and email for a profile overview, clients can request name and email alone.

    Simplified versioning: Unlike REST, GraphQL reduces the need for versioning by allowing new fields and types to be added to the schema without impacting existing queries. This forward compatibility means that clients and servers can evolve more smoothly over time. GraphQL stands today as a mature technology that addresses specific needs in modern web development that are not fully met by traditional REST APIs. Its design promotes efficiency, flexibility, and developer productivity.

    Looking ahead, the future of GraphQL is bright, with community-driven efforts focused on addressing its current limitations, particularly around security, performance and standardization. As these efforts bear fruit, GraphQL’s adoption is expected to widen, consolidating its position as a key technology in the API landscape.

  • Bringing DevOps Automation to Legacy Systems

    Bringing DevOps Automation to Legacy Systems

    A critical step toward adopting automation for legacy applications is to change your organization’s mindset about legacy systems.

    Applying automation to operations isn’t always straightforward, especially with older systems that don’t easily fit into typical DevOps automation tools and strategies. However, legacy systems don’t have to sit on the sidelines of your DevOps automation strategy. Using the right tools and methodologies, it’s possible to integrate legacy system requirements with modern automation techniques.

    Most organizations that adopt DevOps for conventional applications use automation tools and techniques, including Infrastructure-as-Code (IaC) and Configuration-as-Code (CaC), automated testing, release automation and application orchestration. If you’ve been paying attention to DevOps for any length of time, you probably are familiar with the concepts.

    However, those DevOps automation solutions aren’t always straightforward to implement with legacy systems made up of hardware or software deployed long before modern, DevOps-friendly application architectures and deployment strategies existed.

    For example, IaC tools may not support the configuration languages or management tools that the systems require. Most current systems are configured using languages like YAML, but legacy systems may depend on proprietary configuration languages and frameworks.

    For similar reasons, test automation can be cumbersome. Today’s automation frameworks are designed for browser-based or mobile apps. Legacy systems may run locally and often use proprietary user interfaces, making automating testing using standard frameworks more difficult.

    Likewise, many release automation and application orchestration platforms are designed for applications deployed using containers. Because containers didn’t become popular until the release of Docker in 2013, most legacy systems have limited native support for application containerization.

    Bringing Automation to Legacy Systems

    Fortunately, these obstacles are possible to overcome. Addressing these challenges requires adopting innovative practices that enable the integration of automation with legacy systems:
    • Migrate to the cloud: Legacy system vendors now offer cloud-based hosting platforms. While transferring legacy workloads from on-premises to the Cloud doesn’t automatically enable all DevOps automation features, it does significantly facilitate the use of automatically scalable infrastructure. Organizations can move workloads between cloud data centers to mitigate failures in a single location.
    • Containerize legacy workloads: In certain situations, it’s possible to get a legacy application to run in a container. That allows businesses to manage the older software using orchestration solutions like Kubernetes, bringing much greater agility and scalability to legacy application management.
    • Use machine learning: Incorporating machine learning into monitoring and management operations for legacy systems helps to detect issues effectively in contexts where conventional automation is not feasible. For example, if you can’t run automated tests for a legacy application because Selenium won’t support it, advanced ML techniques might help you identify bugs based on how the application behaves.
    • Change your mindset: Instead of classifying legacy systems as outdated and inefficient environments, treat them with equal respect to all the other applications within your IT estate. When your team approaches legacy systems from a perspective that values them, it becomes much easier to refine a corporate culture toward collaboration and innovation that extends to those legacy systems as well.

    To Optimize DevOps Automation, Don’t Ignore Legacy Environments

    There’s no denying that automating the management of legacy apps for DevOps teams is often more challenging than implementing automation for modern apps. However, this doesn’t mean that it’s impossible. Many organizations successfully adopt automation as a strategy for improving the flexibility and quality of legacy apps, while also reducing the costs of building and deploying them. But to achieve this, it’s necessary to think beyond the conventional approaches of DevOps.

  • Hasura Adds “Supergraph” to Platform for Managing APIs

    Hasura Adds “Supergraph” to Platform for Managing APIs

    Hasura, whose product helps compose GraphQL APIs backed by databases and services, today made available in beta an update to its platform. The company is adding a graph modeling framework that makes it simpler to manage application programming interfaces (APIs) at scale.

    The goal is to make it easier for IT teams to declaratively create APIs and then manage them at scale, said Hasura CEO Tanmai Gopal. As application environments made up of multiple backend services and databases become the enterprise norm, there is a pressing need to simplify the management of what has become thousands of APIs in an enterprise IT environment using query compilers and routing capabilities built into the platform, he added.

    In version 3.0 of the Hasura Data Delivery Network (DDN), the “supergraph” execution engine is based on a serverless runtime engine that, the company says, will replace its previous graph technologies to manage both GraphQL and REST APIs.

    In addition, all connectors provided by Hasura have been rebuilt using an open specification and are now available as open source software on the Hasura Connector Hub. Hasura is also making available a software development kit (SDK) to enable IT teams to build custom connectors.

    Written in the Rust programming language, the supergraph framework eliminates the need to create and manage GraphQL servers or services to deploy a graph. Additional data domains as a result can be added or replaced without breaking the graph used to manage other APIs.

    The update to the Hasura DDN also adds new build system to provide instant API previews and support for rollbacks, a redesigned console featuring a graphical supergraph viewer, API analytics, observability, and auto-generated API documentation capabilities. Every iteration of the Hasura supergraph is instantly available as an immutable build that can be tested in preview. Every change to the supergraph is also validated before build, letting users identify potential bugs, stylistic issues, syntax, and type errors.

    In addition, Hasusa has added a sub-millisecond cold start capability to enable rapid autoscaling and plane to shortly add caching to improve API performance in edge computing environments.

    Longer term, the company plans to add additional a range of artificial intelligence (AI) capabilities to enable IT teams to identify issues requiring troubleshooting earlier and generate reports, Gopal added.

    While REST APIs are still more commonly used than GraphQL, more IT teams are employing the latter. That’s because GraphQL provides more control over how data is accessed and consumed. Most organizations will soon be using a mix of REST and GrapgQL APIs, but it might be years before REST is supplanted as the dominant format simply because those APIs are more familiar to developers and easier to create.

    Regardless of the type of API used, however, their numbers continue to steadily increase with each microservice added to an IT environment. It’s not always clear which teams within an IT organization are managing those APIs but increasingly best DevOps practices are being used to deploy, manage, secure and update them alongside every other type of software artifact. The challenge, of course, is making it simple to manage those API workflows in a way that doesn’t require yet another specialist to be added to the DevOps team.

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals are highlighted. Our goal in these challenging economic times is to make it just that much easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the hiring company, the vertical industry segment and naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    Indeed.com

    SAP
    Bellevue, WA
    DevOps Engineer
    $182,312

    CareerBuilder.com

    HRL Laboratories
    Malibu, CA
    Senior DevOps Engineer
    $145,745 to $186,688

    LinkedIn

    Visa
    Atlanta
    DevOps Data Engineer
    $142,000 to $179,900

    SimplyHired.com

    Amazon Web Services (AWS)
    Seattle
    Senior Software Development Engineer
    $134,500

    Dice.com

    Travelers
    Hartford, CT
    DevOps/Machine Learning Operations (MLOps) Engineer
    $94,900 to $156,600

  • Survey Sees AI Playing Larger Role in Test Automation

    Survey Sees AI Playing Larger Role in Test Automation

    A survey of 1,028 senior IT professionals and application developers in the United Kingdom, U.S., Germany and Singapore finds nearly half (47%) still use manual testing for mobile applications. More than a third (38%) noted that their organization could save between half and three-quarters (51-75%) of funding allocated to testing per year by fully automating mobile application testing.

    Conducted by the market research firm Censuswide on behalf of Tricentis, a provider of a test automation platform, the survey also found that just under half of respondents (49%) reported their organization is already applying artificial intelligence (AI) to application testing. Another 21% plan to apply AI in the next six months. Almost three-quarters (74%) said their organization’s general sentiment toward AI in mobile software development testing is positive.

    Respondents also expected AI to improve mobile application quality (37%), increase productivity (36%) enhance end-user experience (34%) and to reduce the number of vulnerabilities and/or bugs (32%) in their applications.

    Mav Turner, chief product and strategy officer at Tricentis, said that rather than continuing to rely on expensive testing services, more organizations are looking to reduce costs by automating a wider range of testing workflows within the context of a DevOps workflow. In fact, the survey finds just under a third of respondents (32%) expect their organizations will invest more than $1 million to further automate testing.

    As modernization of testing processes continues, the return on investment in mobile application development will only continue to improve, noted Turner.

    The survey identifies the primary benefits of investing in test automation, which are increased productivity (32%), increased revenue (31%), increased user retention (28%) and increased compatibility across devices (28%).

    The primary obstacles organizations encounter as they strive to achieve that goal are competing priorities (28%), lack of technology and talent (25%), time (25%) and cost (24%), the survey finds.

    A full 87% said the quality of mobile applications is critical to their business, with 90% noting that poor mobile application quality costs their business as much as $2.49 million in lost revenue per year. However, just over a quarter (27%) said they believe their organization’s current mobile application development and testing strategy exceeds expectations.

    As part of efforts to automate testing, it’s not clear just how far responsibility for testing is shifting left toward developers, but there is no doubt many more are being exposed to the results earlier in the software development life cycle. The goal is to provide continuous testing capabilities without overly disrupting code writing. It’s also becoming simpler for developers to leverage generative AI tools to provide summaries of tests along with recommendations to improve code. The end result should be higher-quality applications that require less troubleshooting once deployed in a production environment.

    In the meantime, as organizations continue to become more dependent on mobile applications to drive a wide range of digital transformation initiatives, the cost of testing will continue to pale in comparison to the potential amount of lost revenue that might occur when end users either don’t invoke a specific feature or capability or, more commonly, simply abandon the application altogether.

  • Survey Surfaces Substantial Platform Engineering Gains

    Survey Surfaces Substantial Platform Engineering Gains

    A global survey of 500 application development and deployment professionals finds that while 43% work for organizations that have had a platform team in place for three to five years, there doesn’t appear to be much consistency regarding where that team reports within an organization.

    The survey, conducted by Puppet by Perforce, a provider of an automation framework, found that among organizations that have platform teams, well over half (58%) operate within the context of a larger DevOps or infrastructure management organization, compared to 40% that have their own dedicated leadership.

    David Sandilands, a principal solutions architect for Puppet by Perforce, said the survey makes it clear that platform engineering, in general, is not a new concept, but it’s clear more organizations are trying to reduce the level of toil currently associated with building and deploying applications.

    Regardless of where platform teams reside in an organization, nearly two-thirds of respondents (65%) said they are important to their organizations and would receive continued funding. The primary purpose for forming these teams is to increase productivity (58%) and automate standardized processes (51%), the survey finds. Top goals for platform engineering teams are to solve problems (30%), enforce security processes (27%) and accelerate transitions to cloud-native computing environments (26%). A full 70% said security was built into their platforms from the start.

    That suggests that, in addition to assuming responsibility for traditional DevOps workflows, many platform teams are now also being asked to ensure DevSecOps best practices are followed at a time when application security requirements are becoming more stringent, noted Sandilands.

    More than three quarters (76%) also reported that they had deployed two or more self-service portals, with 27% having deployed five or more.

    Only 22%, however, said they have deployed applications on Kubernetes in a production environment, with just under half (46%) reporting they have no current plans to deploy a cloud-native computing platform, which are widely seen to be challenging to deploy and maintain.

    Overall, the survey makes it clear the primary focus is to ensure platforms continue to evolve as developer requirements continue to evolve, said Sandilands. Platform teams are not necessarily trying to dictate what tools should be used; instead, they are finding ways to automate processes that are increasing the level of friction developers encounter, he added.

    In the longer term, advances in artificial intelligence (AI) will make it simpler to achieve that goal using natural language interfaces that DevOps teams can more easily invoke, noted Sandilands.

    Each organization will need to decide for itself whether platform engineering makes sense as a methodology for managing DevOps at scale, but as application development and deployment continues to evolve, more nuanced approaches will be required. In general, organizations are trying to strike a balance between empowering developers and the need to streamline backend processes to increase productivity while also simplifying compliance and improving security.

    The challenge, of course, is enticing developers to buy into that concept rather than using their expertise to resist platform teams that might, from their perspective, limit their prerogatives in ways that ultimately stifle innovation.