Category: Blogs

  • Budgeting for DevOps Success

    Budgeting for DevOps Success

    One concept that seems to be universal across all IT departments is the admins lament of “how do I convince my boss that we should spend the money.”  Whether it is security, QA or development tools, technical professionals have a difficult time talking the language of the business to justify the expenditure of always scarce dollars. So why should it be any different with DevOps?

    The good news is that in DevOps unlike some other IT disciplines we can actually show some ROI (sometimes anyway).  Nothing will convince a financial stakeholder that spending money is OK faster than if you can show it will allow the organization to either save money or make more money. But how do you show ROI with DevOps. There is more than one way to skin that cat.

    This coming week I am hosting a webinar that will explore the various ways of showing ROI using DevOps.  We will also be looking at some case studies where ROI was demonstrated successfully. One of these organizations is HM Health Solutions. One of the interesting things in this case is that as a health care related organizations the usual compliance issues such as HIPAA often make things like automation and continuous delivery more complex.

    I will be joined by Valerie Scott, Manager of Shared Services Division, HM Health Solutions who is going to relay first hand what she and her team have done to show their executive team how DevOps delivers a real, tangible and measurable ROI.  Valerie is a seasoned exec and I am sure she will have some great insights.

    In addition to Valerie I will also be joined by Rick Slade of IBM who has lots of experience with different organizations in showing the ROI of DevOps.  I expect this webinar to be very informative.  If you are grappling with how to justify a shift to DevOps in your organization I invite you to join us next Tuesday, June 2nd.

    This webinar is sponsored by IBM. It is the third in the series we are doing on Variable Speed DevOps. Our previous webinars in this series have all been very interesting. You can listen and follow along to those here and here. The series deals with how organizations can do more faster  even though not parts of the stack run at different speeds. It is not how fast they run individually, but how well they work together is the key.

    So join me Tuesday as we discuss DevOps ROI and Variable Speed DevOps.

  • Sleep easy: release automation reduces DevOps security threats

    Sleep easy: release automation reduces DevOps security threats

    Sleep easy: release automation reduces DevOps security threats

    “Devops reigns”. “DevOps redefines the way services are launched and managed”. Just two of the recent headlines from the sea of coverage on DevOps. It’s a reasonable argument. The software development methodology emphasizes communication and collaboration between software developers and other IT professionals, and is quickly gaining ground as organizations see a way to launch services faster and improve operations performance. The current DevOps talent shortage also points to Fortune 1000 companies waking up to the difference DevOps can make.

    Here’s the catch. While DevOps appears the master and commander of faster feature releases, it also has the potential to expose software vulnerabilities and security threats in your production environments. We all know that assembling existing code is more efficient than rewriting it from scratch, for example. And when assembling applications from libraries, developers typically use the latest version of that code, assuming it is likely to have less bugs.

    However, new releases can open up new security vulnerabilities. Take the Spring Framework, for instance, a Java platform that provides comprehensive infrastructure support for developing Java applications. According to Joshua Corman, CTO of Sonatype, 81 of the 85 versions of the Spring Framework have known vulnerabilities.

    Software and security vulnerabilities can also rise to the surface unless there is an audit of the production software for security defects. Developers can easily pick up any code they choose without identifying the source or what they did with it. Speaking at the RSA Security Conference, David Mortman, chief security architect at Dell Software, explained that when he began software audits at the company, 198 known execution flaws were found in the code base—putting the company and its applications at risk. And this risk is set to do more harm as DevOps is used to develop physical ‘Internet of Things’ products and services.

    Here’s another fact to put the issue of security into context. Organizations collectively spend $20 billion every year on network security, $10 billion on host security and $5 billion on data security. And you know how much is invested in software supply chain security by all companies? Just half a billion dollars.

    It’s not all bad news though. During the RSA Security Conference, Mortman commented, “A good DevOps process should be implemented using automation tools that can help to track and document updates. DevOps is about change management, process flow and documenting those processes.”

    And automation really is the answer here. It enables you to bring your new products and services to market faster, whilst remaining in control. By automating your application release process, you package the release from your continuous integration tool and securely promote it to the next environment via a reusable work flow. You maintain complete visibility throughout—and there’s no disruption to the business.

    Any software vulnerabilities are quickly identified using role-based access controls: only authorized staff get to promote packages, and only approved packages can move through the lifecycle. Moreover, the automated deployment model ensures you keep track of the code goes on each server and with what configuration settings. And if you are not happy with any aspect of the release, automation enables you to roll back the deployment to its previous state. Finally, comprehensive audit reports help you see who did what and when throughout the entire release process.

    Automation delivers other unique attributes to reduce security risks:

    • Packages and promotion paths so you can be confident that what is deployed is correct
    • Workflows so you have a standard and quality-assured way to consistently           deploy new changes
    • Deployment models to ensure the correct setting and configurations are applied to each environment.


    Your development squad is under more pressure than ever to deliver more functionality, faster without disrupting current applications. By automating your application release process, you not only embrace DevOps in full strength, you also gain back control.

    About the Author/ Dr. Chris Boorman

    chris-boormanAs Chief Marketing Officer, Dr Chris Boorman is responsible for Automic’s worldwide marketing.
    Prior to joining Automic, Dr. Boorman served as Chief Marketing Officer for cloud collaboration vendor Huddle, and data integration leader Informatica.  He has over 20 years of experience leading international teams at enterprise companies including SDL, salesforce.com, VERITAS and Oracle. Reach him on Twitter: @CHBoorman

  • 5 Steps for Black Friday, Cyber Monday and Holiday Readiness

    5 Steps for Black Friday, Cyber Monday and Holiday Readiness

     5 Steps for Black Friday, Cyber Monday and Holiday Readiness

    Ho. Ho. Ho. It’s that time of year again. Seriously. It is.

    It’s too late for April Fools but it’s definitely not too early for Holiday ecommerce readiness planning. In fact now is the perfect time to get your ecommerce house in order well before the planned lockdowns of your critical web based applications.

    Balance is important in any holiday ecommerce planning. On the one hand, you obviously couldn’t and shouldn’t make too many significant changes to your ecommerce environment too far into November. But you also need to actively seek out and evaluate new processes and new tools that will improve your customers’ and your employer’s experience during the upcoming holiday season. Making too many or too few changes can land you in hot water. So for starters, perhaps we can agree that a reasonable goal is to avoid earning hall of shame status at http://www.isitdownrightnow.com/

    Christmas Downtime can have multiple root causes but can often be traced back to


    1)      Sins of Omission: Lack of proper planning for the anticipated burst in traffic on Black Friday, Cyber Monday and the entire holiday season and

    2)      Sins of Commission: Really frustrating situations where you were trying to upgrade, trying to improve, trying to modernize but sure enough, “changing this breaks that”. You don’t want to spend the holidays remediating one problem after another. Do you?

    Rudolph the Remediation Reindeer from OrcaConfig


    The focus of the remainder of this article is to help you with the latter – those seemingly innocuous, “routine” changes to your ecommerce app and all of the related apps, databases and configurations in your ecommerce ecosystem.

    So what’s a DevOps team to do?

    Life is tough enough dealing with “unknown unknowns.” Let’s not make it any tougher by failing to plan for the “known unknowns”. So here are a few keys that we have picked up over years working with e-tailers and retailers who prioritize Christmas ecommerce:

    1. Blackout Periods: Make sure your automation tools know you’re in a blackout period. Whether you use homegrown tools, commercial automation tools, or a combination thereof, users should not be allowed start automated jobs against Production systems during the holiday blackout without approval.
    2. Role Based Access: If your automation tools don’t support blackout periods (and probably even if they do), now is the time to double check that the role based permissions in each tool are set up correctly and adhere to your organization’s guidelines. The most well intentioned engineer can accidentally select Production as a target environment for an automated job, and if they have permission to do so, it can cause an accidental catastrophe during a business critical time.
    3. Restrict Direct Access: Most organizations have an initiative to lock down all their Production servers from direct access, and if you don’t it’s time to add it to the docket. An engineer logging directly into a server to make a seemingly innocuous configuration change to one application can easily bring down another application in the process. Now not only do you have an outage, you have no way of knowing why the outage occurred and who caused it.
    4. Monitor Changes, Not Just Performance: Don’t just monitor the performance of your Production systems, monitor everything you possibly can including configuration changes. Especially if your engineers still have direct access to Production systems, it is imperative you have the tools and processes in place to monitor for configuration changes to the environment.
    5. Experiment Now, Well Before Show Time: All year you’ve been going to conferences, chatting with your colleagues, and in general hearing about all the new tools you should try out. Now is the time to do it! Plenty of vendors offer free trials of their solutions. Some even offer free, full featured trials (ahem). Make good use of your time now by evaluating new time-saving, error-proofing solutions before the calendar catches up with you.
  • Where is the DBA in the DevOps conversation?

    Where is the DBA in the DevOps conversation?

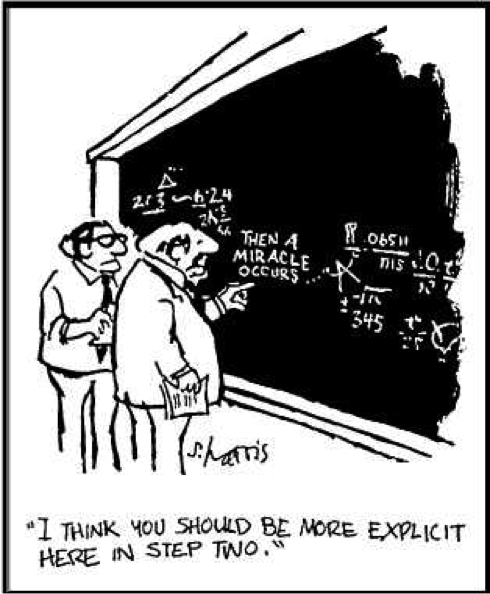
    dbapicIn reading case studies, surveys, and research articles on DevOps I am reminded of a cartoon I saw taped to my high school physics teacher’s file cabinet. Two scientists stand in front of a complex proof scrawled on a chalkboard. Separating steps 1 and 3 of the proof is the statement, “Then a Miracle Occurs.” One of the scientists points to the statement and says, “I think you should be more explicit here in step 2.”

    This is an apt metaphor for the DevOps zeitgeist’s avoidance of the database. ISVs and analysts spend a lot of time talking about how to streamline, accelerate, and automate application development and testing (Step 1) and how to monitor and automate the deployment of those applications (Step 3). But when it comes to managing the database change necessary to support the application and its release processes, it seems that everyone is waiting for that miracle to occur.

    This oversight is unfortunate. DBAs have a lot to offer when it comes to correlating the development of technology with the management of the environment in which it’s hosted. In a sense, DBAs have been DevOps all along.

    On the ‘Dev’ side, DBAs carefully evaluate each change request to ensure that it is well thought out, is compliant with organizational best practices and won’t have unintended consequences on database performance or the validity of dependent objects. They have developed and tested all of the SQL that has materially changed the database and crafted it into what it is today.

    On the ‘Ops’ side, DBAs have designed and provisioned the data platform. They are in charge of monitoring their databases and keeping them available and high-performing. They manage access to and the overall security of the platform. They perform release activities in support of the application and troubleshoot any errors that happen during that process or during day to day operation.

    So why isn’t the larger DevOps community including the data platform in the conversation? Why aren’t DBAs a crucial part of every DevOps team? Why are we relying on a miracle like the scientist in the cartoon?

    Every decision a DBA makes, every process or standard they put in place is influenced by the dual nature of their role. They are used to thinking about the impact of any task, requirement, or problem from both sides. It is deeply ingrained in them. They are deliberate and meticulous in their approach to change management because they understand that what they do has impact beyond what’s directly in front of them. They rely heavily on their expertise and their deep understanding of their organization’s data strategy to ensure they are making safe, future proof decisions to the best of their ability.

    This also explains why we haven’t seen the same proliferation of automation and orchestration solutions for the database that we have seen for other domains in the SDLC. True database automation has to be more than “run this script after that one” or “make this object look like that object over there.” To have a meaningful impact on your release throughput and staff productivity your database automation has to make use of your team’s intelligence. Any solution you implement has to harness the collective experience and knowledge of your DBAs and apply that knowledge to the evaluation of changes as they’re introduced in development. It has to be…miraculous.

    This is the whole reason we started Datical. When it comes to completing your DevOps vision, we wanted Datical to provide a real answer to Step 2 from that comic that has stuck with me all these years. Our flagship product Datical DB was designed and implemented to address the unique challenges associated with automating database changes in support of application releases. It automates and accelerates the propagation of database changes without sacrificing safety. We provide a highly customizable automation framework that is fueled by your experts. It allows you to define standards specific to your organization that are incorporated in our pre-deployment analysis. This greatly reduces the time spent manually reviewing SQL and checking the logic of your SQL scripts for errors that will cause application failures and downtime.

    About the Author/ Pete Pickerill

    High-Res-Peter-Pickerill-6571-150x150Pete Pickerill is Vice President of Products and Co-founder of Datical. Pete is a software industry veteran who has built his career in Austin’s technology sector. Prior to co-founding Datical, he was employee number one at Phurnace Software and helped lead the company to a high profile acquisition by BMC Software, Inc. His ability to understand product demands from a customer’s perspective and translate those demands into actionable product and development plans has led to expanded duties at every company for which he’s worked. In his time at Symantec, Pete worked directly with large financial services companies and online retailers to implement and improve online fraud prevention solutions that were used daily by millions of people worldwide. In addition to managing a development team and product schedule at BMC, Pete worked directly with large financial services institutions to provide the features they needed to achieve greater efficiency and cost savings in their application deployment processes.

  • IT Asset Management: How to Find Out if Your Database is Causing Performance Problems

    IT Asset Management: How to Find Out if Your Database is Causing Performance Problems

    As your IT infrastructure grows, it becomes increasingly important to be able to identify where bottlenecks, performance problems, or outages are occurring so that you can quickly act to fix any issues. Identifying the source of a problem can be a bit tricky once you have grown into having multiple apps, servers, and databases—but there are tools that can significantly ease your burden in locating where an issue has arisen.

    The Problem: Identifying the Source

    sw-request-timeline
    The end user experience is affected when services are not functioning properly. Source: http://logicalread.solarwinds.com/response-time-analysis/#.VWNncfm4TIU

    Often, IT infrastructure begins on a small scale. Perhaps you start with a single app that runs on a single server with one small database. At this point, it is usually fairly easy to determine if that server is down, since everything will simply stop working. If it is simply the database itself, the app will most likely return errors connecting to the database.

    At this level, you likely won’t feel any urgent need to set up a more robust form of monitoring. After all, there are only so many things that can go wrong. However, as your services grow, managing those services in an efficient manner becomes increasingly important.

    Once you begin having multiple apps, servers, or databases, you will find that keeping track of issues becomes more time-consuming and difficult, since it may not always be clear what part of the system is failing. For example, if you have two apps using the same database server and both are not responsive, you will need to determine whether both app servers are down or the single database server is down. This could require checking in several different places to ensure you identify the correct cause.

    The Solution: Using a Monitoring Service to Manage Your Services

    happyapps-blog-sample

    A monitoring service can quickly show you if you have any problems. Source: http://www.happyapps.io

    Time to resolution is important when diagnosing and fixing any downtime for your services. You can save yourself quite a bit of time by having your various services monitored. A monitoring service cannot only send you alerts when things go wrong, but can specify which service is misbehaving or down.

    For instance, if your database server has crashed for some reason, you are alerted immediately and know exactly where to go to fix the issue. If you have multiple database servers, this is even more valuable, since you will know which one it is without looking at each server until you find the one that is in error.

    With a monitoring service like Happy Apps, you also get to tailor the alerts to suit your needs most effectively. You can choose to have notifications arrive by e-mail, text messages, or push notifications to your mobile device. You can also limit your alerts if needed, so that you receive only messages when there is a critical issue as opposed to something being temporarily slower than normal. Incidents are automatically opened whenever a check fails, and once all checks in an incident are passing, the incident will automatically become closed. You can always drill down to a specific incident and view the details (i.e. issues, history, and members), and Happy Apps tracks your incidents so you can understand how you fixed previous problems if the incident were to arise again.

    So, why not setup your services with Happy Apps? The configuration process, often a time-consuming challenge, is made incredibly easy with Happy Apps: with just a few clicks and less than 60 seconds Happy Apps checks are watching your services. Furthermore, in DevOps style, there is an API to add checks as well. The time you save yourself in identifying where problems are occurring will make you and your end users happy!

  • The devOpsSec Dilemma: Effective Strategies for Social Networking

    The devOpsSec Dilemma: Effective Strategies for Social Networking

    I was sad to hear of the passing of John Nash and his wife Alicia this weekend. May they rest in peace. As a game theorist I am familiar with his work and it just so happens that Nash Equilibriums have been in the center of what I’ve been working with lately. It’s an honor to be in a position to build on his ideas and hopefully pass his legacy on to a larger audience at the time of his death. I’ve done my best to pay him my respect by carefully studying his work over the past year, given Velocity starts this week.

    devOps believes in intelligent actors. Security assumes the worst of intentions. Both risk an imbalance of trust. The Prisoner’s Dilemma and the devOpsSec Dilemma, defined here as a lack of cooperation that stems from a lack of trust in an hyper competitive environment, have the same flaw: There’s not a game position that’s safe for everyone because of obliviousness or malicious intent. What I believe is emerging is a low trust cooperative game state. In a devOps world everyone means Everyone both internally and externally. This includes the unique identities of you, your co-workers, the company you all work for, the customers that keep you in business, and even the people who you perceive as your competition.

    The oblivious trampling and opportunistic predation of other people  and organizations are really complementary set operations that mitigate any risk associated with a perceived threat, which is what security is ultimately about. Staying in the lowest risk, highest paying game state is a decent definition of a secure bet for the short game but may not be a safe one over time. If the strategy is damaging others you will eventually compete yourself out of existence.

    We have harassment problems in our industry. I want people to come to events and interact in an effort to network with folks because we grow faster when we share ideas. It would seem we have some of the wrong people showing up given the problems stemming from this type of interaction. If you’re passionate about technology and can respect other people and their skill sets you’re welcome in our community. If not, Keep Out. This applies to everyone, including pushy recruiters and vendors.

    The problem with amensalistic behavior is you’re not aware that your offending someone when it happens. I’ve talked with a lot of people about this and there’s definitely room for a misunderstandings and they’re often cultural. When it turns into harassing behavior and you start looking like a parasite is when it’s characteristically repetitive. The key here is to pay attention to people. Watch for non-verbal queues when people are trying to politely excuse themselves. If you don’t catch the hints people will tell you they don’t have time or the energy to talk and you really need to take No for an answer.

    I’d like to make it particularly clear that if you’re looking for a date you should go look somewhere else. Given the gender ratio issues at events your time would be best spent elsewhere. There are appropriate times and places for it but a professional environment is not one of them. Most conferences and events are in big cities. You can take your name tag off at any time and find plenty of trouble to get into outside of an event if that’s your thing.  That means no one should have to ask you twice, Period. If someone has to tell you three times expect a less than friendly visit from event organizers. Let’s be clear that there’s also zero tolerance for unwanted physical contact in our community. No one should have to explain that to anyone and there is no good excuse.

    With the exception of physical contact and other overtly offensive behavior, we also have to trust that people can make a mistake instead of automatically assuming the worst intentions. An intelligent agent will correct a poor behavior if they’re politely made aware of it. Again, if there’s a characteristic repetition in spite of someone asking them to stop their plausible deniability goes out the door with them. I noticed someone handing out business cards to a strip club in front of a conference recently. I told him that while it was mostly guys here it wasn’t the time and place to be handing those out and he’d have a problem on his hands if he didn’t leave. He apologized and left. Peer moderation can be effective and doesn’t have to hurt anyone. I feel confident this is a fair approach given the explanation of Blameless Problem Solving found on Etsy’s 2014 Progress Report:

    “Making mistakes is an inevitable by-product of doing innovative work. Accidents can actually be valuable and rich sources of learning. We strive to create a blameless culture, in which it is safe to make mistakes and to speak up about them. This allows us to gain as much knowledge as possible from our experiences.”

    We need to move out of no trust interference and do a better job of working together. This is a shift from no trust security towards high trust safety. This is also the split between devOps and security. DevOps believes in intelligent actors. Security assumes the worst of intentions. I covered this material at DevOpsDaysNYC. The video goes into more detail and has some ecological examples of the relationships on the chart, which I’ve added to since the talk.

    [youtube http://www.youtube.com/watch?v=O9hgYtNlo3o]
    The Prisoner’s dilemma is a Pareto inefficient Nash equilibrium because there’s no honor among thieves. Not defecting on the other prisoner leaves an opportunity for them to defect on you, walk out of jail, and leave you incarcerated for the longest period of time. Both prisoners defect and they both end up serving a longer sentence than if they had taken the risk of cooperating.

    Prisoner B stays silent (cooperates) Prisoner B betrays (defects)
    Prisoner A stays silent (cooperates) Each serves 1 year Prisoner A: 3 years
    Prisoner B: goes free
    Prisoner A betrays (defects) Prisoner A: goes free
    Prisoner B: 3 years
    Each serves 2 years


    A significant change in a system replaces the original with a different, adapted system. A minimal number of local changes can be accommodated without inherently changing a system but enough local change in a short period of time is equivalent to a global shift. The devOpsSec Dilemma is the type of systemic failure that demands a systemic change. So I came up with a new game board.

    Here we move from no trust competitive environment where everyone gets hurt towards a Pareto improved equilibrium. By attempting to move out of competition we risk being stepped on or preyed upon if our counterparts don’t make the shift to a higher trust relationship with us. The good news for our game board is that I don’t think anyone has to die or go to jail. While there is some risk here it’s most often a blow to one’s ego, which is a risk I can entertain for something I care about. The solution here is more diplomatic peer moderation and the ability to take constructive feedback even if it’s uncomfortable. We need to move out of safety and danger towards cooperative learning. When you move out of learning and into danger we end up hurt, but it isn’t always competitive.


    adaptiveTrust

    Cooperation is at the heart of John Nash’s work. Trust is fundamental to our survival and is built by showing what you can contribute, not haggling and spit-balling in the bike shed. The more we trust the more we learn and the less we get hurt but it takes a combined effort. If your patterns as an individual or an organization don’t demonstrate these qualities over time then you’re done. As Deming put it, “Survival is not mandatory.”

  • DevOps Connect: Rugged DevOps @Infosecurity Europe

    DevOps Connect: Rugged DevOps @Infosecurity Europe

    We have assembled another top flight list of speakers for our DevOps Connect event @Infosecurity Europe.  While pre-registration is sold out, if you are one of the 15,000+ attendees of Infosecurity Europe, you can still come to DevOps Connect on a first come, first serve basis.  Details and schedule are below:

    When: Thursday 4th June, Olympia London
    Time: 9.00 – 17.00

    Agenda for DevOps Connect:Rugged DevOps

    • 8:30am to 9:00am
      Meet and Greet
    • 9:00am to 9:10am
      Introductions – Alan Shimel and Wai Man Yau

    • 9:10am to 9:50am
      Joshua Corman, CTO, Sonatype and Rugged (Keynote)
      Dr. StrangeOps: How I Came to Embrace Rugged DevOps & SW Supply Chains

    • 9:50am to 10:30am
      Gareth Rushgrove, Puppet Labs
      Maintaining Control While Letting Go

    • 10:30am to 11:00am
      Florin Coada, Technical Specialist Graduate in Application Security at IBM
      Security at Speed; Best Practices for a Secure DevOps Implementation

    • 11:00am to 11:30am
      Helen Beal, Head of DevOps at Ranger4 Limited
      The DevOps Toolkit

    • 11:30am to 12:00pm
      Justin Arbuckle, Vice President, EMEA & Chief Enterprise Architect at Chef (formerly Opscode)
      A Manifesto for high velocity compliance

    • 12:00pm to 1:00pm
      Lunch Break

    • 1:00pm to 1:30pm
      Wai Man Yau, Sonatype EMEA
      Real World Customer Stories from the Software Supply Chain

    • 1:30pm to 2:00pm
      Stephen de Vries, CTO Continuum Security
      Automating Security Tests for Continuous Integration

    • 2:00pm to 2:30pm
      Elizabeth Lawler, CEO and CoFounder , Co-Founder Conjur Inc
      SecDevOps 2.0- Managing your Robot Army

    • 2:30pm to 3:00pm
      Marc Hornbeek, Senior Solutions Architect at Spirent Communications
      Case study – DevOps Cost-Effectively Secured Quality and Time-to-Market for a Complex Hardware/Software Network Product

    • 3:00pm to 3:30pm
      Jonathan Fletcher, Enterprise Architect – Technology & Platform (DevOps) Lead
      DevOps:  How the Industrial Revolution Got Us Here

    • 3:30pm to 4:00pm
      Benjamin Wootten, Co-Founder at Contino
      Transforming to Devops in the Enterprise

    • 4:00pm to 4:10pm
      Thank you and closing – Alan Shimel and Wai Man Yau

    If you are in London during these dates you can still register for Infosecurity Europe for free and attend DevOps Connect. Hope to see you there.

  • What is Adaptive Security?

    What is Adaptive Security?

    72 days after the fact AdultFriendFinder.com, a “very mature” dating site, realized they had been hacked. The VERY personal information of 3 million registrants has been held hostage. By now, it should be clear that in the modern software development world, old-style static security just won’t work. Of course, there are times when the static security model still applies  —  for example, on a relatively stable, hardware-based system with traditional, non-continuous deployment and a limited traffic volume. Such environments can easily be routed through a checkpoint with no significant loss in performance.

    (more…)

  • The DevOps-Price of Segregation of Duties.

    The DevOps-Price of Segregation of Duties.

    Segregation of duties will change because it must change. It has a tremendous impact on our motivation, time to market and IT Security. It influences many parts of an organization. Most organizations have started with DevOps, Continuous Delivery and Continuous Deployment and it is only natural to think about segregation of duties at one point and how we deal with it today. Today, it costs us a fortune that we’re not willing to pay in the near future. And why should we?

    (more…)

  • Continuous Testing: What exactly is it?

    Continuous Testing: What exactly is it?

    ***This post is based on themes and ideas from the great e-book, “Continuous Testing,” by our friends at Parasoft.

    The aptly named DevOps practice of Continuous Testing synchronizes Testing/QA with Dev and Ops processes optimized to achieve business and development goals.

    A few years ago when Agile was all the rage, lightning-fast Dev sprints left the Ops and QA personnel playing catch-up due to inadequate and sluggish testing practices with minimal coverage across frequent builds.

    The widespread culture of Agile development has accelerated development while software testing still lags behind, forcing organizations to cut corners in QA or slow down Dev processes entirely.

    Instead of speeding up the conveyor belt beyond control or slowing down development to kill efficiencies, Continuous Testing in DevOps encourages a systematic approach toward process improvement.

    Continuous Testing goes beyond automation and encompasses all practices — including tooling and cultural change — that help mitigate risks before progressing to subsequent Software Development Lifecycle stages.

    Continuous testing and Automation

    The approach to Continuous Testing can vary and follow diverse pathways to ensure the best user experience is delivered, free of defects.

    It’s barely viable to repeat all tests every time a new feature is added, so the Continuous Testing strategy fosters a company-wide cultural change to achieve four capabilities: Test early, test faster, test often and automate.

    End-to-end test automation practices are intended to integrate QA into existing fast-paced Dev and Ops processes as a means to create continuity while maintaining faster development cycles.

    It’s important to understand the role of automation in Continuous Testing. Automation alone does not enable continuity in testing, but it helps provide a qualitative assessment of risk and practice actionable tasks to mitigate these risks throughout the SDLC.

    In essence, automated testing constitutes the detection process for software issues and defect prevention, whereas Continuous Testing addresses the wider challenge of improving the effectiveness of these detection sensors.

    What does Continuous Testing Look Like

    This example demonstrates how collaboration, automation and tooling enable end-to-end testing that’s performed faster, more often and better aligned with Agile Dev and Ops practices.

    Continuous Testing starts within development processes as Devs use open source tools such as Selenium to test the functionality of their code.

    Tools such as GitHub or other internal repositories can then be used to store tests and version together with the software code. DevOps teams can use the same tests to integrate frequent builds of the software with the Load Impact API.

    Once the code reaches preproduction, dedicated QA teams can use these tests by modifying dynamic test parameters as appropriate. In the production environment, Ops can reuse these tests for acceptance testing and ongoing post production monitoring.

    Once the application goes live, integration with existing APM tools help keep tabs on server-side app metrics.

    Continuous Testing in this example is broken up into at least four environments: Development environment, Continuous Integration environment, QA Pre-production and Performance testing environment, and the Staging environment. Additional post-live monitoring further enable end-to-end continuous testing.

    Key Elements of Continuous Testing

    Parasoft, a global software solutions company, is one of the great thought leaders in DevOps and Continuous Testing. The company has laid out some key elements of the process in a fantastic e-book, and they’re definitely worth sharing here:

    Risk Assessment: Covers risk mitigation tasks, technical debt, quality assessment and test coverage optimization to ensure the build is ready to progress toward next SDLC stage.

    Policy Analysis: Ensure all processes align with the organization’s evolving business and compliance demands. Primary objectives include:

    • Identifying trends associated with injection of dangerous patterns within the code
    • Augmenting defect prevention practices for high risk areas
    • Isolating risk in target areas

    Requirements Traceability: Ensure true requirements are met and rework is not required. An object assessment to identify which requirements are at risk, working as expected or require further validation.

    Advanced Analysis: Using automation in areas such as static code analysis, change impact analysis and scope assessment/prioritization to prevent defects in the first place and accomplishing more within each iteration.

    Test Optimization: Ensure tests yield accurate outcomes and provide actionable findings. Aspects include Test Data Management, Test Optimization Management and Test Maintenance.

    Service Virtualization: Early, frequent and everywhere testing requires access to real-world testing environments. Service visualization enables access to the virtual form of the required testing stages, cutting the waste time to test environment setup and availability.

    An effective Continuous Testing strategy incorporates all of these elements and forces an organization-wide cultural change to synchronize Dev, Ops and QA/Testing as part of the true DevOps philosophy.