— ROELBOB
It’s estimated that the total market for mobile apps will hit $143 billion this year. A big portion of that budget will be enterprise mobile app development. By next year 25 percent of enterprise IT budgets will be aimed at their mobile app efforts. Yet, despite these efforts, most enterprises are still falling behind in their mobile app development pipelines by 12, 15 and even 20 weeks.
To help clear that backlog and meet their internal mobile app demand, more enterprises are focusing on delivering the mobile apps with the features that hold promise to produce the most return on their efforts; that is, the apps that people likely will use and will do the most, for the least investment, to help to improve their daily work lives and productivity. Or, this minimum viable product (MVP) is the minimum required in an app to prove out its app concept.
But when moving apps out quickly, enterprises risk skimping in areas of quality and especially security, which can pose a risk to data that should be handled with care, notes Isaac Potoczny-Jones, research lead, Computer Security with security research and development firm Galois.
“There’s definitely a lot more development in mobile happening,” says Potoczny-Jones. “I think the [security] best practices in mobile aren’t as well-developed as best practices for the web. I think that’s getting a little bit better, and there’s a very fascinating challenge with security [with MVP] because security is a non-functional requirement.”
Of course, apps must be developed with good mobile security—including app password management, server side controls, cryptography and other best practices—in mind. The OWASP Top 10 Mobile Security Risks provides an excellent overview of common mobile risks and associated mitigations.
One of the challenges with mobile security testing is that the best practices and associated processes are not well understood by most, at least not yet, and quality mobile security testing tools are not deployed in many organizations. Plus, those organizations using some of the common mobile security testing tools find that they don’t always suffice and they often have to build their own automated toolsets.
The risk with fast-tracked MVP apps is that they never get anywhere near a security test before being shipped to production. But these apps—just like any other apps that get near enterprise data and networks or may access sensitive, confidential or regulated data—must be vetted, threat modeled and tested (static and dynamic app testing), along with the usual quality tests. And with MVPs, it’s just as important that this testing be an integrated part of the process from the beginning.
The best way to achieve this, of course, is through awareness and secure code training with developers.
Companies may want to consider creating an MVP development guide that could detail security considerations for the MVP. Such a guide could help developers determine what security best practices to follow, as well as what apps need to be sent to the security team for reviews—and when.
Potoczny-Jones says there’s no reason, except for maybe carelessness, why MVP apps are being built with minimum security considerations, as most lean development methodologies have security testing built into their processes. “Once you get these teams to include security testing being a part of [what they consider] ‘being done,’ which I don’t think a lot of people have, then they’re going to do the right things. You’re either going to start to build security either into the user stories or the acceptance testing,” he says.
That’s for sure, and it shouldn’t be left to the end of the development process. “You can’t leave it to just be at the end of the process. If you leave security testing toward the end, naturally your schedule is going to slip. You’ll find that there’s a lot more work to do. Then you’ll be in this unfortunate position of having to decide whether to fix things and let the schedule slip, or choose to let something go out the door that’s not secure,” Potoczny-Jones says.

The rift between Dev and Ops teams has long been one of the main obstacles for organizations managing their IT capabilities. Overcoming it can be crucial for a successful business. In fact, every company should be able to achieve harmony by improving process automation, implementing better procedures and refining workflow regulations. This is where DevOps culture steps in.
To be successful, your DevOps approach must include a detailed understanding of your culture and learned behaviors that will influence the changes you want to see in your organization.
According to recent Gartner research, DevOps will only work when both Dev and Ops are willing to collaborate. They need to embrace change at a behavioral level to initiate and achieve culture change. If not, there is a 90 percent likelihood that any DevOps initiative will fail.
In discussing the importance of communication in implementing DevOps know-how with Consultancy UK, Gartner’s research director Laurie Wurster explained: “With respect to culture, DevOps seeks to change the dynamics in which operations and development teams interact. Key to this change are the issues of trust, honesty and responsibility. In essence, the goal is to enable each organization to see the perspective of the other and to modify behavior accordingly, while motivating autonomy.”
In reality, the existing autonomy of the operations and development teams is one of the most common reasons for a possible failure of the DevOps approach. While the business culture of developers is founded on innovation and breaking the status quo, life in Operations can seem unthinkable without a procedure-based routine.
Going further, these two teams can be pushed apart by their own executives. After all, handing out separate tasks and objectives without actually putting the Dev and Ops teams in a room together (even when working on the same project!) has been a traditional approach that dates back decades.
With Dev and Ops each being unaware of the business value of the other, the departments end up sharing only two business factors: deadlines and objectives. This often leads to a blame game—explaining a delay or a failure seems much easier when you have someone else to blame and a team with an unknown value is always an easy target.
Putting a stop to this poor practice by initiating cooperation and reminding both they are part of the same organization is the best way to improve efficiency and speed of innovation. IT managers must build bridges and encourage Dev and Ops to discover new ways to accomplish their shared objectives.
Modern business has realized that while Agile improves speed and service delivery, it may have skipped some very important aspects of culture change resulting in the birth of “fragile infrastructure.” The term is used to describe the damage that can be caused by Agile’s ‘shortcut policy,’ in which teams may compromise to meet their deadlines.
Many see DevOps as the savior that comes just in time to influence business on a cultural level and unite with Agile toward excellence.
One of DevOps’s flagmen, Mike Kavis, vice president and principal architect at Cloud Technology Partners and a Forbes contributor, points out that “the solution is for dev and ops to collaborate on the environment specs and together build the appropriate automation scripts that can provision environments with a single touch of a button without the need of additional configurations.”
When implementing the DevOps approach, developers can be the toughest audience. They may remember all the arguments and rifts with operations, potentially caused by tentative coding leading to functionality issues within the environment—a destabilization every Operations team fears and detests. So, one question remains: How can you build this collaboration?
As stated by Forrester analyst Kurt Bittner, IT companies of today are helping the cultural rift between dev and ops by incentivizing the teams to do different things—developers are prompted to deliver quickly, while operators are targeted to keep the services up and running.
Encouraged to pull in opposite directions, it is only natural that the two business units end up facing a rift, making cooperation seem more illusion than reality.
Because most companies set their priorities based in part on its incentives policy, it is important that those priorities agree with the company goals. In short, once you “go DevOps,” make sure your incentives policy is encouraging rather than hindering collaboration.
DevOps supporters see DevOps as a cultural movement and a philosophy, rather than a framework or simply an approach.
“DevOps is a mindset of moving away from fragile systems that take too long to deploy to reliable software that can be deployed quickly. DevOps requires great collaboration and teamwork, not just within IT, but also with management and product,” Kavis notes.
Identifying a goal that can bridge the gap and make teams work together is a great way to initiate a change in a positive direction. As Bittner explains, “Part of that means measuring devs on stability, and part of that means measuring ops on innovation. But the best thing is to reward everybody on improving the customer experience.”
A recent case study presented by Orbitz Worldwide’s senior software engineers Greg Burton and Ori Rawlings at the Velocity Conference neatly demonstrated how setting a common goal for Dev and Ops can bring actual results.
The goal itself was simple but ambitious: to double the hotel search capacity across the whole website. While achieving it by working closely with operatives, the development team managed to get a hold of many issues plaguing the system on day to day.
In fact, being a back-end developer himself, Burton defined the term “feature guilt”—the belief among developers that any time spent in aiding operations to resolve outstanding performance issues is lost and unproductive, so everything that does not involve new features must be completed quickly.
Like many other professionals, Burton also believes change should be realized as soon as possible throughout the organization to prevent substantial losses for everyone. Working on a shared goal, such as improving the customer experience, for example, can help influence developers to appreciate that maintaining a system is as important as developing new features.
As Bittner notes, “If agile was the opening act, continuous delivery is the headliner.” Once the culture change is favorable and the company is running at full capacity thanks to the DevOps approach, favoring innovation and experiments within the organization becomes one of DevOps’s main advantages. Still, allowing it to work might prove unattainable to some companies. What lies beneath is the fear of failure that can paralyze every manager and employee.
Randy Bias, director of the CloudStack Foundation and vice president Technology at EMC, speaks of “a culture of fear” that exists within organizations, which is driven by an “endemic” fear of failure.
This is caused by the widely adopted practice of heavily penalizing every form of failure instead of focusing on how to minimize the potential losses and still allow experimentation for the sake of innovation.
The real question is, How can you make this possible when your business is at stake? The secret to success, according to many industry experts, is creating a structure based on separate components that can malfunction without leading the company to bankruptcy.
As hard as this may be for companies relying on monolithic applications, it is best to adopt microservice architecture that will permit managers to allow developers freedom, even if this means paying the cost for the potential mistakes.
According to Mike Kavis, vice president and principal architect at Cloud Technology Partners, and Etsy’s CEO Chad Dickerson, it is essential to allow people to make mistakes as freely as reason allows and turn postmortems into productive and proactive meetings, not a blame game.
One of the greatest success stories of today’s business practices, the e-commerce platform Etsy is a great example of the benefits of DevOps practices and blame-free meetings.
Senior vice president of Technical Operations John Allspaw, who is in charge of Etsy’s “blameless postmortems,” told Business Insider: “Less-skilled companies name, blame and shame. It’s not about avoiding accountability. In a blameless culture, it’s easier for people to take responsibility for their mistakes and learn from them. Developers already feel quite guilty when they break the site.”
One-on-one meetings with management, prearranged brainstorming and specially made presentations are no longer enough to effectively influence culture change. Encouraging communication between teams with the right incentives is vital, but modern management needs to push even further.
The best way to make developers understand operations and vice versa is to get them together and even share job descriptions.
Companies like OnShape, for example, have taken a big step in reorganizing on-call duty by making developers and operations actually work together. According to Paul Beltrani, webops at MC10 Inc. and former techops at Onshape, this has been a win-win game, as the change has helped both teams.
Developers have gotten a grasp of the after-effect of a faulty code, while operations have gained a better understanding of how the code works. Furthermore, making dev and ops share a responsibility has also proven to be less stressful, as developers and operations were effectively cooperating by exchanging knowledge to handle the issues.
CenturyLink goes even further in this direction, by transforming its dev and ops teams into product teams able to support the entire service.
“It aims to be light on management and process, with each product team assigned each aspect of the product with a laser focus,” explains Jared Wray, CTO of CenturyLink Cloud and head of the development center. “There’s no throwing it over the fence, and there’s no distractions between the two organizations.”
If you’re willing to transform your organization according to DevOps, you should invest all of your patience and good will; be ready to listen and improve.
As every business is unique in its organizational structure and services, and is counting on many individuals, there is no strict route to follow when implementing DevOps. Of course, there is something all professionals agree on: “Most people think they’re going to snap their fingers and it’s going to happen overnight by doing a reorg. But it’s a full culture shift. It took us three years to make this model, and we’re still evolving it,” Wray says.
According to Chris Nowak, senior vice president and head of DevOps Services at Bank of America, it’s natural to face initial resistance when presenting teams with new requirements and processes and the best way to handle it is with care. Nowak recommends the human approach: finding and encouraging opinion leaders who can influence change and “eventually help other teams let go and embrace a new way.”
So, setting clear goals is the first step to becoming a DevOps success and rushing change has only ever resulted in a temporary workaround. DevOps is gaining more and more popularity, making it possible to gather opinions and learn from the forerunners.
Industry experts have come together to found the DevOps Institute and share a common language through the DevOps Foundation course, so maybe now more than ever is a good time for your business to “go DevOps” and see the value.
Everyone knows Git. It’s a favorite developer tool and for good reason. Developers love its flexibility, speed and ability to branch locally and in place. It also appeals to the attraction to community development.
But as developers adopt Git within enterprises, IT managers face the challenge of reconciling the needs of developers with the needs of the larger organization, especially when it comes to DevOps. In this article, we will examine some of these challenges and suggest best practices that can alleviate them.
IT organizations often rely on performance and low latency as key indicators of the adoptability of any solution. Speed tests run against Git’s network operations generate impressive results, since the Git protocol for transferring data is highly optimized. Over time, however, an internal implementation reveals limitations that can impact the speed and efficiency of the delivery pipeline.
First, Git works very well for small projects. Yet, when projects grow larger, many teams will feel the pinch of its all-or-nothing architecture. A developer who needs to work on a project must retrieve (or “clone”) every file associated with it. For enterprise software, this necessity is not always feasible or desirable. Large projects can require a lot of disk space and time to clone, even though much of the repository content may not be relevant to that developer. The all-or-nothing approach of a Git clone also compromises security—users will have the same access to the whole repository, whether they should have it or not.
Second, Git is optimized for fairly small assets, such as code and configuration files. But many organizations need to version large binary files such as images, videos and CAD designs. Large binary files are also often the product of the build system. Such content can quickly bloat the size of a repository and, by extension, the file systems of contributing developers. A less obvious issue with large files is the fact that some Git functions require the calculation of hash values over the contents of the repository. As a result, large binary assets can inexplicably reduce some operations to a crawl while others execute almost instantly. To address these issues, you should employ an external store for your large binary assets. There are no formal standards for external asset stores, but there are options available, including git-annex and Git LFS.
The solution that Git offers is to separate components into dedicated repositories or to use Git submodules. Both approaches lead to what is known as Git sprawl, a condition that increases complexity and risk. Git sprawl can be avoided using the narrow cloning approach. Narrow cloning enables developers to retrieve just the subset they need from the contents of a code repository. Although the developer community has long requested this feature, Git currently provides no support for narrow cloning. For these reasons, you should standardize on a Git management system that offers narrow cloning, while using shallow cloning as much as possible to limit file revisions.
As long as repositories are logically divided along component lines, developers might not experience any immediate problems with Git sprawl. Build and test teams, by contrast, are likely to feel the pain immediately. Trying to find all the correct and related revisions of files from many different repositories is an expensive and risky process. Builds will frequently fail if the input files are not correct. The ideal agile workflow supports build and test on every check-in, especially on the mainline. If builds frequently fail, the build and test system will not be able to keep up with the development pace and will slow down the entire DevOps pipeline.
Another bad practice that can result from Git sprawl is having inconsistent or conflicting branching models for different teams or repositories. Dealing with the idiosyncrasies of individual developers or teams is needlessly frustrating and inefficient for the build and test teams. But Git provides no support for defining or enforcing branching strategies across multiple development teams. For this reason, it is critical to define an overall branching strategy, socialize it throughout the organization and review practices on an ongoing basis.
Hosting options for cloud deployments of Git are plentiful. Organizations embracing Git need to evaluate these options carefully because the choice will impact not only information security but also DevOps. Developers generally seek options that make it easy to create new projects, clone or fork and push their work, preferably with great review tools and a simple method to deliver units of work to the master branch.
The developer’s desire for ease of use is often at odds with DevOps’ need for scalability. Available Git management systems vary significantly in their capacity to support enterprise IT, with capabilities ranging from single-server topology all the way up to clustering and, in some cases, high availability. Note that none of the solutions supports disaster recovery. Therefore, organizations need to identify tools for backup and recovery, while also defining internal processes to ensure the system can be restored after a catastrophic event.
Developers’ need for speed and customizability also often run counter to the enterprise’s need to protect the intellectual property locked away in Git. The key issue is that Git lacks a robust and manageable mechanism for fine-grained access control. Git is limited to providing security in the form of authentication; users must present credentials (username/password or SSH key) to access private repositories. Once the user has accessed the repository, Git has no way of controlling what that user does. While this works well for democratized, community-based open source development, it creates security holes and compliance problems for enterprises.
For these reasons, it is critical to think through the necessary roles and permissions that will enable developers and DevOps to do their jobs, while minimizing the risk incurred by hosted Git solutions. Personnel should always be provided with “least privilege” access to assets—that is, they should be given only the permissions necessary to complete their tasks. For compliance purposes, it is often necessary to provide logs showing who did what when. This requirement is especially true for enterprises in regulated industries such as health care and finance. Git, however, gives users the ability to destroy virtually every form of historical evidence. Again, this is useful for developers, but detrimental to information security and governability.
In summary, DevOps is penetrating enterprise IT departments at the same time that Git management solutions are proliferating. The differences among competing Git management solutions become most apparent in the context of DevOps. Remember, DevOps has to manage everything across the application lifecycle. Evaluating Git solely from the perspective of development teams, without considering the requirements of DevOps, can be a recipe for the failure of your DevOps initiative.
 Mark Warren is Product Marketing Director at Perforce, based in the United Kingdom. Mark has more than 25 years of experience working with development and product management teams in software development tools and configuration management.

In software approaches that produce monolithic applications, it is not uncommon to find siloed teams, with development, testing and operations each an island unto themselves. The responsibilities of test and development are distinct from each other and are not meshed into a hybrid team as you might see in advanced DevOps shops.
“QA (quality assurance) always comes late in the game to verify or test the software developed by the development team against the predefined specifications know as software requirements,” says Venkata Vinay Pandella, team lead at Nisum Technologies Inc.
That’s the view inside and among these teams in which legacy development approaches still flourish. The rest of the enterprise sees these teams altogether differently from how they see themselves. “Even in a traditional software engineering organization, folks outside the engineering team generally consider Development, QA and Operations teams as a single group with a single responsibility to deliver a quality software product,” says Pandella.
Even when Dev and Ops do embrace each other, the rest of the enterprise often maintains the same POV it had when Dev, Ops and QA were three entities and not one. How do DevOps and QA see QA after the shift?
Enterprises, the business units, Dev and Ops all expect DevOps to propel software using continuous integration (CI), continuous delivery (CD) and ultimately continuous deployment techniques that are fueled by and gain traction using automation. The more processes that Dev and Ops teams are able to automate, the more that DevOps accelerates the process of software delivery and deployment to the delight of software consumers and the business.
DevOps enables teams to push software out weekly, daily and hourly through continuous software improvement. This negates the many obvious downsides of applying the traditional software development approach, which requires excessive planning, cross-team coordination, staging, testing and releases of monolithic blobs of software all at once. “Given that companies organically adopt DevOps together with agile software development practices, business managers are able to fulfill the objective to get high-quality software out to market faster,” says Pandella.
To meet the goals of DevOps, QA must feed into the automated development process and help teams to achieve increasing software quality and faster time to market.
According to Pandella, QA specialists and teams have a number of roles and responsibilities in DevOps:
• QA should prevent software defects at the earliest point during the software development process rather than find and report on software bugs after DevOps has produced the software. This will help to ensure that customers experience as few defects as possible.
• QA takes ownership of and responsibility for continuous software improvement and software quality tracking throughout the software development life cycle.
• Every QA team member is responsible for identifying problems not just in the product but also in the process, and recommending changes wherever they can to improve the continuous delivery of quality software.
• Tests must be in code, based on the designed release cadence to publish a new release every week, every day or every hour. There is no room for manual testing—QA must develop automation systems through code that can ensure quality standards are maintained.
• Automation rules: QA should automate anything that can be automated.
• QA testers are the quality advocates, influencing both developmental and operational processes. They don’t just find bugs; they look for any opportunity to improve the quality of software through the software development process.
• QA must move beyond functional testing, because even a small, nonfunctional defect introduced into a critical transaction process on an e-commerce website can bring a business to its knees. Many organizations have mature processes for automating functional testing; they are only beginning to apply these practices to other areas of testing such as security and stress testing. In particular, load testing and stress testing are critical disciplines for DevOps organizations that move at high velocity.
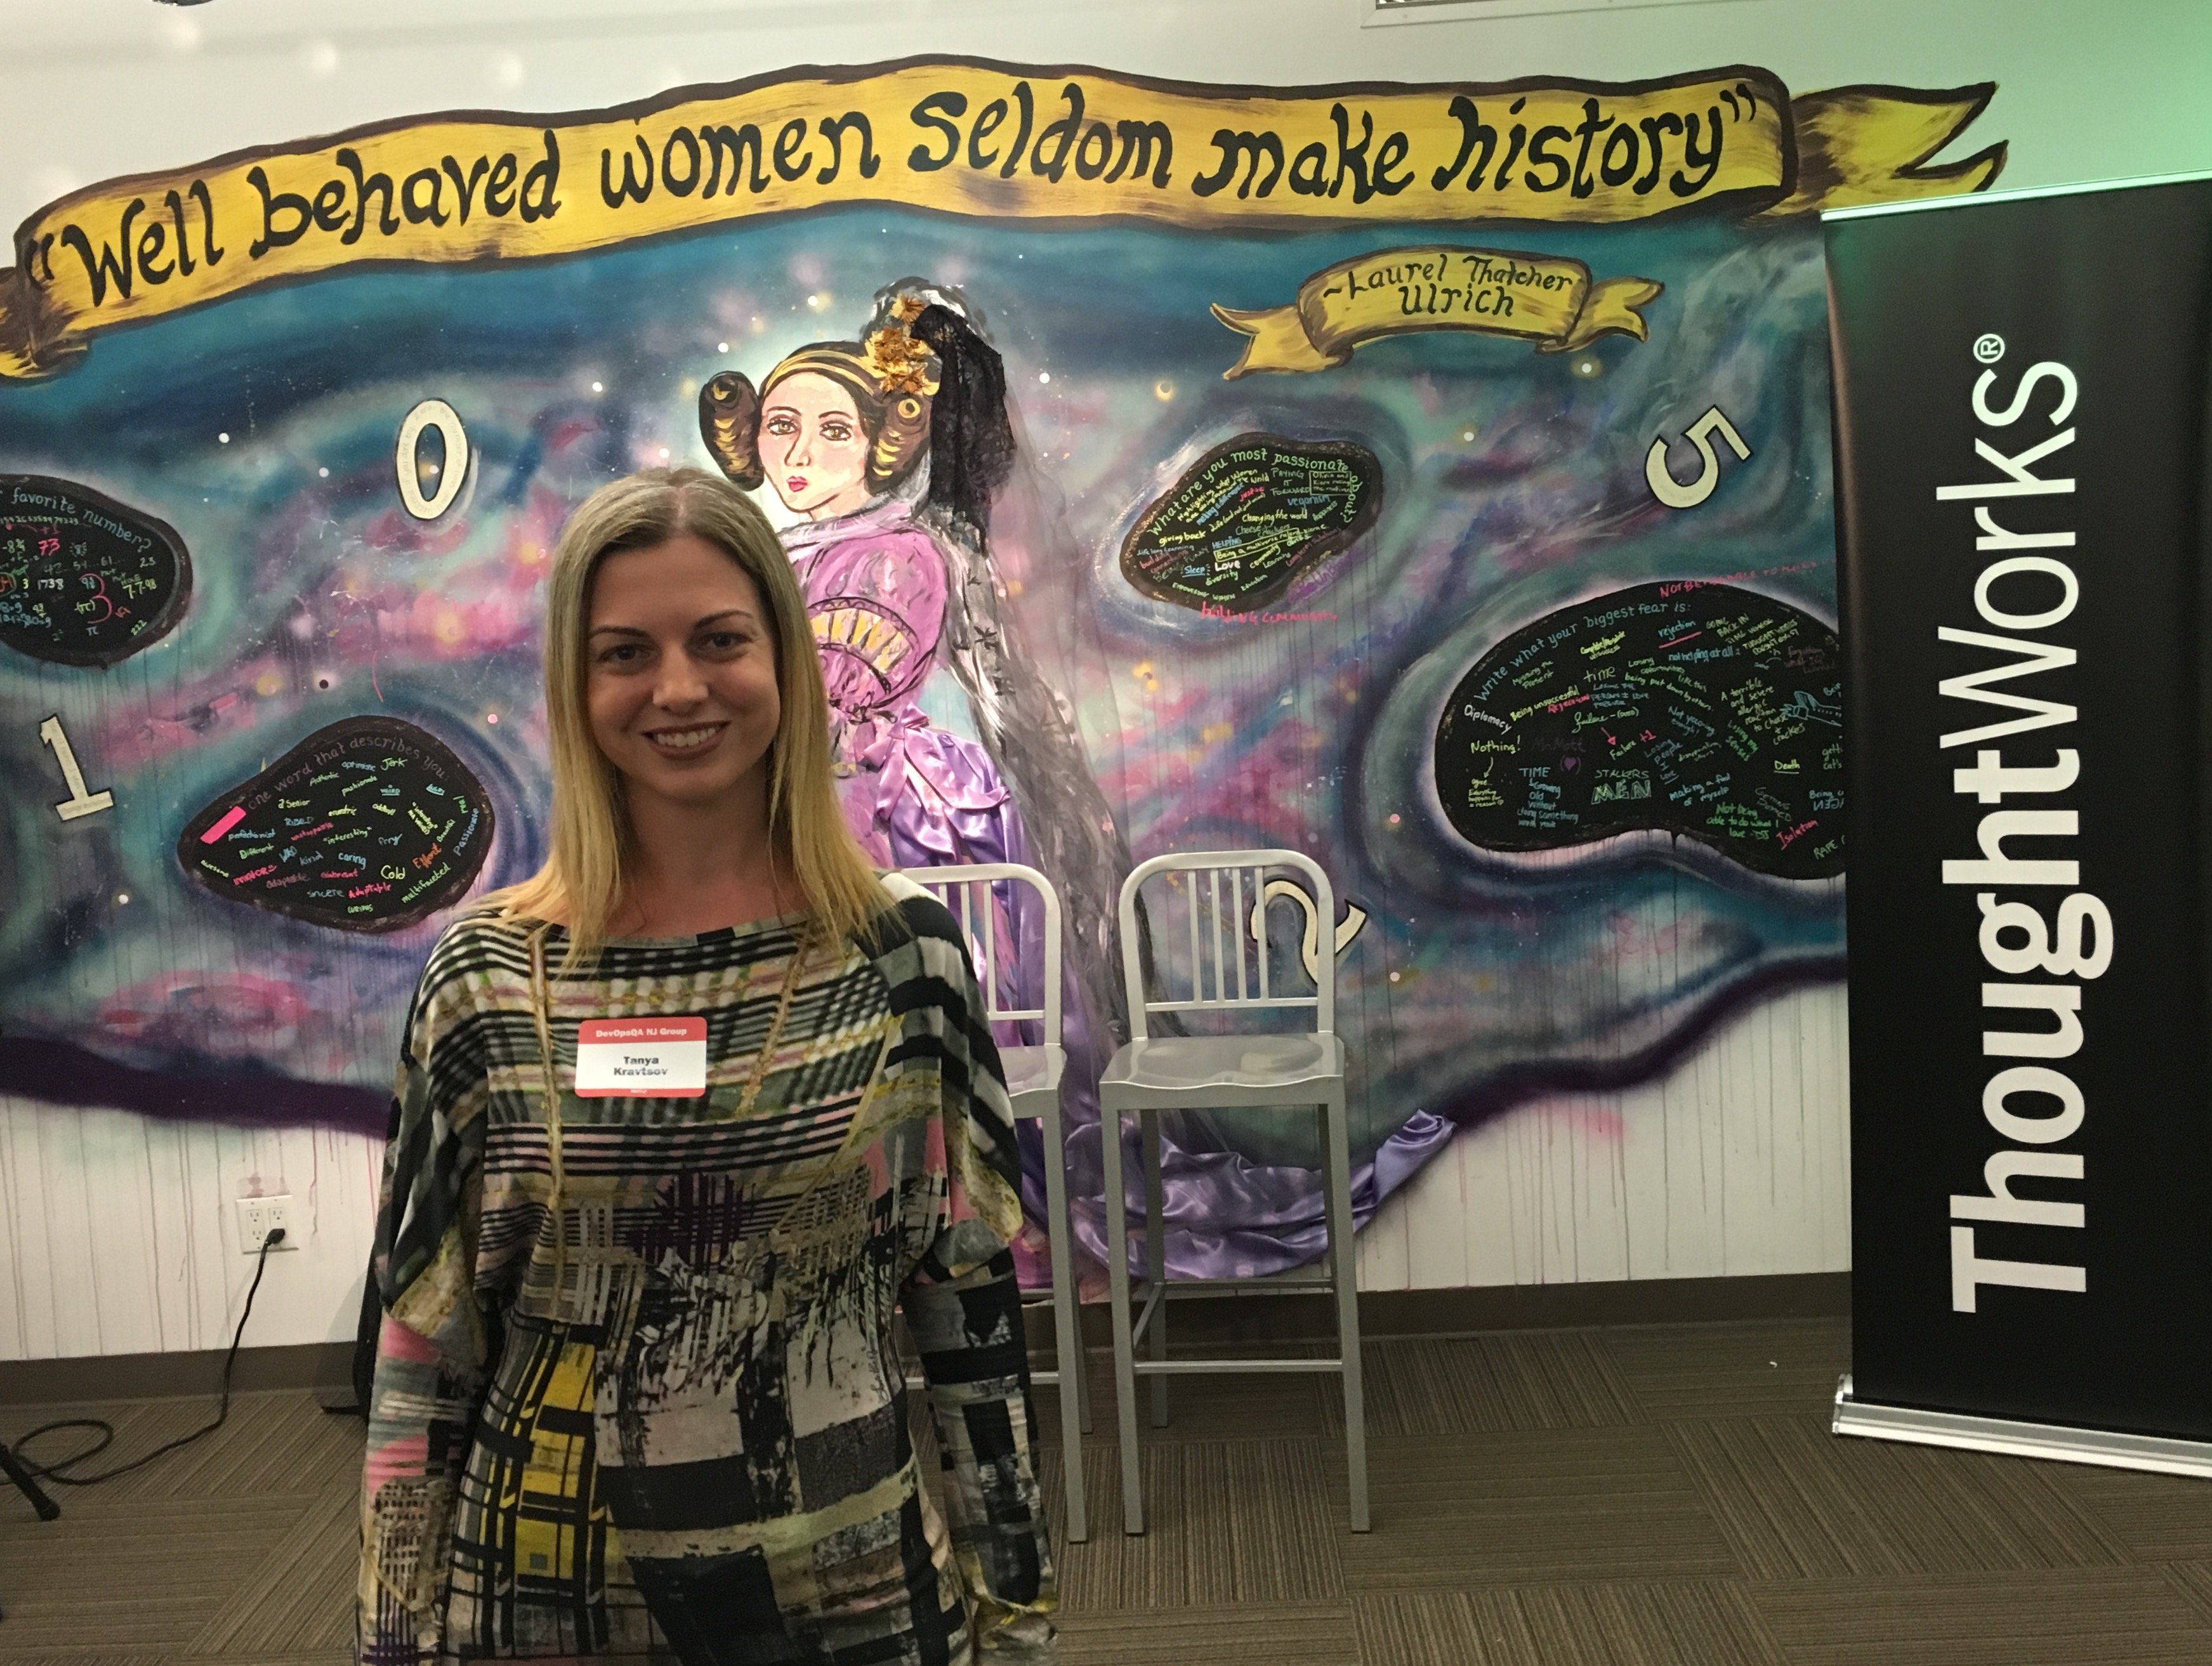
DevOpsQA NJ held our January Meetup on Pipeline Patterns, with Max Griffiths (@_maxamg), Max Lincoln (@devopsy) and Gary Stafford (@garystafford) from ThoughtWorks as speakers. The meetup took place at the sensational ThoughtWorks NYC location, with welcoming, open meet-and-greet area and a huge presentation area with bright, distinctive wall paintings.
Following speed networking with pizza and beer, the discussion kicked off with a brief intro from the speakers, who each has been in the DevOps space for 10+ years. They gave a high-level overview of ThoughtWorks and some  book recommendations including, “Continuous Delivery” by Jez Humble, “Release It!” by Michael Nygard and “The Phoenix Project” by Gene Kim.
So what is the issue that we’re trying to solve? We are trying to gain an ability to make decisions early on to impact how our pipeline is going to scale, with the focus on culture, feedback and governance.
Max Lincoln gave a good definition of a “good” pipeline. It should have incremental QA, fast feedback, visibility of the progress and a consistent, auditable software delivery process. It’s a good idea to be very selective with how you name things in the pipeline. “The purpose of the pipeline is to kill the build as soon as possible,” he said. As the pipeline gets longer, quick feedback becomes more difficult.
Next, each speaker addressed how the pipeline can scale in three difference directions: X (more stages between commit and productions); Y (more projects/applications); and Z (concurrent releases). Max Griffiths gave overview of X-Axis patterns which includ e Linear, Parallel and Layered (with artifact promotion and release channels). Linear is the simplest pattern, which works for simple applications. With a parallel pattern, you start to parallelize where possible; however, that might create dependencies and make it difficult to reorder. The layered pattern encourages parallelizing but prevents direct dependencies between stages.
The layered pattern is further enhanced by adding a separate artifact repository for each layer, which makes artifact retention policies a lot easier. You can use bronze, silver, gold as names for the layers to easily understand how release candidate progresses from one stage to another.
Gary Stafford introduced Y-axis patterns which include joint labeling, aggregate labeling, independent pipelines and VCS labeling. among  others. Gary used the Microservices example to demonstrate how to do continuous delivery with loosely related applications or services.
Max Lincoln spoke about concurrent releases with Z-axis patterns. As per Max, instead of a branching strategy, dev needs a merging strategy, especially if a release branch gets created six months in advance. “If you have Jenkins do 1,000s of builds a day, it does not mean you have CI,” he said. 
The speakers concluded by each introducing an extra pattern which they referred to as “different dimensions.” The parting word of advice was to keep CI (whether it’s Jenkins or GoCD) in source control and test your pipeline continuously. At the end we had a great Q&A session and a very warm, open discussion.
Looking forward to our next session.
If you would like to learn more about ThoughtWorks and/or Pipeline Patterns, you can continue the conversation on the GitHub page: https://github.com/thoughtworks/PipelinePatterns
Performance testing is a vital component of any developer’s working process. The performance of your website or app can be judged by a lot of people in your organization, both technical and non-technical.
Developers, operators and performance engineers are on the front lines when it comes to the development of a functioning site/app, but there will always be people away from engineering with comments, too.
“Can we make this faster?”
“Is the UI making this a little too slow?”
C-level execs, board members and marketers can often make the journey into becoming amateur web performance testing experts and critics, but that’s okay!
Web performance is widely accepted as a crucial factor in user experience—for example, when it comes to the e-commerce buyer’s journey. Your application better be fast, or you’re going to end up costing yourself conversions and money.
Instead of having these conversations after the development and testing has been done, we should definitely include all the stakeholders in the process from the beginning. Sound familiar? (ahem, DevOps, ahem)
Here are a few simple ways you can get everyone involved in your performance testing cycle:
Test Early
In the business of collecting data, getting a baseline is key. Test your minimum viable product (MVP) as aggressively as you would test your “final” product. If the MVP can’t stand up to some pressure early on, it might be in deep trouble moving forward.
Test Often—and Automate
The idea here is to create a performance trend to show if you’re moving in the right direction. More data points is always better.
The best way to generate many data points is to programmatically run tests after each code commit, either using continuous integration software or by having a post-commit hook or something similar in the source code control system that makes an API call to fire off a load test.
This way, you’re arming yourself with the right information to know when new code is impacting application performance, and you’ll know when to jump in and investigate changes right away.
Give People Access
We’re living in the era of transparency in software as a service (SaaS), so it’s always a good idea to give your coworkers access to your testing dashboard data. While some people in the organization might not wholly understand the technical side, it won’t be difficult for them to grasp that an increasing load time can be a bad trend.
There are all kinds of dashboard SaaS companies out there who can help you do this—assuming you want to stay away from pounding numbers into a spreadsheet or table every day.
At Load Impact, we’ve received a lot of feedback from engineers who were looking for an easy way to share test information with team members, and from that, we created the “Team Members” functionality.
Testers simply invite team members to their organization, and the new invitee can see past results and even create scenarios to be tested. That way, everyone’s in the loop, and everyone can get involved to the extent of their expertise.
Play Nice and Share
Continuous testing is a mindset as much as it’s a methodology. It fits neatly into the ideals of DevOps, and a big part of that is an inclusive, collaborative culture with your team members.
So remember, play nice with your colleagues—technical and non-technical—and you’ll create a productive, creative environment for everyone to thrive in.
What are some of the metrics you should be monitoring to track your DevOps efforts, and which metrics should you abandon?