Category: Blogs

  • Unqork Extends Automated No-Code SDLC Platform

    Unqork Extends Automated No-Code SDLC Platform

    Unqork today announced it has extended a no-code platform for managing the software development life cycle (SDLC) to include the ability to automatically document changes to application programming interfaces (APIs) and data models in addition to adding a point-in-time rollback capability.

    Ken Gavranovic, head of strategy and engineering for Unqork, said Unqork 2021.5 also adds a range of dashboards for monitoring application dependencies, service logs, revisions, logs and metrics.

    Finally, Unqork is adding tools to analyze, test and debug configurations along with enabling workflows to subscribe to events and adding a search capability for release candidates.

    Unqork is designed to present IT teams with a set of visual tools through which they can manage SDLC processes without having to build and maintain a platform made up of disparate offerings that they need to then integrate, said Gavranovic. The goal is to reduce the overall size of the team required to maintain an application development environment to enable organizations to allocate more time and resources to building applications, he added.

    The auto documentation for APIs is being added at a time when IT organizations are starting to employ a larger number of APIs as they transition toward building and deploying microservices-based applications. In addition to making it easier to reuse APIs, Unqork also now makes sure documentation for those APIs is always current, said Gavranovic.

    At the same time, Unqork is now providing a means to automatically document changes to data models based on a data store that is integrated in the platform, noted Gavranovic. That capability enables organizations to implicitly add governance capabilities to workflows with a minimal amount of friction.

    As organizations look to accelerate the rate at which applications are being developed to enable multiple digital business transformation initiatives, Gavranovic said more of them are starting to realize their existing processes are too complex and cumbersome to achieve that goal. Unqork is based on a data store that is shared by all the modules that make up the platform, which, in addition to enabling reusability, makes Unqork easier to deploy and manage, added Gavranovic.

    In addition, Gavranovic also noted that, over time, complex processes only increase the overall burnout rate of the development team. It’s hard enough to hire and retain developers today without requiring them to navigate a complex application development environment, he added. Eventually, the best talent will migrate to organizations that make it as easy for them to write code as possible, said Gavranovic.

    It’s not clear to what degree IT organizations will be revisiting the way they build software in the months ahead but as more of them realize how dependent the business now is on the timely delivery of software it’s only a matter of time before pressure to automate as much of the software development process as possible starts to mount. The cost of replacing an application development environment is, of course, not insubstantial. However, continuing to do the same thing with the expectation of producing a different result is, by definition, insanity.

  • Implementing an On-Demand Feature Environment

    Implementing an On-Demand Feature Environment

    Not long ago, developers at LeanTaas implemented an on-demand feature environment. It came about as the result of a collaborative effort to support a faster go-to-market strategy. Moving to an on-demand feature environment resulted in greater agility, effectiveness, quality and a better bottom line for the organization. With careful implementation, any development team can benefit from this exercise.

    With an on-demand feature environment, you can easily test specific features without disrupting development activities that already are in process. Setting up the environment can offer several benefits and enhance the overall outcomes of your product release. Here, we’ll walk through the steps we took to get this implemented.

    feature implementation

    First, we decided to come up with some standards and changes in our development practices:

    Naming Conventions

    Every Git branch name should start with the associated Jira ticket and include details about what that branch is for. We updated the Jira ticket with environment URLs, automated QA test results and comments from product manager reviews.

    Syntax:

    <JIRA_TICKET>-<SHORT_TITLE>-<PRODUCT_NAME>.<DOMAIN_NAME>.com

    For example, LT-123-demo-product1.xxxx.com

    In this case, LT-123 is the Jira ticket, demo is the short title, product1 is the product name and xxxx is the domain name. So, our feature branch URL would be accessible at https://lt-123-demo.product1.xxxx.com, and the internal name would be dev-product1-lt-123-demo, which developers can use to ssh and debug issues (if any) and refer to when they check logs (if necessary).

    Also, following a set naming pattern helps us write a regular expression in a front-facing server environment (we use NginX) that helps proxy/route the requests to the respective feature-specific runtime environments deployed in an AWS EC2 instance.

    If you are using NginX, you can use following regex to achieve this:

    server_name ~^(?<featurebranch>.+)\-product1\.xxxx\.com$;

    set $featurebranch dev-product1-$featurebranch

    proxy_pass https://$featurebranch;

    Data and Microservice Dependencies

    For the environment to work in its own isolated state, it needs a data set stored in its own database. So our teams came up with an automation script for generating an anonymized sample dataset that’s required for this feature instance. We packaged this data, along with other required artifacts, into a golden Amazon Machine Image (AMI) for the specific product. For easy reference, we stored this custom AMI ID in the AWS systems manager (SSM) parameter store so that our Terraform scripts can use this reference while spawning an EC2 instance.

    Once the feature-specific instance came up, we realized it couldn’t play well with our other microservices such as authentication, authorization or notification. They couldn’t differentiate between a real product instance versus a short-lived, feature-specific instance. So, we had to add an additional header in our internal requests, and enhanced these other microservices to be aware of this additional header so that they could exactly respond back to a feature specific instance. When it comes to usage of message services, every feature branch has its own SQS queue, which followed the same naming conventions of the internal hostname. Platform services relied on this same standard to ensure these feature branches worked seamlessly.

    Automation/Manual Quality Checks and PM Reviews

    Now that the feature-specific instance is up and running in its own isolated environment and with its own dataset, it enables a fully functional playground for the QA team and PM team to extensively test new features in an isolated fashion. Having this playground is a game changer for our productivity. It helped parallelize the iteration cycles. Each feature started getting its own feedback and progressing towards the finish line; essentially swimming in their own lane.

    Cost Considerations

    So far, so good. Feature-specific application instances are up and running and development iterations are progressing. But what is the lifetime of these instances? We don’t want to let them run forever; we also want to consider the fact that not every new feature will end up getting released. So, how do we handle such cases? We want to hook up these instance termination actions seamlessly into the developer’s work stream. Here’s how we solved for this:

    • Delete the feature branches-related infrastructure as soon as the feature branch itself is deleted.
    • Stop the EC2 instances every night and start them every morning by using a combination of AWS Cloud Watch Events and Lambda.
    • Automatically delete the feature branches that are active for more than seven days. We later ended up providing an additional feature; skip flag, for some feature branches because sometimes we’d end up making changes that were complicated or revamping things which needed more time.

    Notifications

    We use Slack, so we decided to send Slack notifications every time a feature environment was created and attach test results, as a thread, to the same Slack message.

    feature

    We also decided to use AWS tags and maintain branch_owner (developer name), branch_status (synced with Jira to indicate In-Dev, In-QA, PM Review, Code Review etc.) and tag EC2 instances. We also sent a daily report with the number of active branches, which helped in our daily standup and also provided a quick, at-a-glance overview of features that were ready for release.

    For implementation of CI/CD pipelines, we created a new Jenkins pipeline that had the ability to perform some prereq checks, code quality checks, build applications into Docker containers, spin up infrastructure using Terraform and deploy the Docker container into newly created infrastructure using Ansible, run automation tests against the feature environment and send notifications in Slack as well as update Jira tickets with the build URL and test results.

    feature

    Sample screenshot of our pipeline

    feature

    Once our feature environment was certified, then a pull request is submitted to merge in Master, before merging code review is performed by other developers and engineering leads, and then, finally, merged into Master. Once the feature branch is merged into Master, it gets deleted via a webhook.

    feature

    Now, code is built against the master branch and deployed into the master environment to ensure integrity. We perform one more round of QA using automated and manual checks, regression testing, internal penetration testing and performance testing. Once these are passed, the Docker image is finally promoted to production.

    Following these steps to a seamless implementation of an on-demand environment will help any organization take the same steps towards a more efficient process. If you can apply these steps to your workflows, your metrics could improve exponentially.

  • The Future of Low-Code is Open

    The Future of Low-Code is Open

    The low-code market is seeing meteoric rise across the world, as companies try to keep up with digitization demands and shrinking IT budgets. Even as we witness increasing low-code adoption among professional as well as citizen developers, an intriguing question comes to mind – What lies ahead for low-code, and could it ever become a mainstream approach for modern development teams?

    The answer may well be an open source, low-code platform that offers high productivity, while supporting seamless integration with the overall fabric of modern software development practices within an enterprise.

    It’s feasible to assume that low-code will evolve to become open low-code, resulting in greater innovation and agility.

    To further understand what this means, let’s dive deeper. What are open systems?

    According to Wikipedia, open systems are computer systems that provide some combination of interoperability, portability and open software standards.

    Over the years, the software industry has seen great benefits from designing, implementing and consuming open systems. TCP/IP protocol standards, UNIX systems, Web browsers, REST APIs – all of these are shining examples of open standards that went on to become highly successful and widely adopted. By remaining open, they enabled higher interoperability, streamlined development and fostered rapid innovation.

    Low-code is now at a critical stage in its adoption curve. For the last few years, we have seen citizen developers successfully execute shadow IT with low-code and churn out applications at a breathtaking pace. Today, low-code platforms are hardened for enterprise use, are programmed to understand the scalability and security needs of a complex application and have integration capabilities mature enough to seamlessly fit in with existing tools and technologies. As a result, we are now seeing greater adoption of low-code within the professional development community, covering a diverse set of use cases from simple dashboards to complex applications. The natural next evolution of low-code is that it becomes mainstream within enterprise IT, and is used to build mission-critical applications and systems. So, how does this next phase play out for application development?

    The Case For an Open Low-Code Platform

    The approaches and techniques of modern software development teams has changed dramatically to meet the demands of modern, software-enabled business. Developer velocity and organizational agility have become key benchmarks for high performing software development teams, as those metrics have a direct correlation with software excellence and superior business performance. According to a research report by McKinsey, teams that belong to the top quartile with regards to developer velocity score have 60% higher total shareholder returns and 20% higher operating margins. Such teams can experiment faster and release code to production without delays.

    As application teams continue to embrace low-code for mainstream development, it is vital that low-code platforms support developers so they are encouraged to employ modern application development and delivery best practices. Low-code should introduce minimal disruptions to a developer’s working practices and workflow. Also, it is important that low-code can integrate seamlessly with the fabric of the overall enterprise application architecture. This can happen if a low code-platform is open standards-based and flexible so that the rest of the enterprise application infrastructure can coexist with it.

    What Makes a Low-Code Platform Open?

    Developer-Centric Features

    Developers like control, flexibility and a unified experience. They find comfort in sticking to their preferred languages, tools and application development and delivery workflows. A low-code platform that offers productivity with equal flexibility, with a focus on building robust enterprise architecture, is bound to be the future of application development. Platforms should focus on providing a unified developer experience across concept, design, integration, development and deployment stages of the app life cycle, employing a technology stack that is modern, best-of-breed and cloud-native. It’s equally important to provide a way for developers to easily bring any external innovations into the low-code platform.

    Visualization, Customization and Ownership

    Many low-code platforms do not generate 100% of an application’s code. Also, most of the code generated by proprietary platforms is also proprietary, and quite often remains hidden and not easily accessible or extensible. A platform that generates open standards-based, real code is a great asset, especially for professional developers building complex applications that require extensive customization and deep integration with enterprise tooling (security, testing, debugging, integration etc.). The code generated should be based on developer-friendly, best-of-breed application stacks and standard design patterns. This way, application teams will have complete familiarity with and understanding of the code. Enabling full export of the code allows teams to own the code created by the platform.

    Flexible Application Architecture

    The application architecture should be loosely coupled, supporting microservices and micro front ends that can be independently built, deployed and scaled. This way, architecture can support cloud-native application development easily. Also, all other aspects of the application life cycle should allow for plug-and-play capability. This includes, but is not limited to, plugging in custom UI components (widgets, templates), custom security providers, custom back end code, logging frameworks, event driven systems, etc. A plug-and-play model ensures that development teams can integrate custom providers that are fine-tuned for the enterprise.

    Modern Development Best Practices

    Modern application development practices have evolved to allow teams to experiment faster and release code to production at a never-seen-before pace. Optimizations in performance and scalability have resulted in applications that can support millions of end users. As developers warm up to low-code, the platforms should align with and implement all modern development practices while building applications. The idea is to minimize friction in a developer’s journey towards low-code, so that they continue to leverage the same design principles, application tooling and enterprise integrations as they do in the complex programming world.

    Infrastructure-as-Code (IaC)

    Developers need a way to continuously deploy software so there is always a version of the application ready for production. Low-code platforms should support an IaC option, so code generated is always deployable seamlessly on the developer’s infrastructure of choice. Platform should integrate to build, test and release systems (version control systems, CI/CD, artifact repos, container image repos, Kubernetes clusters and public or private cloud instances, for example). This way, artifacts built by low-code are continuously integrated and deployed to the enterprise’s operational systems.

    Low-code is at an inflection point within enterprises, as it becomes the platform of choice for digital transformation and application modernization. This is the opportunity for low-code platforms to become a key ingredient of an enterprise application architecture. An open low-code approach will allow application development teams to benefit from the underlying best practices prevalent within the organization.

    Low-code is not merely a productivity tool; it has the potential to be a technological and cultural catalyst that drives enterprise innovation and business agility.

  • Le Morte d’Arthur— A DevOps Engineering Journey

    Le Morte d’Arthur— A DevOps Engineering Journey

    The stories of King Arthur have fascinated me from the time I was young. Now that I am old DevOps_the_Gray, I enjoy relating the story of King Arthur to my experiences with DevOps. I hope you find this blog interesting and relevant too.

    Imagine a boy raised in Britain by the wizard Merlin who becomes king because he can pull the magic sword Excalibur from a stone. Once king, he unites warring tribes, forms a brotherhood of knights and creates a round table to be sure everyone who sits around it has equal status as they pursue the quest for the Grail.

    DevOps as the Grail of Software Creation and Delivery

    To engineer DevOps, even the first way of DevOps—continuous flow (harmony)—requires faithful employment of leadership (King Arthur), collaborative team culture (the Knights of the Round Table), disciplined engineering processes (laws of Camelot), technology (Excalibur) and automation (the magic of Merlin, Archimedes and Nimue). The ultimate pursuit of the third way of DevOps—continuous improvement (quest for the lost Grail)—requires persistent commitment to engineering discipline and noble practices.

    DevOps also requires a persistent evangelist (Nimue, the Lady of Avalon) and leadership (Morte d’Arthur) to be forever vigilant and ready to lead DevOps’ evolution into the future (King Arthur is forever ready to rise again with Excalibur).

    Both King Arthur and DevOps depend on the virtuous tenets of chivalry/culture, laws/ processes and use of Excalibur/technology.

    Arthurian tales represent a masterful integration of historical events with misty, imagined magical episodes and, like DevOps, embody tenets of chivalry and respectful moral leadership. While the means can be elusive, the results can be magical. The sword Excalibur and the search for the Grail are powerful symbols that remind me to always try to engineer technology for good and noble purposes.

    The Arthurian Analogy Expresses the Importance of DevOps

    “Then there entered into the hall the Holy Grail covered with white samite, but there was none might see it, nor who bare it.” —Le Morte d’Arthur, BOOK XIII CHAPTER VII

    “…said Sir Gawaine, we have been served this day of what meats and drinks we thought on; but one thing beguiled us, we might not see the Holy Grail, it was so preciously covered. Wherefore I will make here avow, that to-morn, without longer abiding, I shall labour in the quest of the Sangreal.” —Le Morte d’Arthur, BOOK XIII CHAPTER VII

    Like the Grail, DevOps is too often regarded as an ethereal thing, earnestly sought after and pursued. To do DevOps well means treasures and miraculous benefits; satisfying, harmonious production; and competitive advantages in abundance.

    Like Arthur’s battles, hard work and skills are required for success with DevOps.

    “King Arthur rode in the battle exhorting his knights to do well, and himself did as nobly with his hands as was possible a man to do; he drew out Excalibur his sword, and awaited ever whereas the Romans were thickest and most grieved his people, and anon he addressed him on that part, and hew and slew down right, and rescued his people; and he slew a great giant named Galapas, which was a man of an huge quantity and height, he shorted him and smote off both his legs by the knees, saying, Now art thou better of a size to deal with than thou were, and after smote off his head. There Sir Gawaine fought nobly and slew three admirals in that battle. And so did all the knights of the Round Table.” —Le Morte d’Arthur, BOOK V CHAPTER XII

    DevOps, At its Best, is Engineering Greatness

    In my experience, well-engineered DevOps always starts by defining a great goal. Greatness is won by careful, inspirational leadership, measured tactics, superior technology, a culture of collaboration, courage and unwavering persistence in applying skills to the task until the goal is attained. To engineer is to do the noble work of engineering. DevOps engineering requires the skills of elite leaders and engineers that have a profound understanding of DevOps practices.

    DevOps’ Enduring Legacy and Future

    “Yet some men say in many parts of England that King Arthur is not dead, but had by the will of our Lord Jesu into another place; and men say that he shall come again, and he shall win the holy cross.” —Le Morte d’Arthur, BOOK XXI CHAPTER V-VII

    DevOps implementations – and DevOps itself – are not immortal.

    As DevOps leaders, experts, and evangelists come and go, the perceived value of DevOps may wax and wane. The fame of innovative new technologies expires ever more quickly with the acceleration of technological systems facilitated by stacking technologies higher and higher.

    Epilogue

    The stories of King Arthur teach us to lead passionately when needed to triumph against DevOps challenges and to continue the pursuit of perfection. I hope you find this Arthurian DevOps analogy as relevant and interesting as I do, and I hope that it adds a little uniqueness and fun to your DevOps understanding. If you would like to see more on this analogy, I refer you to the only DevOps book with the sword Excalibur on the cover. Now, on with the quest of engineering DevOps!

    Marc Hornbeek – DevOps_the_Gray, esq.

  • Netlify Acquires FeaturePeek to Streamline App Feedback Process

    Netlify Acquires FeaturePeek to Streamline App Feedback Process

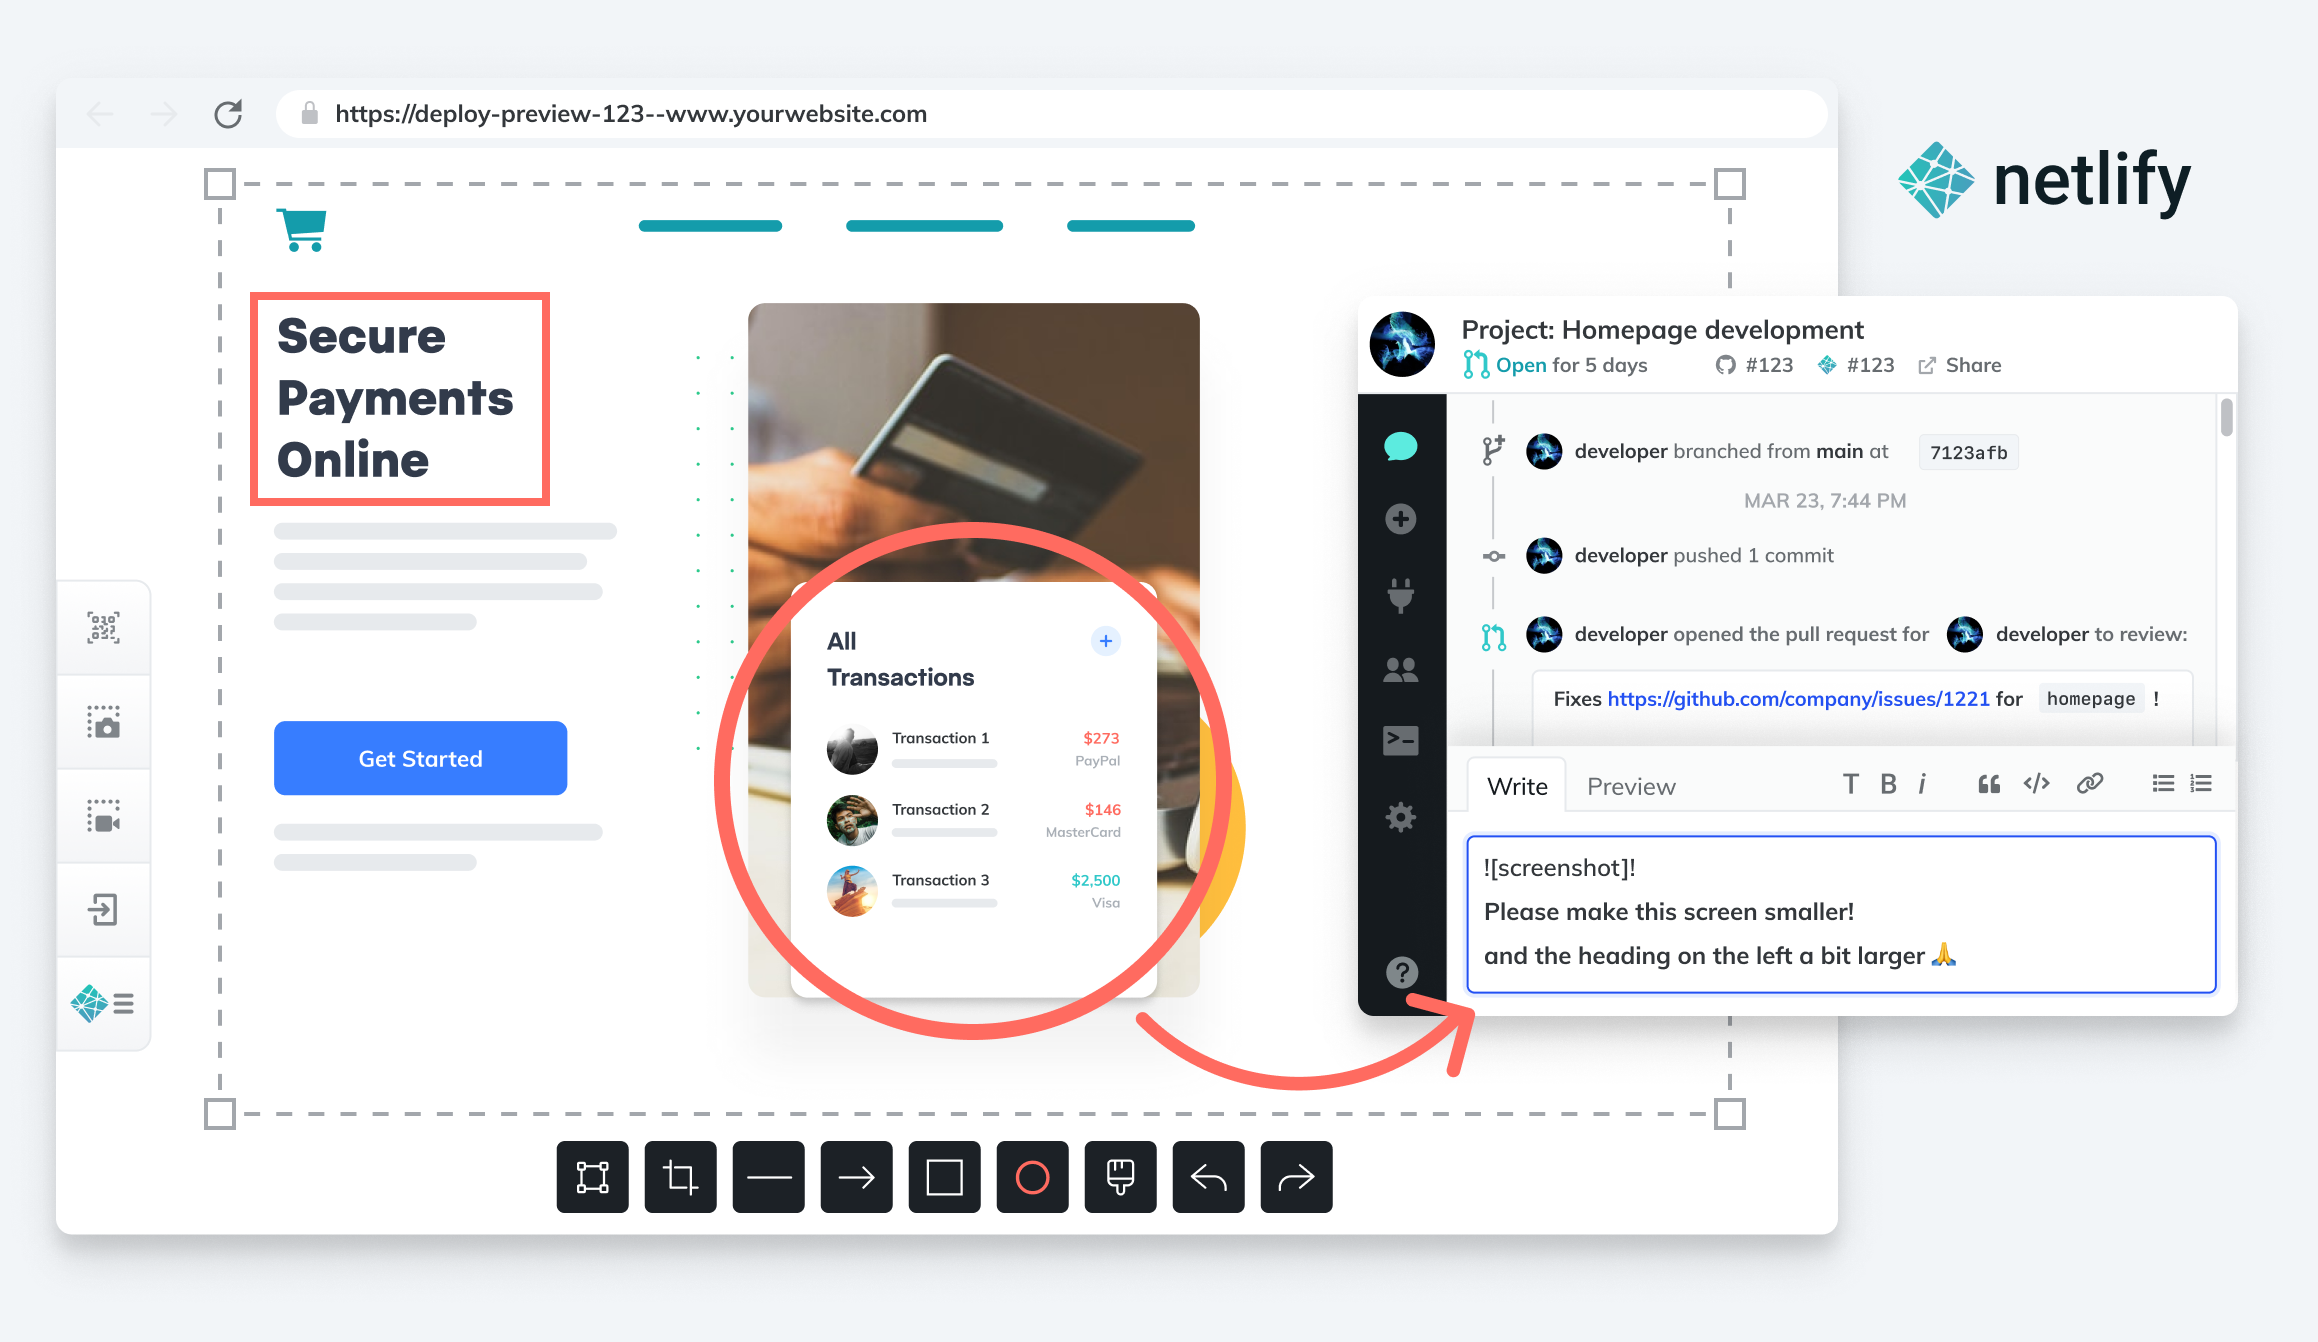
    Netlify announced today it has acquired FeaturePeek as part of an effort to make it simpler for DevOps teams to create a portal through which application stakeholders can both inspect a web application developed using JavaScript and leave comments for developers.

    Matt Biilmann, CEO of Netlify, said Netlify will embed that collaboration capability in the next iteration of its Netlify Deploy Previews. That tool makes it currently possible for a front end pull request from a Git repository to automatically generate a live preview of the site with a unique shareable URL.

    The current version simply shares URLs with application stakeholders, versus enabling DevOps teams to create a portal through which the review process can be centrally managed to make feedback more consistent, said Biilmann. Each piece of feedback from an application owner or stakeholder made via the portal will become a comment on the Git pull request, or can be shared via any collaboration tool a development team employs alongside a Netlify workflow, noted Biilmann.

    In the meantime, Netlify is also making available a free user role license for reviewers that want to make use of Netlify Deploy Previews to view recent updates to applications.

    Netlify has been driving adoption of a serverless computing framework based on a JAMstack architecture for building JavaScript applications faster. An application based on a JAMstack architecture isolates the front end and back end end of an application to make it possible to prebuild front ends that are highly optimized around static pages to make web applications faster. The name JAMstack is a mashup of JavaScript, application programming interface (API) and markup language.

    The need for more collaboration between developers and stakeholders has become more pronounced, in part, because organizations have significantly accelerated the rate at which they are investing in digital business transformation initiatives, noted Biilmann. With organization more dependent on software than ever, it’s critical for them to streamline the feedback cycle as the number of application stakeholders within organizations steadily increases, added Biilmann.

    As the relationship between DevOps teams and the rest of organization continues to evolve, the amount of feedback any team is likely to receive will continue to increase. Everyone from sales teams to the board of directors now realizes how dependent the business is on software. DevOps teams will need to way to organize and prioritize that feedback. They should also expect application owners and stakeholders to follow the progress of software development projects more closely than ever because, in many cases, financial projections are now based on assumptions being made about software delivery timetables.

    Many DevOps teams have been making the case to have a more central role in business planning for years. Now that many of them are getting a seat at the proverbial business planning table, however, they may soon realize they don’t really have the processes in place to absorb the overabundance of enthusiasm and anxiety that application stakeholders are likely to generate in equal measure.

  • ZenHub Brings More Science to Sprint Planning

    ZenHub Brings More Science to Sprint Planning

    ZenHub today revealed it has added a Planning Poker capability to its platform for managing software development projects that is designed to make it possible to prioritize sprints based on feedback collected from members of the application development team.

    That capability extends a sprint planning capability the company added this year to a project management application designed specifically for software development teams that employ the GitHub software repository. That sprint planning tool also automates routine tasks, such as automatically carrying over unfinished work to the next sprint.

    Aaron Upright, head of strategic accounts for ZenHub, said collectively, those capabilities will make it possible for development teams to prioritize their efforts in a way that is less biased using points that weight the opinions of team members based on how accurately they have made previous forecasts. For example, Planning Poker will assign a different weight to a developer that is consistently either overly optimistic or pessimistic about the length of time required to complete previous projects.

    Planning Poker is built right into GitHub, which Upright noted allows developers to make estimates without having to exit an environment where they already spend a good portion of their day.

    Thanks mainly to both an increase in and acceleration of the digital business transformation initiatives organizations have launched, DevOps teams are under increased time constraints.

    Many organizations’ entire business strategies now revolve around the rate at which software development projects can be completed. Many elements of those projects can’t go forward until a specific component upon which it depends is completed. Investors are holding business leaders more accountable for software delivery timetables that have direct implications on revenue generation.

    Not surprisingly, the type of end users that are now accessing project management applications to keep tabs on development progress has increased. Everyone from the sales team to the board of directors now wants more visibility into the rate at which software development projects are being completed. The challenge DevOps teams face is software development is an inexact science. Developers, based on individual personalities, exacting standards and willingness to work extra hours, are going to have widely divergent opinions on how long it may take to complete any given sprint.

    Nevertheless, Planning Poker presents organizations with an opportunity to rely on a more scientific approach than traditional guesswork, said Upright. The simple fact of the matter is that all estimates are wrong. The goal is to narrow the margin of error, he added.

    Regardless of how application development projects are managed, the relationship between DevOps teams and the rest of the organization has fundamentally changed. The entirety of some organizations is wholly dependent on the speed at which high-quality software is developed. In many cases, expectations are not realistically aligned with available development resources. A project management application that is widely employed across an organization should make that apparent to all interested stakeholders, which, in theory, at least, should result in either the hiring of additional developers or reassessment of the business strategy before the existing development team simply decides to abandon ship altogether.

  • Prevent False Positives From Derailing Shift Left

    Prevent False Positives From Derailing Shift Left

    Static application security testing (SAST) tools are designed to balance false positives (incorrect warnings) with false negatives (missed vulnerabilities) primarily because deeper analysis requires more time and computing resources. Both of these are in short supply among developers that are tasked with meeting shorter and shorter product delivery milestones.

    So, while SAST vendors consider a true positive a correct detection of a real defect, and a false positive an alert on a bug that does not exist, this is rarely the lens used by developers. What really matters to them is whether the output of a SAST tool is useful and actionable. For example, there is a great deal of variation in how developers interpret SAST scan results, depending on the nature of the defect, the role of the user, the platform on which the application will run and the environment in which it is deployed.

    Take, for example, a true positive result of a buffer overrun, one of the most notorious classes of C/C++ defects from a security perspective. In the early stages of application development, it almost always makes sense to change the code to fix such a bug. Developers are actively changing the code, anyway, so fixing it involves little extra overhead. However, if the same defect is found after the application has been deployed, then it is much trickier to decide whether it is worth fixing.

    That’s because the cost of fixing a real bug may exceed the benefit of fixing it, and the benefit of “correcting” a false positive may exceed the cost of leaving it alone. Since SAST tools can only be relied on to give narrow technical answers, humans must interpret and determine which static analysis results should be acted upon.

    Consider a hypothetical comparison of different SAST tools in the graph below. Tool A has good recall (i.e., the ability to identify real defects) and precision (i.e., the ability to exclude false positives) which results in finding many of the real bugs with a reasonable amount of false positives. Tool B has high precision but poor recall, resulting in low false positives but a higher number of false negatives (undetected security vulnerabilities). Tool C has poor precision but high recall, resulting in detecting all the possible errors but also with a very high number of false positives.

    A comparison of recall and precision of hypothetical SAST tools.

    Developers hate false positives because they introduce unnecessary work and delays. This, in turn, has a disproportionate effect on the way tools are designed, configured and used. If given a choice between Tool A that reports 40 real defects and 10 false positives, and Tool B that reports 50 real bugs but with 50 false positives, users will almost always prefer the former, even though it is finding fewer real defects. This is perfectly understandable — users are asked to weigh an immediate concrete negative (time spent looking at false positives) against an intangible potential future positive (vulnerabilities that may not show up).

    However, if one offsets the time and risk saved in finding those 10 bugs earlier (i.e. by avoiding expensive and potentially dangerous bugs in finished products) against the time needed to assess the additional 40 warnings as false positives, then it quickly becomes apparent that configuration B is more economical. This is especially true with security vulnerabilities that slip through testing and can have expensive consequences.

    Since the number of warnings within a DevOps pipeline can be a deterrent to getting the most out of a SAST tool – especially early in the project, when it provides the greatest benefits – organizations should consider the following techniques to increase developer attention to alerts:

    • Filter and Focus: Parse the viewed data from the tool’s interface, focusing on what is most important for the project and assigning developers to fix critical issues in priority order.
    • Mark and Defer: Lower the priority, or change the state to “later,” for example, on all or a subset of the warnings based on some set of conditions that are less crucial to the project.
    • Stop the Bleeding: Use the above techniques to temporarily defer existing warnings with the emphasis on fixing new defects that are introduced as code is changed or new code is developed.

    Despite the fact that it will invariably produce some false positives, SAST helps shift security further to the left by ensuring security and programming vulnerabilities are eliminated when code is being written, rather than at the testing stage when they are much more expensive to fix. Filtering and prioritizing warnings are two effective techniques to ensure developers don’t throw out the baby with the bathwater.

  • Best Practices for Building Next-Gen Software Teams

    Best Practices for Building Next-Gen Software Teams

    Technology is moving faster than ever before. The pandemic has accelerated digital transformation across every organization in every industry. Creating new remote working environments or developing new digital revenue channels has taken place at lightning speed over the past year.

    At this time of rapid change, software development teams are continuing to help organizations adapt to our new environment and stay ahead of changing consumer habits. They also have to deal with their own personal situations and shifting organizational priorities – from new COVID-19 protocols to virtual offices.

    As 2021 progresses, what are the elements that can help business leaders stay ahead of the latest innovations and build resilient, forward-looking teams? Here are three tips I believe will help build next-generation software development teams.

    Put Your People First

    Finding the right people is never an easy task. Hiring for the skills you need to fill a role is important, but it’s also necessary to look beyond those requirements. Having the right technology skills is not always the be-all-end-all when it comes to hiring. Is this candidate a good fit from a cultural standpoint? Will they be engaged and motivated? Are they interested in learning and growing their own skill sets? Do they have different experiences and perspectives than your existing team members? Each team member brings something special to the table, and treating each person as an individual and as an essential part of your larger operation is crucial. Everyone should feel valued and connected to the company. This is especially true during the pandemic. Managing with a sense of empathy, understanding, and caring helps team members feel a sense of belonging and as though their job matters – because it does. When employees feel that their role is undervalued or unnecessary, they can easily become detached and uninterested. Hiring for the person and caring for your people during and after work hours builds better teams and keeps them connected to the business and mission.

    Allow Software Teams to Experiment

    Staying ahead of the latest trends and technologies is critical for delivering advanced software. Experimenting and allowing your teams to try new things can go a long way to drive innovation. It gives them opportunities to learn new applications and ways to deploy new technologies. Continuous training is a key part of the experimentation process. Our teams, for example, actively participate in more than 20 events per month. We also invite clients to join and participate, adding another layer of value for our clients. These events come in different forms and settings. They are virtual, gamified and often employee-led. The idea is to create space for open-minded discussions, team-building exercises and knowledge sharing. For example, our head of digital security leads regular sessions to educate our people on evolving security threats and effective security strategies to defend against them. Adapting to new ideas and building expertise in new technologies require a “no fear” mindset. Having the freedom to experiment and learn from each other provides the framework to keep teams ahead of the latest digital trends.

    Empower Your People

    Giving team members a certain degree of autonomy and responsibility for decision-making in their daily work improves innovation and productivity. When you empower employees to make their own decisions and decide their own path to success, you create a better workplace culture. At Cinq, for example, all one thousand of our developers know what projects we are engaged with across the company. Not only are they aware of what’s happening, they know the project goals, objectives and KPIs of every client engagement. Team members can request to be added to certain projects and teams at any given time. They may be interested in the client’s business, want experience with a new application or have an idea or suggestion to help us achieve our goals. We also give them the tools and resources needed to successfully manage or lead their own projects, which can lead to massive innovations inside our own business. Empowered employees are loyal, committed and more productive. When employees are given opportunities to work toward their goals and drive their own careers, the benefits are enormous.

    Staying ahead of new technologies and applications can be a challenge for even the most tech-savvy organizations. Recruiting motivated learners, empowering your employees to move across teams, and creating opportunities for experimentation are critical elements to building next-generation software development teams.

  • Our API Mess is Coming

    Our API Mess is Coming

    APIs are the satisfaction of a long and deep need to be able to create consistent and reliable integrations between disparate systems, operating systems and datasets. As we started to use REST-based APIs, we also realized they fulfilled a previously little-addressed gap in automation. Frankly, they are a force multiplier in DevOps delivery.

    Early efforts at system-independent APIs were not great, but we learned lessons and are steadily getting better. While REST is the default solution for APIs, it probably isn’t the end of the road, as we continue to learn and improve. That’s what we in tech do – get excited about an idea, drive it to broad use and then iteratively improve it.

    And that’s the root of the problem. We have been, and are, saturating our applications with APIs. Internal, external, external-that-rely-on-another-external. The thing that comes to mind every single time I look at an API dependency map for even a medium-sized application is “spaghetti code.” Those lines are going all over, quite frequently returning to themselves.

    And we’re going to have to maintain this creation. Maybe not us, individually, but us as in IT and DevOps teams. The only constant is change, and far too many of us are not only failing to plan for API changes, but failing to even think about them. Because things are generally going swimmingly and most IT managers and DevOps teams have more urgent things to think about.

    But risk management – particularly broad risk – is an essential part of future planning. If you lose access to external API X, what will you do to keep your application running? If you lose an entire internal system that hosts API Y, how can you recover in a timely manner? While most organizations will identify and repair single points of failure, the solution is a pool, and the impact of losing Z servers in the pool needs to be understood, if nothing else – questions like, “At what point would user experience be impacted?” need to be asked, and a plan formulated to keep that from happening.

    We are already seeing issues created by using external APIs. All of them are predictable – an API going offline, or even disappearing completely; an API interface or attendant data format change; a change to the algorithms underlying the API, causing a change in data results, etc.

    API usage is far easier than it has historically been – and companies are working hard to make it easier to access APIs, both yours and others’. This is a good thing, as it means less time spent figuring out and tweaking API calls and request data. But it means our API dependence will only grow, and the number of lines in our dependency graphs – each representing some amount of risk – will only grow.

    “But we’re doing things in the cloud, so we can auto-scale, and failures are no longer and issue for us!” some shout. While that can help some scenarios, it doesn’t help others – if a vendor goes under and takes an API you use with it, or a preferred vendor (or inside component) becomes a security risk, you’ll still need to take steps. Knowing what and where your weaknesses are before they become issues is important, and worth your time.

    Most of you are killing it, cranking out solutions faster, iterating to make them better, using APIs to extend functionality and reduce delivery times. I’m just saying, stay aware of the technical debt you’re creating, because debts always come due, and risks eventually become issues. So know what’s a risk in your infrastructure, and have a plan to react when it does cause problems.