Category: Blogs

  • How Network APIs Will Finally Realize the Potential of 5G Slicing

    How Network APIs Will Finally Realize the Potential of 5G Slicing

    The applications used by people and businesses today run over the top of the network. That is, they use the network to transmit data from one point to another but don’t interact with the network in any way.

    As those applications get more advanced, that comes with a risk. If the network isn’t provisioned adequately, a self-driving car, for instance, might suddenly lose connectivity and freeze in the middle of an intersection.

    That’s why developers are progressively realizing they’re going to require more from the network if they are to create revolutionary new applications. But the catch is they’re also not network specialists.

    Instead, they yearn for quick and simple ways to tap into and onboard 5G network capabilities within their applications — to dynamically adjust connectivity speeds based on real-time conditions, for example. That’s where network application programming interfaces (APIs) enter the picture.

    In 2023, the telecoms industry committed to unprecedented levels of openness with the announcement of the GSMA Open Gateway initiative and the growing popularity of the CAMARA project.

    In 2024, there is an expectation that there could be even more momentum around and demand for open network APIs as developers start to get real access to them — and begin to explore the potential of leveraging specialized network capabilities, delivered through techniques such as network slicing for their enterprise and consumer applications.

    What are Network APIs and How Will They Be Used?

    A network API is like any other API that allows for two or more applications to communicate with each other. It’s just that, in this case, one of those applications is the network itself.

    This is possible because today’s cloud-native 5G networks are fundamentally software-based, meaning they are also programmable through APIs and other software development tools. So unlike the networks of years ago, which were more hardware-dependent and closed in nature, developers can now get easy access to deep functionality and data within the network.

    Through a network API, applications and networks can share information about their status and needs, allowing for optimizations to be made on either side. The network could signal to a drone or autonomous vehicle where other related devices are operating or whether congestion is likely to occur in a given area, enabling on-the-fly route changes to maintain optimal performance. Or the application could use that information to request specialized capabilities from the network in certain situations, such as low-latency connectivity or more uplink capacity.

    The ability to deploy specialized network capabilities for specific applications in specific locations may sound familiar. It’s essentially the promise of network slicing, which was promoted heavily in the early days of 5G rollouts but never really caught on as expected.

    This is largely because network slices have to be planned for and provisioned well in advance — a dealbreaker for applications that need to manipulate parameters such as quality of service based on real-time conditions.

    Network APIs change that, providing access to specialized network capabilities in a dynamic, automated way — whether by spinning up a network slice or through the use of other telecommunications tools. The emerging applications of tomorrow will increasingly require such specialized network capabilities.

    Consider beyond visual line of sight (BVLS) drones that are operated remotely by a person hundreds of kilometers away. As the drone travels, it will need different network capabilities at different parts of the journey based on the unique conditions it encounters along the way.

    Deutsche Telekom has been working to deploy network APIs for this very scenario, which includes APIs for location verification (for more precise tracking of the drone’s position) as well as “quality on demand,” so that as it passes over highly congested areas where thousands of people are also using up network capacity, the drone can get greater prioritization to ensure it doesn’t fall out of the sky.

    That’s just one potential use case. Network APIs can open up innovations for industrial robots, real-time streaming of immersive video using multiple cameras, latency-sensitive applications like VR and cloud gaming, and much more.

    Creating a Network-Powered System Ecosystem

    APIs can help foster a network-powered ecosystem of digital innovation that brings benefits to everybody involved. By being able to leverage specialized network capabilities on demand, developers can create innovative applications and experiences for their customers — transforming their ideas into real solutions.

    Existing applications can also be enhanced for better performance, such as drones that can reliably transmit high-definition video from any location and under any circumstances to improve the situational awareness of first responders and public safety agencies.

    For the communication service providers (CSPs) who operate the networks, these APIs will help deliver a better return on investment for their 5G infrastructure. Revenue growth for traditional communications services in both the consumer and enterprise markets is limited by an unwillingness to pay more for those services and the perception that value lies in the applications rather than the network.

    Thus, the need for CSPs to develop new revenue streams has never been greater. By charging developers for access to the network APIs — and by forging closer connections to the applications that will use the capabilities within the network — CSPs will be better able to generate monetizable value from their networks.

    What’s Ahead for Network APIs

    APIs have been around for more than two decades. The fundamental principles of network slicing have been talked about since the introduction of 4G. While these technologies have been around for years, they will come together in exciting new ways in 2024, enabling entirely new possibilities.

    In the year ahead, there will likely be a greater demand for specialized network capabilities among application developers. That demand will be driven by early digital adopters in industries such as oil and gas, automotive, industrial and high-tech manufacturing, public safety, security, gaming and entertainment, and others.

    But it’s important to note that no one company can make all this work. There needs an ecosystem of companies coming together. Developers need to demand it, and CSPs need to build systems and platforms to support it.

    Infrastructure vendors will play a role as well, with network as code platforms to provide easy access to network APIs — serving as the bridge that enables greater levels of collaboration, innovation and mutual growth so everybody can harness the full potential of 5G networks.
  • Chronosphere Acquires Calyptia to Process Log Data More Efficiently

    Chronosphere Acquires Calyptia to Process Log Data More Efficiently

    Chronosphere today announced it has acquired Calyptia to add additional pipeline management capabilities to its observability platform.

    Calyptia created Fluent Bit and Fluentd, a set of open source log processors that are now being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    Chronosphere CEO Martin Mao said these log processors will be embedded into the company’s namesake observability platform to enable the routing, transformation and optimization of log data at scale. That issue has become problematic because cloud-native applications based on microservices create exponentially more telemetry data than legacy monolithic applications. If it becomes too costly to analyze that data, then DevOps teams will begin to limit the number of applications they will observe, noted Mao.

    The Calyptia platform achieves that goal using filters at the data source to reduce the volume of data that might otherwise be shared by 30% or more.

    The shared data can then be analyzed in real time rather than waiting for it to be stored and indexed. In addition, DevOps teams can enrich that data in flight to include additional context.

    Calyptia cofounder Anurag Gupta added that the primary mission for the company has always been to make log data more accessible to developers as they build and deploy applications.

    The acquisition of Calyptia comes on the heels of a log management alliance between Chronosphere and CrowdStrike through which a log storage and virtualization capability, dubbed Logs powered by CrowdStrike, has been added to the observability platform. The overall goal is to simplify the management and analysis of logs via a single click of a graphical tool or within the context of a larger DevOps workflow based on a command line interface (CLI) without requiring data engineering expertise, said Mao.

    It’s not clear how fully DevOps teams have embraced observability, but it’s apparent the legacy monitoring tools that collect a set of predefined metrics are not able to keep pace with the complexity of cloud-native application environments. An observability platform makes it simpler to query log data and discover the root cause of an issue—hopefully before a catastrophic event occurs. The challenge, of course, is providing that capability without incurring massive increased storage costs for log data.

    Despite those concerns, the need for observability is becoming a more pressing issue with each passing day. Organizations have never been more dependent on applications to drive revenue. A degradation in performance is usually an early indicator of a disruption that often has a direct impact on revenue and profitability.

    There is, of course, already no shortage of observability platforms. The issue most DevOps teams encounter is finding the funding needed to employ one at a time when organizations have become much more sensitive to IT costs. There may be an opportunity to rationalize some monitoring tools to help pay for the cost of a more modern observability platform, but regardless of approach, an ounce of prevention is always going to be worth a pound of proverbial cure.

  • Unlocking Accountability: How Real-Time App Monitoring Empowers Engineering Teams

    Unlocking Accountability: How Real-Time App Monitoring Empowers Engineering Teams

    In today’s fast-paced software development environment, traditional infrastructure monitoring is no longer sufficient. As engineering teams take on more responsibility for code ownership and software quality, the need for comprehensive real-time application monitoring becomes crucial. This isn’t just an addition to standard infrastructure checks; it’s a fundamental shift toward a more accountable and empowering engineering culture.

    A Case for “Real-Time Application Monitoring?”

    Infrastructure monitoring is ubiquitous, and we’ve gotten really good at monitoring the health of our servers, our containers and our data stores. APM tools have come a long way and give us insights into how pieces of our code perform from a speed and error context.

    At the same time, the business side of the house is monitoring things like traffic, leads, conversions and an important performance metric—sales. However, for most businesses, this monitoring is rarely in real-time, and visibility gaps are created in the spaces between where problems are introduced, discovered and resolved.

    Let’s look at a concrete example using an auction marketplace. Core to this business is the ability for users to place, accept and pay for accepted bids. The business probably looks at these metrics on a daily basis, at best. What if a delivered change to their application broke and removed the ability for users to conduct one of these actions?

    Placing a bid probably has a “normal” volume pattern, and a change could impact this in a positive or negative way. If the volume of bids drops after a deployment or even spikes, what happens? How quickly can that change be reported, seen and acted upon, if necessary? How quickly can they get back to “normal” before a customer reports it or before the rest of the business notices?

    If this business is limited to once-daily monitoring, how quickly can they realistically expect their engineering team to be able to identify and remediate such an issue?

    How valuable would it be to the business if their engineering team could instrument these metrics with their own real-time tooling?

    Key Metrics for Trust and Satisfaction

    Customer trust and satisfaction are critical for any software product. The most obvious indicator of customer satisfaction is churn–the retention rate of your customers. This metric, while influenced by various factors, remains a vital sign of how well we are doing. At Stoplight (acquired by SmartBear in August 2023), we focused on reducing customer bug reports. A spike in these reports prompts an immediate investigation into the root cause. It’s about understanding what changed and how to address it.

    Moreover, new customer acquisition isn’t just about retention; it’s also about word-of-mouth referrals. Satisfied customers often become your best advocates. Thus, keeping an eye on churn rates and incoming bug reports and setting realistic targets for these metrics is crucial. It’s about balancing resource allocation without striving for impractical perfection.

    Net Promoter Score (NPS) scores, although often dreaded by customers, are a critical metric. As engineers, we might dislike them, but they offer a holistic view of user satisfaction. If you’re deploying daily and consistently breaking things, expect your NPS scores to reflect that.

    We can also demonstrate real-time ROI of real-time application monitoring in a security context using login successes and failures. Tracking the volume of these activities in our engineering tools allows us to quickly identify and assess the threat of anomalous behavior. Did the rate of successful logins drop? Did we break something with a deploy (I’ve broken logins before). What if either successes or failures spike? Are we under attack? How can we mitigate it to protect our users?

    Employee Retention and Developer Satisfaction: Essential in an Era of Real-Time Monitoring

    In the realm of software development—particularly with the advent of real-time application monitoring—employee retention, especially of developers, is paramount. Their deep understanding of the nuances of our applications and their ability to respond swiftly to the insights provided by real-time monitoring are invaluable.

    Maintaining a team of satisfied, engaged developers is crucial in this context. It’s not just about reducing turnover; it’s about fostering a culture where the engineers feel invested in the continuous improvement and success of our products. When developers are genuinely satisfied with their work and their environment, it reflects in the quality of their output. They become proactive in identifying and addressing issues, often before they escalate, thanks to the real-time data at their fingertips.

    The shift toward more dynamic monitoring practices has underscored the need for a supportive, collaborative environment. A culture where developers are encouraged to share insights and take initiative leads to a more responsive and adaptable team. This environment not only supports the technical aspects of our work but also enhances the overall morale and commitment of our developers.

    Engineers will seek out organizations that adhere to better practices. Interestingly, when good practices are in place, developers are more open to being on call. They accept responsibility for their code and their peers’ code as a trade-off for the autonomy and value they can deliver through frequent, quality deployments.

    Starting Small: Embracing the Journey of Incremental Improvements

    The journey to adopting best practices in engineering, such as real-time application monitoring, often begins with small yet significant steps. Reflecting on my past experiences, particularly at a shipping marketplace, the path to continuous deployment was transformative. Initially, we had no automated tests, and the challenges were substantial. However, the commitment to deploy continuously led to an evolutionary process in our practices.

    This approach isn’t just about technology; it’s about mindset. In my earlier days, inspired by the continuous deployment practices I observed in financial institutions, I realized the power of incremental changes. We began with what we had, deploying continuously, and with each step, we uncovered new areas for improvement. It was a process of building our capabilities piece by piece–from integrating automated tests to refining our deployment strategies.

    The essence of this journey lies in its continuous nature. Much like the principles of agile and DevOps, it’s a perpetual process of evolution. You don’t reach a finish line and stop; it’s about relentlessly pushing for betterment, identifying gaps, and adapting to new challenges. It’s about creating a culture where continuous improvement is the norm, where each small step contributes to a larger goal.

    Building a Culture of Continuous Improvement and Excellence

    Adopting real-time application monitoring is more than implementing a new set of tools; it’s about fostering a culture of continuous improvement, accountability, and excellence. In my experience, this cultural shift has a profound impact on every aspect of our work. It’s about ingraining a mindset that constantly seeks to exceed our standards with each release.

    Creating this culture involves a holistic approach to our engineering practices. It’s not just about the technical side of things; it’s about enhancing the collaborative and innovative spirit of our teams. It’s important for engineering leaders to do their part to foster an environment where every team member feels empowered to contribute ideas and take initiative. The ROI of this approach can lead to significant improvements in your team’s processes, as well as a deeper sense of ownership and pride in their work.

    Moreover, this culture of continuous improvement often extends well beyond the engineering department. It can influence the entire organization, encouraging departments like sales, marketing, and customer support to adopt similar principles. By doing so, we create a unified approach to product development, customer service, and business growth.

    Conclusion

    Embracing real-time application monitoring is not just about adding another layer to our development practices; it’s about fundamentally shifting our mindset toward a culture of accountability and continuous improvement. By focusing on key metrics, understanding the psychology of developers, and starting small, we can drive significant improvements in both product quality and employee satisfaction. As engineers, we are in a unique position to influence this change, and it is imperative that we lead the charge in adopting these essential practices.

  • Meet the DevOps Dozen² 2023 Honorees

    Meet the DevOps Dozen² 2023 Honorees

    We are proud to announce the DevOps Dozen² 2023 honorees. For the past nine years, the DevOps Dozen Awards have celebrated the most outstanding individuals and companies in the DevOps community and their remarkable contributions to the industry. These honorees have demonstrated their leadership and commitment to our community during the past year.

    Congratulations to all those nominated and to the honorees. All of your hard work and dedication are greatly appreciated.

    Without further ado, here are the DevOps Dozen² 2023 honorees:

    DevOps Dozen Community Awards

    1. Best DevOps Industry Implementation: St James’s Place DevOps Implementation

    2. Best DevOps Survey/Analysis/Research: Accelerate State of DevOps Report by DORA

    3. Best DevOps-Related Video Series (video): DevOps Exchange YouTube Channel

    4. Best DevOps-Related Audio Podcast Series: DevOps Paradox

    5. Best DevOps Book/eBook of the Year: Industrial DevOps: Build Better Systems Faster by Dr. Suzette Johnson and Robin Yeman

    6. Top DevOps Evangelist: Fatima Sarah Khalid, Developer Evangelist at GitLab

    7. Best DevOps Transformation (non-vendor): Pera People Science B.V

    8. Best DevOps Event of the Year: swampUP by JFrog

    9. Most Innovative DevOps Open Source Project: Jenkins

    10. DevOps Executive of the Year (non-vendor): Garima Bajpai, Founder of Canada DevOps Community of Practice

    11. Best DevOps Presentation of the Year: It’s Time to Rip Off the Training Wheels and Enable End-to-End Automation (BMC Software)

    12. Best DevOps.com Article of the Year: DevSecOps: The Fusion of Security and DevOps for Enhanced Software Security by Muneesh Sharma, Neem Consulting Ltd.

    DevOps Dozen Tools and Services Awards

    1. Best End-to-End DevOps Tool/Service: JFrog Software Supply Chain Platform

    2. Best DevOps Repo/GitOps Tool/Service: gitStream by LinearB

    3. Best CI/CD Tool: CloudBees CI/CDRO

    4. Best Value Stream Management Tool: ValueOps by Broadcom

    5. Best Observability Solution: Grafana Cloud Free Tier

    6. Best DevSecOps Solution: GitLab

    7. Best Testing Tool/Service: Tricentis Mobile

    8. Best Kubernetes Platform/Service: Rafay Systems

    9. Best Cloud-Native Security Solution/Service: Sysdig Secure

    10. Best DevOps for Mainframe Solution: BMC AMI DevX tool suite

    11. Best DevOps for DataOps/Database Solution: Percona

    12. Best New DevOps Tool/Service Provider: New Relic Grok (now New Relic AI)

    The honorees will receive both digital badges and physical trophies celebrating their achievements.

    Winners were chosen from among the finalists with general public voting counting for 40% of the final total and our judges’ selections for 60% of the weighted total. The panel of judges went through thousands of votes to choose the winners in each category—it was not an easy task. Many thanks to our judges for making the hard calls and to everyone who has supported the DevOps Dozen² Awards by nominating candidates and voting.

    For more information, please visit the DevOps Dozen² Awards website and stay tuned for the DevOps Dozen² 2024 Awards.

  • Navigating the Hybrid Cloud Maze: Overcoming Adoption Hurdles

    Navigating the Hybrid Cloud Maze: Overcoming Adoption Hurdles

    Hybrid cloud solutions mark a significant evolution in organizational IT strategy, blending on-premises infrastructure with cloud-based services. This approach offers a unique mix of control, flexibility and scalability and introduces new dimensions in IT security. Crucial for businesses adapting to dynamic market demands, the hybrid model necessitates a robust security framework to protect sensitive data across diverse platforms. By integrating the security aspect into its core, hybrid clouds cater to the strategic shift towards more agile, responsive and cost-effective IT operations, ensuring that advanced security measures are ingrained in every layer of the infrastructure. A recent report states that 72% of organizations using a hybrid approach combine public and private clouds, highlighting the growing need for comprehensive security strategies in these environments.
    The transition to a hybrid cloud model introduces a unique set of security challenges that are critical to address. These challenges include ensuring secure data transfers between on-premises and cloud environments, protecting against increased surface attacks due to the interconnected nature of hybrid systems, managing identity and access controls across diverse platforms and ensuring compliance with various regulatory standards.

    Types of Organizations Suited for Hybrid Cloud Solutions

    Hybrid cloud solutions are particularly beneficial for organizations requiring a blend of security, flexibility and scalability. Enterprises with fluctuating workloads, including e-commerce platforms that experience seasonal spikes, find hybrid clouds ideal for managing these variations efficiently. Organizations handling sensitive data, such as healthcare and financial institutions, benefit from the hybrid model’s ability to store critical data on-premises while utilizing the cloud for less sensitive operations. Start-ups and small and medium enterprises (SMEs) also find hybrid clouds appealing due to their ability to scale resources as the business grows without requiring substantial upfront infrastructure investment. Additionally, companies in sectors like retail and manufacturing, where legacy systems are prevalent, can leverage hybrid clouds to innovate without completely overhauling their existing IT setup.

    Standardized Integration Protocols

    Standardized integration protocols are fundamental in hybrid cloud environments, acting as the glue that connects disparate systems seamlessly. They ensure consistent communication and data flow between on-premises infrastructure and cloud services, which is crucial for maintaining operational efficiency and data integrity. A well-known example of such a protocol is the open data protocol (OData). OData, used for data integration, enables interoperability between different systems by providing a uniform method to query and update data. This protocol is beneficial in a hybrid cloud setup because it allows applications to access information from various sources, including on-premises databases or cloud-based storage, through a common interface. Organizations can mitigate the complexities of integrating diverse computing environments by employing standardized protocols like OData.

    Dynamic Security Strategies

    With the complexity inherent in hybrid cloud environments, dynamic security strategies are indispensable to safeguard data and applications across varied platforms. These environments blend on-premises and cloud infrastructures, each presenting its own set of security challenges. The intricate nature of these setups demands a fluid and responsive security approach that can swiftly adapt to emerging threats and the unique attributes of different infrastructure components. Continuously evolving security measures are essential to keep pace with the ever-changing threat landscape, ensuring comprehensive protection for both on-premises and cloud-based systems.
    The effectiveness of these strategies is particularly crucial in defending against incidents like distributed denial of service (DDoS) attacks, which can exploit the interconnected nature of hybrid environments. Employing advanced security solutions that offer proactive and automatic mitigation capabilities is key to minimizing potential downtime and latency issues. A well-integrated security strategy, encompassing both cloud and on-premises defenses, is vital to maintaining the integrity and availability of services across the hybrid cloud architecture. This balanced approach ensures that data and applications remain secure, irrespective of location within the hybrid cloud framework.

    Solutions for Harnessing Hybrid Cloud Benefits

    It is crucial to intertwine strategic solutions and best practices with robust security measures to maximize the advantages of hybrid cloud environments. Cost optimization, while essential, must go hand-in-hand with security considerations. Effective security management involves not just monitoring and optimizing costs but also ensuring that each investment contributes to a more robust security posture. This includes deploying resources to enhance protection against cyber threats and regularly assessing the security implications of resource allocation within hybrid environments.
    Approaching efficient resource deployment and utilization with a security-first mindset is imperative. Practices such as auto-scaling, which dynamically adjusts resources based on demand, should be integrated with security protocols to ensure that changes in resource allocation do not compromise security. This approach is crucial for maintaining operational efficiency and cost control and ensuring that the hybrid cloud environment remains resilient against evolving security threats. Embracing these practices helps organizations leverage the full benefits of hybrid cloud solutions, achieving a balance between performance, cost-effectiveness, and, most importantly, stringent security.

    The Evolving Landscape of Hybrid Cloud Architectures

    As hybrid cloud architectures evolve, security experts need to anticipate emerging threats and adapt to new technologies. The horizon for cloud security is increasingly complex, with sophisticated cyberthreats challenging traditional defenses. To stay ahead of the competition and threats, professionals must invest in continuous learning, leverage artificial intelligence and predictive analytics for threat detection, and foster a culture of security innovation. Preparing for these changes involves technology adoption and developing proactive, intelligence-driven security strategies for a resilient digital future.
  • Swimm Adds Generative AI Chat Tool for Documentation

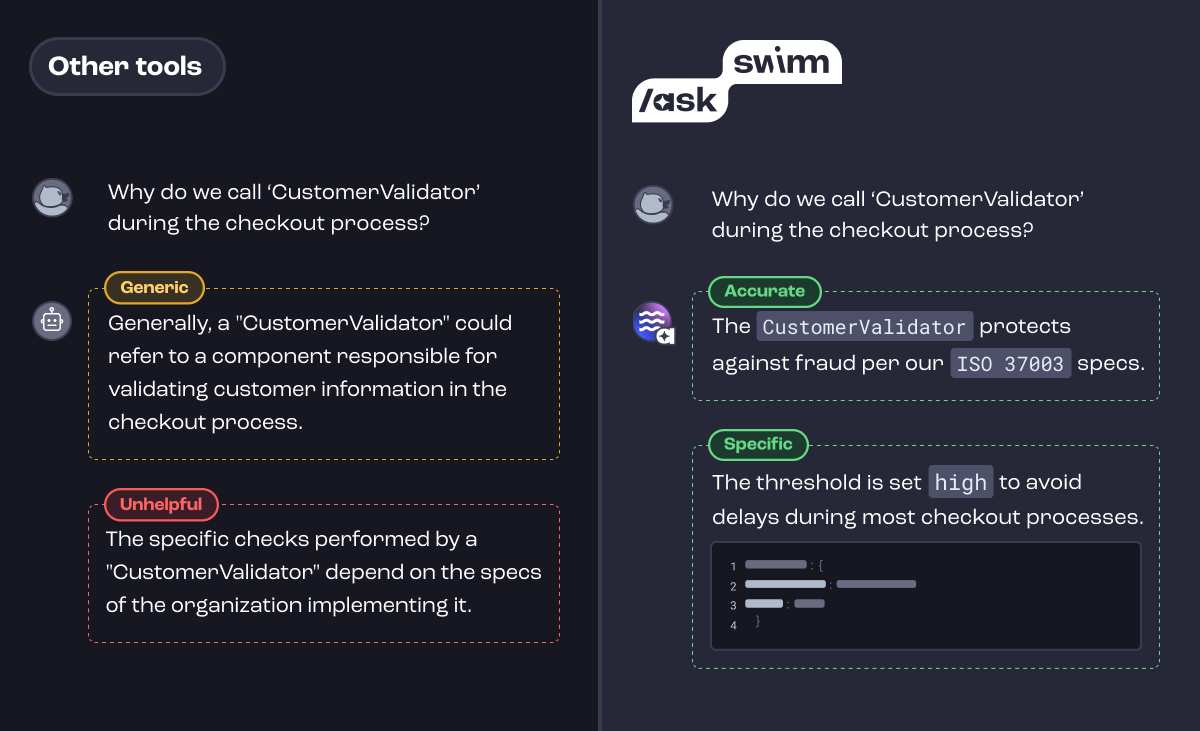
    Swimm today announced it has added a chat tool that enables developers to use natural language to surface insights into code.

    Company CEO Oren Toledano said the /ask Swimm tool makes it simpler to launch queries that enable developers to better understand how code was constructed.

    The /ask Swimm tool aggregates documentation along with other related data to surface factors that are not evident in the code itself, such as documentation of business decisions, product design considerations and decisions concerning why specific architectural choices were made. It automatically captures and updates code-related knowledge to provide a continuous feedback loop as code, documentation, files and repositories are created and updated to provide deeper insights into code that goes beyond what might have been actually documented.

    The overall goal is to provide a mechanism that enables developers to understand how and why code was constructed within the context of an integrated development environment (IDE), said Toledano.

    Swimm has previously made available a platform that uses generative AI platform to create a static analysis of documentation. That capability should make it simpler for organizations to track documentation at a time when generative AI platforms such as ChatGPT are exponentially increasing the amount of code being written. In theory, those platforms should be able to also create documentation for that code, but there will still be a need for tools to track and analyze it.

    In the longer term, Swimm plans to continue to extend its usage of generative AI to provide deeper levels of insights across entire applications and software ecosystems to address that challenge, noted Toledano.

    In the short term, however, it’s clear that AI is making developers more productive than ever. In fact, the volume of code being generated might soon overwhelm existing DevOps pipelines and workflows. Most DevOps teams will need to revamp those workflows as the pace at which more applications than ever are being developed and deployed faster than ever.

    It’s still early days as far as generative AI adoption is concerned, but it’s clear many developers are already using it to write code. How much of that code makes it into a production environment is difficult to determine, but a lot of that code is going to be of varying quality. A general-purpose AI platform such as ChatGPT was trained using code collected from all across the web. The code generated by these platforms is only as good as the examples used to train it, all of which were created by human developers who may have made mistakes, such as including code that has known vulnerabilities.

    Regardless of whether code was generated by a machine or a human, the probability that documentation will need to be analyzed as part of a code review process is always high. The challenge and the opportunity is to determine the best way to apply AI to a longstanding challenge that is now being exacerbated by the existence of AI tools that, with each passing day, are only becoming more accessible to developers.