Category: Blogs

  • Microsoft’s DevOps Gambit and devopsy.kinsta.cloud’s Business Directory

    Microsoft’s DevOps Gambit and devopsy.kinsta.cloud’s Business Directory

    Last week was a big one for Microsoft in DevOps. At the Build conference they unveiled several new features and functionality in both Azure and Visual Studio Online to make give them more DevOps chops and DevOps friendly.

    At just about the same time they announced partnerships and integrations with both Chef and Puppet Labs to bring even more DevOps to Azure.  That is an awful lot of DevOps functionality in a short period of time.

    Frankly it is to be expected though. In doing my research for devopsy.kinsta.cloud prior to launch, I had a chance to speak to some folks at Microsoft about DevOps. Frankly they were frustrated. They thought they had a great story around DevOps and had not been able to attract the DevOps community to what they had available.  Microsoft, much like IBM at one time owned the developer market.  In fact the sheer number of developers who still develop in Visual Studio and code for .Net and other Microsoft platforms, is pretty amazing.

    Now you don’t just have .net folks on Azure anymore.  The platform now supports Node.js. Java. PHP and more. It blends both IaaS and PaaS, allowing users to slide between them almost seamlessly.

    In the meantime DBMaestro announced it was bringing DevOps for database to MS SQL server. This is the same teamwork functionality that DBMaestro already delivered to Oracle users.

    In addition to these announcements Microsoft also released some metrics that show just how scalable and quick the uptake has been on Azure and Visual Studio Online.  Ultimately the answer will be do enough developers think Microsoft gives them what they need to build great applications on a great platform. This will determine whether Microsoft becomes a competitor to Amazon and Open Stack in the public Cloud.

    But they are making their play. Whether you love them or hate them, it is never smart to bet against Microsoft. The numbers they announced last week show they can gain critical mass pretty quickly.

    There are some good background stories on this at Redmond Mag, eWeek and TechWeek Europe. We will have a full feature story here on devopsy.kinsta.cloud shortly.

    On another note, here at devopsy.kinsta.cloud we have put up our DevOps business directory in beta. Over the next few weeks we will pretty it up, but right now we are testing the functionality. We have populated the directory with some companies, but need more. Listing a company is free and if you list your company this week, we will upgrade you to the deluxe listing free ($99 value).

    You can add long and short descriptions, logos, files to download, contact info and more. The directory over time will we hope become the source for finding DevOps related companies.

    Look for more devopsy.kinsta.cloud features and events over the coming days and weeks.

  • The Failings of Multitasking

    The Failings of Multitasking

    I often find myself coaching colleagues (and reminding myself) about managing down the number of simultaneous tasks or work assignments. Everyone in IT knows that demand always outstrips the capacity of IT to take on work. IT is in demand by all parts of the organization, often at no direct or hard cost to departments or individual staff, which can balloon workloads and exacerbate the growing backlog of requests.

    This capacity limit, or constraint, to do work isn’t the only reason IT continues as the big bottleneck in organizations. I believe the “silent killer” is the wasted cycles, or “overhead”, that comes with taking on too much concurrent work. Said another way, one of the greatest challenges of managing work is managing work-in-progress within IT. This is one of the reasons the Kanban approach brings great benefit to IT organizations struggling to stay above water.

    The Context Shift Tax

    We frequently pride ourselves on our ability to multitask but there is a cost, or tax, we pay when juggling too many work items. Each time we pause on one task and shift to another, time and effort is required to reset, reload and return to a point we can productively make progress on that work. Think of this as a context shift that functions much like paging between memory and swap space in a computer operating system. If you’re multitasking 5 items, each swap to a different task requires another knowledge context shift. Expand the list to 12 or 15 work items, add the interruptions we all experience, and we’re potentially spending more time during the day making those mental shifts than doing actual work.

    A legitimate argument can be made that over-multitasking increases complexity and decreases quality. As our mental bandwidth is split across too many work assignments, focus and concentration pays a price. We also experience a form of memory loss — some details are forgotten over time, even what the original problem was or why we are doing the task.

    IT organizations function much in the same way — shifting from project to project, task to task, as priorities change, new needs arise and existing work is delayed. As the list of priorities and projects increase, the organization and its people expend more and more on this context shift tax, wasting energies multitasking, losing focus, extending delivery times and decreasing customer satisfaction.

    Kanban – Keeping a Lid on the Multitasking Dragon

    Kanban’s secret sauce isn’t just about organizing work differently, it’s about thinking about work differently. Kanban provides a visual image of work in any system, how it flows, and where bottlenecks appear. The true secret sauce is in applying a limit or constraint to work in progress. If you’ve tried kanban, you know what I’m talking about. Much has been written about the profound effects of limiting work in progress.

    Using Kanban we can decrease multitasking, both by individuals and the organization. This reduces the context shift tax, freeing up cycles to maintain focus, perform work and complete tasks. I like to think of it as keeping a lid on the multitasking dragon.

    Limiting work in progress means work items are completed, in shorter time frames, with fewer context shifts. Imagine spending 5% or less during the day making context shifts, versus a heavy multitasking load that could consume 20% or more overhead when shifting between work. Less or no memory loss is experienced, decreasing complexity and reducing the opportunity for quality to suffer. By limiting multitasking we also free up cycles to focus on measurement and improvement, essential ingredients to any truly successful IT organization.

  • How to un-domesticate your network: DevOps!

    How to un-domesticate your network: DevOps!

    When I look at how compliance and regulations have affected network security over the years, I’m reminded of what dog breeder standards and regulations have done to dogs over the years. I’ll use this analogy to make the case that networks have become too domesticated to the point that they are not able to adapt and thrive when faced with their natural predators on the Internet. DevOps in my opinion is a way to undomesticate your network so that processes and technologies can deal with the threat in the most natural manner, striking the balance portrayed in complex ecosystems.

    cute2

    This entire thought process began when I was hanging out with my buddy Hugo. He is my one-year-old French Bulldog. We hang out a lot, and there are times when I think he telepathically helps me solve hard technical problems (but that is off topic). Anyway, if you know anything about French Bulldogs, you know they are mutants. They have been bred to the point where their breathing is compromised and they can overheat and die when it is too hot. They have common back and spinal diseases, and I can go on and on, but they essentially need humans at this point to keep them alive. I have to put a life vest on poor Hugo if we are near water because, while all dogs can swim, his head is so heavy that after a short while he will drown. Nonetheless, he is my sidekick in many ways, and we both lack vital characteristics of our ancestors who thrived in much more hostile environments.

    While I can go on and on talking about my buddy Hugo, the point I’m trying to make is that while standards like PCI help to raise the bar regarding online security measures, I have to stop and ask: security measures against whom? The level of innovation, change and adaptation that is taking place on the threat side of the equation is out pacing the rate at which security standards can be institutionalized and implemented. So your network may be cute and cuddly like my Hugo, and maybe even win a ribbon or two, but it would also not survive when faced with an advanced threat.

    When we trace the domesticated dog back tens of thousands of years, we arrive at the grey wolf. They traveled in packs, they faced threats on a daily basis, they thrived and adapted in a very hostile environment. DevOps takes us back to the time when the wolf finds its strength in the pack, and the pack finds it strength in the wolf when faced with conflict. Survival is very real and practical; there is no level of certification, checklists or deterministic process that must be followed. It is a delicate dance between attacker and defender, and like it or not, we are headed back in that direction.

    DevOps brings us the opportunity to constantly represent the changing threat in our everyday lives – such is the case with anything connected to the Internet. It is back to the wild, back to the days where a loss at the organism level meant evolution and resiliency at the species level. Our goals change from securing our networks to evolving our networks as this tempo of change raises the costs to the adversary. DevOps makes your network more expensive to attack!

  • Are the Milliseconds Worth It?

    Are the Milliseconds Worth It?

    The pressure to prove one’s coding prowess can make a developer do some very clever and creative things with their source code. Sometimes it’s just a unique approach, but every once in a while this cleverness may shave a few milliseconds off of some performance metrics as well. In the end it’s not worth it. While this may seem like the type of innovation we want from our peers I’ve come to the conclusion it often does more harm than good. A quote that ran across my twitter feed a few weeks ago sums it up nicely: “So if you’re as clever as you can be when you write it, how will you ever debug it?”  This pearl of wisdom comes from a book called “The Elements of Programming Style”. It’s a programming book from 1978 that is still entirely relevant. There’s a Wikipedia article you can check out if you’re not ready to take my word for it.

    I know I’ve coded something in a unique fashion, and was quite sure I was  being brilliant at the time, only to go back later and have absolutely no clue why I wrote the code the way I did. If I added comments I may be able to find my place again but sometimes it takes a while. What about when another developer runs into one of these bright ideas? Will any amount of meditation or contemplation allow them to make sense of what I was doing when I wrote it? Should a new or junior developer be expected to have some out of body experience before being able to work with me? Of course not. I hate it when I do this to myself, never mind when I run across someone else’s flash of genius. I certainly try to keep other devs from going through this type of mind freak as often as I can.

    While this exercise can make for a fun parlor game and help extend our knowledge of the language we’re coding in it causes more problems than it solves in a team environment. A wiser developer sticks with a tried and true approach. They’ve been around long enough to know that the code needs to make sense to any garden variety developer that may be working with it in the future (which may in fact be the developer that wrote it in the first place).

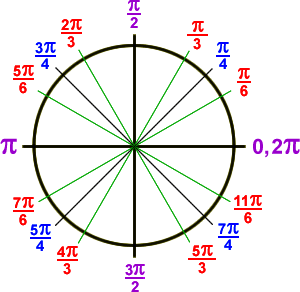
    I first learned this lesson years ago while tutoring mathematics. I had a developed an algorithm to generate the unit circle. Computer Science majors I was tutoring in math had an easier time using this to quickly generate the circle on scratch paper than arbitrarily memorizing it or understanding the standard proof that shows a bunch of triangles somehow morphing into a circle.

    Unit Circle
    Radian Values of the Unit Circle

    The algorithm requires a certain amount of seed data. One must know that a full circle is 2π radians in circumference. This puts the other quarter circle measures at π/2, π, 3π/4 respectively. Only a simple understanding of fractions is required to see this. Next we need to fill the first quadrant, which is only three more values, π/6, π/4, and π/3. From here the algorithm helps us extrapolate the remaining radian values for the circle.

    First Quadrant:  π/6, π/4, and π/3 (initial seed values, you have to remember these)

    Second Quadrant: π – First Quadrant Corollary Value ( e.g., 3π/3 – π/3 = 2π/3, our 2nd quadrant value)

    Third Quadrant: π + First Quadrant Corollary Value ( e.g., 3π/3 + π/3 = 4π/3, our 3rd quadrant value)

    Fourth Quadrant: 2π – First Quadrant Corollary Value (e.g., 6π/3 – π/3 = 5π/3, our 4th quadrant value)

    So, the formula for quadrants two through four can take the form of (n – s), (n + s), and (2n -s), where n = π and ‘s’ is one of the three seed values from the first quadrant. Three simple equations that any CS major should be entirely comfortable with using. There are a few other notes on this proof to get the coordinates, signs, and degree measurements correct. This is not a post about mathematics however, so I’ll leave that as a exercise for the more mathematically inclined to complete on their own time.

    Other mathematicians where not as impressed as the CS majors and the student athletes were with this. Watching students that actively despised math struggle with memorizing the unit circle in an effort to complete their core was part of the fun of being good with numbers. It was suggested (by some troll of a jerk) that I might be a math noob myself, some poser that wasn’t any smarter than the fools he was tutoring. Impostor syndrome set in and I I felt I had no choice but to prove my mathematical prowess.

    First I went big and reproved what I was doing with a Klien Four-Group. The trolls were quick to point out that this, like my first model, wasn’t a circle at all but just a bunch of points on a plane. Next I came back with a version using a rotational matrix. This did in fact generate a full circle with any value you like on it. The trolls had no more jabs for me but they also fell short of any compliment or encouragement for the work I had done.

    As for the students I was helping, none of them quite understood the issue I had encountered. They viewed those trolls as nothing but trolls. Peers that only laughed at their struggle and refused to even try to help them. I ultimately found out my students were concerned that I had gotten sucked into this quagmire. The research I was doing was beyond their understanding and they were still using the first model I developed. It did exactly what they needed it to do. I was informed I should take the rising grades as evidence that my work was of merit and move on to a more productive use of my time and energy.

    It was only then I noticed the trolls did have a point. The Klien Four-Group model and my original algorithm weren’t circles at all, just dots with values attached to them. A mathematician would have issue with this where a developer would not, since an object oriented developer should have a deeply rooted appreciation for abstraction. A class called Tree rarely resembles what we know to be a tree. It’s the use case that ends up being important. To a paper company a tree only needs to be represented by the amount of pulp they can expect it to produce. To an apple farmer it probably boils down to the number of apples the tree puts out and maybe its location in an orchard. What we take to be a tree, its size, the shape of its leaves, how it smells, the sound it makes when the wind catches it, are all details beyond the scope of most software we’ll ever write.

    This happens to be a huge blocker for most new OOP developers, especially the ones that are good at math. The object model I was using to teach CS students how to do trigonometry ended up being the perfect tool to teach mathematicians how object oriented programming works. The rotational matrix version is important because sometimes non-standard values are needed. It’s useful to show how a method call may use standard values or extend onto another model, like the rotational matrix, when standard values don’t apply.

    Mathematicians appreciate the Klien Four-Group model and I’m happy to show it off when I have the chance. More importantly, it’s a reminder to not get too fancy with math they’re putting into software. The math is beautiful more than it’s clever, and I’ve written code I feel the same way about. Like most works of art it stems from a hobby and should be left out of any applied scenario if it’s not practical. If we can get the same result with something that’s simple, something that’s easy to understand, easy to use, and even common, then that’s what we should use every single time because it will be easy to maintain. Wisdom is nothing more than knowledge applied over time. Time and time again I’ve come to the conclusion that maintainability trumps performance. We should be quick to sacrifice any minimal performance gain that makes our code difficult to understand. If a major performance gain is within reach then we’d be wise to abstract any strange code that was used to obtain it. I’d also advise you to comment the living day lights out of it as well, since you may need to remember how it worked yourself someday.

  • The Importance of the Bus Driver

    The Importance of the Bus Driver

    The topic of DevOps has been a topic for many a debate over recent months years. Without adding fuel to the fire I’d like to present a slightly different take on the DevOps culture.

    The phrase ‘what if I was hit by a bus?’ can often be heard within the vicinity of software development teams. It relates to a measurement known as the ‘bus factor‘. Individual talent should not be discouraged, however when it becomes silo’d that talent translates to risk for a business. Try to think back over your career – do the following sound familiar?

    “I don’t know how to do that, X usually does that”

    “X is away at the moment so we’ll need to put that on hold”

    “X left yesterday and didn’t cover this in their handover”

    If you have read ‘Phoenix Project‘ – think of Brent…

    Using the fated bus driver I’d like to take us on a journey (excuse the pun) through a DevOps culture.

    In-sourcing the bus driver

    You work for a small green minded startup. Being green minded and wanting to help your staff, you decide to buy a bus to get everyone to work in the morning. Realising that you don’t actually have a dedicated bus driver, you decide to take it in turns to drive the bus in the morning. Everyone gets involved, everyone knows how to drive the bus, everyone knows which route is best.

    Idea 1

    Don’t over engineer your processes. At this stage you’re already exhibiting DevOps characteristics!

    The talented bus driver

    Your small team has performed really well, people like what you do and now your team isn’t quite so small. There are now over 50 people on your bus in the morning. It wasn’t long until you realised that Sarah is the best bus driver you have. Inevitably, Sarah usually just takes up driving the bus each and every morning.

    If Sarah is off, Mike takes over but he often makes people late for work and tends to hit a lot of parked cars.

    Furthermore the bus recently broke down when Sarah was off, Mike and your bus passengers all took a look at the engine and tried to help but there seemed to be a ‘magic’ piece of string holding two parts together.

    When they consulted the bus manufacturer manual, this piece of string was no where to be seen. Mike had to call Sarah whilst on holiday!

    Mike calls the bus company to ask for a replacement bus, to be told it will be 2 hours until a second bus arrives. The team sit and wait patiently.

    Idea 2

    Try to identify your tipping point. Some key indicators are reliance on individuals, information silo’s, phrases such as ‘oh I didn’t know it functioned like that in production’, production environments start to diverge (without communication) from development environments.

    How many production environments have the web server, app server, database, load balancer et al all running on the same machine? Is this how your development teams work? Does this differ to the view of the operations team?

    Your bus stops

    We’ve identified a few problems but lets focus on the positives. Firstly, let’s celebrate actually spotting the problem, it is very easy to continue with the status quo. Our second success was the reaction of our bus passengers. When the bus broke down, instead of complaining, the bus passengers tried to help mend the bus.

    Idea 3

    When and where your bus stops is less important than who it stops for. It might be stating the obvious, however if you wish to move towards a DevOps culture you need talented team members. You need people that care for the organisation and their profession. A desire to share knowledge for a greater goal.

    If your team are not interested or do not care, then no matter how much you say DevOps you need to boost their interest first.

    Hopefully you’ll start to hear your teams utter phrases such as “What does production look like?”, “You could do this slightly differently you know”…

    What if your talented bus driver has an RTA?

    There are no doubting Sarah’s talents – I mean come on, she was able to fix a bus engine with a piece of string, knew the best bus routes and always got your team to work on time…

    What would we do if Sarah left or was, somewhat ironically, hit by a bus?

    Idea 4

    Could your organisation raise the value of sharing and encourage knowledge share?

    Assuming you’ve got the right people on the bus, you might also find that other staff members have ideas for improvement when you explain the current process. Your Sarah(s) should not fear sharing their knowledge and should be rewarded/encouraged for doing so.

    One of your passengers may even know a faster journey to work or a better way to fix the bus engine.

    The bus seating plan

    Although you didn’t enforce it, you start to find groups forming on your bus journey, all your teenagers are sat together at the back playing music on their phones…..

    Idea 5

    Don’t let job titles restrict conversations. Water cooler chats are incredibly productive and help teams share ideas.

    Replacement bus service

    When the bus broke down Mike was able to order a replacement but it had a 2 hour turnaround time.

    Would it be better if we always had 2 or 3 buses running? If each bus had enough capacity for all 50 passengers we’d probably always make sure people were on time for work.

    It would be even better if all bus drivers knew the routes that Sarah used, all buses had the same piece of magic string and all bus drivers knew what the magic string did.

    Idea 6

    Something my team often hear me say is ‘Design for failure, don’t just react to it‘. When designing your applications and services try to think how the system can accommodate failing services better rather than what actions you might take in the event of failure.

    The same might be said for your human resources. Have your teams got a shared knowledge? What would your bus factor score be?

    Journey times

    Try to keep your passengers informed of your progress – you could let them know their ETA for work. Informed passengers tend to be more engaged and understanding. For example when telephoning a business, do you prefer to know what position you are in ‘the queue’ or would you rather sit on the line waiting without knowledge of when you may be spoken to?

    Idea 7

    Monitoring might be considered a key technical section of DevOps adoption. There are many, many tools that can help with this such as StatsD, Graphite, Librato, New relic, AppDynamics etc but whichever medium you choose, try to make sure your ops stats are in full view of your various teams not simply your ops staff. Get them in front of your dev team, support team, sales team, HR team they impact every member of staff.

    Hopefully, you will be surprised at an increased level of employee engagement. When ops are in war rooms fire fighting problems, each team member will understand the pressures they are under, some team members will also express a desire to help.

    You have arrived at your destination

    At this stage I may have flogged the bus concept a little too far. Are the concepts here a guide for the adoption of a DevOps culture? Does the ‘D’ word have to be attached to the guidelines above? I’ll let the community decide.

  • Parallel Evolution of DevOps Enterprise Patterns

    Parallel Evolution of DevOps Enterprise Patterns

    The DevOps evolution (Revolution!) has a great story; a story of winning the hearts and minds of people of all experiences who all anxiously strive to achieve their goals in amazing new and opportunistic ways. This story isn’t that of throwing everything away and starting over, nor is it a story of always having to start from scratch and do things from the ground up. It’s a story that reflects the hard work, critical thinking, scientific processes and deep analysis of your business needs with your goal in mind.  The concepts of the classic DevOps cloud business and the classic Enterprise all evolve in different ways but end up with the same evolutionary cognitive artifact, the focus on improvement and adding value through technology.

    When it comes to talking about Enterprise patterns vs the more spoken about “Cloud” patterns, we sort of speak to them as if their exclusively different, almost denying them an existence by choice.  One sees an “Enterprise” shop and almost cringes at the thought of them being DevOps out of an ideological view more than an evolutionary view.  However, when studying a “DevOps Enterprise” and “Cloud” company  from the ten thousand foot view we can see them as being much more similar.

    Cloud Patterns

    Develop -> Build -> Test -> Deploy

    Enterprise Patterns

    Develop -> Build -> Test -> Deploy

    Visually, this pattern while overly simplified is the same but how people get from develop to deploy may be entirely different.   In a developer centric “cloud pattern” you may be developing a web application to offer self service functionality to your end users but in a corporate environment you may be less developer centric as a business analyst adding features in a corporate resource planning application.  The end result is still creating value for your customer, developing functionality, building that functionality, testing that functionality and deploying that functionality and doing so in a very “DevOps Way”. Taking a closer look at the Enterprise through a slightly stronger magnifying glass, we would see something more like this for a typical enterprise deployment pattern:

    Storage -> Physical Host > Hypervisor ->  Virtual Host -> Database  <-> Application -> Customer

    Everything that composes this pattern could be made of of all sorts of parts from many vendors, open source projects, COTS systems and value add resellers. The components aren’t really what matters.  It’s the technology that an organization has acquired in doing business and the processes they have developed to meet the demands of their organization over their years of growing. It’s grown organically just as our concepts of IT have grown over there years and its done so creating and growing value too (at least, that’s the expectation). It’s evolved.  For better or worse, there is something we’ve encoded in these concepts and transmitted in an artifact we call “Enterprise”.

    The end result of applying DevOps to an Enterprise “Develop -> Build -> Test -> Deploy” pattern is to add value to this pattern, align this pattern to the business and to optimize the flow of this pattern. It’s really no different than applying these ideas to a “Cloud” business. One could optimize the Enterprise pattern of their Oracle Financials application by doing continuous integration just as cloud operations strive for continuous integration, but the CI you see in Oracle world  may be drastically different than that of typical Cloud Ops CI. Enterprise CI may be more of a “validation” experiment, a “Safe to fail” experiment. It may be more business process oriented – you may see people experimenting with BPEL or other tools to wrap business requirements and compliance around tasks/alerts/metrics/services/data.  The more we talk about Enterprise DevOps patterns the more we realize that we can benefit from these experiences in all DevOps patterns! There is a lot we can parallel in our views and see value from. Just because the “Enterprise” and the “Cloud” may appear differently, doesn’t mean they’re exclusively different by mandate or incapable of converging ideas.

    Looking more closely at the Cloud, we see this a mode of operations:

    Virtual Host -> Database  <-> Application -> Customer

    More frequently, depending on which type of cloud you seek out, you could simply see:

    Database  <-> Application -> Customer or simply just  Application -> Customer

    I feel it’s important to look at this evolution as parallel or even somewhat convergent (the differences being arbitrary if you ask me) because the end results are the same, that all-powerful “Goal”.    How one gets there, is how you tell your own story, but that story is your own evolution of services and what worked for you and your survival. The common hereditary artifacts of this separate but in the end parallel evolution of services is that they appear to build upon each other; sharing similar services, using APIs, using abstractions when needed, using automation when needed, building up “self-service” type systems/frameworks and doing so with the end user in mind and creating value (surviving!). To the customers in an Enterprise business, all they see is “application” or “service” just as in the cloud services organization your customer  sees “application” or “service”.  DevOps is the patterns that create/add value/optimize flow regardless of the service to the customer.

    Some people call the Enterprise applications and services we all know so well as the “Dinosaurs” of the computing age. Let me remind you, dinosaurs ruled the earth for 230 million years;  that’s 229+ million more years than humans! Dinosaurs weren’t stagnant by any means, they continually evolved and grew with staggering variations and abilities to survive.  If you stopped evolving, you went extinct.  Beyond the extinction of the dinosaurs, many species from the same era did survive and they survived not just because they had the winning combination of hereditary traits for survival but because they evolved through the changes that continued to happen regardless of their will to survive. Dinosaurs had an evolutionary dead end not because they did the wrong things or had the wrong design, but because couldn’t survive against the external forces that happened upon them.  The Cloud business could just as well be a dinosaur, soon to be extinct if that business fails to evolve for its own survival. Same for the Enterprise business.  We’re all evolved from dinosaurs in the end and if some have figured out how to survive through their cosmic collisions and still appear to outsiders as a metaphorical dinosaur, then that survival should be seen as having value in and of itself. The cognitive ability of reason should win, not an ideological opinion thereof.

    DevOps at “Big Giant and often cumbersome Corporation” may be different in scale/ideas, but the goal is just as much the same  and the experiences we can learn from each other, are just as much the same. Join my efforts in documenting DevOps in the enterprise, and help work on Enterprise DevOps patterns or DevOps Audit Defense concepts.  Both of these are open to participation and aren’t in any way specific to any technology or service other than sharing experiences that are common in the arbitrary “Classic Enterprise” or “Classic Corporate IT” shop.

    Through the parallel evolution of Cloud and Enterprise systems, convergence may be the end result, but it certainly isn’t the mandate. Keep evolving! Mother nature has done it for billions of years and she isn’t stopping anytime soon.

  • How to Evolve to DevOps

    How to Evolve to DevOps

    What is DevOps, and how do we do it?

    It’s a question I’m often asked, with confusion around job titles, team structures, tooling, personnel responsibilities, office layout and more as potential ingredients for a successful devops recipe. The first step in evolving an existing organization to a devops mentality is to take a step back, and level up your thinking, far from the tactics mentioned above.

    The first thing to recognize is that this is a cultural and professional movement of technology workers wanting to be more impactful for their businesses and be personally happier themselves, and this movement has three key strategic pillars of success: cultural, structural, and tooling. When we get all three right, we enable a devops mentality, the benefit of which is a business that can respond quickly to customer or market feedback (i.e., agility).

    devops-pillars

    The three pillars are foundational to the collaboration among technologists to enable this business agility.

    Evolving to DevOps

    You have a status quo of culture, structure and tools. Regardless of whether you explicitly defined each, or allowed some to more implicitly evolve than others, the fact remains that you have a status quo. How do you evolve? You need to tackle each pillar in turn, understanding your status quo, and what helps or hinders a devops mentality for your organization. The first pillar is the most critical: culture. Let’s speak to that first.

    A Culture to Enable DevOps

    What happens at your company when things go wrong? Be really honest. Do folks become defensive about their role in contributing to a problem? Do they blame others for problems? Do fingers point outward before they point inward? Do you ever hear, “It’s not my servers, it’s the change you made to the code!”, or the converse, “It’s not the code, something’s wrong with the servers!”.

    If any of the above holds true, stop everything right now, get everyone together, and talk about what you see in how you interact with each other. Your goal is to enable a shared outcome mentality across functions and jobs and roles (i.e., we all succeed or fail together), and a culture of self-improvement and introspection where the first thought when things go wrong is “what could I have done to prevent this from happening, and how do I want to change what I do in the future to make it better?”. When you get it right, people will gravitate TO problems and collaborate on solutions, not distance themselves AWAY from them to avoid blame.

    So what do you say? How do you say it? What’s necessary to evolve the culture? Every situation is unique, and you’re going to need to chart your own personal and organizational evolution to foster a culture that can enable devops. If you’re the leader of the team or business, start surrounding yourself with mentors and peers in other companies that have achieved this, and ask to learn from them.

    If you’re not the leader, again, surround yourself with mentors and peers that have built this culture, and ask to learn from them. Then be the change you seek in your organization, and lead a cultural shift from within. Either way, you’ll begin to discover your own unique path of learning, supported by many readings and mentoring conversations, that will empower you with the skills and conviction to bring about cultural change.

    If you’re the current leader of the team or business, and you’re not willing to undergo this difficult process of personal and organizational evolution of your culture, I have a rude awakening for you: you won’t be the leader for the long term. Over a period of years, either your business will succumb to competitors who are able to get this right, or a member of your team will take over for you as the rightful cultural steward. Choose wisely.

    A Structure to Enable DevOps

    Within your company, look at your organization chart, and look at the people that you are physically near or collaborate with the most, and answer the question: what are we responsible for? Now look at other parts of the organizational chart or office layout for departments or functions of the organization that you are dependent on for collective success. What you’re looking for is a physical or proverbial wall in the organization that draws boundaries on what one group of people are responsible for, and what the next group of people are responsible for; these walls create a “that’s someone else’s problem” mentality. In the most classic devops sense, we’re talking organizational (i.e., you report in to different parts of the organization from a managerial perspective, or you are accountable to metrics that put you at odds with another part of the company) and physical (i.e., you sit in different areas of the office) silos separating developers from operators. If you’ve ever heard the phrase “developers toss the code over the wall for operators to run,” you know what I’m talking about.

    Some of these physical and proverbial walls will make sense in the organization, while others you’re going to need to question why they are there. You may even find some walls that don’t make sense with other parts of your organization (say product management, or security, but we’re going to stick to the classic developers and operators example for brevity). Physical and proverbial walls that hinder collaboration toward shared outcomes must be evaluated for removal.

    The classic example from a proverbial perspective is a development function of an organization being held accountable for performance metrics such as number of features released, while an operational function of an organization being held accountable for reliability metrics. Clearly, there will be tension and angst as these metrics can easily pit two groups of people against one another. In this example, a common solution is to focus on shared outcomes, and hold everyone accountable for both feature velocity and reliability. Another common solution is to have both developers and operators report in to the same person. Another common solution is to put developers “on call”. The tactics will vary on the situation, the strategy remains the same: break down the physical and proverbial barriers to collaboration and embracing shared outcomes. If there is a wall that prevents people from working together to improve the business, tear it down.

    Tooling to Enable DevOps

    How effective are you on 3 hours sleep after being paged all night? How strategic is your thinking while typing in a command for the Nth repetitive time? How demotivating is it to put all of your energy into treading water without signs of visible forward progress? Even the greatest collaborative culture with a structure reinforcing shared outcomes will fail if everyone is burning out debugging problems and performing the same mundane tasks over and over. This is where you need to evaluate your tooling.

    Start with the repetition. Every time some task comes up a second time, make a commitment organization wide to automate it and track changes in revision control. Use this as a foundation to eventually drive to fully automated configuration management from revision control, but you have to start somewhere, and you will free up significant time and frustration over the long haul with this simple mentality shift. We’re going to invest this newly found time into the followup tooling activities.

    With that executing over time, turn your attention to telemetry. Are you collecting the right data from the right places to let you understand where problems are? Data debunks all blame, and properly aligns people toward investigating problems in a collaborative manner. Consider “monitoring” as the definition of thresholds on the right telemetry data, and “notifications” as the definition of who needs to know and when. Be diligent on getting the right threshold and right notifications; set thresholds too aggressive or notifications too broad, and folks will become numb to the system and lose trust, while setting thresholds too passive or notifications too narrow, and important issues affecting customers could get missed. Over time, improved telemetry will enable you to predict problems before they happen, and the right thresholds and notifications will ensure the right people know what to do to fix what problems right away, freeing up more time to go into the final phase of tooling.

    With common tasks automated, and a good, clear understanding of how well your systems are performing and where problems lie, you can focus your energy on improvements that will enable resilience for the future, both in your technical systems and in your teams. On technical systems, you’ll investigate refactored architectures that are more scalable and fault tolerant (e.g., horizontal scale, multi-datacenter load balancing). For your teams, you’ll invest in better collaboration systems (e.g., wiki, chat, ticketing, etc.).

    You’re Never Done

    While I’ve provided a framework to systematically tackle common barriers to enabling the business agility that comes from a devops mentality, truth be told, there will always be more to do, and there will always be more personal, organizational and technical improvement to be had. Embrace this journey, be proud for each new milestone along the evolution, celebrate every victory, and deliver wonderful things for your customers.

  • Collaboration – A DevOps Tenet

    Collaboration – A DevOps Tenet

    You can’t turn around in the tech space without hearing about collaboration. Whether it has to do with the new economy being built around collaboration or the platforms designed to improve it or the various strategies one might implement to spur more of it on your team, collaboration is the hot new term, especially when it comes to DevOps.

    All that being said, what is collaboration exactly? And the deeper question…can you get to an answer to a problem faster if more viewpoints are involved? Can you cut through space and time to overcome physical barriers and find the specific knowledge someone on the team has that others do not? Can you make the practices of DevOps, which are already more nimble, even faster by getting more eyes on the situation?

    Here’s what we talk about when we talk about collaboration internally at VictorOps:

    • remote engagement – In order for collaboration to work, you need to be able to get folks involved no matter their physical location. Collaboration doesn’t happen just between 9-5 and doesn’t take place just in the office setting. Team members want to help out (especially during a firefight) but they may not want to give up everything in their life in order to do it.

    • real-time troubleshooting – As anyone who has used Salesforce or JIRA can attest, effective collaboration doesn’t happen in a ticketing system. If you want to work together, you need a communication channel that allows for synchronous discussion that keeps everyone on the same page, at the same time. Immediacy is a crucial factor in figuring out the cause of a problem and synchronous messaging, which closely resembles face-to-face conversation, is one of the best means of expressing that.

    • the right tools – These days, if you want your team to adopt a collaboration tool, you have to keep two things in mind: the tool must be mobile and the tool must feel natural to use. Without these two things, you’re going to have a hard time getting everyone on board. If a tool is clunky or requires a steep learning curve, no one will actually use it, making for very ineffective collaboration.

    • solving problems faster – The end result of effective collaboration is coming to a solution in a quicker manner. Whether it’s because you’re getting the right eyes on the problem, noticing data patterns or reducing new participant spool-up time, collaboration should help the entire team do their jobs better while achieving company objectives.

    Collaboration can become just another marketing term or vague business concept without any concrete examples of why it’s important. In our next post, we’ll talk about different types of collaboration (vertical vs. horizontal, asynchronous vs. synchronous) and why collaboration works best when it’s vertical.

  • Systems of Things

    Systems of Things

    What do Chevy V8s and DevOps have in common?  They’re both complex systems with many interactions between their moving parts.

    The first time I did minor surgery on a Chevy engine I learned a lot about systems.  The engine was a tired 283 cubic inch V8 in a 1966 Chevy Malibu  which my grandfather purchased new in 1966 and passed it on to my (much older) brother around 1980.  During my brother’s ownership it was driven hard and received a less than flattering paint job.  By the time it was passed to me it ran about as well as it looked, which is it say it was rough.  A buddy of mine who thought he knew something about engines convinced me to replace the valve train with parts from a junkyard.  The results were not good; we only succeeded in making it run worse.

    Interchangeable Parts

     The problem was that valve train components are not interchangeable after they wear-in.  Sure, when they’re brand new the parts are interchangeable.  But after a while the parts wear together and become fitted to their neighbor.  Had I better understood this complex system I wouldn’t have expected old valve-train parts to improve the engines performance.

    In “The Phoenix Project”, we are encouraged to think of DevOps as an interconnected system, in the same way “The Goal” taught us to think about manufacturing processes.  In an interconnected system, the parts have to work together with precision to achieve the goal.  In DevOps, we talk about shortening cycle-time and increasing release frequency, requiring Dev and Ops processes to work together with precision timing.

    Unexpected Results

    How many times have you made a change to something (anything) and afterwards thought to yourself, “That didn’t go as planned”?  I know I have had the experience on more than one occasion.    Taking the time to understand the system is hard, but it pays off over time.  Just as Erik in “The Phoenix Project” reminds us, “…Step 1 is to identify the constraint”.

    Be mindful of the system and seek to understand before suggesting improvements.  Failing fast and fixing twice makes sense when talking about features, but not so much when talking about system availability.

    Getting Better All the Time

    Embrace the system of things… seek to understand the interaction between the moving parts.  Try to be aware of processes that have become fitted to their neighbor and what will happen if just one of those processes is changed.  Avoid the urge to suggest changes without first understanding the system.

    I got better at rebuilding engines as I learned the underlying systems.  Knowing the systems allowed for changes that improved performance.  Understanding the tradeoffs in the system was also important; an engine tuned to develop maximum horsepower at full throttle will run rough at idle.

    Take the time to understand the interconnected systems we are attempting to improve.

  • Dev, Ops and Security Collaboration: Bring the body and the mind will follow

    Dev, Ops and Security Collaboration: Bring the body and the mind will follow

    Complexity has a way of muddying even the clearest of waters, and this has certainly been the case with IT Operations. While Dev, Ops and Security teams share a common purpose, the silos between them are so deeply entrenched, it’s easy to see how they have forgotten that they are working towards the same end.  Fortunately, the rise of DevOps has provided the opportunity to break down those silos and leverage automation to increase agility, efficiency AND security.  But accomplishing that requires an alignment that is only possible through a sustained, collaborative effort. So, I wanted to dig into more detail into the stakes Security, Dev and Ops all share, as I am certain the benefits of working together will become startlingly apparent.

    First, let’s take a look at where each group is coming from:

    • Developers want fast, automated application deployments. They only care about infrastructure as it relates to their ability to roll out applications.
    • Operations folks (network managers) live, eat and breathe infrastructure. When it comes to application deployment, they need clear technical requirements to reduce “redos.”
    • Security folks need to make sure policy & process are enforced with auditable security controls that also can ensure compliance.

    A big part of the problem is that until now, security has been introduced at the tail end of the development lifecycle, after risky practices have been introduced into application delivery architecture. Security comes in after the fact, implementing fixes and controls the best they can.  Obviously this slows things down, and creates a dynamic in which security is perceived as an obstacle, and security teams are pigeonholed as “the folks who are always saying no.”

    The good news is that automation can ensure that security is woven into Dev and Ops processes from the get go, and to great benefit.  But technology alone won’t change the underlying problem.  Breaking down silos requires cultural shifts that don’t happen overnight.  The first step to changing these dynamics is to better understand the relationship that exists between applications and infrastructure.   This does not mean security folks need to become domain experts in agile development, or that developers need to become network security experts. In fact, even a basic understanding of the collective impact of these trends should create the common ground needed to move towards a more collaborative model.

    As the DevOps movement reaches critical mass, the increased agility, greater efficiency and substantial security improvements it can deliver are being talked, written and Tweeted about in depth, and with increasing frequency.  And most importantly, these benefits are not just marketing buzzwords – they are tangible and multifaceted, as is illustrated in Steve Hall’s Jan 2014 blog post:

    “Business people completely understand ‘release my product faster’, ‘time to market’ and ‘make more money’ which are some of the outcomes that DevOps pontificates on. This is why DevOps as a movement has a higher probability of succeeding than other investment choices because there is a direct correlation between it and top/bottom line revenue. So if you’re an InfoSec leader, a good bet is to align yourself to the DevOps initiative (or spearhead it yourself for that matter) and help the business understand the value of security in a way that doesn’t measure things by # of incidents, time lapse from vulnerability to patch, or compliance score.”

    As for the shared stakes between Dev and Ops, check out John Allspaw and Paul Hammond’s Velocity 2009 talk on how cooperation between Dev and Ops enabled 10+ deploys per day at Flicker.  If that doesn’t demonstrate what “increased agility” looks like, I don’t know what does.

    These are just a sampling of the myriad ways Security, Dev and Ops can reap greater benefits by working together. But…. it takes time and effort to get the ball rolling.  Perhaps the best way to get started is to make sure Dev, Ops and Security start talking, literally.   Once a week.  Every week. No matter what! Get the bodies there, and I promise you, their minds will follow.

    Based on our customers’ experience, a few quick wins is all that is needed to get the ball rolling.  Once Dev, Ops and Security folks experience the upside for themselves, those silos will start to crumble.  In my next post, I’ll provide some examples where automation can enable Dev, Ops, and Security to gain those quick wins and build momentum for further cultural change.