Category: IT as Code

  • Checkly Adds Monitoring-as-Code to Testing Platform

    Checkly Adds Monitoring-as-Code to Testing Platform

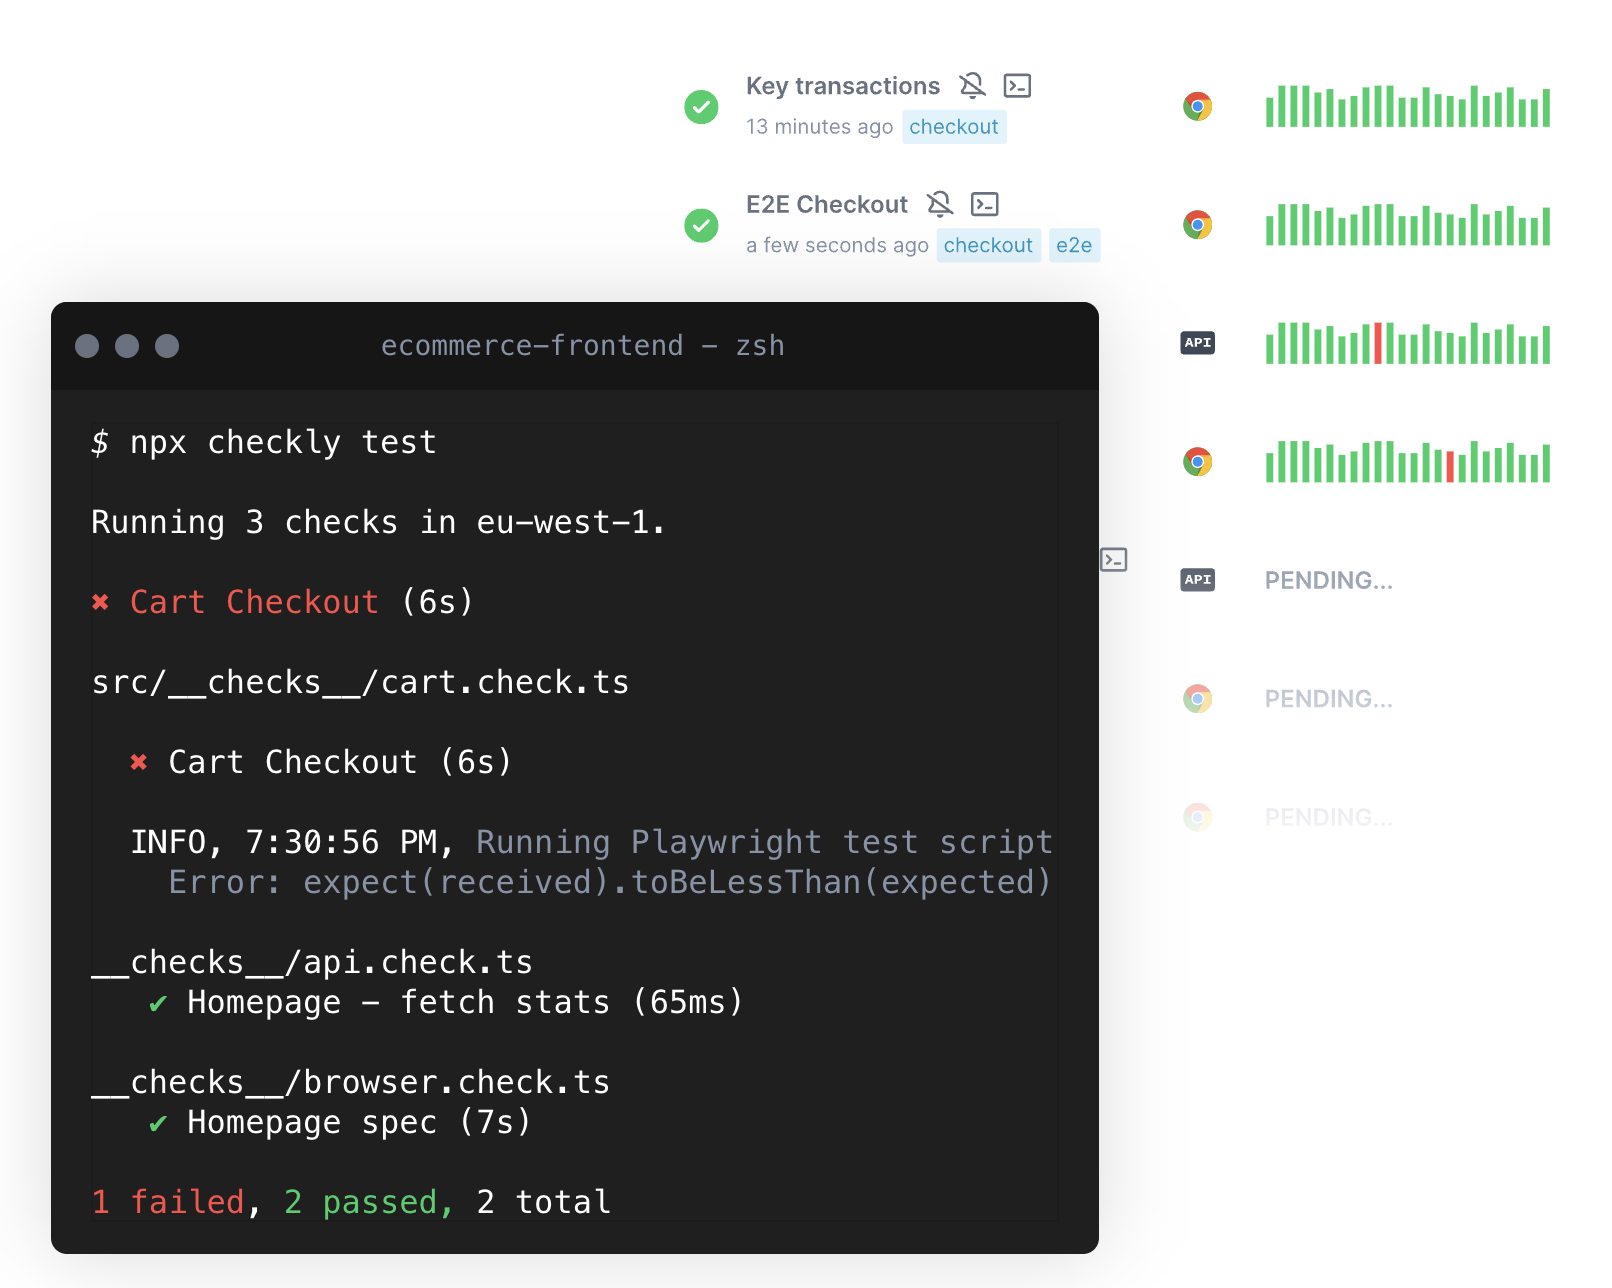
    Checkly this week added a monitoring-as-code (MaC) workflow capability to its software-as-a-service (SaaS) platform that is used to create synthetic tests for applications.

    The Checkly platform spins up browsers to test and can now monitor how applications are performing at both the user interface and application programming interface (API) level. That capability, currently available in beta, is enabled via a command line interface (CLI) for accessing an instance of TypeScript to invoke MaC workflows.

    Checkly CEO Hannes Lenke said that integrated approach enables application development teams to observe applications in as little as 60 seconds without instrumenting them with agent software.

    As part of that effort, Checkly also made generally available Playwright Test, a testing platform for web applications that spins up modern browsers on demand in addition to updating its public dashboards and adding an analytics API.

    Finally, the Checkly SaaS platform has passed a SOC 2 Type II security audit.
    Lenke said the overall goal is to make it simpler for developers to discover and remediate issues as they assume more responsibility for the ongoing management of applications.

    It’s not clear whether developers are taking over responsibility for testing and monitoring applications, but as more responsibility for applications shifts left, organizations are looking to give developers the tools they will require to succeed. That doesn’t mean IT operations teams won’t need to continue to monitor IT environments, but developers do need integrated tools that give them enough meaningful context to address them as they write code. Synthetic testing tools also enable developers to address many routine issues long before they might be discovered by a dedicated testing team that should be focused on ensuring the overall quality of the user experience.

    Regardless of the approach to testing and monitoring, Lenke noted that the silos that make up the software development life cycle are becoming more tightly integrated in modern application development environments. The primary objective is to make it possible for organizations to accelerate application development without compromising quality, he added.

    Of course, the more testing that occurs early in the application development process, the fewer issues a DevOps team should encounter after an application has been deployed in a production environment. The issue is that, historically, much of that testing occurs late in the application development process. Each time a project falls behind schedule, there is naturally a greater temptation to reduce the amount of time spent on testing to ensure the on-time delivery of an application. Providing developers with tools for testing and monitoring applications as they are being built should ensure that the proper level of testing is occurring before an application is deployed.

    There will, however, never be a perfect application. Over time, DevOps teams will discover that every application is impacted by drift to varying degrees as updates are made and the underlying infrastructure is upgraded. The most critical issue is reducing the number of potential issues overworked DevOps teams may need to address later on by ensuring the code being deployed is of the highest quality possible.

  • Nobl9 Adds Service Level Analyzer to SLO Management Platform

    Nobl9 Adds Service Level Analyzer to SLO Management Platform

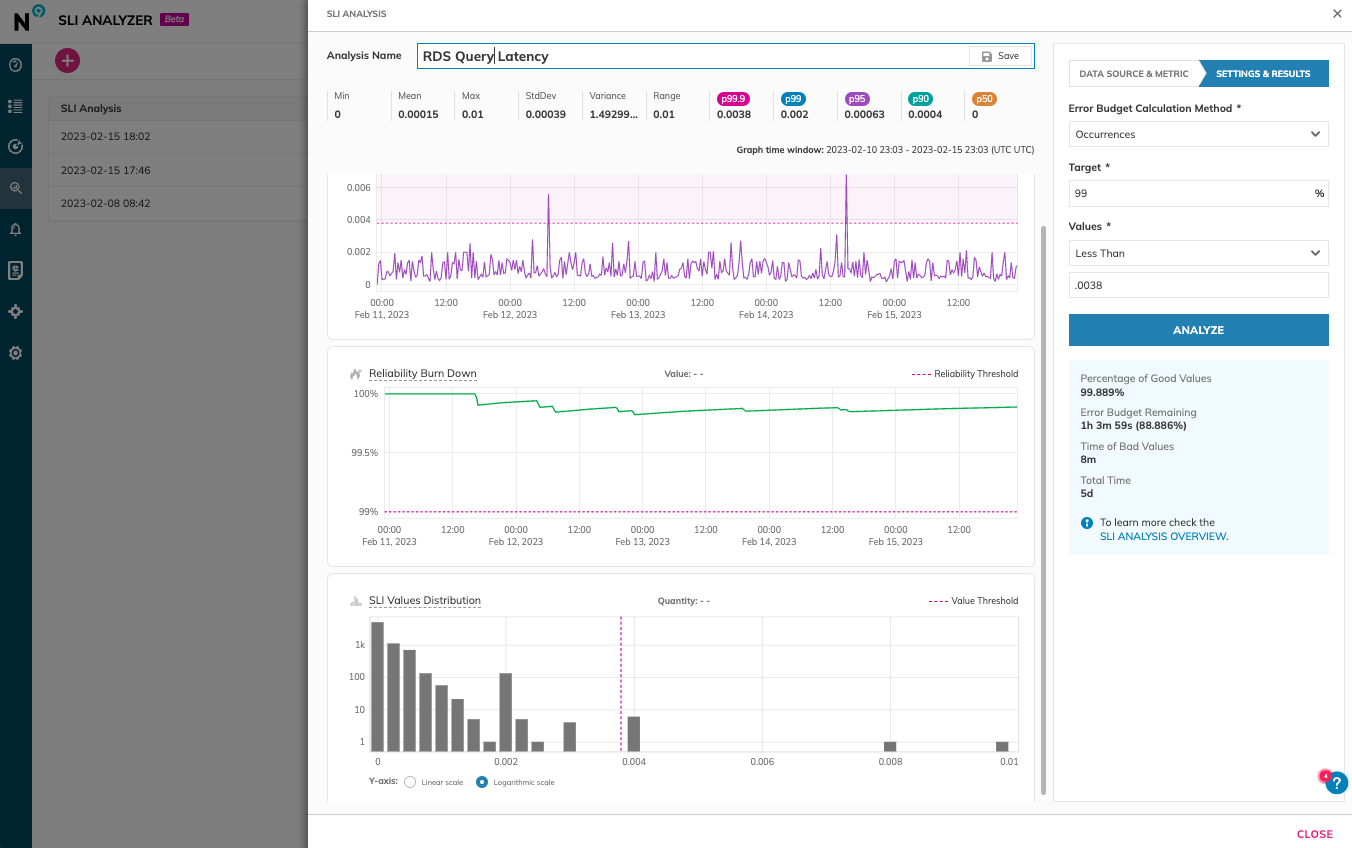
    Nobl9 today added a free tool for analyzing service level objectives (SLOs) to its platform to enable DevOps team to more accurately set reliability goals.

    Brian Singer, chief product officer for Nobl9, said Service Level Analyzer collects metrics and observability data from more than 24 DevOps tools and platforms that can then be used to create an SLO via a single click.

    Included as part of the free tier of the Nobl9 service, Service Level Analyzer also enables DevOps teams to more easily update SLOs as error budgets and error budget burn rates change over time based on actual incidents that have occurred, added Singer.

    DevOps teams can also perform “what-if” analysis to test out the impact of different targets and thresholds on error budgets, he added. That capability ultimately reduces costs because DevOps teams become less likely to overprovision resources to ensure application performance and resiliency, noted Singer. In effect, Service Level Analyzer is providing DevOps teams with an observability tool that spans the entire software development life cycle, said Singer.

    Nobl9 is trying to spur greater adoption of SLOs by making available an open source SLO specification that defines a common interface for constructing SLOs across a DevOps workflow. SLOs, of course, are not a new idea. They have been employed as a metric to track the performance of IT services for decades. However, as more microservices-based applications are built and deployed, it’s becoming more challenging to maintain SLOs across applications because they have many more dependencies than legacy monolithic applications.

    Ultimately, each DevOps team needs to provide some sort of objective benchmark that assesses their overall effectiveness at delivering application services. SLO-as-code is intended to make it simpler to gather the metrics that confirm whether service levels are being achieved. As organizations become more dependent on software to drive digital processes, those SLOs are then tracked across everything from financial services to supply chains.

    In general, DevOps teams are more comfortable with the SLO concept, said Singer. The biggest challenge is making them simpler to implement, he added. The Service Level Analyzer lowers the bar for implementing an SLO by making historical data stored in DevOps tools and platforms more accessible, noted Singer. Rather than having to manually collect that data and then normalize it in an external repository, Nobl9’s Service Level Analyzer automates that process on behalf of a DevOps team using actual data versus relying on less precise statistical analysis, said Singer.

    As IT environments become more distributed, the number of dependencies that exist across application environments only continues to expand. IT teams can spend weeks trying to discover the root cause of issues that are negatively impacting application performance, only to discover that, for example, calls to an application performance interface (API) are being rerouted in a way that significantly increases latency. Tools that enable DevOps teams to more easily understand the relationships between all the services that make up an application environment are more crucial than ever.

  • Logz.io Integrates ChatGPT With Observability Platform

    Logz.io Integrates ChatGPT With Observability Platform

    Logz.io has integrated the ChatGPT generative artificial intelligence (AI) platform with its Open 360 observability platform to extend its automated recommendation capabilities to reduce mean-time-to-remediation.

    ChatGPT, developed by OpenAI, is based on a large language model that Logz.io uses to enrich crowdsourced data. That approach enables ChatGPT to surface links to related information and best practices for resolving IT issues.

    Logz.io CTO Asaf Yigal said the company has integrated ChatGPT with its existing AI engine, dubbed Cognitive Insights, that applies machine learning algorithms to identify anomalies indicative of potentially critical IT issues. The company expects to be able to add other generative AI capabilities as additional advances are made, he added.

    The Logz.io Open 360 platform is based on open source OpenSearch, Prometheus and Jaeger software that the company has infused with machine learning algorithms. The integration with ChatGPT is enabled via an application programming interface (API) that OpenAI has provided.

    The overall goal is to employ AI to surface the most relevant issues a DevOps team needs to focus on without having to search huge volume of logs, tracing and metrics data, said Yigal. Generative AI platforms solve a fundamental cognitive load problem created today as DevOps teams collect more data, noted Yial. The more data a DevOps team collects, the harder it becomes to determine what’s going on in an IT environment, said Yigal. He added that generative AI platforms make it possible to analyze massive amounts of data at a scale that isn’t otherwise achievable.

    AI tools should make it possible to manage IT at a level of scale that eliminates many of the low-level data engineering and analytics tasks that previously required manual effort from a DevOps engineering team. It’s not clear how many other DevOps tools and platforms will be invoking generative AI capabilities in the months ahead, but DevOps teams should assume that large language models will soon be augmenting DevOps teams in ways that previously would have been thought unlikely.

    For example, discovering vulnerabilities in software running in production environments is about to become trivial as artificial intelligence (AI) platforms such as ChatGPT evolve. A generative AI platform can identify code vulnerabilities in much the same way as a traditional scanning tool. An AI platform, however, could theoretically monitor code repositories and scan them for vulnerabilities as updates and commits are being made in real-time. DevOps teams should be able to use generative AI platforms to discover and remediate these issues before code is deployed in a production environment.

    It’s just as probable bad actors will use the same platform to achieve the same goal, so from that perspective, many DevOps teams will now find themselves in an AI arms race to improve DevSecOps workflows.

    There are still lots of issues to be worked out in terms of the overall accuracy of generative AI platforms, but they will only become more intelligent as processors continue to advance. The issue now will be determining precisely where the man-machine interface for DevOps teams is today and in the future.

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    devopsy.kinsta.cloud is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted as part of an effort to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers. Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role, it creates an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    Dice.com

    Pyramid Systems
    Remote
    AWS Cloud DevOps Platform Engineer
    $160,000 to $200,000

    Monster.com

    Apidel Technologies
    Los Angeles, California
    Software engineer
    $140,000 to $160,000

    SimplyHired

    Cox Communications
    Atlanta, Georgia
    Senior DevSecOps Cybersecurity Architect
    $120,000 to $150,000

    LinkedIn

    EdgeLink
    Beaverton, Oregon
    DevOps Engineer
    $110,000 to $120,000

    Indeed.com

    CrowdStrike
    Remote
    DevOps engineer
    $105,000 to $195,000

  • Technical Debt is a Major Threat to Innovation

    Technical Debt is a Major Threat to Innovation

    A survey published today suggested that technical debt is starting to take a heavier toll as IT environments continue to become more complex to manage.

    The survey of 400 IT leaders at organizations with 1,500 employees was conducted by Foundry, the market research arm of International Data Group (IDG) on behalf of Insight Enterprises, a provider of IT services. The survey found that 86% of respondents reported their organization was impacted by technical debt over the past 12 months, with the top areas affected being the ability to innovate (43%), meet service level agreements (41%) and avoid downtime (37%).

    Technical debt is created when organizations cut corners and leave known bugs in the race to meet application delivery deadlines. Application code is often not as thoroughly tested as it should be. In some cases, it turns out that what was intended to be a minimum viable product doesn’t scale all that well. Quick fixes needed to improve performance are also frequently undocumented. Inefficient code also winds up consuming more IT infrastructure than required, which adversely impacts everything from cloud costs to the amount of carbon generated.

    Juan Orlandini, chief architect for the Cloud + Data Center Transformation (CDCT) division of Insight Enterprises, said every organization struggles with technical debt; it will never be eliminated, but it does need to be contained, he added.

    The challenge is instead of trying to keep the proverbial IT lights on during the COVID-19 era, IT teams are now being asked to innovate to advance digital business transformation initiatives, said Orlandini. A full 87% of survey respondents cited modernizing critical applications as a key success driver.

    As a result, many organizations are embracing platform engineering to bring more structure to their DevOps processes, he noted. The challenge, however, is striking a balance between a more centralized approach to DevOps and maintaining the ability of developers to innovate, said Orlandini.

    The issue, of course, is that in addition to massive technical debt, the latest generation of applications are more distributed than ever. The survey found 91% of respondents now rely on multiple public cloud providers for different workloads, with 54% of data residing on a public cloud. However, the survey also found on-premises IT environments are still relevant, with 20% planning to repatriate select public cloud workloads to an on-premises model over the next 12 months.

    Nearly three-quarters (72%) of respondents also noted data volumes are growing faster than their ability to manage them, with 64% ranking implementation of a data governance program to improve data management as their top data-related objective this year. Just over a third (35%) of the data estate is now, on average, driven by edge workloads, with 29% of respondents reporting that at least 50% of data volumes now reside on the edge. Nearly two-thirds (64%) expected that to increase in the next 12 months.

    A total of 85% of respondents also indicated their organization is using artificial intelligence (AI) to some degree to drive business insights and/or efficiencies, although only 36% reported having optimized their use of AI and machine learning (ML) across the enterprise.

    Finally, cybersecurity also remains problematic, with 51% reporting they were impacted by a cybersecurity breach over the past 12 months. Just 20% resolved their issue in one day, while 31% needed less than a week. Nearly half (49%) required one week or more to recover.

    It’s clear that IT isn’t becoming any easier to manage. IT teams need to find ways to build and deploy new applications while reducing technical debt so it doesn’t strangle future innovation.

  • Fiberplane Adds Wasm Plug-in Framework for DevOps Notebook

    Fiberplane Adds Wasm Plug-in Framework for DevOps Notebook

    Fiberplane today announced it is extending the reach of a real-time collaboration notebook designed for DevOps teams by making available tools for building plug-ins based on the WebAssembly (Wasm) framework.

    Micha Hernandez van Leuffen, Fiberplane CEO, said these plug-ins, dubbed providers, will make it much simpler for anyone to connect the Fiberplane notebook to other DevOps tools and platforms.

    The Fiberplane notebook uses the same operational transformation algorithm used in Google Docs to enable teams to easily collaborate around a document or spreadsheet. The core platform itself is built in Rust and WebAssembly. That approach enables a DevOps team to, for example, write and run PromQL queries and display Prometheus charts alongside other data presented via an integrated graph. Wasm makes it possible to run those providers both in the browser and on a backend platform.

    Fiberplane also announced it is open sourcing its Provider Development Kit (PDK), written in Rust, to enable organizations or third-party developers to create additional plug-ins. A Fiberplane Daemon then executes the plug-ins. The overall goal is to provide an open format based on Wasm for consuming DevOps data, noted Hernandez van Leuffen.

    The full open source Fiberplane WebAssembly-based Plugin System includes a Fp-bindgen to provide the bindings generator for building plug-ins, the Provider Development Kit (PDK), a toolchain for building plug-ins, a set of pre-configured plug-ins for Prometheus, ElasticSearch, Sentry, Grafana Loki, Cloudwatch and a generic HTTP provider, the Fiberplane command line interface and the Fiberplane Daemon.

    Fiberplane is essentially taking the concept of notebooks used for collaboration by data science teams and applying it to DevOps workflows. The goal is to improve DevOps teams’ productivity by reducing the amount of time it takes to sort through multiple types and classes of DevOps data to resolve an issue.

    As IT environments become more distributed in the age of the cloud and microservices, troubleshooting issues now invariably spans the responsibilities of multiple members of an IT team. Fiberplane, in effect, makes it possible to spin up a virtual war room that enables the members of an IT organization to collaborate until the issue of the moment is resolved.

    The speed at which any IT issue is resolved has become a crucial metric. Given the complexity of IT environments, it’s inevitable that incidents will arise. Ideally, IT teams would discover those issues before they disrupt the business. However, in reality, the metrics organizations use to evaluate the effectiveness of a DevOps team are often how quickly IT issues are resolved once they are discovered. The longer it takes for a distributed DevOps team to marshal its resources, the more likely it becomes that team will be perceived as being inefficient—regardless of what level of application availability is actually achieved.

    Most DevOps teams have, of course, implemented a wide range of incident management best practices that create a level of muscle memory for responding to a wide range of issues. The trouble is there will always be unforeseen issues that arise. DevOps teams, as a result, need to find ways to quickly focus on an unpredictable issue that they didn’t anticipate.

  • More Java Apps Are Migrating to the Cloud

    More Java Apps Are Migrating to the Cloud

    A survey of 879 enterprise developers and architects from Vaadin, a provider of framework for building Java applications, found that, as part of modernization efforts, the pace at which Java applications are moving to the cloud is now accelerating.

    The survey found more than one-third (36%) of Java applications are already deployed in the public cloud. More than half of respondents (56%) are also already deploying some of their Java applications into Kubernetes or serverless environments. Nearly two-thirds (63%) said they planned to move more Java applications to the cloud over the next 24 months, the survey also found.

    Kim Weins, vice president of product and marketing at Vaadin, said the survey makes it clear that enterprise IT organizations are still highly committed to Java. Still, there is a clear shift underway in terms of where those applications are being deployed. More than a third of respondents (35%) said they have Java applications deployed on Amazon Web Services (AWS), while 22% have deployed them on the Microsoft Azure Cloud. Another 11% are running them on the Google cloud platform.

    This shift, however, will take time. Almost half (47%) of Java applications still need modernization. As a result, 63% of respondents planned to increase their investments in modernizing existing Java applications.

    Maintainability is the top-ranked motivation for modernizing Java applications (32%), followed by security (20%) and ongoing maintenance costs (10%), the survey found.

    The top three challenges in developing Java applications are building an intuitive and simple user interface (81%), upgrading the tech stack (81%) and ensuring app security (78%).

    There is also a shift underway in terms of the frameworks used to build and modernize applications using a more cloud-native approach. A full 70% of respondents use Spring today, but 50% also noted they are planning to increase their use of Spring Boot. Other Java frameworks used include Vaadin Flow, Quarkus, Hilla and React. While derivatives of Spring are the dominant framework, it appeared more organizations are at least evaluating other options, noted Weins.

    Most organizations are also integrating Java applications with modern tools for logging (72%), observability (61%) and single sign-on (53%), the survey found.

    The shift to Java 17 is also well underway, with nearly three-quarters of respondents (73%) using or planning to use it over the next year. More than a quarter (26%) are already on Java 17 or a later release. Another 21% are currently upgrading, while 26% plan to update in the next 12 months.

    Overall, the survey found Java is being widely used for both internal (64%) and customer-facing (62%) applications. Java is most often used to build full-stack Java apps (70%) and backends (69%), the survey found

    Finally, the survey found more than a third of respondents (38%) expected that finding and retaining developers would be a significant challenge in 2023.

    There are, of course, no shortage of options when it comes to deploying Java applications. Most organizations will deploy Java applications everywhere from the network edge to the cloud. The one thing all these applications will have in common is they will be written in a venerable programming language that itself has been modernized.

  • Quali Update Strengthens Infrastructure Security

    Quali Update Strengthens Infrastructure Security

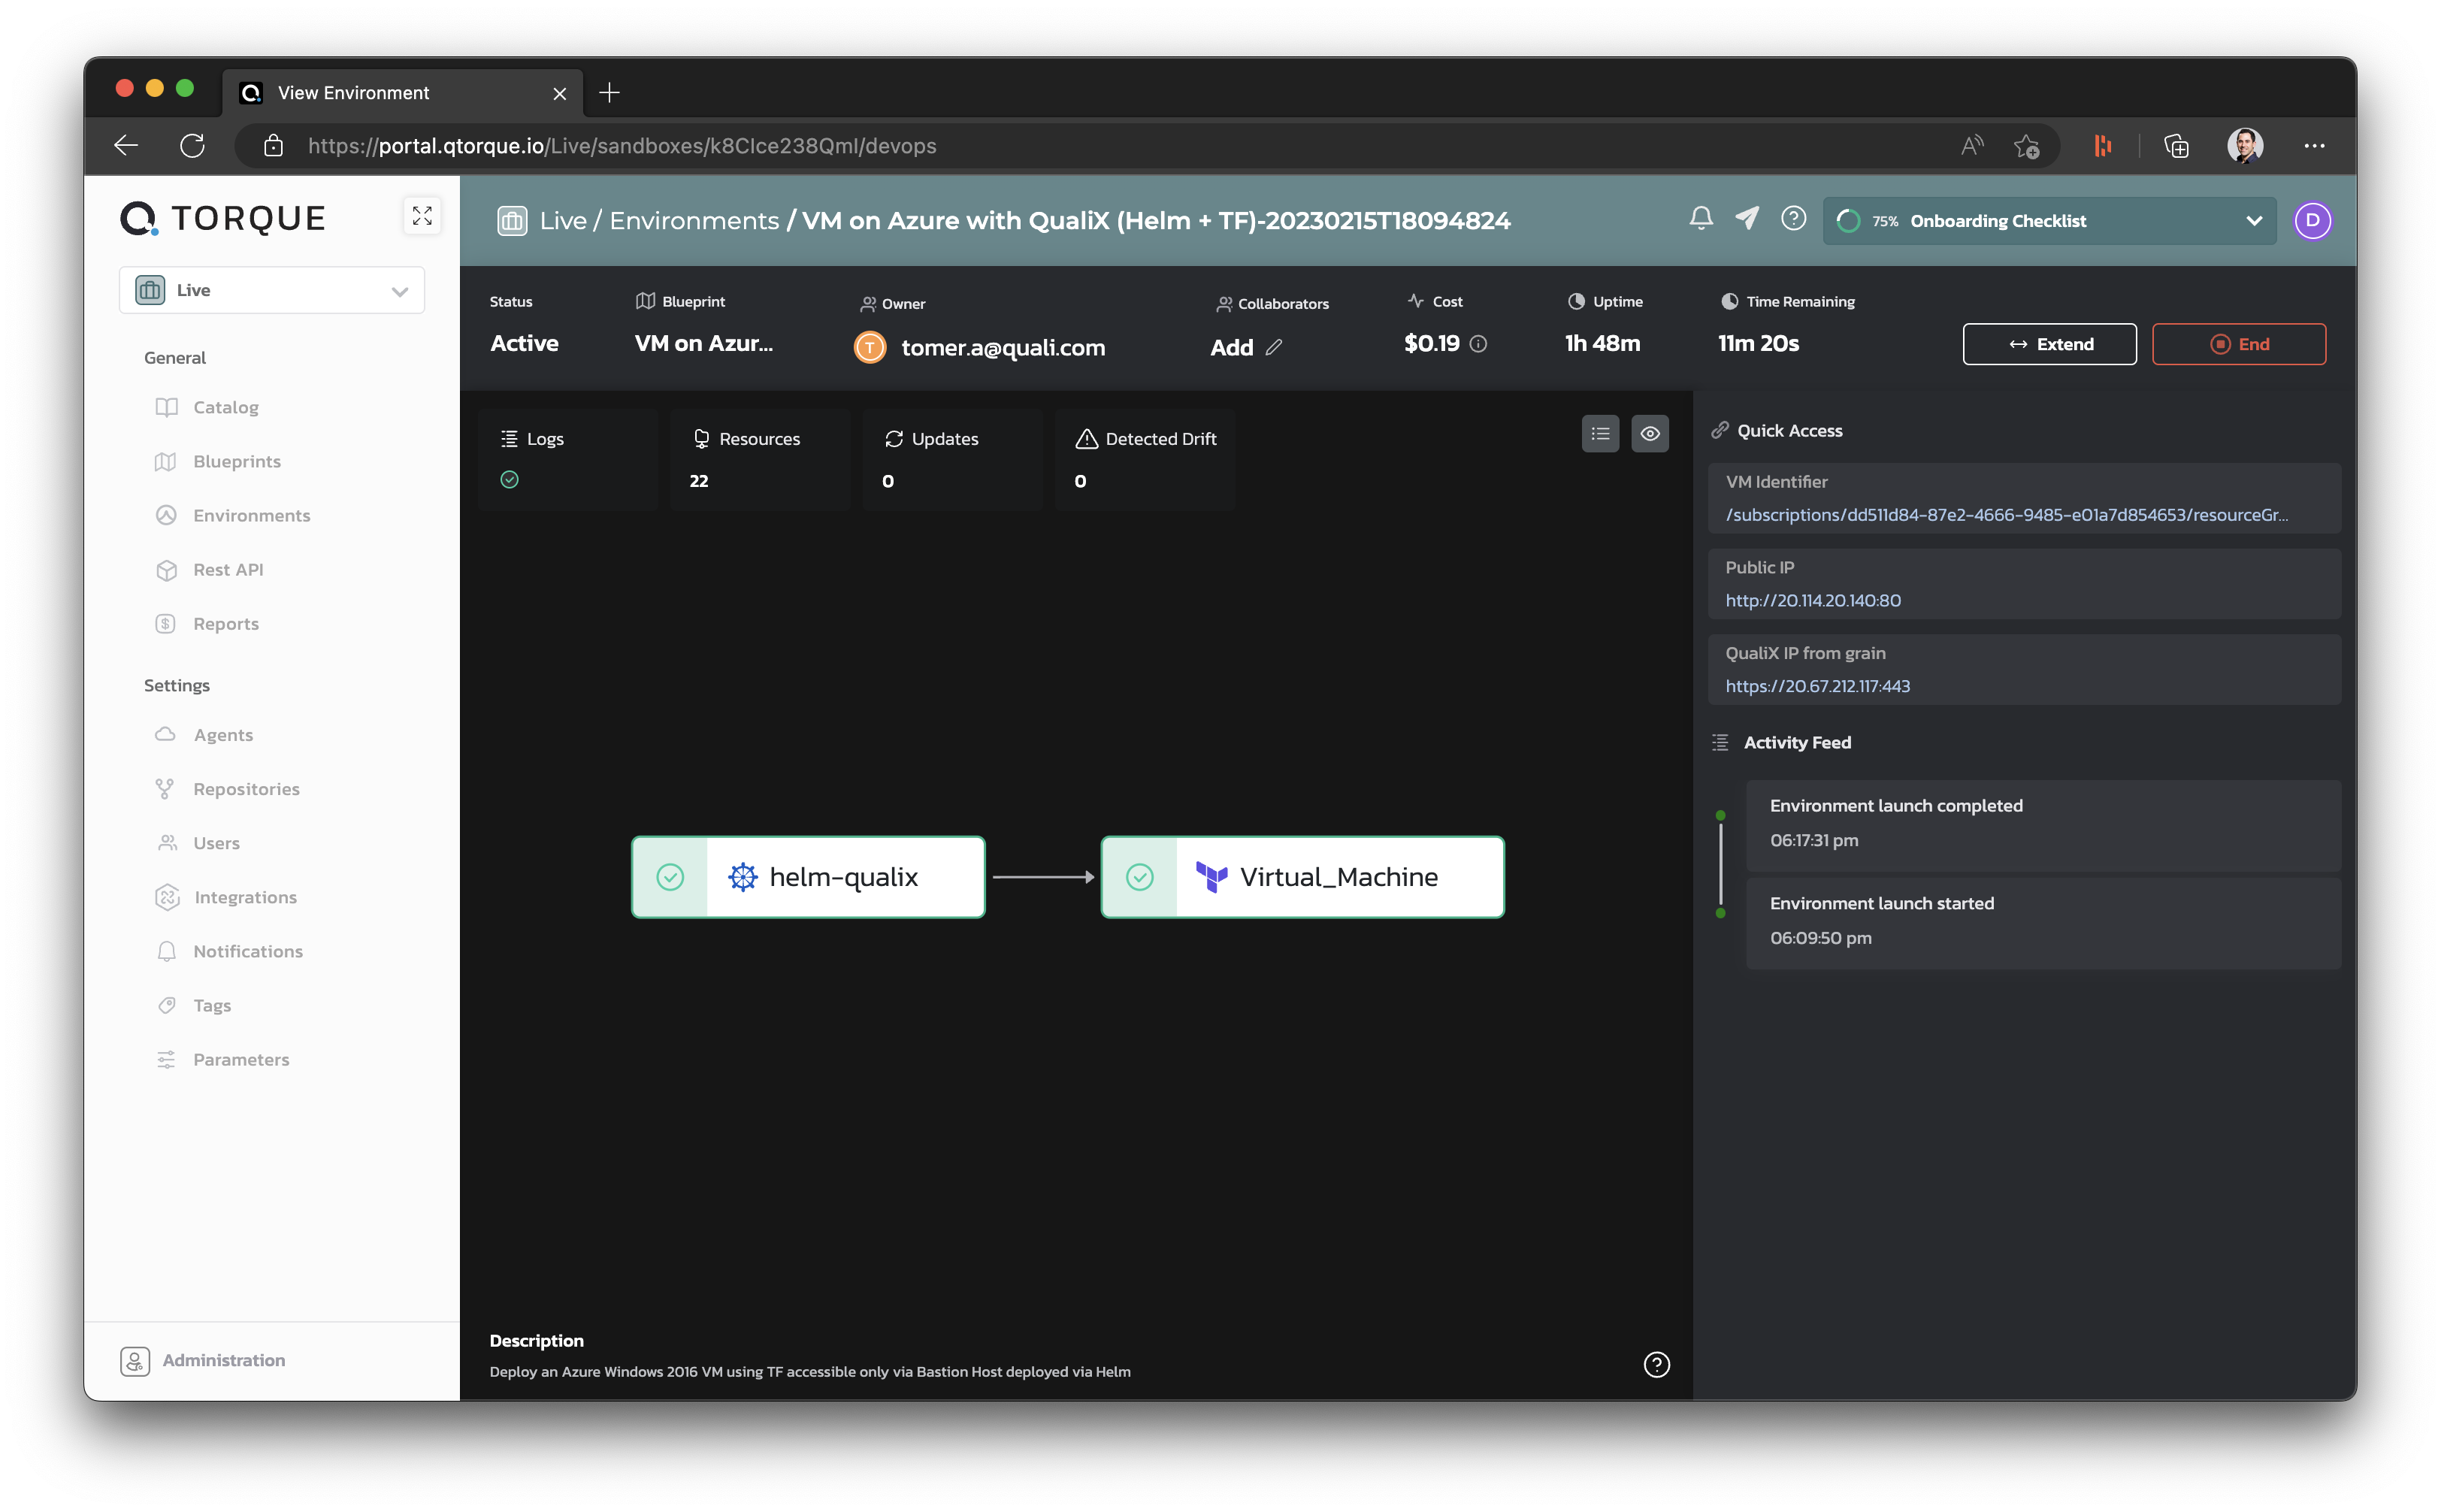
    Quali today announced enhancements to its Torque automated infrastructure platform to add support for security scans and Open Policy Agent (OPA) software being advanced under the auspices of the Cloud Native Computing Foundation (CNCF).

    OPA enables organizations to implement cybersecurity policies as code. The challenge many organizations have encountered is that not many developers have mastered the programming language required to implement OPA. Quali is embedding OPA in a platform that enables IT teams to implement it using a graphical tool that enables central management and application of those policies.

    David Ben Shabat, vice president of research and development at Quali, said the overall goal is to implement scans and policies in a way that reduces the number of misconfigurations that are made when organizations provision infrastructure-as-code (IaC).

    As part of that effort, Torque now flags any policies that fail validation. In addition, administrators can pick and choose which OPA policies to import, including both out-of-the-box and existing custom policies. Those policies then enable Torque to automate approvals or denials of deployments based on compliance with those policies after scans and other health checks have been run.

    Quali has been making a case for policy-based triggers for cost controls, automated start-up, shut down and pausing of IT environments to give IT teams more control over infrastructure using a software-as-a-service (SaaS) platform. That approach enables IT teams to provide a set of guardrails for provisioning infrastructure that prevent mistakes from being made, noted Ben Shabat. Those controls can be applied using the graphical tool Quali provides or programmatically via an application programming interface (API) that Quali exposes, noted Ben Shabat.

    It’s not uncommon for a port to be left open, for example, which cybercriminals later exploit to exfiltrate data. Quali is offering a DevOps platform that allows for central application of policies that act as guardrails to prevent developers from making these types of mistakes as an alternative to scripts created using tools such as Terraform. That approach also provides more visibility into how infrastructure resources are being consumed.

    Every minute a developer spends managing infrastructure is one less minute they could be spending writing code. As application environments become more complex, it is becoming more challenging for developers to manage infrastructure-as-code. The issue is that DevOps teams who could provision infrastructure for developers are overwhelmed by the number of projects they need to manage. As a result, DevOps teams are becoming bottlenecks. Naturally, that only encourages more developers to provision infrastructure on their own, leading to more mistakes.

    It’s not clear whether IT organizations will look for an alternative to provision infrastructure in a way that doesn’t require developers to have as much infrastructure expertise. However, as organizations look to lock down software supply chains, the way infrastructure is provisioned using code will, in many cases, need to be reconsidered within the context of a larger DevSecOps workflow.

  • Watching the Watchers: Solving the Problem of Meta-Permissions

    Watching the Watchers: Solving the Problem of Meta-Permissions

    The move to the cloud and microservices has introduced new challenges in managing permissions. Software has been broken down into small, independently-deployable microservices, each with its own unique set of permissions. These permissions make it excruciatingly hard to ensure and track correct access. While this technological shift is challenging, it pales in comparison to the cultural and organizational shifts it has caused—one of which is the challenge of authorization for authorization. The challenge of authorization for authorization, or “controlling access control,” is a crucial but often misunderstood aspect of system design, and  its recursive nature is quite confusing.

    At its core, authorization for authorization deals with ‘meta-permissions’—the permission to grant and revoke permissions for the designed system.

    Controlling Access Control

    Deciding who can do things inside an application is one thing. Deciding who can decide (or, in other words, dealing with meta-permissions) is another story entirely. Once you start dealing with authorization for authorization, there are two main problems to contend with: Recursiveness, which is a technical challenge, and the question of trust, which can be hard to handle and can have dire consequences if handled incorrectly.

    Naively, developers often choose to be the superusers—the ones calling the shots; retaining all of the power with them. This can produce a very stable and secure application, but will quickly put a strain on precious R&D resources, turning developers into bottlenecks for the entire business operation.

    The opposite approach—delegating all of the power away from developers to other stakeholders—is equally dangerous, often creating a slow-moving, inefficient bureaucracy (looking at you, security and compliance) or an unstable, risk-filled environment (looking at you, sales and product).

    At the end of the day, it’s a question of balance—one that varies for every company and application.

    When building this balance, it’s important to empower the various stakeholders (and customers) working with the application, giving them a significant amount of control and decision-making abilities to enable the business to move quickly and securely while enabling developers to monitor the flow without becoming a bottleneck.

    To keep you on track as you tackle this challenge, here are some guidelines, do’s, and don’ts:

    Common Pitfalls to Avoid

    ● Don’t mix up authentication and authorization: This might seem trivial, but it happens all the time. Authentication is the process of identifying the user, while authorization is the process of granting access to specific resources based on the authenticated user’s roles or privileges. Solutions are required for both.

    ● Thinking you won’t need authorization for authorization: Simple systems may require meta-permissions functionality and advanced ones will undoubtedly need it. It’s important to consider when you’d need this ability and set the groundwork for it accordingly.

    ● Limiting access control to the vendor side: It’s not enough to delegate access control from developers to the rest of the organization. Doing so merely moves the bottleneck up the chain. To appropriately delegate the workload, you must be able to assign at least some access controls to the end customers themselves, providing them with true self-service.

    ● Thinking access control is limited to direct human use: Your first users are likely to be human users, but with increasing automation, more and more of your “users” will be automated agents—other applications and AI agents acting on behalf of humans. You will need to cater to them, too, and it might be sooner than you think.

    ● Delaying providing interfaces to non-technical people: A powerful interface that’s intuitive to non-technical users is crucial for access control systems.

    Best Practices

    ● Create a cascading waterfall of trust and permissions: By creating a cascading system of permissions and trust, you can ensure that the right permissions are granted to the right users at the right time. Often, developers and security would be the main source of this waterfall, but it mustn’t end with them. Design your flow to gradually delegate more and more between the different levels with each level empowering the ones below it.

    ● Assign an owner: To avoid conflicts, such as two admins being able to remove each other, always have a primary admin, or “owner,” who takes precedence to avoid conflict. Owners often cannot be removed without transferring the title first.

    ● Identify bottlenecks early on: Identify potential bottlenecks in permission delegation (permissions that are hard to delegate, or manage) and have a plan and interfaces to mitigate in advance before friction piles up.

    ● Use a classic policy model (e.g. RBAC, ABAC) for your meta-policy: Just like with your regular permissions, there’s no need to reinvent the wheel. Start with common policy models first.

    ● Use the same policy model for your meta-policy: This can help to ensure consistency and ease of understanding across the system, lowering the cognitive load on system managers and users.

    ● Have meta audit logs: The information on who changed the meta-permissions is just as critical, if not more so, than who changed the permissions. Log it and track it.

    ● Build on top of existing AuthZ for AuthZ: Use tools that have authorization for authorization already baked into them (such as Permit.io), saving the effort of starting this from scratch.

    In conclusion, solving the problem of meta-permissions requires a multifaceted approach that considers both the technical and cultural challenges associated with modern software systems. By following the best practices outlined above and by carefully thinking through the design of the interfaces and trust flows that govern the system, it is possible to create a system that is secure, usable and ready to accelerate to the velocity required by modern cloud-empowered business today.

  • Understanding the Infrastructure Automation Maturity Model

    Understanding the Infrastructure Automation Maturity Model

    Nearly every company wants to evolve its digital transformation and increase the pace of software delivery and operations. And infrastructure automation is a new means to achieve these ends. It supports the emerging discipline of platform engineering and can increase scalability and reactivity to unforeseen events, enabling software ecosystems to be more anti-fragile. Increased infrastructure automation also helps free up engineers from focusing too much on managing DevOps when they really should be building out new features.

    But introducing more infrastructure abstraction can be met with certain challenges. This is often because departments have a wide range of cultures, processes and tooling already in place. With varying maturity levels across teams, it can be challenging to gauge where a company is before attempting to introduce new automation across the board. And as further evolution may require significant changes, having a baseline is key to planning for the future.

    I recently chatted with David Williams, senior vice president of market strategy at Quali, about an internal technique they’ve been using at Quali to gauge the maturity of their clients’ infrastructure automation. Their infrastructure automation maturity model breaks down the journey into four unique stages, moving from the least-mature ad-hoc automation to the most-mature autonomous solutions. Below, we’ll review this model and consider what questions need to be asked to ascertain where your team sits on the spectrum. We’ll see how enterprises can leverage such a model to hone in on improving their software operations.

    Four Questions to Determine Infrastructure Maturity

    DevOps is still a wild west in terms of how people approach it, said Williams. So before attempting to mandate sweeping cultural changes, it helps to first determine the base level of DevOps maturity within an organization. Here are four questions that can quickly assess the state of infrastructure automation within an organization.

    1. What Culture Already Exists?

    First, it’s good to evaluate the culture that already exists. How do teams deliver value and how is this value measured? Perhaps throughput or code quality is measured with specific metrics or SLAs. Understanding the DevOps attitude (and aptitude) within the organization will highlight pre-existing capabilities and show how teams collaborate.

    2. How Are People Organized?

    The genetic makeup of teams can dictate much about development and operations. How are teams organized? Are they large, siloed teams? Or are they two-pizza-sized teams? Understanding team organization and communication patterns are necessary to identify bottlenecks.

    3. What Processes Are Already in Place?

    Next, consider the development timelines and procedures already established and in use. Are teams applying SAFe, Lean, Agile or Scrum methodologies? What are these exact processes and how mature are they? Answers to these questions will demonstrate general release cadences and how teams drive productization.

    4. What Infrastructure Automation is Already Being Used?

    Lastly, you’ll need a window into what level of infrastructure automation, if any, is already in use today. How is it delivered? How is it managed? How is the success of this automation measured, and what is the overall outcome? You will likely find that automation is typically quite siloed and teams have differing approaches. This auditing is vital to identify what works well and what doesn’t.

    The Four Levels of the Infrastructure Automation Maturity Model

    Asking the above questions will quickly determine an organization’s “readiness state,” said Williams. But how do these answers map to the overall maturity of the organization’s infrastructure automation? Well, he shared four basic levels of infrastructure automation maturity that are commonly found in practice throughout today’s software development environments, ranging from bespoke scripts to more robust self-defining automation.

    Level 1: Ad-hoc

    The most basic level of infrastructure automation is ad-hoc integrations involving a mix of old and new technology. This level is chaotic and fragmented, with varying processes used throughout the organization. These bespoke integrations and scripts also may not have excellent visibility, limiting the potential for reusability within an organization.

    Level 2: Automation

    Next is having automation that is specifically tied to a certain technology stack. Nowadays, organizations are commonly hybrid multi-cloud, having adopted automation piecemeal with each new stack. This often results in multiple silos of automation stacks that are blind to each other. At this maturity level, one automation might fire off another automated procedure and so on, but engineers aren’t 100% aware of how they influence each other.

    Level 3: Frictionless

    The next level of infrastructure maturity begins to take the reins with more intentional automation adoption. At this stage, organizations embrace an internal developer platform, similar to Spotify’s Backstage, that helps engineers deliver and manage infrastructure more seamlessly. This tooling is more advanced than other levels integrating key commands into the developer’s IDE. Doing so eliminates the need to switch between environments and reduces friction.

    Level 4: Self-Defining

    Finally, the most advanced form of automation involves deeper intelligence within application operations, including the ability to dynamically optimize infrastructure. At this stage, infrastructure is self-defining, meaning production applications can automatically adapt, be self-governed and enable bursting and non-bursting capabilities. Such intelligence is typically proprietary to cloud providers, said Williams, yet companies often desire this intelligence inherent at the application level. Williams describes this stage as the “intelligent allocation of resources in line with application life cycle requirements.”

    Benefits of Self-Defining Infrastructure Automation

    Self-defining infrastructure automation has many benefits for companies, including having the infrastructure in line with application needs, scalability and measuring usage to optimize cloud spending. Many points within the software development life cycle could warrant increased automation, such as infrastructure-as-code (IaC), deployment release engines, configuration, traffic scalability, cloud management, containerization and documentation. But it’s not until you open conversations around infrastructure automation maturity and understand who is responsible for managing it that you can hone in on what areas can be improved.