Category: IT as Code

  • Complete Guide to AWS Savings Plans

    Complete Guide to AWS Savings Plans

    AWS Savings Plans are a flexible and cost-effective way to save on your Amazon Web Services (AWS) usage. These plans allow you to commit to a specific amount of compute capacity over a one- or three-year term in exchange for a significant discount on your AWS usage. Savings plans can help you reduce your AWS bill by up to 72%, depending on the type of plan and your level of commitment.

    Why Do You Need AWS Savings Plans?

    With the growing reliance on cloud infrastructure in modern IT, it is crucial for organizations to optimize cloud computing costs without compromising on performance or scalability. AWS Savings Plans address this need by providing a flexible and cost-effective solution that allows you to commit to a certain level of usage at a discounted rate.

    With AWS Savings Plans, by committing to a specific amount of compute capacity over a set time period, you can save up to 72% on your AWS usage. This can result in significant cost savings for your organization, freeing up resources to invest in other business-critical initiatives.

    Another benefit of AWS Savings Plans is the flexibility they offer. Unlike Reserved Instances, which require you to specify instance type, operating system and region, Savings Plans are more flexible and can be applied across different instance types, regions and operating systems. This flexibility makes it easier for you to optimize your cloud computing costs while still meeting your business needs.

    Difference Between AWS Savings Plans and Reserved Instances

    AWS Savings Plans and Reserved Instances are both designed to help you save on your AWS usage, but they offer different levels of flexibility and cost savings.

    Reserved Instances require you to commit to a specific instance type, operating system and region for a one- or three-year term in exchange for a discount on your AWS usage. While this can result in significant cost savings, it also limits your ability to optimize your cloud computing costs based on changing business needs.

    AWS Savings Plans offer a more flexible solution that allows you to commit to a certain level of usage across different instance types, regions and operating systems. Additionally, in most scenarios, Savings Plans can provide a higher level of cost savings compared to Reserved Instances.

    Types of AWS Savings Plans

    There are two types of AWS Savings Plans: Compute Savings Plans and EC2 Instance Savings Plans.

    Compute Savings Plans

    Compute Savings Plans are the most flexible type of Savings Plans, providing a significant discount on your AWS usage across any instance type, region or operating system. This flexibility makes it easy for you to optimize your cloud computing costs based on your changing business needs.

    Compute Savings Plans offer a discount of up to 66% compared to on-demand pricing, depending on the level of commitment you make. They can be used across all AWS services that are powered by Amazon EC2 instances, including Amazon EMR, AWS Lambda and Amazon ECS.

    EC2 Instance Savings Plans

    EC2 Instance Savings Plans are a more specific type of Savings Plan, offering a discount on your AWS usage for a specific instance type within a region. These plans provide a higher level of cost savings compared to Compute Savings Plans, with discounts of up to 72%.

    EC2 Instance Savings Plans are ideal for organizations that have a predictable workload and require specific instance types within a region. However, they offer less flexibility than Compute Savings Plans, as they cannot be applied across different instance types, regions or operating systems.

    AWS Savings Plans Pricing Models

    AWS Savings Plans offer three different payment options to suit your organization’s budget and commitment level: All Upfront, Partial Upfront and No Upfront.

    All Upfront

    With the All Upfront payment option, you pay for the entire term of your Savings Plan upfront, resulting in the highest discount compared to on-demand pricing. This option is ideal for organizations that have the budget available to make a significant upfront payment in exchange for maximum cost savings.

    Partial Upfront

    The Partial Upfront payment option allows you to pay a portion of your Savings Plan upfront and the remaining balance on a monthly basis. This option provides a balance between upfront commitment and ongoing flexibility, with a lower discount compared to the All Upfront option.

    No Upfront

    With the No Upfront payment option, you pay for your Savings Plan on a monthly basis, with no upfront payment required. This option provides the lowest discount compared to on-demand pricing but offers the greatest flexibility for organizations with limited budgets or uncertain future usage requirements.

    How to Monitor and Manage AWS Savings Plans

    Monitoring and managing your AWS Savings Plans, as part of your overall cloud operations strategy, is critical to ensuring that you are optimizing your cloud computing costs and maximizing your savings. AWS provides several tools and services to help you monitor and manage your Savings Plans effectively:

    • AWS Cost Explorer: A powerful tool that allows you to analyze your Savings Plans usage and costs, helping you identify opportunities to optimize your cloud computing costs. With Cost Explorer, you can view your Savings Plans coverage, utilization and savings, as well as forecast your future usage and costs.
    • AWS Budgets: This service allows you to set custom cost and usage budgets for your organization, helping you track your Savings Plans usage and ensure that you are staying within your budget.
    • Savings Plans Recommendations: This feature analyzes your past usage and recommends the optimal Savings Plans for your organization. It can help you make informed decisions about which Savings Plans to purchase and how much commitment to make.

    Conclusion

    AWS Savings Plans are an excellent solution for organizations looking to optimize their cloud computing costs and save on their AWS usage. With their flexibility, cost savings and easy monitoring and management options, AWS Savings Plans are a valuable tool for any organization using AWS services.

    To unlock the full potential of AWS Savings Plans, it’s crucial to understand the different types of plans, their pricing models and how to effectively monitor and manage your usage. By doing so, you can maximize your savings and ensure that your organization is getting the most out of its investment in AWS.

  • Google Announces Availability of iPaaS Service

    Google Announces Availability of iPaaS Service

    Google today made available an integration platform-as-a-service (iPaaS) capable of invoking a range of methods to integrate applications.

    Initially developed for the Apigee application programming interface (API) management platform Google acquired in 2016, the Application Integration service can now, for example, also consume a publish and subscribe event or an event driven through a Salesforce platform.

    Amit Zavery, vice president and general manager for Google Platform, said the Application Integration service provides IT organizations with all the benefits of an iPaaS without requiring them to stand up and manage an integration platform themselves.

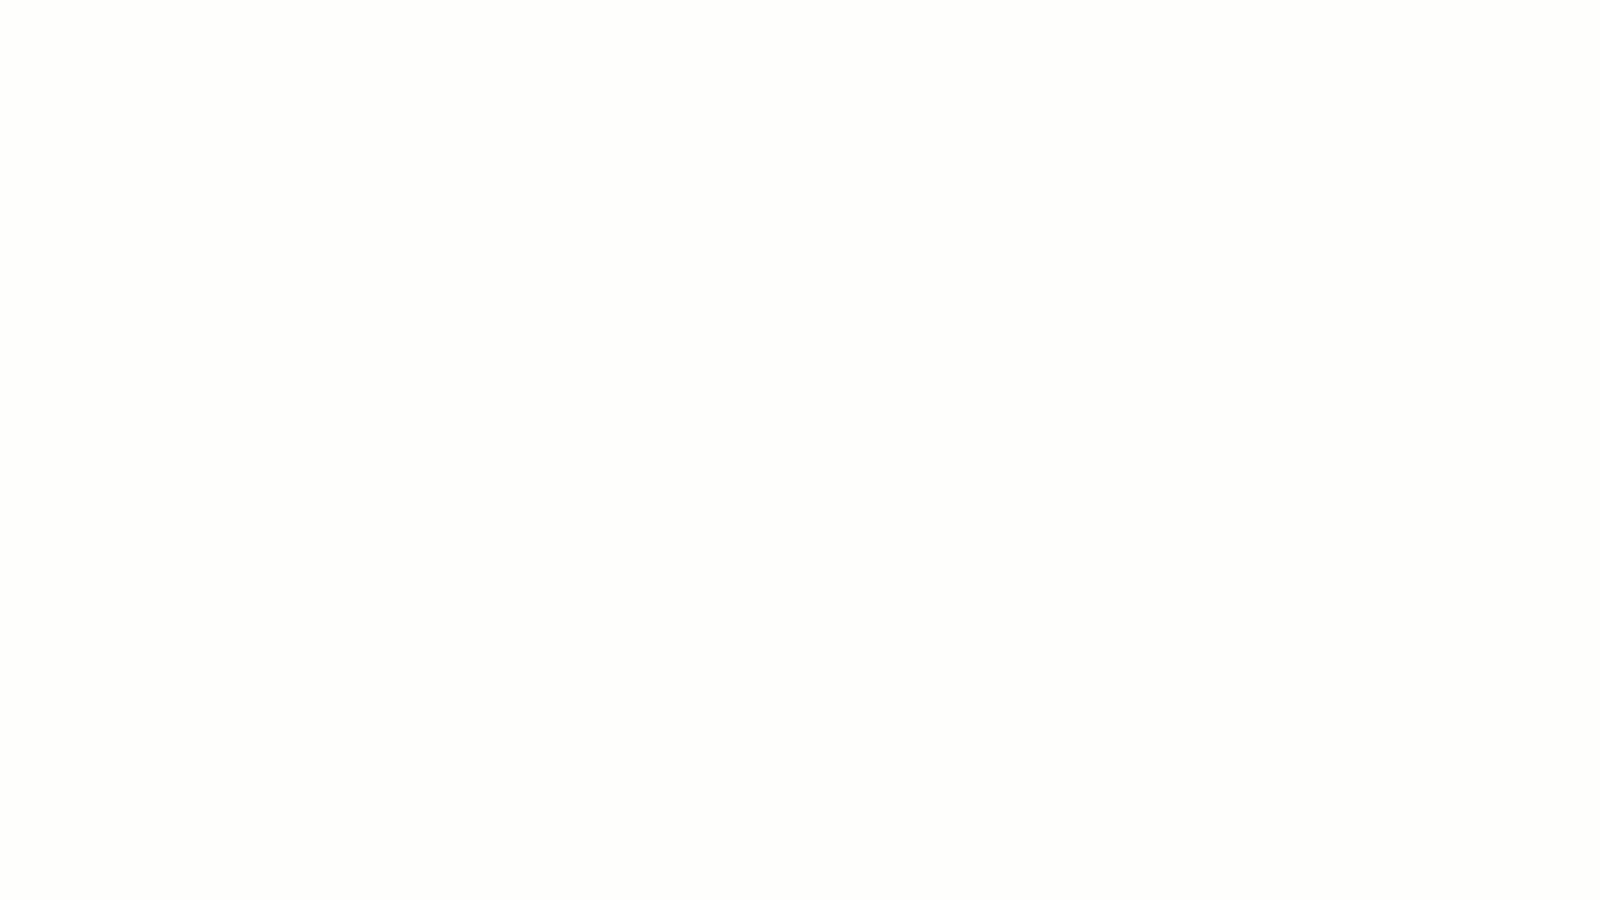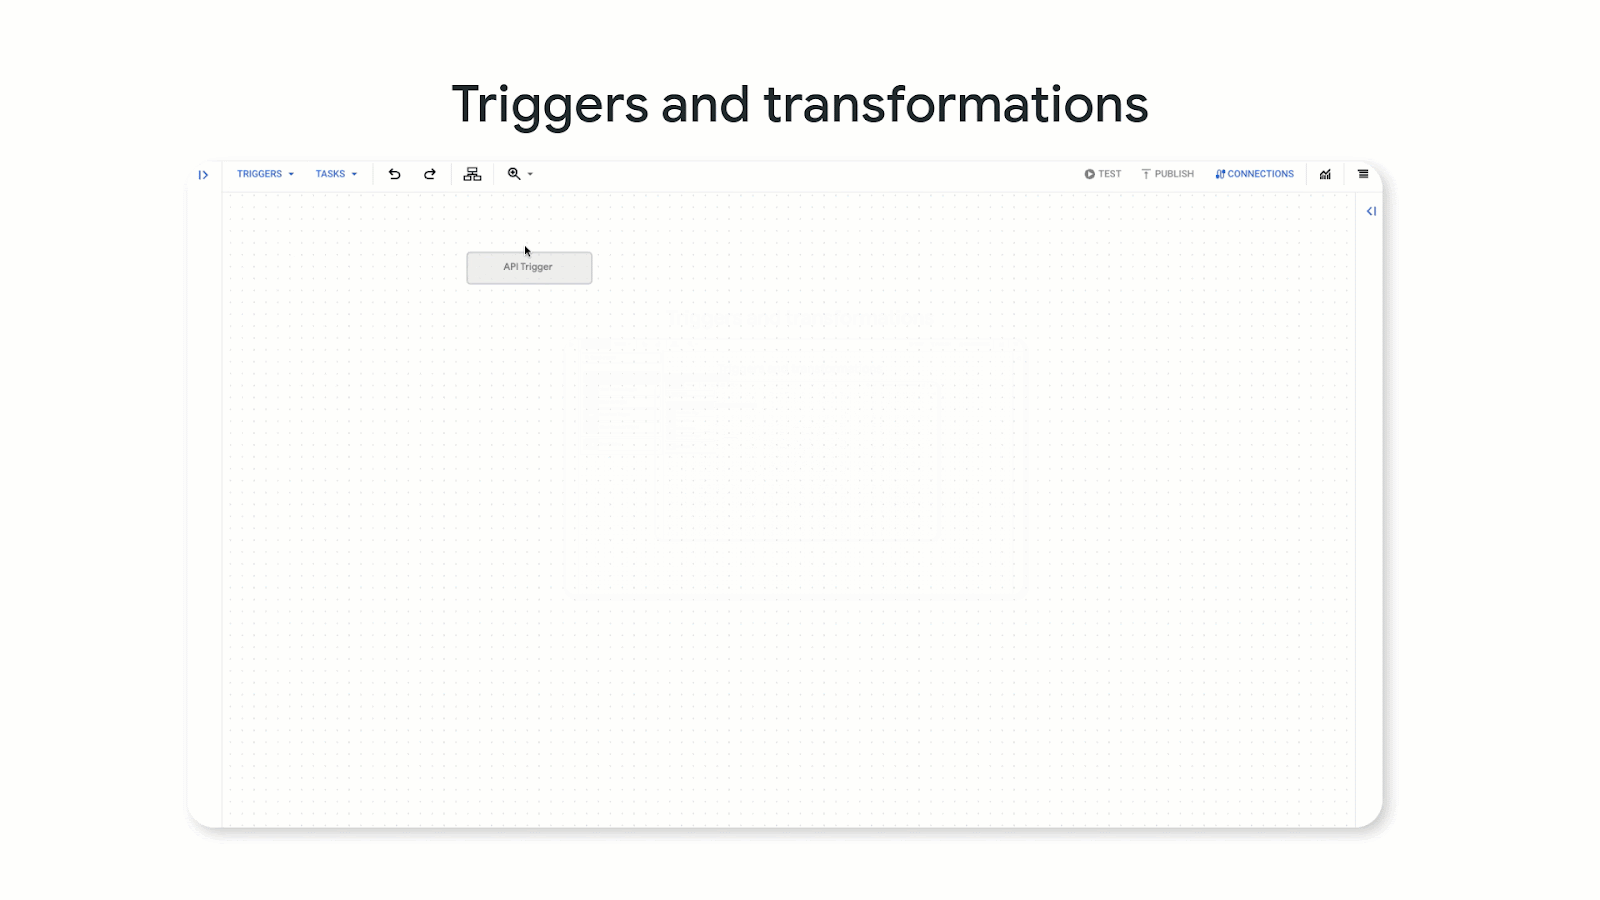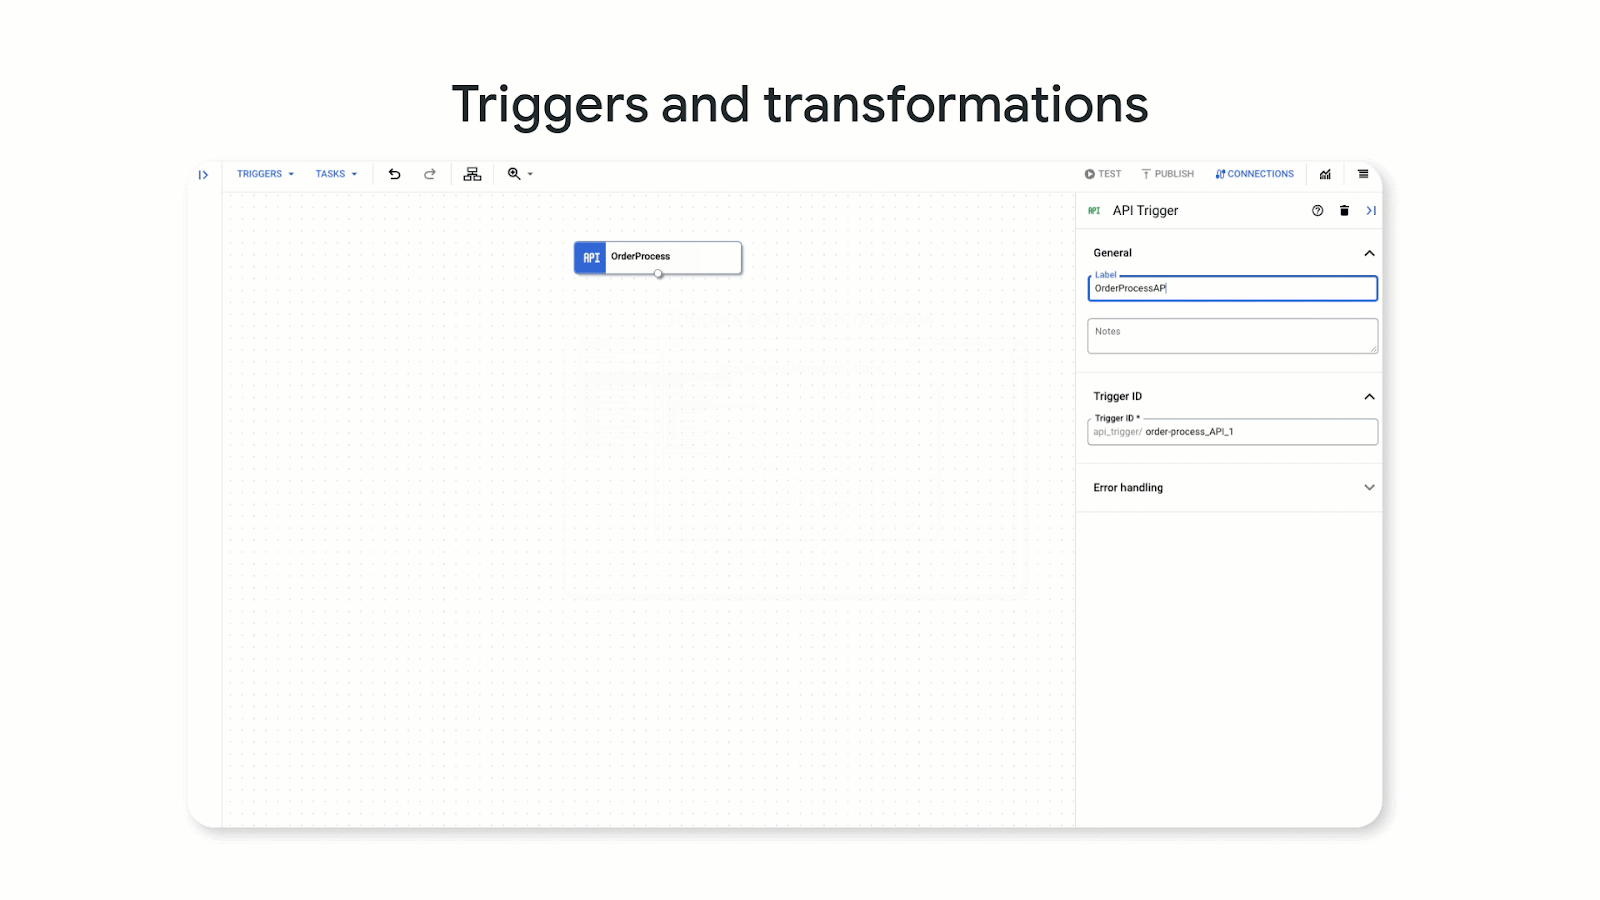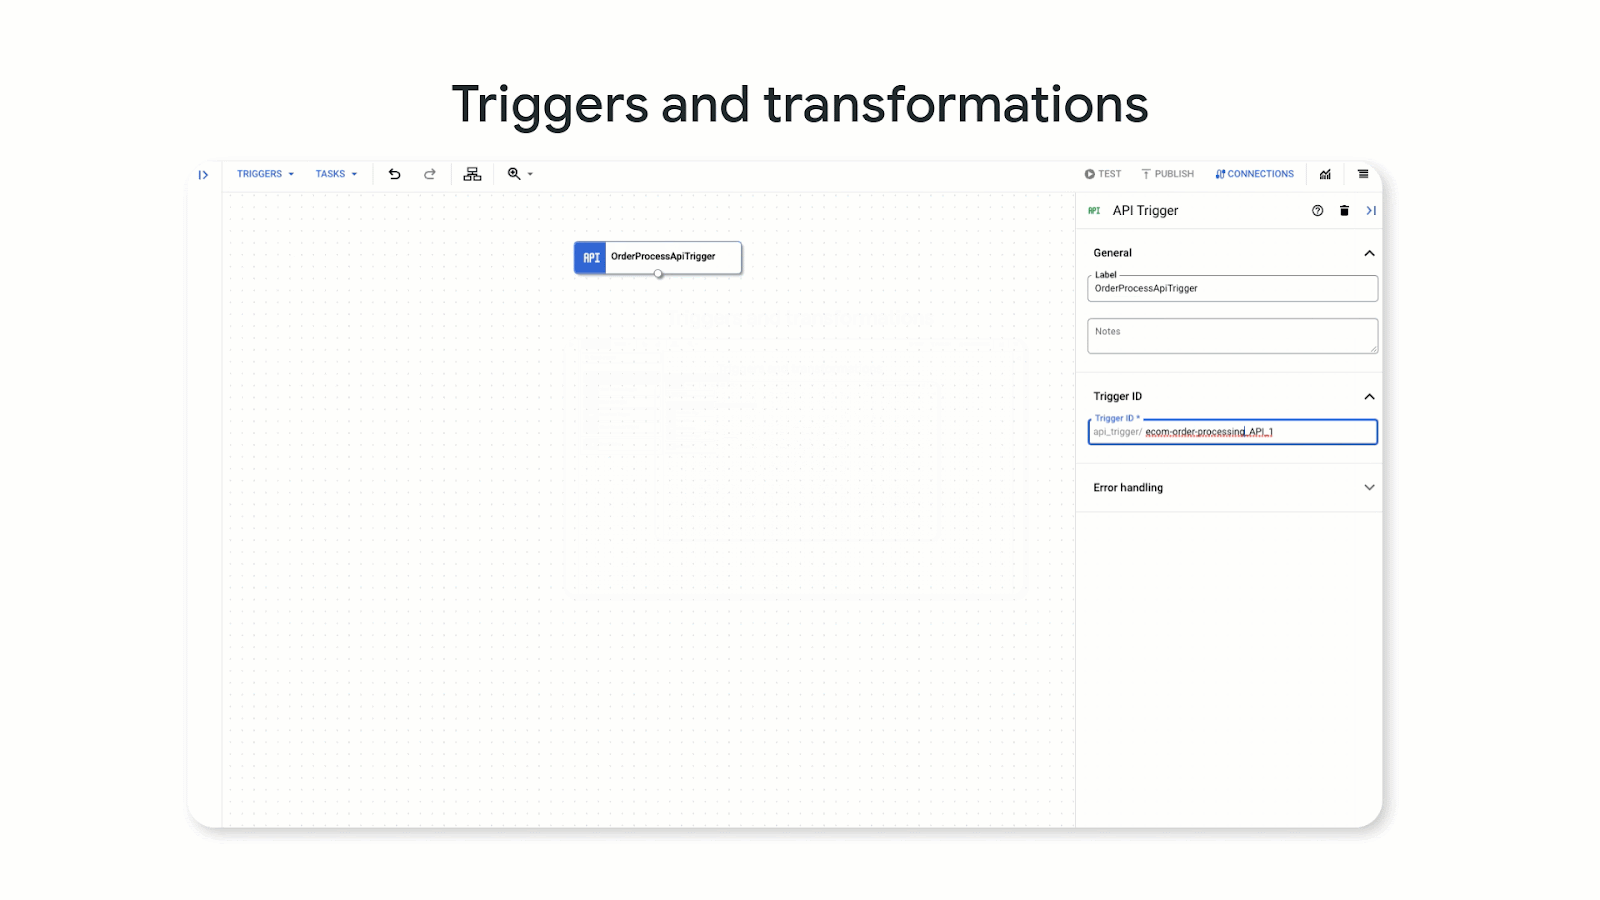
    The Google Application Integration service also provides access to a Visual Integration Designer tool that can be used to build workflows using a low-code tool. In total, there are now more than 75 connectors that can be used to integrate multiple Google Cloud services and third-party platforms that can run in either a cloud or on-premises IT environment, said Zavery.

    In general, visual tools are transforming how integrations are created and expanded within organizations, noted Zavery. Rather than using lower-level procedural code, a visual tool enables developers to employ low-code to create integrations. That makes it simpler to collaborate with business users that can now more easily participate in developing workflows.

    In fact, in some cases, business users, otherwise known as citizen developers, have enough technical acumen to create their own workflows using low-code tools.

    There are, naturally, going to be plenty of complex integration challenges that will require procedural code, but the bulk of the integrations required today are not especially complex.

    Regardless of who creates the integration, the number of them being employed across an enterprise organization continues to increase as more digital business transformation initiatives are launched. Developers are not going to be able to keep pace with the demand for those integrations if they rely solely on procedural code. The only way to effectively reduce the backlog for integrations is to rely more on visual tools to construct them. In most cases, the integration being created is relatively trivial. The only reason it wasn’t created sooner is there are not enough developers available to complete that task using procedural code.

    There are, of course, no shortage of iPaaS options available. As more workloads are deployed in the cloud, Google is betting the center of gravity for integration will shift toward the places where modern microservices-based workloads are deployed to reduce overall latency.

    It’s not clear whether organizations still view integration as an afterthought versus employing an integration platform around which all applications revolve. That latter approach tends to reduce the total cost of integration when compared to using multiple point products that are not managed via single framework, noted Zavery.

    Ultimately, IT teams that adopt an iPaaS are able to focus more on higher-value IT tasks. The issue is determining which integration projects really require professional developers with lots of integration expertise and which, via a low-code tool, can be handled by almost any developer.

  • Postman Acquires Akita Software to Gain API Observability

    Postman Acquires Akita Software to Gain API Observability

    Postman today announced it has acquired Akita Software to gain access to a platform for monitoring and observing application programming interfaces (APIs).

    The first integration of the respective products offered by both companies will arrive in beta this fall.

    Postman CEO Abhinav Asthana said the acquisition of Akita Software will make it much simpler for organizations to discover what APIs are being employed across an enterprise. A recent Postman survey found that 28% of developers are now deploying APIs at least once per week.

    The Akita Software platform will make it simpler for organizations to discover both rogue APIs that have been created by a shadow IT project and zombie APIs that have been inadvertently left exposed long after they are needed.

    Akita Software’s CEO Jean Yang said the integration with Postman’s API management platform will provide a rich source of data that can be used to add artificial intelligence (AI) capabilities to Akita’s API observability platform. For example, generative AI capabilities should make it simpler to create summaries in natural language that explain the calls an API is making to specific data sources.

    In addition, the combined company will be in a better position to enable organizations to better secure their APIs after deployment by surfacing anomalous behavior indicative of an API that is being used to exfiltrate data, she added.

    The merger with Postman will, in effect, enable the combined entity to provide a complete ecosystem for managing APIs, noted Yang.

    Most APIs are used primarily to interconnect internal-facing applications and systems, with a subset used to integrate partners. Only a relatively small percentage of APIs are externally facing in the sense that they expose data to the internet. Many organizations, however, fail to appreciate how quickly an internally facing API can become externally facing over the course of its life cycle. As such, IT teams need tools and platforms that can manage and secure APIs as they evolve.

    As APIs continue to play a crucial role in advancing business goals, there is a clear need for increased visibility as the types of APIs employed also continue to expand. Most APIs in use today are based on the REST format, but there are also APIs based on GraphQL, event-driven architecture and various messaging platforms. None of these newer APIs will supplant REST APIs any time soon. Rather, they are being applied to drive additional processes alongside REST APIs.

    In the longer term, it’s not clear how many APIs will be managed by the developers that created them versus a centralized DevOps team. However, the more APIs that are deployed in a production environment, the less feasible it becomes for developers to manage their life cycle. The challenge is making sure there is some type of structured workflow in place that, at the very least, makes everyone involved in the process aware that a new API has been created and deployed.

  • Shift Left With DAST: Dynamic Testing in the CI/CD Pipeline

    Shift Left With DAST: Dynamic Testing in the CI/CD Pipeline

    Dynamic application security testing, or DAST, is a process used to evaluate an application’s security while it’s running rather than while it’s in a static state. This method involves simulating attacks on an application, identifying vulnerabilities and analyzing the responses. DAST focuses on the exposed HTTP and HTML interfaces of web-enabled applications, making it an excellent tool for spotting security vulnerabilities that may occur during an application’s active runtime.

    DAST is a ‘black-box’ testing method, meaning it tests the application from the outside in—much like a potential attacker might. It doesn’t have access to the source code and instead focuses on the application as a whole rather than its individual components. This external perspective enables DAST to discover potential security threats that static testing methods might miss.

    While DAST is an effective security testing tool, it becomes even more potent when paired with a shift left approach.

    Understanding the Concept of ‘Shift Left’ in Software Testing

    Shift left is a practice in software development where testing is conducted earlier in the life cycle—that is, it’s ‘shifted left’ on the project timeline. Traditionally, testing was seen as the last phase before the release of a software product. However, with the shift left approach, testing becomes an integral part of every stage of the development process from planning to deployment.

    This approach has several advantages. It allows for the identification and resolution of issues earlier in the development process, reducing the cost and effort required to fix them later. It also encourages collaboration between developers and testers, fostering a more cohesive, efficient development environment.

    Shift left is not just a testing strategy but a philosophy that promotes preventive measures over reactive solutions. It’s about building quality and security into software from the get-go, rather than tacking it on at the end.

    DAST in the Context of Shift Left

    Importance of DAST in Early Stages of Development

    The integration of DAST in the early stages of development is crucial for several reasons. First, by conducting dynamic security testing from the onset, teams can identify vulnerabilities earlier, making them easier and less costly to fix. This proactive approach helps to prevent security issues from becoming ingrained in the code, which can lead to significant problems down the line.

    Second, early integration of DAST encourages a security-focused mindset from the beginning of the project, promoting a culture of security within the team. This cultural shift is crucial in today’s cybersecurity climate, where threats are increasingly sophisticated, and the stakes are higher than ever.

    How DAST Complements Other Testing Methods

    DAST doesn’t replace other testing methods; rather, it complements them. While DAST focuses on external vulnerabilities, other testing methods like static application security testing (SAST) can target internal issues. By combining these methods, teams can achieve a more comprehensive view of their application’s security.

    In a shift left approach, this combination of testing methods can be very powerful. By conducting these tests early and often, teams can ensure that both the external and internal aspects of their application are secure. This layered approach to security testing can help to catch any vulnerabilities that might otherwise slip through the cracks.

    Incorporating DAST Into the CI/CD Pipeline

    1. Understanding the Application Structure

    Before we can integrate DAST into the CI/CD pipeline, it’s crucial to understand the structure of the application we’re working with. This involves understanding the layers of the application, the technologies used and the data flows. By analyzing the application’s architecture, you can identify the critical components that need more attention during the security testing phase.

    Understanding the application structure is not just about knowing the technology stack. It’s also crucial to understand the business logic and the functionality of the application. This will allow you to create better test cases during the DAST process. Additionally, understanding the application structure will enable you to make better decisions when configuring the DAST tool, leading to more efficient and effective security testing.

    Finally, understanding the application structure will help you prioritize the vulnerabilities found during the DAST process. Not all vulnerabilities are created equal; some might be more critical due to the data they expose or the potential damage they could cause to the application. 

    2. Configure the DAST Tool

    The next step is to configure the DAST tool. This involves setting up the scanning parameters, defining the test cases, and tuning the tool to reduce false positives.

    When configuring the DAST tool, it’s important to strike a balance between thoroughness and speed. You want the tool to be able to identify all potential vulnerabilities, but you also want the scanning process to be fast enough not to slow down the development process. This balance can be achieved by carefully selecting the scanning parameters and continuously tuning the tool based on the results of the scans.

    Additionally, when configuring the DAST tool, you should consider the unique characteristics of your application. For example, if your application uses a specific technology or framework that is known to have certain vulnerabilities, you should ensure that the DAST tool is configured to test for these vulnerabilities. Similarly, if your application handles sensitive data, you should prioritize testing the components that process and store this data.

    3. Integrating DAST Into the CI Pipeline

    The next step is to integrate DAST into the CI pipeline. The CI pipeline is a sequence of steps that developers follow to merge their changes into the main codebase. By integrating DAST into this pipeline, we can ensure that every code change is automatically tested for security vulnerabilities.

    Integrating DAST into the CI pipeline can be achieved using various tools and plugins. Most DAST tools provide APIs that allow you to automate the testing process. By using these APIs, you can trigger a DAST scan every time a new code change is pushed to the repository. This allows you to catch vulnerabilities early in the development process, reducing the cost and time needed to fix them.

    However, integrating DAST into the CI pipeline is not a one-time task. It requires continuous monitoring and tuning to ensure that the testing process remains effective. You will need to update your DAST configurations as the application evolves, add new test cases as new features are developed, and fine-tune the testing process to reduce false positives. 

    4. Scan for Vulnerabilities

    After integrating the DAST tool, you can start scanning for vulnerabilities. The scanning process involves executing the test cases defined during the configuration phase and identifying potential security issues in the application. Depending on the size and complexity of your application, this process can take from a few minutes to several hours.

    During the scanning process, the DAST tool will interact with the application just like a real user would. It will send inputs to the application, observe the responses and analyze them for signs of security vulnerabilities. This dynamic approach allows the tool to identify vulnerabilities that static analysis tools might miss, such as runtime vulnerabilities and issues related to the application’s business logic.

    5. Analyze and Prioritize Findings

    Once the scanning process is complete, the next step is to analyze and prioritize the findings. The DAST tool will provide a report of the identified vulnerabilities, including their type, location and potential impact. This information should be used to prioritize the vulnerabilities based on their risk to the application and the business.

    Analyzing and prioritizing the findings is not an easy task. It requires a deep understanding of the application, the business, and the threat landscape. You need to consider various factors, such as the potential impact of the vulnerability, the likelihood of exploitation, the sensitivity of the affected data, and the complexity of the remediation process. By considering these factors, you can prioritize the vulnerabilities and focus your efforts on those that pose the highest risk.

    In addition, analyzing and prioritizing the findings should involve all relevant stakeholders. Developers, security teams, and business leaders should all participate in this process, as they each bring unique perspectives and insights that can help make better prioritization decisions.

    6. Remediate and Retest

    After analyzing and prioritizing the findings, the next step is to remediate the vulnerabilities and retest the application. Remediation involves modifying the application’s code or configuration to eliminate the identified vulnerabilities. Depending on the complexity of the vulnerabilities, this process can involve simple code changes or significant architectural modifications.

    After remediation, it’s crucial to retest the application to ensure that the vulnerabilities have been effectively addressed. This involves running the DAST tool again and verifying that the previously identified vulnerabilities are no longer present. Additionally, retesting allows you to check for new vulnerabilities that might have been introduced during the remediation process.

    Remediation and retesting is a continuous process. As new vulnerabilities are discovered and new features are developed, you will need to repeat this process to ensure the ongoing security of your application. This continuous effort is a critical component of the shift left with DAST strategy.

    7. Continuous Monitoring and Updates

    The final step in incorporating DAST into the CI/CD pipeline is continuous monitoring and updates. This involves regularly checking the effectiveness of the DAST tool, updating its configurations as the application evolves, and tuning it to reduce false positives.

    Continuous monitoring and updates are crucial to maintaining the effectiveness of your shift left with DAST strategy. As the application evolves and the threat landscape changes, the DAST tool needs to be updated to remain effective.

    Conclusion

    In conclusion, incorporating DAST into the CI/CD pipeline is a powerful strategy to enhance the security of your software. By understanding the application structure, integrating DAST into the CI pipeline, configuring the DAST tool, scanning for vulnerabilities, analyzing and prioritizing findings, remediating and re-testing, and continuously monitoring and updating, you can unleash the power of shift left with DAST. This comprehensive approach will allow you to identify and address security vulnerabilities early in the development process, leading to more secure and reliable software.

  • Splunk Adds Hub to Extend Observability to Edge Computing Platforms

    Splunk Adds Hub to Extend Observability to Edge Computing Platforms

    Splunk today launched a platform for ingesting data from sensors, industrial equipment and internet-of-things (IoT) platforms so that it can be analyzed alongside data collected from IT environments.

    Announced at the company’s .conf23 conference, the Splunk Edge Hub extends the reach of the troubleshooting platform Splunk provides that increasingly involves various types of edge computing platforms.

    Tom Casey, senior vice president for products and technology at Splunk, said Splunk Edge Hub is designed to be deployed in those edge computing environments and reduce the total amount of data that needs to be transferred back to an instance of the Spunk analytics platform running in a data center or in the cloud.

    That approach makes it possible to remotely monitor everything from environmental conditions to identifying anomalies indicative of an outage that might be prevented. The overall goal is to unify visibility across IT and operational technology (OT) environments as these systems and applications become more integrated, said Casey.

    It’s not clear how quickly that integration is occurring, given the historic cultural divide that has existed between IT and OT teams. But with the rise of digital business transformation initiatives, the data collected from edge computing platforms is increasingly being incorporated into a wide range of applications deployed at the edge, in local data centers and in the cloud.

    In general, observability tools are being used to not only improve processes but identify and block suspicious activity. Of course, OT teams have been monitoring edge computing platforms for decades, but observability platforms make it feasible to interrogate logs, metrics and traces to hopefully discover issues before there is a disruption to services. The challenge, of course, is that not everyone on either the OT or IT team necessarily knows how to shape the queries required to discover the root cause of a potential issue. The Splunk approach essentially leverages the skillset of IT professionals that have mastered its platform to address that issue; something most OT professionals are not going to be able to do using their existing tools and platforms.

    One way or another, DevOps teams will soon need to be able to remotely diagnose edge computing issues as the number of workloads deployed on these platforms expands. IT teams are not going to be able to travel to the physical location of every edge computing platform every time an issue arises. In many ways, the rise of edge computing will force a transition to observability tools that will enable IT teams to more proactively manage IT environments rather than responding after a metric that OT teams are monitoring has already exceeded its threshold.

    In the event there is still an issue, observability platforms should also reduce mean-time-to-remediation (MTTR) as visibility into IT environments, including edge computing platforms, is improved.

    It’s not likely that OT and IT teams will ever be completely unified, but as observability platforms continue to evolve, there will be much greater opportunities for collaboration.

  • A DevOps Guide to IoT Technology

    A DevOps Guide to IoT Technology

    Internet-of-things (IoT) is a term used to describe the network of physical devices—from everyday household items to sophisticated industrial tools—connected to the internet, sharing and collecting data. With the advent of cheap computer chips and the ubiquity of wireless networks, it’s possible to make anything a part of the IoT. Add to that the exponential growth in artificial intelligence and machine learning, and the IoT is a truly significant part of our lives.

    The IoT allows devices to communicate and interact over the internet, and they can be remotely monitored and controlled using technologies many of us have never heard of, such as MQTT, QUIC and AMQP. The proliferation of these devices has led to an exponential increase in the amount of data we can gather, analyze and use to make more informed decisions. We’ve already seen the transformative potential of IoT in our homes, workplaces and cities, and it’s only set to increase as more and more devices come online.

    At the heart of this technology is the concept of seamless connectivity and communication. However, the rapid development and deployment of IoT devices pose significant challenges. This is where the DevOps approach comes in, offering a solution to these challenges by improving efficiency and effectiveness in the development and operation of IoT systems.

    Importance of DevOps in IoT Development and Deployment

    In the context of IoT, DevOps is crucial. IoT devices are often deployed in the field, in homes or in other environments where physical access is difficult or impossible. As such, the ability to update and manage these devices remotely is a critical necessity. DevOps methodologies enable this remote management, providing mechanisms for continuous integration and continuous delivery (CI/CD) that make it possible to push updates to devices regularly and reliably.

    Moreover, given the pace at which IoT technology is advancing, it’s crucial to be able to adapt quickly to changes and new developments. In this regard, DevOps is invaluable. By bringing together development and operations, it allows for more agile response to changes, faster issue resolution and overall better performance.

    The Role of DevOps in IoT

    Speeding Up IoT Development Cycles

    One of the key benefits of using a DevOps approach in IoT development is the ability to speed up development cycles. With traditional development practices, the time between identifying a requirement or an issue and implementing a solution can be lengthy. In contrast, DevOps practices, such as continuous integration and continuous delivery, enable rapid prototyping, development, testing and deployment of new features and updates.

    With the DevOps approach, developers and operations teams work together from the beginning of a project, collaborating closely to ensure that the software being developed is robust, reliable and meets the needs of the business. This cooperative approach, combined with automated testing and deployment processes, significantly reduces the time to market for new features and updates.

    Ensuring High-Quality, Reliable IoT Applications

    Another significant advantage of utilizing DevOps in IoT development is the increased quality and reliability of the applications being developed. With traditional software development methods, testing and quality assurance often occur after the development process. This can lead to issues being identified late in the cycle, which can be costly and time-consuming to fix.

    On the other hand, DevOps practices emphasize continuous testing throughout the development process. This means that issues can be identified and addressed much earlier, leading to higher-quality, more reliable software. In the context of IoT, where devices may be deployed in critical applications such as health care or transportation, the importance of this cannot be overstated.

    Enabling Scalability and Flexibility in IoT Systems

    Finally, DevOps plays a crucial role in enabling the scalability and flexibility of IoT systems. As the number of IoT devices continues to grow exponentially, the ability to manage and monitor these devices efficiently is becoming increasingly important. DevOps practices, such as infrastructure as code (IaC) and the use of containers and microservices, provide the tools necessary to scale and adapt IoT systems as needed.

    With IaC, the infrastructure required to run an IoT application is defined and managed as code, making it easy to replicate and scale. Containers and microservices, on the other hand, allow applications to be broken down into smaller, independent components that can be scaled individually, providing a high level of flexibility and efficiency.

    Implementing DevOps in IoT Development

    Integrating CI/CD in IoT Application Development

    Continuous integration/continuous delivery (CI/CD) is a fundamental DevOps practice that plays a vital role in IoT development. It involves automating the processes of software delivery and infrastructure changes. With CI, developers frequently merge their code changes into a central repository where automated builds and tests are run. CD takes this a step further by automating the release of these changes to the production environment.

    For IoT, integrating CI/CD can help maintain the quality of software, increase efficiency, and speed up the process of delivering software updates or new features to devices. It also ensures that any changes made can be easily rolled back, reducing the impact of any potential issues.

    Applying IaC for IoT Infrastructure Management

    Infrastructure-as-code (IaC) is another key DevOps practice that is highly relevant to IoT. IaC is the process of managing and provisioning computing infrastructure through machine-readable definition files rather than physical hardware configuration or interactive configuration tools.

    In the context of IoT, IaC can simplify the process of setting up and managing the complex infrastructure required for IoT applications. With IaC, developers can quickly and reliably replicate infrastructure setups, making it easier to scale IoT applications as the number of connected devices grows.

    Using Containers and Microservices in IoT Application Architecture

    Containers and microservices are two more DevOps practices that can significantly benefit IoT development. A container is a standalone executable package that includes everything needed to run an application, including the code, runtime, system tools, system libraries and settings. Microservices is an architectural style that structures an application as a collection of small, loosely coupled services.

    In the context of IoT, using containers and microservices can greatly simplify the process of developing, testing and deploying IoT applications. Moreover, they can enhance the scalability and flexibility of IoT systems, making it easier to adapt to changing requirements and scale as the number of connected devices grows.

    Challenges of Implementing DevOps for IoT and How to Overcome Them

    Dealing with Device and Platform Diversity

    One of the main challenges in implementing DevOps for IoT is dealing with the diversity of devices and platforms. IoT devices can range from simple sensors to complex machines, each with its own capabilities, requirements and operating systems. Moreover, these devices may communicate using different protocols and have different connectivity requirements.

    The key to addressing this diversity is to adopt a platform-agnostic approach. This involves developing software that can run on any device, regardless of its hardware or operating system. Containerization can help achieve this by providing a consistent and reproducible environment for running applications.

    Ensuring IoT Security and Privacy

    Security and privacy are significant concerns in IoT, and they can be particularly challenging in a DevOps context. The increased frequency of updates and changes that come with the DevOps approach can potentially introduce new vulnerabilities. Moreover, the interconnected nature of IoT devices means that a security breach can have far-reaching consequences.

    To address these challenges, it’s essential to integrate security practices into the DevOps process. This is often referred to as DevSecOps. This approach involves continuously monitoring and testing for security vulnerabilities throughout the development process rather than treating security as an afterthought.

    Managing IoT Data Volume and Complexity

    The sheer volume and complexity of data generated by IoT devices can also pose a challenge in a DevOps context. Traditional data management and analysis tools may not be able to handle this volume and complexity.

    To tackle this, it’s important to utilize modern data management solutions that can handle large volumes of data. Additionally, employing advanced analytics and machine learning techniques can help make sense of complex data and extract valuable insights.

    Coordinating IoT System Updates and Maintenance

    Finally, coordinating updates and maintenance for a large number of IoT devices can be a significant challenge. This is particularly true in a DevOps context, where updates and changes are frequent.

    To address this, it’s crucial to have a robust system for managing and tracking updates. Automated deployment tools can be invaluable in this regard, allowing updates to be pushed out to devices in a controlled and coordinated manner.

    Conclusion

    In conclusion, implementing DevOps in IoT development can bring significant benefits, including faster development cycles, higher-quality, reliable applications and improved scalability and flexibility. However, it also presents unique challenges that need to be effectively addressed. By understanding and properly implementing the principles and practices of DevOps, we can harness the full potential of IoT technology and drive forward innovation.

  • Adopting a Low-Code GraphQL Approach to Build a Core Data Platform

    Adopting a Low-Code GraphQL Approach to Build a Core Data Platform

    Our education platform has relied on an outdated monolithic legacy application for years. It’s an outdated system built of a single service layer on top of a database designed for use cases that have evolved over the last decade. But we’re using the wealth of data in the monolith as a foundation for our current projects, thanks to our newly adopted tools.

    With our product line continually expanding, our need for a centralized API that can sit over commonly used data has become even more critical. This includes data related to our customers’ organizational units, purchased products, licensing information, and student, teacher and class rosters, among other things.

    The stakes are high since we have multiple downstream clients depending on us. Our goal is to move some functionality and data out of the main system while making sure our design is flexible enough to adapt to future product changes. We envision a hub-and-spoke model where all our products interact through a central hub to access shared data. Efficiency, security and reliability are all top priorities. Because we’re a small team, we need to move fast and be open to new ideas. That’s why we’re using a low-code backend solution to minimize manual coding and maximize our productivity.

    A few months ago, we adopted a tool called Hasura. Its core value proposition is that it places a production-grade GraphQL API over any database, saving teams months of recurring effort in building, shipping and maintaining their APIs. We put the open source Hasura community edition to the test and found that it lived up to its claims. In this article, we’ll show you how it worked for us and how it can work for you too.

    Converting GraphQL to SQL

    Before a team can convert GraphQL to SQL, they must undergo a data modeling phase. After this data modeling phase, backend teams must complete some unavoidable tasks. One of these tasks is to build an API that allows clients to read and mutate data. Hasura provides this instantly, freeing engineers from the toil of writing basic CRUD APIs. Hasura compiles a GraphQL string into a GraphQL abstract syntax tree (AST), which is then compiled into a SQL AST. This abstraction lets us do powerful things, like using a bulk GraphQL mutation to transactionally and atomically insert or update data. GraphQL provides a flexible way for us to query our data in the form of a graph. This means that, as engineers, we get to focus more on business logic.

    API Federation, Aggregation and Composition

    Hasura’s support for remote GraphQL schemas enables us to design a service-oriented architecture in which Hasura functions as an API federation/composition layer and delegates to other Go microservices that provide specialized business logic for a particular domain. This ability to federate doesn’t just end at remote GraphQL schemas—Hasura also supports remote data sources, opening multiple possibilities for how we traverse through the graph and explore relationships in our data, including how we might join remote databases to each other or to remote APIs (REST or GraphQL).

    In greenfield projects, teams typically spend months crafting a fully-featured API, a common language that all clients can share. With Hasura, we get this in seconds and can spend that saved time writing automated tests or implementing business logic.

    Developer Dashboard

    Hasura’s Dashboard/Console improves developers’ experience. Using the dashboard, developers can craft experimental GraphQL queries and mutations against our local instance of Hasura. The embedded GraphQL playground makes it a breeze for new developers joining the team to introspect and discover our API. We can also visualize our database schema in the UI directly and make changes to it with a few clicks of a mouse (if needed), generating source-controlled SQL migration scripts like you’d find in other web frameworks.

    Observability

    No production-ready system would be complete without observability, or the ability to gauge a system’s internal state based on external output, usually in the form of logs, traces and metrics. Hasura ships logs and traces to our New Relic telemetry platform for each database operation, allowing our team to identify bottlenecks and receive early alerts of unexpected or degraded system performance.

    Authorization

    Hasura’s role-based authentication support allows us to check an additional box on our production-readiness checklist. Clients with certain roles may have permission to execute specific GraphQL API operations or access particular database tables. Hasura can derive a client’s role in one of two ways: Either the client will send Hasura a JWT auth header (which includes a signature containing claims providing the client’s role), or Hasura will refer to an external webhook which, in turn, makes the auth decision. Without Hasura, we would need to write and maintain the code to perform all of this work.

    Change Data Capture

    The last way Hasura enables us to build our core platform is through change data capture (CDC), or the process of tracking changes to a database. Hasura provides this in the form of event triggers, which function like a transactional outbox system. When a record is inserted, updated or deleted, a bona fide database trigger will record this event in a table. Then, a reliable process in Hasura will guarantee that the event is delivered at least once to its intended webhook (one of our microservices). This is tremendously useful for our team since we need to sync data from our new database to the older legacy database.

    There are many tools we could use for CDC, such as AWS SQS or Kafka (some of which we use downstream to integrate our platform with individual products), but having this feature baked into Hasura makes the process simpler, as it frees us from having to provision any new infrastructure or deal with the complexities of bringing on additional tools.

    Conclusion

    For the Teaching Strategies platform modernization team, we’re just getting started. As we continue to evolve and improve our product, we’re considering Hasura for finer-grained authorization, such as attribute-based access control (ABAC) over coarser role-based access control (RBAC). We will also investigate real-time streams so other systems, such as users’ browsers, can see data changes as fast as possible.

    Using the functionality and features of Hasura community edition outlined above, our team is well on the way to building a strong core platform. By leveraging this tool, we can meet our milestones faster and provide even more support for educators and caregivers, making their lives easier.

    Interestingly, Hasura is a combination of the programing language Haskell and the Sanskrit word asura—or demon.  As far as tech choices go, this one feels much more like a guardian angel.

  • JFrog Adds Curation Capability for Open Source Software Components

    JFrog Adds Curation Capability for Open Source Software Components

    JFrog today announced it is adding a curation capability for open source software to its portfolio that will use metadata generated by binaries to identify malicious packages and software components that have licensing issues.

    Sharan Hiremath, senior product manager for JFrog, said JFrog Curation is an extension of the JFrog Artifactory binary repository that the company provides to enable organizations to manage their software supply chains.

    JFrog Curation also validates software packages against JFrog’s Security Research library of recorded Critical Vulnerabilities and Exposures (CVEs) and publicly available information to help establish a trusted repository of pre-approved, third-party software components.

    That approach automatically employs the JFrog Xray scanning tool to eliminate the need to individually scan each package before developers employ them, said Hiremath.

    Making sure open source software components are secure is often problematic because developers download them from public repositories that are frequently targeted by cybercriminals. There have now been more than 100,000 instances of malicious software packages discovered in repositories in the last year alone, noted Hiremath.

    In addition, cybercriminals have become adept at creating fake repositories that mimic legitimate repositories; that can result in developers downloading software components infected with malware.

    JFrog Curation takes the shift left concept of application security to the next level by automatically blocking the use of risky open source software packages, noted Hiremath. The JFrog platform will also surface advice on how to remediate any vulnerability discovered, in addition to creating an audit trail to enable organizations to comply with various regulatory mandates.

    While open source software components reduce the cost of application development, from a cybersecurity perspective, it’s the wild, wild West, noted Hiremath. Organizations are trying to bring more discipline to the way software is constructed by adopting DevSecOps best practices, but they need an approach that doesn’t introduce any additional friction into the application development process, he added.

    JFrog Curation addresses that issue by addressing cybersecurity and compliance issues before any open source component becomes part of the build, said Hiremath.

    As regulations to hold organizations more accountable for the security of the software they deploy are being proposed around the world, it’s only a matter of time before organizations must revisit the security of their software supply chains. Cybercriminals have already proven how adept they are at injecting malware into software components that could be used in thousands of downstream applications. In the eyes of regulators, organizations that don’t scan open source software for malware and vulnerabilities are engaging in reckless behavior that will warrant stiff penalties.

    The challenge is that, after giving developers free rein to develop software any way they see fit, organizations are now faced with a challenge that is as much cultural as it is technical. Automated processes will naturally play a key role in curbing aberrant behavior in application development, but there is, as always, no substitute for some good old-fashioned common sense.

  • BigPanda Extends AIOps Platform to Embrace Generative AI

    BigPanda Extends AIOps Platform to Embrace Generative AI

    BigPanda today added generative artificial intelligence (AI) capabilities to analyze incidents surfaced by its AI for IT operations (AIOps) platform.

    Blair Sibille, field CTO for BigPanda, said Generative AI for Automated Incident Analysis leverages generative AI platforms based on the general-purpose large language models (LLMs) created by OpenAI.

    The goal is to make it simpler for IT teams to discern the root cause of an issue by, for example, taking advantage of summaries of alerts enabled by generative AI to make it simpler for IT professionals of any skill level to understand what requires their most immediate attention, he added. Today, insights are lost in the sea of alerts that often inundate IT teams, Sibille noted.

    BigPanda has been at the forefront of applying machine learning algorithms to automate IT operations management. Now, the company is incorporating external general-purpose LLMs to further augment IT teams, said Sibille.

    As IT environments continue to be more complex, it’s becoming essentially impossible for IT teams to manage them at scale without relying more on automation. AI technologies take automation to another level, but they won’t eliminate the need for DevOps teams to manage IT environments, added Sibille.

    BigPanda claimed generative AI capabilities will make it possible to reduce the amount of time required to resolve tickets by seven minutes each, with an accuracy rate of 95% during beta testing. Over time, those capabilities not only reduce mean-time-to-resolution but also reduce the level of toil that often conspires to burn out DevOps teams, said Sibille.

    At the core of the BigPanda AIOps platform is a data lake capable of consuming data generated by multiple applications and systems. That data then provides the foundation on which machine learning algorithms are applied to surface insights.

    It’s not clear how much generative AI will automate DevOps workflows, but in effect, more IT teams will be able to take advantage of having the equivalent of a DevOps engineer that they can query any time an issue arises using natural language, noted Sibille.

    AI doesn’t mean that IT outages will be completely eliminated, but it does mean they will become a lot less stressful, he added.

    Naturally, there’s a lot of speculation concerning the impact AI will have on DevOps. Some contend it’s only a matter of time before the entire software engineering process is automated. As those advances are made, the cost of building applications will effectively drop to zero. Others argue that AI will simply augment DevOps teams in a way that makes it simpler to manage IT at scale using either the same number or possibly even fewer engineers.

    The one thing that is clear is that AI will soon be pervasive. DevOps teams should start evaluating today which tasks will be automated with an eye toward planning how DevOps roles will evolve as AI advances accelerate.

  • How to Keep Your IT Infrastructure Invisible

    How to Keep Your IT Infrastructure Invisible

    IT infrastructure is critical. IT infrastructure enables businesses to run—from day-to-day operational execution to visionary strategic innovation and everything in between. What’s interesting, though, is that people are only aware of it when there’s a problem: HR can’t access the payroll application, customers are complaining about how slow the transactional system is or this month’s cloud bill was double what you expected it to be.

    No one should notice a well-orchestrated environment, but once application performance slows or an outage occurs, people start to grumble. The same is true for IT infrastructure.

    The Top Four Ways Your IT Infrastructure Can Become Undesirably Visible

    Given the complexity of modern hybrid/multi-cloud environments and the applications they support, it’s no surprise that countless things can go wrong—and when they do, your IT team takes the flack.

    If your infrastructure is humming along nicely, that’s a testament to the IT infrastructure team’s hard work and expertise. Sadly, they don’t get the recognition because it’s all invisible to the rest of the organization. It’s only when *BAM!* something happens that the team is scrutinized.

    While there are many ways this can manifest, it usually falls under one of the following four categories:

    • Availability — This may be the most catastrophic because when systems are unavailable, people can’t do whatever it is they need to do.
    • Performance — A system might be available, but that doesn’t mean it’s performing to SLA or user expectations. The result can range from minor annoyance to lost revenue and customer churn.
    • Cost — Runaway expenditures don’t necessarily affect users, but you do not want to be called to account by the finance team or, worse, executive leadership.
    • Compliance — This is another area that may not have a broad impact on user experience, but the repercussions of non-compliance can be financially and reputationally significant.

    Common Infrastructure Culprits and How to Address Them

    To ensure the necessary availability, performance, cost control and compliance to keep your IT infrastructure under the radar, you must understand what can cause problems in these areas. Here are eight common culprits, along with ways you can address them, so your IT team stays invisible.

    Broken or Misunderstood Dependencies
    Your infrastructure is a complex web of interdependent applications and services. Every time you make a change, it could have a rippling effect on the categories mentioned above. Automated discovery and service mapping capabilities enable you to easily trace dependencies throughout your infrastructure to avoid unintended consequences.

    Cloud Waste
    Chances are very high that you’ve got cloud waste. This means that you could be getting billed for a storage block that’s attached to a stopped instance, for compute instances that are not being used, or for unattached load balancers. Finding idle and abandoned resources can keep your monthly cloud bill under control and on budget.

    Un-Breakdownable Cloud Costs
    Cloud bills are notoriously complex, and while cloud providers do offer tools to help you analyze your cloud spend, those tools often don’t answer all the questions your business might have. In addition to adding clarity to such opaque expenses, you need to be able to parse your cloud spend based on what makes business sense to your organization, not what makes technical sense to your cloud provider.

    Poor Capacity Planning
    Your infrastructure needs to meet your business needs, which are continuously evolving. As changes happen, whether it’s increased utilization of existing resources or modified/added resources to support new requirements, workloads could push current capacity and impact performance and stability. You need to be able to forecast infrastructure demands against business objectives to minimize potential issues before they happen.

    Poor Workload Placement Decisions
    Your infrastructure consists of various environments each with its own characteristics. If you migrate a workload without understanding the implications of that particular environment, you could risk performance problems or spiking costs. To prevent this, you need any-to-any migration insights to make better decisions about workload priorities, groups and deployments.

    Poor Reservation Planning
    Reservations (i.e., reserved instances or programmatic discounts) offer discounts for committing to a particular plan. If you plan well, the savings can be significant. But if you don’t use the capacity you’ve bought, the savings might not materialize. To improve cloud resource planning, you need to be able to evaluate your potential savings in varied scenarios.

    Workload Drift
    Over time, your workloads evolve due to changing demand, data volumes, etc. As a result, they can outgrow their current configurations, leading to performance issues or rising costs. This is a natural result of business growth, so the goal isn’t to prevent that drift. Instead, you want to optimize capacity and cost on an ongoing basis to keep your workloads right-sized.

    Slow Problem Troubleshooting and Remediation
    No matter how many precautions you take, something somewhere will inevitably go wrong. And once you become aware of the situation, the clock starts ticking to find the cause and fix it, all of which takes time. The longer the entire process takes, the longer your infrastructure will be visibly and painfully not working as expected. For those cases, you need full-stack visibility with application-centric, AI-based analytics to minimize impact duration as much as possible.

    Keeping the engine running behind the curtain can be a daunting task, but with proper planning and management, your IT team will remain visible to those responsible for managing it and invisible to those in the rest of the organization. Of course, the complexity of today’s cloud infrastructure makes that challenging, and there will be IT fire drills that take place, but it’s about how IT leaders react to the situation and resolve it in the quickest way possible, allowing themselves to return to their preferred place in the shadows.