Category: Enterprise DevOps

  • AI ‘is Getting Worse’ ¦ AI ‘Will Lose India Jobs’ (Probably Isn’t ¦ Probably Won’t)

    AI ‘is Getting Worse’ ¦ AI ‘Will Lose India Jobs’ (Probably Isn’t ¦ Probably Won’t)

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week, a conundrum: On the one hand, researchers say ChatGPT is losing the plot; and on the other, we hear outsourced coding jobs in India will be replaced by AI. (more…)

  • Google Announces Availability of iPaaS Service

    Google Announces Availability of iPaaS Service

    Google today made available an integration platform-as-a-service (iPaaS) capable of invoking a range of methods to integrate applications.

    Initially developed for the Apigee application programming interface (API) management platform Google acquired in 2016, the Application Integration service can now, for example, also consume a publish and subscribe event or an event driven through a Salesforce platform.

    Amit Zavery, vice president and general manager for Google Platform, said the Application Integration service provides IT organizations with all the benefits of an iPaaS without requiring them to stand up and manage an integration platform themselves.

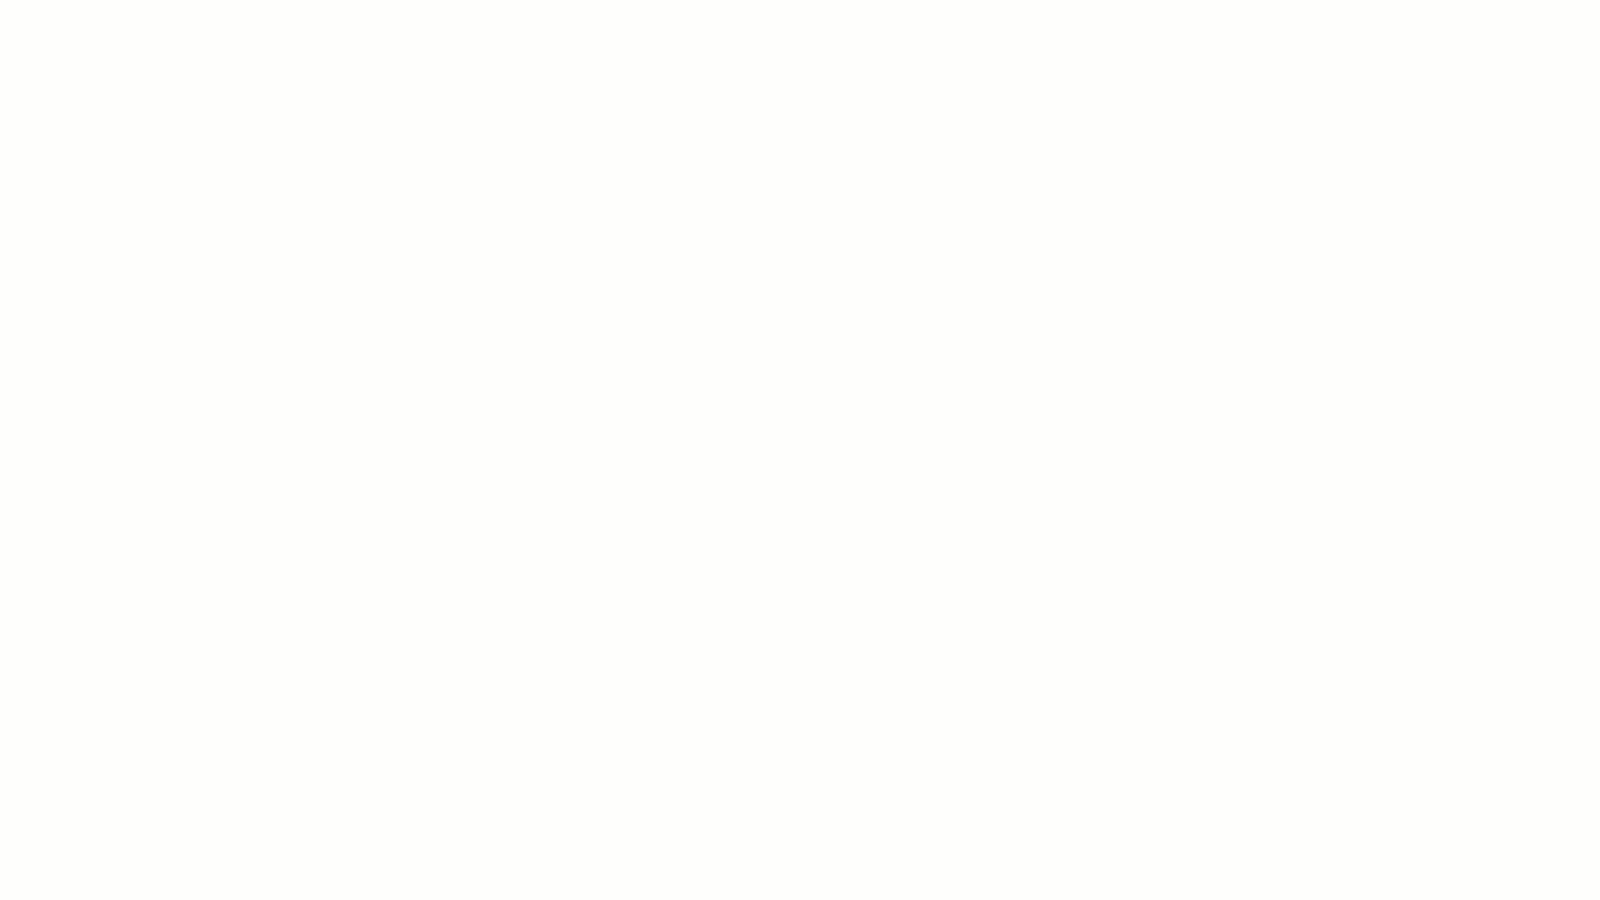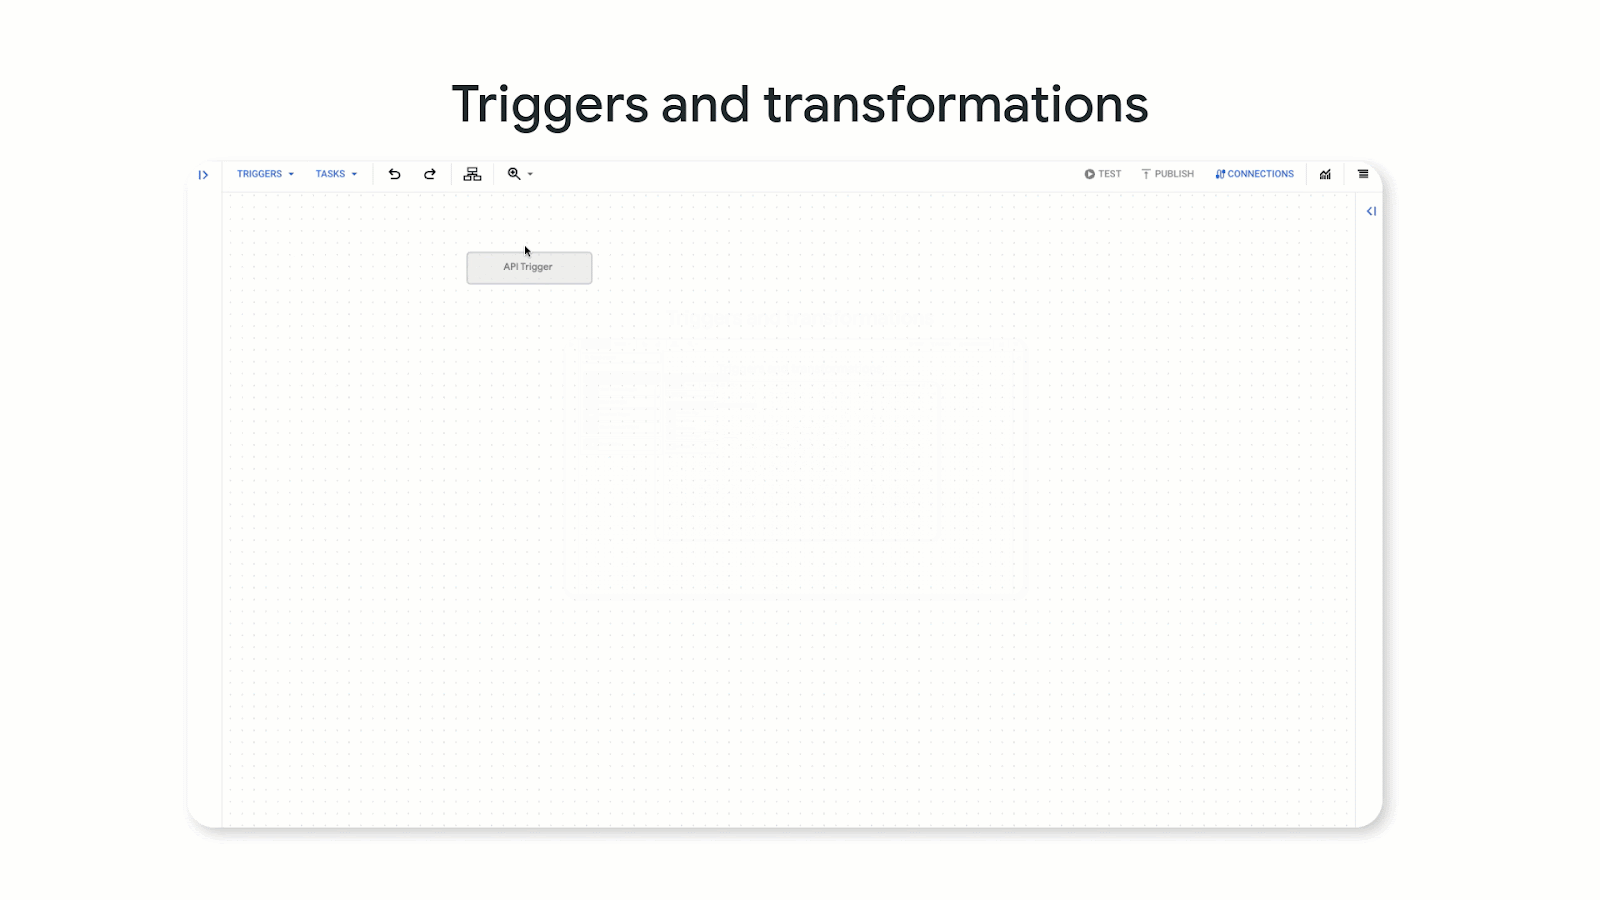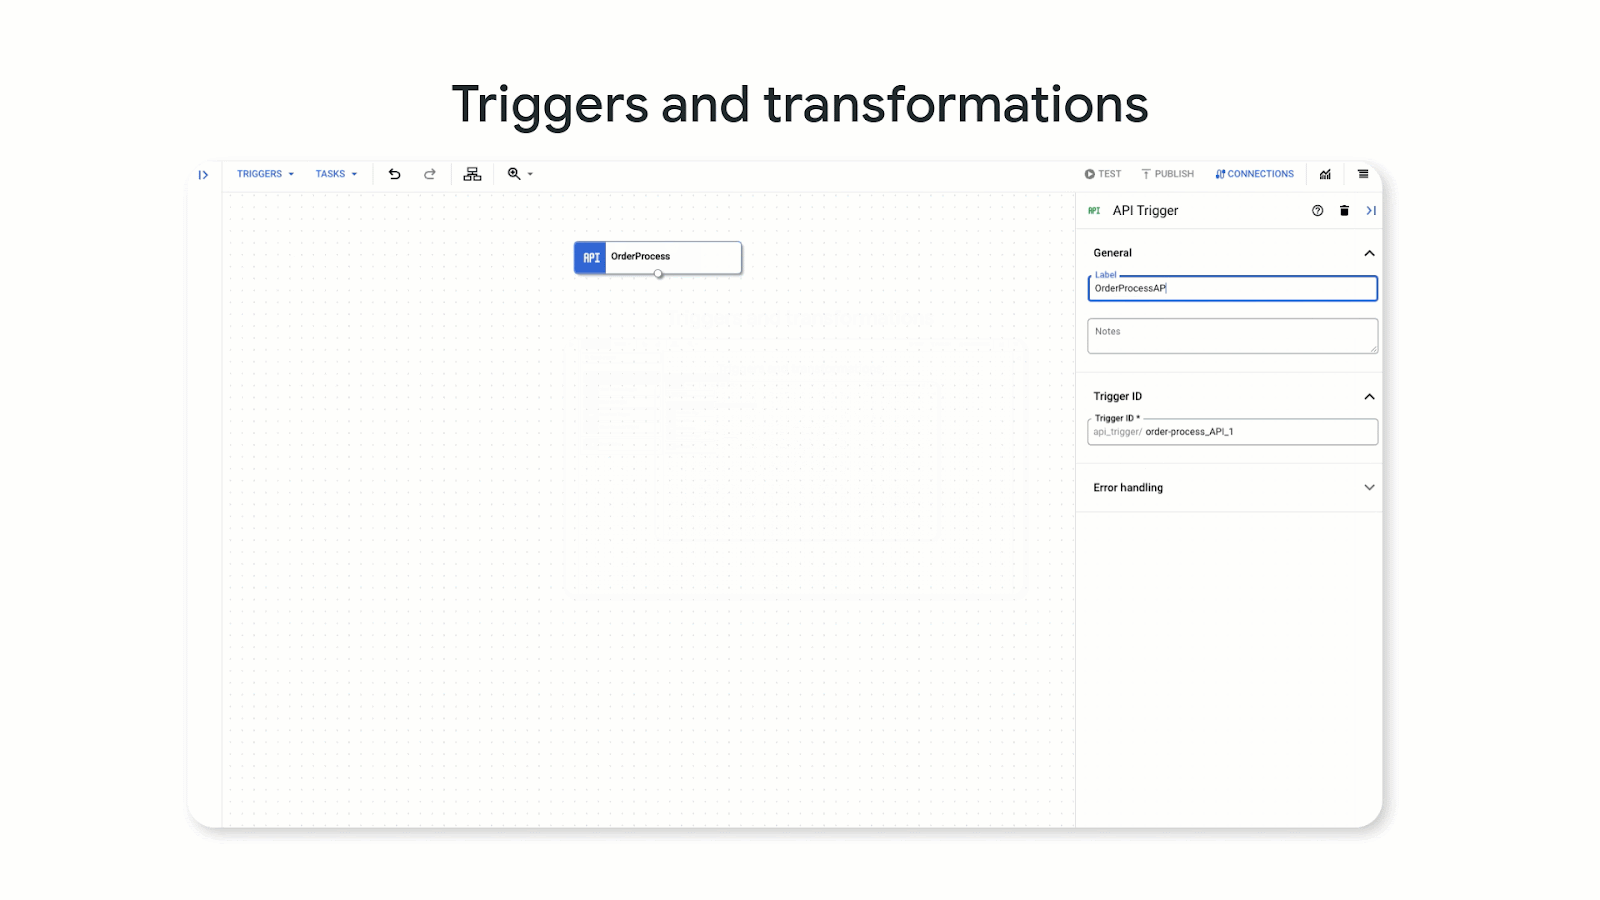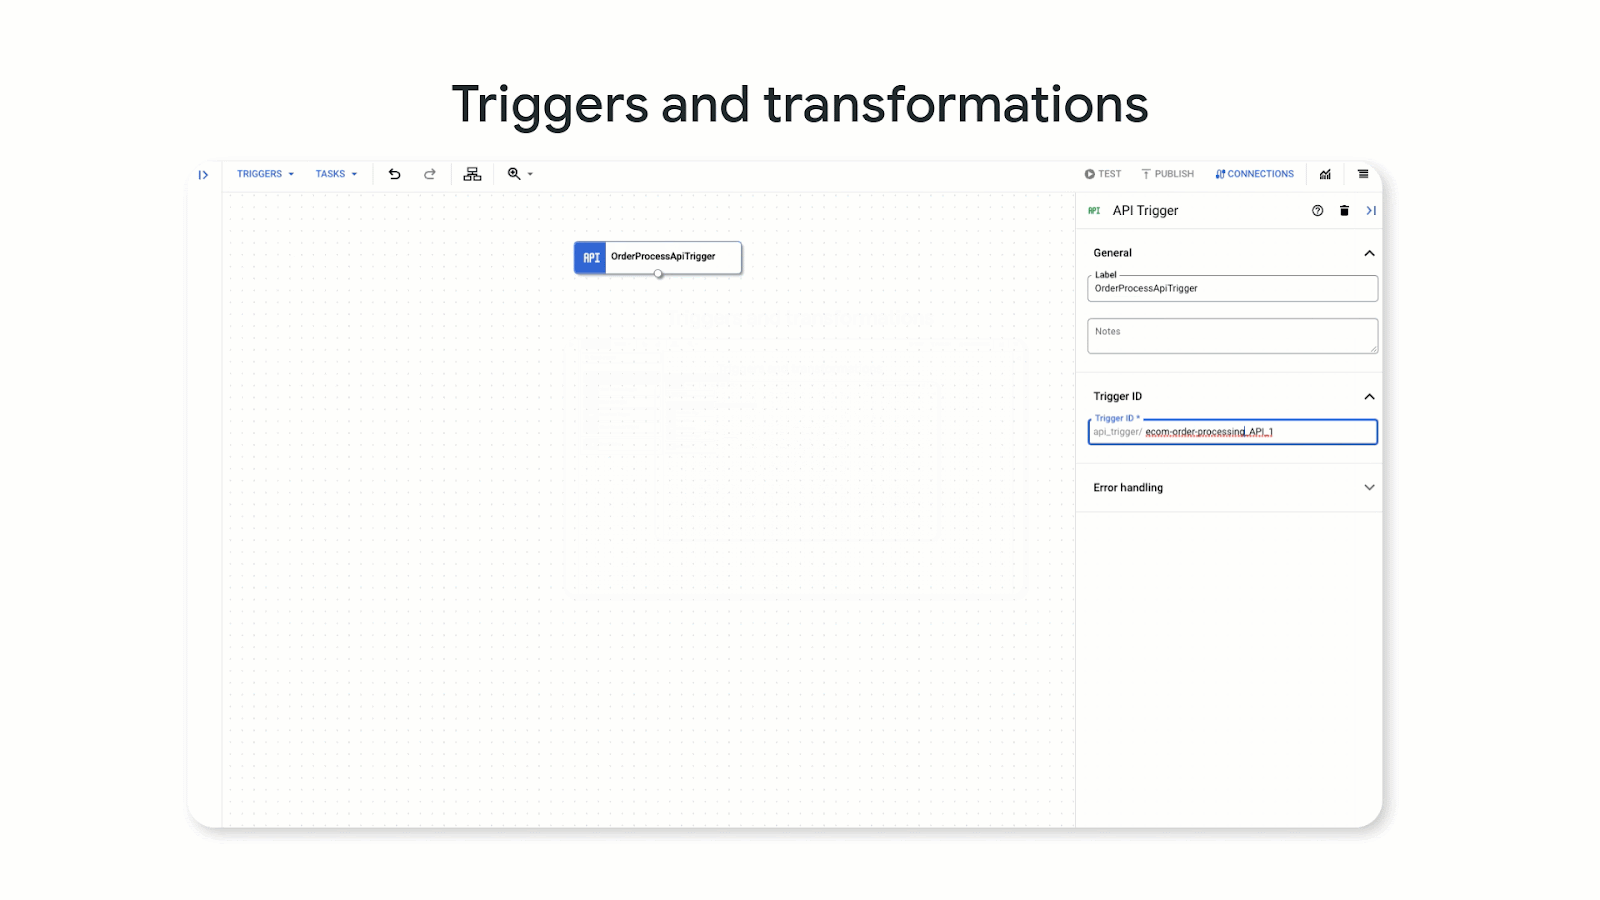
    The Google Application Integration service also provides access to a Visual Integration Designer tool that can be used to build workflows using a low-code tool. In total, there are now more than 75 connectors that can be used to integrate multiple Google Cloud services and third-party platforms that can run in either a cloud or on-premises IT environment, said Zavery.

    In general, visual tools are transforming how integrations are created and expanded within organizations, noted Zavery. Rather than using lower-level procedural code, a visual tool enables developers to employ low-code to create integrations. That makes it simpler to collaborate with business users that can now more easily participate in developing workflows.

    In fact, in some cases, business users, otherwise known as citizen developers, have enough technical acumen to create their own workflows using low-code tools.

    There are, naturally, going to be plenty of complex integration challenges that will require procedural code, but the bulk of the integrations required today are not especially complex.

    Regardless of who creates the integration, the number of them being employed across an enterprise organization continues to increase as more digital business transformation initiatives are launched. Developers are not going to be able to keep pace with the demand for those integrations if they rely solely on procedural code. The only way to effectively reduce the backlog for integrations is to rely more on visual tools to construct them. In most cases, the integration being created is relatively trivial. The only reason it wasn’t created sooner is there are not enough developers available to complete that task using procedural code.

    There are, of course, no shortage of iPaaS options available. As more workloads are deployed in the cloud, Google is betting the center of gravity for integration will shift toward the places where modern microservices-based workloads are deployed to reduce overall latency.

    It’s not clear whether organizations still view integration as an afterthought versus employing an integration platform around which all applications revolve. That latter approach tends to reduce the total cost of integration when compared to using multiple point products that are not managed via single framework, noted Zavery.

    Ultimately, IT teams that adopt an iPaaS are able to focus more on higher-value IT tasks. The issue is determining which integration projects really require professional developers with lots of integration expertise and which, via a low-code tool, can be handled by almost any developer.

  • Defining ‘Best’

    Defining ‘Best’

    (Note: For the last few years, I’ve been sparse with naming vendors in blogs. This one will have more than usual as examples.)

    We all have a ton of tools at our disposal. From installed tools to products to open source, we can solve any given problem in fifteen different ways. Several years ago, I wrote a blog about using what you have to get the most out of your purchases. There are several “platforms” that solve a lot more problems than just what you are currently using them for. At the time, my shining example was F5’s BIG-IP. That thing can do everything: Networking in your data center and probably cooking your breakfast, too. At the time, most people used the box to handle load balancing but then were concerned about the cost. Duh? I mean, you have a tool that can solve a fistful of problems … and you’re using it for load balancing. I mean, it’s very good at load balancing, don’t get me wrong. But I feel like quoting Marvin from The Hitchhiker’s Guide to the Galaxy. “Here I am with a brain the size of a planet and they ask me to pick up a piece of paper. Call that job satisfaction? I don’t.” (Interestingly, at the rate that generative AI is advancing, it is only a question of time before a machine throws that quote out there.)

    The thing is, investors and the hype machine told all of your vendors three things. First, that they needed a recurring revenue stream. Second, that you wanted everything as-a-service and third, that they needed to be a platform. That means that those fifteen SaaS products you’re on the hook for now want to solve all of your problems because “they’re a platform.” Some of them do a kick-arse job of it and you might very well have a SaaS license that covers whatever you need to do today.

    This is screamingly obvious for some vendors. If you’re an Akamai customer, for example, the breadth of things you can do through them is stunning. Most customers do not seem to take advantage of that to the extent they should. This is no different than that BIG-IP in your DC; it’s just as-a-service. You’re already paying for both. You should make the most of them.

    Other vendors might surprise you but  they have done the same through M&A or expanding their “platform” from marketware to reality. I have hinted at this in the not-too-distant past but will say it point-blank here. Know what your products are capable of. Tomorrow you might need some of that functionality, and knowing if it’s already in the organization (but not being used) is a big deal. Also, if the “platform” already fits into your organization, then choosing a ‘best’ solution leans toward that product line already–less integration is the best integration.

    And keep those lights on. You may have more tools than you need, but you’re managing them and keeping the organization online. You should be getting kudos for that, so I’ll offer them. Thank you. I replaced my phone this weekend and had to reconnect everything and to all of those orgs I had to log back into, reinstall or reconfigure, let me say: I am grateful for each IT person there. Even my bank, who honestly pisses me off—I’m still grateful for their IT.


  • The Role of AI in ITSM: SLAs, SLOs, SLIs and Error Budgets

    The Role of AI in ITSM: SLAs, SLOs, SLIs and Error Budgets

    In my recent blog Revolutionizing the Nine Pillars of SRE with AI-Engineered Tools, I classified SRE into nine pillars of SRE practices, a comprehensive framework that covers the full scope of SRE practices and suggested how AI can help with each of the pillars.

    For SLAs, SLOs, SLIs and error budgets—arguably the most important pillar of SRE—I indicated that AI can assist by providing accurate predictions of system performance and identifying potential bottlenecks. In this blog, I’ll explain in more detail how AI-engineered tools can be used to improve SLAs, SLOs, SLIs, error budgets and error budget policies within IT service management (ITSM).

    AI for SLAs, SLOs, SLIs, Error Budgets and Error Budget Policies

    Service Level Agreements (SLAs): An SLA is a contract between a service provider and the end user. It outlines the metrics by which the service is measured as well as remedies and penalties if agreed-upon service levels are not achieved. Setting the right SLAs is crucial, as they directly impact on customer satisfaction and the service provider’s reputation.

    The challenges in defining SLAs often involve understanding the trade-off between the cost of providing the service and the level of service that customers expect. AI can assist in this process by providing data-driven insights to inform these decisions. By analyzing historical performance data, customer usage patterns and feedback, AI models can predict the impact of different service levels on both customer satisfaction and operational costs. This can help service providers to set SLAs that meet customer expectations without unnecessarily inflating costs.

    AI can also be used to proactively monitor the agreed-upon SLAs. By continuously analyzing performance data, AI tools can detect potential SLA breaches before they occur, allowing the service provider to take preventative action. This kind of proactive SLA management can help to improve customer satisfaction and reduce the risk of penalties for SLA breaches.

    Service Level Objectives (SLOs): Establishing SLOs involves making informed predictions about system performance, defining realistic yet challenging targets that align with user expectations and business goals. A common challenge in defining SLOs is dealing with the complex nature of distributed systems and their interdependencies, making it difficult to predict performance and set appropriate targets. AI can assist in this process by analyzing historical data to model system behavior and predict future performance trends. This allows SRE teams to set more accurate, data-informed SLOs that reflect the system’s true capabilities. For instance, machine learning models could identify patterns in traffic and use this information to predict periods of high demand, allowing SRE teams to define SLOs that account for these peaks.

    Service Level Indicators (SLIs): SLIs are quantitative measures of some aspect of the level of service such as latency, throughput, availability, error rates, etc. The challenge lies in identifying the right metrics that accurately reflect the user’s experience and the system’s health. Traditionally, these decisions are based on domain knowledge, experience, and sometimes trial and error. AI can assist by analyzing a broad range of metrics across the system, correlating them with issues, incidents and user satisfaction levels to identify which indicators provide the most meaningful measure of service quality. By doing so, AI can help teams select the most appropriate SLIs, thus providing a more accurate picture of their system’s health and performance.

    Error Budgets: An error budget represents the acceptable level of risk or unreliability in a service, providing a balance between reliability and the pace of innovation. Determining an appropriate error budget involves an understanding of system behavior, user tolerance for errors, and business needs. The challenge lies in predicting future performance and understanding the likely impact of potential issues. AI can help overcome these challenges by simulating different scenarios and predicting their impact on the error budget. Machine learning algorithms can learn from past incidents and understand the correlations between different factors, helping teams predict future performance, establish an appropriate error budget, and make better-informed risk decisions.

    Error Budget Policies: These are policies that dictate actions based on the remaining error budget. These decisions often involve human judgment, like deciding when to freeze releases due to an exceeded error budget or when to allow more risk for a new feature rollout. AI can support these decisions by using predictive models to estimate the likely impact of different actions on the error budget. For example, it could simulate the impact of a new release on system reliability, providing insights to help decide whether to proceed with the release or hold it back. By doing so, AI can help teams manage their error budgets more effectively and make more data-driven decisions.

    Implementation Roadmap

    Implementing AI tools for SLAs, SLOs, SLIs, error budgets, and error budget policies must be well-planned and executed systematically. Here’s a practical implementation roadmap:

    Assess the Current Situation: Start by examining the current situation, identifying the areas of need and understanding the existing process of how SLAs, SLOs, SLIs and error budgets are being managed. Also, evaluate the data you currently have available and its quality because AI tools rely heavily on data.

    Define the Goals: Clearly outline what you hope to achieve with the implementation of AI tools. This could include better prediction of system performance, quicker identification of potential bottlenecks, more effective allocation of error budgets, etc.

    Select the Right Tools: Research and select suitable AI tools. Examples of AI-engineered tools that could be useful include:

    • Nobl9 for SLO management: It can assist with setting, monitoring and managing SLOs with AI-driven predictions.
    • Dynatrace: This tool uses AI to detect and diagnose system anomalies, improving observability and helping to inform SLOs and error budgets.
    • Datadog: Offers machine learning-based features that can help forecast future infrastructure metrics, contributing to better SLA and SLO management.
    • New Relic: Its applied intelligence feature can help with incident detection and resolution, helping to better manage error budgets.

    Data Preparation: Aggregate data from various sources, clean it and possibly format it in a way that’s suitable for the AI tools.

    Integration and Deployment: Integrate the AI tools with your existing systems to ensure that the AI tools can effectively communicate with your existing systems.

    Training and Calibration: Many AI tools require a period of training and calibration where the tool learns from your data to make accurate predictions and recommendations.

    Monitoring and Evaluation: Once the AI tools are in place, continuously monitor their performance.

    Iterate and Improve: Based on the evaluations, make necessary adjustments to the tools, your data or your goals.

    Training the Team: They need to understand how to interpret the results and how to take action based on the recommendations of these tools.

    Summary

    In the complex landscape of ITSM, AI is emerging as a transformative force, enabling organizations to manage their systems with unprecedented precision and proactivity. Through smart analysis of historical data and predictive modeling, AI tools are elevating how we define and handle SLAs, SLOs and SLIs. Gone are the days of generic, one-size-fits-all service-level targets. Today, AI empowers us to set realistic, data-informed goals that accurately reflect a system’s capabilities and align with user expectations, ensuring high customer satisfaction and operational efficiency.

    Furthermore, AI brings remarkable improvement to the management of Error Budgets and Error Budget Policies. By simulating different scenarios and predicting their impact, AI helps teams proactively manage risk, making well-informed decisions about error allowance and guiding actions when error budgets are threatened. AI enables us to strike the perfect balance between reliability and innovation, allowing IT teams to continue pushing boundaries without compromising service quality. As the era of AI in IT service management dawns, we stand on the cusp of a new phase of efficiency, control, and excellence in system management. So, join us as we delve deeper into this fascinating intersection of AI and SRE practices.

  • Forking RHEL! Oracle and SUSE Join the Fight ¦ Silverman Sues AI Firms

    Forking RHEL! Oracle and SUSE Join the Fight ¦ Silverman Sues AI Firms

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: SUSE announces a Red Hat Enterprise Linux fork after Oracle said a similar thing, and Sarah Silverman says OpenAI and Meta have stolen her words. (more…)

  • Are LLMs Leading DevOps Into a Tech Debt Trap?

    Are LLMs Leading DevOps Into a Tech Debt Trap?

    Everyone thought AI would free us from toil. Unfortunately, that’s not true. What it will do, however, is lead to an explosion of technical debt. Some of the most alluring uses of LLMs have the potential to lead to some of the worst outcomes for enterprises and their DevOps and platform engineering teams.

    SK Ventures and Adrian Cockcroft raised the alarm bells in their warning posts about the tipping points LLM introduced into work and society. And in my own Gluecon 2023 presentation, I challenged just how powerful and disruptive the new generation of AI/ML will be for ITOps and DevOps efforts.

    Working Faster is not Working Smarter

    There is no doubt that LLMs are powerful and will change how we think about expertise and knowledge work.  While they are not truly innovating, their ability to draw on such a vast pool of human expertise makes it difficult to distinguish from true creative work. Since they are unbounded, they will cheerfully use the knowledge to churn out terabytes of functionally correct but bespoke code.

    It’s easy to imagine a future where LLMs crank out DevOps scripts 10x faster. We will be supercharging our ability to produce complex, untested automation at a pace never seen before! On the surface, this seems like a huge productivity boost because we (mistakenly) see our job as focused on producing scripts instead of working systems.

    But we already have an overabundance of duplicated and difficult-to-support automation. This ever-expanding surface of technical debt is one of the major reasons that ITOps teams are mired in complexity and are forever underwater. Generating even more scripts, even if they were better written, does not reverse the trend.

    Can AI/ML Avoid This Technical Debt Trap?

    It depends on how we use the expertise in the models. Instead of asking it to generate new code, we could ask it to interpret and modify existing code. For the first time, we have tools to take down the “not invented here” barriers we’ve created because of the high cognitive load of understanding code. If we can help people work more effectively with existing code, then we can actually converge and reuse our systems. By helping us expand and operate within our working systems base, LLMs could actually help us maintain less code.

    Imagine if the teams in your organization were invested in collaborating around shared systems! We haven’t done this well today because it takes significantly more time and effort. Today, LLMs have thrown out those calculations.

    Taking this just one more step, we can see how improved reuse paves the way for reduction of the number of architectural patterns. If we improve our collaboration and investment in sharing code, then there is increased ROI in making shared patterns and platforms work. I see that as a tremendous opportunity for LLMs to improve operations in a meaningful way.

    It comes down to whether we ignore complexity by replacing it or embrace complexity by understanding it. I see this as a choice between independence or collaboration, as illustrated by the table below.

    LLM Driving Independence

    LLM Driving Collaboration

    Create new code

    Interpret existing code

    Replace existing code

    Maintain existing code

    Design new architectures

    Be a guide and mentor

    Build new stacks

    Evaluate alternatives

    Bypass documentation

    Improve documentation

    Can AI Help us Collaborate?

    We keep taking the same hardware and software components and then building unique systems. That variation makes it impossible to leverage each other’s work. At its heart, the reusability problem lies in the difficulty of understanding systems, and that makes it nearly impossible for us to work together, collaborate, reuse and accelerate.

    Breaking this cycle has been our mission at RackN for nearly a decade. We’ve seen tremendous ROI from availability, reliability and speed when customers are able to leverage standardized infrastructure pipelines. We’ve seen firsthand that it is possible to guide teams into collaboration with sufficient guidance, mentoring and training. Collaboration creates 10x outcomes even without AI, but it takes building expertise, deliberate effort and leadership discipline to implement.

    Why does collaboration create 10x ROI?  It works because true innovation actually comes from understanding and building on top of systems rather than rebuilding them from scratch over and over again. The key is being able to leverage LLMs to better understand existing automation and platforms instead of creating yet another bespoke stack.

    Enterprises Should use LLMs to Drive Collaboration

    I believe that the most effective enterprises will use these tools to elevate their IT leaders and architects to focus on collaboration and reuse. They must actually direct them to produce less bespoke automation; instead, they can use expertise in these tools to find and maintain existing systems. LLM presents options, but collaboration requires new thinking and strong leadership.

  • Monitor Toolchain Health, Too

    Monitor Toolchain Health, Too

    A funny thing happened on the way to being agile. We adopted a ton of tools to make us more responsive. They really do help us deliver software quickly and efficiently, and they have improved IT processes along with our specific process improvements.

    They also created a toolchain that resembles areas of responsibility of old. That makes perfect sense; we still need to store source code, build applications, deploy somewhere, worry about security, etc. And we need to do all of that faster, which is where automation and the toolchain really shine.

    But you need to keep in mind the overall impact of the toolchain upon the development process. Now the organization is dependent upon those tools. We went from slow and steady to fast and with a large series of steps along the toolchain. Things are better, we’re delivering quality software at a faster pace, but in some ways, the process risks becoming more fragile. If a tool in the chain shows signs of trouble, you need to be aware of it and on top of the issue almost immediately. The price of ignoring issues in the process can be catastrophic disruptions in software delivery. Losing a CI tool is akin to shutting down customs at an international airport: The source of the problem is big, and the downstream problems are show-stopping.

    So while you are tooling your applications, make certain you are tooling the build chain, also. Know when a build that always takes ten minutes suddenly spikes to triple that. Know when a test suite delivers non-breaking errors at an increased rate. Know when space is low on a shared drive that the build tools use. Tool everything, because the software delivery toolchain is now the core of application development and deployment.

    Tooling these systems can also offer a warning of problems in a given application. It is possible that the increase in build time is because there are a lot of previously unused libraries being included … and that those libraries have not been properly vetted by security. It is possible that the disk space on that shared drive has PII test data that needs to be cleansed. There is a lot of good that can come from over-tooling the build chain, and unless you have a bit of tooling that slows the process, there is no downside. It won’t take too long to build a list of what to watch, and modern DevOps tools have enough reporting and APIs that it won’t take long to begin watching those items, either.

    That is where the people part comes in. Don’t ignore the tooling once it is in place. Build a process to regularly review results and take action when necessary. No tooling is useful if the results are ignored; sadly, we have a long history of spectacular failures that started with, “We saw indications, but didn’t think it was important at the time …” So act on results, even if that just means flagging them for review in the next reporting cycle—just don’t ignore them.

    And keep rocking it. The organization thrives on the software you build, deploy and support. It is a massively complex system that has IT staff at its heart, so keep it thriving and watch for indicators of illness in the core toolchain.

  • Key Insights From the Stack Overflow 2023 Developer Survey

    Key Insights From the Stack Overflow 2023 Developer Survey

    Stack Overflow has released its seminal yearly developer survey. The 2023 report, which surveyed over 90,000 developers, provides a comprehensive view of the current software developer experience.

    Below, I’ll highlight a few important findings, namely the significant programming language and tooling preferences, the use of AI in the development workflow and what these trends could mean for the DevOps field. I also gathered insights from Joy Liuzzo, vice president of product marketing at Stack Overflow, to dive deeper into some of the findings.

    Developer Technology Preferences in 2023

    Of note is that more and more developers are learning to code online. Learning to code using online resources increased from 70% in 2022 to 80% in 2023. Although many developers (47%) still have a Bachelor’s degree in computer science or the equivalent, these trends underscore the movement toward alternative knowledge solutions, especially for younger programmers. The topmost online resources include technical documentation, blogs, forums and how-to videos.

    JavaScript is still king—it’s now in its eleventh year as the most common programming language. But it’s worth highlighting that Python has overtaken SQL as the third top language. “SQL was solidly in the top three (JavaScript, HTML/CSS, SQL) since 2015, so it’s a big deal for it to have fallen below Python,” said Liuzzo. “We’ve seen Python’s popularity increase based on the number of questions asked on our public site, so we’ve been expecting some shifts.”

    TypeScript and Bash/Shell have also consistently grown in usage over the last few years. “These two languages are involved with the functions of other popular programming languages, explaining their prevalence among programmers,” Liuzzo said.

    PostgreSQL also overtook MySQL as the most common database type. In terms of web frameworks, Node.js and React.js are the most dominant. Other frameworks, like jQuery and ASP.NET, are showing signs of going out of style, likely because they are older web frameworks.

    Spotlight on AI

    The explosion of new AI innovations, such as large language models (LLMs) and chat-driven generative AI tools, had a major impact on this year’s technology findings. In fact, 83% of respondents have used ChatGPT over the past year. This is followed by Bing AI (20.6%), WolframAlpha (13.36%) and Google Bard AI (9.86%). GitHub Copilot was ranked as the top most-used AI developer tool.

    There was a significant spike in using AI tools amongst those learning to code—these folks often see benefits like speeding up learning, increasing productivity and greater efficiency. “Pair this with how they are currently using AI tools to debug and get help (68%) and learn about a codebase (50%), and we see that the commonality is that AI tools enable learning,” explained Liuzzo.

    That being said, there’s skepticism around AI’s accuracy, and only 13% see improved accuracy in coding as a benefit of using such tools. These pain points may resolve as LLMs evolve, but for now, there still needs to be human judgment to catch bugs and avoid hallucinations.

    “AI has a complexity cliff. Much like Helmsman’s complexity cliff found in project management, after a certain point, the ability for AI to handle all the nuances and interdependencies of a solution drops off,” said Liuzzo. “That’s when humans, their ability to apply judgment and have original thoughts, saves the day.”

    So what are some takeaways for those working in the DevOps field, namely DevOps tooling providers and platform engineers? Well, new tooling preferences and habits will continue to evolve in the DevOps field in new ways. Here are some potential examples:

    • More Markdown-based collaboration. Markdown is the most admired asynchronous tool and has increased in popularity this year. New programmers are adopting a blend of Markdown, GitHub Discussions and Notion for their asynchronous tooling. Flavors of Markdown are already being used for comments, merge requests, issues and more.
    • Continued Docker reliance. Docker remains the top-used tool, followed by npm and Pip. Despite the rise of managed container services, Docker is still a popular way to package and distribute software.
    • Challengers to the big three loom in the distance. Amazon Web Services (AWS) is still the most-used cloud platform at 48.62%. It’s followed by Microsoft Azure (26.03%) and Google Cloud (23.86%). Yet, newer developers want to work more with Hetzner and Vercel.
    • Online learning is paramount to knowledge sharing. Given the steady increase in new programmers and their reliance on online resources rather than traditional schooling, DevOps and open source communities should seek to enhance their online footprint by making knowledge like tooling documentation and tutorials easily consumable.

    Last but not least, generative AI is set to enhance programming in many areas and is already becoming embedded into many environments. Just as AI can be used for code generation and debugging, LLMs will likely assist the DevOps side of the equation, helping automate the CI/CD pipeline, optimize infrastructure, detect anomalies and provide more chat interfaces to initiate these capabilities.

    “AI tools are empowering and enabling learning,” said Liuzzo. “Generative AI will democratize coding and grow the developer community by several folds—and that growing number of developers will be the ones using the tools and also verifying and validating the outputs as they learn—bringing the power of the developer community and the technological power of AI together.”

  • Revolutionizing the Nine Pillars of SRE With AI-Engineered Tools

    Revolutionizing the Nine Pillars of SRE With AI-Engineered Tools

    In my blog Rapid Strategic SRE Assessments Accelerate IT Transformations published last year, I classified site reliability engineering (SRE) into nine pillars of SRE practices—a comprehensive framework that covers the full scope of SRE practices. This nine pillars SRE framework is consistent with the SRE blueprint published by the DevOps Institute. Each of these pillars represents a vital area of SRE implementation and, together, they ensure a holistic approach to aligning development and operations for effective collaboration, uneventful continuous deliveries and reliable, highly scalable, safe operations.

    The current generation of AI-engineered tools is now being applied to each of the SRE pillars and has the potential to significantly increase efficiency, reliability and scalability for all SRE practices.

    Just as SRE practices complement DevOps practices, these nine pillars of SRE complement the nine pillars of DevOps explained in my recent blog Revolutionizing the Nine Pillars of DevOps With AI-Engineered Tools.

    AI Applications for the Nine Pillars of SRE

    The following briefly explains how the current generation of AI-engineered large language model (LLM) tools are being applied or could be practically applied to improve each of the nine pillars of SRE.

    Culture: AI can help identify patterns and trends in system behavior that may not be immediately evident. This can assist in shifting the wisdom of production further to the left. Tools like Datadog’s Watchdog can be used to automatically detect and surface anomalies in your system behavior, for example.

    Toil Reduction and Automation: AI can help reduce toil by automating more complex tasks that were previously challenging to automate. Machine learning models can predict system behavior, enabling proactive responses. AI operations platforms like Moogsoft or BigPanda can automate incident management, from detection to remediation.

    SLAs/SLOs/SLIs and Error Budgets: AI can assist in refining SLAs, SLOs and SLIs by providing accurate predictions of system performance and identifying potential bottlenecks. Tools like Nobl9 can use machine learning to better predict and define SLOs based on historical performance data.

    Measurements and Observability: AI can help analyze vast amounts of data from monitoring and observability systems, identifying patterns and correlations that may be difficult for humans to detect. Tools like Dynatrace and New Relic use AI to analyze monitoring data, detect anomalies and correlate events.

    Anti-Fragility: AI can contribute to the development of more resilient systems by analyzing system behavior under stress and identifying vulnerabilities. The data gathered from chaos experiments using tools like Gremlin can be used in conjunction with machine learning models to predict system behavior.

    Work-Sharing and Incremental Technical Debt: AI can help analyze code and infrastructure changes to assess their impact on technical debt. Tools like DeepCode and SonarQube use AI to provide guidance on how to manage this debt incrementally.

    Deployments: AI can be used to optimize deployment strategies by predicting the impact of new releases. A tool like Harness can use machine learning to optimize deployment strategies and minimize risks.

    Performance Management of Apps and Infrastructure: AI can analyze application and infrastructure performance data to identify optimization opportunities and predict capacity requirements. Tools like Turbonomic leverage AI to optimize resource allocation in real-time.

    Incident Management: AI can assist with incident management by automating the detection and triage of incidents, helping to quickly identify the root cause. Tools like PagerDuty use AI to automate detection, triage and suggest potential remediation steps, leading to faster resolution times.

    Pitfalls and Challenges

    Applying AI to SRE is a complex process with certain challenges. Here are some potential pitfalls along with ways to address them:

    Lack of Quality Data: AI and machine learning models are only as good as the data they are trained on. Inadequate or poor quality data can lead to inaccurate predictions and insights.
    • Prioritize data hygiene and governance. Collect comprehensive and diverse data from your systems; ensure that it is well-structured and free of errors and store it in a way that’s easily accessible for training AI models.

    Over-reliance on Automation: While AI can greatly enhance automation, relying on it too heavily without human oversight can lead to missed signals or overcorrections in response to false positives.
    • Maintain a balance between automation and human oversight. Use AI to support decision-making, not replace it entirely. It’s important to have experienced SREs review AI outputs regularly to ensure they make sense and are beneficial.

    Underestimating the Need for AI Expertise: Implementing AI is not just about buying and deploying a tool. It requires a deep understanding of AI and machine learning principles, as well as the ability to interpret the results correctly.
    • Invest in training your team on AI and machine learning principles or consider hiring AI specialists. Having in-house AI expertise can help ensure that you’re using AI tools effectively and interpreting their outputs correctly.

    Ignoring the Importance of Integration: AI tools need to work seamlessly with your existing infrastructure and processes to be effective. A lack of integration can lead to data silos and inefficiencies.
    • When selecting AI tools, consider how easily they can be integrated into your existing infrastructure and workflows. Use APIs and other integration methods to ensure that your AI tools can access the data they need and that their insights are easily accessible to your SRE team.

    Neglecting Ethics and Privacy: AI tools often need access to sensitive data to operate effectively, which can raise ethical and privacy concerns.
    • Implement robust data privacy and security measures. Ensure that you’re following all relevant regulations and industry best practices for data privacy. Use anonymization and other data protection techniques to protect sensitive data.

    Summary

    Artificial intelligence is revolutionizing SRE practices by automating complex tasks, analyzing vast amounts of data and making proactive predictions. AI can reduce toil, enhance system understanding, and streamline incident management. It allows SREs to shift further left by integrating predictive insights into the development process, thereby enhancing the culture of proactive issue prevention. AI also aids in defining more precise service level objectives, error budgets, and optimizing deployment strategies based on predictive analytics. In the realm of incident management, AI aids in detecting, triaging, and mitigating incidents faster by identifying patterns and suggesting remediations. Overall, AI is fast becoming an essential tool for SREs, facilitating a shift from reactive problem-solving to proactive management, thereby increasing system reliability, performance, scalability and efficiency.

  • How AI Transforms DevOps Infrastructure

    How AI Transforms DevOps Infrastructure

    In my recent article Revolutionizing the Nine Pillars of DevOps with AI-Engineered Tools, I explained that the elastic infrastructure pillar involved automated provisioning and management of computing resources, often leveraging cloud-based solutions for scalability and resilience. This includes practices like infrastructure-as-code (IaC).

    In this article, I explain how AI can help manage cloud resources for DevOps by predicting future needs based on usage trends and automatically adjusting resources to optimize cost and performance.

    Here are some common DevOps use cases that IaC practices aim to address, along with potential AI tools that can assist in each scenario:

    Private and Public Cloud Agnosticism:
    • Use Case: Needing to deploy and manage infrastructure across multiple cloud providers or environments without vendor lock-in.
    • AI Tool Example: AI-powered cloud management platforms (e.g., Turbonomic, CloudHealth) can analyze resource utilization, performance and cost across various cloud providers to optimize workload placement.

    Reducing Infrastructure Configuration Bottlenecks:
    • Use Case: Avoiding manual and error-prone configuration processes that delay deployment and cause inconsistencies.
    • AI Tool Example: Intelligent configuration management tools (e.g., Puppet, Chef, Ansible) can automate the provisioning, configuration and management of infrastructure resources.

    Infrastructure Cost Optimization:
    • Use Case: Optimizing resource allocation and minimizing infrastructure costs.
    • AI Tool Example: AI-driven cost optimization platforms (e.g., ParkMyCloud, Cloudability) can analyze usage patterns, recommend resource resizing or right-sizing and suggest cost-saving opportunities.

    Infrastructure Sharing:
    • Use Case: Sharing infrastructure resources securely across multiple teams or projects.
    • AI Tool Example: AI-powered resource scheduling and sharing tools (e.g., Kubernetes with cluster autoscaling) can dynamically allocate and release resources based on demand and workload requirements.

    Infrastructure Quality:
    • Use Case: Ensuring consistency, reliability, and adherence to best practices in infrastructure deployments.
    • AI Tool Example: AI-based infrastructure validation tools (e.g., Terrascan, Checkov) can scan IaC templates, provide security and compliance checks and offer recommendations for improvement.

    Infrastructure Security:
    • Use Case: Integrating security controls and policies into the infrastructure deployment process.
    • AI Tool Example: AI-driven security tools (e.g., Aqua Security, Sysdig Secure) can analyze infrastructure configurations, detect vulnerabilities and enforce security policies during deployment.

    Dynamic Orchestration:
    • Use Case: Needing to dynamically manage and scale infrastructure resources based on workload demands.
    • AI Tool Example: AI-powered orchestration platforms (e.g., Kubernetes with horizontal pod autoscaling) can automatically scale resources up or down based on metrics such as CPU utilization or request latency.

    Integration and Control of Infrastructure with CICD Pipelines:
    • Use Case: Seamlessly integrating infrastructure provisioning and deployment with CI/CD pipelines.
    • AI Tool Example: AI-enabled CI/CD platforms (e.g., Jenkins with ML plugins, Harness) can leverage machine learning algorithms to optimize pipeline execution, provide intelligent recommendations and automate release processes.

    Monitoring Infrastructure Performance:
    • Use Case: Monitoring and ensuring the optimal performance of infrastructure resources.
    • AI Tool Example: AI-powered monitoring solutions (e.g., Dynatrace, Datadog) can leverage machine learning to detect anomalies, predict performance issues and provide actionable insights for infrastructure optimization.

    Rapid Restore of Infrastructure:
    • Use Case: Quickly recovering and restoring infrastructure in the event of failures or disasters.
    • AI Tool Example: AI-driven backup and recovery tools (e.g., Veeam, Rubrik) can automate backup processes, intelligently prioritize data restoration and leverage machine learning for predictive data recovery.

    Challenges With the Transformation to AI-Engineered Infrastructure

    An organization may face a number of challenges when transitioning to AI tools for infrastructure, as follows:

    Lack of Expertise and Skill Set:
    • Challenge: Organizations may lack the necessary expertise and skill set to implement and operate AI tools effectively.
    • Solution: Invest in training and upskilling programs for employees to acquire the required knowledge and skills. Partnering with external consultants or hiring experts in AI and infrastructure can also bridge the expertise gap.

    Data Availability and Quality:
    • Challenge: AI tools heavily rely on high-quality data for training and accurate decision-making, but organizations may face challenges in obtaining relevant data and ensuring its quality.
    • Solution: Implement robust data governance practices to ensure data availability, quality and consistency. Invest in data collection, storage and processing frameworks that support AI initiatives. Data cleansing and preprocessing techniques can be employed to improve data quality.

    Integration Complexity:
    • Challenge: Integrating AI tools into existing infrastructure and workflows can be complex, especially when dealing with legacy systems and heterogeneous environments.
    • Solution: Plan for seamless integration by conducting a thorough assessment of existing systems and infrastructure. Leverage APIs, automation frameworks and standardized protocols to enable smooth integration. Adopt modular and scalable architectures that facilitate the incorporation of AI components.

    Ethical and Legal Considerations:
    • Challenge: AI tools introduce ethical and legal considerations, including privacy, security, bias and regulatory compliance, which can pose challenges during infrastructure transformation.
    • Solution: Develop clear guidelines and policies around data privacy, security and ethical considerations. Perform rigorous testing and validation to detect and mitigate biases in AI models. Engage legal and compliance teams to ensure alignment with relevant regulations and standards.

    Change Management and Cultural Shift:
    • Challenge: The adoption of AI tools often requires a cultural shift within the organization, including changes in mindset, processes and collaboration between teams.
    • Solution: Develop a change management strategy to communicate the benefits of AI tools and address any concerns or resistance. Foster a culture of experimentation, learning and collaboration. Encourage cross-functional teams to work together and share knowledge. Provide ongoing support and training to ensure successful adoption and adaptation to the new tools and practices.

    Summary

    Incorporating AI into IaC practices for DevOps brings transformative benefits that drive efficiency, agility and scalability. By leveraging AI tools, organizations can optimize resource allocation, streamline deployments, enhance security and improve performance monitoring. Embracing AI for IaC empowers teams to automate and intelligently manage infrastructure, resulting in faster time-to-market, cost savings and increased productivity. Unlock the full potential of DevOps by embracing AI and revolutionize your infrastructure management with the power of intelligent automation.

    It’s important to note that challenges and solutions are to be expected when transforming to the use of AI, and the specific context and requirements of each organization may vary. Therefore, it’s advisable to assess the organization’s unique needs and constraints to tailor the solutions accordingly.