Category: DevSecOps

  • Authentication in Serverless Apps—What Are the Options?

    Authentication in Serverless Apps—What Are the Options?

    Serverless applications are growing in popularity among DevOps engineers. They provide a convenient, predictable way to run simple processes like CI/CD builds or automation scripts with no need to stand up infrastructure. They are also commonly used to deploy microservices. However, serverless applications present unique security challenges, one of them being authentication. 

    How can you ensure services communicate with other services or with the outside world only if authorized to do so? How can you ensure users can conveniently and securely access multiple instances of a serverless function?

    In serverless applications, there are many components interacting—not only end users and applications but also cloud vendors and applications. This is why common authentication methods, such as single factor, two-factor and multifactor authentication offer only a bare minimum foundation. Serverless authentication requires a zero-trust mentality—no connection should be trusted, even communication between internal components of an application should be authenticated and validated.

    To properly secure serverless authentication, you also need to use authentication and authorization protocols, configure secure intraservice permissions and monitor and control incoming and outgoing access. In this article, I’ll cover all these briefly and demonstrate a practical example—setting up authentication in the AWS serverless ecosystem.

    What Are the Most Common Authentication Methods?

    Here is an outline of the standard authentication methods used by most applications.

    Single-Factor Authentication

    Also called primary authentication, this is the most prevalent and straightforward type of authentication. Single-factor authentication asks for only one authentication method; for example, a security PIN, password or PIV card, to gain access to a service or system.

    These methods are solid in relation to familiarity and usability; however, they are generally linked to poor security and credentials can readily be stolen or guessed through phishing, data breaches or by using keyloggers.

    Two-Factor Authentication

    Two-factor authentication (2FA) adds another layer of intricacy, as it needs an additional factor to authenticate a user’s identity. Common verification methods include one-time passwords, tokens created by a registered device or PIN numbers. The presence of two verification methods significantly improves your level of security. 

    Multifactor Authentication

    This is the most complex process of authentication. It makes use of two or more independent factors to verify a user’s identity and authorize access to the system. In common scenarios, multifactor authentication (MFA) makes use of at least two of the following factors:

    • A PIN or password (something known)
    • Security token or mobile phone (something owned)
    • FaceID or fingerprint (something you are)
    • Location information, typing speed or the like (something you can do) 

    Authentication and Authorization Protocols

    An authentication protocol is a communication protocol that protects authentication data as it transfers between two entities. It enables a receiving entity to authenticate a connecting entity as well as authenticate itself to a connecting entity. This is achieved by declaring the type of information required for authentication and syntax.

    There are several types of authentication and authorization protocols, including:

    • Lightweight Directory Access Protocol (LDAP)—a software protocol that enables anyone to find data about individuals, organizations, and resources like files and devices within a network. LDAP allows this whether a user uses the public internet or a corporate intranet.
    • The Security Assertion Markup Language (SAML)—an open standard that allows sharing security information about authentication, authorization and identity across several different systems. 
    • Open Authorization (OAuth)—an open standard authorization framework designed for token-based authorization established over the internet. OAuth enables third-party services to use end-user account information without exposing user account credentials to the third party. This blog post can help you understand the differences between SAML and OAuth.
    • OpenID—enables authentication services and websites to exchange security information in a standardized manner. OpenID Connect—the newest version of the protocol—provides improved identity management, support for mobile application development, and interoperability. Learn more in the official OIDC FAQ.

    Secure Authentication on Serverless

    In serverless systems, there are four forms of access—four forms of communication that should be secured. An individual service won’t have to include all four, but the categories that it does feature should be well-protected. 

    Intraservice Access

    Creating a system by uniting serverless services has many advantages. However, you should consider the security of every additional service. 

    A service with excess permissions is a liability. Unnecessary permissions provide excessive access to data, actions or services, and a bug might let malicious users exploit that service and use its permissions to endanger your system. Hence, you should give careful consideration to the permissions required by each service.

    Effectively overseeing intraservice access permissions is often an overwhelming job. Luckily, all of the top-tier cloud providers have native access management services to make this task simpler. AWS has AWS IAM, Azure has Azure Active Directory and Google Cloud Platform (GCP) provides Cloud IAM. 

    Incoming Access

    A network is made accessible through a SaaS offering to external users. Access will be restricted, and every user will require the official credentials to achieve that access. 

    However, this brings up the same problems raised above—the secrets must be stored somewhere. You cannot manage how your users access and store the credentials that you provide them with; therefore, you should assume that their credentials are not being kept securely and that they may be compromised at any point.

    This would appear to be an unmanageable issue, but there is a solution—to provide temporary credentials. This means that even if the secrets were revealed, they would expire shortly afterwards. 

    The cloud providers have services for this. Google Cloud IAM offers short-lived credentials, AWS IAM lets you create temporary credentials and Azure Active Directory lets you configure expiration dates for its signatures that have shared access.

    Outgoing Access

    When your organization’s serverless function has access to an external third-party service, it typically needs some sort of access credentials. These credentials need to be kept somewhere, but this storage is sometimes not as secure as it should be. Today, certain web applications continue to store secrets in databases, text files or hardcoded within the function code. 

    Cloud providers have services for securely retaining credentials and secrets. AWS has AWS Secrets Manager, Azure offers Azure Key Vault and GCP offers Google Cloud Secret Manager.

    End User and Customer Access

    The issues with this access type are akin to those for incoming access, though the solution is different. Whether in B2B or (particularly) B2C environments, not many users would put up with a requirement to continuously regenerate or refresh their credentials. Thus, another approach is needed. 

    The top-tier cloud providers all have a user authentication service—Azure Active Directory B2C, AWS Cognito and Google Identity Platform. You should also consider using third-party end-user verification, as this will help you avoid vendor lock-in. Third-party offerings also tend to offer a better developer experience. The most common third-party authentication providers are Okta and Auth0.

    AWS Lambda Authentication Solution Example

    Amazon Cognito offers managed authentication and authorization that can help you build secure web services in a serverless architecture. It is typically used in combination with Amazon API Gateway when building complex serverless applications that require permission control.

    For example, a payroll system may have a manager and two additional employees. The three employees can use their unique usernames and passwords to log into the payroll system—this process is called authentication.

    To retrieve paystubs, the three employees undergo role-based authentication:

    REST API GET /api/employee/{employee_id}/paystubs

    However, the permissions they get through this process should be unique to their needs. This may involve setting up the following conditions:

    • The manager can access the paystubs of all employees.
    • Employees cannot access the paystubs of other employees, only their own. 

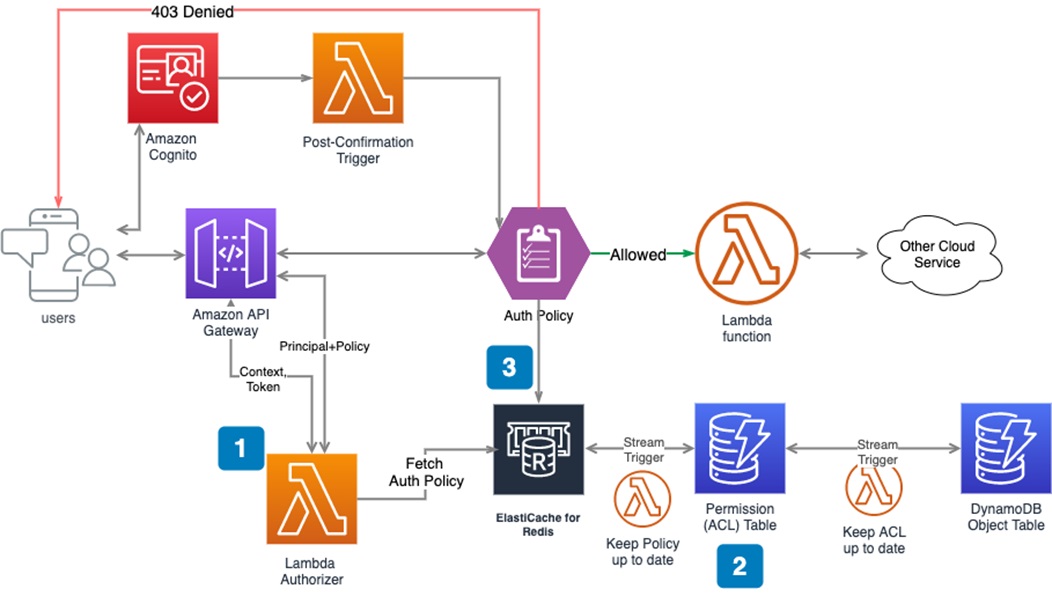
    You can use AWS managed services to fulfill the above requirements and also meet future scaling needs.

    Image Source: AWS

    Step One: Setting Up AWS Lambda Authorizer

    The Lambda authorizer is the brain that centrally determines whether the requester has the relevant permissions for the requested API resources.

    Here’s how you can set it up:

    • Navigate to the Amazon API Gateway and create an authorizer.
    • Select the API resources you want to secure and assign the AWS Lambda function to them.
    • Configure your new AWS Lambda authorizer.

    Step Two: Building User Access Control List (ACL)

    It is crucial to establish user permissions and keep them up-to-date. The approach might differ according to your identity provider. Here is an example of the process if you use Amazon Cognito as your IDP. 

    1. Initialize the ACL

    Every user has a unique ID, so you can describe each user’s permissions by inserting items in the permission table in Amazon DynamoDB when you register with Cognito. The DynamoDB permission table stores the access control list for all users, although the implementation may differ based on the use case. 

    For this example, let’s use a single integer ID for each employee (the UUID strings in real applications tend to be much longer). 

    Manager:

    uuid: xxxx-xxx-xxx-xxxx-xxxxxxxx

    employee: {“allow”: [“/5”,”/5/*”]}

    paystubs: {“allow”:[1,2]}

    Employee 1: 

    uuid: xxxx-xxx-xxx-xxxx-xxxxxxxx

    employee: {“allow”: [“/6”,”/6/*”]}

    paystubs: {“allow”:[3,4]}

    Employee 2: 

    uuid: xxxx-xxx-xxx-xxxx-xxxxxxxx

    employee: {“allow”: [“*”],”deny”:[“/7”,”/7/*”]} // employee_id=7 is the manager of employee 2

    paystubs: {“allow”:[1,2,3,4]}

    2. Manage the Access Control List (ACL)

    The user permissions in a complex project are constantly changing. Employees can be promoted, demoted or terminated, with different access requirements depending on their changing roles. A new manager, for example, needs access to all pay stubs, which means you have to create a new pay stub object for every employee. 

    You can manage user permissions using the Amazon DynamoDB stream:

    Lambda functions can easily be integrated when you insert or modify items in the permissions table. A Lambda function might include code that modifies permissions according to changes to the role of a user.

    3. Build an ACL policy

    Once you’ve established an ACL with user permissions for every object, you should create an authorization policy document. The Lambda function authorizer uses this policy to evaluate whether user API requests should be allowed or denied.

    Amazon API Gateway offers a mechanism for evaluating policies internally. internal policy evaluation mechanism. The Gateway will automatically evaluate any policy JSON returned by the authorizer. For details about Lambda authorizer’s output standard, see this document.

    In this article, I covered the basics of authentication in serverless applications:

    • Single-factor authentication
    • Two-factor authentication
    • Multifactor authentication
    • Intraservice access
    • Outgoing access
    • Incoming access
    • A real-life example with Amazon Cognito

    I hope this will be of help as you gain a better understanding of authentication and authorization techniques that help secure serverless applications.

  • Learn a Bit About AI

    Learn a Bit About AI

    Every once in a while, a trend becomes broad enough that I feel the need to offer career advice. This year it will be simple: Know enough about AI/ML to be dangerous. We are past the point where not having at least a basic understanding is a good idea. Looking around the data center, AI is in use from the earliest stages of development through production network performance evaluation. Somewhere in your environment, you are using AI and ML. More to the point, somewhere in the places you may interview going forward, they are using AI and ML.

    I’m not suggesting you become an AI/ML expert—though you certainly could; I have a relative that is a data scientist and that’s all he does—design and tweak algorithms. He’s learning new things pretty much daily, so if you like that (as I do), it’s an option. But for those of us doing DevOps or SRE or even regular old operations, we’re only going to have to understand a bit.

    Understand what tools like Jupyter are, and what the most commonly used ML algorithms in your space are. Then, learn about how AI and ML help with what you are doing. Just as knowing more about the compiler/interpreter of your chosen language helps you solve more odd problems, AI is going to have that same issue. Think about how those folks who understand the guts of routing are the ones we want solving our routing problems. Again, same scenario.

    Moving forward, AIOps, NetOps, DevSecOps … All intend to increase the amount of work offloaded onto the AI in question. In a lot of cases that is great. We have enough to do; if you can paw through those logs and give me relevant summary info, go for it. But it doesn’t end there—some AI engines are making the calls and implementing changes. In both network and application security, a fair number of vendors will tell you there is no time to wait for humans to stop an attack, and they encourage their customers to turn on automated responses. That’s the first of many applications for AI/ML. We will see an increasing number of AI/MLOps tools being used for full-on automation. We all do difficult jobs with a complex—sometimes bewildering—number of inputs. But we use pattern recognition and experience to make determinations and do what’s best for our organization. Our software has reached the point where sometimes, it can do that for us on the easier tasks so we can focus on the more complex ones. When the AI/ML fails—and it will, because pattern recognition and historical trends are not always indicative of normal usage—knowing what is going on under the covers can help you determine if it did the right thing in the wrong way, or simply did the wrong thing. And it can help you to quickly recover. I can’t speak for every organization, but I’ve never seen one that lamented, “Sure wish that outage had lasted another couple of hours!”

    And keep rocking it. Somewhere in the distant future, an  AI may be able to do your job as well as you. But that isn’t today. Even if it can handle one bit, it certainly isn’t rocking the entire breadth of your responsibilities like you are. Thank you, from all the users that don’t realize you’re keeping them live.

  • A Blueprint for Securing Software Development

    A Blueprint for Securing Software Development

    Software development has changed dramatically in recent years, as technologies like DevOps, application containers, and cloud-native transform how software is built and distributed. Unfortunately, attackers have been paying close attention to these changes, and have retooled their attack strategies to take advantage of relatively weak security controls in software development and build environments. Attackers recognize that security teams are more focused on protecting infrastructure and less focused on software development and supply chains. This is how damaging attacks like SolarWinds happen – and it’s likely that attackers will strike again to yield even more successful outcomes.

    A new approach is needed to secure the software development pipeline. What’s more, this approach needs to be put in place by the engineers developing the software—and not by information security teams. Engineering teams need to be responsible for design and implementation while giving security teams visibility and assurance that controls are operational and that policies are being enforced.

    A new blueprint for securing the pipeline centers on a flexible set of controls that secure the software build pipeline by ensuring that authentication and authorization are properly managed, that the integrity of software artifacts are tested at appropriate stages and that controls are placed on third-party and open source solutions incorporated into the software. The result: Software innovation and delivery at lower risk of supply chain tampering, and reduction of attacks during development.

    A Pragmatic Design Philosophy

    This modern software security blueprint is based on the following design philosophy:

    • Least-privilege: Only grant the access and permissions required to accomplish a job, and no more.
    • Immutability: Artifacts and infrastructure are not modified after deployment to an environment. If a change is required, it’s done in the image or script in the development environment and then promoted through the higher environments.
    • Everything-as-code: Infrastructure, security policies and other parts of the pipeline are also implemented as code and subject to the same controls as the software artifacts.
    • Traceability: All changes, whether to infrastructure or business code, are version-controlled. 

    Controls Blueprint for Software Development Pipelines

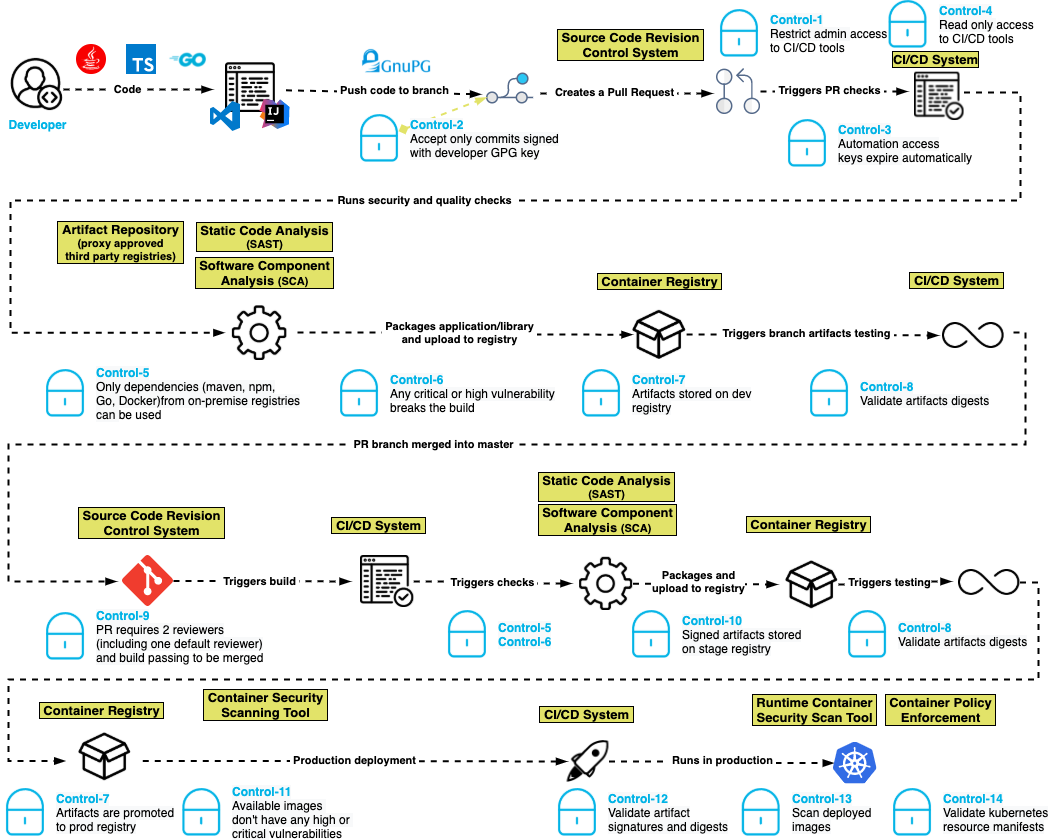
    The basis for this software security blueprint centers around a set of 15 controls that are built for modern development pipelines where developers, pipelines and execution can happen anywhere in the world.

    Control one: Restrict administrative access to CI/CD tools. Ensure that only authorized people can make administrative changes to the CI/CD system, which prevents unauthorized changes to pipeline definitions.

    Control two: Only accept commits signed with a developer GPG key. Unsigned code commits are challenging, if not impossible, to trace and pose a risk to the integrity of the codebase. 

    Control three: Automation access keys expire automatically. By ensuring that access keys used by automation expire periodically, developers create a shorter window of attack when keys are compromised.

    Control four: Reduce automation access to read-only. CI systems should have read-only access to source code repositories following the principle of least-privilege access.

    Control five: Only dependencies from trusted registries can be used. By configuring the dependency manager to only allow connections to an authorized list of registries, attacks can be blunted by keeping malicious packages in public registries from entering the pipeline.

    Control six: Any critical or high-severity vulnerability breaks the build. Supply chain attacks may introduce code with vulnerabilities into the software pipeline. Static application security testing (SAST) helps to identify serious security issues, including poor cryptographic practices, hard-coded credentials and injection vulnerabilities. 

    Control seven: Artifacts are stored in a repository in development, staging and production. This control helps to enforce the immutability of the artifacts so they can be compared in the development, staging and production repositories.

    Control eight: Validate artifact digest. Before an artifact is deployed in any environment, its digest should be validated against the artifact in the repository to ensure that it has not been compromised.

    Control nine: Pull requests require two reviewers (including one default reviewer) and a passing build to be merged. In addition to supporting good coding practices, this control also helps ensure that no commits are made without competent human oversight. 

    Control 10: Artifacts in higher repositories are signed. Requiring artifacts to be signed in a repository throughout the process ensures visibility and traceability for whatever is deployed to production. 

    Control 11: Available container images don’t have any high or critical vulnerabilities. Just as applications need to be tested for vulnerabilities before being placed in production, so do the container images into which they are packaged for deployment. Container images could have open source vulnerabilities if they contain open source software. 

    Control 12: Validate artifact signatures and digests. Validating the signature of the artifact against the digest ensures that the artifact was not tampered with in the repository and that the artifact being deployed is the same one that was tested.

    Control 13: Scan deployed images in production. This helps to ensure that the prior controls were followed for all software in production.

    Control 14: Validate Kubernetes resource manifests. If the resource manifests are tampered with, they could be tricked into deploying a container of the attacker’s choice. 

    Control 15: Ensure build environments are ephemeral and immutable. Build environments should be defined in code with automated creation and teardown and a fresh environment created for every build. Build hosts should not be accessible using interactive logins.

    We believe this blueprint provides engineering teams with an actionable architecture that security teams can rally behind and support. By adopting these standards, engineering teams are promised the delivery of assured software at lower risk of supply chain tampering, reduction of attacks during development and manipulation in staging and production.

    Here’s what it looks like:

    blueprint

    To learn more about the suggested blueprint, read our GitHub post about the project. Our goal is to prioritize speed and agility for software development while incorporating a security-always mindset.

  • Why Observability and Monitoring Matter to SREs

    Why Observability and Monitoring Matter to SREs

    Site reliability engineers, or SREs, do many things. They help developers build reliability into applications. They manage SLAs and SLOs. They play a leading role in incident management and incident response.

    For all of these tasks, SREs draw heavily on observability and monitoring. Although other parts of the IT organization also typically help to manage observability and monitoring, it’s virtually impossible for SREs to do their jobs effectively in today’s cloud-native world without observability and monitoring tools and data.

    Here’s what observability and monitoring mean, why they’re so important for SREs in particular and how SREs can systematically measure the success of their monitoring and observability practices.

    Defining Observability vs. Monitoring

    Monitoring is the collection of data from applications, infrastructure or other IT resources to track the status and performance of those resources. Monitoring has been a core IT practice since the late 1990s when the first modern monitoring tools, such as Nagios, appeared.

    When compared to monitoring, observability is more intensive. Observability is the collection of discrete types of data from multiple systems and the correlation of those data sets to achieve actionable visibility into IT resources. One thing to note: Observability has a more technical definition in the field of control theory that has to do with using external outputs to make inferences about the internal state of a system; however, when people talk about observability in the context of IT and SRE, they usually mean the collection and correlation of broad sets of data in order to understand complex systems.

    The debate about the differences between observability and monitoring is ongoing, but the consensus is that they boil down to:

    • What versus why: Monitoring helps SREs determine that a problem exists. Observability goes further by allowing them to understand why it exists.
    • Context: Observability provides context around what is wrong with a system. Monitoring, for the most part, offers surface-level information about the existence of a problem.
    • Actionability: Observability empowers SREs to respond effectively to outages, performance degradations or other problems. Monitoring merely lets them know that something is wrong and that it may require intervention.

    In most respects, monitoring is one step in the greater observability process. But observability involves additional practices, such as the correlation of various types of data, to achieve a level of context and actionability that monitoring alone can’t deliver.

    Why SREs Should Understand Observability

    Again, observability has become a core practice for engineers in a variety of roles. Developers can use observability tools to help measure and optimize application performance before deployment. IT engineers can leverage observability to gain visibility into issues that exist in a production environment. Observability tools can help QA engineers determine why an application failed a test.

    But no group has more to gain from observability than SREs. Given that maximizing the reliability and performance of systems is the core mission of SREs, the ability to not just detect problems via monitoring but also to understand them through observability is critical for modern SRE teams.

    That’s all the more true for SREs tasked with managing reliability for complex systems, like those based on microservices. In complex applications, identifying the root cause of a reliability issue—such as which specific microservice contains buggy code or which type of request triggers a performance bug—can be very difficult. By maximizing context into reliability problems, as well as allowing teams to trace requests across complex, distributed systems, observability places SREs in the strongest position to find and fix reliability problems quickly.

    What’s more, beyond detecting issues in systems that have already been deployed, SREs can also leverage observability tools to help build reliability into applications before they are put into production. By observing applications in dev/test environments, SREs may be able to identify reliability risks and then use that insight to find ways to make the application inherently more reliable. Observability might reveal reliability weaknesses that stem from an application’s architectural design, for instance, or from the orchestration tool that manages the application.

    How to Measure Observability and Monitoring

    Getting the most from observability and monitoring requires systematic measurement of observability and monitoring initiatives. It’s only by collecting metrics about observability and monitoring outcomes that SREs can ensure they are improving reliability rather than merely collecting and analyzing data to no particular end.

    While a full discussion of observability and monitoring measurement is beyond the scope of this article, consider the following types of metrics for assessing these practices:

    • Incident frequency: How often do incidents (especially severe incidents) occur that impact production systems? Ideally, SREs will see a decrease in incident frequency that correlates with increased use of observability and monitoring tools.
    • Rollback frequency: The less often an application release is rolled back to a previous version, the more effective the SRE team’s observability and monitoring practices likely are.
    • Mean-time-to-remediate (MTTR): MTTR is a measure of the overall time it takes to resolve a reliability problem. It reflects how well you monitor (which determines how quickly you detect problems) and how well you observe (which is the key to resolving problems).
    • Total data analyzed: Tracking the total volume of data that you collect and analyze through observability and monitoring tools helps you assess the overall scope and scalability of your practices.
    • Total systems analyzed: In addition to tracking total data volume, consider measuring how many discrete applications, hosting environments, CI/CD tools and other systems you are managing as part of observability and monitoring workflows.

    The ultimate goals of SREs extend beyond observability and monitoring. However, observability and monitoring serve as essential means to the broader ends that SREs are tasked with achieving: Maximizing uptime and performance. And while monitoring alone was once sufficient for supporting the goals of SREs, it’s very difficult to imagine an SRE team today that doesn’t also make extensive use of observability, which takes monitoring to the next level.

  • Welcome to the New Field of Software Supply Chain Management

    Welcome to the New Field of Software Supply Chain Management

    Supply chain management is the newest ‘shiny object’ in both the DevOps and DevSecOps communities. But what does it mean in relation to software development?

    Historically, supply chain management is a commerce term that refers to tracking the logistics of goods and services moving between producer and consumer. This would include the storage and flow of raw materials with a focus on the channels that support the process.

    When we look at this concept from the perspective of software development, we will soon see that it is a new form of software configuration management. Yes, the new SCM is … SCM. The core of supply chain management is the process of controlling changes in software. The new SCM expands those old practices to include all ‘raw materials’ which we manage as part of our software build and package steps. For instance, when companies purchase and download open source libraries used in their in-house software. Supply chain management includes the interrogation of these ‘raw materials’ as well as all of the internal code and libraries. We will soon be hearing more about software bill of materials (SBOM) reports and difference reports, as they are critical for understanding the objects that flow through the software we create.

    The software supply chain or software configuration management practice hasn’t been talked about much until recently. This area of expertise has never been ‘sexy.’ That is, until the SolarWinds supply chain hack. The SolarWinds hack was a hard lesson to learn, but it taught us to take a closer look at how we consume our raw materials and to be more serious about how we build and package our software.

    According to FireEye, the firm that discovered the backdoor supply chain hack:

    “SolarWinds.Orion.Core.BusinessLayer.dll is a SolarWinds digitally-signed component of the Orion software framework that contains a backdoor that communicates via HTTP to third-party servers. We are tracking the Trojanized version of this SolarWinds Orion plug-in as SUNBURST.”

    It was obvious, something went very wrong with the creation of that .dll. I don’t pretend to fully understand how this breach occurred. But I do understand the build process and have been talking about the potential for these types of breaches for over 25 years.

    There have always been big security gaps and vulnerabilities in our most basic software development practice—the compile/link process. Most build processes are imperatively defined using an Ant, Make or Maven script. Each time the build runs, it rebuilds all the binaries, even if the corresponding source code has not changed.

    This is a problem. Instead, we need a build that is incremental. Incremental builds are difficult to script because they need more advanced logic. Most developers are not given adequate time to create a better build process, one that only rebuilds the changes. This means it is next to impossible to audit why a binary was recompiled because they are always recompiled. If we only recompiled the binaries that had corresponding code updates, we could more carefully audit the code and make sure that only approved coding updates were included.

    This may not have caused the SolarWinds attack, but it could have. Once hackers have gotten past the firewall they can find the build directory, read through the build scripts and identify the perfect piece of code to update with their bad function. The next time the build runs, a ‘clean all’ recompiles everything and, like dark magic, a SUNBURST is created.

    In our not-too-distant past, the developer community had tools that controlled software builds beyond what an imperative script could do. OpenMake Software, for example, provided a build automation solution called Meister that ensured that incremental builds were easy. As part of the build, it generated SBOM reports and differences reports allowing teams to easily audit and compare the actual source changes to confirm that only approved code updates were included. Another example was Rational Software’s ClearCase which used a program called ClearMake. ClearMake used a process called ‘winkin’ to reuse ‘derived’ objects that had not changed. This process created an incremental build that could be easily audited.

    I realize that I am simplifying the overall problem, but it is a good example of the basic supply chain best practices and how potentially vulnerable our processes are.

    The time to carefully think about how we manage our raw materials and overall supply chain is now. I’m guessing that most monolithic practices will not change much; it is too costly and impactful to rewrite hundreds of CI pipelines. But that does not mean we can’t solve the supply chain puzzle as we shift into cloud-native development in a microservice architecture.

    In a microservices architecture, we need to begin thinking about what the supply chain looks like. How do we track raw materials that are in the form of hundreds of small ‘bounded context’ functions? The good news is there is an emerging microservice catalog market that can become part of the supply chain solution. A microservices catalog can track versions of services to versions of their consuming applications. Your new SBOM report will have two levels: First, an SBOM for the microservice. Second, aggregated data at an application level. Remember, in this new architecture a full build is not done.

    It’s important to understand that microservices are naturally incremental and are independently built, packaged and deployed. Managing these small services opens the door to more closely auditing their source code before they are released.

    As we shift from monolithic development to microservices, we have an opportunity to incorporate supply chain and configuration management best practices. This includes being able to carefully audit the code before a release is done. And remember, we must do this as fast as possible. It sounds like a big task, but it’s well worth the effort. Collectively, we will find the answers as we explore new ways to manage our DevOps pipeline and incorporate configuration management and DevSecOps principles.

  • Security is About People, not Technology

    Security is About People, not Technology

    Just a random thought of the day: We have the world’s best example of how many of our security woes are actually people problems, not technology problems.

    We all know that. We’ve all discussed it—but let’s consider this example and have a quick discussion about 2FA.

    Epic Games had a problem not unlike the rest of us. But it was costing them money every day, in part because of the nature of their user base. The problem? Attackers taking over the accounts of legitimate Fortnite users. In the world of gaming, scammers are rife because the player base is younger. At least since Ultima Online (1997), online games have been growing and Fortnite is at the forefront of that movement, with user counts unheard of before it became popular. That many users combined with hackers and scammers taking advantage of the younger demographic attracted to games—over 60% of Fortnite’s massive user base is under 24 years old—they do not provide a further breakdown, but there are certainly kids as young as six playing; and possibly even younger players).

    That made for a problem. Investment of time and money and energy for supporting customers having account issues was no doubt huge. I do not have an insider feeding me information, but simple math—and the evidence of steps they’ve taken—suggest that this is the case.

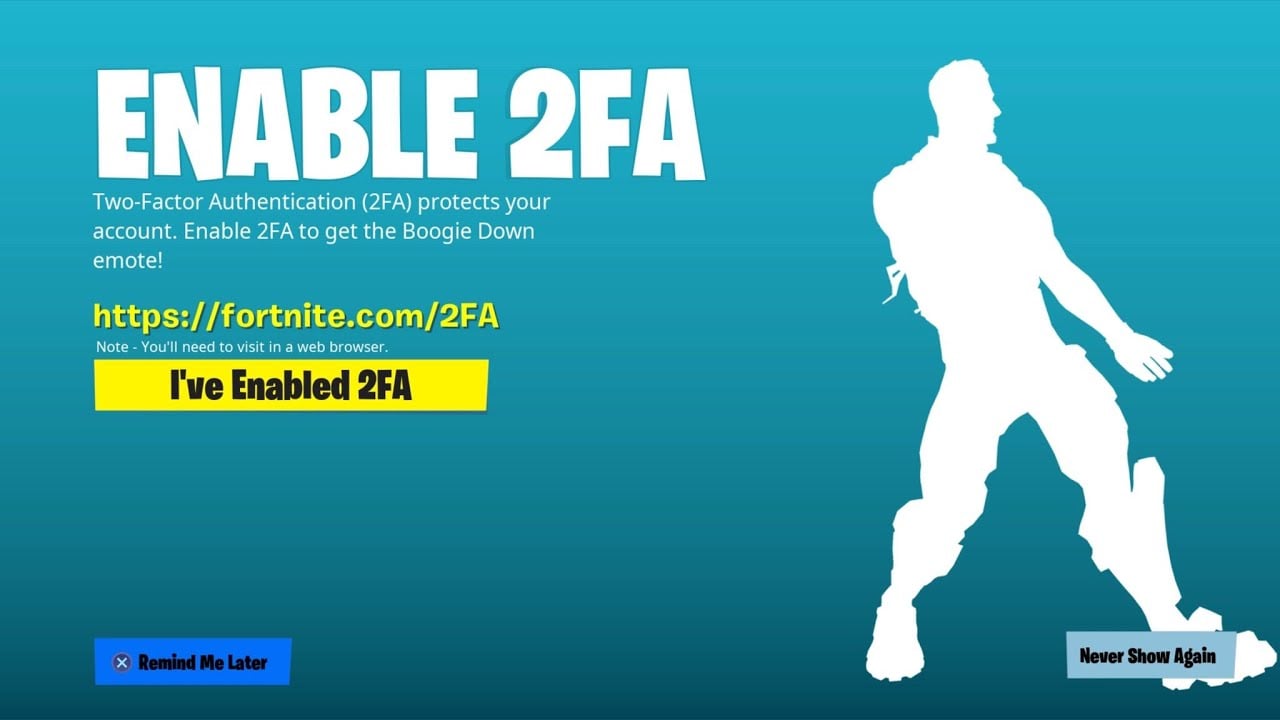
    So they did with kids what far too many of us don’t have the guts to do with our adult workforce. They implemented 2FA. While they did not require it—and, like most game companies, are tight-lipped about any kind of player statistics—they implemented it with a carrot-or-stick approach that, no doubt, has been successful. My gaming group of half a dozen all use it—because we either wanted the carrot or were avoiding the stick. It’s not really a stick. Call it carrot and wall. The carrot comes in two forms for the two most popular versions of the game: A free dance for your character (toon, if you prefer) to perform in Fortnite: Battle Royale.

    Fortnite Dance

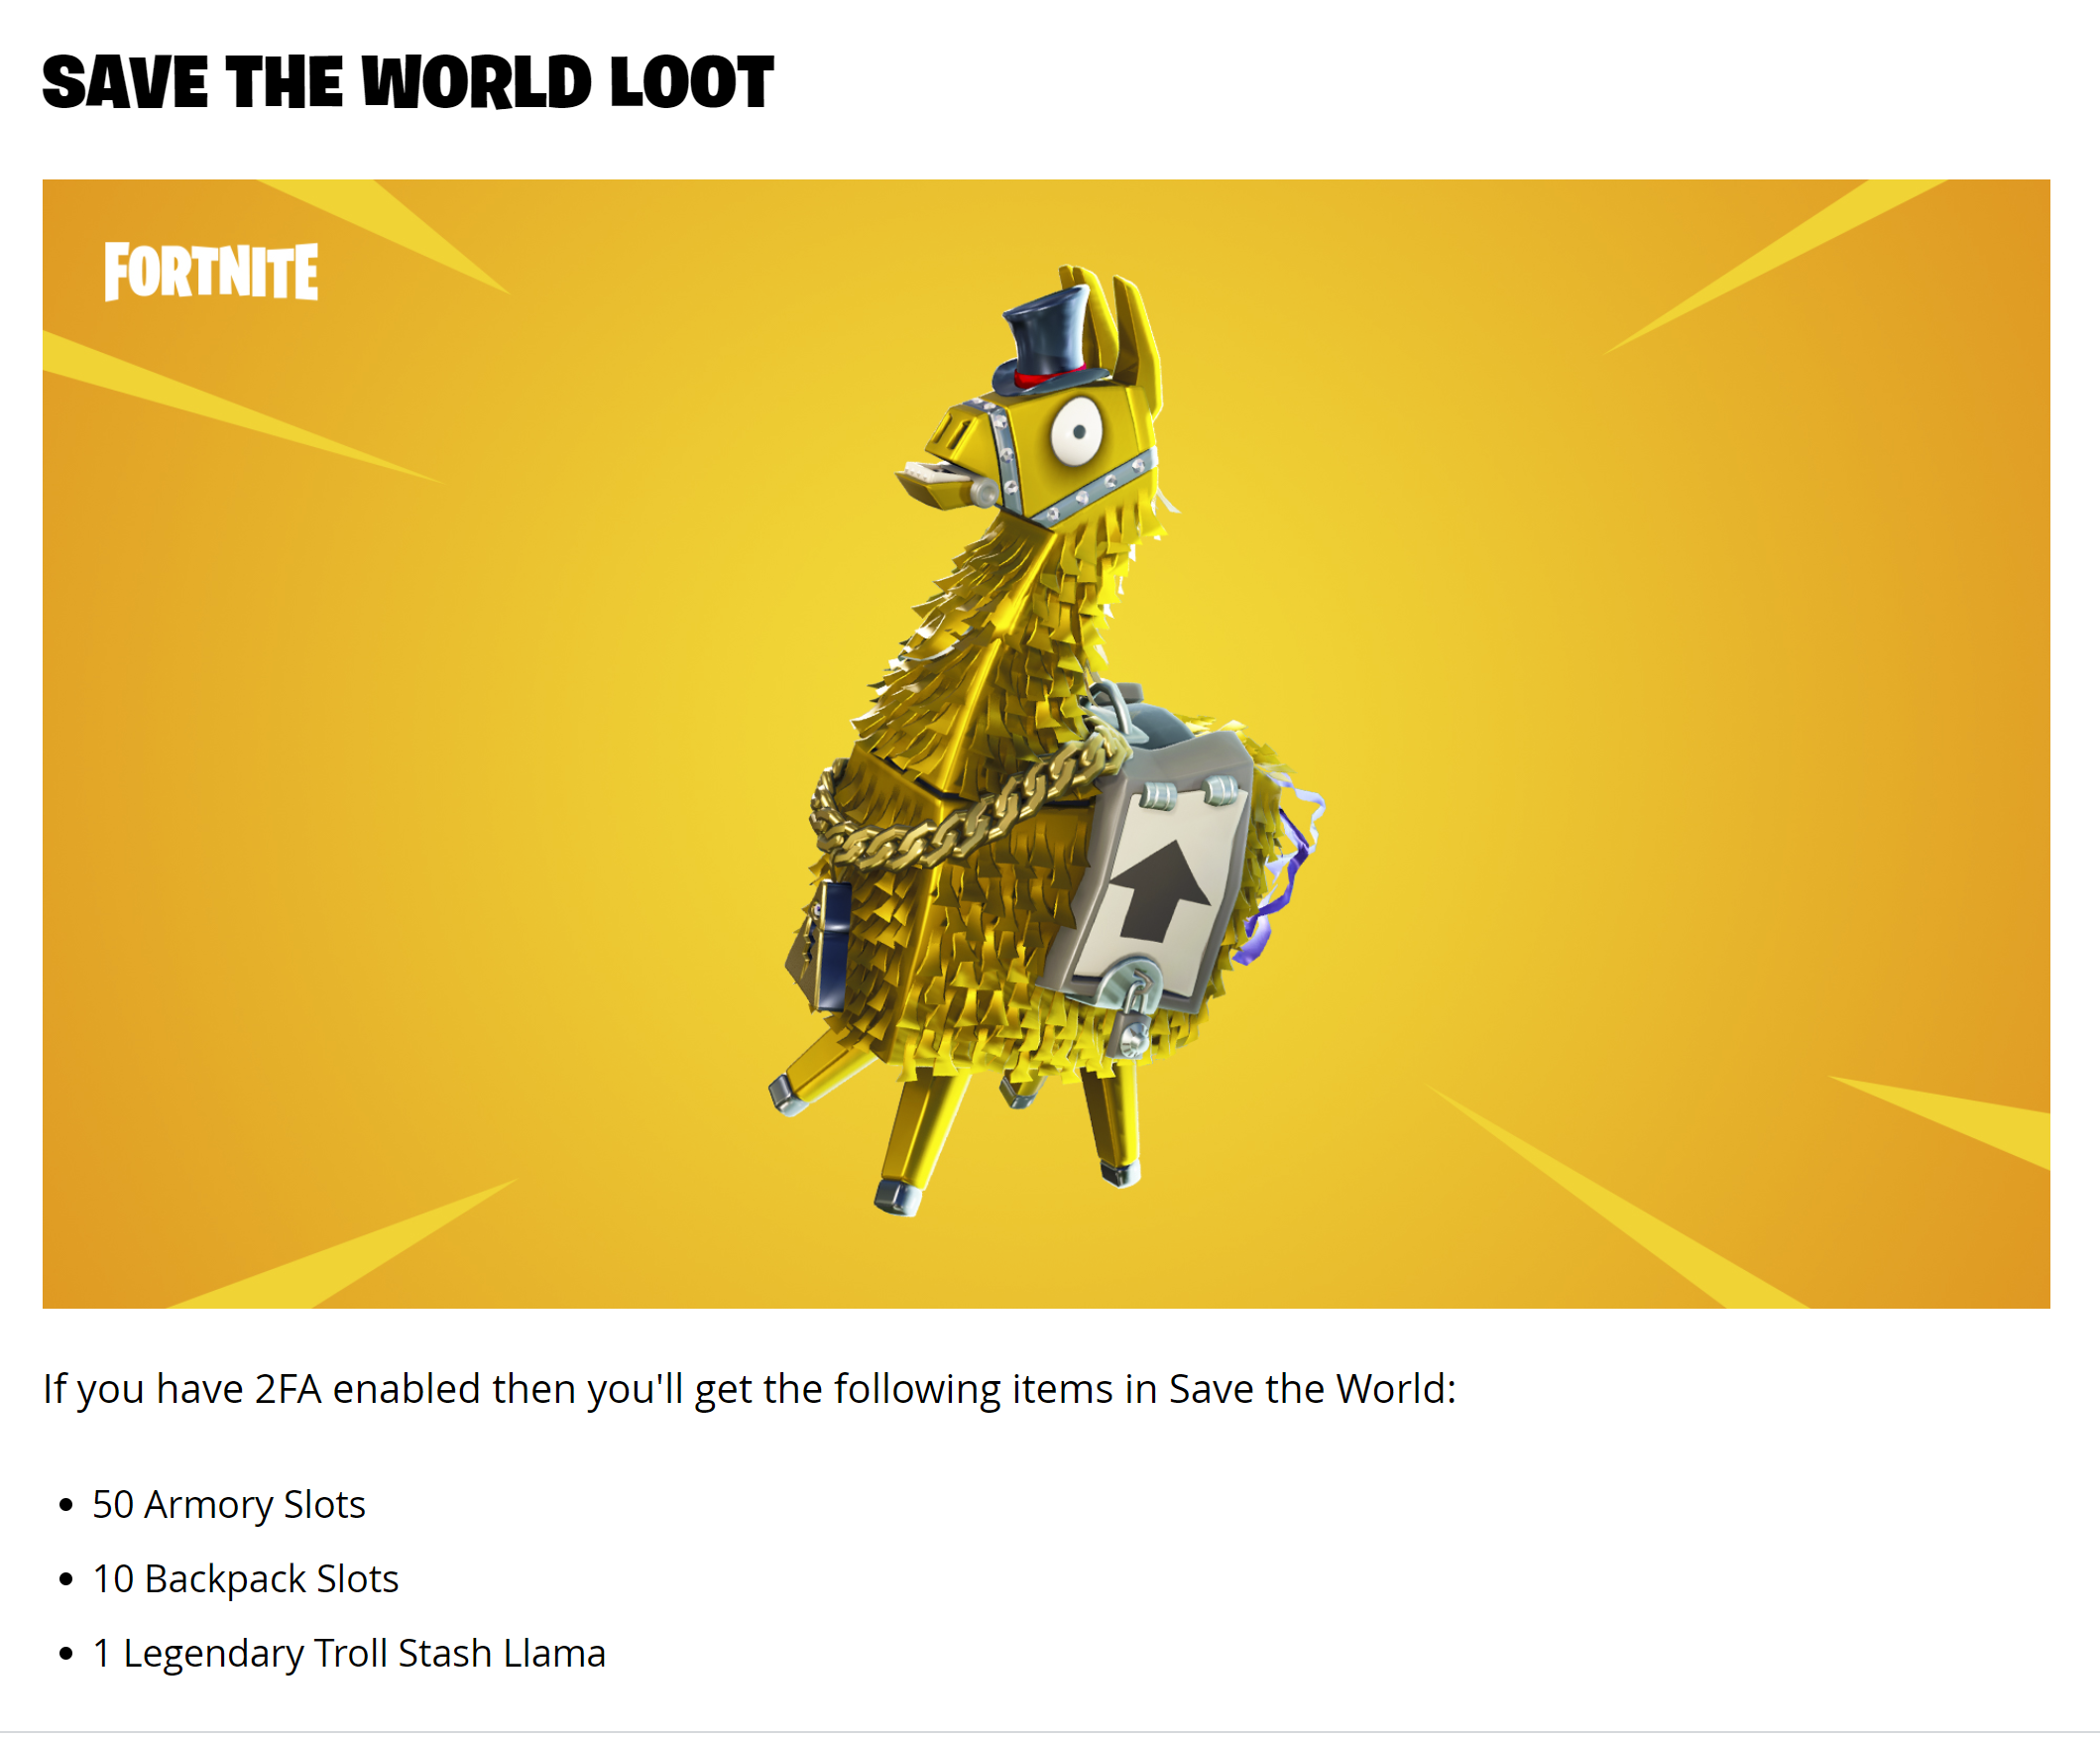
    And free gear in the paid version –  Fortnite: Save the World.

    Free gear

    For those of you who are not familiar, both of these are decent rewards; calculated by the Fortnite team to be compelling enough to warrant the steps, but not insane. The Save the World rewards are actually better in terms of usefulness, but the dance for Battle Royale is likely more popular.

    Then, they put up a wall. If you want to play competitive Fortnite, you must have 2FA turned on. It is possible that this was done to protect the sanctity of their tournaments, but it has the effect of providing the other half of the “reward and punish” equation. According to Compare Camp, 40 million players attempted to qualify for the game’s World Cup alone. So that is the minimum number of 2FA activated accounts—you cannot participate in competitive Fortnite without 2FA turned on.

    They then made turning 2FA on as easy as possible. You need to learn from this. It was harder for me to turn on 2FA and get it working for Discord than it was to turn it on and get it working for Fortnite. Strive to be as easy as Fortnite.

    At this point, we should all recognize that some form of 2FA, even the much-maligned ones like email (maligned because someone who compromises your email then has easier access to everything because 2FA is compromised), is almost essential. The cost of someone hijacking a valid user account—like the lead systems engineer or the CEO—is just too high to ignore. But some 2FA solutions are harder than others. So, we need to follow Epic Games’ lead, and make it as simple as possible, provide incentives to employees to turn it on and, if suitable, wield a stick. A minor ding on reviews until implementation is complete should be enough, if the incentives are nice. A free day off? A small bonus? You know your organization, both what management will agree to pay for and what users will find compelling.

    Get it done. The last thing you want is for your CEO to suddenly start saying/doing erratic things on corporate accounts. Unless they already do—then I suggest you consider looking for a new job. I know; there are 5,000 things to do and only a few of you. But this one is big. Don’t wait until you’ve lost accounts to turn on a pretty effective prevention mechanism.

  • Snyk Extends Tools Portfolio to Drive DevSecOps Adoption

    Snyk Extends Tools Portfolio to Drive DevSecOps Adoption

    During its online SnykCon 2021 conference this week, Snyk extended Snyk Code, a static application security testing (SAST) tool that already supports the Java, JavaScript and Python programming languages to include support for C#, Ruby, PHP and Go.

    At the same time, Snyk Open Source, a platform for remediating open source vulnerabilities, has been extended to provide native integration with Atlassian BitBucket and AWS CodePipeline platforms for driving DevOps workflows. Snyk has also tightened integrations with platforms from DigitalOcean and HashiCorp.

    Snyk also added support for the Elixir programming language and package managers Yarn 2 and Poetry alongside integration with a C++ scanning tool from FossilID, a provider of a software composition analysis (SCA) tool for open source code that Snyk acquired earlier this year.

    The Snyk Container platform is now integrated with the open source Trivy container scanning tools and with Snyk’s vulnerability database in addition to adding support for container registries such as Quay, GitHub Container Registry, GitLab, Google Artifact Registry and Harbor.

    The Snyk infrastructure-as-code platform now also makes it possible to detect configuration issues in Kubernetes manifests in Terraform code in a way that is compatible with cloud platforms from Amazon Web Services (AWS), Microsoft Azure and Google Cloud Platform (GCP).

    Snyk also is adding support for version 3 of OpenAPI, which the company reports is three times faster than the previous version. That API is also the foundation for Snyk Apps that the company will continue to roll out.

    Finally, Snyk launched both a new free developer security education program, dubbed Snyk Learn, through which developers can attain and measure their level of DevSecOps expertise and Snyk Impact, an effort to foster collaboration among developers involving a wide range of socio-economic issues.

    Company president Guy Podjamy said as DevsecOps continues to evolve, the primary focus remains on developers and DevOps teams. However, as an issue, DevSecOps is also becoming more important at both the C-level within organizations as well as individual security operations teams. As such, and in the wake of recent high-profile security breaches, the sense of urgency surrounding DevSecOps is now a lot higher. The fundamental challenge organizations are trying to address is finding a way to improve overall application security without slowing down the pace at which applications are built, noted Podjamy.

    Snyk itself revealed it has secured an additional $530 million round of funding to address those issues. The company has now raised a total of $775 million to date with a valuation of $8.5 billion. Snyk also revealed it has increased annual recurring revenue (ARR) by 154% year-over-year from a customer base that now spans more than 1,200 organizations, including Asurion, Google, Intuit, MongoDB, New Relic, Revolut and Salesforce. Snyk customers and users collectively have run more than 300 million tests in the last 12 months to fix more than 30 million vulnerabilities in a 90-day period of time, the company claims.

    It may be a while before most organizations have embedded security tools within every DevOps workflow. However, given the resources being poured into DevSecOps, it may be more a question when DevSecOps will be finally achieved rather than if.

  • Tips for a Successful DevSecOps Life Cycle

    Tips for a Successful DevSecOps Life Cycle

    A DevOps implementation, if done correctly, can do wonders for any organization that’s on the hunt for efficiency, productivity and speed. As per the 2020 survey conducted by Atlassian, 99% of survey respondents said that DevOps has had a positive impact on their organization.

    However, it won’t do any good if security isn’t prioritized while adopting the DevOps best practices. That’s where DevSecOps comes into play.

    Enterprises need to understand that leveraging the alignment of development and operations for workflow enhancement while ignoring underlying security issues is like trying to generate electricity from a broken solar cell on a cloudy night. Undoubtedly, the success of any DevOps initiative predominantly relies on general security practices and a robust security mechanism to mitigate risks—this is where DevSecOps plays a vital role.

    There are several essential components of a successful DevSecOps implementation. Here’s how you can leverage them in your organization.

    The Emerging Need for DevSecOps

    DevOps can be simply defined as the next evolution of an agile development environment that bridges the gap between operations and development teams. Enterprises increasingly are turning to DevOps to boost their application development speeds and operational efficiency. Often, though, prioritizing development velocity means security concerns are left behind.

    That’s why there’s an equally growing need for a secure, efficient yet still agile development environment. DevSecOps puts security at the forefront of the entire operational and development process, which safeguards good cybersecurity hygiene right from the beginning. Implementing DevSecOps directly benefits developers and operations teams working hard to deliver a flawless application in a short period of time. Moreover, this approach encourages enterprises to develop secure code and thus, secure applications. To do so, there are several resources and strategies to help implement DevSecOps into an organization’s software development life cycle (SDLC).

    Secure Coding Practices

    Secure coding is perhaps the most crucial aspect of ensuring stringent security right from the beginning of the SDLC. Developers who aren’t following secure coding best practices, security guidelines and maintaining compliance while coding the application are inviting many security risks, including breaches of sensitive data and exploitation of an individual’s identity.

    Hence, an organization must focus on enhancing the skills of developers and ensuring that they are following security best practices while their application is in the initial stages of development. Moreover, establishing and adherence to coding standards are also crucial, as they help application developers to write clean code.

    Leveraging Automation

    As we know, automation is a driving force and a key aspect in DevOps; the same goes for DevSecOps. Automating security is vital to keep up with the pace of application code delivery, especially for more prominent organizations working on various code versions. Choosing the right automation testing tools can be beneficial for organizations that wish to speed up their operations and enhance the reliability of code when it comes to security. Organizations should strongly consider using at least static application security testing (SAST) tools that help developers identify potential vulnerabilities in code in the early stages of the development life cycle.

    Early Stage Testing

    The biggest mistake for any organization leveraging DevSecOps is testing the application only when it’s finally completed. Beginning early with automated testing offers numerous advantages, including identifying and resolving vulnerabilities in early development stages, a quick and inexpensive way to fix issues and saving valuable time during deployment.

    However, testing during the early stages of the SDLC may also halt the overall DevOps development pipeline, so take that into consideration from a security perspective.

    Implementing DevSecOps

    Implementing DevSecOps isn’t a quick process and requires specific steps to get it right.

    Planning and Development

    A solid planning strategy for successful implementation must include test criteria, design, vulnerability models and analysis. Once the planning is complete, the next step is development. Development teams should initially evaluate the overall complexity and challenges of their current practices. Adding a code review system in the development process can help to encourage safe and reliable coding practices in a DevSecOps environment.

    Build and Test

    Now it’s time to build! You can use automated tools to help combine source code with machine code; many of those build automation tools offer security features like automatic vulnerability detection. Once the build is complete, rigorous testing is carried out through various automated testing frameworks that ensure the highest level of performance and security.

    Monitoring

    Monitoring is another crucial aspect of DevSecOps implementation to ensure your security mechanisms are performing up to snuff.

    Undoubtedly, DevSecOps has revolutionized the way enterprises handle security, especially in challenging DevOps environments. Businesses that want to get to the next level of agility without sacrificing robust security should be implementing DevSecOps.

  • Transform Mobile DevOps into Mobile DevSecOps

    Transform Mobile DevOps into Mobile DevSecOps

    Mobile developers are mostly focused on adding new features and functionality to their apps. Security features—such as RASP protection, obfuscation, encryption, jailbreak/root prevention and MiTM prevention—are usually addressed at the end of the development cycle if they are addressed at all. Unfortunately, most apps ship with significant vulnerabilities. One internal app test showed that most apps can be cracked within 15 minutes, and a recent academic study found that 67% of the malicious app installs came from the Google Play Store.

    An Appdome global survey of more than 10,000 smartphone consumers released in August 2021 showed that this approach—features over security—is an enormous mistake. Nearly two-thirds (63%) of consumers say they value security as much or more than features when it comes to mobile apps. Nearly three-fourths (73%) said that they would stop using a mobile app if it left them unprotected against attacks.

    The survey revealed a big shift in consumer sentiment. For the first time in recent history, consumers are on the security team’s side! They expect strong protection from threats and fraud. But meeting these expectations is extremely challenging for development teams, because DevOps and security are so often at odds. 

    Here’s why: Nearly all the work done in DevOps is automated, from GitHub to Jenkins to Fastlane, while almost all security work is manual. Sure, security software development kit (SDK) vendors position themselves as an alternative, but buyer beware. Implementing a security SDK is never just a couple of lines of code. It’s still a brittle, manual process that does not offer a guaranteed outcome.

    Mobile app security solutions available today don’t fit into the automated delivery model that is DevOps. The only way to automate security and make it fit within the DevOps workflow is to stop trying to squeeze it in at the end of the Dev cycle. As a result, security does not have a seat at the mobile app development table today. And as long as security is manual and cannot be seamlessly plugged into the existing DevOps workflows, it will remain an afterthought, at best.

    The Encryption Example: Why Security is so Hard

    As an illustration, let’s take a look at incorporating mobile encryption, an absolute necessity to protect data against harvesting, theft, interception, deception and trickery. For every type of data inside the app, developers must choose the right combination for each component of the encryption model, including encryption algorithm/protocols, cipher suites, key strength, key derivation technique, key protection and safeguarding. It has to match both the security and performance requirements for a highly variable set of data format characteristics. Even small errors or mismatches could slow app performance or render the app unusable. On the other hand, the app may perform well, but the encryption may be too weak to provide sufficient protection. 

    It’s complex, time-consuming work that developers don’t want to have to do twice. That’s why they tend to wait until after the app is built to add encryption. Unfortunately, this means all the network information is stored in the app unencrypted, and if a bad actor gets their hands on a UAT version of the app, the “keys to the kingdom” are in the clear, ripe for the picking.

    The demands on DevOps to get new releases out of the door quickly are high. Security is often seen as a negative force that holds back innovation and delays release, especially when it’s left until the very end of the software development life cycle (SDLC). The term DevSecOps is used to describe a security-focused, continuous delivery SDLC. But that should involve much more than penetration testing. Identifying issues isn’t enough. Security needs to be built into the development cycle without slowing down release times or creating uncontrollable costs.  

    The only way to incorporate security into DevOps and to achieve DevSecOps is to imbue security with as much automation as development currently enjoys. By using an automated, no-code platform that builds security directly into the app, security can become a natural part of the DevSecOps workflow. Plus, security can be consistently applied with documentation that demonstrates protection. It’s the only way to enable developers to get their secured mobile apps into the hands of their end-users at a rapid pace, align all stakeholders to a common shared set of objectives and outcomes and eliminate the sources of friction commonly found between DevOps and security teams. 

  • Relyance AI Shifts Compliance Left Using ML Algorithms

    Relyance AI Shifts Compliance Left Using ML Algorithms

    Relyance AI emerged from stealth this week to unveil a namesake platform for managing privacy and data governance in real-time within the context of a larger DevOps workflow.

    Fresh off raising $30 million in seed capital, Relyance AI co-CEO Leila Golchehreh said organizations can now quickly and accurately answer essential privacy questions and ensure compliance and governance by mapping requirements directly to their codebase. The platform provides transparency and visibility all the way down to the source code in real-time using machine learning algorithms, she added.

    Relyance AI co-CEO Abhi Sharma also noted most legal and data protection teams today have limited visibility into digital operations. Developers and data scientists are constantly creating and updating applications. By the time compliance teams gather the data required, it’s obsolete, said Sharma.

    The Relyance AI platform analyzes contractual requirements against the operational reality as determined by data processing in real-time. Compliance teams can then address privacy issues as they arise, added Sharma.

    At the core of the Relyance AI platform are five integrated components that first inventory assets by connecting to application programming interfaces (APIs); generate universal records of processing activities (ROPAs) by scanning code and understanding how data is being processed; share alerts when issues are detected; provide views into data life cycles to highlight data subject access request (DSAR) exceptions and extensions and address vendor life cycle management to ensure third-parties are complying with policies.

    Relyance AI

    Sharma said compliance, much like security, is shifting further left toward application development as organizations look to eliminate issues before they arise in a production environment. The Relyance AI platform is designed to be integrated with continuous integration/continuous delivery (CI/CD) platforms that are the core of modern software development life cycle processes, he added.

    Undoubtedly, as the worlds of compliance and application development collide, there will be cultural challenges similar to what is now occurring with the rest of DevSecOps best practices that require more collaboration between developers and security teams. The challenge is compliance officers tend to be even further removed from application development than their IT security counterparts.

    However, it’s now only a matter of time before compliance becomes code. Modern applications already make use of the Open Policy Agent, for example, to embed compliance rules in applications. AI platforms should make it simpler to identify compliance issues as they arise so that they can be addressed before any infraction ever occurs.

    DevOps teams, of course, have a vested interest in managing compliance as code. It’s not uncommon for DevOps teams to race to build and deploy an application only to encounter a wave of compliance issues that need to be addressed by recoding elements of the application. Not surprisingly, those compliance issues often result in application delivery deadlines being missed. Machine learning algorithms provide an alternative to the current raft of documents that compliance officers create, but not enough other members of the IT team read those, much less understand them.