Category: DevOps Toolbox

  • Automation is Key for Success of 5G at Scale

    Automation is Key for Success of 5G at Scale

    5G is more than a progressive step; it is a catalyst for individuals, society and industries to meet their digital aspirations. 5G goes beyond connectivity by providing a platform to collaborate across industries, and 5G networks will be at the center of an ecosystem that pushes society’s continued digital transformation forward. By design, 5G networks will be flexible and modular, with technologies such as network slicing, software-defined networks (SDN), cloud-native and cloud radio access networks (cloud RAN). A flexible architecture makes it feasible to increase overall network capacity as needed, completing the standardization of application programming interfaces (APIs) towards underlying infrastructure, which will be key for automated connectivity to a heterogeneous network. APIs have sparked a revolution in banking, finance, health care and other fields, and now it is communications’ turn.

    Communications service providers (CSPs) can’t lose sight of the imminent innovation coming from cloud and cloud-native software. 5G is where telco meets IT. Virtualization, cloud edges and containerized 5G deployment alongside a legacy network bring tremendous challenges with numerous interfaces, processes and complexities. The basic automation model that exists today will not be able to support the next-generation networks that come with a plethora of connected devices and the volume of traffic that must pass through. End-to-end, closed loop automation is going to be the catalyst that accelerates the space from network-centric operations toward customer-centric operations.

    Why Automation is Crucial in 5G

    5G drives incident-driven operations toward data-driven operations. It also drives human-triggered automation toward outcomes, triggers processes and initiates massive machine-to-machine communications. At the same time, the internet of things (IoT) has vastly increased the number of endpoints that need to be managed and, as network slicing comes to fruition, network slices will include SLA delivery models, which will be beyond humans’ ability to manage.

    As a result, CSPs must rethink the way their networks operate now and enhance their existing value-adds by complementing their existing, strong cellular expertise with software capabilities. As organizations integrate their networks with cloud assets, databases and application assets, they must focus on incorporating automation at every step to efficiently manage their 5G networks and enable new 5G offerings.

    AI/ML and Automation

    5G is evolving alongside AI and ML. The high speed and low latency of 5G along with AI and IoT are going to significantly impact the way we live and work. 5G and intelligent connectivity enable automation to go through a complete transformation from digitization to artificialization. ML is pushing CSPs from playing the role of digital service provider to becoming cognitive service providers. AI will augment human decision-making in telecommunications to achieve newer use cases. The power of AI can be used to identify features and qualities in the current environment from a large set of big data, then analyze the use cases and predict future network failures which will help to mitigate the impact of any possible failure.

    Enabling digital innovation is a high priority for CSPs as they transition from a prescriptive model to a declarative, API-driven and DevOps model. Success will ultimately depend on efforts to build the necessary organizational readiness. By leveraging cloud technology, managing risk, embracing openness and establishing a human-augmented AI model, CSPs can break silos in their network and enable this transition to happen.

    Are CSPs Ready to Embrace the New Era of Automation?

    In the 5G era, mobile will become even more central to our daily routines. According to a GSMA report, the economic value created by 5G connectivity will reach $1.4 billion by 2025 and 5G will contribute $2.2 trillion to the global economy over next 15 years.

    5G networks will require automation that can support multi-domain and multi-vendor technologies, as services such as network slicing will traverse across multiple network segments like radio, access, core and edge, which may contain a mix of virtual and physical network functions.

    On their journeys from communications service provider to cognitive service provider, many network operators today have orchestrated network and IT domains, but few have the capability to orchestrate end-to-end services, given the fact that physical legacy networks will coexist with cloud-native network functions. While network slicing and tailored connectivity are still in their early days, full automation will not happen without end-to-end service orchestration.

    To enable automation on every aspect of the network, CSPs must embrace fully interoperable, data-centric solutions that offer the visibility and monitoring that is expected of cloud-based applications. By working closely with customers, each network function can be built in microservices with fully automated testing and regression testing and by leveraging DevOps for carriers.
    5G is the catalyst that is converging telecom network engineering and operations with IT. The vast amount of data to be analyzed for insight-driven business models is forcing a cultural shift from pure network management to services management. Evolved, smarter networks, new agile and insight-driven business models all require that 5G automation be taken to the next level. Simply put, automation is not an option but a necessity.

  • Netlify Leverages GraphQL to Simplify Access to Backend Services

    Netlify Leverages GraphQL to Simplify Access to Backend Services

    Netlify this week added a Netlify Graph tool to its portfolio that makes backend services available to developers via a single click. The tool aims to simplify DevOps teams’ access to those services when building their applications.

    Netlify Graph is based on the GraphQL query language for application programming interfaces (APIs) and enables developers to integrate services such as GitHub, Salesforce and Stripe within frontend and web application development tools without any direct intervention required from a DevOps team.

    Netlify provides an application development framework based on JavaScript, application programming interfaces (APIs) and markup languages, otherwise known as a JAMstack, to isolate frontend and backend components of an application.

    Netlify CEO Matt Biilmann said Netlify Graph is based on the GraphQL technology the company gained when it acquired OneGraph. The overall goal is to make it simple for frontend developers to invoke backend services accessed via either GraphQL or REST APIs, he said. Services based on GraphQL can be especially complex for developers to invoke as they navigate the management of tokens and application secrets, Biilmann added.

    It’s not clear to what degree GraphQL APIs will supplant REST APIs. However, developers tend to prefer GraphQL APIs because they provide more granular control over what data is accessed. The challenge is the number of backend services that expose GraphQL APIs is still comparatively limited. As GraphQL becomes more widely adopted, the level of effort DevOps teams now need to expend to expose backend services should decline as tools such as Netlify Graph are employed by frontend developers.

    As a result, at least theoretically, the rate at which new applications are built and deployed to drive digital business transformation initiatives should increase. Most IT teams will not be replacing REST APIs with GraphQL-based APIs overnight, but the percentage of new applications that rely on GraphQL APIs will steadily increase. DevOps teams looking for easier ways to provide developers with simpler access to backend services now have an incentive to embrace GraphQL.

    Ultimately, Biilmann said, the goal is to enable developers to build applications without having to directly engage anyone on the IT team. Each backend service can be managed in isolation from the frontend of any application. It’s not clear how long it might take to achieve that goal, but as responsibility for the end-to-end management of the application experience continues to shift left toward developers, the need to surface backend systems-as-a-service becomes more pronounced. In fact, given the current focus on improving developer productivity, IT organizations might soon face a mandate to embrace GraphQL more broadly. After all, every minute that a developer spends on plumbing is time they’re not spending writing actual business logic.

    Naturally, it may take time for enterprise IT to be truly transformed into a set of services that developers can easily consume. But as progress continues to be made, that dream may finally be realized.

  • Agile and DevOps for Kiosks

    Agile and DevOps for Kiosks

    Alan Shimel talks with Sam Zietz, the CEO of Grubbrr and Touchsuite, about how software for kiosks can use Agile and DevOps to keep up with a wide range of hardware profiles. The video is below followed by a transcript of the conversation.

    Announcer: This is Digital Anarchist.

    Alan Shimel: Hey, everyone. Welcome to another segment here on TechStrong TV. I’m really happy to be joined by a good friend of mine today. His name is Sam Zietz. Sam is the founder, CEO of GRUBBRR. You may not know the company but Sam’s going to tell you all about it. Hey, Sam. Welcome to TechStrong TV.

    Sam Zietz: Al, thank you for having me on. Excited to see you again.

    Alan Shimel: Yeah, it’s been – well, with COVID it’s been a long, strange trip. Sam, we’ve never had you on TechStrong TV though. We’ve never really talked about the company. Why don’t we start with that. Give people a little background on GRUBBRR and maybe a little of your own background.

    Sam Zietz: Sure. So GRUBBRR is the leader in self-ordering technology. When you talk about self-ordering technology you think kiosks, mobile ordering, online ordering. And in reality, this was going to naturally occur over the next 5, 15 years. That’s before COVID hit. COVID came about and acted as a huge accelerant. So if you think about how we used to go to a bank and there used to be a teller, that teller got replaced over a 5 to 15-year period of time by online banking and ATMs.

    We used to go to the airport, and in the airport we used to see a ticketing agent. That ticketing agent got replaced by a bank of kiosks or QR codes on your smart phone. Same thing was going to happen in many verticals like restaurants and hospitality and retail, and it’s going to be a combination of kiosk, mobile and online, and that online will be the company’s website or a third party delivery service like an Uber Eats, a Grubhub, or a Postmates. What ended up happening through is COVID, and now all of a sudden nobody wanted to interact with a cashier and cashiers didn’t want to interact with consumers either.

    This was all of a sudden a hazardous position and people didn’t want to shop any longer for that type of work. So that accelerated the move towards self-ordering technology. Then Joe Biden was elected president, and one of this four pillars was this $15.00 an hour minimum wage, and regardless of where you fall out politically, whether you think it will be successful or not, he has, and whether it’s passed or not the minimum wage has increased. And right now we’re in a labor shortage on that end of the market for a combination of factors, many of which is people don’t want to come back and do those types of jobs.

    And as a result, you’re seeing especially in restaurants that they can’t even open their doors many times because they don’t have the employees. So for all of these reasons we’ve accelerated the movement towards self-ordering technology.

    Alan Shimel: Yeah. I mean, Sam, this all falls under what we call digital transformation, right? And digital transformation, as you mentioned, was well underway before COVID, but we’ve probably accelerated four to seven years of digital transformation in the last year, year and a half. And the move towards automation, which is what this is, was again well under way. Quite frankly, when we look at should we automate everything – this is a question for academics – should we automate everything, should we automate only what should be automated or should we not automate everything for the sake of preserving jobs, and whether you believe in a Star Trek future where you get a basic, whatever they call it, wage where they send you money or not, quite frankly, if a machine can do it better they don’t take sick days, they don’t steal, purposely anyway.

    Hopefully not. They’re a better employee in some regards. So if there’s a machine that can do the job better, a futurist or technologist will say by all means the machine should do the job then because that frees up people to do hopefully higher-level work, more valuable work. Now are there some people that can’t do higher level, more valuable work and what do we do with them as a society – that’s probably a discussion for another day. But the fact is that today we have the technology, to quote an old TV show, to do this, and that’s really what you guys are doing there at GRUBBRR.

    Sam Zietz: Yeah. And historically this should’ve occurred years ago. It really was restaurant owners said, “Hey, you know what? We’ve been doing it the same way for the last 20 years,” and because labor was so cheap and because the minimum wage was so low, instead of investing in technology like almost every other industry has they said, “You know what? Let’s just throw cheap labor at it,” and that’s what occurred. COVID has exposed those businesses that had not invested in technology, and quite frankly rewarded those companies that had been proactive.

    They were extremely successful during the pandemic, the ones that had digital, they had an online presence, they had these self-ordering applications already in place. They were hitting record numbers. Everybody else either exposed or permanently shut down as a result. And by the way, these aren’t jobs that anybody wants.

    Even pre pandemic, the average turnover for a cashier in this country was 150 percent annually. I think Panera put out a stat before COVID that they were at 100 percent. And they were bragging that they were at 100 percent. So they were proud of the fact that every one of their employees –

    Alan Shimel: It was only 100 percent.

    Sam Zietz: Yeah. So these aren’t –

    Alan Shimel: There’s no doubt. Look, I think we’re both saying the same thing. This is the way it was going. We just had an accelerant take place. So let’s talk now about GRUBBRR. So you guys are filling that void by developing software solutions that allow for self-ordering. And whether people are ordering online via the internet for like a third-party delivery or in person, it’s still a software-empowered transaction. Like everything else, software is leading the world.

    In your case though, Sam, the challenge is that even with self-ordering it comes in a lot of form factors. It comes in a lot of shapes and sizes. And how do you make a software that is shape and size, form-factor independent? I imagine that’s got to be a challenge.

    Sam Zietz: Yeah. Well, we’ve got talented dev people, so from my perspective it’s easy. They do all the hard stuff.

    Alan Shimel: You didn’t write too many lines of code. I get it. But the challenge is there.

    Sam Zietz: We’re agnostic on the hardware side, so we work with all of the leading kiosk manufacturers too. They bring us in for the software. Why? Because nobody’s going to buy a kiosk by itself. A kiosk by itself doesn’t do anything. It’s the software that does it. Just like your Dell computer doesn’t do anything.

    It’s the Microsoft and the other applications that you put on it, that’s the reason you’re buying the computer. So it works the same way on the kiosk. We’re agnostic. So it’s funny, we built this beautiful restaurant of the future in our headquarters here that people can come in and they can see everything in a working environment, but then after they realize we want a kiosk or we want KDS or we want mobile, whatever it is, we take them next door into our showroom and there we have everything.

    In there they can decide do we want a wall mount, do we want a tabletop, do we want freestanding, do we want a 15-inch, a 21-inch, a 24-inch, a 32 – you know, whatever they want. Do we want it in a portable fashion where it’s truly mobile? All of those options are there, but the software at the end of the day, the core that’s running it, it’s the same. It’s the same software. And you’re right, that’s exactly what we spent our time building, was software regardless of form factor that will work the same.

    And the key to this is that somebody can operate it with no training. So you don’t need to – our competitors in the kiosk space, for the most part, fall into two categories. There are POS companies that turn their POS system sideways and say now it’s a kiosk. Well, that doesn’t work. Or they’re writing an app on an iPad, and that clearly doesn’t work either. So really the advantage in which you were talking about online and now going in store with a kiosk, one of the great things about that is the marketing team and the brand owners can now curate that user experience much like they do with the online experience.

    So you can control and provide that consumer the absolute best experience, where before you had a cashier and maybe you taught them at the end to say, hey, at the burger place, do you want fries with that? Okay, and more people buy fries because the cashier asked them if they wanted fries. However, if I’m ordering a salad the likelihood that I’m going to buy fries is pretty low. However, I might take a fruit cup, I might take a healthy treat.

    So being able to, again, pair offerings to the items that that consumer would like increases the average ticket and improves the experience for that consumer. You also eliminate all the errors, right? Because now you’re putting it in yourself. How many times have you gone and said, “Listen, I’d like a hamburger – I’ll have a cheeseburger with extra ketchup, no pickles,” so they go, “Got, it extra pickles, no ketchup.” You’re like, no.

    So there’s a whole host of reasons why that experience is better and could be faster, because maybe you could only afford to put one cashier in there, but you could put a whole slew of kiosks in there for a fraction of the price of one cashier. Well now you eliminate wait times and you can redeploy personnel into the actual prep of food and improving consumer experience.

    Alan Shimel: Yep. There’s another issue I wanted you to touch on, Sam, and that is really one of the inherent advantages of modern software and whether it’s an app, think of it as an app, or it’s just portable software that’s not particularly tied to – hardwired, if you will, into the form factor of hardware, the ability to update on the fly. Right? You change your menu items, you change your price, your running specials, or I mean really, really big functionality – we’re going to start accepting PayPal or Apple Pay or Google Pay or whatever the – we’re going to start taking bitcoin.

    I don’t care how you want to pay for it. But right? We need to update that. By having it all dependent on software, not burned into the silicon, we do that as well. How does GRUBBRR handle that? Like the whole update process?

    Sam Zietz: Yeah. So first off, we can update everything in real time as well as – so we can also be notified before even the client knows that there’s an issue with software. So maybe their internet went down because their provider – there was a problem, whatever. Many times we’re calling them and saying, “Hey, your internet’s out.” Oh, wow. Somebody was in the closet and unplugged the router or whatever and, boom, it’s back up.

    But you’re talking about an entire ecosystem. So because we have the ecosystem instead of a bunch of disparate pieces of technology in there, you’re absolutely right. You make one change. So price would be an example. If we want to change up a price it changes on a kiosk, it’ll change in the POS if they’re using a POS. It will also change on their digital signage, so the menu board above.

    Great. We want to change the price. Now let’s say you’re out of avocados. Boom. Now guacamole comes off the menu, so now it’s not even on the menu board if you don’t want it to be. If you run happy hour, great. At 5:00 we change the price, at 7:00 we change it back.

    There’s none of that whiteout or cardboard being take up with those changes. We’ve also integrated –

    Alan Shimel: [Inaudible comment]

    Sam Zietz: – AI and machine learning into it, so based on weather, time of year, time of day, order frequency, items will move up or down on the menu. Because we all go left to right. So what you want to do is you want to feature the most popular items or the items that that consumer’s most likely to order at that point of time to the left so that they can then make their decision quicker and move on in the ordering process.

    Alan Shimel: Excellent. Sam, we’re running low on time. I did want to mention, I know you guys recently announced a deal with Samsung, I believe, which is probably one of the largest – I’m going to assume one of the largest kiosk producers in the world – to be powered by GRUBBRR. Do you want to tell us a little bit?

    Sam Zietz: Yeah. So Samsung is obviously a very large company. I think they’re the sixth most recognizable brand in the world. They announced on June 30th that they’re entering the kiosk space. I would bet that in short order they will probably be the 800-pound gorilla in the kiosk space. What they’ve really done is they’ve democratized it, bringing that price standpoint down so it’s affordable to everybody.

    So you’re going to have a lower price. But traditionally kiosks were kind of hobbled together. They were a shell with a whole bunch of other pieces of technology kind of plugged in to make it look like it was one thing, but it was really five or six things. Samsung has truly built one slick unit that has it all built, which has allowed them to eliminate points of failure so the unit will be more successful. Obviously nobody builds screens as effectively as they do.

    In fact, they also have it so from touching it you can’t catch bacteria or COVID or any of that. But the exciting thing for us is, again, as great as a piece of software is, no one is going to buy a kiosk unless it does something, and that’s where we come in. We provide the true value proposition that powers it, and by buying the kiosk with our software you end up reducing OPEX or labor or at least solving for labor when you can’t even find it. More importantly, you increase your revenue.

    Typically, our clients see a 12 to 22 percent uplift in average ticket because people will buy more as a result of that curated experience, and we improve customer experience. So those are the value propositions there, but it’s exciting. When you partner with somebody like Samsung it’s not just here in the US. It’s worldwide. And they’ve got unbelievable reach.

    Alan Shimel: Oh, yeah. We’ve dealt with them. I mean, just another example, no pun and no irony intended, but software is eating the world. Hey, Sam, you know what we didn’t tell people? Where can get they go get more information about GRUBBRR?

    Sam Zietz: Our website’s probably the best place, GRUBBRR.com, G-R-U, double B, double R dot com. So, yeah.

    Alan Shimel: Excellent. Alright, man. Hey, say hello to the family. Best of luck with GRUBBRR. Maybe we’ll be ordering somewhere on some GRUBBRR software soon out there. Check it out. Full disclosure. I know Sam a long time, maybe 20 years. Happy to see him doing well with this and playing in the software game. Sam, be well, and we’ll speak to you soon. Come back on and keep us posted.

    Sam Zietz: Alright, Al. Thank you again for having me on.

    Alan Shimel: Alrighty. Sam Zietz from GRUBBRR here on TechStrong TV. We’re going to take a break. We’ll be right back with our next guest.

    [End of Audio]

  • IBM ‘is Ageist and Sexist’ | IBM Mainframe-aaS | IBM Vaccine Mandate

    IBM ‘is Ageist and Sexist’ | IBM Mainframe-aaS | IBM Vaccine Mandate

    Think! Welcome to Big Blue Week here at The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: IBM’s employment practices scrutinized, IBM z/OSaaS breaks cover, and IBM encourages staff back to the office.

    1. ‘Dinobabies’ and ‘Dated Maternal’ Workforce Woes

    First up this week: IBM’s defense in an employment age discrimination lawsuit looks to be shredded. Internal emails “appear to show high-level discussion about paring the ranks of older employees.”

    Analysis: Not a good look

    According to one of the plaintiff’s lawyers, unnamed “top IBM executives were explicitly plotting with one another to oust older workers … to make room for millennial employees.” On the face of it, they seemed to be doing the polar opposite of the Age Discrimination in Employment Act.

    Noam Scheiber: Making ‘Dinobabies’ Extinct: IBM’s Push for a Younger Work Force

    Top IBM executives were directly involved in discussions about the need to reduce the portion of older employees … sometimes disparaging them with terms of art like “dinobabies.” … Documents made public by a Federal District Court … show executives discussing plans to phase out older employees.
    …
    The newly unsealed documents, which quote from internal company emails … show top IBM executives specifically emphasizing the need to thin the ranks of older workers and hire more younger ones. [One] email refers to IBM’s “dated maternal workforce,” an apparent allusion to older women, and says: “This is what must change. They really don’t understand social or engagement.”
    …
    Adam Pratt, an IBM spokesman, [claimed,] “IBM never engaged in systemic age discrimination.” [He] said that some of the language in the emails “is not consistent with the respect IBM has for its employees” and “does not reflect company practices or policies.”


    Yikes, ageism and sexism? Experienced staff are valuable, says MrBanana:

    I did some time at IBM [and] remember being invited to a meeting with a new group, headed by a new “thinker,” who had something to present to myself and a colleague. We walked past the foosball table to the meeting room. Naturally the room had no chairs, and was covered in multi-coloured Post-it Notes. Once they had gone through their mood boards and the non-linear presentation of this new idea, I turned to the other old geezer in the room. “Didn’t we look at something like this 8 years ago?”

    “Yeah, we worked out that compute power just to run the UI for one session wouldn’t be available for a couple of decades.” The children were somewhat disappointed, and (fortunately) we were never asked back to their romper room.


    But experience can be both a blessing and a curse, learned aahortwwy:

    I experienced both sides of this in five years at a company in hypergrowth. … I learned so much at that job: … In year 1, I was determined to accomplish X and ignored the skeptical comments of some colleagues who’d been at the company longer than me. I failed and wasted some time. In years 4 and 5, new colleagues were determined to accomplish X and ignored my skeptical comments.


    2. IBM Wazi as-a-Service Confusion

    “Mainframe” is not a dirty word. It’s secure, vertically scalable, and it put the VM in VMware. Now, what IBM Wazi did for on-prem LPARs, Wazi aaS promises to extend to hosting z/OS instances.

    Analysis: Mainframe-as-a-service reinvented

    Mainframes and cloud-native DevOps need not be incompatible. To modernize legacy apps using hybrid cloud instances for dev/test—and even prod—can be a big productivity boost. But isn’t it weird that IBM spun out its mainframe-as-a-service zCloud offering only a few months ago?

    Mike Vizard: IBM Shifts Mainframe App Testing to the Cloud

    While many workloads over the years have been migrated off mainframes or simply retired, the applications that run on z/OS today are still among the most mission-critical that organizations run. … IBM this week revealed it has added the ability to set up testing environments on the IBM Cloud for z/OS mainframe applications.
    …
    IBM plans to make IBM Wazi as-a-Service (Wazi aaS) for z/OS generally available in the second half of this year, [which] will enable DevOps teams to self-provision an instance of a z/OS virtual server on a secure private space running on IBM Cloud. … At the same time, it will become easier to modernize mainframe applications by making them more accessible to other applications via a set of secure APIs … using a cloud-native set of DevOps tools that run in a Kubernetes environment.
    …
    Modernizing mainframe applications is a less complicated endeavor than migrating them. The challenge is that building, deploying, maintaining and securing all the APIs required to do so represents a significant amount of effort.


    OK, boomer, why are we talking about 1960s mainframes on devopsy.kinsta.cloud? Here’s ArchieBunker:

    Mainframes are different beasts altogether, almost alien when you compare them to PC hardware. You have binaries written for the S/360 system in the 1960s? Good news you can still run them natively without a recompile.

    You think virtualization and containers are a hot topic? IBM was running multiple OS instances inside a VM in the 1970s. … The engineering is incredible.


    But z/OSaaS? It’s déjà vu time for Beleagured Greybeard:

    “Cloud Managed Services for z” AKA “zCloud” has been around for over 10 years. … IBM offloaded it with the Kyndryl spin, so its odd that they now want to re-invent it.
    …
    If it’s a strategic platform, why didn’t they hold onto it instead of spinning it off to Kyndryl? Sounds like yet more daft leadership decisions.


    3. IBM’s Return to Work Plan has Vaccine Mandate

    IBM wants to “keep employees safe” as they return to office work after being fully remote. In practice, this means a vaccine mandate.

    Analysis: IBM Digital Health Pass is divisive to vocal minority

    Although there are exemptions on medical or religious grounds, IBM has promised to place dissenters on unpaid leave. As you might expect, the policy has a few employees up in arms.

    Cassie Werber: How Salesforce, IBM, and HSBC are approaching return to work

    When the pandemic hit, and IBM moved 95% of its workforce to fully remote, it was pleasantly surprised to discover no drop in productivity. … Still, they planned to return to offices.
    …
    The company saw this as a way to keep employees safe. … One example … is its development of the IBM Digital Health Pass as an alternative to vaccine cards or paper vaccine certificates, which they use to make sure all the staff that come into their offices are vaccinated.
    …
    Arvind Krishna, IBM’s CEO, meanwhile came up with what he called the IBM Work From Home Pledge. [It] included commitments to flexibility, kindness, sensitivity to family, setting boundaries, and acknowledged video fatigue. It concluded with a commitment to “be connected.”


    Tricky to “be connected” if you’re not allowed back in the building. Anne D’Innocenzio, Heather Hollingsworth, Tali Arbel, Mae Anderson, Ken Sweet, Matt O’Brien and Dee-Ann Durbin:

    IBM software engineer Justin Albano said his company recently notified employees that it would be revoking badge access to workers who aren’t vaccinated or haven’t proved that they are. “We’re not able to enter an IBM office at this time,” said Albano.
    …
    He said some workers have successfully sought religious exemptions but “my thought process was I shouldn’t have to explain to my company my faith” to get out of a policy that’s “immoral in its foundation.”


    What’s the alternative? With a perspective, it’s Chris Haney:

    Or, get the vaccine. Protect yourself and the people around you. You people really are detached from reality.


    The Moral of the Story: Those who know do not speak; those who speak do not know.


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Marcin Wichary—cc:by; leveled and cropped (ask your parents)

  • Cloudify Integrates DevOps Automation Platform With Terraform

    Cloudify Integrates DevOps Automation Platform With Terraform

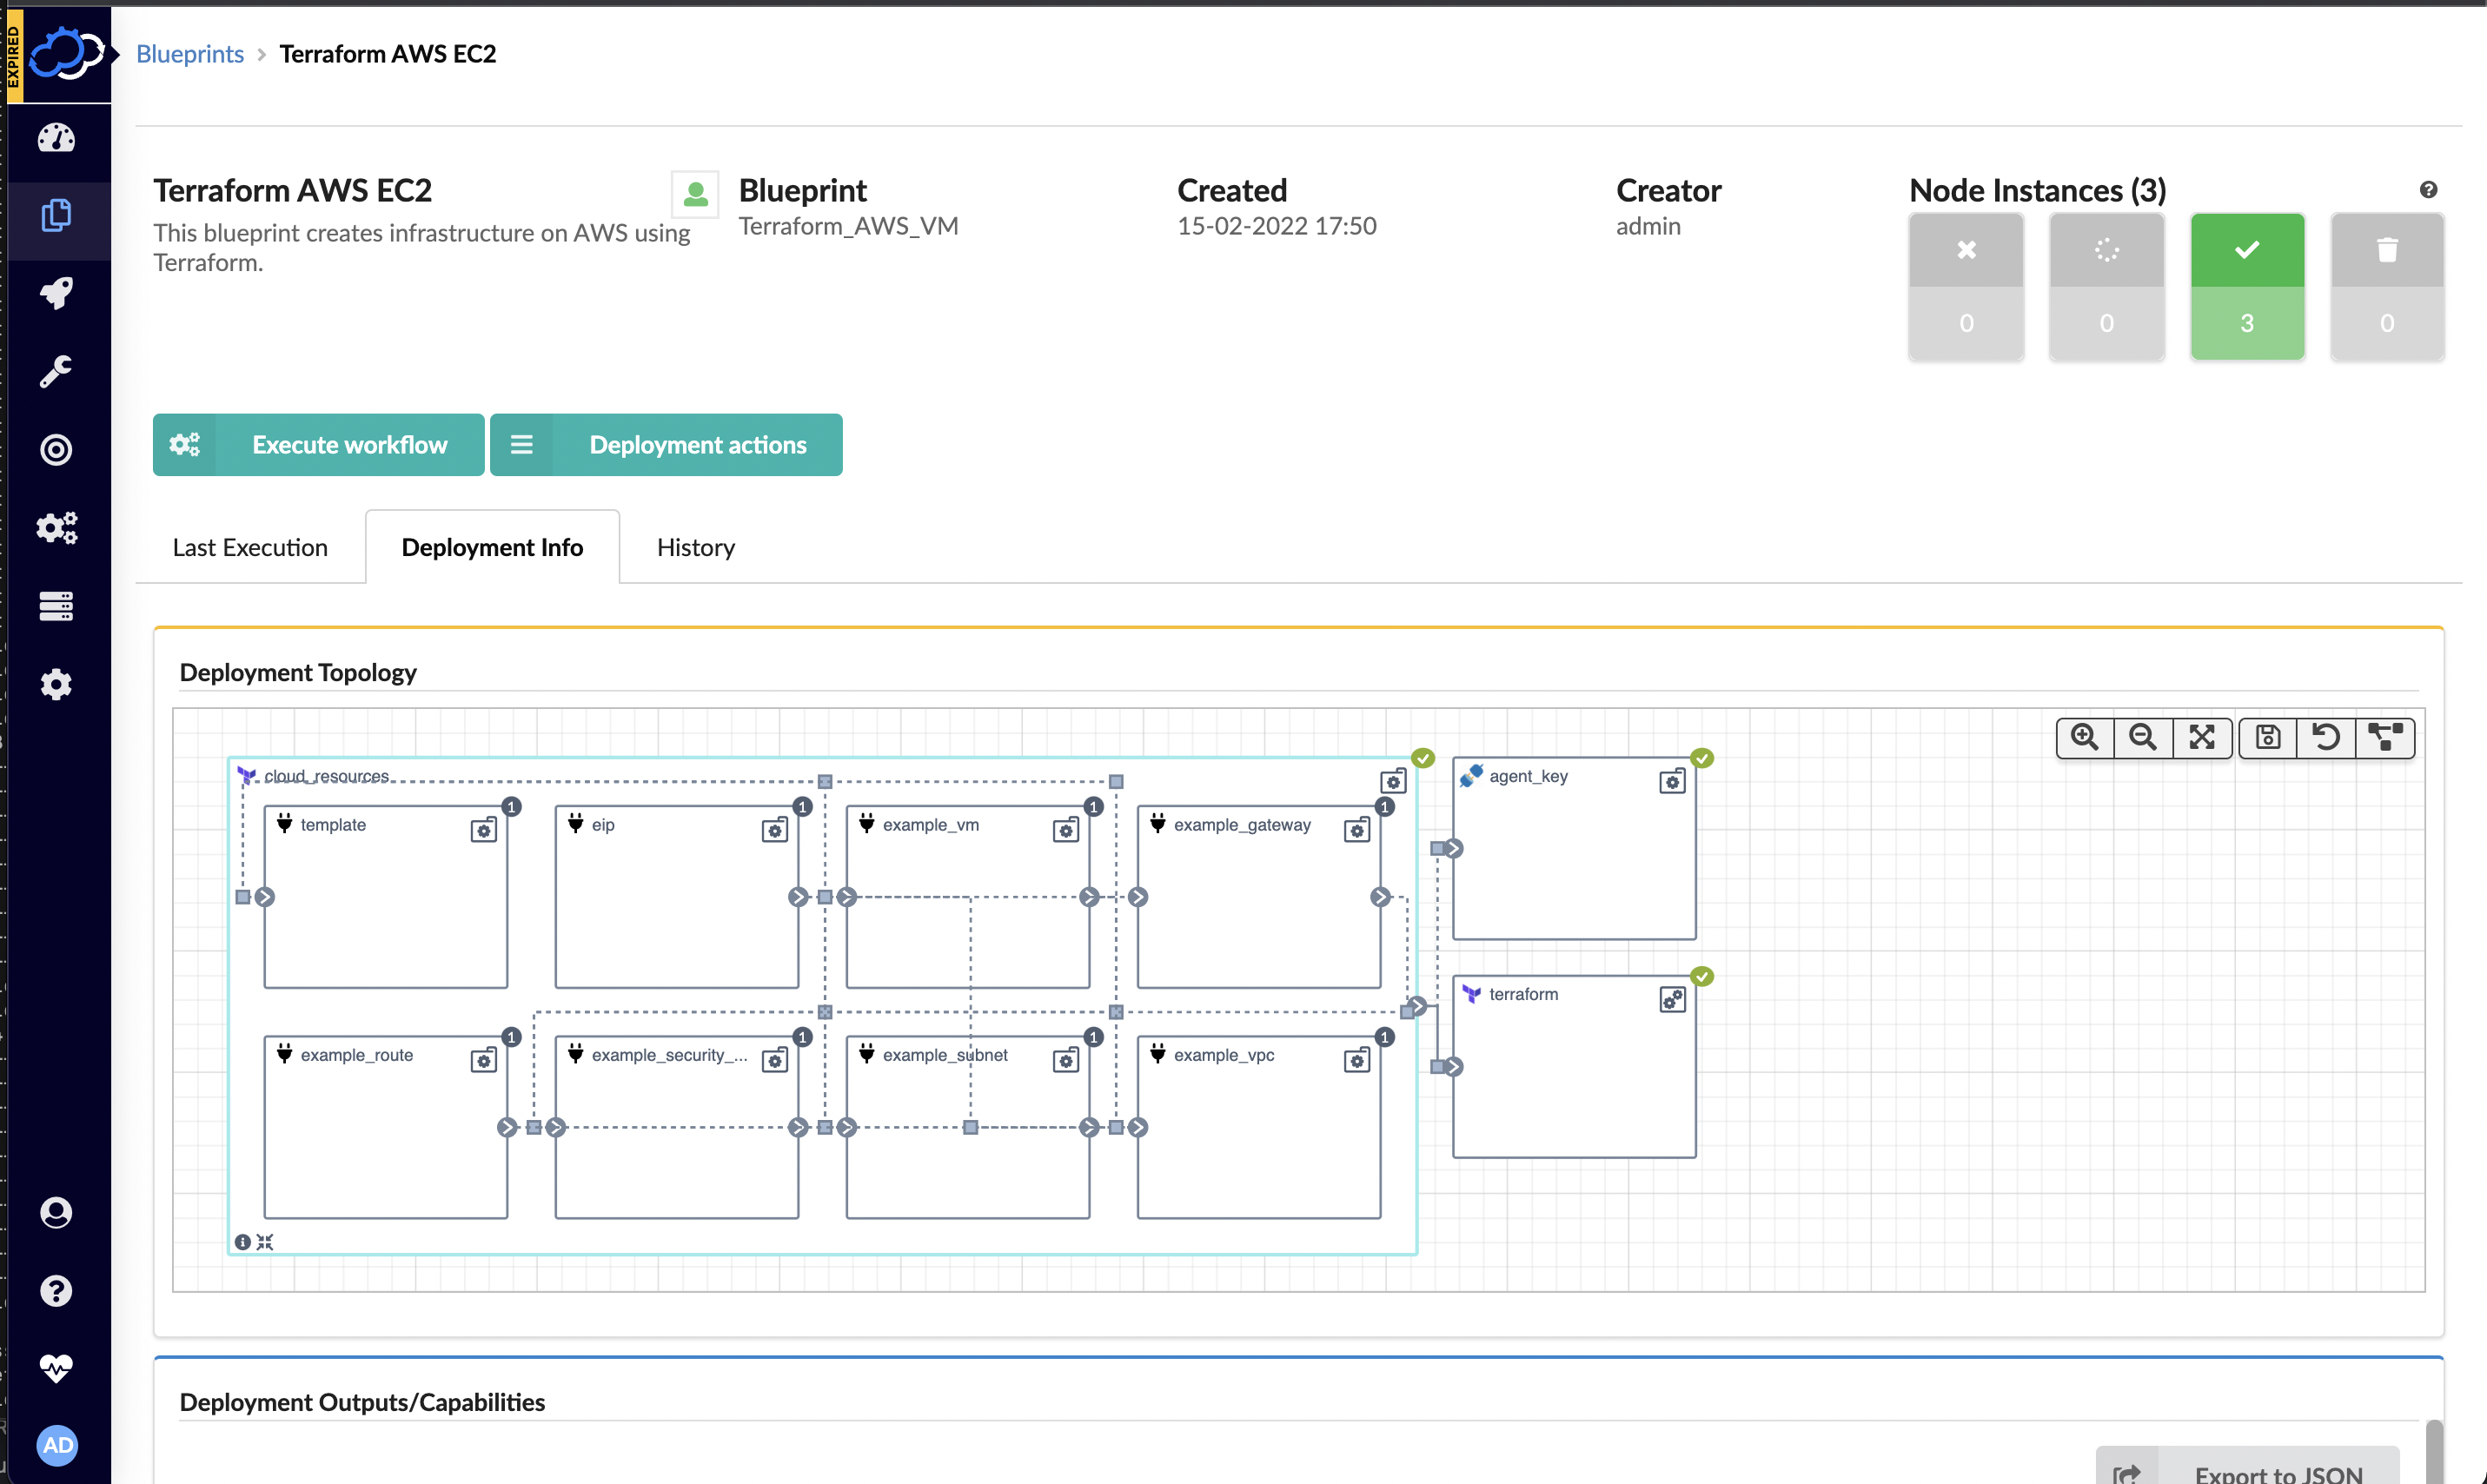
    Cloudify this week announced a free user interface (UI) module that extends its infrastructure provisioning platform and enables DevOps professionals to integrate unlimited Terraform modules.

    Nati Shalom, Cloudify CTO, said Terraform UI provides a familiar construct for DevOps teams using the open source DevOps automation platform to provision infrastructure-as-code (IaC). The module enables DevOps professionals to seamlessly import Terraform modules to Cloudify without writing blueprints or any additional glue code, he said.

    Cloudify now automatically generates the wrapper required for each Terraform template to enable DevOps teams to collaboratively manage secrets, execute concurrent deployments, store states remotely and monitor deployments, users and versions via any Git repository. Those Terraform modules can then be integrated with application programming interfaces (APIs) and continuous integration/continuous delivery (CI/CD) platforms as DevOps teams require.

    DevOps teams can also import existing automation modules and scripts into Cloudify. Those modules and scripts can be automatically converted to environments that can be centrally managed via the Cloudify console or via export to ServiceNow’s IT service management (ITSM) platform as a software-as-a-service (SaaS) application.

    That approach provides the added benefit of enabling DevOps teams to centrally manage all Terraform modules and versions via a single console as part of an effort to reduce misconfigurations that lead to security breaches, he added.

    Cloudify enables DevOps teams to create a self-service catalog and portal through which infrastructure can be managed. Many DevOps teams have built their own portals to manage this process. However, Shalom noted those DevOps teams then need to devote resources to maintaining that portal when those resources could be allocated to other critical tasks.

    DevOps teams can not only use Cloudify to apply patches, change topologies, add security features, make configuration changes or make additional resources available, Shalom added, they can also now integrate Terraform tooling with platforms such as Kubernetes or other automation frameworks such as Ansible. Cloudify also makes available an enterprise-grade version of the platform with these integrations.

    It’s not clear how much time and effort IT organizations are investing in building and maintaining DevOps environments. In many cases, however, organizations should probably revisit decisions about building capabilities that, at the time, didn’t exist. That doesn’t necessarily mean that replacing custom DevOps tools makes sense across the board, but it is likely that, in the intervening years, the range of tooling made available via DevOps platforms has greatly expanded. Relative newcomers to DevOps, meanwhile, are enjoying the benefit of platforms they did not have to construct themselves.

    In fact, Shalom noted that, in terms of DevOps adoption, an inflection point has been reached as more organizations launch digital business transformation initiatives that require applications to be both built and deployed faster than ever. The challenge, of course, is enabling that to occur both safely and at a reasonable cost.

  • Watch Your Language(s)

    Watch Your Language(s)

    Just about every organization I am familiar with today is using more languages, frameworks, libraries, etc. than they were a decade ago. Back then, most organizations were doing a lot of Java, and maybe a little bit of PHP or .NET (almost always VB.NET). Now we have Java, Python, Ruby, Go, Swift, etc. And etc., etc.

    The problem is that employees don’t come pre-instructed with your selection of languages. Most developers can bring Java or Python and most know at least one other language well. All of them can learn (more on that in a moment), but when hiring, an organization needs to focus on the one or two languages the hiring team is using, not all the languages an organization might ask a developer to learn over the course of their employment. After all, when hiring 20 years ago, the tools of the mainframe team weren’t generally listed as requirements for a desktop developer. While there is a difference (desktop developers were only asked to work on mainframes when the shortage of experienced big iron devs got really bad), it is a similar situation today.

    You can hire with an eye to training, and most developers will be more than willing to pick up a new language and learn its ins and outs. But ask any manager that pays close attention, and they’ll let you know that there is a huge difference between time-to-productive and time-to-proficient. One manager told me that any programmer with experience could start contributing relatively quickly in Ruby, but to do the important stuff—things like knowing which array access methods were faster and the most efficient communication between Ruby and other languages—took far longer. His numbers seemed too high, in my opinion and based on my experience, so I asked around. All the managers I know that worked with Ruby (because to a great extent, this is language-dependent, so I didn’t want to make hasty generalizations though, in hindsight, the same data point in Python would have given me more responses) agreed there is a curve, and the range was somewhere between six months to two years. This is strictly anecdotal, but it seems the more technical the team in question, the longer the manager thought proficiency would take.

    But even if the lower number is accurate and applies more generally, it is an argument for keeping your language count down. Yes, some languages are better at X or Y or Z than others, but most modern languages can do just about everything an average enterprise team will ask of them. So, keeping languages within a smaller pre-defined set still allows teams to choose the best tool for the job while keeping the number of skills developers at the organization might need down to a manageable level.

    And keep wowing them. No matter what languages you are using, your user base is logging in and using the results daily—or perhaps your devices are reporting the results daily or processing them. No matter how you are delivering, you are, as our digital world shows. Keep rocking it, and do what you can to keep the number of languages under your roof down.

  • Using Data Fabric for Real-Time Processing

    Using Data Fabric for Real-Time Processing

    Charlene O’Hanlon and Scott Gnau from InterSystems talk about silos in organizations and how data fabric enables organizations to process, transform, secure and orchestrate data from disparate sources in real-time. The video is below followed by a transcript of the conversation.

    Announcer: This is Digital Anarchist.

    O’Hanlon: Hey, everybody, welcome back to Tech Strong TV. I’m Charlene O’Hanlon, and I’m here now with Scott Gnau, who is the VP of Data Platforms at InterSystems. Scott, thank you so much for taking the time and getting on the call with me, I really appreciate it.

    Gnau: And likewise—thanks for having me. It’s great to be here.

    O’Hanlon: Alright. So, tell me a little bit about InterSystems.

    Gnau: InterSystems is a creative data technology company, we’re based in Cambridge, Massachusetts. We’ve been around for about 40 years, and we actually build data integration, data platform technology that’s used by a lot of very sophisticated applications around the world—in fact, more than half of medical records in North America go through our systems, 15 percent of global equity trades touch an InterSystems data platform or interface along the way.

    So, we’re known for solving very large, complicated, business critical problems that are centered around data.

    O’Hanlon: Well, data is the new oil, right, is that what I’ve heard? Time and time again, so many companies now rely on the data to make their business decisions and find areas of opportunity and so much more just, you know, ways to do their business better. So, data—you guys are definitely in the right space, for sure.

    Gnau: Absolutely.

    O’Hanlon: [Laughter] So, let’s talk a little bit about, then, the issue of silos when we’re talking about data and access to data, especially when we’re talking about things such as customer experience or uncovering those opportunities within the business, whether it’s improving internal processes or external applications and issues and things that do touch end users.

    So, we’ve been talking for a long time about breaking down silos when it comes to data, but do you think that that’s something that’s feasible or do you think that it’s kind of one of those wishes that will never really come true?

    Gnau: [Laughter] I’ve kind of given up on the breaking down the silos, and I’ll back into that with, you know, I’ll hit on a couple of things that you said. Because I think some of the things you said are actually really, extremely relevant, right? Data being the new oil and, you know, people have been saying that, and it’s absolutely the case. If you look at the wealth that was created in the 18th Century, it was railroads, and if you look at the wealth that was created in the 20th Century, it was energy and oil, right? Look at the wealth that’s been created in the last 20 years. It’s all about data centric kinds of companies, right?

    O’Hanlon: Right.

    Gnau: And that’s a really cool thing. And the difference really is, you know, companies can leverage that data not only to understand their business and have a rearview mirror view of what happened in the business and be able to make better decisions about it, but actually synthesize that data into building new businesses for themselves and new ways to interact with customers and so on. So, it’s absolutely critical and important.

    And sadly, I’ve been in industry, I guess, about 35 years. It feels like just five, but a long time. And throughout that career, we’ve been talking about how do we break down silos in data and silos in data processing? And, you know, silos crepe up for many different reasons. They can creep up because you’ve deployed an application that’s very specialized to go solve a problem that’s extremely important and the data that gets collected is kind of in that application and not shared easily, and that becomes, eventually, a silo in and of itself.

    Certainly, there are business model and political silos that get created, right? I’ve got a business unit model and the mortgage folks don’t wanna talk to the consumer lending folks don’t wanna talk to the deposit folks and so on. And it’s also very easy for silos to build up because of geographic differences in the business, right?

    O’Hanlon: Mm-hmm.

    Gnau: And so, this has been going on for a long time, and for a long time, we in technology have tried to solve and advise our clients, “Hey, don’t let silos control you.”

    O’Hanlon: Right.

    Gnau: I would say that the problem of silos and how they come up has actually gotten larger and is increasing at almost an unimaginable pace. Certainly, with the advent of the cloud and microservices and easy to spin up applications, more and more silos can come up very, very quickly. The fact that data and relevant data, the oil of our businesses used to be created inside the business, inside the firewall by our application, so we actually had some semblance of control over it. Now, a lot of the data that we need to use, understand, consume, and drive decisions from may live its entire life cycle outside the firewall of our business and out of our control.

    So, you think about one of the drivers of silos, and it just has now gone kind of exponentially very different.

    O’Hanlon: Mm-hmm.

    Gnau: Certainly, the pandemic has created more geographic silos, but also, the need to be able to deploy data and decision making very quickly as many of us have been remanded to our home offices and trying to manage customer relationships and run our businesses remotely in a new and a different way.

    So, I think kind of the drive for silos is going to continue to increase. And so, I think it’s also then unimaginable to think that we will live in a world without data silos. So, if that were the case, it’s kinda like, how do we come up with an approach that lets us leverage and build beyond that?

    O’Hanlon: Yeah. So, you know, it’s a very good point that you make, the fact that we’ve had so many silos, the number and the velocity of silos has increased multifold, I would imagine, since the onset of the pandemic. And with this remote and hybrid work environment that we’re now entering into, I don’t think those silos are gonna be going away.

    So, short of I don’t know what, short of whatever an organization needs to do to break down those silos, how can an organization work effectively to access that information and to get the information they need and really kind of make the most of it without being able to break down those silos? Is there a way that they can still utilize that information as effectively as they could if there was—you know, if everything was kinda linear and they could just kind of skip across the data meadow, if you will, and kinda pick the flowers as they went along? I don’t know where that analogy came from, but [Laughter].

    Gnau: Well, listen, it would be less interesting if it was equally kind of a serial thing when you go pick up those flowers.

    O’Hanlon: Right, right.

    Gnau: And certainly, we talk and work with our clients, really, about this concept that we call the data fabric and a lot of technology ins and outs and all that kinda stuff with data fabric, which we probably won’t get into a lot today, but it’s almost at a mindset. And the way I describe it, being a pilot myself, is—think about being able to have a control tower kind of impact to how you manage and integrate your silos.

    So, think about control towers in flight, right? What is the purposes of having control towers? Well, obviously, the mission is to provide safe flights. How do they do that? Well, they connect different kinds of data together and synthesize that data for decision making, right? They don’t consolidate it, they don’t fly the planes, necessarily, but they collect that data and then disseminate it in a way to kind of control and coordinate the flow.

    O’Hanlon: Right.

    Gnau: They also, it’s not a single point of contact kind of consolidation, right? There’s a control tower at every airport, right? And they connect to each other as well to manage traffic between their segments and sectors in that grid. And so, the notion of control tower is a way to think about, how do you apply that technologically speaking into thinking about your infrastructure more as a data fabric and the things that are necessary from a mindset—again, not a specific technology or a vendor, necessary—but just a mindset of how to manage through the notion of silos.

    And so, the first thing, really, is something that’s also kind of nontraditional in data processing, at least during my career, it’s all about connecting data and not consolidating data, right? And for many years, it was like, “How do I consolidate all this stuff into one place to make it more manageable to take cost out?” and all that kinda stuff. Again, in a cloud-centric world, almost unmanageable.

    O’Hanlon: Mm-hmm.

    Gnau: So, instead of thinking about consolidating it, really think about how do you connect the different data across different places? And that obviously becomes a key part of your data fabric—the connectivity, the pipes, and the widgets, and how they fit together. Connectivity isn’t enough without context.

    O’Hanlon: Mm-hmm.

    Gnau: So, data that’s created in the silo may have a certain context inside of the silo, but that context needs to be reflected externally just like the control tower needs to understand what kind of plane you’re flying, because they’ll understand the operating capacity of that plane—how fast does it go, how high can it go, and what are its maneuvering capabilities, right?

    Same kind of thing in a control tower kind of aspect to data fabric—connect the data and provide context for the data so that, as the data get connected, there’s some relevance to what is happening and something could actually be derived from it.

    O’Hanlon: That makes a whole lot of sense, and to your point, having the data remain kinda siloed and just being able to kinda select the data that you’re looking for, you know, that’s most relevant to you at that time, I imagine actually, is a little bit easier than kinda sifting through an entire haystack for one little needle. So, that’s a really interesting concept.

    Is this a technology that is currently being used within the data management space, the data science space?

    Gnau: You know, there are more and more people talking about it, and I’m sure there’s some folks that maybe have different words to describe it. We’re thinking, and some of the analysts that we work with as well, are talking about the data fabric. I’d say first and foremost, it’s a mentality, but like I said, connect, don’t consolidate. Provide the context. Have the control towers communicate amongst themselves so it’s not a single control tower but multiple different control towers for the context or the application that’s required and kinda think about the network effect of being able to build that out.

    Once you have that mentality, then it comes down to a checklist of, you know, certainly a list of what is the existing technology that we have and what is the existing technology that we use, how are the data created, how are the data stored—you know, kind of just a roadmap of what ya got. And then, think about the connectivity and the context provisioning that you want to create and look at other technologies that might need to be added to the mix to make that work in an end to end state.

    So, it’s a mindset first, and then it’s a collection of some technologies to enable that, and it’s a combination of the existing stuff that you’ve got, and certainly, an application that’s been deployed in a business-critical nature, you’re not gonna yank that out for some technology decision. So, again, it’s all about that connectivity and fitting it together and piecing it together.

    The other thing that most of the clients that we’re talking with about this are very pragmatic, it’s not a—like anything ever really should be, it’s not a 10-year plan, but it’s an, okay, how do I map this sector? How do I put a control tower at this airport and this airport and how do I leverage that, right? So, how do I go connect this silo and that silo, and then let’s go get the next silo and let’s go get the other business unit and figure out how to kinda build that out over time.

    And what’s really cool is, the value accelerates as you start to collect more of these things together. And, you know, you’ve got three or four and then you add the fifth one—the value doesn’t go up 20 percent, the value actually, of what you can do with that can go up dramatically, much higher, because of being able to understand all of the customer interaction points and create new programs, or leverage that data to actually go build a new line of business that your customers weren’t expecting.

    O’Hanlon: Mm-hmm. Right, right. Interesting. That’s really, really fascinating to me. Now, does this also kinda democratize the data? Does it enable other parts of an organization to access the value from a lot of this data by using this data fabric without the need for maybe a data scientist or somebody who’s a specialist in this in an organization?

    Gnau: Yeah, absolutely, absolutely. And again, it’s a mentality and needs to be kind of thought of with a design going in, right?

    O’Hanlon: Mm-hmm.

    Gnau: So—right, in today’s world, thinking about security and privacy on one plane and then democratization of data on the other plane, they’re almost kind of at odds. So, there needs to be some forethought that goes into what is appropriate for the appropriate eyeballs in these different spaces, and then again, making sure that the technology stack that’s been built out has the capability to deliver that. But certainly, companies that—in my experience, at last, companies that have the most success in kind of refining their oil, their data, are the ones who are actually getting data anywhere that the data need to be for a decision that’s local, right?

    So, you know, people talk about real time decisions and real time AI models and all that kinda stuff. All really compelling, all really valuable, but all completely worthless if you can’t leverage that to deliver a yes to a customer when the customer asks a question, right? And so, democratization and the architectural democratization of the data is an important key component to making your data fabric really successful and really showing up with a lot of value for the business.

    O’Hanlon: And I would imagine that AI, machine learning—you know, those technologies can actually add a whole lot to making this a much more intelligent way of gathering data as well.

    Gnau: Yeah, and it’s a symbiotic relationship, right? So, you know, machine learning and AI are all the rage and all really good stuff. A lot of the math behind it is not particularly new. What’s interesting is, the math behind it dictates that the more data you add to the model, the more accurate the prediction becomes, right? And that is very different than some of the previous kind of data mining and data science stuff that went on.

    And so—okay, that means you need lots of data. How do you get lots of data? Well, you don’t if it’s in a bunch of silos that don’t talk to each other with no context and no connectivity.

    O’Hanlon: Right.

    Gnau: So, I actually think they’re kind of symbiotic in that an effective data fabric could actually enhance the capabilities of your AI programs, and your AI programs can actually enhance the value of your data fabric in return.

    O’Hanlon: That’s really, really fascinating. [Laughter] I love this topic. I think this is definitely something that more organizations should be considering, because you know, especially if you think about just the sheer volume of data that’s out there and, I mean, really, what organization today is not basically putting their entire business on the shoulders of data without having that information that they need to make those business decisions to uncover those opportunities to just basically survive and thrive in today’s environment. I really—short of having that data, I just don’t know how organizations today can do it.

    So, I think anything that’s going to make it easier for them to uncover those areas of opportunity and find those nuggets of information that’s in all of that data, I think, is gonna be a huge, huge value add for organizations.

    Gnau: Yeah. I mean, and the last piece, really, of success for a data fabric and why I think data fabric is so important—I tried to come up with something that started with a C, because I said connect and then context. But the last one really is lineage, because lineage creates trust.

    O’Hanlon: Mm-hmm.

    Gnau: So, you know, it’s interesting, the other interesting thing about some of the AI models out there is that the answers they create are actually sometimes not intuitive.

    O’Hanlon: Right.

    Gnau: And as human beings going to execute these things, we’ve gotta really trust that the models and the data are effectively connected, so that we’re gonna risk our business on these decisions, right?

    O’Hanlon: Yep, yep.

    Gnau: And so, you know, connectivity, context, and ultimately lineage or trust of the data are kind of the three key components, again, of the mentality. Nothing to do with technology, but you’ve gotta kinda build in what’s your framework, what’s your appetite in your business for these pieces and then go look at the technology landscape to start building it out.

    O’Hanlon: That’s a very intelligent way of going about that, too, so—I love that. Scott, thank you so much for having the conversation with me about data fabrics. I know we’re gonna be hearing more about it in the future. I think it’s a great mindset and a great way to approach data access and data use in an organization. So, thanks again for your time and your expertise, I really do appreciate it.

    Gnau: Thank you.

    O’Hanlon: Yeah. Alright. Alright, everybody, please stick around, we’ve got lots more Tech Strong TV coming up, so stay tuned.

    [End of Audio]

  • Kong Enterprise 2.7 Simplifies API Management

    Kong Enterprise 2.7 Simplifies API Management

    Kong Inc. this week advanced its service connectivity platform strategy with an update to Kong Enterprise that makes it simpler to collectively manage groups of application programming interfaces (APIs).

    Michael Heap, director of developer experience for Kong, Inc., said that capability will make it simpler to, for example, assign rate limits to different tiers of APIs.

    In addition, Kong Enterprise version 2.7 adds support for real-time and event-based use cases involving the open source Kafka streaming platform and webhooks. Usage of event-driven architectures is rising as more organizations embrace digital business transformation initiatives that require near-real-time processing versus relying on traditional batch-oriented applications, noted Heap.

    Finally, IT teams can now also securely store secrets such as user names/passwords, API tokens, database credentials and private keys that might be used to access Kong Gateway. An improved user interface for Kong Manager UI makes it simpler to configure the Kong OpenID Connect (OIDC) Plugin for the Kong Gateway.

    Overall, Heap said, the latest update also provides 25% increased throughput and improved latency. In tests run by GigaOM, a third-party research firm, Kong Enterprise 2.7 achieved 52,250 transactions per second (TPS) maximum throughput with a 100% success rate.

    Kong is making a case for a service connectivity platform that enables an IT team to manage APIs at a higher level of abstraction by integrating all Layer 4 through Layer 7 services for both monolithic and microservices-based applications. Rather than having to manage an array of networking services and associated services in isolated silos, that layer of abstraction makes it simpler to manage distributed applications that have dependencies on a wide range of APIs.

    In general, the number of APIs that organizations are using both internally and externally has expanded tremendously over the last several years. The challenge now is finding a way to not only manage and secure all those APIs but also retire them as new services come online. Many APIs are created and simply forgotten about because their developer neglected to inform IT operations of their existence. Those so-called “zombie APIs” then become a cybersecurity liability when cybercriminals discover they can surreptitiously exfiltrate data via those APIs.

    APIs are, of course, an integral element of any software supply chain. But as high-profile security breaches put software supply chain security in the spotlight, it’s only a matter of time before IT teams look for more efficient ways to manage and secure APIs at scale.

    Inevitably, that also means organizations will need to decide how much they want to rely on proxy software, API gateways and service meshes to achieve that goal within the context of a larger service connectivity platform.

    In the meantime, the days when APIs were managed in isolation from the rest of the IT organization are coming to an end. The only thing left to determine is how involved API developers need to be in their ongoing life cycle management.

  • Codenotary Launches Cloud Service to Generate SBOMs

    Codenotary Launches Cloud Service to Generate SBOMs

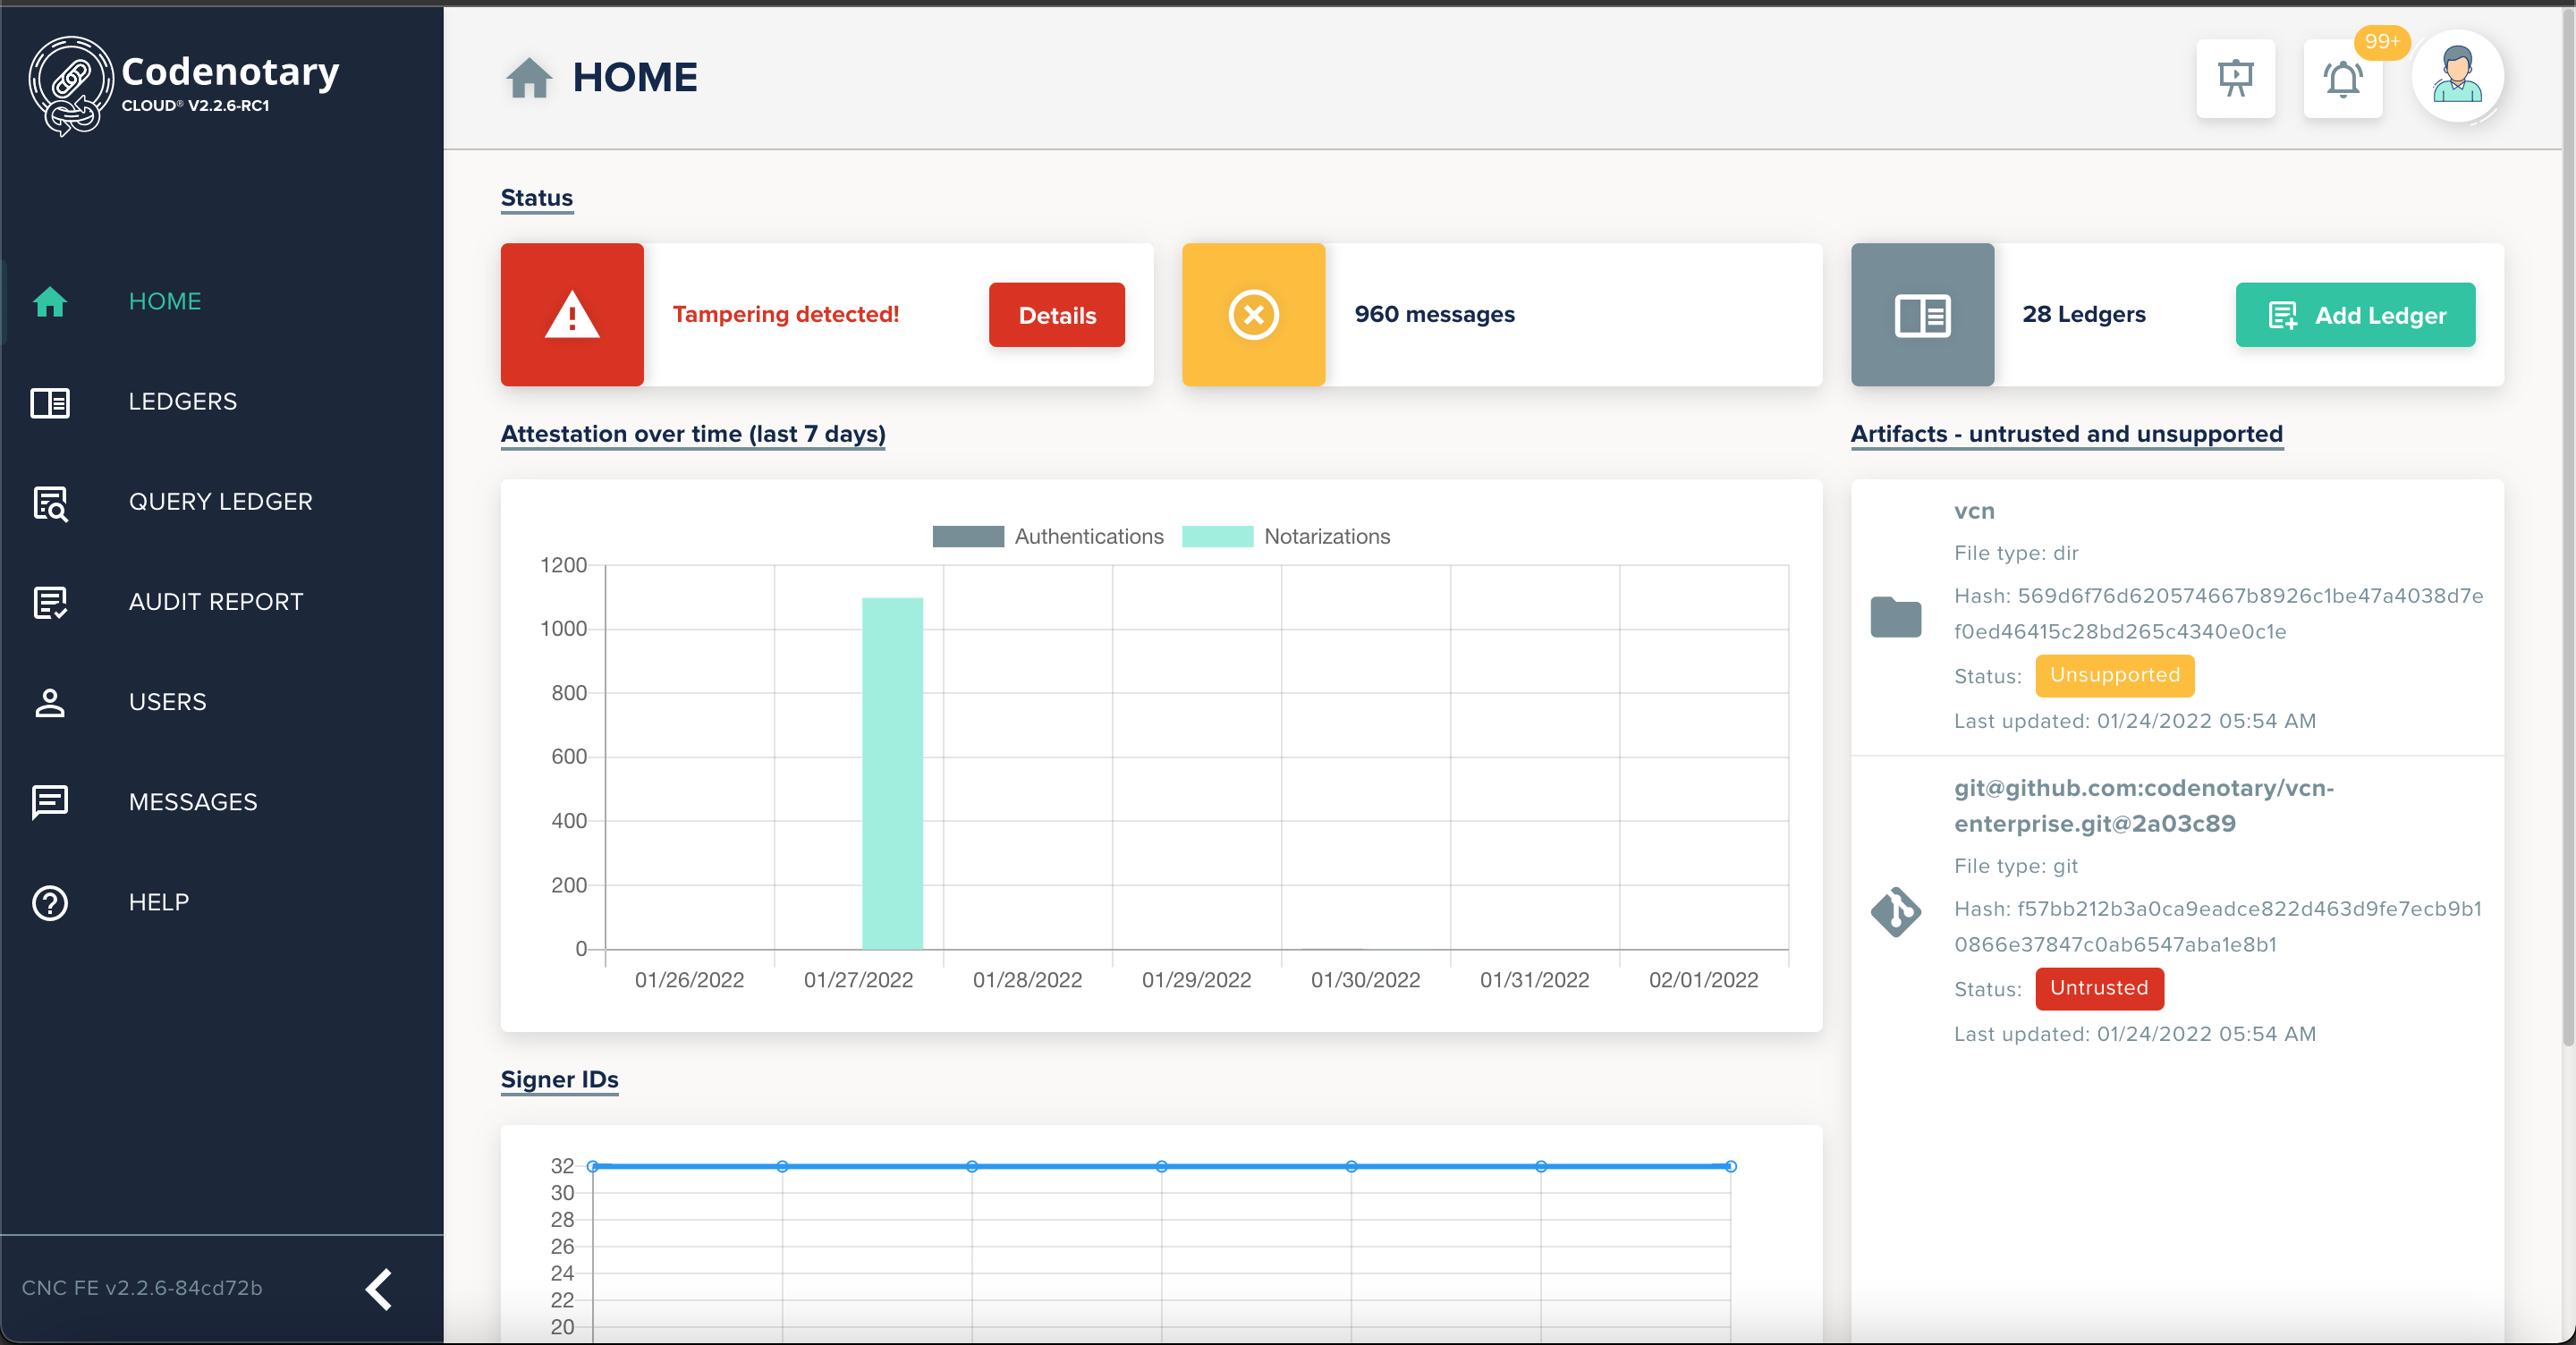
    Codenotary has launched a Codenotary Cloud platform that can automatically generate a software bill of materials (SBOM) and make it easier to discover what components have been included in an application.

    Moshe Bar, Codenotary CEO, said that capability can also play a key role in identifying which components in an application might contain, for example, the Log4jShell vulnerabilities that were recently discovered in Java applications.

    That capability can reduce the time required to remove insecure artifacts by as much as 80% simply because organizations are not dependent on scanning tools to search for vulnerable components, added Bar.

    Codenotary Cloud is based on an immutable open source immudb database that cryptographically attaches an identity to each software artifact. In the wake of a series of high-profile breaches, there’s now a lot more focus on the integrity of software supply chains. In fact, the Biden administration recently issued an executive order requiring all federal agencies to, among other things, make sure an SBOM is available for all the software they use.

    Codenotary claimed Codenotary Cloud can scale to millions of integrity verifications per second across source code, builds, repositories, Docker container images and Kubernetes deployments in a way that doesn’t require DevOps teams to upload data to a centralized platform, noted Bar. That makes it possible to notarize and verify the provenance of all the code being employed, he added.

    Codenotary Cloud can also be fully integrated with most vulnerability scanners and popular cloud-native continuous integration/continuous delivery (CI/CD) systems running on any cloud or on-premises host via a managed service. Pricing starts at $5,500 for a workgroup of 10 developers.

    It’s not clear to what degree the Biden administration’s executive order will improve overall software security. There have been multiple vulnerability issues over the years that have not resulted in any material change in how organizations manage their application development processes. However, the executive order issued by the Biden administration, coupled with a recent summit on the state of open source software security, means more senior business and IT executives are at least aware of growing concerns.

    The one thing that is certain is there will be more zero-day vulnerabilities discovered. Developers today routinely reuse open source software and free components maintained by a small number of volunteer programmers. Like any other developer, the amount of security expertise those individuals have is limited. Many organizations reuse that code without contributing anything meaningful back to the project—either in terms of financing or vulnerability identification and remediation support. Contributors to these projects freely donate their time and expertise to build these components. Many of those contributors feel the onus for securing the software they created is on the organizations that decide to deploy that software.

    Regardless of who is responsible for security, it’s apparent cybersecurity teams are going to be reviewing application development processes. Theoretically, that should benefit all concerned and lead to DevSecOps best practices being more widely adopted.

  • How Does IT Management Govern EverythingOps?

    How Does IT Management Govern EverythingOps?

    The number of tools engineers use to provision software architecture in the cloud is starting to get a little out of hand. There are many competing ways to do one thing. Most often, people simply adopt a new tool to solve a DevOps problem in the moment, not always considering the longevity of the solution or how other departments are handling it. This could result in fragmentation and technical debt, making it difficult to find consistency and increase speed simultaneously across all company divisions.

    I recently interviewed Jeff Kukowski, CEO, CloudBolt Software, to explore why these issues persist and how executives should approach cloud management within their organizations. According to Kukowski, many flavors of Ops now permeate large companies. Different approaches often exist per department or interdepartmental, with teams using various software stacks.

    According to Kukowski, a new frame of mind will be necessary to remain agile in the new cloud order and to address this state. Doing so will require organizations to erode false dichotomies around ownership and IT governance.

    Everything’s Going Ops

    At this point, most large suites of digital services have adopted a complex hybrid and multi-cloud modality. And many teams have embraced their own unique form of DevOps to get a handle on the management difficulties of delivering software and maintaining reliability for microservices architectures. Different groups pulling in various directions create an ongoing battle of EverythingOps, explained Kukowski.

    You can think of it as separate Ops approaches emerging around different business functions. For example, FinOps is emerging to control spending, ITOps is about delivering services, DevOps is improving release fluidity and DevSecOps aims to bring security to the forefront of the release process. Lastly, BizDevOps is about increasing observability for business outcomes.

    At a high level, CIOs have committed to digital transformation to move quicker. Yet the problem now is “battles between different Ops can easily lead to broken IT governance,” said Kukowski. This tension introduces several false dichotomies, he explained. In addition to slowing agility, a lack of DevOps unity eschews reusability, contributing to waste and increased IT expenses, said Kukowski.

    Solution: Shifting Governance Left

    There is a belief in IT that true innovation will come if you only give engineers the keys to use anything they want. While that may be true, without better leadership with regard to the basics in this new cloud order, some things can get out of control very quickly, Kukowski warned. Instead, he argued that built-in guardrails for provisioning tools are necessary. “We have too many tools—we need better frameworks to tie this together.”

    Not only would increased cloud governance help tie together disparate tooling decisions, but Kukowski argued it also can reduce the cognitive load necessary to onboard each tool. “Shifting left will increase speed—it won’t slow people down,” he said. Contrary to popular belief, he said that shifting guardrails left can have the effect of increasing speed, which may greatly outweigh the negatives of shackling developers to a single approach.

    CloudBolt predicted siloed management will shift to organizational governance around tools in the coming year. But it’s not only the tooling decisions that require forethought, “it’s the leadership and cultural approach,” said Kukowski. A common area where greater leadership is required is in tagging workloads for applications, he said. “It’s not being done well anywhere.”

    Or, consider containerization. Containers have become fundamental to most modern cloud technology stacks, yet, the cognitive load required to deploy, configure and run a contain remains quite high, explained Kukowski. Do you allow every developer to custom-code each container, or do you enable a self-service repeatable provisioning process? If standard code is not being reused, you’re not getting speed or governance, he explained. Furthermore, with green IT initiatives becoming a priority, companies should be looking at ways to reuse processes and reduce waste where they can.

    Final Thoughts: Shift Left, Automate and Reuse

    For a cloud-native company, the emphasis is constantly on speed and growth. And engineers are absolutely driving this focus and the resulting innovation. Yet, this innovation can’t come at the expense of bringing all departments onto the same level of innovation. “Innovative stuff in the cloud can’t be separated from governance, ESG and security,” said Kukowski.

    A big hurdle of tomorrow’s cloud management will be identifying and uniting these islands of automation, these pockets of tools and preferences that differ between departments. It will also require a different frame of mind across divisions. “There’s a difference between solving the problem for the task and solving the problem for reuse and speed,” explained Kukowski. Delivering on reuse and speed will require less bespoke DevOps automation and better foundations for solving future problems, he said.

    “Shift left, automate and reuse—people shouldn’t have to touch it. That’s the thinking that needs to be applied to this new cloud order,” said Kukowski.