Category: DevOps Practice

  • Cisco AppDynamics Survey Surfaces DevSecOps Challenges

    Cisco AppDynamics Survey Surfaces DevSecOps Challenges

    A survey of 1,150 large enterprise IT professionals from the AppDynamics unit of Cisco suggested application security progress is being made slowly and steadily as organizations continue to embrace DevSecOps best practices.

    The survey finds that while more than three-quarters of respondents (76%) believe that DevSecOps is essential for organizations to effectively protect against a multi-staged security attack on the full application stack only 43% reported their organization has already started to implement DevSecOps workflows while another 46% said they are currently considering making the shift.

    More than three-quarters of respondents (78%) also said a lack of a shared vision between application development and security teams presents a challenge to application security over the next 12 months. More than half (55%) said they currently considered security to be more of an inhibitor of innovation than an enabler. Nevertheless, 81% admitted a lack of application security skills and resources is now an issue for their organization, with 79% acknowledging that securing the full application stack is now a priority for their organization.

    A full 92% admitted that the rush to rapidly innovate and respond to the changing needs of customers and users during the COVID-19 pandemic has come at the expense of robust application security. Well over half of respondents (58%) also noted their organization often ended up in ‘security limbo’ because they didn’t know what security issues to focus on and prioritize. A total of 88% acknowledged their organization could be doing more to secure the full stack of modern applications across the entire application life cycle.

    Not surprisingly, 93% said it’s important to be able to contextualize security so that they can correlate risk in relation to, for example, application performance, end user experience and business metrics. However, more than two-thirds (68%) reported that their current security solutions work well in silos but not together. A total of 85% stated that cultural changes to support the shift to a DevSecOps approach are important to improve application security.

    AppDynamics Executive CTO Gregg Ostrowski said it is apparent organizations are still wrestling with not just application security technologies but also people and process issues. The most critical issue is to knock down the silos that exist in organizations that often result in one team demonizing another, he added.

    Overall, application security is becoming more challenging as the attack surface expands. A full 89% of technologists reported that their organization experienced an expansion in its attack surfaces over the last two years, with almost half (46%) noting that this expansion is already increasing cybersecurity challenges. One of the primary drives of that expansion as been the rise of the internet-of-things (IoT) applications (59%), rapid adoption of cloud computing platforms (56%) and digital business transformation initiatives (51%).

    On the plus side, more than three-quarters of respondents (76%) said they believe artificial intelligence (AI) will play an increasingly important role in addressing application security challenges. The issue, of course, is how soon those advances might be made at a time when attacks against software supply chains are clearly on the rise.

  • Jellyfish Adds Tool to Visualize Software Development Workflows

    Jellyfish Adds Tool to Visualize Software Development Workflows

    Jellyfish today unveiled a tool that identifies bottlenecks in software engineering processes using data the company collects via Git repositories and project management software from Atlassian.

    Krishna Kannan, head of product for Jellyfish, said Life Cycle Explorer provides managers with a tool that makes it simpler to identify the root cause of a process breakdown.

    Life Cycle Explorer goes beyond providing simple top-level metrics to calculate the time consumed at each stage of a workflow for any given process and then visually map it to surface trends, noted Kannan.

    That makes it possible to identify gaps, see where work areas overlap—indicating parallel processes—and drill into how outlier events may be impacting the overall life cycle of a development project.

    The launch of Life Cycle Explorer comes at a time when there is more focus on the efficiency of DevOps teams than at any time in recent memory. During uncertain economic times, organizations of all sizes are looking to optimize DevOps workflows to ensure maximum efficiency because many organizations are hesitant to hire additional full-time engineers.

    The important thing to remember when analyzing DevOps workflows is there is no such thing as the optimal “Goldilocks” workflow that can be universally applied, noted Kannan. Instead, most DevOps leaders will discover one team excels at one segment of a DevOps workflow while others are more efficient elsewhere. Life Cycle Explorer makes it easier to identify those best practices in a way that makes them simpler to replicate when appropriate, said Kannan.

    Life Cycle Explorer follows the addition of a benchmarking tool and DevFinOps offering that addresses cost capitalization reporting for research and development. The core Jellyfish engineering management platform is designed to ingest data from the tools an organization already uses to build applications and then applies proprietary algorithms to create a comprehensive view of workflows across an organization. The challenge many organizations encounter today is they often lack visibility into workflows that have each been individually constructed by a diverse range of DevOps teams working on very different types of software projects.

    At the very least, DevOps teams need to establish a baseline that surfaces the current rate at which software development occurs. Once that baseline is established it then becomes possible to measure the impact changes to software engineering practices are having. Today many organizations make educated guesses about what changes are needed without really understanding the impact they might be having across the entire software development life cycle.

    Of course, it will be up to each organization to determine the degree to which they want to measure workflows. The Jellyfish platform makes it simpler to identify workflow issues, but there are also value stream management (VSM) platforms that track the impact software engineering workflows are having on specific business goals. Those VSM platforms are typically much more challenging to implement and maintain. The Jellyfish approach focuses more narrowly on improving the efficiency of DevOps teams.

    Regardless of approach, things that are not measured are not being managed. At a time when organizations are more dependent on software than ever, the need to manage software development life cycle as efficiently as possible has become a lot more important.

  • 3 Performance Challenges as Chatbot Adoption Grows

    3 Performance Challenges as Chatbot Adoption Grows

    Today, many organizations are starting to use voice or text-enabled chatbots for the first time or already have chatbot systems in place. In fact, Gartner said 25% of organizations are predicted to make chatbots their primary customer communication channel by 2027. This is because consumer behavior has shifted to primarily digital interactions and away from traditional customer support channels.

    As a result of today’s digital landscape, consumers are now accustomed to immediate gratification and expect instant responses and resolution from customer support, which makes chatbots an ideal solution for brands to rapidly serve customers. Due to this rising demand for instant customer service, chatbot systems have become more sophisticated and consumers’ reliance on them is increasing. This increase in adoption has led to higher performance expectations for bots and if those expectations are not met, customer satisfaction and brand loyalty will suffer.

    Below, we’ll look at three major challenges tied to the growing popularity of chatbots as they handle larger and more diverse groups of customers, and how business leaders developers and DevOps and customer experience (CX) teams can tackle these common challenges with a continuous testing approach.

    The Pain Points of Adoption: 3 Key Challenges as Chatbot Usage Grows

    As the popularity of chatbots explodes for customers around the world, the underlying systems that handle natural language processing (NLP), latency, data security and other functions need to be stronger. This is due to a growing and increasingly diverse demographic of users, many of whom are sharing more of their personal information to address a wider range of customer needs. Common chatbot pain points can be summarized by three overarching challenges.

    Challenge #1: Chatbots must contend with a larger and more diverse base of customers

    Chatbots that are voice or text-enabled must be smart enough to operate securely while navigating countless variations in spelling, a wide range of spoken accents and vernacular, background noise, static from bad connections and more. Even in a single language, there may typically be only four or five “intents” from most customers in engaging a chatbot, but those intents may be phrased in hundreds of different ways. Now, the global growth in adoption raises the chance of poor connections and exponentially increases the number of languages and variations in phrasing that a chatbot must understand and interpret.

    Challenge #2: Customers are trusting chatbots with more personal and sensitive data

    As chatbots become smarter and more trusted by customers to meet their needs, people are getting more comfortable giving their personal data to chatbots. That increases the number of situations where chatbots are working with personally identifiable information (PII) or other highly sensitive data. Especially given GDPR and other data privacy regulations being enacted worldwide, there’s added pressure to ensure a chatbot system’s handling of this data remains secure and compliant across all use cases and geographic regions.

    Challenge #3: Modern chatbots require 24/7 availability and reliability

    In an era of flexible work and millennial and Gen Z audiences interacting with bots after business hours and on weekends, chatbots can’t afford to work in shifts. Users may be spread across many time zones or around the world, meaning there’s always a sizable portion of customers awake, online and looking for fast and efficient service. Because of this, chatbots must be able to handle spikes and heavy traffic 24/7.

    The executive takeaway from these challenges is that modern chatbot investments must be built around dynamic systems capable of adjusting to shifting customer usage and performance requirements.

    A Continuous Testing Mindset is Required for Top Chatbot Performance

    Fortunately, by honoring a few best practices and making the right strategic technology investments in automated artificial intelligence (AI) and machine learning (ML)-driven systems, C-suite leaders responsible for CX and the teams they manage can deploy chatbots capable of keeping up with the above challenges. Perhaps the most central element for success is to embrace a continuous testing approach.

    For example, when a company is undergoing digital transformation and shifting its contact centers and supporting systems to the cloud, they are moving a significant amount of data, reimagining complex integrations and rearchitecting processes. In order to maintain application stability and existing integrations in the contact center, continuous testing is critical to ensure that an organization’s systems still operate effectively throughout the cloud migration process. With continuous testing, development and testing aren’t separate processes. The testing is automated and quality assurance is involved as developers submit code.

    The most effective approach to continuous testing includes end-to-end analysis across all channels. Testing chatbot behaviors should mimic real-time customer interactions. This should include challenging scenarios such as unexpected user inputs and usage spikes at random times of the day and night. Automation is critical, especially in peak demand scenarios such as Black Friday, Cyber Monday, open enrollment, etc. Load testing up to 1,000-100,000 bot requests per second, or more, can help ensure companies will be able to handle the increased traffic. Ideally, the testing approach should be comprehensive to include automated NLP score testing, conversational flow testing and security testing and performance testing and monitoring.

    By promoting the continuous testing approach across contact center operations, executives can empower their teams to build and maintain chatbots that remain optimized on an ongoing basis and that form an essential part of providing exceptional CX. This will make a huge difference in performance and reliability as systems scale and adapt to the evolving demands of a growing customer base.

    Continuous Testing Elevates Chatbot Reliability and Value

    High-performing chatbots and the continuous testing that keeps them optimized at those performance levels can benefit any company by lowering risks and enhancing revenue. Organizations that become adept at applying continuous testing avoid 90% of the downtime from high-severity (SEV 1) errors, which can result in saving $2.2 million in costs over a three-year period. When continuous testing touches every stage of the development process, it identifies issues earlier and helps strengthen an organization’s ability to innovate faster and service its customers effectively and profitably.

  • Looking Ahead, 2023 Edition

    Looking Ahead, 2023 Edition

    DevOps is in a perpetual state of change that keeps all of us engaged and busy, but makes a mess of things overall. Do you cloud-first? Are your APIs GraphQL yet? Are you doing SDN to connect to the VPN so you can put files on the CDN and build closer to the market? Sorry, had to do it. You get the point.

    The point is that the ground is forever changing under us, and often things that seem straightforward are not. Like “cloud-native,” including Kubernetes. Yeah, I get it, you mean software-defined infrastructure that works well with infrastructure-as-code (IaC); this field is confusing enough—calling it cloud is dumb when, these days, cloud has a specific meaning in the minds of IT.

    In our current round of change, a few patterns are showing up. Automation is king. Sometimes it is sold as AI/ML because those are the buzzwords of the day, but it is just continuing the trend of automation to make IT more responsive and predictable. We are rapidly approaching a point where the entirety of the application development/deployment process can be automated reliably and configured to create predictable results. By that I mean that development has more assistance writing code, test has more assistance running tests and processing results, deployment environments can be grabbed from application release automation/orchestration tooling and the final product all of that means that builds can be deployed with very little human interaction unless something breaks.

    Highly automated systems are a prerequisite of high-volume output, though – automobile factories are the easiest example of that statement. My problem is that we don’t seem to be asking “Should we be high-volume producers?” Does the average enterprise require non-stop development? I think that the initial answer is yes, and the more considered answer is “Only because the business wants more, consistently.”

    At some point, the gains we received from DevOps need to be looked at from the “What value is added?” perspective. And that is a business function with IT input. Before SaaS and DevOps made IT easier (to get something running; not minimizing our work here), the business had to consider carefully if it needed that application or that change to an existing one. Today, that consideration is pretty much “Because we want it, put it on the backlog.” But all of our new development adds to our technical debt. While the wave of automation we have been living through since “The Pheonix Project” was first published is keeping us ahead of the curve, we will inevitably need to consider flattening the curve. I suggest that the time is now.

    Getting started with this is actually pretty easy. For many organizations, simply stating, “We do not need two ways to do that” will yield benefits quickly. Other organizations will have to ask “Why can’t we use the functionality of existing tools/apps to do that?” and yet others will need to ask the business, “Do we even need to do that?” Prioritization still exists, and management does an okay job of pushing back at all of the organizations I talk to. Still, at some point it goes beyond “prioritize your wishlist,” and IT managers will have to start asking if a project is even necessary–even if doing so makes waves.

    Continue to rock it, but we’re past time to look for redundancy, synergy and misdirection. There is more complexity coming, and more sweet solutions to problems (both known and unknown) are right around the corner. But, as I’ve said before, simplify as you go because you need to be able to handle the next wave, and eventually, automation won’t cover the gap.

  • How To Build Anti-Fragile Software Ecosystems

    How To Build Anti-Fragile Software Ecosystems

    Just as organisms are susceptible to diseases and viruses, software systems are susceptible to hacks and errors. And within many complex interconnected systems, a minor bug could have a cascading effect across an entire organism, causing it to break. As such, increasing the resiliency of a software ecosystem is something engineers continually strive for. But how do we get there?

    One concept to consider is anti-fragile. Being anti-fragile refers to the ability of a system to thrive in adversity and adapt to change. Specifically, with regard to software, anti-fragile can equate to responsive coding practices, such as auto-scaling or default backups, to mitigate unforeseen events. Chaos engineering, for example, is one method to expose edge cases and build with adaptability in mind. And with the introduction of intelligent automation, often fueled by machine learning (ML) and artificial intelligence (AI), it’s becoming more and more feasible to build anti-fragile software systems.

    I recently met with Asim Razzaq, co-founder and CEO of Yotascale and former head of platform engineering at PayPal, to discover what it takes to build anti-fragile software. According to Razzaq, anti-fragile represents the next evolution of reactive, resilient software systems. And introducing anti-fragile concepts into your application networks can be done with just a few (relatively) simple steps. Below, we’ll define what anti-fragile is and see how this concept can be applied to software development and DevOps.

    Understanding Anti-Fragile

    As the adage goes, “What doesn’t kill you makes you stronger.” And it’s true—many natural systems tend to thrive under inhospitable conditions. As described by Nassim Nicholas Taleb in the book ‘Antifragile: Things That Gain from Disorder,’ anti-fragile systems thrive in adversity. For example, consider how human muscle grows under stress and load. Immune systems similarly adapt and respond to new viruses and improve the body’s resilience over time. So, how does this relate to software development?

    Well, organizations need to develop highly-tolerant software systems to meet rising digital consumer expectations. Especially when under extreme loads, systems must be elastic to adapt and survive. To meet high user demands, as well as specific service-level objectives (SLOs) and agreements (SLAs), most software companies are already investing in cloud-native tools that improve reliability. For example, a hallmark of site reliability engineering (SRE) is introducing automation to enhance the stability of applications.

    One example of gauging anti-fragile in software environments is chaos engineering, says Razzaq. Chaos engineering is the act of throwing a wrench into the machine. You randomly introduce bugs and malformed requests and attempt to create as much havoc as possible to see what happens. This could mean pulling out cables and restarting servers to gauge how software systems respond.

    “Software that can respond the best adapts the best,” said Razzaq. For example, if you manually remove a few nodes from the cluster but the system knows it needs seven to function, it could automatically spin up additional nodes. Or if the whole cluster goes down, ideally, the system would automatically restart and scale to the necessary requirements. In essence, anti-fragile software systems can understand and adapt to new environments without much, or any, human input.

    Tips to Construct Anti-Fragile Software Systems

    So, how can we construct anti-fragile software systems — especially when real-world challenges are often unpredictable? Razzaq shared helpful advice to consider when crafting anti-fragile software architecture.

    1. Start With Your Most Critical Systems First

    First, introduce chaos engineering to your most absolute critical systems. Define these vital components at the heart of your product which must remain functional. For a payments processor SaaS, for example, this would be the infrastructure supporting its transactional engine, such as the login and payment microservices.

    2. Determine How to Test Fragility

    Once you’ve identified this critical infrastructure, figure out how to test for fragility in your environment. Introduce chaos engineering to the component to see how it behaves. For example, returning to our payment platform example, this may include switching off a payment transaction type to see how the system functions in an extreme scenario.

    3. Decouple Components

    If systems are too closely coupled, errors and outages can ripple across multiple software services. To avoid that, it’s a good practice to prevent tight coupling between components—especially between critical systems and non-critical ones.

    4. Introduce Alternate Paths

    One method to decouple is by introducing alternate paths. For example, if a credit card verification component goes offline, the system should naturally accept other forms of payment and automatically suggest another form, such as a bank transfer. If all systems are down, the system could still accept unverified payments in a queue and let this continue until the threshold reaches a certain risk level.

    5. Learn From Past Events

    The next frontier of designing anti-fragile architecture is developing self-learning, autonomous systems. Of course, there is a limit to how automation can respond to unforeseen issues. But by feeding a machine learning model with more and more experiences, it could deal with untested new scenarios more gracefully. Of course, AI has the potential to make harmful decisions and even introduce unintentional bias, so organizations should have accountability for the algorithms they oversee, cautioned Razzaq.

    Benefits of Building With Anti-Fragile in Mind

    The goal is to able to thrive and function even under duress. By identifying the elements of core infrastructure to keep alive and putting it through the wringer, you can discover frailties before they cause significant consequences. And by decoupling components and introducing alternate paths, software systems can be better equipped for whatever may come. Uplevelling system operations with increased automation and AI is likely the future of constructing more fault-tolerant applications.

    “Software is everything in this day and age,” said Razzaq. “It increasingly plays a critical role in life-enhancing capabilities.” As such, the end benefits of developing an anti-fragile style could have hugely positive effects. In health care situations, it could make a difference in saving lives. For other less dire scenarios, increased fault tolerance leads to less lost revenue during peak traffic times and more consistent end-user experiences.

  • Let the Machines Do It: AI-Directed Mobile App Testing

    Let the Machines Do It: AI-Directed Mobile App Testing

    AI has been in the news a lot lately. We’ve all heard a lot about ChatGPT and you’ve no doubt encountered the end result of a variety of other advances in AI technology of late, such as Lensa. But there’s also a much quieter and less visible shift happening behind the scenes during the development of your favorite apps—AI-directed mobile app testing. Let’s take a look.

    Behind the Scenes

    It’s no secret that every product, no matter the industry, goes through a gauntlet of tests before it’s unleashed on the general public. This goes for everything from a simple object like a cardboard box, for example, to a far more complex product, such as the latest electric vehicle.

    The same goes for the mobile apps on your phone. And if you haven’t given that much thought, then good! It means that the QA team behind the app’s functionality did its job, producing a seamless experience that functioned without a hitch, exactly as you wanted and expected.

    But that’s not always the way it goes, and mobile app testing is only growing more complex. That’s a growing problem that AI will eventually resolve.

    If your app didn’t perform as expected, you—and many other users like you—may delete it and move on to the next app that promises to do the same thing. While this may not seem like a big deal to you as the user, it’s a total disaster for the tireless teams working behind the scenes to ensure a successful app launch or update.

    The adage ‘You only get one chance to make a first impression’ is very true in the mobile app market. It’s a big, crowded and cutthroat mobile app world out there, and users simply have no incentive to put up with an app that doesn’t do exactly what it’s supposed to do. After all, for every single app, there are often several others standing by to scoop up your unhappy (former) users.

    This issue is by no means restricted to small development teams strapped for resources. I’m sure you can think of some high-profile software releases from major companies that have launched in a disastrous state over the past few years (particularly in the tremendously profitable arena of video games).

    So why is it that some teams cut corners when it’s time for testing, only to dearly wish they hadn’t?

    Well, the answer is pretty simple: Up until very recently, mobile app testing has traditionally been time-consuming, complex and bewildering, all too frequently delaying releases and flabbergasting QA teams.

    To understand this ongoing problem, let’s take a look at what this kind of mobile app testing entails and how this landscape has recently started to shift, as well as what’s on the horizon to make it all more efficient.

    Cutting Corners = Consequences

    Once upon a time—in an era that seems like it was really just yesterday—software testing was performed manually, entirely by hand. This was possible because quality assurance personnel only needed to consider a very limited set of variables: There were only so many use cases and form factors to consider, and programs were only expected to do so much.

    It’s hard to imagine testing a modern app manually and having the result be effective. The approach is only reasonable under very limited circumstances. Nowadays, teams use automated tests, which save them a tremendous amount of time, effort and resources.

    Yet these automated tests come with their own problems. Most of these automated tests are hand-coded, meaning that they must be set up and adjusted by specialists with a background in computer programming. Such specialists are not only costly and in demand, but they’re also needed for later aspects of the software development cycle, such as developing new product features and overseeing other aspects of production.

    And this is where companies start to cut corners and miss problems and issues, both large and small. Instead of what is known as shifting left (that is, testing as early in the cycle as possible), many teams, unfortunately, view testing as a burden or afterthought. Only when things go haywire and they have a full-blown crisis on their hands does the need for rigorous app testing become apparent.

    Testing, Machine-Made

    This is where machine learning and artificial intelligence enter the picture. For several years, we’ve known that testing performed by machines will be more and more necessary to handle increasingly complex apps, and it won’t be long before the cost associated with the complex testing scenarios will simply become too much for many developers.

    Fortunately, advances continue to appear on the horizon. These include the much-discussed no-code revolution, which abstracts away much of the noise associated with software development and opens the door to a much wider testing base.

    AI- and machine-learning-based testing is also on the horizon, yet there’s a significant challenge that must be overcome before this can happen at speed and scale. To develop mobile app tests with true intelligence and maximum efficiency, machines must be capable of autonomously completing the following steps:

    1. Comprehension: Draw from the ability to understand what’s changing in an app. For example, the machine must be able to detect differences and issues in a signup sequence or a checkout screen change.
    2. Impact analysis: The machine must know what test cases can cover that change. This sort of identification can be quite tricky.
    3. Test case generation: Next, the machine must possess the ability to generate test cases related to steps one and two. To do this, the machine must draw from several data sets. These include:
      1. Extent test collateral/test cases with product code
      2. Data from actual customer usage so that numbers one and two above may be identified
      3. What user environments look like, including information like how many users are active in the United States and in Europe
      4. Automatic execution: Perhaps the most crucial need is that the machine can perform testing entirely by itself. With the ability to self-execute tests, we’ll have reached a new era in testing.
      5. Reports: Before the testing cycle can begin again, the machine must be able to produce detailed reports that make sense to its human handlers. When it comes to test results, the more detail the machine can provide in as approachable a manner as possible, the better.

    Problems and Solutions

    Some testing platforms are now capable of many of the tasks I highlight above, and quality assurance teams that move away from self-coding tests and toward the future of testing stand to benefit from these solutions (particularly when their competitors do not).

    Partially enabled by AI and ML, no-code solutions provide a stopgap solution until machines can really get a handle on the above five steps. At this point, it’s really just a matter of time: We can already see glimpses of a wholly automated testing cycle where human input is limited and machines do the heavy lifting.

    It’s easier than ever to imagine a world where there’s no need for testing to be an afterthought and software disasters have become a thing of the past.
  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted as part of an effort to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    LinkedIn

    SiriusXM
    Washington, D.C.
    Director – Client Build and Release Management
    $166,000 to $300,000

    SimplyHired

    Dataflix
    Remote
    DevOps Engineer
    $140,000 to $190,000

    ZipRecruiter

    Bay Systems
    Mountain View, California
    Senior Full Stack Developer
    $120,000 to $174,000

    Monster.com

    GlobalLogic
    Remote
    Senior DevOps Engineer
    $120,000 to $130,000

    Indeed.com

    Leidos
    Ashburn, Virginia
    DevSecOps Engineer
    $97,000 to $202,000

  • The Strategic Product Backlog: Lead, Follow, Watch and Explore

    The Strategic Product Backlog: Lead, Follow, Watch and Explore

    The economic outlook for 2023 suggests many organizations will be leading through a period of resource scarcity as IT budgets are scrutinized and organizational priorities are re-evaluated. For the product manager, smaller budgets and fewer resources place even greater emphasis on ensuring alignment between enterprise priorities and the product backlog.

    Many tools are available to help product managers prioritize individual work items at a tactical level for DevOps teams. These models generally seek to quantify some combination of internal stakeholder value and level-of-effort required for developers and DevOps teams to complete. Higher-value lower-effort items rise to the top.

    Other strategic factors are just as important in the prioritization process, particularly for products living within a larger enterprise product portfolio and competing for scarce resources. For these, a product manager must understand why a given work item or capability should be given priority and how it should be pursued. This involves asking questions such as: On what basis should an item come into the product consideration set? How much should DevOps and developers seek to innovate in delivering a specific capability or feature? What is the product and the portfolio-level opportunity cost of pursuing a given piece of work?

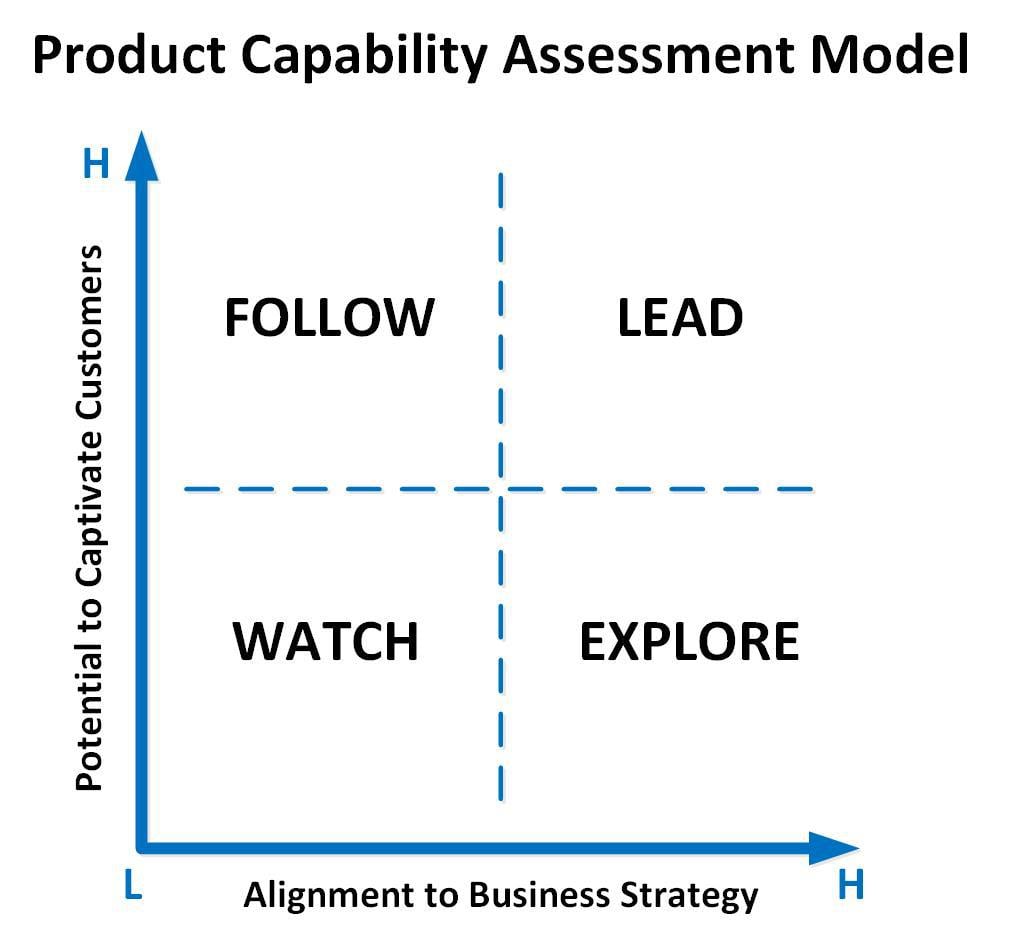
    A strategic model for backlog evaluation helps to set expectations with DevOps, developers and other internal stakeholders and ensure customer needs are front and center in prioritization decisions. It establishes a common language for collaboration. Two dimensions should emerge in evaluating capabilities at higher product and portfolio levels: Capability alignment to business-level strategy and the potential for a capability or feature to not just satisfy but captivate customers with a novel or compelling experience.

    The intersection of business strategy and customer experience factors can serve as a useful model for a product manager to think strategically about their backlog. The model helps to inform not only the question ‘Should we do this?’ but also ‘How should we proceed?’ and make things clearer for DevOps teams.

    Lead

    Items in this quadrant are the unicorns of the backlog and have the greatest potential to both strategically differentiate a product or enterprise and captivate customers. Product focus in this quadrant should be to invest in innovative, industry-leading approaches to satisfying customer needs in a manner that is consistent with business strategy and unique selling proposition. These items should receive the highest strategic priority on the product backlog.

    Follow

    Potential work items in this quadrant have a high potential to delight customers if handled well and irritate them if not. However, these elements are unlikely to be competitively differentiating given the current business strategy. Product focus in this quadrant should be to continually assess competitor treatment of these elements and adopt proven best-in-class experiences within the industry and adjacent industries. The product should focus moderate priority on competitive intelligence for elements in this quadrant and follow existing competitor approaches that enhance the customer experience.

    Watch

    Items in this quadrant are generally not problematic for customers. They are unlikely to differentiate the product or enterprise from competitors given the current business strategy and should be given low priority. The product should monitor proposed solutions in this quadrant to ensure no unnecessary customer effort is being introduced by other backlog items.

    Explore

    Product functionality in this quadrant is either not problematic for the customer experience or represents capabilities that are still emerging in the marketplace. These elements have a likelihood of developing into competitive levers, provided they can be developed in a manner that enhances the customer end-to-end journey. The product should place a high priority on product discovery for elements in this quadrant. It should explore capability innovation through design thinking or similar customer-centered ideation approaches.

    Mapping a product backlog to these four quadrants is as much art as science. It requires a deep understanding of business strategy, intended outcomes and customer needs. As with any strategic model, its value comes from the quality of discussions it produces and its role in surfacing implicit assumptions from the product’s stakeholder group, including DevOps teams and developers. Whatever model is used, having a mechanism to drive strategic product discussions is a critical tool in the product management toolbox and an important step to product management maturity.      

  • Atlassian Extends Automation Framework’s Reach

    Atlassian Extends Automation Framework’s Reach

    Atlassian this week extended its namesake automation framework to include its Confluence collaboration software. In addition, it’s now possible to automatically create bi-directional branches in Bitbucket, GitHub or GitLab platforms from within the company’s Jira project management application.

    At the same time, it’s now possible to automatically generate feature flags from within Jira through integration with the feature management platform created by LaunchDarkly and automate alert and incident responses stemming from the Amazon Web Services (AWS) cloud.

    Dilani Kahawala, head of product for the automation platform at Atlassian, said these extensions to the Atlassian Automation framework are part of a larger ongoing effort to remove the silos within software engineering teams and the rest of the business.

    DevOps teams, for example, will now be able to expand the number of those automated actions being taken because change requests can be automatically created. Atlassian estimated that IT teams will spend 25% less time managing change requests and save 115 hours per month.

    To save more time, templates that automatically create Wiki pages in Confluence can be spun up at the completion of every sprint.

    Since it first launched for Jira in 2020, Atlassian claims more than 10 billion automated actions have been executed across the Atlassian platform.

    Kahawala said as more organizations realize how dependent they are on software to drive revenue, the need to close the divide between software engineering teams becomes much more pressing. She noted that changes to the timetable for one project can have a cascading effect across the entire business. At a time when organizations are counting on digital business transformation initiatives to remain competitive, the speed at which organizations share updates across silos is critical, said Kahawala.

    At the same time, organizations are also striving to become more productive in an uncertain global economy. Automating rote tasks makes it possible for development teams to spend more time writing code, added Kahawala.

    Less clear right now is whether businesses can absorb the pace of change that is enabled by modern software development. Historically, business leaders complained that their dependency on IT was holding the business back because it took too long for IT teams to implement changes. Today, however, many organizations routinely deliver code updates to mission-critical applications daily. While not every delivery may involve a major new update, it’s apparent that the pace of innovation is now occurring at speeds many organizations find challenging to absorb.

    As organizations continue to adopt best DevOps practices, the pace of innovation is only going to accelerate further. The challenge—and the opportunity—is to ruthlessly eliminate as many manual tasks as possible to accelerate the pace of innovation. After all, software engineering pros have better ways to spend their time than manually creating yet another branch in a continuous integration/continuous delivery (CI/CD) platform or, worse yet, reenter data into a project management application.


    Join the makers of Jira for a brand-new (free) Agile & DevOps event. Atlassian Presents: Unleash is designed to help your team collaborate from discovery to delivery to running great software. Get first access and “cheat codes” to the newest Jira Software features and products from Atlassian; network with peers, industry experts, and Atlassian product leaders; and solve real-life challenges around your Jira and toolchain configuration and workflow. Live in Berlin or digitally on February 9. Register for free.

  • Software Supply Chain Security Debt is Increasing: Here’s How To Pay It Off

    Software Supply Chain Security Debt is Increasing: Here’s How To Pay It Off

    Last year, the world woke up to the software supply chain dilemma. We saw a spike in attacks as hackers sought to exploit known and unknown vulnerabilities within dependencies. There is also the chance of typosquatting, and malicious code commits to consider. Such supply chain attacks have increased by a shocking 742% over the past few years.

    It’s easy to let software security debt accumulate, as it’s cumbersome to stay on top of frequent updates — especially when new releases cause breaking change. Furthermore, companies might unknowingly collect security debt by hastily looping in projects whose origin is unknown. Plugging these gaps can bring a high burden down the road, which too often falls on the shoulders of developers to manage.

    I recently reconnected with Dan Lorenc, founder and CEO of Chainguard, to discover why risks in the software supply chain contribute to increased security debt and how organizations can proverbially pay it off. Lorenc is a key figure behind Sigstore, the open source utility built to verify the provenance of open source packages. Below, we’ll consider the state of software supply chain security and examine some modern solutions that lessen its severity.

    Why is Supply Chain Security Debt Rising?

    Modern software ecosystems are an intricate mosaic of dependencies, and supply chain security concerns often arise at the cracks between them. “It’s about the gaps and hand-off points between individuals in the software life cycle,” said Lorenc. Since these hand-off points can threaten systems at large, they can accumulate considerable security debt if left unguarded.

    Another reason why security debt is increasing, said Lorenc, is that fixing issues is rarely incentivized—it’s always thought of as “someone else’s problem.” Minimizing this debt will require organizations to change this mindset and follow modern security best practices, like implementing multifactor authentication infrastructure and more frequent code reviews. It will also take a coordinated effort from package managers to integrate tooling that helps verify the legitimacy of packages, said Lorenc.

    Solutions to Reduce Software Supply Chain Security Debt

    Automated Vulnerability Scanning

    In addition to advancing internal culture toward greater security awareness, organizations will benefit from automation that enhances the discovery of vulnerabilities. Because when a severe incident like Log4j hits the presses, it’s a mad scramble to respond. Even a year later, one in four downloads still possesses the infamous vulnerability.

    Integrating automated security scanning is the first step to knowing how these incidents impact your security posture. A tool like Snyk can do a great job of surfacing known vulnerabilities and finding where they lie within your software stack and provide remediation advice. Continually checking for updates can also help pay off security debt “as you go” instead of upgrading everything all at once, says Lorenc. But although scanning tools are essential for increasing visibility, they don’t address the root cause of why they are vulnerabilities in these packages in the first place, says Lorenc.

    Checking Transitive Dependencies

    Reports find that 95% of vulnerabilities stem from transitive dependencies. These are dependencies that are buried deep within the dependency tree of another package. And depending on the programming language, they’re not always that visible. The combinatory effect of transitive dependencies can lead to exponentially more vulnerabilities and issues if not carefully tracked. And since they’re running locally with the same privileges as your other packages, you shouldn’t treat these vulnerabilities any differently, said Lorenc. “You need to realize they can affect your application in the same way.”

    Validating The Source

    The link between the package manager and the source code is a frail area that warrants additional verification. Social engineering tricks can effectively trick users into downloading insecure packages that appear safe at the outset yet hide corrupt code. Or, account takeovers can result in attackers inserting malicious code into commonly used open libraries. Package managers often host built versions and forked versions of software produced by the community on GitHub, yet do not validate a clear link to the original repository. This gap heightens the chance for a malicious package to slip through the cracks, says Lorenc.

    This is something that Sigstore, the open standard for signing, verifying and protecting software, aims to accomplish. In mid-2022, Sigstore was implemented within Kubernetes, signaling the adoption of Sigstore as a standard throughout the open source ecosystem. It’s also been adopted by Npm and PyPI and Maven Central will soon support Sigstore as well, said Lorenc. Although some of these moves have received pushback from developers, Lorenc argued that such verification is necessary to help link packages to their source and increase credibility for open source dependencies.

    Chipping Away At Security Debt

    Like technical debt piles up over time, security debt can quickly rise if left unchecked. Chipping away at increasing software supply chain security debt will likely require a “pay as you go” approach wherein developers continuously scan and update their dependencies. One good sign is that people are paying more attention to risks latent within their code, and the industry is discovering and sharing more potential vulnerabilities before they are exploited.

    “Security has advanced, and there are common best practices across the industry,” said Lorenc. But if these practices aren’t followed, it could bring dire consequences for the organizations and the industry as a whole. And although Sigstore can help bridge the disconnect between the package managers and the source code, there are plenty of other techniques to help improve a security footprint for open source software and cloud-native infrastructure. For example, SLSA and greater use of SBOMs can help address security debt more holistically.

    The software supply chain security dilemma is an advanced topic that requires a coordinated effort from various stakeholders to remedy. The important takeaway is to stay positive, see the debt, and pay it off incrementally, says Lorenc.