Category: DevOps Practice

  • The Role of Developers in Digital Transformation

    The Role of Developers in Digital Transformation

    Developers are an integral part of digital transformation. They architect the modular systems that overcome legacy and build the applications and solutions that allow firms to deliver products and services in new and innovative ways. Yet, when it comes to business decisions, many organizations overlook their developer talent.

    Developers come from a variety of different backgrounds, but it’s safe to say that most have studied computer science, engineering or mathematics in some form. Coming from these disciplines means they are inherent problem solvers, so giving them a seat at the table when it comes to discussing business goals is, of course, beneficial.

    To ensure the business insights of developers can be unlocked, organizations should consider the following four points. 

    Encourage Personal Development

    More and more developers are actively taking an interest in improving their communication and leadership skills, recognizing that these are important tools for career development. 

    Soft skills, for example, are key to establishing relationships internally, as well as communicating to external parties. At any moment, stakeholders may want to understand the workings of product teams, or it may be the case that a customer requires more attention when implementing a solution. In the former scenario, developers must become advocates for the business and the way they work; in the latter case they must ensure that they take an empathetic approach to end users. 

    Whether it’s learning new programming languages, getting to grips with new technologies, or developing soft skills, developers relish the chance to grow. Organizations that offer learning and development programs internally will likely attract developers who are both apt and keen to involve themselves in other areas of the business. 

    Keep Things Agile

    Operating within an Agile framework gives developers and other members of product teams a chance to develop soft skills through scrum meetings. During a scrum meeting, each member of the team is given the opportunity to communicate openly about their challenges and devise solutions for other issues. This not only ensures a high level of transparency internally, it also allows business analysts to provide an accurate picture of progress to clients.

    Sharing insights and troubleshooting in an open forum enables those with a natural inclination for leadership to establish themselves as effective communicators. The limited size of Agile teams also keeps things personal enough that each team member’s feedback can be heard and considered by their colleagues. 

    Agile software development brings disciplines together, encouraging an exchange of ideas and an expansion of knowledge. This is in stark contrast to the Waterfall method, where siloed teams hand off work with little communication.

    With Agile, teams share responsibility, communicate and apply their disciplines in contexts outside those they are used to. In essence, Agile is the ideal way to establish a culture that enables learning and development on the job. This is much more practical than setting up a program that teaches soft skills and educates teams about other areas of the business, as these sessions can eat into work time and reduce productivity.

    Be Clear on Requirements

    It’s all well and good attracting the best and brightest developer talent, but in order to get the best from them, firms must be transparent about what is expected day to day.

    Firstly, efficient code delivered in a timely manner should be the goal of every developer. Testing and QA will, of course, reveal issues, and no one is perfect, but developers must be mindful of the impact inefficient or inaccurate code can have on a business. Workarounds may get you past a problem, but this is not best practice and leaves the business exposed should a client pick up on it–especially if the workaround causes more serious issues further down the line.  

    Fewer bugs or defects means scrum meetings can naturally focus more on strategy and new initiatives that might help grow the business. Organizations should therefore establish best practices and coding guidelines to reduce the temptation for workarounds, ensuring code releases are reliable and ready for the production environment. 

    Developers must also be able to comprehend the requirement to work with designs given to them by design teams, as these will align with customer expectations. Being able to dynamically incorporate client feedback into the development process is also key, particularly for those working with continuous delivery and continuous integration pipelines. 

    An interest in emerging technologies is desirable, as is an eagerness to innovate new solutions using them, but so too is an aptitude to leverage rather than re-invent solutions. This helps to keep costs down and ensures a maximum return on investment in existing solutions. 

    Keep an Eye on the Future

    Increasingly, the ease with which organizations can react to advances in technology will determine their long-term success. It is therefore in their interest to ensure developers have the freedom to learn new skills and explore new tools that might increase efficiency or unlock new offerings. 

    Advances in IoT, connected devices, augmented and virtual reality, AI and machine learning, blockchain and 5G networks are just some of the technologies opening up new challenges for firms and developers alike.

    Developers with the skills to harness these technologies will increase their employability, allowing them to secure better positions and salaries. They will also be well placed to advise on wider business goals, positing new use cases and solutions and fueling innovation.

    — Arun Ramachandran

  • A Developer’s Task: Minimizing Challenges Created by Fragmentation

    A Developer’s Task: Minimizing Challenges Created by Fragmentation

    Over the past decade, there has been a wellspring of apps, services and platforms to help developers build custom solutions for businesses. Some are great, some not so much. Regardless of quality, the quantity of options and each one’s varying level of sophistication has made it difficult for developers to separate the wheat from the chaff.

    A recent survey from IDC supports this notion. It contends that the current landscape of software development languages and frameworks is highly fragmented. Having too many options—as opposed to a single, unified environment—leads to holes and disconnects in the development process, not to mention the potential for significant complications in the long-term support of today’s apps.

    Here are some ways developers can navigate the challenges created by this high level of fragmentation. 

    Don’t Be Afraid of Low-Code (or No-Code) Solutions

    The IDC survey found that less than half of developers—44%—have used low-code development tools professionally at one point or another. As one would surmise, low-code programming brings with it a host of advantages, such as easy-to-use and intuitive interfaces, and the ability to deliver applications faster. 

    Some low-code platforms also enable developers to build applications that can be used on any device while also reducing dependency on outsourced IT. A built-in script builder can allow even relatively inexperienced developers to turn complex business logic into functional workflows—such as automating a repetitive task—within a matter of minutes. Even after apps are launched, workflows can be updated and customized to fit specific business needs nearly instantly.

    Achieve Scale with Serverless Applications

    When building on a serverless platform, developers prevent infrastructure maintenance from inhibiting applications from scaling globally. This also allows developers to build mobile apps without managing the backend infrastructure. Cloud computing using public clouds typically involves renting virtualized servers across the technology stack. But when looking to scale, the onus is on developers to deal with the operating system and database while also managing necessary updates. This can lead to a work-intensive process on the app infrastructure level.

    A serverless infrastructure, on the other hand, abstracts databases and file servers, shifting focus to the app logic level. This allows developers to build and manage microservice-based apps that integrate with other services, making it easy to scale applications.

    Make Things Easy on Your Team

    According to the IDC survey, just 20% of developers claim they are “extremely familiar” with containers and microservices. With such expertise hard to find, using flexible tools that allow teams to quickly deploy code in scalable, compartmentalized components is vital.

    Organizations should aim to help their developers focus more on designing top-class user experiences of serverless applications, rather than spending (or wasting) time and resources on setting up and maintaining components on the server side. This gives developers the ability to focus on doing what they love—developing—as opposed to other tedious and mundane activities such as manually managing servers and storage solutions, or tweaking the underlying infrastructure of their microservices.

    Of course, making things easier for developers means deploying a powerful tool built on a stable foundation that can offer SDKs and APIs for both mobile and web apps, the ability to test early and often in a sandbox environment and analytics that monitor and report performance in real-time.

    Developers know just how challenging their jobs can be, and the fragmentation that can occur due to the vast number of options on the market can make it even worse. There is nothing wrong with using multiple solutions, of course, but having a sturdy and unified underlying infrastructure goes a long way toward avoiding unnecessary headaches.

    Finally, organizations should look to those who know best when deciding which company-wide tools to implement: the developers themselves. As the IDC study states, developers should be viewed as key stakeholders in IT purchasing within any organization moving to the cloud accompanied by an internal digital transformation.

    — Raju Vegesna

  • Building a Real-Time App: 13 Open Source Projects You Should Be Tracking Right Now

    Building a Real-Time App: 13 Open Source Projects You Should Be Tracking Right Now

    Open source is the dominant model of software consumption in the modern era. Cutting-edge startups and entrenched incumbents alike find open source software development and community building a significant part of their overall business strategies.

    For many open source projects, independent steering committees ensure that projects remain stable and are not beholden to a single company or profit motive. Alternatively, for open core projects where a single company financially supports and contributes the vast majority of open source code, open sourcing makes a project publicly available and accessible for potential new users. Opening a project to public contribution widens the pool of potential users and contributors, therefore ensuring more rapid innovation than commercial software offerings.

    Choosing the Right Open Source Projects for Your Real-Time App

    There are seemingly limitless open source projects to evaluate. Further complicating matters, each project has its own domain competence and cultural nuances. Considering a single distributed application will have tens or (many) more open source dependencies, development teams must continuously test new open source offerings and hone new skills to use these solutions, while simultaneously architecting their applications.

    In order to help sort through the noise, I’ve looked at six categories of open source projects for this article: data storage, message systems, service meshes, REST frameworks and streaming frameworks. For each category, I’ll identify any dominant players as well as some other projects of note.

    Here are the top 13 open source projects by category.

    Data Storage: Cassandra, Hazelcast

    Apache Cassandra, originally developed at Facebook, is one of the most widely used open source projects for real-time applications. Functionally, it’s a distributed NoSQL database management system. But practically, it’s become the linchpin of most at-scale, real-time applications. This is because Cassandra was designed to handle large amounts of real-time data across many servers, and has robust clustering support.

    For applications that require extremely low latency or have exceptionally high data rates, Hazelcast may provide a useful alternative. Unlike Cassandra, Hazelcast is an in-memory data grid database, which enables development teams to benefit from the latency advantages of in-memory computing. 

    Message Systems: Kafka, Pulsar, NATS

    Apache Kafka is the dominant open source messaging system used by application development teams today. Originating at LinkedIn, Kafka has grown into the de facto standard for high performance open source messaging systems. For streaming use cases, Kafka users can also turn to Kafka Streams.

    Apache Pulsar, developed at Yahoo!, is another alternative messaging system which has been optimized for streaming data sources. Pulsar further differentiates itself with TTL message support and queuing via shared subscription.

    For applications where latency is a critical consideration, NATS.io (a CNCF project) is one of the fastest pub-sub messaging systems available.

    Service Meshes: Istio, Linkerd

    Trends such as microservices, serverless and hybrid cloud deployment have contributed to the increasing architectural complexity of distributed applications. With hundreds or thousands of distributed application services, service meshes provide a mechanism for pulling all the disparate services together into a manageable and cohesive whole.

    The most notable open source service mesh offering is Istio. One of the most popular open source service mesh projects, Istio is primarily used for applications built on top of Kubernetes. Another alternative is Linkerd, a flexible service mesh solution for Kubernetes or other frameworks.

    REST Frameworks: Node.js, Spring

    Node.js is a popular JavaScript framework for building scalable web applications. When comparing web development frameworks, Node.js typically ranks among the top three most (along with frontend frameworks React.js and Angular.JS). While Node.js can support large scale applications, it does not support real-time use cases well at scale.

    Spring is another application framework, optimized for distributed microservices-style architectures. Like Node.js, Spring “focuses on the ‘plumbing’ of applications so that teams can focus on application-level business logic, without unnecessary ties to specific deployment environments.”

    Streaming Frameworks: swimOS

    SwimOS is a software framework for distributed streaming applications. Unlike REST-based frameworks, swimOS utilizes a unique and lightweight Web Agent architecture, optimized for composing and transforming many data streams in real-time. Whereas DevOps oriented projects, such as Spinnaker, seek to provide an abstraction layer to converge distributed cloud services, swimOS provides an abstraction across distributed data streams, so teams can build applications by composing many distributed data streams in a single mesh environment.

    In order to ensure real-time consistency of distributed services, swimOS automatically ensures eventual consistency between all Web Agents. Complete with a UI toolkit and it’s own stateful messaging protocol called WARP, swimOS is the fastest way to build stateful streaming applications.

    DevOps: Kubernetes, Spinnaker, RancherOS

    Kubernetes is one of the most talked about open source projects in the world. Kubernetes describes itself as “an open-source system for automating deployment, scaling and management of containerized applications.”

    While it may simply be a platform for container orchestration, rightly or wrongly, Kubernetes has become a stand-in for DevOps on the whole. In spite of its dominance, there are alternatives to Kubernetes, for example there’s RancherOS to manage Docker containers.

    Furthermore, as application architectures continue to become more distributed and complex there is a need for platforms which can converge multiple distributed edge and cloud environments. Spinnaker provides an abstraction layer to connect the various environments and provides a simple mechanism for continuous integration/continuous delivery (CI/CD). 

    Final Thoughts

    Your own particular use case should determine the appropriate open source technologies for your team’s real-time application. Whether you’re building an ultra-high performance low latency application or simply trying to tame large volumes of real-time data, knowing your options and choosing the right framework or platform can save you significant time and effort.

    The open source software landscape is changing every day. If you have something to add about one of the technologies above or think I skipped over the next OSS breakthrough, I’d love to hear about it. Let me know your thoughts in the comments section below.

    — Chris Sachs

  • The Disservice of Cloud Consolidation

    The Disservice of Cloud Consolidation

    There’s no secret that over the past five years especially, the major (“tier 1”) cloud infrastructure players—Amazon, Microsoft and Google—have been snatching up smaller specialty providers, particularly cloud migration and security services.

    While this acquisition strategy immediately aims to strengthen and expand the provider’s direct and tangential cloud infrastructure offerings, the long-term goal is customer attraction and retention.

    In consolidating cloud infrastructure and related services, cloud vendors are targeting a basic human desire that often bleeds over into business decisions: convenience.

    • “Finding a cloud provider seems hard.”
    • “Switching to the cloud seems hard.”
    • “Managing more than one cloud seems hard.”
    • “Keeping up with more than one vendor seems hard.”

    The play is transparent; the marketing is already in your psyche. People don’t like doing more than they have to, whenever possible. So, why not apply that tick to the cloud infrastructure experience? Why not use a provider where everything is already in one place?

    Truthfully, the move toward cloud consolidation is a step in the opposite direction from where we should be going. The future lies in a multi-cloud approach, not a consolidated one.

    Multi-cloud approaches offer both businesses and their customers several advantages over consolidated infrastructure.

    • When a business’ cloud infrastructure exists solely with one provider, every cloud-related business activity—and every customer interaction with those activities—is beholden to the provider. A provider outage is a business-wide outage, and a business-wide outage is unacceptable.
    • Multi-cloud approaches allow businesses to take advantage of best-of-breed cloud infrastructure. A business can implement databases, containers and other virtual infrastructure in a more highly optimized way.
    • Data held in disparate systems can be better partitioned and more secure than data stored with a single provider. Also, these disparate systems can bolster adherence to existing (and likely coming) data privacy laws and compliance regulations both nationally and internationally.
    • Utilizing cloud infrastructure housed physically closer to a business or its key users can drastically influence business activities in industries where parts of seconds count (e.g., finance).

    Aside from the standard reasoning, I’d argue that there’s additional economic health in taking a multi-cloud approach. Competition naturally drives innovation, stabilizes costs and encourages improvement. Where one provider may falter, three others might specialize. If the majority of businesses consolidate their cloud resources with a single provider, though, the likelihood increases of services gradually worsening with no alternatives toward which to turn.

    Multi-cloud takes planning and coordination to properly implement, and careful monitoring to maintain. An additional tool or two, such as a cloud management platform or cloud integration solution (which, truthfully, many businesses are likely already utilizing), may be needed.

    But, the benefits far exceed the challenges. After all—to call upon Ken Jenkins’ iconic chief of medicine, Bob Kelso—nothing worth having comes easy.

    — Zack Busch

  • Service Meshes: Improving Security, Delivery and Availability

    Service Meshes: Improving Security, Delivery and Availability

    Containerized microservices are taking over the software world. These services provide developers a way to quickly create and deploy cloud-native applications. However, containers aren’t perfect. Orchestrating and managing container deployments can be a serious challenge. 

    To help ease this challenge, service meshes were developed. In this article, you’ll learn about service meshes components and architecture options. You’ll also learn how services meshes can improve your container deployments.

    What Is a Service Mesh?

    A service mesh is a dedicated communication layer that sits on top of your request/response layer. It works similarly to a Container Networking Interface (CNI), which controls the connection of your services to your network. A service mesh sits on top of your CNI, adding additional functionality, such as service discovery or security. A service mesh is not a replacement for a CNI or a service orchestration platform.

    Services meshes are designed for use with containerized microservices. You can use this technology with any container or container orchestration tools. However, the most active projects seem to favor developing service meshes for Kubernetes.

    Service Mesh Architectures

    When deploying a service mesh, there are three architectures you can choose from.

    Library 

    The library architecture employs a library that is imported in an application’s code and runs from inside the application. Using a library eliminates the need to call out to a remote service, making it more secure.

    Libraries make it easier to allocate resources since all work is contained in the microservice running the library. A library architecture works well for in-house applications that are written in one language. Third-party applications are difficult or impossible to add the library to.

    Node Agent 

    A node agent architecture uses a node agent or daemon that serves all containers on a particular node. A node agent architecture is language-agnostic since it doesn’t run from inside your microservice. It can be used with in-house and third-party applications. However, node agents must be coordinated with infrastructure processes, making this architecture more complex to deploy.

    Node agents require less memory than sidecars since information can be shared across a node. This architecture employs work resource sharing, with dynamically shared resources, making it easier to scale. The downside of sharing, however, is that it can be abused, with one service hogging all available memory.

    Sidecar Proxy 

    A sidecar proxy architecture uses sidecars that run alongside your containers. The sidecar handles all traffic into and out of the container it is attached to. Sidecars do not require coordination with your infrastructure since one proxy is assigned to each container. This lack of coordination makes sidecars easier to set up than node agents.

    Sidecars only serve one pod and are not influenced by other pods. This isolation makes this architecture better for zero-trust deployments as each container is accountable for its own actions. Sidecars can be added to containers at any time, enabling you to easily scale processes.

    Use Cases For Service Meshes

    Service meshes are an emerging technology, with new use cases being actively developed. The three use cases introduced here are just the ones that are currently most common.

    Improving Security

    Containers are isolated environments and generally considered to be more secure than traditional applications. However, containers still contain vulnerabilities, such as possible abuse of root access. 

    Service meshes can help address security concerns by providing:

    • Zero-trust security—any communication, either from inside or outside requires verification. Verification prevents compromised containers from interfering with other microservices or your broader system. It restricts a container’s actions and communications to that container alone.
    • Communication tracing—enables you to collect communications information and isolate errors or issues. If a container is communicating in an unexpected way or against protocol, you can identify it. Once identified, you can easily replace the container with an uncorrupted image or remedy the issue. Tracing enables you to pinpoint possible attacks, including where attackers came from and what they’re trying to accomplish.

    Improving Delivery

    Containers already improve on application and service delivery by making it easier to release and patch services. Service meshes expand upon these capabilities by improving application and performance monitoring functions. 

    Service meshes can also help improve service delivery by enabling:

    • A/B testing—provides advanced routing, enabling you to divide traffic between A and B versions. This routing makes it simpler to set up A/B testing. Additionally, tracing features enable you to gather and analyze user traffic and interactions.
    • Rapid versioning—new versions can be released with zero downtime and reduced risk. Containers can be started and verified healthy before traffic is gradually shifted between versions. If issues arise, changes can be rolled back without system-wide consequences. Easier corrections enable you to relax delivery requirements with minimal risk.

    Improving Availability

    Containers can provide improved availability, depending on your hosting configuration and resources. Service meshes can expand upon these abilities by improving load balancing, traffic management and health monitoring functionalities.

    Service meshes can also help improve availability by enabling:

    • Resilience testing—enables you to test how services respond with fault injections. Service meshes enable you to test your services’ fault tolerance. Increased understanding of how faults affect resilience helps you identify and correct vulnerabilities. Greater service resilience leads to greater availability.
    • Deployment and request shadowing—enables you to simulate anticipated traffic flow and see how services respond. Shadowing enables you to test the traffic and workload capacities of your services. With this information, you can determine whether you need to scale resources and connections. Proper scaling ensures that your traffic needs are met and prevents traffic bottlenecking and decreased availability.

    Conclusion

    As microservices become standard, teams are placing an increased focus on improving container performance and security. The development of service meshes is a result of this increased focus.

    Hopefully, this article helped you understand what service meshes are and how this technology can help improve your container deployments. If you’re interested in seeing how a service mesh might help you, check out this tutorial explaining how to build a service mesh.

    — Gilad David Maayan

  • DevOps Versus ITIL: How to Win the Battle Over Change Management

    DevOps Versus ITIL: How to Win the Battle Over Change Management

    Ever since DevOps came on the scene a decade ago, ITIL has been under siege.

    ITIL lays out a number of IT service management (ITSM) best practices, including release management, change management, incident management, problem management and many other aspects of running an IT shop so that its priorities align with the business’s. For many enterprises, ITIL is essential for governance and regulatory compliance–especially in heavily regulated industries.

    The basic idea of DevOps is that by leveraging better automation technology across the software lifecycle, it’s possible to rework the culture and organization of all the teams involved in software production and deployment. By breaking down the numerous silos and fostering greater collaboration, it should be possible to dramatically accelerate the ability to deploy quality software at scale.

    From the DevOps perspective, ITIL is nothing but a set of speed bumps and roadblocks, getting in the way of its continuous integration/continuous delivery (CI/CD) priorities.

    DevOps wants to speed up software release cycles, while change management often slows them down. Does this dichotomy mean that enterprises have to choose one or the other? Or perhaps we have to water down one of these approaches sufficiently so it’s marginally compatible with the other one?

    Is ITIL Part of the Problem?

    ITIL skeptics abound. “Frameworks like ITIL create the illusion of control that results in [the] organizational delusion that IT is efficient and manageable,” said Greg Ferro, long-time consultant and co-founder at Packet Pushers Interactive. “The single biggest problem in ITIL [is that] the creation of silos creates ‘not my problem’ attitudes.”

    One such silo is the change advisory board (CAB), a team that has the responsibility for making thumbs-up or thumbs-down decisions on numerous different activities across the IT organization. “Having the CAB review every single change request isn’t efficient,” said Kaimar Karu, head of ITSM at AXELOS, “and it’s definitely not common sense, especially when their costs can run to tens of thousands of deployments per hour in some organizations.”

    One organization that has struggled to transform their ITIL process as it moved to a DevOps model is financial services firm ING. In fact, its CABs were a point of contention for it. “We were just like an insurance company, always rejecting your first claim,” said Mark Heistek, IT specialist at ING. “And then come back if you have good arguments.”

    ING found it was able to modify ITIL to work within its new DevOps approach. “Don’t do everything the ITIL book says,” advised Jan-Joost Bouwman, ITSM process owner at ING. And yet, following ITIL for practices such as incident management are “still the best way to do it, because everybody knows what to do and you don’t get confused about the rules.”

    Or Is ITIL Part of the Solution?

    In spite of the skepticism, there are plenty of proponents of using ITIL with DevOps. “The DevOps Movement fits perfectly with ITSM,” according to Gene Kim, DevOps thought leader, author of The Unicorn Project and coauthor of The Phoenix Project. “ITIL and ITSM still are best codifications of the business processes that underpin IT operations, and actually describe many of the capabilities needed into order for IT operations to support a DevOps-style work stream.”

    Kim, however, focuses more on human capabilities than on the ITIL processes and procedures themselves. “ITSM practitioners are uniquely equipped to help in DevOps initiatives, and create value for the business,” said Kim. “ITSM skill sets are ever more important in a world where there is an ever-quickening business tempo.”

    Phil Tee, CEO and co-founder of Moogsoft, agrees with Kim–and also echoes the experience of Heistek and Bouwman at ING. “ITIL is not in conflict with DevOps,” said Tee, “but it must be adapted to DevOps practices in order to define clearly where issues arise and how to solve problems efficiently.”

    Adapting ITIL to work within the context of DevOps–without slowing it down–has become the crux of the discussion. “ITIL is not explicitly opposed to Agile and DevOps,” explained Charles Betz, principal analyst at Forrester Research. And yet, he found that “the overall ITIL narrative is still sequential, plan-centric and deterministic.”

    Rock and a Hard Place

    Part of the DevOps way of thinking is to reevaluate how the organization makes the decision to deploy software into production. “By combining developers and operations into smaller, more agile DevOps teams, organizations can build software more quickly than ever, enabling them to respond faster to changes in the market,” said RJ Jainendra, general manager and vice president, IT business management and DevOps business unit at ServiceNow. “But, that’s a difficult challenge for larger companies, however, that haven’t been able to realize the full benefits of DevOps for a variety of reasons, including the complexity of manual processes they manage, and a shortage of DevOps expertise.” 

    There are many business contexts where internal process or regulatory compliance concerns are the issue, introducing requirements beyond what current DevOps approaches can satisfy.

    Jumping to the opposite extreme and requiring rigid change management procedures, however, can easily be overkill. After all, even for the most heavily regulated, quality-conscious enterprise, some of the changes they put into production don’t have the same stringent requirements as the rest. Not all software changes carry the same level of risk.

    The challenge, therefore, is telling the difference–and putting into place proactive, automated ways of handling different change scenarios that are subject to different levels of rigor.

    Judicious Use of Automation

    In spite of what many DevOps zealots may say, the approach is inherently flexible and human-driven. People still create software, after all–and DevOps is more about encouraging new ways for people to cooperate to achieve a common goal than it is about offloading human tasks to automated processes.

    As a result, DevOps is not nearly as black and white as those zealots might have you believe. For example, the “continuous” in CI/CD doesn’t mean “all the time” or even “as fast as possible.” In practice, continuous means “as fast as practical given the particular business requirements that apply in this situation.”

    Sure, Amazon may deploy several times a minute and be able to easily integrate compliance and governance into their technologies, but that doesn’t mean you can, or even that you must. After all, enterprises have a very different business and technology context from web-scale, born in the cloud companies such as Amazon.

    You may simply have different requirements–and even more importantly, different software will likely have different deployment cadences, even within the same organization.

    These principles of flexibility and human-centeredness apply beyond deployment to all aspects of change–and thus, they apply to the change management and release management practices of ITIL more broadly. 

    Sometimes you need a CAB, and sometimes you don’t. Sometimes you need to change windows, and sometimes you don’t. Sometimes fully automated quality checks are sufficient for giving the green light for deployment, and sometimes they’re not–and so on.

    And perhaps most importantly, sometimes humans should make approval decisions, and sometimes those decisions should be automated. 

    The more you can automate these approvals, the faster your deployment will be. But if you are able to identify those changes that require human approval and route those accordingly, then you’ll have optimized how you handle change in a way that pulls together DevOps and ITIL practices.

    Bringing ITIL and DevOps Together in Practice

    Traditionally, ITSM products are ticketing systems. When some incident occurs or someone calls for a change, they must create a ticket that then kicks off a set of manual tasks, often by different people.

    DevOps can bring automation to this traditional ITSM context. “One of the modern miracles of DevOps principles and practices is that many parts of ITIL processes can now be automated, solving significant challenges, especially in the configuration, release and deployment management processes,” Kim explained.

    Such manual workflows are typically well-suited to supporting ITIL practices, but fall short of the speed that DevOps requires. “ServiceNow DevOps leverages the data and metadata it already has on its platform, combined with new information from the DevOps pipeline to create, automate, and manage ITSM changes from within DevOps workflows on an enterprise-wide scale,” said Jainendra.

    In fact, ServiceNow can oversee the full automation of the deployment, integrating with other DevOps tools as necessary to effect the change, eliminating the need for any additional action from a developer. On the flip side, when the policies in place require a human approval of a change, then ServiceNow routes the change to the appropriate person. 

    The Intellyx Take

    Automation, for all its benefits, has never been about taking humans out of the decision-making loop. On the contrary, automation takes low-value tasks off of people’s plates, allowing them to spend more time and effort on more valuable activities. Decision-making is often among those high-value activities.

    That being said, automation is getting better at making decisions, both because of the breadth of machine-understandable policy representations and other configuration metadata, as well as the increasing prevalence and sophistication of machine learning.

    For DevOps professionals, it’s essential to understand this increasing level of sophistication for the automation available in today’s tools. The choice between automated or manual is no longer a black-and-white affair. Instead, there are different levels of capability for automated decision-making depending upon the situation at hand.

    — Jason Bloomberg

  • How the Nuts and Bolts of the Internet Are Evolving to Change the Way You Code

    How the Nuts and Bolts of the Internet Are Evolving to Change the Way You Code

    2019 was a big year for internet infrastructure, programming languages and platform development. In the last 12 months, we saw things like new connectivity in the sky and the sea and greater security of those connections with the growth of TLS 1.3 and certificate transparency. But three trends in particular stood out as having some of the biggest impacts on developers as we head into 2020. 

    Rust Capabilities Boost Its Popularity

    Rust continued to grow in popularity as it was voted Stack Overflow’s most beloved language for the fourth year in a row, due in large part to its unmatched ability to free developers from the choice between safety and performance in a programming language. Before Rust, developers had to decide between languages like C, which is fast, but has a high likelihood of security failures, or Haskell, which comes with more safety, but is noticeably less performant. Rust provides a level of safety guarantees developers haven’t been able to enjoy before, while still delivering on low-level, native performance. The learning curve is fairly steep, but the batteries-included features you’d expect from a modern language check the boxes developers need to deliver on priorities next year. 

    HTTP/2 Paves the Way for HTTP/3, Allowing Developers to Build Even More Performant Sites Without All the Hassle

    Protocols that deliver and secure richer content saw progress in 2019, too, with HTTP/2 becoming the most common web protocol and a glimpse of the even greater benefits of HTTP/3 to come in 2020. HTTP/2 made developers’ lives easier by simplifying the hacks and workarounds they had to do to get performant sites working with HTTP/1.1 by addressing the complexity of lots of tiny objects within a page. By reducing page load times and improving responsiveness, HTTP/2 has paved a solid foundation for HTTP/3, which has the potential to become widely deployed in early 2020 as the new transport protocol, QUIC, nears completion. QUIC, a replacement for TCP, addresses the head-of-line blocking delays HTTP/2 exhibits for some p90 scenarios. Additionally, QUIC incorporates TLS 1.3, ensuring an easy upgrade to the most recent version of the internet’s standard security functionality.

    WebAssembly Promises New Possibilities

    Most excitingly, love for and support of WebAssembly (Wasm) by developers picked up steam in 2019 due to the recognition it has received for its secure, performant, cross-platform and cross-device runtime. A glimpse into Wasm’s future promises greater portability, as it allows developers to take the code they have written and run it on entirely different platforms, at scale. Wasm is a sea-change for the entire industry as programs will be able to work not just on different browsers—as we saw with the Google Earth launch on Wasm—but beyond the browser, across various devices and platforms. Think watches, TVs, cars and security systems that can be more securely connected—not to mention the functions-as-a-service speeding up the world on the edge. With the backing of the Bytecode Alliance, a newly formed collaboration between Mozilla, Fastly, Red Hat and Intel, Wasm becomes a prime foundation for more secure and portable software development in 2020.

    With all the changes in 2019, 2020 stands to be another exciting year for developers, bringing even greater flexibility to their roles and career opportunities. Ongoing internet infrastructure improvements continue to empower our developer community and enable more secure and efficient programming and computing—all while improving the end-user experience.

    — Tyler McMullen

  • DevOps Unbound: How DevOps has Changed Testing Forever

    DevOps Unbound: How DevOps has Changed Testing Forever

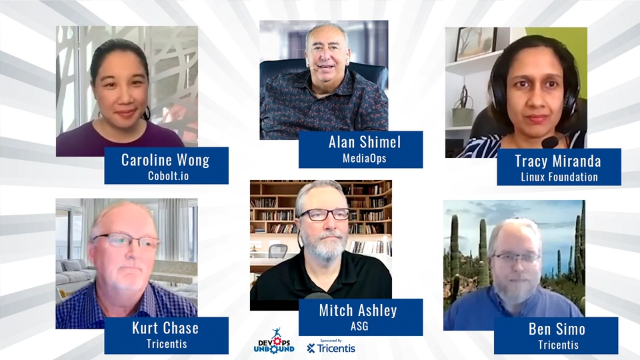
    DevOps has changed the game in almost every aspect of testing: who, what, when, where and even why. What’s working, what needs to change immediately, and what challenges—and opportunities—lie ahead? Hosts Alan Shimel and Mitch Ashley are joined by Abel Wang from Microsoft, Tracy Miranda from CDF, Caroline Wong from Cobalt, Kurt Chase and Ben Simo from Tricentis to share a variety of perspectives on how testing fits into the ever-evolving world of DevOps. The video is below, followed by a transcript.

    DevOps Unbound is sponsored by Tricentis, the world wide leader in automated testing. DevOps Unbound airs biweekly on TechStrong TV, with all episodes available on Digital Anarchist. There is also a live monthly roundtable open to audience participation.

    Alan Shimel: Hey, everyone. Thanks for joining us on this special edition of DevOps Unbound. You’re watching this, probably, at the Tricentis Virtual Event and we are happy to have you join us, happy that you’re attending the event, and we’ve got what we think is gonna be a great discussion on testing and all of its various facets and what does the future – or near future – hold. We’ve got a great lineup of speakers that I’d like to introduce you to who are on our panel today. Let me first start with – she’s on the top of my screen – is Caroline Wong. Caroline, why don’t you say, “Hello” and introduce yourself?

    Caroline Wong: Hello. My name is Caroline Wong. I’m the Chief Strategy Officer at Cobalt. So, at Cobalt, what we do is pen testing as a service. We build a security software platform – like a lot of DevOps companies.

    We have data-driven product-based teams. We have – we really value automation and failing fast. I’ve spent 15 years in the information security industry. I wrote a book called Security Metrics. I host a podcast called Humans of InfoSec, and I teach the OWASP Top 10 Learning Path on LinkedIn Learning, and super excited to be here with this group today. Thanks for having me.

    Shimel: Thank you, Caroline. Next up, we have Kurt Chase.

    Kurt Chase: Hey, everyone. I’m Kurt Chase. I’m currently Head of Release Management and Engineering Services at Tricentis. Engineering Services is a group that supports the engineering function so, we do our own type of testing – testing all the processes and everything we use – to deliver our software at Tricentis. So, prior to Tricentis, I spent some years at Splunk and at AutoDesk. It’s great to be here with all of you today.

    Shimel: Fantastic.

    Chase: Be here today with all of you.

    Shimel: We got what you meant, Kurt. It’s okay. Next up, we have Ben Simo. Ben, why don’t you introduce yourself?

    Ben Simo: Hi. I’m Ben Simo. I’m a software tester of 30 years and past president of the Association for Software Testing who has recently stepped into a product management and product research role at Tricentis trying to discover and develop our testing platform of the future and bring new things to Tricentis customers and hopefully introduce new people to Tricentis with new products that enable new ways of testing.

    Shimel: Okay. Happy to have you here. Next up, Tracy Miranda. Tracy – well, I’m gonna let you introduce yourself. Go ahead.

    Tracy Miranda: Hi, everybody. I’m Tracy Miranda. I’m the executive director at the Continuous Delivery Foundation. It’s an open source organization that’s part of the Linux Foundation, and also home to projects to like Jenkins and Spinnaker, and our members include companies like Netflix and Google. And I have over 20 years of experience in open source so, I love open source and I’ve worked in it as a developer – also in QA and all different facets. So, yeah. Big fan.

    Shimel: Thank you, Tracy. Last, but not least, is my co-host on DevOps Unbound – my partner in crime here, Mitchell Ashley. Mitchell, why don’t you introduce yourself?

    Mitch Ashley: Thanks, Alan. Yes. I’m CEO of Accelerated Strategies Group, which is an analyst firm that focuses on, in addition to cyber security, digitial transformation, DevOps, and cloud-native kinds of applications, which really matches my background very well. I’ve been both a product creator CEO/CTO as well as running IT, CIO, CSO – that kind of thing. So, currently, I’m also CTO with MediaOps – I guess CSO at MediaOps, too, so, I’m trying to collect as many three or four-letter titles as I can. So far so good.

    Shimel: Alrighty. So, first of all, thank you all for coming on today. Secondly, testing – what a wild, mixed-up world we have in testing, right? Just from looking at the folks on our panel today, we have security testing – pen testing, in particular. We have the world of open source and what a factor that is in testing.

    We have product testing, right? We have sort of new product testing – taking testing to new heights. And you know, that variety is sort of a double-edged sword, right? Because it’s like jack of all trades, master of none type of thing. There’s so many aspects of testing, right?

    Even in our audience here at this virtual event, we have testers who come from, you know, what’s called old line QA testing, right, to DevOps enabled testing to visual testing – testers who, if it’s not an open source testing platform, they won’t use it, to proprietary systems. Through it all, though, a lot of times, all of this testing becomes sort of a red-headed stepchild or a whipping boy, if you will, right, to the whole application development system operations teams. It’s like, at the same time, their best friend and their worst enemy, right? They want everything tested, but they don’t want to give you the time, the budget, or the resources to do it, and then, when something doesn’t work, they said, “Well, we should have tested more, right?” So, how – first of all, do we agree that testing has been sort of the whipping boy of a lot of what we’ve seen go down in app dev and operations? Anybody want to jump on that?

    Chase: Well, I think it’s certainly gotten a bad name. I think some of that comes from prior to the digital transformation. A lot of the engineering was waterfall, and testing was always that last stop before the software went out live, you know? Nowadays, I think everyone’s come to realize the speed and scale at which we develop things, you have to do the testing up front at the very beginning. You can’t wait till the end, you know?

    You’re gonna be too slow. So, I think, from that perspective, absolutely. I think that’s why testing has really, I think, gotten a bad name, because they’re kind of the blockers to getting anything out into the public domain, whereas nowadays, you have to enable that up front because you want to get it into the public domain yesterday.

    Shimel: Yeah. And so, in many ways, to me, that sounds like, well, DevOps has been the best thing that ever happened to testing, right? In many ways, DevOps has been the best thing that’s happened to security testing, right? We’ve certainly seen that shift left, if you will. But has that shift left helped – has that rising tide lifted all boats?

    Miranda: I still see –

    Shimel: Oh, okay, Tracy. Go ahead.

    Miranda: I’m gonna jump in and say one thing that strikes me as funny. Like, we have, in our industry, everybody has embraced the DevOps terms, and then, you start to see all these spinoffs to put emphasis on things like, for security, we have DevSecOps, and you’ve got every variant of something with ops. But when it comes to testing, you know, there’s no TestOps. There’s no new buzzwords and it kind of speaks to how much it’s being neglected. Like, we had a conference on continuous delivery, and we asked for talks of everything in the life cycle, and we got lots and lots of submissions except for testing.

    So, again, I think it still is really under-appreciated and just not given the due credit for what it stands for.

    Shimel: Very –

    Simo: Yeah. And I think some of this comes from, as Alan mentioned, that testing is a very broad and diverse subject, and I’ve often watched people argue about testing that each interpret it to their piece of what they do with testing. And things like CI and some of the DevOps practices have helped us improve with the checking that our software can work – you know, demonstrating that it can work – and there’s a lot of people – if you primarily wear a developer hat, you’d look at that’s what testing is. And we’ve automated that.

    There’s been huge improvements in tooling and technology to do that, but sometimes, along with that is we throw out that we need someone involved that’s looking at things from a critical perspective that’s concerned about the safety and efficacy of what we’re delivering that is the, I guess, the one questioning and searching for information that they raise issues that we need to deal with that are reasons to not push things out to production now – so that we can make informed decisions. So, often, I think just that critical side gets thrown out as we improve the other side of testing, which is being able to demonstrate that things can work.

    Shimel: Anyone else?

    Ashley: You know, Alan, one of the ways you can tell who drew a diagram is to look at what’s in the center. And so, if we think about CICD, we kind of surround testing, but we don’t talk about testing. So, in some ways, it’s elevated, and some ways, it still sort of abstracts it out of DevOps. But my experience has been not really, because most teams know that testing has to get automated as part of that process, ’cause you can’t have this automated checking and automated deployment, then let’s kind of let a bunch of manual things happen. And not that testing hasn’t been automated – it has been – but I think it has elevated, at least in part, I think a good deal.

    My experience has been. I haven’t worked in every environment, maybe, where test still isn’t thought of very highly. By the way, the thing that the – it isn’t the last thing in the chain. Documentation is the last thing.

    Chase: That’s true. That’s true.

    Ashley: Let’s give documentation –

    Chase: And release notes. It’s true. I have tech doc’s team, too. You’re right. [Laughs]

    Shimel: And that hasn’t really changed much either, though testing has. No. No. But you know what? Caroline, I’d like you to focus in specifically.

    I mean, I think about – you know, Mitchell and I co-founded a security company, and we came out with a product in 2003 of just a vulnerability assessment and manager – “VAM”, we called it – and at that point, look, we used to beg people to scan their infrastructure at least once a year, right, if not quarterly. We were really pushing for quarterly. And you know, the idea of scanning and testing applications before you deployed them – unheard of. It was unheard of, right? We didn’t have the security tools or people.

    We did that after the fact. Now, that’s not normal anymore, right? Today, at least 85 percent of applications are tested prior to deployment. I don’t know who those other 15 percent are, but that’s a whole nother story. But talk to us.

    You’ve lived through this, Caroline. What do you think?

    Wong: Sure. So, you know, I think there needs to be an acknowledgment. There’s sort of these like, first order priorities and these second order priorities. When I think about security – and I think some of these concepts apply to testing more broadly – there’s a saying that, “You don’t take a $200.00 fence to protect a $5.00 asset.” I think security is about you have something of value and so, you want to test it – rather, so, you want to secure it.

    Testing, I think, is like you made something new and so, you want to test it. You’re not gonna test something unless you have something new. You’re not gonna secure something unless you have something of value. So, it’s okay that security and testing are not sort of the number one thing, you know? Inherently, by their definition, it’s sort of a second order attribute, if you will.

    Now, I think, you know, each of us has been through a version of annual organizational budgeting. You know, each organization says, “Okay. Here are the goals for the years. We’ve got limited resources and budget to accomplish those goals. How are we gonna allocated those resources?”

    And there are some things that, for a lot of organizations, are very clear. You know, even if I take a step way back and I say, “Okay. Most organizations might think about budget allocations in three buckets. Number one – general and accounting; number two – sales and marketing; number three – research and development.” You know, nowhere in those words is either security or testing.

    And that’s okay, you know? I think, Alan, when you share your story about VAM, you know, Vulnerability Assessment and Management, I agree that over the last, I would say, decade-two decades – so, when I started my security career 15 years ago, we were almost trying to convince folks that breaches really happened – that this was really a thing to be worried about. You know, today, everyone knows because it’s on the media headlines every day. This is real. And so, that has been a shift in the perception, I think, in our industry.

    There’s also been a big compliance driver. So, the – in the area that I’m very familiar with, security pen testing, a lot of that pen testing is actually driven by external compliance requirements – things that say, “Because of compliance framework A, B, C, you must actually conduct manual pentest on your application, for example, once a year.” You know, doing it more often than that is often because of perhaps what a lot of this group might think of as a really good thing – trying to actually secure your software, trying to actually test your software to ensure it does what you think and what you intend for it to do, but that’s not necessarily the first thing that comes to an executive’s mind when they’re thinking about budgeting, and there’s a variety of reasons for that, right? There’s an external perception thing. I think there’s also a lot of learning, certainly, that the security industry can do to be more approachable and to really understand better what is the software development methodology that we’re engaging with.

    What is the specific methodology and behaviors of these individuals? And how can we actually collaborate with them most effectively?

    Shimel: Fair enough. I mean, look, I don’t want to be the pessimist in the group or the bluebird of happiness here, but we have had success over the last 5-10 years, Caroline. You’re right. Especially in security, but not just security. We’ve had success in testing across the board.

    Tracy, to your point, the fact that we don’t have DevTestOps, I think, is, you know, testament to the fact that we’ve recognized that testing is so critical to the CICD process that it’s part of it. I mean, you can’t have DevOps, you can’t have CICD without a level of continuous automated testing in there – in my mind, anyway. I mean, prove me wrong. But, you know, I think that has been probably one of the biggest successes that the DevOps movement has brought – has been responsible for.

    Miranda: Yeah. And I really like Caroline’s analogy with security because, you know, that’s something else we think of as fundamental to DevOps, but it’s sort of elevated itself and, in a relatively short space of time, went from being ignored to being, you know, headline news. And I think there’s a lot of lessons there. And I – like, I will say, I do think testing is going through that journey and we’re probably on the cusp of it kind of really exploding and watching a few players in the industry and companies starting to do really interesting work in testing. I think that’s gonna turn around very shortly.

    So, yeah, there’s an exciting space that I think its moment is coming – just like securities has.

    Chase: Yeah. I think it’s all about the testing now, quite honestly. I mean, when you look at the future with low-code/no-code, it all becomes question-question mark ops, you know? Any function in a company could actually put something together and run it, and they’re gonna have to test it, you know, and it becomes less about all the engineering and more about the test patterns and things like that that are needed as you get to these future states. So – and speed and scale is gonna continue, I think.

    That’s driven everything with the digital transformation. It’s speed and scale. Everything needs to come faster, and we want more of it, you know? And so, I think that really pushes the envelope, and that’s what DevOps has responded to and, I think, addressed very, very well, but it’s not over. We’re gonna continue to scale up and go even faster.

    So, we have to be prepared for that, and I think it becomes more about testing in the future, and less about, you know, we’re gonna have these pre-built components – APIs you can piece together however you want – then, testing becomes, I think, almost first order, to Caroline’s point. And security, especially. I think security, we’re seeing that change now. If you’re a SAS company especially, security has to be top in line, ’cause you just can’t put something out there and not have it tested from a security perspective. And, furthermore, with compliance, it’s not just ISO and GovCloud and those programs, but large corporations now are saying, “Hey, if you want software in my ecosystem, these are my rules and I want to see your pentest reports and I want to see this.”

    So, I think more and more people are realizing that if the software’s not tested, it’s not worth it. And so…

    Simo: And, in my experience, part of adopting a DevOps culture and not just tool set is putting testing at the forefront. Some of the most productive teams that I’ve worked with that deliver some of the highest quality software I’ve seen – testing was center to absolutely everything that everyone on those development teams did.

    Ashley: Hm-hmm.

    Chase: Yep.

    Shimel: Yeah.

    Miranda: Yeah. We think – go ahead.

    Ashley: I’m just gonna jump in and say – there’s another factor that actually works to our benefit and that is not only to speed through automation and DevOps process, but contemporary software architectures, containerized micro-services, service mesh – we’re releasing smaller bits of code in encapsulated forms, which means, you know, we’re not testing monolithic applications all the time anymore so, we’re not having to run two weeks’ worth of tests just to get one pass through.

    Chase: Yeah.

    Simo: Right. _____ container solved the “It works on my machine” problem because we can ship the developer’s machine.

    Chase: Yep.

    Shimel: Yeah. That was always a big problem, right? Tracy, you were gonna say something though.

    Miranda: Yeah. No. I think the direction we see it heading is we’ll start breaking the testing monolith to talk about what is unit test, what is system test, and appreciate that is a specialization in itself. And the other things I’m starting to see from some of the end user teams we talk to is this real focus on culture – you know, a continuous quality culture – and seeing that hand in hand as part of the testing movement and again, _____ back to security – you know, the security first culture went hand in hand with that whole emphasis on security so, similarly, the continuous quality culture is starting to be something that – like, the really high performing teas we see pay a lot of attention to.

    Shimel: Absolutely. You know, Kurt, you said something there about low-code/no-code and how that could be a game changer. You know, some people refer to that as the rise of the citizen developer, and I’m wondering if maybe what we need is the rise of the citizen tester, right? Is testing too hard?

    Chase: Yes. I waste gonna say – the one thing we haven’t touched upon – I think Caroline did – is testing is hard. Security testing is super hard. And when you look at today’s modern environment and a lot of the ISVs – at least the ones I’ve seen and been associated with – you have a legacy of monolithic applications that you have to support that are bringing in a ton of revenue, and, at the same time, you’re transitioning – you know, going through your own digital transformation. So, that adds complexity after complexity in testing, and I do think, in the future, testing – you know, a lot of us, like Ben said, to his point, we have to push testing up – you know, shift left, move it far left as we can.

    And that’s gonna continue. I think that has to be the norm. To Caroline’s point, it has to become first order. And I think it’s starting to right now. I really do. Especially the – all the SAS solutions that are out there – you know, shipping code daily, hourly. You need excellent testing to do that and do it with competence.

    Shimel: Yeah. I think you do. But we do have to – and it’s funny that we’re talking about making testing easier because – not security testing, right? Security testing, pentesters – they were always sort of the hired guns of the security space, right? There were SAS or – there weren’t companies like Cobalt, right?

    The pentesters that I knew growing up – growing up – you know, that I knew coming up in the security space were gun slingers. These were, you know, white hat/gray hat folks who would come in and they’d do a little social engineering and pen testing using some open source tools, and you know, they give you a report. But you know, these were folks who traveled around the world doing that kind of thing. You know, we didn’t have a company like Cobalt that did this as a service, so to speak. So, it’s very different.

    But here’s the underlying thing with like, QA kind of testing – and, you know, I don’t mean any disrespect to anyone in our audience today, but for too long, a lot of folks in testing were viewed as failed developers or people who couldn’t be really good developers did testing or maybe testing was a weigh station on the way to becoming a real developer – like a Pinocchio stop or something, right, where you’re not a real boy yet. But that’s not true. There’s also – there’s a whole cadre of professional testers. And you know, in their capable hands, you could do great things. But I guess the question is – does testing have to be so hard that we need professional testing – professional testers to do testing?

    Or can we make testing automated enough that you – I’m not saying it has to be the dunces who don’t become developers. That’s ridiculous. But can we broaden the base of people who do testing? And that includes security testing? I’ll throw it out. Ben, you were a big-time guy in the testing industry. Tell us – what do you think?

    Simo: So, I think we can expand who’s involved in testing and that more people than those currently doing testing can learn to do testing. I don’t know _____ developers learning to become better testers and test their stuff. But I will say that ultimately, the part of the work that is the testing cannot be automated. Tasks that we do in testing can be automated. So, whether – not matter what hat someone primarily wears, if it’s a developer, you know, writing tests to demonstrate their code works or someone’s using TDD and they’re building some tests and then, building some code that matches it, the testing is the critical evaluation that’s going on in their mind of solving the problem and demonstrating that it’s solved – or evaluating how something might go wrong and coming up with some approach to demonstrate that it may go wrong and check for that.

    So, those things, whether you’re doing it automated or the execution is automated or done manually, the actually testing work, I’d argue, is the cognitive work that people are doing. And there is some – that we can never automate away. There are some ways that I think AI can help us. There’s also some ways that may lead us astray. But ultimately, I think we need people to learn to be critical thinkers to understand the technology, to understand the domain of the users and the problems that are being solved, and applying that critical thinking is the testing.

    Of course, then, we want to use tools to help us with some of our tests so, when we come into DevOps and CI, executing those demonstrations of the software working is a key part of that. Now, whether we do it as part of our, you know, building to those tests or we create them afterwards, then they can, at the very minimum, act as changed detectors going forward. But there was some testing in people’s minds that was going on that created those.

    Shimel: Caroline, what about – okay.

    Wong: I agree with quite a lot that Ben is saying. You know, I can’t help but think to myself that – I actually have this sort of visual in my mind, and it’s actually at a circus of a trapeze artists, you know? I think about these people, and they’re sort of like, whirling in the air and they’re doing these like, really incredible feats, you know, and they just do whatever they do, you know? But there’s like, a safety net to catch them if something goes wrong. It also reminds me of a metaphor that is often used in security that says, “We put brakes on a car so that you can go fast.”

    You know, when Mitch said earlier, you know, “These days, we’re releasing smaller pieces of code, modules of code” and there’s a way in which, yes, each small piece of code – each module – can be tested and some of that can be automated. We should automate performance testing. We should automate unit testing. But, to Ben’s point, there’s a lot that can’t be automated. There’s a lot of testing that actually depends on things like human judgment and opinion and it actually requires a person’s decision, you know?

    So, I think there’s – I think there’s a couple of frameworks for us to consider, right? If the first order is about creating value and making something new and the second order is about testing to make sure it does what you wanted it to do and protecting the value created, there’s also this spectrum that says there’s smaller bite-size stuff that may be a good candidate for automated testing, but, I think it’s super important to recognize that these small pieces of code – these modules that Mitch was talking about – it’s also super important to test what happens when they come together. So, to the extent that security folks need to be able to test chained exploits and business logic flaws, you know, those are exactly the types of things that will never be automated – is what I think, anyway.

    Shimel: I don’t disagree. I think security in particular is just there’s some things you’re just not gonna automate. I don’t care what you say. But that’s okay. Anyone else?

    Chase: I do want to make a comment on something you said. This was a long time ago now, when I was a dev manager, that I used to sense that when my developers – you know, if you were on my team, if you wanted to really get me mad, treat your tester badly. Treat them, you know, a bit, like you said, like they’re not quite at the level you are. I would be incensed as a manager. You know, that was a long time ago.

    Fortunately, I don’t see that as much nowadays. I think that role has been elevated where I don’t feel that at all on my teams, and if I do, that is, again, to this day, I’ll get super mad about that because I think it takes all kinds to develop software today and ship software. Testing role is just as critical as an engineering role, just as critical as the ops’ role, the security role. So, yeah, that was one thing that would drive me nuts ’cause I did sense that and go through that, and this back in, you know, the late ’80s-’90s, if you will, before the year 2000 – I’m dating myself – but it definitely was palpable in some of the large ISVs, you know? And as a manager, that was something that would drive me nuts.

    Shimel: Agreed. Agreed. Tracy, open source – look, testing has been inexplicably wound up with open source for as long as I’ve been around, right? Whether it’s security – open source security testing and you know, things like Metasploit and Nessus and Nmap or you know, in QA testing kind of stuff, it’s a rich history of open source testing tools. How do – and part of your mission at CICD is – at the CICD Foundation – is to nurture that, I’m going to assume, correct?

    So, how do you guys nurture that? What are you – what do we do to maintain that rich, open source tradition here?

    Miranda: Yeah. No. Absolutely. And, as I say, we at the Continuous Delivery Foundation, we want to look across the entire software delivery life cycle, and I think it is safe to say, you know, that testing hasn’t risen to the top. We’re actively – like the board wants it to be a more focused-on topic, the technical committee wants to encourage folks to bring us more projects in open source and with testing, but we’re still having to kind of fight through all the noise around other projects.

    And one of the ways we’re approaching it is, for example, our technical oversight committee wants to set out a landscape of the types of projects in each kind of bucket and say, “Okay, look. We need to have something in security. We need to have something in testing that covers these different aspects.” Almost like a call to action to say, “Bring us your testing projects and –” like my favorite saying about testing is, “There’s two key problems in testing – not enough tests and too many tests.” And yeah, I think we’re starting to see some really good frameworks around test generation.

    I’d love to see more open source options for that. And Kohsuke Kawaguchi, the famous creator of Jenkins, move on to focus on testing so, that says a lot about the importance of this area getting more open source focused. So, yeah, I’m excited to see what could come out, but we do have to actively encourage folks to come join us and have those conversations and not to, you know, have it assumed it’s all focused on delivery of pipelines for delivering software.

    Chase: I think another thing you’re seeing today is a lot of people, when they start developing an app, when they start creating something new, that’s the question they ask up front. “How are we gonna test this? How are we gonna automate it? How are we gonna pentest it?” I think those things, at least, are starting to bubble up a lot stronger in the cycle – you know, early on. ‘Cause I know that’s something we recommend highly – is that if you’re developing something new or need to head down a digital transformation, think about the testing. How are you gonna test that up front, you know? And products are actually being developed with that mindset now.

    Simo: And with short iterations, it’s how are we going to test this tomorrow, next week? It can’t be left off for months later to be someone else’s problem. So, people, I think, are learning to deal with those questions about testing from the start of their discussions about what the requirements are.

    Chase: The other thing I love – and in Caroline’s world, has been very successful – I know it is specialized skill set, but trying to teach that throughout your troops – you know, throughout the engineering team. Show them what, you know, across _____ scripting errors. What does it look like in code? That’s super successful. That really, really helps make – ’cause security is difficult, you know, no matter how you slice it.

    Even when you’re looking at product development – if you want to invest in fixing security defects or add a cool new thing for your users, you know, a lot of times, the cool new thing is gonna win out. But that’s starting to change as well, too. I think people are starting to value security – especially in today’s modern world, you know? It has to be up front, really.

    Ashley: Yeah. It’s all about AppSec at the moment. That’s one of the hot topics as well. You know, someone mentioned AI earlier. I just want to offer a perspective about that because we always seem to focus on the shiny new object.

    I know I have. I often do. But I think what we’ll see with AI is select applications when it comes to testing. The sort of vertical place is where it’s really well suited. When we say, “Yeah, AI”, we really mean machine learning in most cases, which is machine learning algorithms, and there’s two types – there’s supervised/unsupervised.

    Supervised is, “That’s a car. That’s a car. That’s not a car, right? That’s a bug. That’s a bug.”

    And unsupervised takes massive amounts of data and intellectual patterns and learnings from that. So, I think that as we’re taking our test automation and our test tools, there may be some of that, and it might be really useful for AI. I wouldn’t get worried about people being replaced as testers. Not in my lifetime, that’s for sure. It is still a – there’s very much a craft to it, just like there is software design.

    There is a craft to testing and a skill and a mentality about it that’s unique, just like with security.

    Shimel: No doubt. Caroline – oh, go ahead, Ben. I’m sorry. No, no, Ben. Go.

    Simo: Yeah. I was gonna say – and with any other sorts of automation – even you know, not learning automation that’s come before AI and machine learning based things, is that it not only has potential, in some cases, to replace some of the mundane work we do, but to enable to the skilled people to focus their work and apply their brain power to the things that really matter. So, I think there’s great potential for AI to help direct people’s attention to the things that maybe should be of concern and help deal with that big question of testing out of infinite possibilities of PaaS and data variations. Which one’s gonna show me the problem? And I think there’s huge potential for AI to help us find that if we’re also aware it may guide our eyes away from something that we do want to see.

    Shimel: Caroline, how does that relate to security, though? I mean, is AI helping Cobalt with pen testing? Be honest.

    Caroline Wong: So, the type of software that we’re building today is actually workflow and collaboration software. So, what we’re trying to do, is we’re trying to bring security folks and developers and penetration testers all together sort of in one place where they can collaborate. The technology piece, for us, is not about automating defect discovery. It’s not – I mean, if we’re gonna us ML or AI in the future, honestly, what we’re gonna do is we’re gonna use it to say, “What are the characteristics of this organization that wants us to do a test on this particular type of asset? What are the attributes of that asset and how might we match that to our talent pool – something that we do totally manually today?”

    I think that’s the opportunity. I don’t think that we’re gonna get to a point where we’re using the AI and the ML for automating the defect discovery itself. Frankly, I think that even if I take a step away from pen testing and I look at the security scans that are in existence today, I think, you know, whether or not they’re referred to as using AI or ML techniques, they’re just simply imperfect, you know? And there’s a super important place for them, but there’s a lot of false positives. There’s a lot of interpretation of data.

    And I think that’s always gonna be the case. I think that no matter what, when it comes to humans and machines, the machines can add a lot of value, but I don’t know that when it comes to software development testing and security in particular that there’s every gonna be a complete substitution. I don’t think that – I don’t think that makes sense.

    Shimel: Absolutely. So, guys, we’re coming up on the end of our time. I need to wrap up. Tracy, let me say this for you, if you don’t mind – and if I’m wrong, correct me. For you testers out there, the CICD Foundation – or CD Foundation, actually; I keep – we always say “CI” like it’s attached at the hip – but the CD Foundation is looking to hear from the testing community.

    Probably some companies – including Tricentis – may want to look into becoming involved with CD Foundation because if you don’t have a seat at the table, you don’t have a right to complain about not being heard. And so, you know, when we look at foundations like Linux Foundation and the CD Foundation, CNCF, we need the testing community – vendors, professionals, folks in it, you know – to be involved and get involved. Be heard and be part of it. So, I’m gonna extend that out there to everyone. But, short of that, though, Caroline, Tracy, Kurt, Ben, and, of course, Mitch, thank you so much for joining us on this special edition of DevOps Unbound.

    We hope everyone enjoys the rest of their Tricentis Virtual Summit. This is Alan Shimel for MediaOps, DevOps.com, Security Boulevard, Container Journal, Tech Strong TV. Have a great day, everyone, and thanks for joining us.

    [Musical outro]

    [End of Audio]

  • Breaking Down the OWASP API Security Top 10, Part 2

    Breaking Down the OWASP API Security Top 10, Part 2

    Due to the widespread usage of APIs, and the fact that attackers realize APIs are a new attack frontier, the OWASP API Security Top 10 Project was launched. From the beginning, the project was designed to help organizations, developers and application security teams become increasingly aware of the risks associated with APIs. This past September, the OWASP API Security Top 10 release candidate (RC) was finalized and published on OWASP.

    In my first article on this topic, I provided a high-level view of the interaction between API endpoints, modern apps and backend servers, in addition to how they’re different from their traditional browser-based counterparts. I also discussed why this project was so important to the contributors and industry overall. 

    In my second article, I focused on the first five risks and emphasized some of the respective possible attack scenarios. In this article, I will attempt to clarify the last five risks to help organizations understand the dangers associated with deficient API implementations. The following discussion follows the same order as found in the OWASP API Security Top 10.   

    API6:2019 – Mass Assignment

    Modern frameworks encourage developers to use functions that automatically bind input from the client into code variables and internal objects. Which means users should have the ability to update their user name, contact details, etc. (within their profiles for example), but they should not be able to change their user-level permissions, adjust account balances and other administrative-like functions. An API endpoint is considered vulnerable if it automatically converts the client input into internal object properties, without considering the sensitivity and exposure level of these properties. This could allow an attacker to update things they should not have access to.

    Example Attack Scenario:

    To illustrate this further, imagine a ride sharing application provides the user the option to edit basic information about themselves in their user profile. For example, they can adjust their user name, age, etc. In this case, the API request would look like this: PUT /api/v1/users/me with the following legitimate information {“user_name”:”john”,”age”:24}

    However, the attacker determines the request GET /api/v1/users/me includes an additional credit_balance property (field) as shown below.

    {“user_name”:”john”,”age”:24,”credit_balance”:10}.

    The attacker desires to increase their credit balance on their own and replays the first request with the following payload:

    {“user_name”:”john”,”age”:24,”credit_balance”:99999}

    Since the endpoint is vulnerable to mass assignment, the attacker can easily adjust their own credit_balance at will, for example changing it from 10 credits to 99999 as shown above.

    API7:2019 – Security Misconfiguration

    Attackers will often attempt to find unpatched flaws, common endpoints or unprotected files and directories to gain unauthorized access or knowledge of the system they want to attack. Security misconfigurations can not only expose sensitive user data, but also system details that may lead to full server compromise.

    Example Attack Scenario:

    Say for instance that an attacker uses a popular search engine such as Shodan to search for computers and devices directly accessible from the internet. The attacker found a server running a popular database management system, listening on the default TCP port. The database management system was using the default configuration, which has authentication disabled by default, and the attacker gained access to millions of records with PII, personal preferences and authentication data.

    API8:2019 – Injection

    Injection vulnerabilities cause computing systems to potentially process malicious data that attackers introduce. To put it in its simplest terms, attackers inject code into a vulnerable piece of software and change the way the software is intended to be executed. As a result, injection attacks can be somewhat disastrous, since they normally lead to data theft, data loss, data corruption, denial of service, etc.

    Example Attack Scenario:

    Suppose an attacker starts inspecting the network traffic of their web browser and identifies the following API request designed to help a user recover their password. The attacker identifies the request responsible to start the recovery-password process as follows: 

    POST /api/accounts/recovery {“username”: “john@somehost.com”}

    Then the attacker replays the request with a different payload: 

    POST /api/account/recovery {“email”: “john@somehost.com’;WAITFOR DELAY ‘0:0:5’–“}

    By adding the ;WAITFOR DELAY ‘0:0:5’–” the attacker observes that the response from the API took five seconds longer, which helps confirm the API is vulnerable to SQL injection. Exploiting the injection vulnerability, the attacker was able to gain unauthorized access to the system.

    API9:2019 – Improper Assets Management

    Old API versions are often unpatched and can become an easy way to compromise systems without having to fight state-of-the-art security systems, which might be in place to protect the most recent API versions. Attackers may gain access to sensitive data, or even takeover the server through old, unpatched API versions connected to the same database.

    Example Attack Scenario:

    Say for instance that an organization redesigning their applications forgot about an old API version (api.someservice.com/v1) and left it unprotected, and with access to the user database. While targeting one of the latest released applications, an attacker found the API address (api.someservice.com/v2). Replacing v2 with v1 in the URL gave the attacker access to the old, unprotected API, exposing the personal identifiable information (PII) of millions of users.

    API10:2019 – Insufficient Logging and Monitoring

    Without logging and monitoring, or with insufficient logging and monitoring, it is almost impossible to track suspicious activities targeting APIs and respond to them in a timely fashion. Without visibility over ongoing malicious activities, attackers have plenty of time to potentially compromise systems and steal data.

    Example Attack Scenario:

    Imagine that a video-sharing platform was hit by a large-scale credential stuffing attack. Despite failed logins being logged, no alerts were triggered during the timespan of the attack, and it proceeded without being noticed. As a reaction to user complaints about a possible breach, API logs were analyzed and the attack was detected, way after the fact. The company had to make a public announcement asking users to reset their passwords, and report the incident to their regulatory authorities.

    Pertaining to the five risks above, one could easily imagine similar attack scenarios. Those provided were just examples of the nearly unlimited possibilities when attacking vulnerable API implementations. Hopefully, you can see the risks above are primarily caused by errors or oversights that could be easily remedied, especially when it comes to the way organizations utilize APIs today.

    — Erez Yalon

  • The 2020 Digital Leader Priorities

    The 2020 Digital Leader Priorities

    When it comes to digital transformation, 2020 promises to be full steam ahead as many of the trends are already well underway. However, it’ll be those businesses that can execute at the quickening rate of technological change that will set the leaders and laggards apart for the years ahead.

    A survey conducted earlier last year by market research firm Vanson Bourne found that 50% of technology leaders have a challenging time managing their digital operations, and nearly 50% of respondents also said it’s their customers that identify problems before their technology and quality control teams do.

    Which brings us to our priority: Digital laggards need to step it up.

    Digital Transformation: Laggards Versus Leaders Packs Separate

    When enterprises shifted from their focus on e-commerce to a broader focus on their digital transformation efforts a few years ago, those who have been successful with their transformations are starting to reap results.

    Still, while the vast majority of enterprises do have digital transformation strategies that they are implementing, a Tech Pro Research report found 70% of respondent companies either had a digital transformation strategy in place or were developing such a strategy. While a separate study, the Kony Digital Experience Index Survey found a strong indication that those efforts aren’t paying off as well as many businesses may like—at least when it comes to their customers.

    According to Kony’s survey, customers are more satisfied when their digital experiences are effortless, and 63% said they would spend more money when their digital experiences are, in fact, effortless. That study concluded that businesses are not listening to the needs of their customers because only 28% of enterprise digital transformation initiatives are explicitly started with customer needs as the priority.

    The 2020 Priority: CIOs and chief digital officers are going to have to ensure that their organizations can execute against their digital transformation strategies. Those that create superior digital experiences are going to start to set themselves further apart from their laggard rivals dramatically. Those CIOs and CDOs at laggard companies are going to have to focus on turning themselves around as quickly as they can.

    The Continued Rise of Robotic Process Automation

    To advance their digital transformation efforts, most enterprises are increasingly turning to robotic process automation (RPA) and software bots to automate any cumbersome and costly manual processes they have in place. While the benefits of RPA and software bots are high, they don’t come without potential danger. These bots, if not managed properly, can open enterprises to increased security and regulatory compliance risks.

    The 2020 Priority: Effectively govern the security of their software bots so the associated risks are mitigated, and they can reap the most significant benefits from RPA.

    Low-Code Development Continues to Help Clear App Backlogs

    The demand for software is relentless, while the availability of professional developers isn’t limitless. And most enterprises have a backlog of application requests they can’t clear. According to a report from OutSystems, currently, 41% of enterprises use low code platforms, with an additional 10% about to start. That was up from 34% in the prior year report.

    Low code development platforms are popular because they help to make software development more accessible to non-developers by creating development more graphical. The low code development platform market is expected to grow to $27.2 billion by 2022.

    The 2020 Priority: focus on low code platforms for business users where it makes sense for them to be able to create their applications and capabilities. Not as a way to displace the development team, but to augment until those applications that warrant development and require professional developers can be built.

    AIOps Starts to Meet Its Promise

    As enterprises increasingly run their business-technology systems on a mix of clouds (both public and private) as well as on-premises systems, managing this infrastructure has grown more complex. The embracing of microservices, continuous delivery and DevOps has enabled organizations to deliver application enhancements more rapidly, automate testing and deliver their software with increased agility. However, interdependencies and the complexity of systems have also increased. This increased complexity shortened the amount of allowable time necessary to resolve system issues.

    When it comes to effective operations management, operations teams need to become as effective as possible since a breakdown anywhere in the environment can initiate thousands, and alerts can create multiple application and service disruptions.

    The 2020 Priority: This increased complexity will prove a catalyst for more enterprises to turn to AIOps. By using data gathered from operations management tasks with machine learning, organizations can become more effective at managing performance and availability and service management. AIOps has remained a buzzword for several years now, with very few actual deployments. That’s set to change.

    Optimizing Microservices Architectures

    Enterprises face a seemingly limitless demand for applications–customer-facing apps, back-office applications, APIs and digital services–and this demand has been a significant catalyst behind the popularity of microservices architectures.

    Microservices also help to ease budget constraints. Almost every survey shows microservices architectures are now in use by the majority of organizations, with benefits being cited, such as improved employee efficiency and customer experience, as well as infrastructure management. Microservices architectures also help enterprises to improve application scalability and bring new digital products and services to market more quickly.

    The 2020 Priority: Identify where microservices architectures can have the most significant impact on revenue-generating processes and prioritize the deployment of microservices to these areas first. It’s these areas where workflow improvement and application agility can have the greatest business impact.

    Looking out at a new year and imagining the possibilities is always exciting, but with the accelerated change in enterprise technologies and the level of digital transformation underway, this year is setting itself up to be more interesting than most.

    — George V. Hulme