Category: DevOps and Open Technologies

Editorial Calendar for February 2016

  • Cisco Extends Ansible Support to Advance DevOps

    Cisco Extends Ansible Support to Advance DevOps

    Cisco Systems announced today that it is further embracing the open source Ansible automation framework on its storage area network (SAN) platform as part of an effort to extend best DevOps practices to IT infrastructure. The latest version of the Cisco MDS 9700 platform modules automates tasks such as VSAN configuration, device-alias and zoning configuration.

    Adarsh Viswanathan, product manager for data center storage at Cisco, said the company has embraced the Ansible framework because it’s an open framework that is now being adopted by enterprise IT organizations to manage infrastructure in a more adroit fashion. The rise of cloud-native applications being developed with DevOps processes not only result in more applications accessing a common pool of data, but also require changes to be made dynamically to the underlying storage platform.

    Cisco is adding support for 64G-line cards when they become available along with support for non-volatile memory express (NVMe) and All-Flash arrays. Cisco has also extended its SAN Analytics software to add support for the NVMe/Fibre Channel protocol along with existing support for SCSI/Fibre channel.

    Viswanathan said support for Ansible will make it simpler for IT organizations to embrace automation at scale. Cisco has previously embraced open application programming interfaces (APIs), OpenStack and Python-based scripts. Ansible takes those efforts to a higher level by make available a declarative framework that doesn’t necessarily require IT operations teams to develop programming expertise, said Viswanathan.

    IT operations teams are coming under increased pressure to provide developers with an IT experience that rivals cloud service providers. Frameworks such as Ansible make it possible for IT operations teams to make IT resources available on-demand to developers using IT infrastructure residing in an on-premises environment.

    Friction between developers and IT operations teams is rising as DevOps processes are employed more widely within enterprise IT environments. Many of those developers have alternatively turned to cloud service providers to build and deploy their applications. However, many organizations still need to deploy applications once they move into a production environment hosted in a local data center. In fact, more than 70% of enterprise applications still run in a local data center a decade after the initial rise of cloud computing. IT operations teams that manage those on-premises IT environments need to provide developers with access to resources they can easily scale up and down as required.

    Cloud-native applications based on microservices will further challenge IT operations teams as the number of application services trying to share a limited set of IT infrastructure resources only increases. In the case of Cisco, those limited resources are rack-based servers attached to SANs such as the Cisco MDS 9700.

    Of course, not every IT operations team is going to embrace DevOps processes overnight. Instead, many of them will be exposed to frameworks such as Ansible as they upgrade servers and storage over time. The one thing that is certain is developers will continue to apply pressure to make that transition sooner than later as more organizations continue to appreciate the extent to which they now depend on software to innovate.

    — Mike Vizard

  • GitHub Actions Advances Automation Strategy

    GitHub Actions Advances Automation Strategy

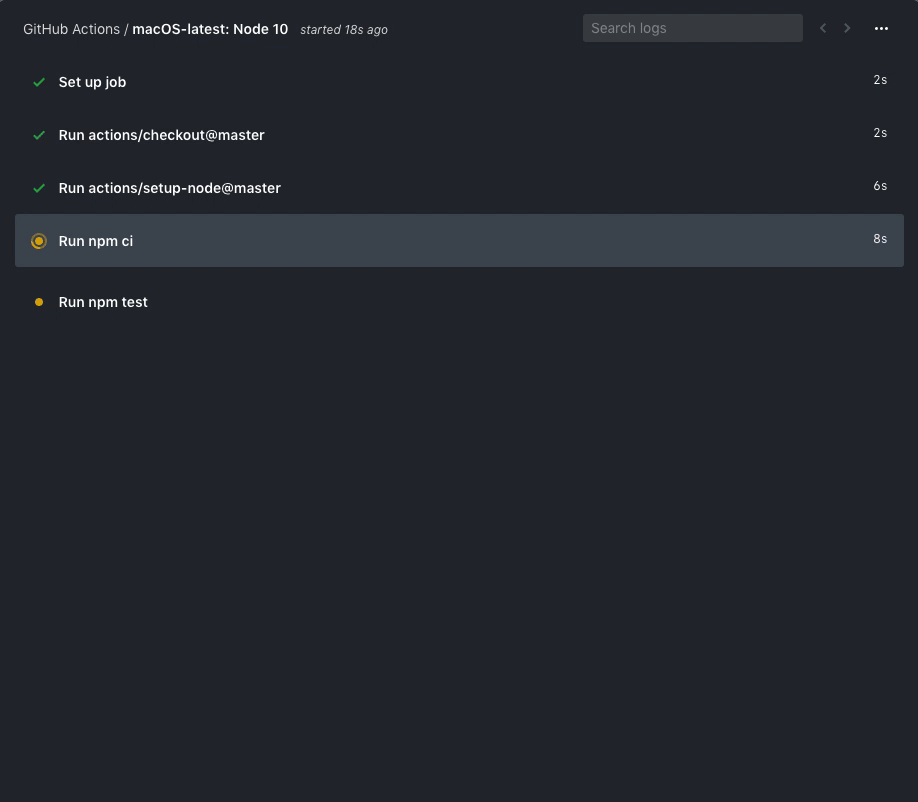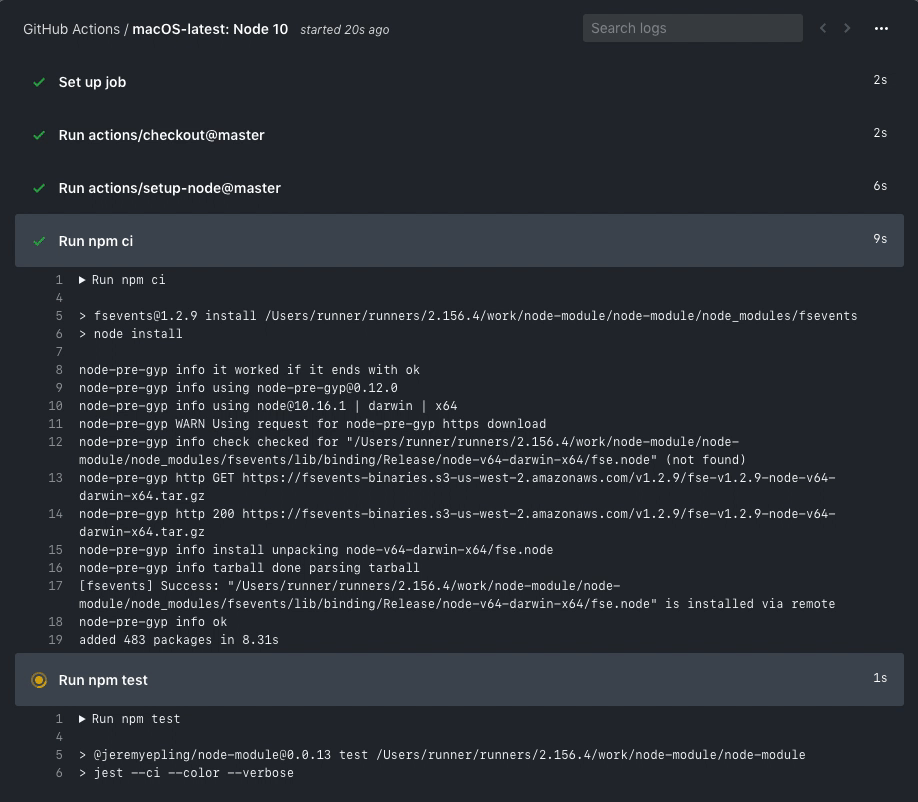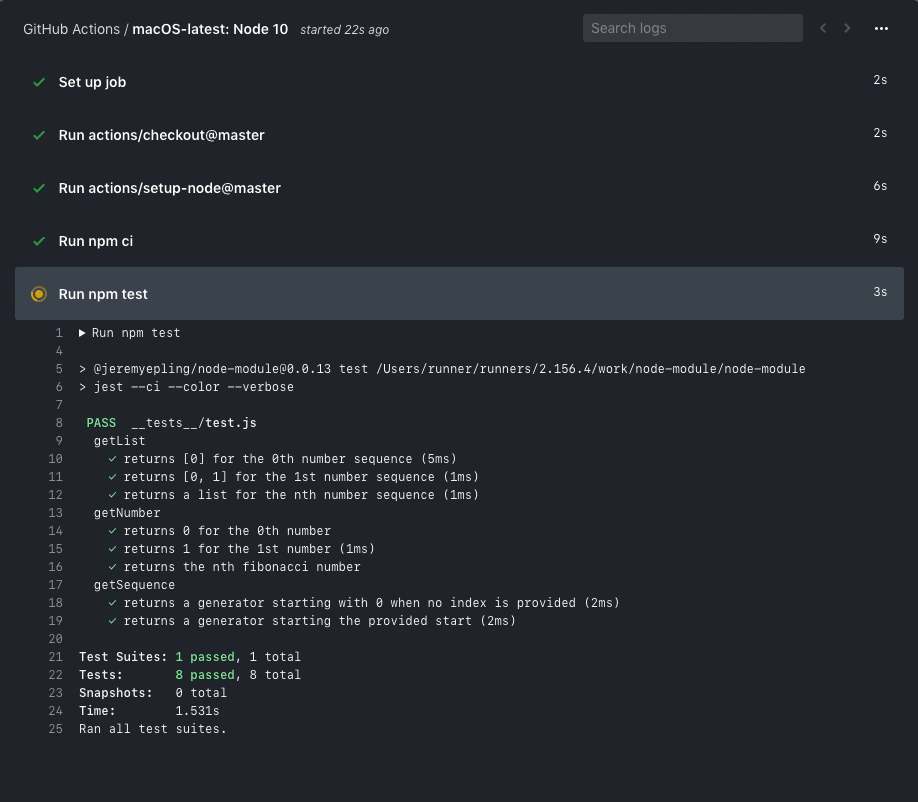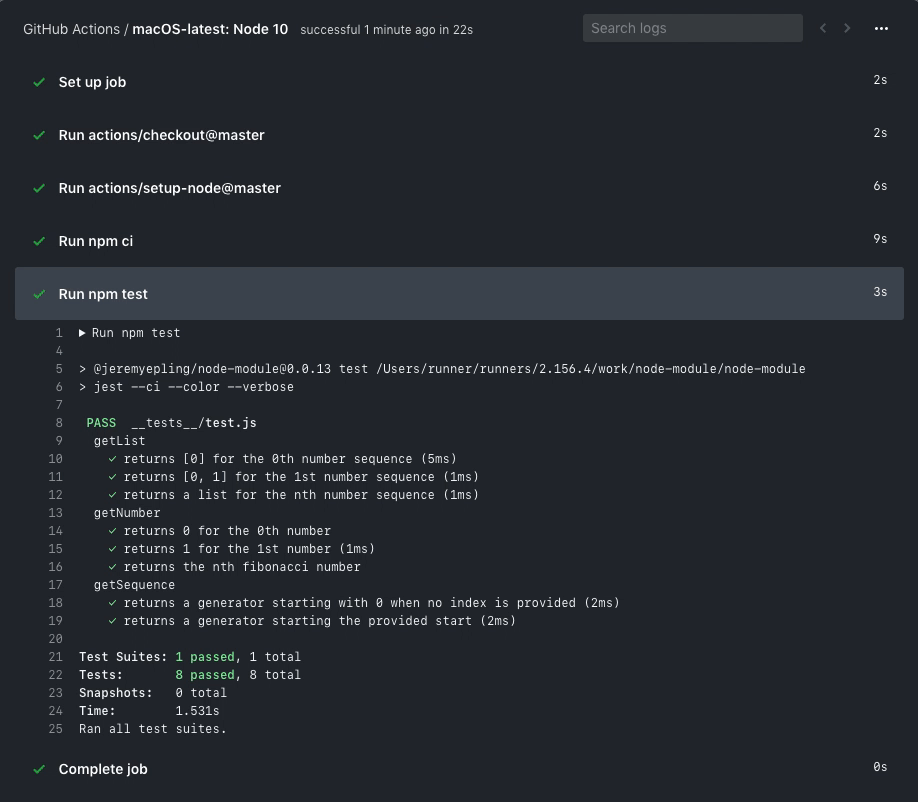
    GitHub Actions, a set of application programming interfaces (APIs) through which DevOps tools can automate workflows, is now available in beta.

    Previewed last year at the GitHub Universe event, GitHub Actions is intended to provide not only a way to automate responses to events occurring within a GitHub Repository but also share those workflows across multiple DevOps teams, said Max Schoening, senior director of product design for GitHub.

    Actions are based on YAML files, which makes it possible to write them in JavaScript or other programming languages or package them up as a set of containers. In either instance, they are designed to interact with the full GitHub API and any other public API.

    In addition, higher levels of automation enabled by GitHub Actions should make it more feasible for DevOps teams to test multiple versions of a project in parallel as workflows written in code replace manual processes, said Schoening.

    As more manual processes become automated, the number of IT teams who are intimidated by DevOps processes today should begin to decline. Organizations also should be able to apply best DevOps practices more consistently across multiple teams. Too often today the DevOps practices within the same organization tend to vary widely. Schoening also noted that given the open source history of GitHub, organizations will be able to see how workflows have been created for popular open source projects and then copy them.

    In addition, Schoening said the arm of Microsoft will continue to invest in analytics that will surface workflow recommendations that can be applied to any project regardless of the language employed or the platform on which it’s destined to be deployed.

    On one level, DevOps is all about a ruthless commitment to automation. But when automation goes wrong at scale, it can be extremely problematic. Rather than relying on “black box” approaches to automating processes, a truly open source approach to automation makes it possible for DevOps teams to see how a process is being automated and then extend it if they so choose, said Schoening. To help address the concern, GitHub Actions also provides access to live logs to provide real-time feedback as builds run, which Schoening said makes it easier for DevOps teams to debug automations created using GitHub Actions.

    It’s too early to say just how automated DevOps processes will get. There’s an emerging school of thought that contends the goal is to make it feasible for developers to spend 100% of their time writing business logic. It’s not clear whether that goal is achievable anytime soon, but progress is made with each update to continuous integration/continuous development (CD/CD) platforms. As complementary advances in machine learning algorithms and other forms of artificial intelligence (AI)—otherwise known as AIOps—occur, it’s apparent many manual DevOps processes will fall by the wayside.

    In the meantime, the workflows that make up any DevOps process should become increasingly sophisticated as advances in automation span everything from hybrid cloud computing environment to internet of things (IoT) deployments. The issue soon may not be how cumbersome any DevOps workflow is, but rather the potential limits of the imagination applied to automating them.

    — Mike Vizard

  • The Challenge of Securing Open Source Applications

    The Challenge of Securing Open Source Applications

    As enterprises have increased their reliance on applications over the years, there has been a significant rise in the use of reusable software components such as third-party libraries and open source code. This makes perfect sense, as this development method makes it possible to add value to applications and other software offerings quickly and easily. After all, why reinvent the wheel when supposedly well-tested and proven software components are readily available?

    As a result, open source code has become a vital part of software development for most organizations. Today, nearly 70% of every application is comprised of reusable software components, including open source software. At one time, open source software was considered too risky for commercial use. That is not the case today, however, as even major corporations are making use of open source components to innovate and deliver applications to market rapidly.

    While enterprises have gotten very good at using open source to speed the application development process, they have not yet figured out how to do so without inadvertently introducing vulnerabilities into their code. This is due in part to the fact that as more enterprises increase reliance on applications, they fail to implement application security into the software development life cycle. Consequently, as the adoption of open source software continues to grow, the likelihood of applications inheriting vulnerabilities is higher than ever before.

    This is evidenced by the fact that, according to my company’s research, unpatched library vulnerabilities make up 21% of all application vulnerabilities, by far the most of any type. In fact, nearly 20% of the inquiries we answer are related to unpatched libraries, which is almost on par with injection vulnerabilities.

    That is why it is imperative for development teams to stay up-to-date with open source library maintenance and updates.

    Software Composition Analysis

    The right way for organizations to track their open source components is through a set of technologies known collectively as software composition analysis (SCA). These technologies, which arose out of a need to automate the open source management process, provide organizations with visibility into their open source inventory. This allows them to identify third-party and open source components integrated into their applications.

    Using SCA, organizations can determine easily if any of their applications are relying on a vulnerable library, if any libraries are out of date and whether licensing is legal/proper. SCA helps them identify multiple types of risk introduced by third-party and open source components. These can include known vulnerabilities, intellectual property risk and technical debt related to component age.

    It’s important to remember the use of open source software code is not a problem in and of itself. On the contrary, it has been an essential part of the recent innovations in software development, and, in fact, it is no riskier than proprietary or commercial off-the-shelf offerings.

    Problems arise only when organizations fail to be proactive in identifying and managing security and license risks associated with open source code. This may occur in part because it is assumed that, as with commercial software, updates, patches and information are pushed to the user. But that’s not the case in the open source world, where the onus is on the user to keep track of these things.

    It takes diligence, but in the end, the only way to mitigate both the security and legal risks associated with your open source code—and to fully realize its benefits—is to track every piece of it. Today, SCA is the proven way to help you do that. By incorporating SCA into the development process, developers can capture inherited vulnerabilities early enough to prevent them from being introduced. Of course, it should go without saying, but it’s not enough to just find vulnerabilities; you also must fix them. The most typical remediation is replacing vulnerable components with the non-vulnerable ones.

    Considering most application code is now open source, and attackers are going after vulnerabilities in open source more than ever before, SCA should not be an afterthought. It needs to be an integral part of any organization’s application security and secure DevOps processes.

    — Joseph Feiman

  • The Linux Foundation Breathes New Life into Osquery

    The Linux Foundation Breathes New Life into Osquery

    Facebook’s useful but neglected DevOps tool Osquery has gotten a new lease on life, thanks to The Linux Foundation.  

    Anyone who has been tasked with monitoring the security of server instances in a data center or cloud knows how laborious and time-consuming it can be. Osquery, a project started by Facebook, aims to lessen this burden by reframing how developers engage with their infrastructures. DevOps professionals can use Osquery to expose an operating system as a high-performance relational database, making it possible to use SQL commands to access data about a system, just as they would for a database. 

    Osquery works on Mac, Linux and Windows systems and is provided as an open source download via GitHub. Although Osquery was developed by Facebook to monitor and safeguard the security of its own platform, the social media giant quickly realized the utility of the platform would extend to other enterprises that depend upon insight into the low-level behavior of operating systems. 

    Facebook publicly released the project’s code and documentation in 2014, in response to feedback from a small number of other companies that tested Osquery. The public availability of Osquery resulted in a number of major companies including Airbnb, Dropbox, Netflix, Etsy and Uber to bring Osquery into their software development environments. Nevertheless, users have voiced frustrations with Facebook’s handling of Osquery, and have accused the internet giant of neglecting the project.

    To address those complaints, The Linux Foundation has taken over the mantel of Osquery and recently announced the formation of a new foundation to support the Osquery community. 

    The new Osquery Foundation brings together engineers and developers from Dactiv, Facebook, Kolide, Trail of Bits, Uptycs and many others committed to supporting the project with technical contributions and long-term stewardship. A Technical Advisory Board will be created to handle the shift in management from Facebook to the Osquery Foundation and will oversee the priorities initiated by the foundation’s members.

    This restructuring of management promises to extend the usability of the project as a number of developers contribute to the codebase.

    “Osquery has drastically simplified the process of operating system monitoring, which has unlocked new methods for securing infrastructure, detecting anomalies and more. We look forward to working with the Osquery community to develop the foundation in a manner that will continue to foster the growth and adoption of Osquery while supporting the community’s diverse needs,” said Jim Zemlin, executive director at the Linux Foundation.

    Developers working to maintain the security of their systems believe it would be wise to incorporate Osquery into their workflow. “Although Osquery will never do everything that a security team needs, it gets about 80% of what you need for endpoint insight in one package,” said Doug Wilson, director of security for Uptycs.

    Although the platform requires some configuration, developers familiar with SQL will feel accustomed to using Osquery to retrieve information about their systems. Furthermore, Osquery’s cross-platform support and customizability make it especially attractive to businesses with newer types of infrastructures and ones that work at scale. 

    The move away from Facebook toward a more community-friendly foundation is sure to breathe new life into the project, and as development on Osquery expands, it is likely to become a more valuable resource for security teams moving forward.

    This article was co-authored by Tyler Ohlhorst, research analyst and freelance copy editor and copywriter at Magnum Consulting.

    — Frank Ohlhorst

  • State of the Software Supply Chain: Secure Coding Takes Spotlight

    State of the Software Supply Chain: Secure Coding Takes Spotlight

    After almost a year of research that involved studying 36,000 open source software projects, 12,000 enterprise development teams and 3.7 million open source releases, we at Sonatype are excited to share the “2019 State of the Software Supply Chain” report.

    This year, we worked with research partners Gene Kim, founder of IT Revolution, and Dr. Stephen Magill, principal scientist at Galois and CEO of Muse, to examine and empirically document objectively for the first time the attributes of exemplary development practices, especially in relation to secure coding practices. But, as in years past, we’ve also analyzed the rapidly expanding supply and continued exponential growth in demand for open source components.

    Not All Open Source Projects Are Created Equal

    For the past four years, we’ve studied the ins and outs of the software supply chain—what it’s comprised of; how vulnerabilities are getting in and how often; the growing regulations; and, most recently, a new trend in which adversaries are purposely attacking the supply chain with malicious components.

    For our fifth anniversary of the report, we wanted to look deeper. We wanted to understand exactly how enterprise development teams—and potentially even more importantly, how OSS projects—were thinking about and addressing the software supply chain security issues. We wanted to understand and identify the very best practices so we could share them with others.

    As a result of our research, we identified five common behavior patterns across 36,000 open source development teams. This includes identifying attributes of Large Exemplars and Small Exemplars who rest within the top 3%, or 1,229, OSS project development behaviors.

    To arrive at this list, we examined a large number of variables, including:

    • Do differences exist in how effectively OSS projects update their dependencies and fix vulnerabilities?
    • Are there exemplary teams that do this better than others?
    • Are components from exemplary teams more widely used than “non-exemplary” components?
    • What factors correlate with exemplary components?
    • What advice can be offered to producers of OSS components and the developers that consume them?

    The answers were quite striking—and the resulting data even more illuminating. While the report identifies Small Exemplars and Large Exemplars, we’ve also identified three additional groups of OSS projects: Laggards, Features First and Cautious.

    Secure coding: 2019 State of the Software Supply Chain

    Exemplary Commercial DevSecOps Practices Create Superior Software

    There are clear, competitive advantages for teams with exemplary DevSecOps practices.

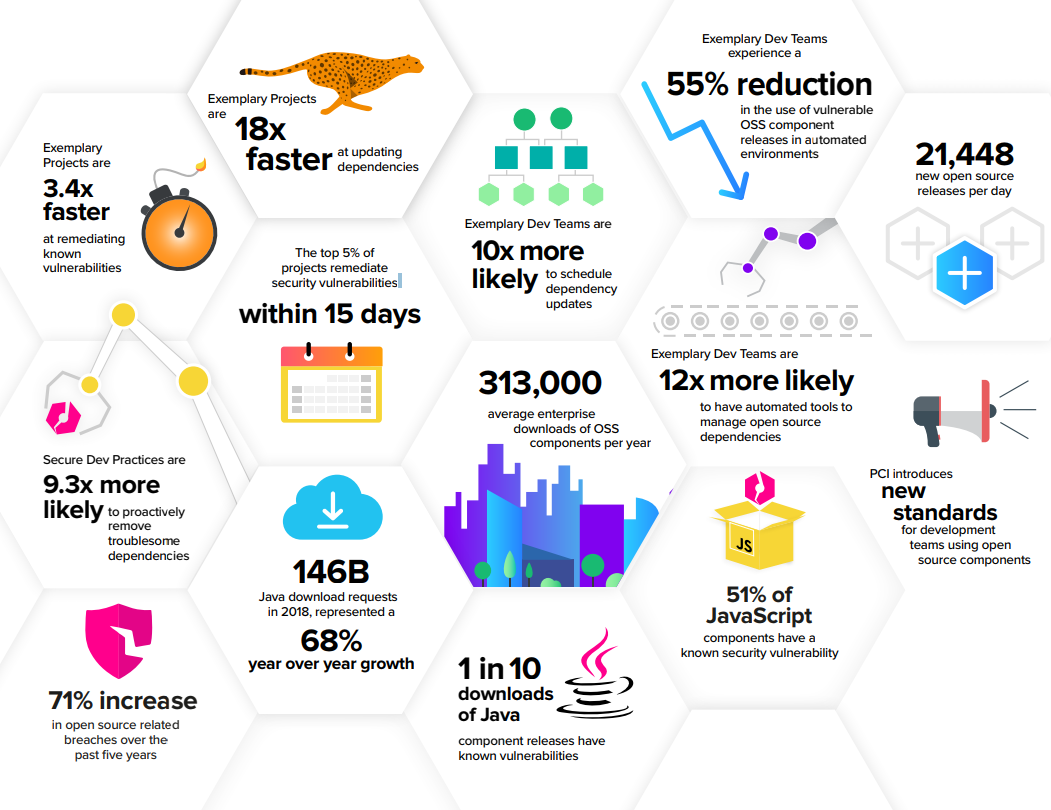
    We’ve known for years that innovation is critical, speed is king and open source is at center stage. This research further underscores these accelerating trends throughout the software supply chain. It also shows that taming the supply chain is possible. By making better supplier choices, component selection and using automation, dev teams are seeing impressive rewards. In fact, for those development teams actively managing their software supply chains, the use of known vulnerable component releases was reduced by 55%.

    The report details 11 other behaviors and attributes of leading enterprise development teams, including their frequency of software releases, their use of repository managers and their reliance on a software bill of materials.

    Gene and Stephen helped shed new light on exemplary development and DevOps practices that I believe will help developers around the world better understand what secure coding means and how to start addressing it.

    — Derek E. Weeks

  • 5 Ways DevSecOps Can Manage Software Supply Chains

    5 Ways DevSecOps Can Manage Software Supply Chains

    The unbridled use of open source components within the software supply chain is on a major uptick, according to new research. Even as this surge in open source dependencies fuels faster innovation, the study shows that it comes with high cybersecurity costs, as the number of breaches related to these components is similarly on the rise.

    However, the numbers also indicate there are some clear practices used by the best DevSecOps teams to minimize the risk while maximizing the speed and agility that third-party components offer.

    Sonatype and research partners from IT Revolution and Galois made a thorough analysis of download patterns, software component makeup and DevSecOps behaviors around open source components and third-party libraries for the “2019 State of the Software Supply Chain Report.” Their analysis found that the rate of open source component releases has picked up by 75% in the last two years and that download requests from teams using these components have risen 68% year over year.

    Most tellingly, the study showed that among modern applications today, 85% of the average code base is comprised of open source componentry. Not only are the majority of applications using open source components and libraries, but also they depend on them heavily.

    “The practice of assembling open source component releases into the form of an application screams of efficiency. Developers no longer need to code every line from scratch,” according to the report. “Developers can download component releases in seconds that deliver new capabilities, built by experts outside of their organizations who make their code freely available to others.”

    Perhaps not coincidentally, the study noted a parallel rise in breaches associated with open source component use. Last year 1 in 4 organizations suspected or verified they experienced a breach related to open source components in the last 12 months. That’s a slight improvement over last year’s stats, which had it pinned at 1 in 3 organizations. But since 2014, that rate of breaches has risen by 71%.

    The trouble is, many of the components developers download and integrate into their code are full of dangerous vulnerabilities. For example, just over half of all JavaScript package downloads contain known vulnerabilities, with 1 in 3 rated as high vulnerabilities. One in 10 of those flaws were rated as critical.

    The point the report hammered home is that not all components are created equally. There exists a certain class of well-run open source projects that release updates more frequently, update problematic vulnerabilities faster and remediate flaws more quickly. It is up to DevSecOps teams to systematically manage components, so they leverage more of these high-quality open source projects and try to avoid the riskier open source dependencies.

    “Management of software supply chains is not simply ensuring quality at velocity. Our supply chains are being attacked by adversaries in new and creative ways,” according to the report. It found that organizations that actively manage their supply chains are able to reduce the proportion of vulnerable components by 55% compared to those who do not.

    The report found several software supply chain practices contributed to this reduction of risk, with the following five standing out as the most impactful:

    Develop a governance program: Foundational to this is having some sort of open source governance or standards policies in place, according to the report, which noted that among the best DevSecOps organizations at managing risky components, nearly 3 in 4 have such policies in place.

    Have a process for evaluating and adding new components: As a part of that open source policy, the best teams have standardized processes for how developers add new open source components. This includes how these components are evaluated, approved, standardized and so on. The exemplary organizations are 11 times more likely to use this kind of process for new dependencies.

    Proactively remove problematic components: New vulnerabilities are discovered every day, so simply evaluating a dependency upon its first inclusion in an application can only take an organization so far. The best organizations also take the initiative to look for potential sources of open source vulnerabilities in existing code. That includes proactively seeking out and removing known vulnerable dependencies, as well as reducing the attack surface of the code by eliminating open source dependencies that aren’t being used. The best organizations are 9.3 times more likely to do so.

    Aim to always use the latest versions of components: It should go without saying that the latest version of any given component has the least vulnerabilities. The report showed that component releases that are 3 years or older have a 65% higher defect rate compared to newer components. Exemplary organizations strive to use the newest updates of all of their open source components and are 6.2 times more likely to do so than other organizations. That doesn’t happen accidentally—these teams are 10 times more likely to schedule update dependencies as part of the daily work of DevSecOps teams.

    Use Enforcement Automation: Just having a policy in place is not enough—organizations need to enforce the open source standards to reduce risk meaningfully. The study showed that DevOps practices combined with automated enforcement of policies increase developer adherence to standards by 150%. The exemplary teams with the lowest open source defect rates are 12 times more likely to have automated tools to track, manage and/or ensure policy compliance of open source dependencies.

    All of these best practices add up to less risk from components, as well as less pain for DevSecOps teams, who are three times less likely to consider the process of updating components as painful.

    — Ericka Chickowski

  • Pivotal Software Embraces OpenJDK

    Pivotal Software Embraces OpenJDK

    Pivotal Software has officially thrown its weight behind OpenJDK, the open source version of the standard edition of Java, by adding support for OpenJDK to the Pivotal Spring Runtime on its Spring framework.

    At the same time, Pivotal announced it is extending its commercial support for open source Apache Tomcat servers in addition to providing commercial support for all the major open source Spring projects, including Spring Framework, Spring Boot, Spring Cloud and Spring Cloud Dataflow.

    Since 2011, Oracle, IBM and SAP have been making a case for employing OpenJDK. Ryan Morgan, vice president of engineering for the application platform at Pivotal, said that while other languages have become increasingly popular, the primary workhorse for building back-end applications in the enterprise remains Java. Now that Oracle has formally relinquished control over Java source code to The Eclipse Foundation, research and development into the legacy programming environment should accelerate. Oracle retains licensing rights to the name Java, but versions 8 and higher of Java Enterprise Edition are being converted to an open source platform known as Jakarta.

    Morgan said much of the work going forward would be focused on modernizing monolithic Java applications to make it either to turn them into microservices or at least make it easier for microservices developed in other languages to make calls via application programming interfaces (APIs) to those back-end applications. As enterprise IT organizations make the shift, they increasingly will rely on DevOps processes to manage the transition. The effort should accelerate the extent to which many organizations will need to rely on modern best DevOps practices.

    As both OpenJDK and Jakarta continue to move forward, Morgan said Pivotal is committed to continuing investment in the Spring framework, which has done much to make developing Java applications a much more agile endeavor. The most immediate benefit, of course, is the reduction of licensing fees associated with employing Java platforms. Many IT organizations that have mandated open source code-first and adopted alternative programming languages now may want to reconsider their options, especially when the number of developers who know how to write applications in more modern languages is comparatively small.

    Of course, it will take many years for enterprise IT organizations to fully make this transition. In the meantime, many of them will continue developing applications in Java simply because they have large teams that have mastered a programming construct that has been in place for three decades or more. Many of those same organizations may be making greater use of rival programming constructs, but Java and its descendants will play a major role in the enterprise well into the next decade. The primary challenge Pivotal will face is maintaining dominance of the frameworks employed to build new applications based on Jakarta and OpenJDK, in addition to updated existing Java applications.

    — Mike Vizard

  • Adobe Aims to Build Developer Ecosystem

    Adobe Aims to Build Developer Ecosystem

    Adobe today outlined an approach to building a developer ecosystem that revolves around open source code, application programming interfaces (APIs) and DevOps processes.

    Matt Asay, head of developer ecosystem for Adobe, said in the last few years Adobe has increased its reliance on open source code to deliver offerings such as Adobe Experience Manager, a content management system that incorporates open source code for as much as 65% of its modules. In the course of that effort, the company has made reciprocal code contributions to a variety of open source projects being developed under the auspices of the Apache Software Foundation (ASF), including Apache Sling, a web development framework; Apache Oak, a content repository; Apache Felix, an implementation of a services gateway; and Apache Lucene, a text search engine.

    Adobe also recently launched Adobe Experience Cloud, which relies on a variety of open source technologies to create a big data repository on top of which Adobe is encouraging developers to invoke APIs to build applications. Rather than build their own big data repositories, Adobe is making a case for relying on a multitenant big data platform it manages on behalf of customers.

    Based on GitHub data, Adobe currently ranks as the 14th largest corporate open source contributor, up from No. 32 in 2017. One of the primary reasons Adobe was able to move up that list so quickly was its move to acquire Magento, an e-commerce platform based heavily on open source code. But now that the company has come to appreciate what can be accomplished by relying on open source code, organizations should expect to see Adobe accelerating the rate at which it will be making contributions to a wide variety of open source projects.
    At the same time, Asay said, Adobe is making major investments in developing microservices that it plans to make it possible for developers to consume via its APIs. The Adobe Experience Cloud, for example, is a suite of software-as-a-service (SaaS) applications that employ a common data model deployed on a set of Kubernetes clusters running in the Microsoft Azure cloud.

    Asay noted Adobe is trying to make it clear that it has a lot of empathy toward developers committed to open source code. Adobe is a provider of commercial software-as-a-service (SaaS) applications, but it wants to develop a developer ecosystem that consumes the data residing in those applications via its APIs. To foster the development of those applications, Adobe has already signaled it is willing to share best DevOps practices with organizations that commit to invoking those APIs.

    Adobe is one of many providers of commercial software that are increasingly dependent on open source code. It will be interesting to see where the line between the desire to use open source projects to build applications and actual open source applications lies in the years ahead. But the one thing that is clear is that without DevOps processes and a well-defined set of APIs to guide them, there’s not much chance any vendor would be able to build a meaningful developer ecosystem of any size.

    — Mike Vizard

  • Open Source Versioning: The Race to Stay Up-to-Date

    Open Source Versioning: The Race to Stay Up-to-Date

    Open source libraries, once shunned as risky and not ready for prime time, are now used extensively across major corporations, including insurers. The reason is simple: In time- and resource-constrained companies trying to stay technologically competitive, it doesn’t make sense anymore to try to reinvent a wheel that’s already been battle-tested. However, having made the commitment to open source code and solution sets, it’s imperative to keep up-to-date with open source library maintenance and updates.

    The Risk of Open Source

    Some active open source libraries are updated multiple times a year. Getting out of date means missing out on newer features. Also, if the gap between upgrades bridges several iterations, some future upgrades may not be backward-compatible, causing functional problems at best and risk exposure problems at worst. On occasion, an out-of-date open source library version can expose a system and a company to attack. In 2017, a major U.S. financial company was hit by a hack that exposed the information of millions of customers. The hackers had exploited a software vulnerability that had been public for a month, but the company had not patched its system in time. There are several other well-known examples of a similar vein.

    Keeping current is not easy. Upgrading may be costly, but falling behind can make it costlier to catch up. The question is, How frequently should one upgrade to the newer versions?

    The Effort and Cost

    One of the reasons companies choose not to upgrade every time there’s a new release is the cost involved. While the open source code itself is free, the effort required in time and resources can be substantial and can take valuable resources away from higher priority business-technology initiatives. An additional concern is that, even though the upgrade is supposed to be backward-compatible, there is no way to verify that without actually performing the upgrade. If there are compatibility problems, then a larger effort ensues involving upgrading, restoring or rebuilding a system. Any large system has to be tested thoroughly after upgrading, and without the help of automated tools, testing can be costly and time-consuming.

    One approach for mitigating these costs and risks is the process of continuous integration (CI) for open source libraries. A good suite of automated testing tools provides a high degree of confidence that nothing has been broken by the most recent upgrade, before it is implemented into any production environment. However, without automated tests that flush out potential issues from upgrading, the risks and costs are high enough that companies have a hard time keeping up and managers become more motivated to delay upgrades than to perform them. That’s why it’s important that companies employ CI and continuous delivery (CD) processes that include robust automated testing.

    Additionally, the use of microservices—an increasingly effective and popular way to construct systems—puts another twist into the efforts and costs of keeping open source libraries up to date. Individually, each microservice might be quick to test. However, if an application has been broken into 50, 100 or even more microservice components, even a small amount of manual work testing each component will add up quickly. Additionally, in an environment that has deployed microservices broadly, there may not be a business need to change some services for months—that is one of the benefits of using microservices.

    The Right Approach to Open Source

    There is a right way to deal with open source library updates that has the benefit of taking advantage of new functionality and code stability in a low-risk, low-effort and low-resource manner as follows:

    Planning: Enterprise and application architects should be vigilant regarding the road maps of any large frameworks that employ open source libraries as a key component to any project or initiative. Proactive identification of open source libraries that may need to be upgraded is key. Likewise, application project managers should make open source library upgrade part of a regular and ongoing project plan. For example, when microservices are involved, they should be classified proactively as services by the libraries they use, as a way to identify the few services that would normally be upgraded first. This has the benefit of providing a few sprints’ worth of feedback before rolling out the upgrades to other libraries.

    Monitoring: Open source version monitoring is essential. There are products that can help to identify and report library versions that have vulnerabilities. Such monitoring can and should be used as part of the CI/CD pipeline and also to monitor artifacts that already are deployed in production. Monitoring processes also can report when newer open source library versions are available, even if the incumbent library has no reported vulnerabilities.

    Automated compatibility triage: It is often too risky to set up production builds to always use the latest version of an open source library. However, separate automated processes can identify new versions, run them through a build and test process and report back the results. If a test fails, the development team gets an early warning that their code is not compatible with the upgrade version. This helps to plan and schedule fixes, and if a vulnerability is discovered in the current version, this kind of proactive planning enables a quicker resolution and turnaround.

    Processes: Strong processes, preferably automated ones, are the foundation of open source versioning. For critical security upgrades, a process must be in place to triage and prioritize identified changes. For other version updates, good processes can help make upgrades easier. For example, a standard and repeatable process may incorporate minor version upgrades into the regular flow of sprint work, thus saving time while mitigating risk.

    Open source versioning can be difficult, but it doesn’t have to be. With automated testing, good monitoring tools and some proactive planning, the costs and risks of staying up to date can be kept to a minimum, allowing companies to reap the benefits of new features and functions.

    — Darius Cooper

  • DevOps Chat: F5’s NGINX Acquisition, with F5’s Lori MacVittie

    DevOps Chat: F5’s NGINX Acquisition, with F5’s Lori MacVittie

    F5 Networks has acquired NGINX, the leading open source web server player. The move clearly puts F5 in the DevOps space, as well as the open source market.

    In this DevOps Chat, we speak with Lori MacVittie of F5 along with Sidney Rabsatt of NGINX. Some great insights into why this acquisition makes sense for both parties.

    As usual, the streaming audio is immediately below, followed by the transcript of our conversation.

    Transcript

    Alan Shimel: Hey everyone, it’s Alan Shimel, devopsy.kinsta.cloud, DevOps Chat, and you’re listening to another chat. Today’s chat features two folks from an acquisition announced yesterday. In case you haven’t heard, F5 Networks has acquired NGINX. We’re going to hear more about it from two folks. Number one is our friend, Lori MacVittie from F5 Networks. Lori, welcome. Glad to have you here.

    Lori MacVittie: Thanks, happy to be here.

    Shimel: Fantastic. Joining Lori and I is Sidney Rabsatt. Sidney is VP of product at NGINX. Correct, Sidney?

    Sidney Rabsatt: That’s right, and I’m happy to be here too.

    Shimel: Well, everyone’s happy to be here. That’s not a bad thing. Are you happy to be here at the DevOps Chat or are we happy to be here talking about F5’s acquisition of NGINX? Let’s hope it’s both. Lori, give us a little background here. When I saw the deal yesterday. I said, “Wow, that’s a big deal.” I’m not sure – it’s certainly an expansion, up the stack, if you will, for F5.

    MacVittie: Up the stack, deeper into the app. It’s all about application delivery. One of the – Sidney mentioned earlier when we were chatting, building on NGINX’s vision, which as I read it, is flawless application delivery. That’s certainly something that F5 has always aspired to achieve as well, but there’s just pieces in the application stack that we don’t play in, or haven’t played in until yesterday with the acquisition. NGINX is the leading webserver. They’ve got an app server. They do some app delivery. They’re very prevalent in many, many places. So we’re very excited to have them on board to see how we can bridge the gap between those two worlds.

    Shimel: Absolutely. What about the perspective of NGINX? Money is always nice. Don’t get me wrong. What’s the attraction to F5 here?

    Rabsatt: I think there’s at least two sides of it. Working with the folks on this early on, we got to get a sense of the culture of the organization. It felt very compatible. The people we met were great. We had a great time talking, hanging out, sharing ideas. There’s some real optimism about what can be done together. The thing that really gets folks excited, especially on my side of the house, on the NGINX side of the house is the opportunity to do even more faster. We’re a startup. It’s grown to a good size. The set of resources that we have, but looking at F5 and talking to those folks, understanding that they have a shared vision. They see the world very similarly and bringing more resources to bear to execute on the vision that we’re always working towards. It’s something that’s very exciting for us.

    Shimel: I can’t disagree with you. I think we’re in violent agreement on it. It is a great opportunity. I guess the next question is how do we integrate, Lori or Sidney, how do we integrate the NGINX webserver, appserver, and the rest of the toolset into the F5 family? Or do we not?

    Rabsatt: Do you mind if I take a stab at it?

    MacVittie: Go ahead, Sidney, please.

    Rabsatt: Sure. Look, I think on the surface of things it might seem as if there’s a ton of integration that needs to happen, and a lot of overlap needs to be addressed, but quite frankly, I’ve been pleased to see how much complementary capabilities we actually have. Oftentimes, in the marketplace, folks will actually deploy both solutions side by side. It’s because we do slightly different things, both super important to folks. When we think about integration, there’s opportunity for F5 customers to be able to leverage NGINX solutions in places where they couldn’t necessarily before. That should be a net benefit to them.

    There’s the ability for folks that leverage NGINX solutions to take advantage of things that F5 does, that we don’t particularly do. I think that’s going to be another win for them as well. The integration is really focused on making sure we have the right extensions to the product line identified so we can really give customers the things they need to succeed in delivering those end to end applications, and yes, of course, we’re going to be looking to bring the best of both sets of technologies together in the places where it makes sense, but we’ve been pleased to see it’s not as many overlapping things as we might have found in some situations. We’re very optimistic about the path forward here.

    Shimel: So crystallize for me, where do you see things that overlap versus things that play well together? Can you give us some specifics?

    Rabsatt: Sure. Things that play well together fall into the category of “Hey, can I bring better scrutiny, better analytics, to the types of solutions that I might already have with NGINX?” On the NGINX side, I’m sorry – on the F5 side, “Hey, can I leverage solutions to give me a little bit more freedom and flexibility to build my apps wherever or however I might choose to?” So I think there’s some goodness there that folks will definitely get access to.

    On the integration side, you’ll find most of it is just around making sure that the products work seamlessly together. So to the extent of I have multiple devices in my environment. How do I have a single solution that gives me the ability to manage it the way that I need to? We still need to go through the work of understanding exactly how the different buyers are going to need to interact with the different solutions that we use going forward, but all that work is in progress and again, the overlap tends to be the little stuff. Oh, do you draw a report? Oh yeah, we draw a report. Do you guys do that too? Sure. So how do we bring the best of those technologies together? It’s that kind of thing.

    Shimel: Got it. Lori, interested to hear, you heard Sidney here. What do you add to that? What are your feelings on it?

    MacVittie: I think he encompassed everything well. We already – you already see both of us in F5 and NGINX together in a lot of environments. From our perspective, I think we’re looking at – one, continuing to invest and amplify the NGINX vision and what they’re trying to execute on, but also where can we add security? Security is a big deal that has to extend from end to end. Right now, that’s a very disjoint process sometimes. That’s why we keep telling security to shift let. I think this is an opportunity that we’re going to be looking for to be able to do those kinds of things and shift that security even lefter with NGINX.

    Shimel: Absolutely. It’s funny when you think about security being a driving force behind this acquisition. With NGINX being a webserver, that’s been an area and app server, that’s been an area where security has been required and important forever, even going back to IIS in the day, Internet Information Server and stuff. Here’s an area though I was thinking about. So many people in the public cloud use NGINX as their webserver of choice, whether we’re talking about Amazon or even Microsoft Google or any of them. Lori, does F5 maybe view this acquisition as a way to expand your footprint in public cloud? If so, how?

    MacVittie:  I don’t think we looked at exactly how that’s going to play out, and what we’re going to do with that. The webserver is something different from the proxy technology that most of our products are built on. So there’s some differences there in how that works. We’re still looking at roadmaps and trying to figure that out. For right now, we’re just going to keep going ahead with both sets of road maps and moving forward. As we continue to explore what we can do together, we’ll figure out where it makes sense.

    Shimel: Sidney, same – flip side of that coin – of that question to you around public cloud. Do you see an angle where F5 helps there?

    Rabsatt: Yeah, I think F5 already had strong relationships with quite a few of the cloud vendors as do we, and we expect that – we ultimately want to give folks a choice. This all boils down to organizations are trying to build the applications that make sense for them. They want to be able to leverage the best tools and capabilities that help them deliver those applications while giving them the freedom to build the application they want. So whether that is on one cloud, on multicloud, across clouds, and on prem locations, they need that flexibility to do what makes sense for them. A big part of what we’re trying to accomplish here is making sure that F5’s large customer base has the capabilities that NGINX large user base has, which is again, that freedom of flexibility. That means that whether it’s on Amazon Google, Microsoft, any cloud, or any on prem solution, they get to deliver their applications with the security, controls, the visibility that they desire.

    Shimel: Excellent. I’m just – in hybrid situation, what about – one of the hottest topics certainly in technology today is the whole Kubernetes container thing. I know both F5 and NGINX had Kubernetes-related solutions and playing in that market. What, if any, does this acquisition, what if anything does this acquisition bring to that? Either one?

    Rabsatt: I would say it should be a net benefit. NGINX, there was a recent report I saw. It’s in the public domain. NGINX is the most commonly used ingress controller for Kubernetes environments today. If you think about what Kubernetes means for organizations that are building these modern applications, it’s giving them an environment that allows them to build typically microservices-based applications. So getting those applications exposed to the outside world requires the first thing, the foundational element, the hierarchy of need. It’s getting traffic in and out of that Kubernetes environment. How do you do that? Through the ingress capability.

    Our ingress controller is pretty much the number one solution out there for doing that today. That’s the first place people have to start before they get into some of the more complex or exotic things they’d like to be able to do. So our customers, our users are already benefitting from that. It’s allowing them to do what they need to do when it comes to adopting or testing Kubernetes for their own uses.

    Shimel: Sure. Lori, even independent of NGINX, what effect is this whole move to Kubernetes and container-ized environment having on F5’s business?

    MacVittie: Wow. On the business? Don’t really know. No. There is – we see a lot of customers asking. One, they want guidance on how to do this at scale and safely. A lot of our customers are very concerned about security, about performance. How do they bridge those two worlds, coming out of Kubernetes and trying to get into an environment where there’s a lot more traditional apps and infrastructure still supported? It’s trying to bridge those two worlds.

    Our customers are looking at it and they’re bringing it in and they’re adopting it, but they’re also having challenges with the deployment side where NetOps traditionally sit that they don’t have the skills to do the automation. They have problems with integration of the toolsets to build those pipelines. So one of the things that this kind of an acquisition does is bridge that gap. Hopefully we’ll see better integration and easier in and out, both actually in the flow of traffic, but also just between the teams in the businesses, so we think this will help address some of the pains at the people level in organizations by having this end to end delivery chain with both F5 and NGINX.

    Shimel: Sure. Sidney, maybe you would know. What are the plans with some sort of common interface or more integration between the two lines?

    Rabsatt: I’d say it’s still very early on. We have some good ideas, but we’re not really in a position to preview too much. I will say there’s going to be a focus on again, making sure we’re bringing the best of both solutions together. Again, not nearly as much overlap as you might have expected, or we – I should say as we might have expected. Yeah, what we’re looking at is really the opportunity to bring more features to the things we already have, more so than trying to get rid of things. We’re looking forward to getting this innovation stuff underway. We’ve had some very early conversations, but over the next days and weeks, we’re going to be digging into it very deeply.

    Shimel: Makes sense. Lori, so this was as we said right from the outset, what we’re turning to is a move up the application stack. What – is F5 done with that? Will we see more F5 potential either via the acquisition or holistically – organically moving up this stack here in the application world?

    MacVittie: I can’t obviously comment on any kind of [laughter] –

    Shimel: Can’t tell _____ acquisition is. I get that one.

    MacVittie: That’s right. With any company, that’s always a possibility. We have been transforming ourselves in the past year really moving forward with a lot more innovation in terms of exploring things and looking at – we’ve got Aspen mesh going, which is service mesh trying to bring some sanity to Kubernetes inside for scaling. Cloud services, we’ve made a lot of our services as a service. You just hook them up. We’ve been moving deeper into the application stack for a while. This is just going to accelerate that transformation from ADC to application services company.

    Shimel: Understood. Understood. Well, guys it really is exciting. One of the things I sit here at devopsy.kinsta.cloud and Security Boulevard and we go to all of the conferences and we cover all the news, and you hear so much “What’s bleeding edge, bleeding edge, bleeding edge?” We tend to forget, or we overlook what are the nuts and bolts, the bread and butter that keeps the internet and these applications going? It is things like the NGINX web server that is the dominant web server in the world today. It is things like the F5 lineup of software and of _____ actually that have been delivering the internet to the public since 2002 or whatever it is. Lori, you probably know, but so it’s good to see innovation continuing to happen. It’s good to see new combinations taking place.

    I’m excited to see what comes out of – Sidney, as you said, it’s very early on. It’s a day after the acquisition was announced. Maybe we could check back in six months and see how things are progressing along these lines. In the meantime though, just the usual questions. Everyone from NGINX is staying on? There’s not going to be layoffs as part of the consolidations and stuff, or again too early to tell?

    Rabsatt: I mean what we know is F5 is interested in our organization and not just products. They’ve made it very clear they want the vast majority of folks to stay and we expect that to continue to be the case. We look forward to what the future holds together.

    Shimel: Yep, understood. Look, I wish you a lot of success, both you guys individually, as well as F5 and NGINX. It’s an exciting combination. Congratulations to both organizations and Lori, I think congratulations on especially to F5 for really making a real great addition to the family there.

    MacVittie: Thank you. I know there’s a lot of us. We’re just really excited about this and about the future and what we can do together.

    Shimel: Cool, cool, cool. All right, congratulations, guys. We’re going to call it a rap on this edition of DevOps Chat. Lori MacVittie for F5 networks. Sidney Rabsatt for NGINX, soon to be F5 Networks. Thanks for being our guest today on DevOps Chat. Thank you everyone for listening. You’ve just listened to another chat. Bye bye.


    — Alan Shimel