Category: DevOps and Open Technologies

Editorial Calendar for February 2016

  • Vercel Acquires Turborepo to Gain Build System

    Vercel Acquires Turborepo to Gain Build System

    Vercel today announced it has acquired Turborepo, a provider of a build system for JavaScript and TypeScript applications that provides developers with access to an easy-to-use monorepository for their code.

    In the wake of that acquisition, the command line interface (CLI) for accessing Turborepo will now be available under an open source license.

    Jared Palmer, creator of Turborepo and other popular open source projects including Formik and TSDX, will continue working on accelerating Turborepo’s capabilities as the new leader of a build performance team at Vercel.

    The goal is to move existing users of the Turborepo cloud service to a Vercel platform for building applications using the Next.js framework, which makes it possible to build web applications based on the React library for creating user interfaces that enable both static site generation (SSG) and server-side rendering (SSR).

    Palmer said monrepositories such as Turborepo not only make it easier for developers to manage builds but also reduce the amount of time required to process those builds using a continuous integration/continuous delivery (CI/CD) platform.
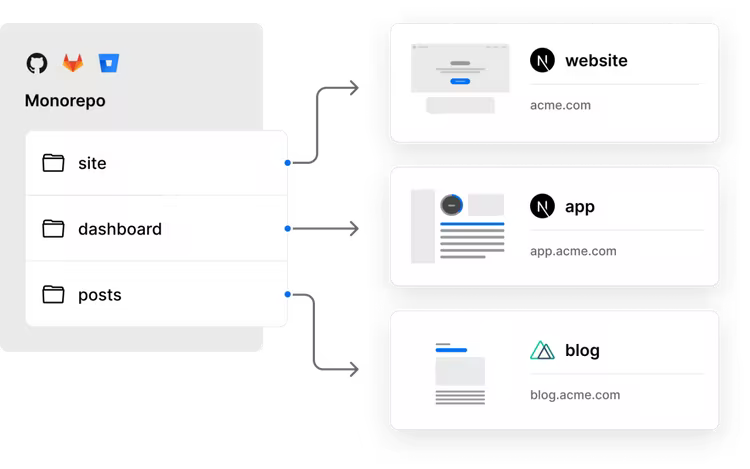
    Rival build systems are also much more complex to configure and manage, which Palmer said is a primary reason many developers have not yet set up their own mononrepositories.

    As the number of applications that organizations want to build and deploy in the digital business transformation era increases, the focus on developer productivity is intensifying. Rather than having to maintain a complex build system, Turborepo is designed to be simple to configure. As a result, more developers can reduce build times by as much as 50%, noted Palmer.

    In effect, front-end developers are able to more easily become full-stack developers by combining that build system with the Next.js framework, he added.

    DevOps teams will need to adjust to applications capable of providing richer application experiences without relying as much on backend infrastructure. That shift has implications for everything from the amount of network bandwidth consumed to the performance of web applications. The Vercel platform employs caching, routing and a React framework to optimize application performance in a way that reduces the dependency on backend infrastructure to optimize application performance.

    As web application development continues to evolve, the overall rate at which they web apps are built should increase significantly. Naturally, DevOps teams will need to consider the implications of having more applications move through DevOps pipelines and the need to continuously update those after they are deployed.

    It’s not clear whether or how much DevOps teams will nudge developers toward frameworks such as Next.js to develop web applications that might not tax backend infrastructure as much as previous generations of applications. In effect, developers can take advantage of frameworks that enable them to treat the underlying IT infrastructure as if it were serverless whenever possible with tools that have a familiar JavaScript construct. Vercel claimed there are already more than 30,000 sites running Next.js in production at organizations like Airbnb, Hulu, Nike, Ticketmaster and Uber.

    One way or another, it’s clear that the way web applications are being built is fundamentally changing. The only issue now is determining to what degree the rest of the IT organization is prepared to absorb that level of change.

  • AWS Outage Outrage | Rusty Linux | ARM Latest

    AWS Outage Outrage | Rusty Linux | ARM Latest

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Amazon Web Services falls on its face, Linux’s move to Rust takes the next step, and the FTC stabs another fatal wound in the horrible Arm/Nvidia deal.

    AWS us-east-1 Breaks the Internet

    First up this week: Amazon Web Services’ outage on Tuesday sent scads of DevOps teams scrambling. But what was the cause?

    Analysis: DNS DDoS?

    While we still don’t officially know, there is some chatter to speculate on. Could it be that AWS’s DNS infrastructure is vulnerable to DNS reflection attacks?

    Hello. It’s Dave Lee: From angry Adele fans to broken robot vacuums

    It started early on Tuesday morning. Robot vacuums ceased sucking, Wi-Fi cameras stopped watching and eager Tinder daters were left unable to “swipe right.”
    …
    Within Amazon itself … the unthinkable occurred: grounded delivery drivers were unable to load packages and deliver to customers’ doorsteps, just as the peak Christmas season begins to step up. … Drivers at multiple facilities across the country were sent home … some dreading whatever workload may await.
    …
    An outage at Amazon Web Services … had rippled through the online economy, crippling services used by millions of people. … An “impairment of several network devices” in … US-EAST-1 was the “root cause” of the disruption, Amazon said.


    I was wondering what DevOps’ers learned? Enter Max Rozen:

    AWS took approximately an hour to update their status page to indicate anything was happening. … While our infrastructure is hosted across 20 AWS regions, a single point of failure was hosted in us-east-1.
    …
    What we learned: … I learned the saying, “Friends don’t let friends deploy in us-east-1.” As a result, we’ll be moving some things over to us-east-2 to start with. Secondly, we’ll be adding redundancy and the ability to failover to another AWS region.


    Getting inside the business, here are Eugene Kim and Katherine Long, to go over everything:

    Even inside AWS … information on the outage remained sketchy [and] rumors spread among staff. One AWS employee speculated that the outage was caused by an “orchestrated DNS attack,” while another employee downplayed those concerns.
    …
    According to a screenshot of an internal AWS communique … ”firewalls are being overwhelmed.” … A separate internal note said … the network issue “specifically impacted” Amazon’s internal DNS servers.


    Linux Officially Gets Rust Code

    The Rust language has taken the next step toward being part of Linux kernel development. Some “drivers and other non-core kernel programs” written in Rust can now be PR’ed. But there’s still no plan to go further.

    Analysis: Still needs lubrication

    Rust is much better than C for writing memory-safe code, and coding provable implementations. However, bootstrapping the toolchain is still stupidly hard.

    Steven J. Vaughan-Nichols: Linux is getting more Rust in it by the day

    It wasn’t that long ago that the very idea that another language besides C would be used in the Linux kernel would have been laughed at. [But] this has been coming for several years now. … Why? Because it’s much safer than C, especially at handling memory errors.
    …
    The next “patch series [adds] support for Rust as a second language to the Linux kernel.” … While he’s encouraging a slow but steady approach to introducing Rust into Linux, [Linus Torvalds] has also said that using Rust interfaces for drivers and other non-core kernel programs makes sense. [But] no one’s going to rewrite the kernel’s 25 million lines of C in Rust.
    …
    The Rust code proposed for the kernel now relies on the stable Rust compiler rather than the beta compilers. … As Linux kernel and lead Rust on Linux, developer Miguel Ojeda, put it, “By upgrading the compiler, we have been able to take off the list a few unstable features we were using.”


    How is it “safer than C”? ssokolow shares this fascinating insight:

    Rust tries to encourage that through good API design which allows it to be proven at compile time that the invariants will be upheld, thus avoiding the need to choose between safety and performance. My favourite example … is “the typestate pattern” which lets you teach the Rust compiler to prove correct traversal of any state machine.
    …
    A more mundane example would be the iterator APIs: No need for bounds checking if the iterator looks up the length once at the beginning and the APIs prevent you from wandering out of each entry it hands you. … Rust programs tend to run faster than their C and C++ counterparts because the developers feel comfortable introducing and maintaining more aggressive optimizations.


    “And then a miracle occurs,” quips @dave_universetf:

    I’m intrigued [but] I can’t help but feel sorry for the people doing bootstrapping work. C is hard enough to bootstrap, but Rust is a whole new level of pain.
    …
    Rust is literally not source bootstrappable. [The compiler] that works right now is Rust 1.39. So then you have to compile 18 more Rust compilers to get up to the current version.


    Nvidia’s ARM Woes Continue

    As I’ve said before, this deal really shouldn’t go through. Ownership of the ARM ISA and the core designs would be a huge strategic stick to beat Nvidia’s competition with. ARM chips are an increasing fixture in the datacenter—especially those that value “performance per Watt.”

    Analysis: Stick a fork in it

    Nvidia’s attempt to buy Arm from SoftBank is suffering death by a thousand cuts. And the latest wound comes from the FTC’s Higonokami knife.

    Paul Thurrott: FTC Sues to Block Sale of Arm to Nvidia

    The U.S. Federal Trade Commission … sued to block Nvidia’s $40 billion acquisition of … Arm, citing competitive concerns. … Nvidia announced its intention to purchase Arm from Softbank for about $40 billion, over one year ago, in September 2020. But the deal fell under immediate criticism from the major industry players that rely on Arm’s … designs, and the UK government announced … it would “intervene” for national security reasons.
    …
    Now, it may not happen at all. “We will continue to work to demonstrate that this transaction will benefit the industry and promote competition,” Nvidia said.


    Explain like I’m 5? Here’s swillden:

    ARM has a non-trivial and increasing share in the data center. … ARM is much, much bigger than phones … Arm is an important competitor to Intel and AMD. … Arm licensing IP to Qualcom, nVidia, Mediatek, Unisoc, Samsung, Apple, Google, etc., has been great for many areas of technology.
    …
    Arm acting as a common … designer for a bunch of different chip vendors has been extremely good for … progress in CPU/SoC design. … It would be really unfortunate if a lot of the industry were to shift back to x86, eliminating all of the competition on hardware features that we get from the many ARM chipmakers.


    But what of SoftBank? Ian King runs the numbers:

    Wall Street analysts are all but calling the deal dead. … According to Citibank analysts, the chances of the Nvidia purchase closing are now just 5%.
    …
    The company faces the prospect of losing a jackpot of roughly $74 billion. … Other suitors are unlikely to match such an offer. … So SoftBank’s best alternative may well be an initial public offering for the Arm business—but that is likely to value the company at … $19.8 billion—only about 27% the value of the … Nvidia deal.


    The Moral of the Story: It’s no secret that the both of us are running out of time


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk. (It’s so typical of me to talk about myself—I’m sorry.)

    Image: Ləman Şirinzadə (via Unsplash)

  • Securing the Software Supply Chain with Behavioral Analysis

    Securing the Software Supply Chain with Behavioral Analysis

    Lately, software supply chains find themselves in a very interesting and uncomfortable position—the industry spotlight—and not in a good way. While significant and costly breaches such as  SolarWinds or Kaseya make front-page news, supply chain attack tactics (e.g. typosquatting or dependency confusion) that target package managers such as npm, PyPI or WinGet can poison downstream applications or compromise developer credentials.  

    The software engineering community has been steadily increasing its use of third-party and open source solutions to help create new offerings. In fact, over the last five years, there has been a 259% increase in the use of open source.

    One reason for this is the simple fact that creating new applications takes time and can strain budgets that are already tight. With open source code, software engineers gain fast access to pre-existing code that’s already demonstrated a proven ability to address the very unique challenge they are looking to solve. By removing the need to reinvent the wheel, the development timeframe is accelerated, the costs are lowered and teams are freed to focus on the creation of new and unique features that the customers demand.

    At this point, turning to third-party code may seem like a no-brainer. However, it can also open the door to potential risks. This is especially true with engineers who, rather than checking software to ensure it is secure and compliant, take the providers’ assurances as gospel. 

    They are not alone. Other groups will try to conduct their initial due diligence at the onset if that’s possible. Soon after they then ease into a “set it and forget it” approach, where they fail to update the code over time. As a result, while the code may appear secure initially, vulnerabilities can emerge over time, and if the software is not continually updated, bad actors can leverage an unprotected window of opportunity. In fact, according to Enterprise Security Group’s “Modern Application Development Security” eBook, 48% of organizations regularly push vulnerable code. The same research also found that 60 percent of organizations have had production application vulnerabilities exploited.

    Organizations conduct static application security testing (SAST) and dynamic application security testing (DAST) to assess pre-production code vulnerabilities. They will also scan with AV before releasing software, examine signing certificates, and code quality. Yet, despite these efforts, they remain challenged by gaps in security processes and the ability to sufficiently inspect large, complex and multi-layered software packages. What’s missing is the ability to conduct in-depth analysis to pinpoint behavioral differences between compiled software versions.  

    Malicious tampering can often involve changing how the software interacts with the system on which it is deployed.  Differential behavior analysis highlighted below makes it easier to detect those unusual changes. For example, having an application suddenly add a pre-install script that downloads files via certutil is highly unusual. If the addition was planned, reasons for the change would be well documented and it would be associated with a significant new feature. For this type of change to happen in any other scenario is suspicious and deserves further investigation before the software is released. In this case, such action would have caught ua-parser-js developer’s account compromise.

    supply chain

    With the software supply chain at risk and with shared code the new normal, what’s needed is software assurance. 

    Software assurance allows teams to inspect every application layer within an installation package for the presence of software tampering, malware and other indicators of software supply chain attacks.   

    Begin the software assurance process with the deep inspection step through recursive package decomposition. The resulting software bill of materials (SBOM) becomes so much more than a build manifest (a list of components that should be in the final build). It becomes the means to determine exactly which components have unacceptable build quality or those that contain unwanted software behaviors. This enables developers to verify the code they are working with and take appropriate action to protect their customers and partners from the majority of software risks. These assessments include:

    • Software grading: The software package and every included component can be graded based on the types and severity of security issues found. Using a grading system makes it easy for software buyers to gauge the level of risk posed by a software package and determine whether additional deployment measures can be taken to mitigate those risks. For developers, component grading makes it easier to prioritize their remediation efforts and aids in the selection of higher-quality third-party components.  
    • Application hardening: Activating specific build or compiler options can mitigate vulnerabilities and protect applications against attack—but only if they are implemented correctly. Assessing whether these mitigations are correctly implemented ensures that these protection mechanisms will work as expected. 
    • Binary behavior analysis: This allows teams to fully understand how each software component interacts with the system on which it will run. The ability to understand third-party component behaviors, even when developers have no access to the source code, delivers a more comprehensive understanding of supply chain risks. Checking for unusual software behaviors or unexpected behavioral changes between one version and the next is often the only way to identify software tampering by a malicious actor. The ability to have this final check before distribution enables software developers to validate that the software being released is trustworthy.

    For companies that are using software to create business value or producing software that is mission-critical for their customers, turning a blind eye or making software assurance assumptions can no longer be tolerated. In today’s climate where increasingly sophisticated threats loom, inspecting software and monitoring updates for signs of tampering, malicious or unwanted additions is essential and must become a part of standard software development practice. 

  • Iterative Adds Experiment Versioning to MLOps Platform

    Iterative Adds Experiment Versioning to MLOps Platform

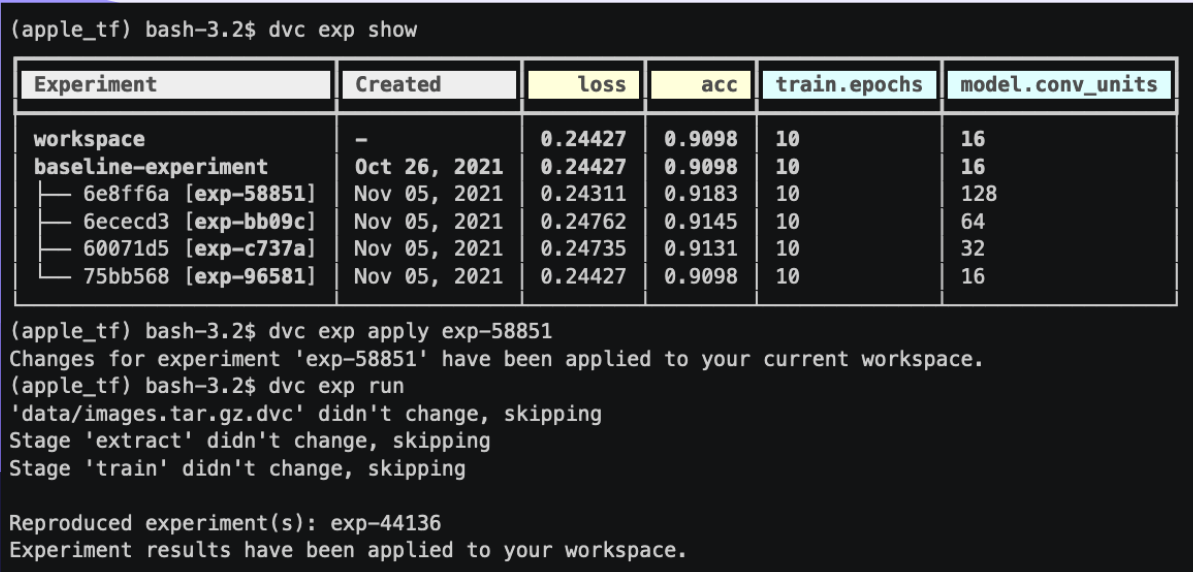
    Iterative today added an experiment versioning capability to an open source platform for managing machine learning operations (MLOps) using GitOps workflows.

    Dmitry Petrov, Iterative CEO, said the latest version of the Data Versioning Control (DVC) platform makes it simpler to save, compare and reproduce machine learning (ML) experiments at scale without requiring organizations to set up an additional repository to track them. Instead, organizations can store those experiments alongside other software artifacts in a Git repository, he said.

    As a result, IT teams will no longer need to try to keep track of experiments using spreadsheets or notebook tools such as Jupyter, he noted. Organizations that are building AI models for applications constructed using DevOps workflows will also find it easier to comply with a wide range of existing and forthcoming compliance mandates, added Petrov.

    The DVC platform makes use of a Git-like interface to enable organizations to track multiple versions of data sets, models and pipelines across an MLOps workflow. That capability is being extended to make it easier to manage the experiments data science teams create during the construction of an AI model.

    Iterative is at the forefront of an emerging debate over how best to infuse AI models into applications. Providers of platforms used by data science teams are making a case for separate repositories for tracking the artifacts used to construct an AI model. Iterative, on the other hand, is arguing for the use of an AI model build framework that uses the same Git repositories where any other type of software artifact is stored and shared. Iterative’s argument is that, in effect, AI models are just another type of software artifact, noted Petrov.

    In addition to reducing the total cost of building AI models by reducing the number of platforms required, a Git-based approach also makes it simpler for DevOps and data science teams to collaborate because the DevOps team will have more visibility into what AI models will eventually need to be incorporated into an application.

    It may be a while before the development of AI models and applications fully converges. Data science teams today typically have defined their own workflow processes using a wide range of graphical tools. However, as it becomes obvious that almost every application is going to be infused with machine learning and deep learning algorithms to some degree, the need to bridge the current divide between DevOps and data science teams will become more acute.

    In the meantime, DevOps teams should assume that many more AI models are not only on the way but that those models will need to be continuously updated. Each AI model is constructed based on a set of assumptions; however, as more data becomes available, AI models are subject to drift that results in less accuracy over time. Organizations may even determine that an entire AI model needs to be replaced because the business conditions on which assumptions were made are no longer valid. One way or another, the updating and tuning of AI models is likely to soon become just another continuous process being managed via a DevOps workflow.

  • CI/CD Is Still All About Open Source

    CI/CD Is Still All About Open Source

    One of the lessons I’ve learned in my years at the helm of devopsy.kinsta.cloud is that the heart of DevOps is CI/CD. And at the heart of CI/CD is open source. While the names have been changed to protect the innocent (and the obsolete), these lessons are as true today as they ever were. CI/CD is still all about open source.

    When we first started devopsy.kinsta.cloud, folks said that DevOps was just a symptom; CI/CD was the cure. For many of you, that cure was delivered via open source—probably using Jenkins. Jenkins, which itself was a fork of the open source Hudson project, was created by Kohsuke Kawaguchi.

    Jenkins was a CI tool at heart and later morphed into a CI/CD tool. Many people think that this fork in the road may have hurt the continued evolution of continuous delivery in the long term. But that is an argument for another devopsy.kinsta.cloud article (or maybe even a panel discussion at an upcoming DevOps live event).

    Regardless of where you stand on that issue, as an open source project, it is hard to argue with the success of Jenkins. Driving a lot of that success is the Jenkins plug-in architecture. There are literally thousands of plugins that allow Jenkins to work with just about anything. That is the engine that powered Jenkins, yes; but its secret superpower was and is open source.

    That said, Jenkins has grown a bit long in the tooth over the years. It’s not that it doesn’t do what it always did, it’s that what we do and how we do it has changed. Microservices, Kubernetes and even cloud have changed the very fabric of the tapestry in front of which Jenkins sits. The open source community that supports Jenkins should receive enormous credit here: It has tried mightily to keep up with the many changes. 

    Jenkins X sought to bring Jenkins to Kubernetes, for instance. But ultimately, nothing lasts forever and, as it says in the Bible, “For everything there is a season, and a time for every purpose under heaven: A time to be born, and a time to die.” Now, I am not saying Jenkins is dying, but I think its time as the leader of the pack is behind it.

    The good news is there are a host of new CI/CD tools that have risen to fill the vacuum left by Jenkins. Some of them are entirely open source; some are based on open source. Solutions such as Buildkite, Harness, Codefresh, GitLab, GitHub, CircleCI, JFrog and Tekton to name but a few. 

    Another major development has been the rise of GitOps. Weaveworks has led the way in adoption, not to mention coining of the term GitOps itself, but clearly, they are not alone. What these solutions all have in common, though, is open source.

    I used to think it was sort of a chicken-or-the-egg question when it came to CI/CD and open source. But I realize now that it is not. I firmly believe that, if not for open source, CI/CD would not be the force it is today. Make no mistake, it is truly a force. CI/CD has become the dominant method for software development.

    Of course, you could say “Why stop at CI/CD? Open source has become the dominant software development foundation in observability, OS, cloud and so much more!” Yes, I agree—we are living in the open source age. This rising tide may in fact lift all boats, including CI/CD.

    This wave is forcing all vendors to either go entirely open source or at least support open source. What’s more, for the foreseeable future, I don’t see that changing. Open source has also wrought other changes in the market. How software tools, including CI/CD, are distributed and consumed. Who is hiring enterprise software salespeople anymore? Doing large POCs? No, open source has resulted in getting software into the hands of developers and DevOps teams directly and delivering delight. If your product works, they buy it. If it doesn’t work, they won’t, either—and they will let you know, too!

    This meritocracy is another benefit of open source and is helping to speed the development of better, next-gen CI/CD tools in the market. And at the end of the day, we are all better off for that.

  • 22 Engineering Leaders Weigh in on APIs

    22 Engineering Leaders Weigh in on APIs

    Every business today is a digital business … and if it’s not, it will be soon.

    A recent survey by Deloitte found that digitally mature companies are better able to navigate rapid change and, as a result, perform much better financially.  Nearly two-thirds of survey respondents asserted that organizations that don’t digitize in the next five years will be “doomed.”

    Application programming interfaces (APIs) are the cornerstone of these digital transformation efforts. APIs aren’t just technical conduits that let applications communicate with each other. In a software-driven world, they allow developers to build services more quickly, enable innovation, open up new markets and drive competitive advantage.

    A new State of the API report from Postman, which surveyed 28,000 developers and other tech pros, offers a vivid snapshot of APIs’ central role in modern organizations. It showed that API-fueled innovation has helped companies respond to the pandemic; that the global API ecosystem is growing; that developers are spending more time than ever with APIs and that almost everyone believes investment of time and resources into APIs will increase or stay the same in their organizations for the next 12 months.

    To learn more about APIs’ status in the enterprise, I’ve spent part of 2021 interviewing 22 engineering leaders from various companies for my podcast, Breaking Changes. I wanted to dive deeper into how and why these leaders view APIs as critical to business strategy and hear what lessons they’d share with others.

    Here, in 20 bite-sized chunks, are the recurring themes:

    Business. The greatest value generated from API operations is rarely directly from any single API, but around the partner enablement APIs make possible. Over and over, companies see that building an API ecosystem helps extend their business’s reach and deepens the connection with partners and customers.

    Strategy. Without proper planning, an organization will always be stuck in reactive mode when it comes to the applications that API operations are powering. It’s much better to have a comprehensive API strategy.

    Third-party relationships. Reliance on third-party systems—the vast supply chain of partners and vendors that organizations share data with via cloud-based technology—is exponentially increasing, pushing organizations to develop a more formal and external API strategy.

    Resources. The resources surrounding API operations need to speak to developers, support them and help make their lives easier as they work with a company’s APIs.

    Governance. It’s important to be cautious in automating governance at the pipeline level before developing relationships across teams and a centralized API governance approach is vital, too. API governance is the practice of applying common rules and security policies for APIs. 

    Management. The management of APIs is a continuous journey and not a destination, requiring a significant amount of planning and attention to reach desired objectives.

    Global. We are all increasingly reaching a global audience with APIs, and every organization’s message and resources need to reflect the increasingly diverse audience.

    Multi-Protocol. The future of APIs is multi-protocol, requiring a diverse toolbox of API protocols and patterns to properly grow ecosystems over the next decade.

    Enablement. Companies need to be enabling their API development teams, not governing them; making sure they have what they need to do APIs well while also failing safely.

    Regulations. API regulations are here and are pushing mainstream enterprises to become technology companies, requiring that they have an API strategy for the future.

    Mobile. The world reached a milestone in 2019: There are now more cellphones than people. APIs are how digital resources are made available on these devices in both leading and emerging markets.

    Opinionated. Informed and opinionated approaches to the API life cycle will make a bigger impact than any single technology used in the infrastructure stack.

    Intelligence. There is a massive opportunity in deriving intelligence in aggregate across the millions of API requests we make each day across core business applications.

    Quality. Organizations should prioritize not just testing APIs but testing the API tests themselves. This ensures a level of quality and reliability across all APIs, regardless of the team working with them.

    Education. Ensuring that teams have the proper ongoing training and education around the API life cycle must be a top-line priority across API operations.

    Authentication. The authentication layer of the API infrastructure holds a wealth of intelligence. Having humans study this dimension is critical for security.

    Data. Challenges and opportunities at the API data layer are massive, and machine learning is giving teams an exoskeleton to support failing and iterating faster during development.

    Privacy. Ensuring that privacy is a basic building block of the API life cycle helps developers focus on what they do best, resulting in higher-quality applications that also respect privacy.

    Observability. API analytics have matured in the last few years; becoming much more about observability across the API infrastructure and helping organizations see and respond to what matters.

    Open Source. Open-source technology is an essential part of growing and supporting an API ecosystem, providing both the technical and human nutrients needed to be healthy.

    By keeping these 20 points in mind, organizations can maximize APIs’ role as an extremely powerful mechanism for leveraging data and application functionality for business success. APIs will underpin digital transformation for many years to come, so it’s important to cover all the bases.

  • AWS re:Invent Roundup: Private 5G | Graviton3 ARM Chips | DevOps Guru++

    AWS re:Invent Roundup: Private 5G | Graviton3 ARM Chips | DevOps Guru++

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Three things that caught my eye from Amazon Web Services’ re:Invent 2021 conference: Private 5G, Graviton3 chips, and something called DevOps Guru for RDS (yes, really).

    Private NRaaS vs. Wi-Fi

    First up this week: AWS Private 5G is a new turnkey service, offering local private cellular data infrastructure, for places where Wi-Fi just doesn’t cut it. Despite the name, it offers a 4G/LTE fallback to 5G/NR. Because it’s AWS, the hardware is free—you just pay for usage.

    Analysis: Combine with an Outpost for a sharper edge

    Wi-Fi is unreliable and low powered. 5G over the 3.5 GHz “citizens’ band” seems like a great alternative (just don’t tell the lunatic fringe of the anti-5G brigade).

    And, of course, AWS makes it easy to buy—Amazon ships you all the private radio gubbins for “free” and just bills you based on capacity and usage. It’s automatically configured and remotely maintained. You just take your internet connection and plug it in.

    Aisha Malik: Amazon launches preview of new AWS Private 5G managed service

    “AWS Private 5G” … is a new service that aims to make it easy to deploy and manage your own private network. … AWS CEO Adam Selipsky said that with AWS Private 5G, you can set up and scale a private mobile network in days instead of months.
    …
    There are no upfront fees or per-device costs: … Customers pay only for the network capacity and throughput they request. [It] scales capacity on-demand.
    …
    AWS Private 5G is available in preview in the United States.


    And this is better than Wi-Fi how, exactly? Ballu counts the ways:

    Industrial area coverage: Where you need 50 Wi-Fi radio units, you can provide service with 3–4 p4G/p5G radios.
    …
    Hazardous areas: Where you can’t provide the networking at all the corners or areas, one p5G radio blast area (esp with beam technology) can.
    …
    Packet loss: Less packet loss compared to Wi-Fi (believe me, it’s a big deal in the Industrial world)
    …
    Compatibility: What’s a negative for 5G modems (not many devices are available), is positive to some extent. Once investment is made with 5G modems, the devices can be on the road too.


    Unsurprisingly, Brian Roemmele feels vindicated:

    Precisely as I wrote about in 2017 to great ridicule from an analyst at a famous VC firm: Amazon is becoming a phone company.
    …
    From the Sidewalk Network to the Kuiper satellite system to local 5G. The network is no longer just “dumb pipes.”


    Graviton3: AWS ARM SoC is PDQ

    Graviton3 is the latest version of Amazon’s ARM server chip. It looks like it’s based on a 5nm process implementing the latest ARMv9 ISA. AWS is making the usual claims about it being much faster than the previous generation, but it also has new security features.

    Analysis: Cool chips

    AWS is deadly serious about low-power, high-performance compute. Amazon is just one licensee that would be distressed to have Nvidia owning Arm.

    As I said last week—and the week before that—ARM chips are an increasing fixture in the datacenter, especially ones that value “performance per Watt.” Other IaaS providers might bleat about how they’re reducing the energy used to cool their data centers, but surely it’s a better plan to start with less waste heat.

    Maria Deutscher: AWS debuts new compute-intensive and AI instances powered by custom chips

    AWS’ new Amazon EC2 C7g instances target compute-intensive workloads such as analytics tools and scientific modeling software. The C7g series is based on the AWS Graviton3 chip, the third iteration of the cloud giant’s internally-designed processor.
    …
    Companies that plan to use C7g instances for machine learning workloads can expect an up to threefold performance jump in AI performance. The speed jump is partly the result of the processor’s support for bfloat16, a specialized data format [that] enables applications to process floating point numbers faster and using less memory than FP32, the data format historically used for the task.
    …
    For cryptographic tasks, Graviton3 delivers as much as double the performance of the Graviton2. … The chip introduces a feature called pointer authentication to reduce the risk of cyberattacks.


    Tim Anderson has been sifting through the re:Invent announcements:

    Top of the list perhaps is Graviton3, the next generation of AWS’s homemade [ARM] server processors. These chips will be used in new C7g instances previewed offering DDR5 memory (50 percent more bandwidth than DDR4) and up to 25 per cent better compute performance compared to instances powered by Graviton2.
    …
    Adam Selipsky gave his first Re:Invent keynote as AWS CEO. [He] said Graviton uses “up to 60 per cent less energy.” … Graviton matters because it is among those leading a charge to get more [ARM] microprocessors into data center and cloud infrastructure, and because if it’s more energy and cost efficient to operate, it’s critical to Amazon’s bottom line, sorry, today’s environmental concerns.


    And is that pointer-authentication feature useful? Yes, very, says spijdar:

    Very useful. … If the performance is good, this is a nice extra layer that makes return-oriented programming more difficult. Combined with NX bits, it really raises the difficulty in developing/using many types of exploits (it’s not impossible to bypass … but there’s no perfect security).


    DevOps Guru Adds RDS Support

    DevOps Guru for RDS is the latest upgrade for AWS’s oddly-named smart monitoring features.

    Analysis: Silly name; useful tool

    Laplace and Gauss were right: Your DevOps team aren’t all rockstars. “Average” ops staff are in the majority. So extending AWS’s monitoring automation to your database instances should be a positive step.

    But that branding: Can anyone take it seriously?

    Stephanie Condon: AWS brings more automation to database management

    The new Amazon DevOps Guru for RDS automatically can find and fix database issues … helping developers using Aurora detect, diagnose and resolve database performance issues. [It] can help remediate a range of issues, such as over-utilization of host resources, database bottlenecks, or misbehavior of SQL queries.
    …
    Last year, AWS introduced DevOps Guru, a service that uses machine learning to automatically detect and alert customers of application issues. … Amazon DevOps Guru for RDS builds on that
    …
    Users can view [issues] in the DevOps Guru console or via notifications from Amazon EventBridge or Amazon Simple Notification Service (SNS).


    Sounds interesting, says u/random_dent:

    I thought the DevOps Guru for RDS sounded interesting. You need to enable performance metrics first, which have their own charges, but it still looks not too expensive, plus three months free-tier, so we may try it out.

    We’ve had some odd issues with RDS performance that are too inconsistent to lock down. It would be interesting to see if this could give us some insight.


    But that name! Here’s Thomas LaRock—@SQLRockstar:

    I’m old enough to remember when DevOps Guru for RDS was just called “database performance monitoring.”


    And @shmick is young enough to say it like this:

    such a cringe name


    The Moral of the Story: Misfortune tests the sincerity of friends


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Andrew Svk (via Unsplash)

  • GraphQL as a Meta Layer

    GraphQL as a Meta Layer

    There’s a lot of interest in GraphQL lately. The query language is excellent for data retrieval, and it could act as a more usable mechanism to evolve the traditional REST API integration approach. But as adoption grows steadily, architects are now considering the implications of managing GraphQL at scale.

    Certain issues may hinder GraphQL in practice. To review, security concerns require a nuanced approach to authorization. This is because it wraps multiple data retrieval points into a single request. Without native caching, performance could also suffer. Changeability is also required to continually update the graph, which may ruffle feathers with those seasoned in the world of REST where a guiding tenet is to build for longevity using web-compliant methods.

    According to Jens Neuse, CTO, WunderGraph, there is a simple way to mitigate most of these issues and harmoniously work with various API styles. To Neuse, the core problem is that GraphQL is not meant to be exposed over the internet. Instead, he advocates for interacting through a gateway. Such an intermediary would enable more implicit calls and proper authentication and authorization for specific underlying functions and resources. Using GraphQL as an internal integration layer could also help combine disparate APIs into a similar language, exposing GraphQL-like usability for frontend developers while allowing them to hit any API style on the backend.

    Below, we’ll consider the drawbacks of exposing GraphQL directly and see how an intermediary layer could benefit development. We’ll also uncover what open source software is on the horizon that could power this setup.

    Why GraphQL Shouldn’t be Exposed Publicly

    Facebook, the creator of GraphQL, uses an internal GraphQL API to power all of its apps across Android, iOS and web browsers. (This is not to be confused with their public Graph API). Interestingly, if we look at Facebook’s use of GraphQL, we see these endpoints are not exposed to the public web at all.

    It’s true. Open up Developer Tools in Chrome, and you’ll see there is not a single mention of a root HTTP endpoint like https://api.graphql/. Functions name GraphQL, sure, but they call it more implicitly. Other companies, like Twitter and Airbnb, use a similar abstracted approach to interact with a private GraphQL.

    In fact, most GraphQL APIs are not public. APIs.guru only charts 35 public GraphQL APIs—notable services include GitHub’s GraphQL API, Shopify Storefront and GitLab. This number is minuscule compared to the total number of public APIs, at over 24,000 according to ProgrammableWeb.

    A Layer In Between

    If we treat it as Facebook intended (and how they use it in production today), it could reverse the issues above, said Neuse. “These problems come down to our core belief that GraphQL is not supposed to be exposed over the internet,” he said.

    But if clients do not access a GraphQL endpoint, what are they interacting with? According to Neuse, the ideal architecture involves a layer between the client and the server. Such a layer would validate queries and represent verbose calls with simple functions. The process would involve a handshake as follows:

    1. Take query, store it on a server.
    2. Validate it; make sure it’s not malicious.
    3. Send back a handle to the client.
    4. Then, execute the query.

    Such a process could also enact universal policies on a per-function basis, thus solving potential authorization issues when fetching data from multiple backend services with a single query.

    “The issue is that using the query language comes with a cost,” Neuse said. “Not exposing GraphQL directly but ‘compiling’ it to a JSON-RPC API when deploying solves these problems.”

    Thus, the scalability issue isn’t so much an issue of size but of access. “GraphQL can be very valuable, even in small environments,” said Neuse.

    The Next Evolution of a Virtual Graph

    Another potential benefit of using GraphQL as an intermediary is combining APIs; a “virtual graph,” as Neuse calls it. This virtual graph offers a common integration language to interact with various API styles, whether REST, GraphQL, gRPC or webhook, in a GraphQL-like manner.

    Consider the ease with which package managers like npm enable developers to instantly install dependencies. For example, installing a package like React.js is as simple as initiating the command npm install react within Terminal.

    On the other hand, the API integration is very cumbersome. Users must read through documentation, create an account on a third-party site and download an SDK to call the service in their preferred language. So, why isn’t looping in dependencies like APIs and cloud services as simple as other common dependencies?

    According to Neuse, one reason is that the REST paradigm is obsessed with the resource constraint—aside from HATEOAS, it lacks a concept of relationships between data and fields. A virtual graph could enable a straightforward process similar to package managers, said Neuse. Interestingly, the WunderGraph team plans to open source a project that allows just that ability.

    GraphQL as a Meta Layer

    Many folks assume that GraphQL and REST are mutually exclusive. However, as we’ve seen, there are ways to use them in combination. Plus, with an abstraction layer, the REST versus GraphQL comparison becomes just an underlying technical nuance.

    “If you compare GraphQL to other specifications, like OpenAPI spec, you see GraphQL has the fastest-growing community,” said Neuse. As of 2021, JSON Schema is the most popular, used by 75% of developers, followed by Swagger 2.0 (54%), OpenAPI 3.0 (40%) and GraphQL (31%) according to the Postman State of API Report. While this number may be small now, 35% of respondents also said they plan to use GraphQL in the coming year.

    “It’s a very, very interesting movement,” said Neuse. What began at Facebook as a framework for data fetching for React apps has now expanded into something much bigger. Within this second new movement, largely driven by companies like Apollo and Hasura, GraphQL becomes the new data layer, he said.

    “Still, everybody is looking at GraphQL thinking they must migrate from REST—this is the wrong direction,” said Neuse. Instead of migrating all existing REST APIs to GraphQL, he predicts the industry will coalesce on using GraphQL as the integration language for querying REST APIs. A meta layer, if you will.

    Of course, meta has been a bit co-opted lately with Facebook’s rebranding …

  • WhiteSource Report Finds NPM Vulnerabilities Fixed Fast

    WhiteSource Report Finds NPM Vulnerabilities Fixed Fast

    WhiteSource today published a report that found most of the vulnerabilities that affect node package managers (NPMs), widely employed to deploy JavaScript applications, are addressed long before they are assigned a Common Vulnerabilities and Exposure (CVE) in the National Vulnerability Database (NVD).

    The report, based on an analysis of the vulnerabilities that WhiteSource tracks in its own vulnerability database and revealed at the AWS re:Invent conference, found more than 90% of vulnerabilities in NPM packages are fixed before the vulnerability is published in the NVD.

    Susan St. Clair, director of product management for WhiteSource, said that fact suggests that, overall, the open source community is staying on top of vulnerabilities as they are disclosed rather than waiting for them to be assigned a CVE number.

    The WhiteSource report comes on the heels of a breach of UA-parser.js, a widely employed NPM based on a JavaScript library that detects browser, engine, OS, CPU and device type/model from User-Agent data. Unknown malicious actors found a way to inject malware into the NPM that modified the library. That vulnerability has since been remediated.

    In fact, the WhiteSource report noted 83% of the CVEs assigned to the most widely used versions of vulnerable NPMs could be remediated before the publication of the CVE.

    In the wake of a series of high-profile breaches of software supply chains, there is a lot more focus on how open source software is actually secured. Commercial software products have a distribution list that they typically notify of a security patch. Open source updates, on the other hand, need to be tracked by developers that use that software. The level of attention individual developers might pay to any number of open source updates can vary widely.

    Many developers are also hesitant to immediately update their applications because they are not sure what impact that additional code may have on their application, said St. Clair. For example, their application may have dependencies that are no longer backward compatible with the updated code, she noted.

    Developers also need to determine the degree to which that vulnerability may affect their applications because they often don’t use every component of an open source library, so the fix being offered may not be required.

    Open source project maintainers often depend on their community to help uncover vulnerabilities and create the fixes as quickly as possible. When a vulnerability is detected in an open source library, the more common practice is to report it to the NVD even after the fix for that issue has been made available.

    In general, St. Clair noted the most important thing for the open source community to remember is to remain proactive when it comes to tracking vulnerabilities and then implementing DevSecOps best practices. The one thing that is certain is that a wide range of malicious actors also are tracking those vulnerabilities closely. It’s not uncommon to see a wave of exploits being created once a vulnerability is disclosed via the NVD.

    The challenge, of course, is that the more open source software that is employed, the more difficult it becomes for individual developers to stay on top of every vulnerability in an application portfolio that only continues to grow. On the plus side, vendors have pledged more than $10 million to help better secure open source software. Hopefully, the return on that investment will become apparent sooner than later.

  • WTH? We Wanna WFH | DoD Dual-Sources JWCC | More Nvidia ARM Woes

    WTH? We Wanna WFH | DoD Dual-Sources JWCC | More Nvidia ARM Woes

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Working from home is de rigueur, JEDI redux, and more about Nvidia/Arm.

    Survey Says: Devs Stay Out of Office

    First up this week: GitHub’s annual survey of developers has some fascinating data on the workplace (ahem) “new normal.” The pandemic has radically changed devs’ expectations of where they can do their jobs.

    Analysis: WFH is SOP

    As with other roles, Dev people want to continue to work from home. But does this pose a threat to your DevOps culture? Make sure you can do Ops with equal flexibility.

    Paul Krill: Dev productivity is back to pre-pandemic levels

    GitHub’s “2021 State of the Octoverse” research … sees signs that work rhythm is returning to pre-pandemic levels. GitHub also found that 46 percent of developers who worked co-located with teammates now expect to work fully remotely or in a hybrid environment.
    …
    Based on data culled from more than four million repositories and surveys of more than 12,000 developers … JavaScript and Python remain the top languages, followed by Java and TypeScript. [And] GitHub found that development team performance can increase as much as 87 percent when reusing code and as much as 43 percent when using … CI/CD.


    Zeroing in on the WFH angle, it’s Richard Speed:

    Respondents who were in the office either full or part-time dropped from 42 percent before the pandemic to a mere 10.7 percent now. … That’s a lot of empty desks.
    …
    Fans of the ctrl-c, ctrl-v combo will be delighted to note that GitHub found that when code reuse was made “frictionless” at work, developer’s performance increased by up to 87 percent. … It’s all splendid stuff.


    But beware of statistical fallacies, thinks Henrik Ingo—@h_ingo:

    #WorkFromHome may have been more common than anyone realized. [But] is the population of GitHub users/respondents somehow skewed toward pioneers/early adopters? … This might be a case of correlation is not causation.


    Defense Dept. Orders New Clouds

    The DoD issued its latest cloud contract opportunity notice, with the snappy title of “Joint Warfighting Cloud Capability” (JWCC). Reading between the lines of the notice, it all sounds very DevOps-cum-Agile.

    The Pentagon has backed away from its previous insistence on a single supplier, and now wants at least two cloud providers.

    Analysis: JEDI redux, because AWS wants a do-over

    JWCC is the follow-on from the aborted JEDI procurement. Amazon Web Services was “disappointed” to have been passed over in favor of Microsoft. Now it appears the DoD wants them to share.

    What can you learn from such a multi-vendor DevOps strategy?

    Jordan Novet: Pentagon asks Amazon, Google, Microsoft and Oracle for bids

    Amazon and Microsoft were the finalists for a single Joint Enterprise Defense Infrastructure. … Microsoft won it in 2019, Amazon filed a protest and the Pentagon canceled the contract in July.
    …
    The new effort [is] known as Joint Warfighting Cloud Capability. … JWCC differs from JEDI because it allows the Pentagon to rely on multiple cloud providers.
    …
    The U.S. General Services Administration … said only two U.S. cloud infrastructure providers, Amazon and Microsoft, appear able to comply with all of the Pentagon’s requirements. … The value of the new contracts is not known, but the Defense Department estimates it could run into the multiple billions of dollars.


    In summary, heed this Anonymous Coward:

    Competing suppliers will try harder than one non-competing supplier. The DoD has had a lot of problems with One-Ring-to-rule-them-all systems like the F-35. … JEDI would have been the same.
    …
    Smaller steps with upgrades while testing/using offers better returns. Done right they can get a better deal by making the companies compete against each other in making sure the products are actually useful.


    But look carefully at the DoD contract opportunity, says bustinbrains:

    They’ll all get contracts. Then DoD will simply use the one that they actually like the best. No one can complain because it’s open-ended with no guarantees.


    Arm/Nvidia Deal on FTC’s Radar

    Last week, we talked about Nvidia’s goal to acquire Arm Ltd from SoftBank, and the regulatory challenges it poses—notably in the UK, home of the chip architect. After we went to press, the other shoe dropped.

    Analysis: Just Give Up Already

    As we said last week, Nvidia can’t be allowed to do this. Not only are ARM chips found in 99% of smartphones, but they’re an increasing fixture in the datacenter—especially places that value “performance per Watt.”

    Richard Waters: What’s next for the tumultuous takeover of Arm?

    Nvidia’s acquisition of UK chip design company Arm from SoftBank has provoked serious opposition on both sides of the Atlantic. … The US Federal Trade Commission had its own worries. China, meanwhile, is waiting in the wings.
    …
    The deal has shone a spotlight on the unique position Arm plays in the chip industry. [Nvidia] offered a guarantee that it won’t block any other companies from licensing Arm’s designs. The offer has fallen on deaf ears, with both the EU and UK ruling it inadequate. … Post-Brexit politics have also come into play.
    …
    At what point might Nvidia and SoftBank call it a day? … A stock market listing [is] the most likely alternative, with the UK a favoured venue.


    How’s it viewed from the inside? Here’s a hint from fivemack:

    I was at ARM when Softbank bought them; it came as a surprise to everybody, because we were absolutely confident that we were unbuyable because anyone interested in us would want to use differential licensing as a weapon against their competitors, and we … were confident that regulators wouldn’t accept that.
    …
    Lots of people went home with a year’s pay check in free money. And not a few people … went home with a decade’s pay check in free money.


    More and more DevOps workloads are running on ARM silicon. Here’s Biophoton:

    The low power expertise of ARM has to be an advantage in the data centre (DC) market. … Plus Linux is available on ARM so architectural lock-in of Intel could be eroded in the DC market.


    The Moral of the Story: You are known by the company you keep


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Lukas Mann (via Unsplash)