Category: Doin’ DevOps

  • Automation or Concatenation?

    Automation or Concatenation?

    We’ve been in a period of mergers and acquisitions for a while in the DevOps and DevSecOps spaces, and it seems to be heating up even more. Combined with products expanding to cover a more broad segment of the software development life cycle (SDLC) and strategic partnerships to cover more of the SDLC, it is starting to look like our automation efforts are going to be increasingly driven by vendors. Those efforts will be more concatenation than automation–though technically the same in perception, they vary wildly in implementation, and we should be planning for it.

    Build Versus Buy

    We have always struggled with build versus buy, and we have always struggled with best-of-breed versus overarching solution set. The entire hype of Every. Single. Vendor. Claiming to be a platform is partially driven by the latter argument. Putting “platform” in your marketing does not make a vendor better at those things outside its historical strengths, though, so that movement is doomed to fail for most organizations. Some were already moving to be a platform and had assembled–by M&A or by internal development–an impressive platform already, and those were successful because they were good at a breadth of things. The best of them are continuing this trend. I try to avoid plugging vendors here, but I think an example is in order in this case.

    Akamai’s recent purchase of NeoSec is the poster child for vendors doing the platform thing super well but not resting on their laurels. I’ve followed Akamai’s security offerings for years, and the platform has impressive functionality, but NeoSec is exactly what they needed. It plugs a couple of holes in their security offerings and brings a whole customer base into the Akamai fold. That’s what I’m talking about when I refer to the good ones.

    The problem is the acquisition and expansion of offerings trend is starting to gain a lot of steam, and not every vendor jumping on the bandwagon does the job as well as Akamai does.

    This leaves enterprise IT staff responsible for DevOps and DevSecOps – even straight security staff – with a new set of issues. Best-of-breed is taking a hit again, and overarching solutions are on the rise. The difference is the breadth that some of these new “platforms” offer is massive. And we know that even the good ones will have better and worse parts of the overall solution. So IT now has to start considering what vendors call a feature and how it individually compares to the competition. This will require more up-front work for evaluators. Now, a larger (and growing) list of “features” that were once “products” has to be considered piece-by-piece against the competition, and organizations must evaluate the feasibility (and cost) of implementing two (or even multiple) massive platforms to get the most critical functionality needed.

    As of this writing, point solutions that do one thing extremely well are holding up, but the trend is obvious. Those markets will be subsumed into larger offerings that may not do as well at other parts of the overall problem. Evaluators will have to be more careful and consider their options with an eye to the larger infrastructure and problem domain. Do you want a single vendor doing all of the steps of DevOps or responsible for every aspect of application security? That will be an individual decision and, if not, how the final solution/architecture looks will be a more complex discussion.

    Integration and Automation

    In our quest for integration and automation, many vendors are responding with the concatenation of tools to solve the automation part. You’ll be stuck figuring out if they’re doing it well enough for the org.

    But that’s not a problem you can’t resolve. You’ve been rocking it through staffing issues, lockdowns, growth and shrinking… Just keep rocking it. Choose the solution that makes the overall best sense for your organization, get it running and take a break; head to the beach for some relaxation time. Or whatever you do to clear your head – because the next problem will still be there when you get back, and it’s better to be relaxed when you tackle it.

  • Using Generative AI for Issue Remediation and Software Reliability

    Using Generative AI for Issue Remediation and Software Reliability

    In today’s fast-paced digital landscape, keeping your services up and performant, especially for cloud-based and online services, is crucial for staying competitive. Downtime or latency issues can drive customers away, especially when all it takes is a click to switch over to a competing SaaS solution. DevOps and site reliability engineering (SRE) teams face the constant challenge of minimizing mean-time-to-remediation (MTTR) when dealing with errors and issues. As valuable as search engines like Google are, the sheer amount of information available can make finding the right solutions a time-consuming task. What if there was a way to automate and streamline this process, making error investigation more intelligent, focused and efficient?

    This article will walk you through the journey of error resolution from the first obscure log line to identifying the problem hidden within it. We’ll resolve the issue using several tactics, ultimately leading to the use of generative AI to cut MTTR and provide precise IT recommendations. This journey includes useful measures and principles that can be applied by DevOps teams and explores the potential for applying generative AI.

    The Current Experience of DevOps/SRE

    Picture this: A log line pops up with an obscure error message, and the first instinct is to search for this message on Google for potential solutions. After all, someone else must have encountered a similar problem, right? However, the abundance of resources and search results can be overwhelming. The search results are often displayed based on website relevance, not necessarily the relevance of the error itself. Consequently, precious time is wasted sifting through countless search results, leading to a longer time to understand and remediate the error. For DevOps and SRE teams responsible for maintaining system stability, reducing MTTR is a crucial key performance indicator (KPI). This begs the question: How can we leverage automation and artificial intelligence to improve the search process and accelerate error resolution?

    Our First Step: Cognitive Insights

    In our organization’s initial attempt to tackle this challenge, we focused on leveraging crowdsourcing techniques to get more relevant results than the brute-force Google search. Moreover, we wanted to automate the process and run it offline so that when an incident occurs, we can offer useful insights rather than starting the search as the system is down or malfunctioning.

    The approach involves an offline phase and an online phase. The offline phase involved analyzing all our ingested logs and identifying common log patterns. This also allowed us to count how often this pattern occurred in our system and how prevalent it is. Then we crawled relevant technology forums like StackOverflow, Google Groups and Bing Groups for relevant discourse around these log patterns that could offer relevant solutions. The next step was to rank the search results by relevance and take the top five most relevant links.

    The offline phase resulted in a library of known log patterns and, for each one, a cognitive insight containing these links, as well as additional information such as the severity level, how many times this pattern occurred in the logs, the date of first occurrence and additional tags of involved technologies, tools and domains.

    The online phase occurs in real-time as new logs come in. Upon ingesting the log, it is automatically matched against all known patterns; if it matches one, it gets the cognitive insight for that pattern. This means that as soon as the problematic log comes in, the DevOps engineer already has focused and ranked search results and context to start from, which accelerates the investigation process.

    The Next Step: Why Don’t we ask Generative AI?

    After reflecting on our initial approach, we had an epiphany. Large language models (LLMs) like ChatGPT had already crawled the web and absorbed a vast amount of information. So, why not leverage their capabilities and ask them directly for insights? The idea was simple: Let the AI “read the posts” for us and provide us with recommendations. We started by formulating specific questions such as “What could the possible errors be?” and even went a step further by asking for further investigation steps. However, implementing this seemingly straightforward approach came with its own set of challenges. We needed to run preprocessing before asking the generative AI, as well as running post-processing on the answers it returned, to get what we expected. Let’s see what that process entails.

    How we Did It: Analyzing, Sanitizing and Validating

    Before asking ChatGPT (or any other generative AI tool) for assistance, several preparatory steps were necessary. First, we had to analyze incoming logs, identify patterns and score them based on severity. This allowed us to prioritize the most critical issues.

    Secondly, we had to carefully design our prompts for the generative AI using prompt engineering, ensuring that we framed our questions in a way that yielded precise and relevant responses. Prompt engineering is the practice of strategically designing effective prompts or instructions for language models to achieve more accurate responses. It involves carefully specifying the input format, context or constraints to guide the model’s generation process and obtain more accurate and desired results. This is true for any use of generative AI, and for our case in particular. Beyond accuracy, prompt engineering helped us tune the requested format and length of the answer to fit the “executive summary” paragraph we popped up for the user. This ensured it wasn’t too lengthy nor too short to provide meaningful insights.

    Additionally, we took great care in sanitizing the queries and removing any sensitive data to maintain privacy and security. This step was especially crucial for those working with public services, highlighting the importance of protecting users’ personally identifiable information (PII), such as names, emails, phone numbers, IP addresses or GPS coordinates.

    With all this preprocessing done, we sent the prompt to the generative AI. It is important to note that public services may not always be available (as some returned a “service is busy” message when working with ChatGPT and other services), so automation should take care of delays and employ retries as needed.

    Finally, as responses were received from the AI, it was essential to validate those. We ran an analysis and filtered out non-relevant answers from different domains (after all, a log is also a product of a tree, and Kafka is also a novelist), ensuring there was no offensive content or misleading information. The semantic integrity of the responses was also carefully evaluated.

    These AI insights have proven to be a powerful troubleshooting tool, and we’ve made it an integral part of our service.

    This journey is not unique. In fact, DevOps teams can employ similar measures for their own telemetry data to serve their own operational workflows. These principles, such as data sanitization and validation, even apply to other types of data and use cases.

  • Complete Guide to AWS Savings Plans

    Complete Guide to AWS Savings Plans

    AWS Savings Plans are a flexible and cost-effective way to save on your Amazon Web Services (AWS) usage. These plans allow you to commit to a specific amount of compute capacity over a one- or three-year term in exchange for a significant discount on your AWS usage. Savings plans can help you reduce your AWS bill by up to 72%, depending on the type of plan and your level of commitment.

    Why Do You Need AWS Savings Plans?

    With the growing reliance on cloud infrastructure in modern IT, it is crucial for organizations to optimize cloud computing costs without compromising on performance or scalability. AWS Savings Plans address this need by providing a flexible and cost-effective solution that allows you to commit to a certain level of usage at a discounted rate.

    With AWS Savings Plans, by committing to a specific amount of compute capacity over a set time period, you can save up to 72% on your AWS usage. This can result in significant cost savings for your organization, freeing up resources to invest in other business-critical initiatives.

    Another benefit of AWS Savings Plans is the flexibility they offer. Unlike Reserved Instances, which require you to specify instance type, operating system and region, Savings Plans are more flexible and can be applied across different instance types, regions and operating systems. This flexibility makes it easier for you to optimize your cloud computing costs while still meeting your business needs.

    Difference Between AWS Savings Plans and Reserved Instances

    AWS Savings Plans and Reserved Instances are both designed to help you save on your AWS usage, but they offer different levels of flexibility and cost savings.

    Reserved Instances require you to commit to a specific instance type, operating system and region for a one- or three-year term in exchange for a discount on your AWS usage. While this can result in significant cost savings, it also limits your ability to optimize your cloud computing costs based on changing business needs.

    AWS Savings Plans offer a more flexible solution that allows you to commit to a certain level of usage across different instance types, regions and operating systems. Additionally, in most scenarios, Savings Plans can provide a higher level of cost savings compared to Reserved Instances.

    Types of AWS Savings Plans

    There are two types of AWS Savings Plans: Compute Savings Plans and EC2 Instance Savings Plans.

    Compute Savings Plans

    Compute Savings Plans are the most flexible type of Savings Plans, providing a significant discount on your AWS usage across any instance type, region or operating system. This flexibility makes it easy for you to optimize your cloud computing costs based on your changing business needs.

    Compute Savings Plans offer a discount of up to 66% compared to on-demand pricing, depending on the level of commitment you make. They can be used across all AWS services that are powered by Amazon EC2 instances, including Amazon EMR, AWS Lambda and Amazon ECS.

    EC2 Instance Savings Plans

    EC2 Instance Savings Plans are a more specific type of Savings Plan, offering a discount on your AWS usage for a specific instance type within a region. These plans provide a higher level of cost savings compared to Compute Savings Plans, with discounts of up to 72%.

    EC2 Instance Savings Plans are ideal for organizations that have a predictable workload and require specific instance types within a region. However, they offer less flexibility than Compute Savings Plans, as they cannot be applied across different instance types, regions or operating systems.

    AWS Savings Plans Pricing Models

    AWS Savings Plans offer three different payment options to suit your organization’s budget and commitment level: All Upfront, Partial Upfront and No Upfront.

    All Upfront

    With the All Upfront payment option, you pay for the entire term of your Savings Plan upfront, resulting in the highest discount compared to on-demand pricing. This option is ideal for organizations that have the budget available to make a significant upfront payment in exchange for maximum cost savings.

    Partial Upfront

    The Partial Upfront payment option allows you to pay a portion of your Savings Plan upfront and the remaining balance on a monthly basis. This option provides a balance between upfront commitment and ongoing flexibility, with a lower discount compared to the All Upfront option.

    No Upfront

    With the No Upfront payment option, you pay for your Savings Plan on a monthly basis, with no upfront payment required. This option provides the lowest discount compared to on-demand pricing but offers the greatest flexibility for organizations with limited budgets or uncertain future usage requirements.

    How to Monitor and Manage AWS Savings Plans

    Monitoring and managing your AWS Savings Plans, as part of your overall cloud operations strategy, is critical to ensuring that you are optimizing your cloud computing costs and maximizing your savings. AWS provides several tools and services to help you monitor and manage your Savings Plans effectively:

    • AWS Cost Explorer: A powerful tool that allows you to analyze your Savings Plans usage and costs, helping you identify opportunities to optimize your cloud computing costs. With Cost Explorer, you can view your Savings Plans coverage, utilization and savings, as well as forecast your future usage and costs.
    • AWS Budgets: This service allows you to set custom cost and usage budgets for your organization, helping you track your Savings Plans usage and ensure that you are staying within your budget.
    • Savings Plans Recommendations: This feature analyzes your past usage and recommends the optimal Savings Plans for your organization. It can help you make informed decisions about which Savings Plans to purchase and how much commitment to make.

    Conclusion

    AWS Savings Plans are an excellent solution for organizations looking to optimize their cloud computing costs and save on their AWS usage. With their flexibility, cost savings and easy monitoring and management options, AWS Savings Plans are a valuable tool for any organization using AWS services.

    To unlock the full potential of AWS Savings Plans, it’s crucial to understand the different types of plans, their pricing models and how to effectively monitor and manage your usage. By doing so, you can maximize your savings and ensure that your organization is getting the most out of its investment in AWS.

  • How Platform Engineering Bridges the IT and DevOps Divide

    How Platform Engineering Bridges the IT and DevOps Divide

    Ballooning lead and process time, with an opaque corollary relationship to fixed and marginal cost, is a significant and complex burden for any enterprise. And multi-cloud complexity and inefficient organizational and technical processes are some of the most wasteful areas companies face–so much so that Synergy Research reports organizations are cutting back on their cloud spend as tech budgets continue to fall under intense scrutiny, resulting in a Q1 2023 cloud spending growth rate of 19% compared to 32% just last year. With cloud cost containment a top priority, Forrester advised tech leaders to demonstrate to CFOs how they will stay on budget and demonstrate ROI at the board level. A key area where companies can eliminate expensive waste and increase time to value is the relationship and workflow between IT and developers, which, while being the DevOps charter for nearly 15 years, has gotten less attention among the viable cost-containment strategies for enterprises in 2023. Revisiting the latest iteration of this DevOps charter through the implementation of platform engineering strategies can help enterprises create a faster, leaner and more scalable dynamic. Let us examine why it’s now time for enterprises to consider platform engineering as a potent way to not only increase efficiency but also to bridge the divide between DevOps and IT.

    The Old Way: Forcing DevOps to Dance to the ITSM Tune

    In traditional enterprise organizations, IT typically dictates a top-down ITSM practice that limits the tools an organization can use for development and deployment; in many cases, it inhibits CI/CD and other core capabilities and practices of DevOps. This awkward attempt to accommodate modern DevOps practice through an aging ITSM paradigm has led to a suboptimal software delivery performance and poor developer experience (DX).

    McKinsey, highlighting the criticality of DX, found developers at a leading SaaS provider spent 20% to 30% of their time integrating different services such as firewall changes, DNS and security access to deliver code through its CI/CD pipeline. That’s a lot of time spent on low-value, repetitive tasks, ensuring a painful journey for a disappointing result. If the DX pain is high enough, developers often go around IT and create resources on their own, leading to shadow IT, adding new cost burdens and growing security exposures. Every minute and engineer count: Five minutes saved per day among 500 developers saves a week’s development time.

    Surely, there is a better way.

    Platform Engineering: Collaboration Through Composition

    Platforming engineering and “platform as a product” have been key to the PaaS ecosystem for years but are now gaining fresh traction in the industry. In Puppet’s State of DevOps Report, 51% of respondents said they had already adopted platform engineering and 93% said it was a step in the right direction. Gartner predicted 80% of software engineering organizations will have platform teams by 2026.

    The concept can be defined in several ways. Gartner reported platform engineering is “an emerging trend intended to modernize enterprise software delivery… designed to support the needs of software developers and others by providing common, reusable tools and capabilities, and interfacing to complex infrastructure.” PlatformEngineering.org’s recent blog post defines it as the discipline of designing and building toolchains and workflows for self-service capabilities in software engineering organizations during the cloud-native era.

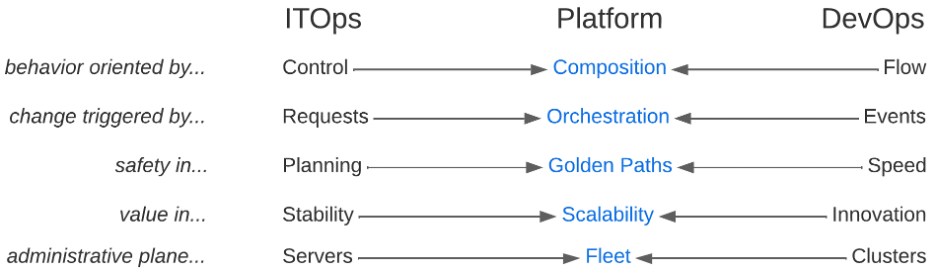
    Regardless of definition, platform engineering is the latest iteration of IT centralization, though now attempting to retain all the benefits of distributed team empowerment through “composition” rather than converged control. As modernization continues, we experience the ebb and flow of composition and decomposition, both organizationally and technically. Microservices, Kubernetes, and GitOps patterns pushed the rational limits of decomposition and significantly raised the level of technical complexity in the enterprise. The natural counter pressure is a new cycle of composition that aims to simplify that complexity through platform engineering practices. Teams now look for these toolchains and workflows to be centralized in internal developer platforms (aka IDPs), exposing the development, deployment and maintenance of the entire life cycle of modern, cloud-native applications.

    IDPs can facilitate the flow, speed and innovation DevOps teams are demanding without sacrificing stability, security and control. They enable developers to configure their toolchain while meeting all controls through approved blueprints or “golden paths,” reducing lead and process time. Developers can focus on delivering business value instead of infrastructure tasks.

    Bringing IT and DevOps Back Into Alignment Saves Time, Money and Sanity

    Platform engineering creates a collaborative framework that connects IT and DevOps teams, so they can focus on outcomes rather than methods. Developers can use an IDP to follow conventions that speed up development and prevent anti-pattern creep. Guardrailing choices through golden paths reduce cognitive load and simplify execution context for security teams. The result? Developers can focus on what they were hired for and want to do–creating innovative, transformative applications and differentiated value. Security can sleep well knowing bespoke behavior isn’t opening new attack surface areas.

    On the Day 2 operations side, IDPs enable SRE and support teams to have a fleet-wide view and work effectively with developers to streamline the management of production needs across all applications, clouds and tech stacks.

    The reframing of composition breaks the false dichotomies between IT and DevOps practices. You don’t have to choose between control and flow, change isn’t triggered by serial requests or async events, safety isn’t found in planning or speed, value isn’t found in stability or innovation and administrative plane primitives aren’t servers or clusters. Platform engineering practices allow you to prioritize composition, orchestration, golden paths, holistic scalability and fleet management to get teams out of entrenched myopia and embrace systems thinking that gets your business delivering strategic gain instead of tactical win/loss tallies.

    Finally, platform engineering positively impacts software delivery and operational performance metrics by streamlining development processes and reducing manual efforts. The bottom line is faster time to market while ensuring more consistency, less human error and improved software quality. This maximizes productivity, minimizes downtime and optimizes resource utilization, leading to cost advantages and increased efficiency for enterprises.

  • Is ChatGPT Helping or Hurting Your Developers’ Productivity?

    Is ChatGPT Helping or Hurting Your Developers’ Productivity?

    ChatGPT’s ability to translate natural language into working code has sparked tremendous interest in the programming community. Developers are exploring ways to use ChatGPT to reduce redundant tasks, from creating code snippets to analyzing and debugging programs. This also allows them to focus on more complex tasks like data analysis and monitoring with the help of a strong full-stack observability platform. Despite ChatGPT’s impressive capabilities, developers and their employers are split on whether the AI chatbot significantly boosts developer productivity.

    We will explore how to use ChatGPT to benefit your developers’ productivity and go over the advantages and disadvantages of ChatGPT to help you make the right decision for your business.

    How to use ChatGPT for Better Productivity

    ChatGPT has quickly become the most popular intelligence chatbot, with over a million user signups in its first five days and over 100 million in the first two months. Here are a few ways ChatGPT, developed by OpenAI, can help boost productivity in your organization.

    Improve Their Code
    Sometimes manually written code snippets consume additional CPU resources. Using ChatGPT, developers can optimize their functions for better performance. Additionally, ChatGPT can also write test cases and spot security vulnerabilities in their code, helping developers work faster.

    Simplify Documentation
    ChatGPT can give a simple explanation for the layman, avoiding technical jargon to a large extent. For instance, a developer at Twitter fed ChatGPT their code and it responded with a pretty detailed explanation. Using ChatGPT to generate the first draft of a company’s internal documentation would make knowledge transfers easier. New hires could quickly get up to speed on the company’s codebase. Further, ChatGPT could also be used for external-facing documents where other developers can learn how to use the company’s APIs and frameworks.

    Test and Understand Code
    ChatGPT can write automated tests for code that is fed into it. Although many developers consider testing boring and stressful—and sometimes a waste of time—it’s a critical step in ensuring that published applications are bug-free.

    With ChatGPT, developers can output reliable, well-tested code much more quickly and easily. ChatGPT can also give high-level and line-by-line explanations of code and even teach developers how to use external modules and APIs in their own code, helping them build much faster.

    Debug Code
    ChatGPT makes a great debugging tool for developers. It can take in error messages and output information on the likely cause of the error and how to fix it. This is typically a lot more time efficient than browsing forums and blogs for a solution.

    The tool can also suggest helpful code alternatives. Many developers claimed that ChatGPT can be much faster and less mentally challenging than the conventional approach of searching the web for a solution.

    As the CEO of Replit, Amjad Masad, put it, “ChatGPT could be a good debugging companion; it not only explains the bug but fixes it and explains the fix.”

    Code Comprehension
    ChatGPT’s terabytes of training data come from various sources, including common crawl and WebText2. This training data makes it easy for ChatGPT to simplify explanations of complex pieces of code for developers. Therefore, developers can save time deciphering any code’s underlying logic and structure.

    For instance, Stanford instructor and well-known developer Matt Harrison used ChatGPT to build a simple graphic design tool. He explained, “I’m using ChatGPT to create a GUI program for drawing lines. I haven’t used QT [a development framework] in years, yet I can throw this together really quickly.”

    Generate Documentation
    Writing code documentation is often considered a mundane task by developers. With ChatGPT, developers can significantly cut down on the amount of time needed for documentation. For instance, they can expedite the creation of troubleshooting guides, tool user manuals and test cases by asking ChatGPT to perform code analysis and generate detailed technical reports. Accelerating this documentation process allows for easier onboarding of new developers and faster product release times.

    Writing Tests
    ChatGPT can analyze code snippets and automate testing for them, saving developers lots of time and helping them output reliable code. Test coverage is an essential metric for most enterprises, and ChatGPT could help streamline the process.

    ChatGPT Disadvantages

    While many developers have praised ChatGPT for increasing developer productivity, others have criticized it as unreliable. Let’s understand some key areas where the tool falls behind.

    Outputting Buggy or Unusable Code
    Developers have complained that the chatbot would sometimes output plausible-looking code that doesn’t work. This might result from misunderstanding the user’s requirements or simply being unable to come up with a correct answer—then faking it.

    Programming Q&A forum Stack Overflow even issued a temporary ban on ChatGPT-generated answers. The ban was because the chatbot generated an influx of answers whose average accuracy was pretty low. ChatGPT sometimes uses nonexistent commands and outdated modules in its code, so while they theoretically might make sense, they don’t work in practice.

    Writing Outdated Code (and Forgetting Previously Written Code)
    Since ChatGPT’s training data cut off in September 2021, the chatbot has no knowledge of the recent developments in programming languages and modules after that. As a result, ChatGPT often needs to use outdated commands, modules and paradigms in its code.

    ChatGPT also occasionally forgets the context within which it is working, affecting code output. Some users have reported that ChatGPT sometimes forgets about the task at hand and begins generating incompatible code.

    Security Concerns
    Security concerns are the biggest drawback to having developers work with ChatGPT. Open AI uses the data users input into ChatGPT to train the underlying AI model.

    Research by cybersecurity firm Cyberhaven has shown that 11% of the data employees input into ChatGPT is confidential. This presents a significant risk, as such data can be used in the chatbot’s next responses. Corporations like JPMorgan and Verizon have even gone as far as to block employees’ access to ChatGPT because of these concerns.

    Lacks Problem-Solving Skills
    A developer’s job is to understand the business problem and develop customized solutions to address it. Although AI/ML tools like ChatGPT help developers code faster, they can’t help in problem-solving or implementing a software application.

    Furthermore, when developers become overly reliant on AI-generated code, they’re discouraged from upskilling on new programming frameworks and languages. This can hurt the organization in ways that might not be evident immediately.

    To ChatGPT or not to ChatGPT

    As Google’s head of developer experience Bret McGowen said, “While AI will transform software development in many ways, human judgment, intuition and creativity will remain essential to building great products.”

    While ChatGPT may not be a perfect solution for every aspect of software development, it can be a useful addition when combined with human problem-solving skills. However, companies should be careful while allowing the usage of AI in day-to-day processes. Guidelines educating in-house developers on the fair usage of AI are a must to protect sensitive information and maintain a high-quality control process.

  • How to Keep Your IT Infrastructure Invisible

    How to Keep Your IT Infrastructure Invisible

    IT infrastructure is critical. IT infrastructure enables businesses to run—from day-to-day operational execution to visionary strategic innovation and everything in between. What’s interesting, though, is that people are only aware of it when there’s a problem: HR can’t access the payroll application, customers are complaining about how slow the transactional system is or this month’s cloud bill was double what you expected it to be.

    No one should notice a well-orchestrated environment, but once application performance slows or an outage occurs, people start to grumble. The same is true for IT infrastructure.

    The Top Four Ways Your IT Infrastructure Can Become Undesirably Visible

    Given the complexity of modern hybrid/multi-cloud environments and the applications they support, it’s no surprise that countless things can go wrong—and when they do, your IT team takes the flack.

    If your infrastructure is humming along nicely, that’s a testament to the IT infrastructure team’s hard work and expertise. Sadly, they don’t get the recognition because it’s all invisible to the rest of the organization. It’s only when *BAM!* something happens that the team is scrutinized.

    While there are many ways this can manifest, it usually falls under one of the following four categories:

    • Availability — This may be the most catastrophic because when systems are unavailable, people can’t do whatever it is they need to do.
    • Performance — A system might be available, but that doesn’t mean it’s performing to SLA or user expectations. The result can range from minor annoyance to lost revenue and customer churn.
    • Cost — Runaway expenditures don’t necessarily affect users, but you do not want to be called to account by the finance team or, worse, executive leadership.
    • Compliance — This is another area that may not have a broad impact on user experience, but the repercussions of non-compliance can be financially and reputationally significant.

    Common Infrastructure Culprits and How to Address Them

    To ensure the necessary availability, performance, cost control and compliance to keep your IT infrastructure under the radar, you must understand what can cause problems in these areas. Here are eight common culprits, along with ways you can address them, so your IT team stays invisible.

    Broken or Misunderstood Dependencies
    Your infrastructure is a complex web of interdependent applications and services. Every time you make a change, it could have a rippling effect on the categories mentioned above. Automated discovery and service mapping capabilities enable you to easily trace dependencies throughout your infrastructure to avoid unintended consequences.

    Cloud Waste
    Chances are very high that you’ve got cloud waste. This means that you could be getting billed for a storage block that’s attached to a stopped instance, for compute instances that are not being used, or for unattached load balancers. Finding idle and abandoned resources can keep your monthly cloud bill under control and on budget.

    Un-Breakdownable Cloud Costs
    Cloud bills are notoriously complex, and while cloud providers do offer tools to help you analyze your cloud spend, those tools often don’t answer all the questions your business might have. In addition to adding clarity to such opaque expenses, you need to be able to parse your cloud spend based on what makes business sense to your organization, not what makes technical sense to your cloud provider.

    Poor Capacity Planning
    Your infrastructure needs to meet your business needs, which are continuously evolving. As changes happen, whether it’s increased utilization of existing resources or modified/added resources to support new requirements, workloads could push current capacity and impact performance and stability. You need to be able to forecast infrastructure demands against business objectives to minimize potential issues before they happen.

    Poor Workload Placement Decisions
    Your infrastructure consists of various environments each with its own characteristics. If you migrate a workload without understanding the implications of that particular environment, you could risk performance problems or spiking costs. To prevent this, you need any-to-any migration insights to make better decisions about workload priorities, groups and deployments.

    Poor Reservation Planning
    Reservations (i.e., reserved instances or programmatic discounts) offer discounts for committing to a particular plan. If you plan well, the savings can be significant. But if you don’t use the capacity you’ve bought, the savings might not materialize. To improve cloud resource planning, you need to be able to evaluate your potential savings in varied scenarios.

    Workload Drift
    Over time, your workloads evolve due to changing demand, data volumes, etc. As a result, they can outgrow their current configurations, leading to performance issues or rising costs. This is a natural result of business growth, so the goal isn’t to prevent that drift. Instead, you want to optimize capacity and cost on an ongoing basis to keep your workloads right-sized.

    Slow Problem Troubleshooting and Remediation
    No matter how many precautions you take, something somewhere will inevitably go wrong. And once you become aware of the situation, the clock starts ticking to find the cause and fix it, all of which takes time. The longer the entire process takes, the longer your infrastructure will be visibly and painfully not working as expected. For those cases, you need full-stack visibility with application-centric, AI-based analytics to minimize impact duration as much as possible.

    Keeping the engine running behind the curtain can be a daunting task, but with proper planning and management, your IT team will remain visible to those responsible for managing it and invisible to those in the rest of the organization. Of course, the complexity of today’s cloud infrastructure makes that challenging, and there will be IT fire drills that take place, but it’s about how IT leaders react to the situation and resolve it in the quickest way possible, allowing themselves to return to their preferred place in the shadows.

  • Threads: Twitter Killer or Ad-Infested Hellscape?

    Threads: Twitter Killer or Ad-Infested Hellscape?

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Meta launches its much-leaked Threads microblogging app. A spinoff from Instagram, it’s already reached 30 million signups at the time of writing—even before it’s available in the EU. But how is Meta’s DevOps team making it scale? (more…)

  • Five Great DevOps Job Opportunities

    Five Great DevOps Job Opportunities

    DevOps.com is now providing a weekly DevOps jobs report through which opportunities for DevOps professionals will be highlighted to better serve our audience.

    Our goal in these challenging economic times is to make it easier for DevOps professionals to advance their careers.

    Of course, the pool of available DevOps talent is still relatively constrained, so when one DevOps professional takes on a new role it tends to create an opportunity for others.

    The five job postings shared this week are selected based on the company looking to hire, the vertical industry segment and, naturally, the pay scale being offered.

    We’re also committed to providing additional insights into the state of the DevOps job market. In the meantime, for your consideration:

    LinkedIn

    DuckDuckGo
    Remote
    Senior DevOps Engineer
    $170,000

    CareerBuilder.com

    Credit Acceptance Corp.
    Remote
    Staff DevOps Engineer
    $145,000 to $150,000

    Indeed.com

    NASDAQ
    New York, New York
    DevOps Engineer
    $104,400 to $174,000

    SimplyHired

    U.S. Bitcoin
    Remote
    Software DevOps Engineer
    $100,000 to $130,000

    Dice.com

    ITBMS
    Remote
    DevOps OpenShift Engineer
    $80,000 to $100,000

  • How Platform Engineering Protects Profit, People and our Planet

    How Platform Engineering Protects Profit, People and our Planet

    Platform engineering is emerging as a way of evolving DevOps, with 94% of respondents to the recent State of DevOps report agreeing that the practice helps their organization to reap the benefits of DevOps. The business arguments for platform engineering are clear: In that same report, respondents stated that platform engineering improves efficiency (59%), speeds up delivery time (58%) and improves workflow and process standards (57%).

    But in addition to the huge benefits organizations are now realizing in terms of business value, platform engineering is also pretty crucial for a business’s long-term viability. And by that, I mean that platform engineering can be inherently sustainable.

    How Can Platform Engineering Be Sustainable?

    First, it’s important to note that ‘sustainability’ here doesn’t just mean ‘green.’ Rather, sustainability means that an organization is able to meet the needs of the present without compromising the ability of future generations to meet their needs, too. These are needs that come in three different varieties: People, planet and profits.

    This means that to be truly sustainable, platform engineering needs to deliver lasting and stable returns on things like return on investment year-over-year, improved awareness of and reduction in an organization’s carbon footprint and better governance and optimization through monitoring and analytics.

    Any approach which supports business growth while simultaneously empowering employees and being kind to the planet is the dream for pretty much every organization. But how exactly can departments and wider organizations unlock all of these benefits? The answer is: There’s no magic bullet.

    Sustainable platform engineering is about treating your platform as an iterative cycle: It isn’t the actual creation of the tool that matters, as much as it is the maintenance, upkeep and usability of the platform as your business moves forward. This, naturally, will take time, effort and money—all of which, it’s safe to say in the current climate, are in short supply. But it is crucial that businesses act strategically, looking for areas for improvement and paths that will all add up to a more sustainable business in the long term.

    The Three Paths to Success

    These paths can be divided into three main areas of focus, and the first is GitOps or infrastructure-as-code (IaC).

    A tweak that every organization should start making is using Git as a single source of truth for deployments, enabling developers to work faster by empowering them to use their own code without hands-on involvement from ops teams. This could be combined with optimized infrastructure, moving toward IaC to enable faster and more efficient deployments.

    These principles form the foundation of sustainable platform engineering as they protect profits, allowing the business to keep moving forward and investing in the other areas crucial for a sustainable operation. Combining IaC with GitOps ensures speed and simplicity while maintaining a high-quality end product.

    Creating an optimized infrastructure is important, but just as important is empowering employees to feel good about the work that they are doing. That’s why implementing a self-service tool alongside an optimized UX is the second area of focus. This removes the pressure on those in the tech department to be infrastructure experts while erasing the need for endless tickets to be raised for issues.

    By freeing up DevOps engineers and platform experts to spend more time doing what organizations need them to do, businesses can keep innovating to maintain an edge over their competitors. Self-service capabilities combined with an accessible UX are a useful combination for a much-improved developer experience (DevX).

    Finally, it’s important to keep in mind that self-service isn’t just going to benefit end-users; it also has major upsides for improved governance, as well as keeping control of cloud spending and carbon footprint impact. Optimizing and iterating your platform engineering tool means that a business can keep up with the fast pace of the global tech market while also continuing to implement the latest tweaks and upgrades. It all adds up and builds on the organization’s platform engineering solution.

    Reaping the Rewards of Sustainability

    If an organization follows the above three paths, it is well on its way to a more sustainable business powered by platform engineering. By focusing on targeted, achievable projects to build a solid foundation, organizations can achieve big benefits for people, the planet and profit.

    From an economic perspective, sustainable platform engineering ensures legacy infrastructure is modernized, silos are broken down and production is accelerated, all ensuring the business doesn’t risk lagging behind competitors. A stable and secure return on investment is key to sustainability in the medium to long term, and sustainable platform engineering ensures a business is able to weather future challenges and keep a healthy profit margin.

    As we all know, underpinning any great business is the people who work there. Techs get stressed by having to interact with infrastructure they know nothing about, DevOps and specialists get stressed when those techs desperately raise tickets in an attempt to get help, and platform engineers get stressed when the weight of providing a solution to these problems rests squarely on their shoulders. Implementing a UX-strong self-service portal relieves the pressure, allowing employees to focus on delivering real value to the business through innovation. A better DevX ultimately leads to better business outcomes.

    And, of course, it’s ultimately no good having a successful business if the planet we all share continues to suffer from the effects of the climate emergency. Just like a business that hemorrhages money is unsustainable, so is a planet that wastes its finite resources. By getting control of cloud usage and controlling cloud climate impact, businesses will not only be empowering their people and improving their bottom line, but they will also be making a tangible difference to our shared environment, supporting our planet as it recovers from years of climate neglect.

    Platform engineering offers lots of tangible benefits for businesses, but sustainable platform engineering can be even better, not just for a business, but employees and our shared environment. It might just be time to upgrade DevOps and start thinking about building a sustainable organization that supports profit, people and the planet.


  • How Can DevOps Evolve? Platform Engineering

    How Can DevOps Evolve? Platform Engineering

    Kaylee Van De Voorde co-authored this article.

    Has your team adopted a DevOps mindset? Are your engineers using tools like Docker containers, Kubernetes and Terraform? Over the last decade, many engineering teams that adopted DevOps culture and pivoted to cloud-native applications that required rapid scaling may face a new set of problems. 

    DevOps

    DevOps practices have brought operations and software engineering teams together throughout the entire development life cycle, from initial concept through the engineering process to production support. This collaboration paved the way for iterative development: Improving velocity, providing rapid feedback and consequently improving application quality by uncovering bugs and environment requirements earlier without user impact. DevOps automation created a more “blameless” culture that improved trust, collaboration and innovation, which boosted team morale and increased engagement. 

    That said, DevOps teams have encountered many obstacles, including fears of job obsolescence and steep learning curves for every member. Teams that learned how to implement DevOps practices on their projects may have moved more slowly at first while learning how to work together in new ways and adopting new tools.

    What is Platform Engineering?

    So, what is platform engineering? Platform engineering bridges the existing gaps between software, hardware and infrastructure that come with adopting DevOps practices: Automated horizontal scaling, service discovery and cost optimization. Platform engineering makes it even easier and simpler for engineers produce high quality applications quickly by standardizing CI/CD deployments, ensuring that infrastructure is auditable and monitored, automating deployment methods and processes, providing accurate documentation and incorporating FinOps.

    Platform engineering teams can make these improvements available to their teams by creating tools such as an internal developer platform (IDP) that includes APIs that expose internal tools and features within the platform. 

    The Next Evolution

    Evolution does not mean starting from nothing.

    The core tenets of DevOps practices still hold their value; aligning software engineering and operations teams to better create applications that embody business and user functionality and run smoothly within an incorporated infrastructure, automation, security and dedicated site reliability engineering (SRE). Many DevOps teams may already be moving toward an overarching platform engineering culture and simply need to refine their standards. Distinct application teams may already be building similar features to provide platform functionality; a strong indication that a platform engineering team would be beneficial.

    Choosing to create a dedicated platform engineering team has tradeoffs: Building a platform engineering team pulls resources from building applications and new features that the business needs, but application teams could experience an increase in productivity if a separate platform engineering team is created. A dedicated platform engineering team can also provide clear, unified direction and nuanced goals for application teams; this is incredibly important when creating standards and internal tools.

    A platform engineering team is just one way that to advance and improve engineering culture. DevOps teams that may not require platform engineering can continue their growth by refining their existing practices and patterns in their everyday work.