Category: DevOps in the Cloud

  • FinOps Cloud Cost Optimization via Governance-as-Code 

    FinOps Cloud Cost Optimization via Governance-as-Code 

    Cloud implementations continue to grow in scope and complexity. Too often, this expansion also means costs keep spiraling out of control. In this article, we’ll examine why the emerging practice of cloud financial management (FinOps) is so essential to containing costs in the cloud. We’ll then discuss the challenges teams encounter as they start to apply FinOps approaches. Finally, we’ll reveal the opportunity presented by employing governance-as-code to establish continuous cloud cost optimization—and how this approach makes it practical for teams to put the theory of FinOps into practice so they can keep cloud costs in check.

    The Emergence of FinOps

    For many organizations, there’s been a race to leverage cloud services, with teams seeking to realize advantages in flexibility, agility and efficiency. Within an organization, it’s not only a matter of more workloads running in the cloud, it’s a matter of more distinct deployment models being used, more teams using cloud services and leveraging multiple service providers.

    In the process, teams have had to contend with rapid growth in the size and diversity of the implementations that have to be managed—and paid for. It is this latter aspect that has been a rude awakening to those responsible for managing budgets. Left unchecked, this growth in cloud use has led to spiraling costs and predicting, managing and controlling these costs only grows more difficult as deployments get more complex and more frequent.

    This need for improved cost management has given rise to a new discipline: Cloud financial management; or FinOps. In short, FinOps is a way of bringing financial discipline and accountability to the variable-cost paradigm found in the cloud. FinOps brings together a combination of technologies, processes and teams, including professionals from technology, finance and business. By gaining an improved ability to understand, track and manage cloud costs, teams can begin to maximize the value realized through their cloud expenditures. Given the strategic and urgent nature of cloud cost management, it’s not surprising that FinOps teams are growing. According to research conducted by the FinOps Foundation, FinOps teams expanded 47% over last year, and these professionals are expecting their teams to grow 75% in the next year.

    Challenges in Establishing FinOps

    While there’s a lot of promise behind the establishment of FinOps practices, there are also many obstacles standing in the way for teams. When the FinOps Foundation queried respondents about top challenges, these were the top five responses:

    • Getting engineers to take action (39%)
    • Dealing with shared costs (33%)
    • Accurate forecasting (26%)
    • Reducing waste or unused resources (25%)
    • Full allocation of costs (23%)

    Lacking comprehensive control and visibility over multi-cloud environments means these teams can’t proactively manage costs—and too often find out about wasted expenditures and high costs of underutilized resources after the fact. Because stretched teams are reliant upon manual follow-ups and tactics, it is difficult to get engineers to respond as quickly and effectively as needed.

    Compounding these challenges is the fact that across teams, different tools and processes are used. For example, different development teams might be using different provider services along with varying deployment tools, such as AWS Cloud Formation, HashiCorp Terraform, Kubernetes and so on. This inconsistency introduces inefficiencies and miscommunication and stifles team productivity.

    While the cloud offers a range of benefits compared to legacy, on-premises infrastructure, without proper governance, cloud costs can quickly spiral out of control. In fact, Gartner analysts report that in the next few years, 60% of organizations will encounter cost overruns in public clouds.

    Rethinking Cost Management

    For all the reasons articulated above, teams are being asked to take a new approach to cloud cost management, one that aligns with the principles of FinOps. For many, this means embracing the concept of governance-as-code to optimize cloud costs. Cloud governance-as-code represents a way to automatically and dynamically apply policies, including for cost optimization, in fast-changing cloud environments.

    With governance-as-code approaches, policies are defined using a standard language. Code associated with cost policies is created, deployed and maintained in much the same way developers manage application or infrastructure code. Developers don’t have to worry about tracking or managing costs. Cost policies are continuously evaluated against current state, utilization and configuration of cloud infrastructure. If any violations occur, automated notifications and workflows can be triggered. Here are the key requirements for using governance-as-code to establish continuous cloud cost optimization:

    Cost Policies are Defined via an Intuitive Language

    Traditionally, development, operations and financial groups worked in silos. Each team had its own tools, workflows and policies, and even fundamental terminology could vary substantially.

    To maximize the potential of continuous cloud cost optimization via governance-as-code, solutions need to enable teams to define, manage and revise policies using an easy-to-understand, consistent language. This makes it much easier for different teams to collaborate and gain alignment on key cost management policies and best practices.

    Finally, to be effective in establishing continuous cloud cost optimization, governance-as-code offerings need to employ a language that is independent of any specific programming languages that application developers may use. Further, these languages should be applicable to the broadest set of applications, cloud services, development tools and so on. This is vital to ensure that development teams retain maximum flexibility in the tools and services they can use.

    Cost Policies are Managed and Deployed via Git Within CI/CD Workflows

    Once policies are reviewed and finalized, teams must be able to apply these policies within the development organization’s existing continuous integration/continuous delivery (CI/CD) workflows.

    Through robust governance-as-code approaches, teams can create cost policies as code artifacts and deploy them via open source version control systems like Git. Through this approach, teams can apply policies in a manner consistent with their software development and delivery life cycles.

    By codifying cost governance in this way, cost controls can be deployed via Git within a CI/CD pipeline. This approach enables teams to avoid complex manual processes associated with tasks like managing tickets, requesting changes and so on. This also helps teams keep up with the accelerating pace of today’s dynamic cloud and development environments. Further, this approach means governance code can be traced through various state changes, rolled back if needed and so on, just like application code.

    Cost Policy Violations are Detected and Addressed in Real-Time

    Through continuous cloud cost optimization via governance-as-code, teams are  empowered to institute not only continuous detection but also immediate action. Policies can be employed at regularly scheduled intervals or they can be triggered based on certain events.  This approach enables enforcement of workflows and actions that may be required. If policy violations occur, notifications to relevant teams or team members can happen automatically and advanced workflows can be triggered. For example, a policy could identify RDS instances greater than 30 days old that have had no connections in the last 14 days. It would then notify the owners of these instances. If they don’t take action in seven days, the instances could automatically be stopped.

    Cost Policy is Continuously Enforced and Refined

    Continuous cloud cost governance-as-code has a never-ending life cycle, just like the team’s software development life cycle. Cost governance code is built, deployed, tested and released, and the process continues as new policies are developed and refined over time. As requirements change, teams need to be able to periodically analyze cost data and update policies as needed.

    As organizations continue to invest larger sums in their cloud implementations, the need to establish strong FinOps capabilities will only grow more critical. However, as these cloud deployments continue to grow more complex, it can get increasingly difficult to realize the promise of FinOps. For these reasons, employing governance-as-code to establish continuous cost management is emerging as a key approach. With this approach, teams can achieve sustained compliance and minimize waste.

  • HashiCorp Previews Updates to Consul Service Mesh

    HashiCorp Previews Updates to Consul Service Mesh

    During an online HashiConf Global conference, HashiCorp today made available a beta of an update to its open source Consul service mesh for virtual machines and Kubernetes clusters that makes it possible for multiple administrators to share the same instance of a multitenant service mesh.

    Version 1.11 of Consul will also add support for a command line interface (CLI) for Kubernetes that will provide an alternative to Helm charts for installing Consul on those clusters.

    Raymond Austin, director of product marketing for HashiCorp, said it’s become apparent that there is a need for a higher level of abstraction for managing application programming interfaces (APIs) that is easy to deploy across both legacy IT environments based on virtual machines and cloud-native environments based on Kubernetes clusters.

    Of course, in many cases, those Kubernetes clusters are deployed on top of virtual machines. However, there are also now more instances of Kubernetes being deployed on bare metal platforms at, for example, the network edge.

    As IT environments become more complex, a service mesh makes it simpler to discover, access and secure APIs that are now rapidly proliferating across the enterprise. That transition requires a more dynamic approach to not only managing APIs but also the network services those APIs depend on, added Austin.

    HashiCorp is betting that many IT organizations will prefer to rely on a lightweight open source platform supported by a single vendor rather than relying on more complex open source service mesh offerings being developed under the auspices of a consortium.

    It’s still not quite clear who within an IT organization is assuming responsibility for deploying a service mesh. Most often, it’s a development team that makes the initial decision. However, as IT operations teams become more aware that service meshes represent a capability that needs to be horizontally made available across multiple applications, it may be only a matter of time before some organizations decide to standardize on a single service mesh to reduce operational overhead, noted Austin.

    Service meshes will also play a critical role in simplifying management of networking and security services at a higher level of abstraction within a larger DevOps workflow.

    It’s still early days as far as service mesh adoption in the enterprise is concerned, but there are already a large number of service mesh options. In fact, there may never be a single dominant service mesh platform. Interoperability standards still need to be ratified that enable organizations that have standardized on different service meshes to apply policies to microservices spanning hybrid cloud computing environments.

    Of course, not every IT organization requires a service mesh yet, either. Many IT teams can still get by using a traditional proxy server or an API gateway until the number of microservices-based applications deployed starts to achieve critical mass. One way or another, however, the more APIs there are to manage, the more inevitable it becomes that an IT team will deploy a service mesh.

  • Pulumi Adds Registry to Share Secure IaC Code

    Pulumi Adds Registry to Share Secure IaC Code

    Pulumi this week added a public registry to its portfolio that makes it easier to discover packages that have been created using its tools to manage infrastructure-as-code (IaC).

    Joe Duffy, Pulumi CEO, said the Pulumi Registry will make it simpler for DevOps teams to share and reuse IaC tools that have been vetted versus always requiring each development team to write new code each time they want to programmatically provision infrastructure. Pulumi Packages provide modern cloud reference architectures in the form of software development kits (SDKs), code samples and how-to guides.

    One of the primary reasons that security has become a major cloud issue is that developers often misconfigure infrastructure. The registry provides a way to reduce those configuration errors by making it easier for developers to reuse code written in TypeScript/JavaScript, Python, Go and .NET that they have stored in repositories such as npm.

    In addition to the major cloud service providers, there are also Pulumi Provider Packages for Auth0, CloudFlare, Confluent Cloud, Datadog, DigitalOcean, Docker, GitHub, Kong, MinIO, MongoDB Atlas, PagerDuty, Snowflake, Spot by NetApp and others.

    There are also Pulumi Component Packages for deploying container applications on instances of Kubernetes and other related platforms in addition to deploying applications on serverless computing frameworks.

    Duffy said in addition to providing a “golden image” of their configurations the registry reduces the overall level of friction that often exists between developers, IT operations teams and cybersecurity professionals.

    The latest Pulumi offering is part of an ongoing effort to democratize cloud computing in a way that is repeatable and reliable, noted Duffy. Pulumi, for example, just added support for a set of AWS Cloud Control application programming interfaces (APIs) that reduce the number of APIs that developers would otherwise have to master. The more APIs there are, the more likely it is a developer will make a mistake.

    IT teams should expect that other cloud service providers will similarly streamline the APIs they present developers as part of an effort to make their services both more accessible and secure. In the meantime, frameworks provided by Pulumi provide a means to invoke those lower-level APIs at a higher level of abstraction for both developers and internal IT operations teams alike.

    It’s not clear today how many developers routinely employ IaC tools, but as the number of workloads deployed in the cloud steadily increases, so too does the percentage of developers that employ these tools. While that shift represents a major boon in productivity for developers, it brings with it additional security risks that many organizations fail to appreciate until it’s too late.

    The only way to really solve that issue is for organizations to adopt DevSecOps best practices that require a level of collaboration between DevOps and security teams that is still relatively rare. However, as the tooling provided continues to improve, the technical challenges associated with achieving that goal continue to decline. The next big issue, as always, is bringing together all the diverse cultures within an IT organization to actually implement those tools and define a set of best practices that work for all concerned.

  • Why Distributed Cloud Is the Future of Cloud Computing

    Why Distributed Cloud Is the Future of Cloud Computing

    A distributed cloud is a public cloud service that allows you to run public cloud infrastructure in multiple physical locations while being centrally managed for performance and compliance. The most innovative companies are moving all their assets to a distributed cloud structure. It is safe to say that distributed cloud is the future of cloud computing.

    Lou Senko, senior vice president of IT and chief availability officer at Q2, will be speaking about distributed cloud, how it can benefit your business and why it is the next generation of cloud computing at DevOps Experience: The Roaring 2020s Virtual Summit, on Oct. 28 at 9:45 a.m. ET. Lou will explain how distributed cloud makes the most of multiple channels and how this emerging strategy can enhance your digital posture.

    During a quick interview with Lou, he explained some of the main benefits and advantages of distributed cloud and shared a sneak peek of his upcoming session. Check out the interview below to find out what to expect at DevOps Experience 2021.

    This year’s DevOps Experience will focus on DevOps and the use of the cloud to enable digital transformation. The two-day event, starting on Oct. 27, will bring together DevOps and cybersecurity luminaries from around the globe for a free, interactive learning experience.

    The agenda for the two-day virtual event features a mix of topics, including technical sessions, deep-dives and case studies covering digital transformation, DevSecOps, cloud-native, Kubernetes, AppSec, CI/CD, open source, value stream management and more. The virtual environment features more than 50 sessions by industry leaders and an expo hall lined with booths full of downloadable resources.

    To check out the full agenda and to register, please visit the DevOps Experience website.

  • Trust in Cloud Providers is a Developer Issue

    Trust in Cloud Providers is a Developer Issue

    Earlier this summer, we worked with ClearPath Strategies to ask developers about the level of trust they have in their various cloud service providers. What we learned spoke volumes: While developers’ familiarity and comfort with Amazon, Microsoft and Google position these well-known cloud providers as market frontrunners, developers often do not agree with the companies’ values.

    The research project gathered insights from more than 800 developers at small and mid-sized businesses, those with less than 500 full-time employees, across a wide variety of industries and geographies worldwide. You can download the summary report here (no signup required).

    In ClearPath Strategies’ report, senior analyst Stephanie Fairchild said that “approximately 20% of developers believe that the big three hyperscalers will engage in behaviors that include leveraging their brands to stifle competition, focusing on shareholders more than customer needs, hosting or working with customers that developers find morally objectionable, monetizing user data for their own use and locking them in with proprietary tools. Criteria such as security and performance clearly take priority over these trust issues for developers, but it’s interesting to note that a sizable portion of developers are thinking about how their values align with those of their service providers.”

    • Trust plays an important role in developers’ choice of a cloud hosting provider, but needs take precedence; when prioritizing needs or values, developers report they prioritize needs over their values 73% of the time.
    • The top three reasons cited for developers’ preference of their chosen third-party cloud provider: Security, trust and quality of service.
    • Survey respondents indicated that both hyperscale and alternative cloud providers deliver equally effective performance and security.

    The report cited three top criteria for choosing a third-party cloud provider: Security, trust and quality of service. Survey respondents felt that hyperscale and alternative cloud providers deliver equally effective performance and security. Interestingly, although 73% of respondents said they prioritize needs over values when making a purchasing decision, approximately 20% said they don’t trust the big three providers (AWS, GCP and Azure) in what could be considered key moral areas.

    It’s no secret that the extensive functionality and brand awareness of hyperscalers make them popular choices for developers, but an alternative cloud provider like Linode, DigitalOcean, OVHcloud or Hetzner can be a more trustworthy partner for innovative upstarts—one that likely offers better pricing and doesn’t threaten or compete with their business. And when an alternative cloud provider meets a developer’s functional needs—which is nearly always the case—developers can have the best of both worlds: A provider they can trust to meet their needs and one that shares their values. 


    To hear more about cloud-native topics, join the Cloud Native Computing Foundation and the cloud-native community at KubeCon+CloudNativeCon North America 2021 – October 11-15, 2021

  • Energy Efficiency and the Data Center

    Energy Efficiency and the Data Center

    The IT industry has historically been a leader in the ongoing race to reduce CO2 emissions. Reducing emissions is good for the environment and for the corporate bottom line. The data center is well-known as a voracious data consumer. But the data center consumption findings keep pace with the trend. Even in the face of remarkable growth in data center capacity and performance, their energy consumption has increased only a few percentage points since the 2010s. This almost-flat rate of energy consumption is primarily the result of the shift to cloud computing as well as the shift to solar and wind energy, where it makes sense.

    Investments in renewable energy sources have helped tamp down criticism over the overall IT carbon footprint. Knowing that it takes a tremendous amount of energy to power a data center, owners and operators are always looking for ways to improve efficiency and reduce carbon expenditure. Today, there are newer and better ways for organizations to deliver the performance to properly power modern applications while keeping in mind the energy efficiency and carbon reduction the world requires.

    Minimizing Energy Use and CO2 Production

    How did we get here? Decades of semiconductor process miniaturization in concurrence with living out Moore’s Law has culminated in ongoing improvements in performance, storage capacity and device density. Today’s mobile phones are a great example of that ongoing progress. A secondary factor in the mobile phone revolution is a processor architecture optimized for efficiency and flexibility. This ARM architecture has been used to power almost all devices since the first iPhone. Over the years, ARM has also become a realistic platform for servers; often a better choice than an x86 system.

    Energy efficiency is one area where ARM systems win out over conventional server architecture. But it was not until recently that ARM processors could deliver the required performance for the data center. Today’s systems, based on Armv8 designs, have brought into play x86-class capabilities in a more energy-efficient way. The advent of the ARM-based AWS Graviton processors, which by some estimates have already captured 20% of the instance share on AWS, demonstrates that ARM can run production workloads while delivering what AWS calls “up to 40% better price performance over comparable current-generation x86-based instances for a wide variety of workloads.”

    To illustrate the impact on carbon production when a data center shifts from x86-based architecture to ARM servers, an analysis of the top elements contributing to data center energy use was undertaken. The energy savings was calculated and translated to reduced CO2 emissions based on the fuel mix used to power the electric grid in various locations. The results prove that an ARM-powered data center reduces CO2 production by 74%, equivalent to almost half a million barrels of oil.

    Power Consumption Reduced by Efficient Servers

    The premise is simple—innovative server design significantly reduces data center energy use. In this model, a server’s power draw and physical size are key factors. The energy needed for other data center subsystems was extrapolated by using ratios derived from experience and validated by estimates from other data center operators.

    Data center energy use can be divided into five categories of equipment and infrastructure: Servers, network communications, power supplies, conversion and UPS, cooling systems and storage. Servers and cooling comprise about 75% of the total.
    The calculations were based on the energy used by a medium-sized data center with 750 racks of conventional 1U servers (42 servers/rack; around 31,500 in total). Assumptions used included servers comprising two-thirds of the floor space and that the equipment space accounts for 65% of the total, translating to a 62,000 square-foot data center. For comparison, facilities operated by the major cloud vendors can be a million square feet or more. Knowing server power consumption and the ratios for the equipment categories, algebra can be used to calculate the energy consumption for each.

    The data center in this hypothetical example has, as we said, 31,500 servers. Using the 912.5W power draw of a Dell R640 as typical of 1U x86 servers, the total server usage in the ARM data center would be 251,795 MWh/year. Using this formula, the amount of energy saved by using ARM servers can be calculated. Each server requires about one-quarter the electricity of a standard server. In the formula, the assumption is that the ARM server installation would require half the equipment racks (375 instead of 750) and 52% of the power-per-system, comprising a data center using only 26% as much electricity (152,409 MWh/year) as one based on x86 systems.

    The math shows that switching one medium-sized data center to ARM servers can produce annual savings equivalent to 45,459 fewer cars on the road or 486,749 fewer barrels of oil used.

    The value in CO2 reduction is widely understood for preserving the environment. It is also advantageous from an economic standpoint. In fact, there are many technical and economic reasons to adopt energy-efficient ARM-powered servers in the next-generation cloud data center.


    To hear more about cloud-native topics, join the Cloud Native Computing Foundation and the cloud-native community at KubeCon+CloudNativeCon North America 2021 – October 11-15, 2021

  • What Does the Future of DevOps Look Like?

    What Does the Future of DevOps Look Like?

    During the past couple of years, we have seen a rapid acceleration of digital transformation. Many businesses have been leveraging the benefits of DevOps and the cloud to accelerate their digital transformation journeys. With so many changes going on in the industry, it is time to take a look ahead at what DevOps is becoming and how DevOps teams are managing change across the lifecycle.

    On October 27, DeployHub CEO and CDF Board Member Tracy Ragan will discuss the future of DevOps and the convergence of GitOps, event-based continuous delivery and the coming use of microservice catalogs at DevOps Experience: The Roaring 2020s Virtual Summit, during her session “Tomorrow’s DevOps Pipeline — A Radical Shift.”

    We sat down with Tracy Ragan to talk about some of the challenges that the DevOps community has been facing, how to overcome these challenges and how the role of DevOps is changing. Watch the interview below to take a sneak peek of her upcoming session at DevOps Experience.

    This year’s DevOps Experience explores how DevOps and the cloud are reinventing the path of digital transformation. The agenda for the two-day virtual event features a mix of topics, including technical sessions, deep-dives and case studies covering digital transformation, DevSecOps, cloud-native, Kubernetes, AppSec, CI/CD, open source, value stream management and more. The virtual environment features more than 50 sessions by industry leaders and an expo hall lined with booths full of downloadable resources.

    To see the full agenda and to register, please visit the DevOps Experience website.

  • The Inevitability of Multi-Cloud-Native Apps

    The Inevitability of Multi-Cloud-Native Apps

    We all know the story: Enterprises moved to the cloud. They learned about data center virtualization and multi-tenancy and self-service developer provisioning. Along came Kubernetes, and they moved to cloud-native, where they learned about automation, DevOps and infrastructure-as-code (IaC). Now, even though most enterprises are still figuring out how to do cloud-native at scale, there’s a new imperative they must master: Multi-cloud-native applications. And for almost every enterprise with a global footprint, the move to multi-cloud-native applications is not optional—it’s inevitable. 

    But before we explore why this is the case, let’s first retrace our steps. For almost every enterprise out there, the journey to the cloud started with adopting a public or private self-service infrastructure provisioning and management model. These enterprises quickly realized that this new IT model required a new set of tools to solve challenges they’d never before faced—enabling their developers with self-service provisioning, managing and operating infrastructure. Enterprises figured it out, but as soon as they figured out the cloud, they quickly had to gear up for the second phase: Automating and operationalizing an enterprise-wide rollout of cloud operating models throughout their entire developer organization. 

    Of course, this phase has its own set of challenges, and a rich ecosystem of tools emerged to address them. Even so, we all can agree that the majority of mainstream enterprises are still in this second phase. They’ve adopted cloud, they’ve expanded its use, and they’re grappling with the challenges around multi-tenancy, security, DevSecOps and governance. Hand-in-hand with this goes a whole new set of challenges around cost management. Suddenly, enterprises are faced with managing the variable costs of public cloud infrastructure: Optimizing compute infrastructure, utilization and capacity to rein in cloud spend. It’s an issue Sarah Wang and Martin Cassado took head-on in their research on the Trillion-Dollar Paradox.

    So, enterprises moved to the cloud and are now, for the most part, successfully grappling with scaling it. But nothing stays the same for long, and businesses drive IT to innovate. This is where cloud-native entered the picture to help enterprise software development teams become more agile and help businesses transform to deliver new services and experiences faster. In fact, the consumer experience this model makes possible has rapidly become the norm.

    Consistently delivering rapid software iteration across a global footprint forces DevOps organizations to grapple with an entirely new set of technical challenges: Leveraging containerized applications and microservices architectures in production across multiple Kubernetes clusters running in multiple geographies. Customers want an on-demand experience. This third phase is what we call multi-cloud-native, and it was pioneered by hyperscale IaaS players like Google, AWS, Azure and Tencent.

    The reality is, of course, that hyperscalers aren’t the only ones who have figured out how to deliver multi-cloud-native apps. Webscale innovators like Doordash, Uber, Twitter and Netflix have done it, too. To get there, they had to make and share their multi-cloud-native apps across every geography where their customers live. And, in turn, to make that happen they had to tackle a new set of challenges: Develop new tools and techniques like geographically distributed, planet-scale databases and analytics engines, application architectures that run apps on the backend close to the consumer in a multi-cloud-native way. This enabled them to do arbitrage across fleets of infrastructure capacity across regions, all while giving their customers that instant experience they increasingly grew to expect.

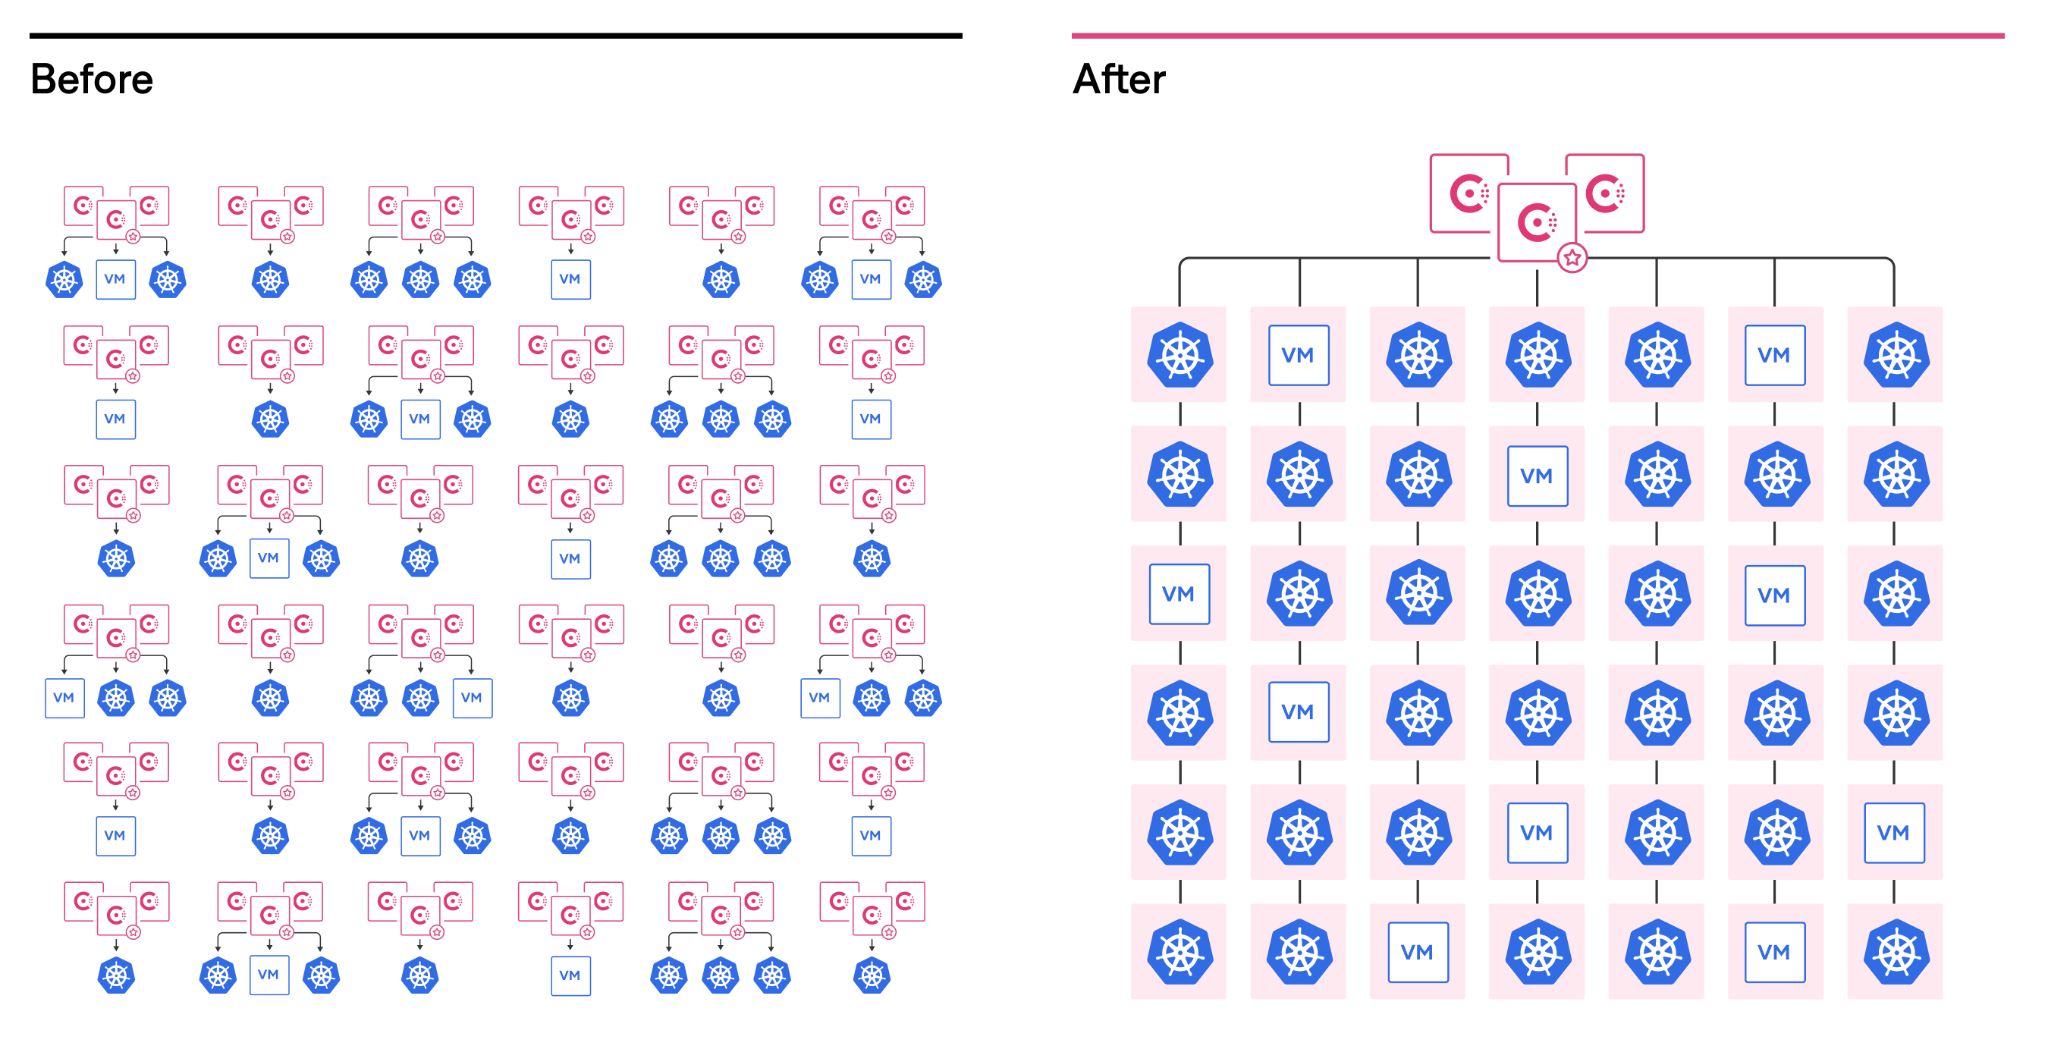
    What enterprises must realize is that this experience consumers have grown to expect from webscalers is rapidly becoming the same experience they expect when accessing their bank account, their insurance apps and their tax records. For almost every planet-scale enterprise, this sets up a whole new set of challenges: To span multiple clouds and multiple geographies running multiple Kubernetes clusters, you now must worry about new ways to do autoscaling, self-healing, disaster recovery, operations management and cost optimization—all of which are things that you’re just now getting figured out for virtual machines (VMs) and clusters in single regions.

    Enterprises must face the reality that cloud-native application models are not the destination but rather a waypoint on a journey to becoming multi-cloud-native. Because the consumer experiences delivered by webscalers make this the inevitable destination.

    The Enterprise Journey: Cloud, Cloud-Native and Multi-Cloud-Native

    Don’t take my word for it.

    Uber and Twitter public disclosures describe how the multi-cloud-native model is an integral part of their strategic game plan. Hybrid and multi-cloud are part of this, too, leveraging Kubernetes as a cluster manager, but they still need tools to manage all those clusters across multiple environments in multiple regions at planet scale.

    The bottom line is that the architecture that webscale companies are using today is the same one enterprises will need to adopt tomorrow to remain competitive. Alternatively, these enterprises will cede market share and relevance to the next webscale innovator to disrupt an industry. In adopting this model of building multi-cloud-native apps, enterprises will have to deal with unified access management, controlling multiple clusters, resource management and more, all across multiple regions and clusters of capacity, aggregating versus disaggregating cluster resources, using logical services that span clouds versus namespaces that span a single cluster.

    The Enterprise Solution: Planet-Scale Cluster Manager

    They will need a planet-scale cluster manager to do this; something that can observe costs, operations, performance and SLAs across clusters, across public and private clouds, spanning VMs and Kubernetes through a single pane of glass so they can operate above the clouds in an automated, easy-to-use way. Band-aid solutions like running multiple spreadsheet models to figure out how to optimize are not scalable. What’s needed are tools like machine learning to automate and optimize at scale, bin packing technology to intelligently and automatically optimize across a planet-scale infrastructure fleet and high levels of automation either with humans in or out of the loop. That’s how hyperscalers and webscalers are already doing it.

    Every planet-scale enterprise is multi-cloud-native, running data-driven apps. It’s not a fiction: It’s already happening across webscale companies, not just hyperscalers. Multi-cloud-native is the path that every enterprise is going to need to follow if they want to transform themselves to compete with the next webscale upstart. The good news is, the pioneers have left us a map to follow.


    To hear more about cloud-native topics, join the Cloud Native Computing Foundation and the cloud-native community at KubeCon+CloudNativeCon North America 2021 – October 11-15, 2021

  • Closing the Education Gap for IoT Developers

    Closing the Education Gap for IoT Developers

    The most common thing I hear from developers who are building internet of things (IoT) solutions is: It isn’t easy. And it’s not. Not because of a lack of skill—the developers I interact with are incredibly talented. There’s also no shortage of technologies to choose from for deploying an IoT solution. The challenge often comes down to a gap in available educational materials and learning support when in the development phase.

    We’ve moved from the early stages of the IoT when there was a lot of talk but not a lot of application. Now, we’re coming into the “reality phase” where cheaper, large-scale IoT solutions are feasible. In this phase, developers are tasked with identifying, building and deploying technologies that they’re likely having to figure out as they go. It’s a tall order to expect today’s developers to know the ins and outs of all of the moving pieces required for an IoT solution, including the wireless technologies that help to enable them. 

    While developers are renowned for being effective at independent learning, they still need better access to educational resources and tools when it comes to IoT technologies. This is especially true for newer technologies that you won’t yet find in a textbook or college course. 

    One example of this newer IoT technology is low-power, wide area networks (LPWAN)—specifically using the LoRaWAN standard. It’s an area that I not only expect to become increasingly relevant for IoT developers but also one that can greatly benefit from more robust educational resources. 

    IoT Development Is Relatively New 

    Modern LPWAN technologies have only been around for the past decade, and LoRaWAN became an open standard when the LoRa Alliance was formed in 2015. In the grand scheme of things, that’s pretty new. It’s not a concept that’s widely included in higher education curricula and, although we see more inclusion each year, it can be difficult for developers to find peers who have experience in building with LoRa devices. 

    ABI Research forecasts that by 2026, LoRa will be the leading non-cellular LPWAN technology. This means that over the next five years more and more developers will need to understand the basics of LoRaWAN but may not have foundational knowledge or experience to draw from. 

    From what I’ve seen, that gap can lead to teams biting off more than they can chew. Without enough training or support, developers risk building LoRaWAN deployments that may have inadequate coverage or go over scope or budget or that simply don’t live up to their vision.

    Complexity in Developing With IoT

    The other major reason IoT technologies operating with LoRaWAN need more robust educational support is due to their complexity. Developing an IoT solution requires several different skillsets that well-equipped teams either have to account for in their staffing or—as happens in many cases—rely on a single developer to figure it out and wear many hats.

    There are many aspects to building and deploying a LoRaWAN solution; for instance: Hardware engineering, device stack choice and application fit, gateway deployments and networking coverage, cloud considerations and application development involved for deployment. That’s a lot of moving parts.

    So, if enterprises and IoT vendors are expecting developers to make large-scale IoT deployments a reality, we have to provide the proper resources and training.

    Resources and Communities for LoRa Developers

    As the industry works on ways to better educate developers about LoRa technology, there are some good places to start for developers who want to hit the ground running. Here are some resources where you can learn the basics, build prototypes, get advice from other developers and test and certify solutions. 

    • LoRa Developer Portal—A hub where IoT developers can learn, connect with peers and accelerate their builds with resources like tutorials, dev kits and a free network server. Helpful for every level of expertise, from learning the basics of LoRaWAN to creating a network to rolling out a full-scale commercial solution.
    • LoRa Alliance—A nonprofit association where members collaborate and share experiences working with the LoRaWAN standard. They offers events, webinars, a resource hub and more. 
    • LoRa Basics Station —A GitHub Repository for the open source software that runs on gateways operating with the LoRaWAN standard.
    • AWS IoT Core for LoRaWAN—A guide for AWS IoT developers, spanning coverage development and deployment from connecting gateways to monitoring and logging. 
    • Azure IoT Hub—Guide for connecting the ChirpStack open source network server using LoRaWAN to the Azure IoT Hub.

    I expect higher education institutions to begin further integrating LoRaWAN into their curricula over the next several years, which will help to fill the education gap for the next wave of developers. At the same time, IoT vendors can step up and provide additional support to developers who are learning how to build with technologies like LoRa for the first time. This is critical for the success of large-scale deployments that all of us IoT believers hope to see across enterprise environments, cities, regions and beyond.

  • Microservices Adoption and the Software Supply Chain

    Microservices Adoption and the Software Supply Chain

    Software development is undergoing industrialization, with more and more software rapidly assembled out of components and an emphasis on building automation around software validation and release processes.

    Modern cloud-native software is no longer a monolithic application living in a single repo with the majority of its dependencies self-contained. It is integrated from third-party components provided by vendors, cloud providers and open source software (OSS) components, with as much as 90% of code coming from such dependencies. This allows developers to build applications much faster but makes maintenance much harder as it is no longer entirely under their control. If the third-party vendor makes a change to their API, developers are on the hook to update their applications before they break. 

    Each microservice interacts with hundreds of other microservices and each is built and released independently, making it hard to understand how to coordinate API changes across them. For example, if you want to make an API change to a microservice, what impact will this have on the consumers in the organization? Who will need to coordinate the change? When it was all within the same repository and released all at once, it was much easier to make such changes.

    The Changing Nature of Technical Debt

    What we continue to call technical debt is really the activities that are related to tending to and upgrading our software when third-party components are evolving or have common vulnerabilities and exposures (CVEs) and need to be upgraded.

    These are tedious, repetitive tasks that usually fall to the most experienced engineers as they require technical expertise to do correctly. Such activities can paralyze engineering organizations and are a tremendous burden on engineers; that often leads to burnout. Up to 30% of engineering time is spent on technical debt. The perception that somehow developers were responsible for accruing this technical debt and are doing something wrong that prevents them from keeping up is hugely demoralizing and demotivating. 

    However, if we reframe technical debt as software supply chain management and stop blaming engineering for it, we can make maintenance more predictable and consistent. By taking steps like inventorying third-party components and determining how pervasive they are in the application (frameworks take more effort to maintain than a third-party API that you just call from one part of the application), an organization can arrive at a maintenance estimate. 

    These activities are highly repetitive across organizations, as everyone is integrating some subset of the same third-party components to create business value. This high level of repeatability points us to automation. 

    Specialized Developer Tools for Software Maintenance Don’t Exist

    When developers write code, their hands often lag behind their thoughts. They think much faster than they are able to type the code. You often hear developers finishing a tedious task and complaining, “My fingers hurt.” When their IDE can autocomplete syntax, it helps reduce this lag to minutes.

    When a major framework version is released, developers contemplate the codebase. Maybe they need to change this type to that, reorder some method arguments or change dependencies. The types of changes they need to make are enumerable and must be made almost immediately; again, the ability to implement them lags far behind their recognition of the problem. Often, this type of lag can represent months or years of work when dealing with a large codebase. Accumulate enough of this lag and the codebase can grind to a halt.

    That lag kills the joy in development for most senior developers and leads to burnout. Upgrades/migrations amplify that lag by orders of magnitude.

    However, there are few (if any) tools that focus on helping developers automate these remediations/upgrades/migrations. The IDE’s focus is rightly on helping developers write new code and maintain their own code, but code maintenance needs to be coordinated across multiple places across the codebase, within the same repository or across the repository boundaries. Often, developers have a pattern they want to change in their repository, but the IDE only suggests this as an improvement in their current location (one file). Other times, changes need to be coordinated across repository boundaries if developers want to change APIs and their consumers. That’s why this technology needs to exist outside of the IDE.

    OpenRewrite

    OpenRewrite is an open source project that offers semantic analysis and refactoring of code as standalone operations so that everyone can use and contribute over time; composing more and more refactoring operations that make whole framework migrations possible. It is integrated with build tooling and can be plugged into different workflows, from CI integrations to mass refactoring of multiple microservices/repositories. Similar to an IDE or other developer tools, OpenRewrite manipulates an abstract syntax tree (AST) representation of code, but this AST has special characteristics that allow it to transform this AST and generate code back to the standard text representation. 

    The OpenRewrite AST is produced by guiding the compiler through the first two phases of compilation to generate compiler type-attributed AST. This is then mapped to the OpenRewrite AST, preserving formatting and breaking cycles in the AST. The three unique characteristics of OpenRewrite AST are:

    • Type aware, allowing 100% correct semantic code analysis and transformation.
    • Style-preserving, so transformations produced are idiomatic within the projects they are applied to. So, the same transformation applied to multiple projects will potentially look different.
    • Serializable, allowing to output the AST from the build and operate on it outside of the build en masse.

    OpenRewrite ASTs is full of metadata about code. Visualizing the code itself as a highly connected tree of various vertices and edges, we can start to get an idea of the density of this representation. Syntactic elements alone are blue, type attribution is yellow and formatting information is red. If we were to just represent syntactic elements, the tree might look something like this.

    Adding type attribution and formatting, the tree looks quite a bit denser.

    A spanning tree of the data involved in this AST can be laid out in three-dimensional hyperbolic space and then projected onto the unit sphere similar to the way that two-dimensional space can be projected onto a disk—the famous Poincaré disk model. This three-dimensional approach was pioneered by Tamara Munzner at Stanford.

    Every edge that isn’t part of the spanning tree is rendered as a lighter gray, and, as you can see, it is dense! In fact, to make this layout more tractable, we’ve omitted in this view an additional 600,000 vertices representing type information that make the syntax itself seem tiny.

    OpenRewrite calls a single code search or transformation operation a recipe. It provides a number of building block recipes such as find method, change method, find transitive dependency, upgrade or exclude dependency. These recipes, in turn, can be composed into more complex recipes by grouping them together into a composite recipe. When the building blocks are not enough, a recipe can be written as a program in the same language as the code we want to transform, allowing us to encapsulate complex logic with the full expressiveness of the language already familiar to developers. We don’t need to learn a new DSL or programming language.

    These building blocks abstract away many of the details to ensure that edits that we make to source code obey the original style of the project. This is possible for even complex changes like this automated migration from Spring Boot 1.x @ConditionalOnBean to Spring Boot 2.x AnyNestedCondition looks idiomatically consistent in the context of the project that it is inserted into:

    It is important to note that OpenRewrite is not a replacement for an IDE. With software now composed of so many independent components, we need to start to remediate and manage it using new approaches that go beyond single lines of code to looking across entire code repositories.


    Olga Kundzich, co-founder of Moderne, co-authored this article.