Category: DevOps in the Cloud

  • Quali Adds Free Tier to DevOps Automation Platform

    Quali Adds Free Tier to DevOps Automation Platform

    Quali has added a free tier of service to its Torque platform for automating infrastructure provisioning and application workload deployments.

    In addition, the company has updated the software-as-a-service (SaaS) platform to provide blueprints through which it provides tighter integration with Terraform, an open source infrastructure-as-code (IaC) tool, along with support for custom tags to make it easier to generate reports and dashboards that provide greater visibility into infrastructure costs.

    Quali CEO Lior Koriat said the free tier is intended to make the Torque platform more accessible to both small teams of DevOps professionals and individual users. It includes the ability to build environments on Amazon Web Services (AWS) or the Microsoft Azure cloud in addition to providing integration with a variety of DevOps tools and platforms and access to a sample blueprint library. Support for the free tier is provided via an existing community edition of the platform.

    Koriat said Torque takes IaC a step further by also making it possible to automatically deploy complete application environments on top of infrastructure provisioned as code using blueprints rather than low-level Terraform scripts. The goal is to increase developer productivity by extending Terraform so that developers can spin up environments across multiple cloud computing platforms via self-service, he added.

    That approach also sharply reduces the chances a cloud platform will be misconfigured, which Koriat noted is the bane of cloud security professionals’ existence. Most developers lack the cybersecurity expertise required to ensure cloud computing environments are configured properly. Simplifying the provisioning of infrastructure is especially critical when developers employ complex platforms such as Kubernetes, added Koriat.

    At the same time, Quali’s Koriat said IT leaders want more visibility into how cloud resources are being consumed as the number of workloads deployed in these environments steadily increases. Developers tend not to remember to de-provision cloud resources when no longer needed, which Koriat noted conspires to increase cloud costs unnecessarily.

    It’s not clear just yet how quickly DevOps teams might be moving away from relying on lower-level tools toward automation frameworks accessed via a SaaS platform. However, as application environments become more complex, it becomes even more challenging to provision and manage IT environments—especially since many DevOps teams are still working from home to help limit the spread of the COVID-19 pandemic.

    One way or another, the amount of time and effort spent managing IT infrastructure needs to be reduced. After all, while application environments are increasing in both size and complexity the number of individuals that make up a DevOps team remains largely the same. The need to rely more on automation frameworks has reached a tipping point that is becoming increasingly obvious to all concerned.

    As more organizations start to operate as software companies in the age of digital business transformation, it’s clear the way IT has been managed in the past is about to fundamentally change. The issue now is determining which automation framework lends itself best to enabling DevOps teams to achieve that goal.

  • Red Hat Adds Service to Customize RHEL Images

    Red Hat Adds Service to Customize RHEL Images

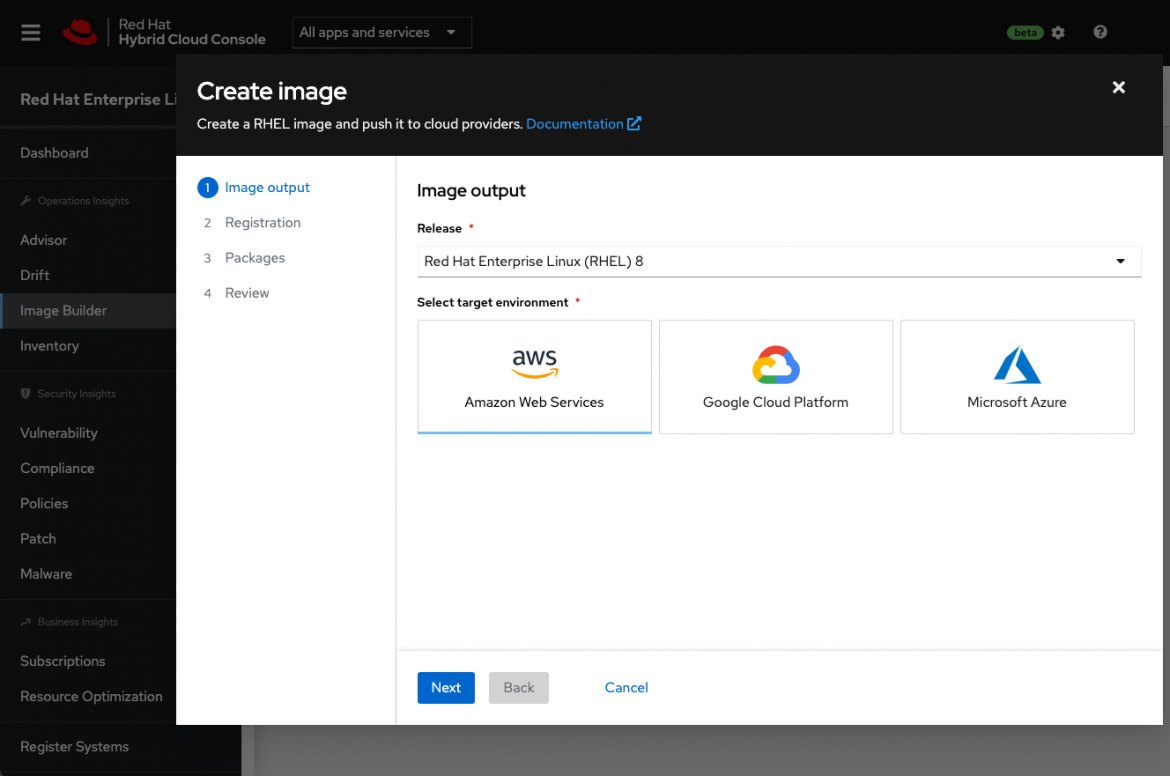
    Red Hat this week announced a public beta of an Image Builder service that streamlines the process of building customized instances of the Red Hat Enterprise Linux (RHEL) operating system.

    Scott Herold, director of product management for RHEL at Red Hat, said the Image Builder service enables an IT team to define a “gold” template for each target deployment environment that only contains the RHEL code required. Initially, Image Builder is configured to default to build a minimal, recommended RHEL server image for Amazon EC2, Microsoft Azure and Google Cloud Platform (GCP) cloud services.

    Future updates to the service will add support for VMware vSphere platforms as well as downloadable images and installation media for physical servers, customized filesystem layouts and versions 9.0, 8.5, 8.4 and 7.9 of RHEL. The service itself is accessed via the Red Hat Hybrid Cloud Console that is currently being made available in beta.

    Herold said building or installing operating systems is often a slow, tedious and error-prone process that needs to be manually performed in a slightly different way for each platform. Each physical server or edge computing platform requires different configurations and workflows. As a result, the chances mistakes will be made is high; Image Builder can greatly reduce the possibility of mistakes because there is no guesswork required, noted Herold.

    IT teams can also opt to include additional content from Red Hat in those builds to further streamline deployment processes, noted Herold. Those images can then be automatically registered with Red Hat to ensure future updates are received.

    The ability to customize those images also serves to reduce the overall size of the codebase that needs to be secured, added Herold. At a time when there is increased focus on software supply chains in the wake of a series of high-profile security breaches, many IT teams are revisiting their software deployment processes, he noted.

    Ultimately, Herold said Red Hat is moving toward providing IT teams with a more cloud-like experience regardless of where they deploy Red Hat’s curated open source software. The goal is to reduce as much friction as possible so that IT teams can more easily manage infrastructure at scale, he added.

    One way or another, the entiree software deployment process is becoming more automated. Much of the drudgery that has historically made it challenging to deploy and manage IT platforms at scale can be traced back to manual processes created when organizations ran a much smaller number of applications in on-premises IT environments. As IT teams increasingly deploy more applications in the cloud and at the network edge, it’s become more apparent that manual legacy processes won’t scale—especially when it’s already challenging to hire and retain IT personnel.

    It’s not clear how quickly IT teams will modernize software deployment processes using automated DevOps processes. Simple inertia is often a powerful force to overcome; however, most IT professionals can easily find something more compelling to do with their time that doesn’t involve using manually customizing operating system images.

  • Hasura Adds Engine to Transform REST APIs to GraphQL

    Hasura Adds Engine to Transform REST APIs to GraphQL

    Hasura today unveiled a Data Hub repository for integrating application programming interfaces (APIs). The repository includes a connector that makes it easier for IT organizations to convert REST APIs into ones based on the GraphQL specification.

    Tanmai Gopal, Hasura CEO, said the connector eliminates the need to write custom code to connect existing REST endpoints to a GraphQL API using an update to the transformation engine developed by Hasura. Instead, the model for the GraphQL API is automatically overlayed on top of the REST API endpoint, explained Gopal.

    Originally developed by Facebook, GraphQL has emerged as a popular alternative to REST APIs because it enables developers to retrieve data at a more granular level, which results in improved performance. Hasura provides an instance of a GraphQL engine the company has developed around a project that is now hosted by the GraphQL Foundation, an arm of the Linux Foundation. GraphQL provides a complete description of the data made available via an API and is organized in terms of types and fields rather than traditional endpoints. In addition to clarifying what data is available via that API, developers can employ types to avoid writing manual parsing code.

    Hasura claims its engine has been downloaded more than 400 million times since its introduction in 2018. It automates the repetitive work involved in mapping models to APIs by providing common access patterns for pagination, filtering, joining, setting up authorization rules and optimizing performance. Hasura also provides APIs that are able to connect to multiple services and data sources, embed domain-specific authorization logic and provide additional layers of security.

    Hasura is now also adding a way to create identity-specific authorization policies for any GraphQL service or data source, enforcing security by limiting the models and fields of the GraphQL APIs in a way that eliminates the need for IT teams to cobble together disparate libraries and frameworks, said Gopal.

    In addition, Hasura is adding support for Google Cloud to Hasura Cloud in beta, a managed API integration service the company already provides via the Amazon Web Services (AWS) cloud. Support for the Microsoft Azure cloud will be forthcoming in 2022, added Gopal.

    It’s not clear the degree to which organizations are looking to replace existing REST APIs with ones based on GraphQL. However, Gopal noted there are plenty of instances where organizations need to overlay a GraphQL API on top of a REST API that they may not own. For example, a software-as-a-service (SaaS) platform that currently exposes a REST API may not have any plans to support GraphQL, he said.

    There’s no doubt the number of GraphQL APIs being employed in the enterprise is about to dramatically increase. The challenge now is finding a way to manage them alongside the previous generations of APIs that remain. The trouble is that many of those APIs were created by developers that may not have documented the APIs they created or, in some cases, never informed DevOps teams that they existed in the first place.

  • Speedscale Makes Free API Observability Tool Available

    Speedscale Makes Free API Observability Tool Available

    Speedscale today announced it is making a free edition of its observability tool for application programming interfaces (APIs) available to developers.

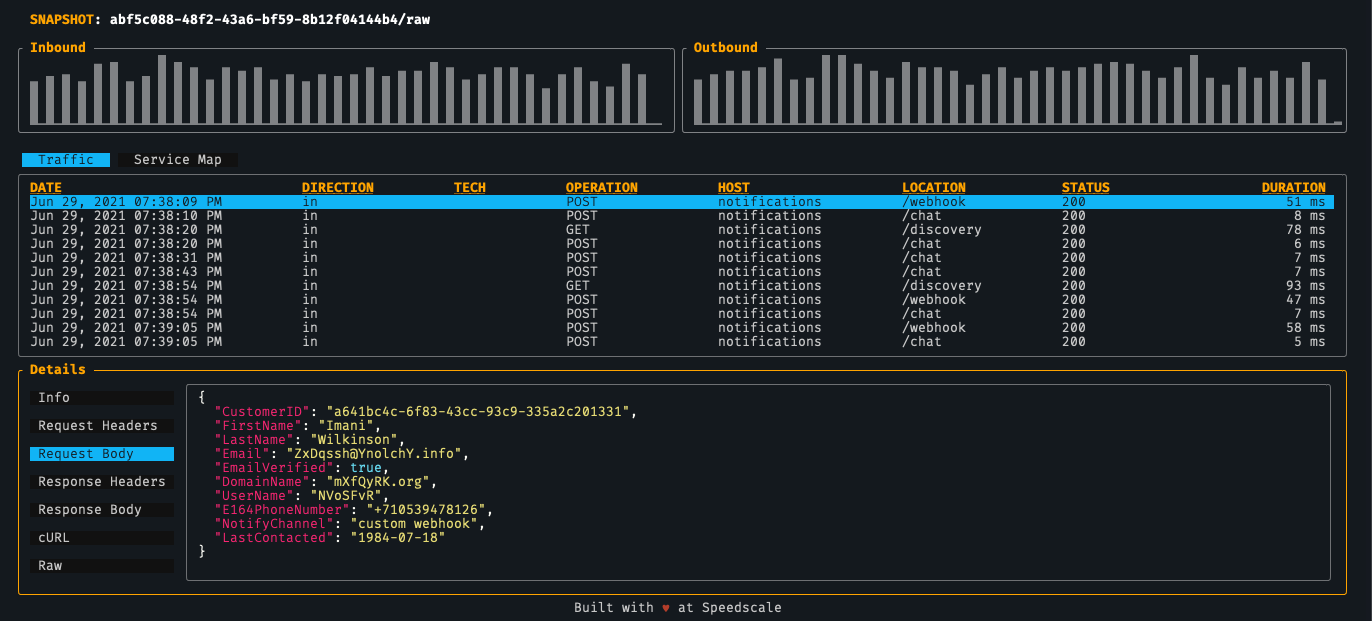
    Ken Ahrens, Speedscale CEO, said the goal is to expose more developers to the company’s API testing tool that can be accessed on their local machine via a command line interface (CLI). Dubbed Speedscale CLI, it is designed to enable individual developers to inspect, detect and map API calls on local applications or containers rather than having to subscribe to the company’s current API testing platform via a software-as-a-service (SaaS) model.

    That approach should reduce the number of disruptions DevOps teams are likely to encounter after an application is deployed in a production environment, noted Ahrens.

    Speedscale CLI features include service mapping, which enables developers to auto-detect and map external dependencies that could break, a traffic viewer for logging and tracing API calls and latency detection tools that show how code changes are impacting performance. In a forthcoming update, Speedscale also plans to include load generation capability to enable developers to run tests locally. The overall goal is to enable IT organizations to shift more responsibility for the management of APIs further left toward the developers that create them, said Ahrens.

    Naturally, Speedscale is also hoping that, as more developers are exposed to its observability platform for APIs, there will be increased demand for its SaaS platform among DevOps teams that need to manage and maintain APIs in production environments within their existing workflows. Speedscale exposes a set of APIs of its own to enable that integration, noted Ahrens.

    At its core, the Speedscale SaaS platform is designed to enable DevOps teams to replay how calls are made between APIs and external mock services to make it easier to diagnose issues.

    In general, there’s a lot more focus these days on APIs, thanks to digital business transformation initiatives that are dependent on APIs to integrate processes. The challenge organizations face is many of those APIs are built by separate development teams. In some instances, organizations can find themselves deploying redundant APIs. Other organizations will create APIs that, over time, are simply forgotten about or that go dormant when the developers that created them leave the organization. These “zombie APIs” often represent a security risk because cybercriminals now routinely scan IT environments for unattended APIs through which they can exfiltrate data without anyone noticing.

    One way or another, the management of APIs is becoming a distinct discipline within many organizations as they come to appreciate the level of IT flexibility they enable. Replacing backend services is a lot simpler when the APIs calls that invoke them both internally and externally remain relatively simple. The challenge is that building and maintaining microservices-based applications based on APIs is a more complex endeavor than building a monolithic application. The first step toward reducing that complexity is, of course, to provide more visibility into the application environment for all concerned.

  • U.S. Govt. CX EO | Mozilla Revenue | Log4j Latest

    U.S. Govt. CX EO | Mozilla Revenue | Log4j Latest

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Improving U.S. government CX, how much money Mozilla makes, and the latest on the Log4j/Log4Shell débâcle.

    EO: “Transforming Federal Customer Experience”

    First up this week: The Biden–Harris administration makes an executive order directing its Federal agencies to make 36 specific customer experience (CX) improvement commitments. Much of this involves using technology to improve what DevOps teams would call UX—but government doesn’t like the language of “users.”

    Analysis: Customer-centricity FTW

    Remarkably, a lot of interaction with government still involves paper forms. But this EO shouldn’t merely be about putting existing processes online. Work also needs to be done to solve the underlying complexity and fragmentation of services: Focusing on CX is a helpful frame.

    Brett Samuels: Biden to sign order to streamline government services

    [The] executive order [is] intended to cut back on the bureaucracy around government services for the public such as renewing passports, applying for loans or changing names. [It] affects 36 “customer experience improvement commitments” across 17 federal agencies, [targeting] travel, retirement, business, health and updating personal information.
    …
    For example … to renew their passports online rather than dealing with print forms. [It] will create a single portal for … student loan debt, and small-business owners will have a more streamlined process for … loans, grants and certifications.
    …
    Survivors of natural disasters will also no longer be required to complete forms with several agencies when applying for assistance … and they will be able to file smartphone photos and use virtual inspections when filing claims. [That] could be critical as natural disasters become increasingly devastating, as evidenced by the tornadoes that ravaged Kentucky over the weekend, killing dozens of people and destroying communities.


    Is this a technology problem? Yes, in part—but it’s also a government problem, argues Jennifer Pahlka:

    Surely laws like the 21st Century IDEA Act … which required agencies to … “eliminate or consolidate websites or web pages that are duplicative or overlapping … and ensure that each website or digital service is designed around user needs,” made life easier for the customers of those agencies? What’s that you say? You’re not sure you’ve noticed that? Turns out you’re not alone.
    …
    An EO is one of the many mechanisms our government has at its disposal for what I like to call “magic words.” [But there’s a] gap between magic words and the changes they are supposed to compel. [Failures] happen at such a staggering scale they have become entirely expected.
    …
    We tend to assign the blame … to government technology [but] at some point, you can only improve the customer experience by addressing [underlying] complexity. … Most of the Kafka-esque nightmares people get stuck in happen because each service sees only the burden they impose, and not [what] the customer experiences.


    If, like me, you’re inherently cynical about government efficiency, you’d expect this effort to be a huge failure. But let’s not be too cynical: Warning of “the hazards of selection bias,” here’s ShanghaiBill:

    In the olden days, I took half a day off work to go to DMV and renew my DL. Now I can do it online in 5 minutes. … I pay my property tax online. I renew my business licenses online. I incorporated online.


    $500 Million per Year—But for How Long?

    The Mozilla Foundation has unveiled its revenue forecasts for this year. As in previous years, Mozilla makes the lion’s share of its cash from Google—by making it the default search engine. But there are new revenue sources.

    Analysis: And not a moment too soon

    The future of the browser market should be a strategic focus for DevOps teams. Mozilla’s Googley cash cow might not last. It’s often assumed the maker of Chrome keeps Mozilla alive so it can point to Firefox as “competition.” But with Microsoft’s browser Edging up the usage charts, that might no longer be true.

    Frederic Lardinois: Mozilla expects to generate more than $500M in revenue

    For 2021, the organization forecasts revenue of more than $500 million. What’s maybe most important, though, is that Mozilla’s new products like its Mozilla VPN service, Firefox Relay Premium, Pocket and other commercial initiatives are slowly but surely starting to pay off.
    …
    But for all intents and purposes, Mozilla remains fully dependent on Google for the time being. Diversifying its revenue sources is really the only way for Mozilla to decrease its reliance on a search deal with a company that is both a competitor, thanks to its dominant Chrome browser, and is increasingly out of alignment with Mozilla’s overall philosophy.
    …
    There is a window here for a non-Chrome browser, with users increasingly skeptical about Google’s motivations and Microsoft’s Edge team making a few missteps in recent months. Yet at the same time, Mozilla’s efforts to bring sponsored suggestions and ads to Firefox haven’t necessarily endeared the organization to its own users either.


    Why is Google funding its competitor? u/SerAaron:

    Google is Mozilla’s biggest donor. … It’s basically to avoid any monopoly allegations—so they can point to Firefox and say “look, we have competition”.

    Mozilla takes their money, sure, but … they don’t sell data, and they aren’t beholden to Google.


    But don’t count on that cash continuing to flow, says Maelwryth:

    That money is probably under threat now with Edge going for the market. Why give Mozilla hundreds of millions to show competition when you have actual competition from Microsoft?


    Log4j/Log4Shell Seems Worse Every Time We Look

    The list of popular DevOps tools vulnerable to Log4Shell grows by the hour. Merely finding your exploitable services can be an impossible task—let alone patching them.

    Analysis: Defense in depth is key

    Searching for and patching your vulnerable code is not enough. You’re also going to need to shore up your network defenses, by auditing internet-visible services and by tightening your application firewall rules. And—ironically—keep a close eye on your logs for signs of attempted exploits and IoCs.

    Steven J. Vaughan-Nichols: We Are in So Much Trouble

    Log4j is used a lot. And, when I say a lot, I mean it’s used in hundreds of applications [including] Druid, Dubbo, Flink, Flume, Hadoop, Kafka, Solr, Spark, Struts, Apple iCloud, … LogStash, GrayLog2, … Steam, Twitter, and … VMware.
    …
    Log4Shell is both easy to exploit and can be used to grab complete control of vulnerable servers. … Even as you’re reading this, odds are decent you’re being attacked. [But] even if you patch it in your systems, it’s all too likely to be hiding in other applications.
    …
    Log4Shell may be the worst security problem in a generation. … This is going to be a long, hard ride.


    Hyperbole? Even December 25 isn’t close enough for government work. Catalin Cimpanu:

    The US Cybersecurity and Infrastructure Security Agency has told federal civilian agencies to patch systems affected by the Log4Shell vulnerability by Christmas Eve. … Federal agencies have ten days … to test which of their internal apps and servers utilize the Log4j Java library, check if systems are vulnerable to the Log4Shell exploit, and patch affected servers.
    …
    Despite being a recent vulnerability, it is already considered one of the worst security flaws ever discovered, primarily due to its near-ubiquitous use among enterprise software makers, its simple and easy-to-use exploit, and the ability to hijack systems remotely. … Days after being disclosed, the vulnerability has been massively abused. … The first attacks were seen on December 1.


    There’s always another shoe. Here’s Teri Robinson:

    Maybe Log4j vulnerabilities are like rats—for every one that’s visible, multiple others scurry beneath the surface. … Apache said the fix addressing “CVE-2021-44228 in Apache Log4j 2.15.0 was incomplete in certain non-default configurations,” according to … CVE 2021-45046.


    The Moral of the Story: In the end, the love you take is equal to the love you make.


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Bernd Dittrich (via Unsplash)

  • AWS Outage and App Resiliency: Did a Roomba Replace the Canary?

    AWS Outage and App Resiliency: Did a Roomba Replace the Canary?

    Canaries were once sent into coal mines as an early warning sign against danger—for me, it was my Roomba failing to automatically search out dog hair and clean the floor under my sons’ dining room chairs. Cloud-enabled apps also were acting “weird”. Some were down, while others were just slow—although, in my view, slow may as well be down; who has the tolerance to wait for an application to load?

    What caused this headache felt across the internet? An AWS disruption.

    In the days since the December 7 outage, I’ve had a number of conversations with CIOs, colleagues and other industry analysts and many of our shared concerns remain unanswered. Here are a few quick thoughts on the latest us-east-1 outage.

    Understanding AWS SLAs

    It’s important to remember that AWS requires instances/apps be deployed across two or more regions for redundancy and resiliency. And an SLA is not only a way for service consumers to gauge the value they’re getting for their money, it’s also the contractual agreement between a cloud service provider (CSP) and a customer. It outlines the uptime, availability and performance standards to which a cloud service will adhere. It may also specify that the service provider’s helpdesk will respond to an outage within a set amount of time. Amazon has very clear SLAs. If a customer receives less than 99.99% uptime in a given month, the company will provide credits to their account.

    However, there are three things to keep in mind:

    A 99.99% uptime agreement still means you are willing to tolerate services being down for almost four and a half minutes per month (53 minutes per year), and you must architect your AWS instances and applications in a way that meets the AWS SLAs. The third point is that, in AWS’s view, the outage wasn’t their fault.

    Outages Don’t Just Impact Startups and Organizations With Poor Planning Practices

    The cloud allows organizations to regularly make budget versus resiliency decisions. However, the recent AWS outage didn’t just impact born-on-the-web startups. Mature businesses like Disney, McDonald’s and Amazon itself were impacted by the outage. These technology-first companies aren’t sacrificing budget over resiliency. They understand that they are technology companies—they have large IT budgets that represent this priority and were still blindsided.

    The recurring question is why all these organizations were crippled by a single Amazon region going down? Was it poor architecture? Did these AWS customers not fully understand AWS’ SLAs? Did they choose budget over resiliency? 

    Amazon as an Enterprise Platform

    Adam Selipsky’s keynote and industry analyst Q&A at re:Invent 2021 made it clear that AWS is completely focused on the enterprise. Amazon understands the needs of the DevOps community, but they are still working on developing their approach to the enterprise. Google Cloud recognized the same shortcomings in its own organization and brought Thomas Kurian from Oracle to build up the company’s enterprise and IT industry persona.

    Everyone in the technology industry understands that outages and slow performance happen, but they expect service providers to provide best practices and avoid downtime. In response to Selipsky’s re:Invent keynote, Linda Jojo, executive vice president of technology and chief digital officer for United Airlines, said that the airline settled on a “one cloud” approach. Surely United Airlines can’t tolerate regular downtime.

    My View

    December 7, 2021 won’t live in infamy for AWS; we have seen plenty of other outages.

    Application resiliency is still an emerging area of focus. In the past, the focus was on platform and data center uptime; however, in many cases, developers have no control over the infrastructure. Therefore, teams need to focus on the resiliency of an application and assume that the underlying IaaS (cloud infrastructure) will fail for one reason or another.

    In addition, Amazon needs to offer more opinionated offerings. Disaster recovery and failover should be built into every level of AWS. Software companies shouldn’t be forced to sign up for multi-region deployments, but AWS should at least be prescriptive with best practices that advise such a practice.

  • NetApp Survey Shows Hybrid Cloud is Maturing

    NetApp Survey Shows Hybrid Cloud is Maturing

    A small survey of 79 midsized to large enterprises conducted by NetApp suggests enterprise IT organizations might finally be embracing hybrid cloud computing beyond use cases involving backup and recovery.

    The survey finds 20% of respondents are currently employing both on-premises and cloud resources to support the same workload in a production environment, with another 17% planning to do so within 24 months.

    Darnell Fatigati, senior product marketing manager for hybrid cloud at NetApp, noted that a hybrid approach to cloud computing will dominate with more than three-quarters of respondents reporting their organization plans to operate a hybrid cloud environment for the foreseeable future. Only 17% expect their organization to eventually migrate all their IT environments to the cloud.

    A major factor in the decision to not migrate all workloads to the cloud is the amount of data gravity that legacy applications running in on-premises IT environments exert, noted Fatigati. The amount of effort required to successfully migrate terabytes and even petabytes of data into the cloud is simply too great, he added.

    The primary benefits of hybrid cloud computing cited by survey respondents are faster innovation (26%), increased responsiveness (25%) and increased collaboration (22%). Survey respondents also noted they are looking to improve infrastructure flexibility and scale (27%), optimize costs (21%) and improve data accessibility (13%). Data protection involving disaster recovery, backup and archiving remains the most widely employed use case for hybrid cloud, with 29% either employing it today or planning to do so in the next 24 months.

    Most hybrid cloud computing environments today consist of multiple clouds and on-premises IT environments that are managed in isolation from one another. The fact that more organizations are now starting to deploy the same workload across both a cloud service and an on-premises IT environment has significant implications for DevOps teams that will be required to manage those workloads. Most DevOps workflows today do not span multiple platforms. However, as more organizations become impacted by the occasional cloud outage, the level of resiliency enabled by hybrid cloud computing is becoming a higher priority.

    In many cases, the shift to hybrid cloud computing was accelerated by the COVID-19 pandemic that drove many organizations to increase the number of workloads deployed in the cloud. Now, heading into 2022, those same organizations are looking to reduce IT costs by centralizing IT management as much as possible, noted Fatigati. Each time an IT organization adds a new platform, the tooling and personnel required to manage that platform increase the total cost of IT for any organization. Much of the shift to hybrid cloud is being driven by C-level executives looking to reduce those costs.

    It may be a while before most enterprise IT organizations are able to deploy workloads across multiple platforms. However, as both cloud and on-premises IT environments continue to evolve and as more platforms deployed in local data centers are increasingly managed using a cloud operating model, the way those platforms are accessed on demand will continue to converge. In fact, there may come a day when the term cloud computing itself disappears from the IT lexicon as every IT platform, by default, leverages one type of cloud or another.

  • AWS Outage Exposes Weaknesses of DevOps Resilience

    AWS Outage Exposes Weaknesses of DevOps Resilience

    The December 7, 2021 Amazon Web Services (AWS) outage severely disrupted services from a wide range of businesses for more than five hours and highlighted just how reliant businesses have become on internet-delivered services. The outage mostly impacted web services in the eastern U.S., yet the implications are universal: It’s a reminder that many businesses blindly ignored the old axiom about putting all your eggs in one basket and instead are relying on a provider with a single point of failure.

    Services ranging from airline booking systems to streaming video to e-commerce were disrupted during the outage, causing millions of dollars in lost revenue and countless hours in productivity. One of the more interesting aspects of the outage is the impact it had on services from collaboration vendors such as Slack, Trello, Asana and Smartsheet—tools that many development and DevOps teams have come to rely on.

    Furthermore, core AWS services, such as the company’s Elastic Compute and DynamoDB cloud tools were also impacted, disrupting many third-party services and severely hampering business processes that use those services. While the obvious victims of the outage are well known, like Amazon’s own e-commerce operation, there is a troubling undercurrent: The disruption to DevOps frameworks and those using them.

    AWS has been rather tight-lipped about the root cause of the outage thus far; however, there are still many lessons to be learned for the DevOps community and questions that must be asked such as “Can the DevOps process survive during IaaS/SaaS disruptions?” and “Can multi-cloud failover solutions be baked into the applications DevOps builds?”

    There are no simple answers to those questions, but the outage highlights the need to understand the underlying architecture and framework of a deployed DevOps system. Take, for example, how many developers in the DevOps community have embraced SaaS tools to accelerate the development process and to feed CI/CD pipelines. SaaS applications such as code scanners, pipeline orchestration and even IDEs have become common in the world of DevOps. But has anyone bothered to ask what happens if a single one of those tools fails?

    What’s more, the reliance on SaaS tools in the development process has led to the creation of potential liabilities in the applications created by DevOps developers. DevOps applications have come to rely on APIs, are often driven by microservices and are frequently deployed into containers that run on SaaS. If any of those elements become non-functional, numerous applications could fail, ultimately putting the onus on developers to explain why they are creating applications with a single point of failure.

    Moving forward, the DevOps community needs to take a serious look at the components of their frameworks and determine if there are any single points of failure—including their IaaS/SaaS providers. While it may be impossible to remediate every single one, there is a lesson to be learned about how fragile the development process can become if no one bothers to build an inventory of the tools used and take into account how a failure of any one of those tools could impact workflow. There are numerous examples of how an external failure of a single component impacted the functionality of an application, while the discovery process of the root cause has taken days or even weeks. This can be mostly attributed to not only a lack of knowledge, but a lack of visibility into the components used.

    Those lessons can be extended to the development process itself, where the best practice of rooting out single points of failure can be extended to the applications themselves. Leveraging that intelligence starts with understanding the concept of a software bill of materials (SBoM), a piece of supporting documentation that is becoming increasingly important to the purveyors of applications. A properly-defined SBoM reveals all of the components (libraries, APIs, etc.) that are baked into an application and can be used as a map to define where weaknesses may lie.

    For the DevOps community, the recent AWS outage has become a clarion call to look inward and discover how the applications they are building may be part of the problem. With continuity and resiliency becoming major topics in the IT and business realm, it’s about time that DevOps practitioners start to look at how they can support both of those business-critical needs. The days of finger-pointing to shift blame must come to an end, and if businesses that rely on software want to grow, someone needs to take responsibility for providing answers when outages occur and learn from those outages to create applications that are more resilient.

  • DevSecOps for Databases: Data Masking, Cloud Backup, WAF and More

    DevSecOps for Databases: Data Masking, Cloud Backup, WAF and More

    DevSecOps is everywhere. More and more organizations realize that the traditional separation between DevOps and security is wasteful and dangerous. As a result, they are rushing to integrate security into all their software development processes. 

    Adding security to containerized applications, cloud resources and other parts of modern DevOps infrastructure is already well understood. But what about databases? Databases were always—and remain—a critical system component and a prime target for attackers. Here, I’ll review the basics of modern database security and show you how to create a continuous security process for databases in a DevSecOps organization.

    What is DevSecOps?

    DevSecOps incorporates security practices into the DevOps methodology. DevSecOps promotes a ‘security-as-code’ approach via the partnership between release engineers and security teams. Similar to DevOps, the DevSecOps approach focuses on creating innovative solutions for complex software development processes. Teams complete this within the framework of an agile approach.  

    DevSecOps aims to close the gap between security and IT teams while ensuring the speedy and safe delivery of code. Organizations replace the siloed development method with a new approach that promotes the shared responsibility of security tasks during the delivery process. 

    In DevSecOps, two supposedly opposite aims—delivery speed and secure code—are united into one effective process. 

    Database Security Basics

    The term “database security” is an umbrella term used to describe all of the tools created to develop and preserve database availability, integrity and confidentiality. A key responsibility for any DBA is to ensure that the information stored in databases is always secure.

    The goal of database security is to protect:

    • Database management systems
    • Applications that access database information
    • Datastores within databases
    • Hardware servers
    • Virtual database servers, such as cloud-based servers
    • Network access points

    It is critical to strike a balance between security and usability. While you must prioritize data security, information needs to be accessible to offer value to the organization. The more access you provide to the information retained in a database, the more vulnerable the information is. However, an overly secure database is neither practical nor functional.   

    A good way to achieve a balance between accessibility and security is to create meaningful security protocols, create tiered levels of information access and invest in a robust database security and activity monitoring tooling. 

    Common Threats and Challenges

    Here are some of the most common types of database attacks:

    • Insider threats—These involve privileged users misusing their access credentials. An insider could be a negligent employee who unwittingly exposes the database to attack, a malicious insider who abuses the database on purpose or an outside infiltrator who steals credentials to breach the database. The risk of a breach increases as more employees hold privileged access credentials.
    • Injection attacks—These involve inserting arbitrary attack strings into the database queries that HTTP headers or web applications serve. These attacks can be SQL or NoSQL. Secure coding practices and regular vulnerability tests should help protect you against injection attacks.
    • Database software vulnerability exploits—Database software providers regularly release security patches for vulnerabilities in their software. However, if you don’t apply the patches quickly, you prolong your exposure and run the risk that hackers will exploit vulnerabilities in your database. 
    • Backup attacks—If you don’t protect your backup data with sufficient controls, you expose your database to an attack on your backups. 

    The following challenges can exacerbate these threats:

    • Large volumes of data—Organizations must adequately manage increasingly large volumes of data using scalable tools and practices.
    • Sprawling infrastructure sprawl—Organizations are increasingly shifting to hybrid and multi-cloud environments, making their networks more complex and security harder to manage. 
    • Evolving regulations—With the global regulatory landscape changing and growing more complex, it is increasingly challenging to maintain compliance.
    • Skill shortage—The demand for cybersecurity personnel far outstrips supply, and this shortage is only likely to increase in the future. 

    4 Techniques for Continuous Database Security With DevSecOps

    A DevSecOps approach calls for continuous database security during all stages of database development and usage. Let’s explore a few techniques for achieving continuous security.

    Data Masking

    Data masking technology lets you create a structurally similar, anonymized version of an organization’s data. You can use this data for user training or software testing. The aim is to safeguard the real data while using a functional substitute for use cases in which the actual data is not needed.  

    In data masking, you keep the format of the data the same. You only change the values of the data. You can alter the data in various ways including character shuffling, encryption and word or character substitution. Whichever method you choose, you have to modify the value in some way that makes reverse engineering or detection impossible. 

    Use data masking when presenting data to users (whether inside or outside the organization) who don’t need to access the data as part of their role. You should apply data masking to all sensitive information before displaying it in public forums. 

    Use Web Application and Database Firewalls

    Protect your database server from security threats using a firewall that stops access to traffic as a default. The only traffic permitted should come from particular web servers or applications that require access to the information. The firewall must also prevent your database from establishing outbound connections unless they are specifically needed. 

    Protecting the database using a firewall is not enough. You should also deploy a web application firewall (WAF). That’s because SQL injection attacks, which target web applications, can be employed to delete or exfiltrate data from the database. A database firewall may not stop this from occurring if attacks are initiated from an application that is a permitted source of traffic. However, a web application firewall likely will stop attacks of this nature because it can analyze traffic at the application layer and identify malicious query patterns.

    Cloud Backup

    Database backup solutions help organizations safeguard their data with backup database copies in the event of user error, physical hardware failure, data corruption or ransomware attacks. Organizations can ensure their information is always accessible by using database backup tools, even if their central database fails or is compromised. 

    Cloud backup services allow you to send a database copy to an off-site, secondary location for safekeeping if there is a disaster or failure. A third-party service provider typically hosts the secondary data storage systems and servers. This provider bills the backup customer based on capacity used or storage space, number of users, data transmission bandwidth, number of times the information is accessed or the number of servers. 

    Using cloud data backup can help you improve data protection without overwhelming IT staff. This labor-saving advantage could be significant and may even offset some of the added costs connected with cloud backup, including data transmission costs. 

    Secure Database User Access

    You must strive to limit the number of individuals with access to the database to the extreme minimum. Administrators should only have minimal privileges—those they require to carry out their job and only when they require access. 

    For small organizations, this might be difficult to achieve because employees have multiple roles, and there may be only one or two database administrators. However, you should at least manage permissions using roles or groups rather than granting access directly.  

    If you have a large organization, you must think about automating access management via access management software. Access management software can give authorized users a provisional password with the privileges they require every time they want access to the database. This software also logs the activities conducted during that time and stops administrators from sharing their passwords. 

    It is critical to lock down any form of password sharing—this is a common practice by administrators and database users, but it makes accountability and effective database security nearly impossible. 

    In addition, you should follow standard account security procedures: 

    • Enforce the use of strong passwords
    • Store, encrypt and salt password hashes
    • Lock accounts after three or four login retries
    • Deactivate accounts when employees leave or switch to different roles

    DevSecOps and Database Security

    In this article, I explained the basics of DevSecOps and database security, covered the primary threats facing database systems in a modern IT environment and provided four ways you can implement continuous security for databases:

    • Data masking—All modern RDBMS systems offer data masking mechanisms that can reduce the impact of compromised accounts.
    • Using WAFs and database firewalls—Firewalls provide excellent runtime protection and visibility for application-layer attacks.
    • Cloud backup—Backing up databases in the cloud is a continuous process that can enhance availability and reduce the impact of ransomware attacks.
    • Secure database user access—Using least-privilege principles can dramatically reduce the threat surface of a database.

    I hope this will be useful as you extend your DevSecOps practices to critical database systems in your environment.

  • Sumo Logic Extends Observability Reach to AWS Lambda

    Sumo Logic Extends Observability Reach to AWS Lambda

    At the AWS re:Invent conference this week, Sumo Logic announced that in addition to collecting log data, metrics and traces, it now can collect telemetry data from the Lambda serverless computing service provided by Amazon Web Services (AWS).

    In addition to collecting telemetry data, Sumo Logic also revealed that the Sumo Logic Continuous Intelligence Platform hosted on the AWS cloud can now analyze how functions used on the AWS Lambda service perform during transactions.

    That data can then also be correlated against the performance of other AWS services that Sumo Logic tracks via integrations with the AWS CloudWatch and AWS CloudTrail monitoring services.

    George Gerchow, chief security officer for Sumo Logic, said the company is making extensive use of the OpenTelemetry agent software created under the auspices of the Cloud Native Computing Foundation (CNCF) to make it simpler to instrument IT environments. That data is not only being used to improve application performance but also to surface anomalies indicative of a security breach, he added.

    As part of this ongoing security effort, Sumo Logic this week also added Sumo Logic AWS Quick Start integrations for rapid access to security and compliance insights along with support for Amazon Inspector, a vulnerability management service provided by AWS.

    AWS this week named Sumo Logic as its independent software vendor (ISV) partner of the year. The two companies have a longstanding relationship that began with Sumo Logic’s decision more than 10 years ago to build a monitoring platform hosted on the AWS cloud.

    As IT monitoring tools continue to evolve into observability platforms, Gerchow said it’s becoming much easier to leverage machine learning algorithms and open source agent software to identify the root cause of an issue before it results in a major disruption.

    Most IT teams today are still relying on legacy monitoring tools that only tack a set of predefined metrics to identify when a specific platform or application is performing within expectations. The metrics tracked generally focus on, for example, resource utilization. In contrast, observability combines metrics, logs and traces—a specialized form of logging—to instrument applications in a way that makes it simpler to troubleshoot issues.

    Observability, of course, in one form or another, has always been a core tenet of DevOps best practices. Initially, DevOps teams focused on continuous monitoring as the most effective way to proactively manage application environments. However, it can still take days (and sometimes weeks) to discover the root cause of an issue. Observability platforms promise to make it easier to manage IT environments even as the overall complexity of those environments continues to increase.

    It’s not clear at what rate IT organizations will be transitioning to observability platforms. However, it generally takes only one major outage before IT organizations start looking for better tools to manage their IT environment. As those IT environments become more complex, the probability that there will be a significant disruption is now higher than it’s ever been. The challenge and the opportunity is to find a way to instrument applications more widely; the expectation being that an observability platform will be able to analyze telemetry data to reduce the number of issues that lead to service disruptions.