Category: DevOps Culture

  • Is DevOps in the Enterprise Real?

    Is DevOps in the Enterprise Real?

    Is DevOps in the enterprise real? The short answer is yes, but you may assume it’s only relevant to the world’s leading cloud companies because they’re the ones that make the headlines. DevOps offers the promise of agility, quality and ultimately better-performing software. While DevOps processes can increase agility, and agile approaches are a great help in improving responsiveness to change, the overall process still needs a clear objective, measurable KPIs and a finite scope.

    In other words, unlocking the promise of an agile (product) organization requires a few complementary approaches. If those are ignored or applied incorrectly, DevOps agility can become an impediment to adaptability and agility for your enterprise.

    Yet, I’ve read so many blogs about how the cloud and DevOps processes solve problems. It’s true they can, but the nuance is that, while a few teams can coordinate change amongst themselves, when you attempt to deploy a DevOps practice at scale, challenges are quickly apparent. For example, if I’m working for a startup that has fewer than 50 developers and very few layers of management between the CTO and her team, the management and communication lines are likely short enough that strategy and direction can be conveyed directly to the teams. However, for larger organizations—where there are many often geographically distributed teams with silos of responsibility and layers of management—far more coordination and communication are required.

    In these environments, it is more likely the business will achieve agile teams but not an agile culture. This is because it’s too simple and, therefore, commonplace for these environments to execute in silos not aware of changes to other silos and where environmental constraints and dependencies are not considered throughout the development process.

    The best solution to these challenges is to focus on a cascading framework of objectives and goals. Every company has its mission-critical goals—some call them strategic imperatives, others call them (or include in them) board-level mandates—and those goals should cascade into a more refined product, program and team goals as you traverse the management tiers. This ensures the business leaders can set a strategic direction that will be measured in a certain way, and every subsequent layer below them understands how their initiatives align with supporting that direction.

    The first critical element for building a successful, sustainable DevOps culture is understanding your goals and how you’ll define and measure success.

    The next element is to establish which decisions each level of management can make autonomously. For example, risk tolerance is a strategic decision, architecture and security posture are typically defined for a product, platform-level technology decisions can be delegated to program teams and project teams can then focus on making the more granular technology decisions that will differentiate their product, service or feature.

    Finally, communication is key. This sounds trite, but communicating this cascading decisioning framework, exposing the decisions each group makes that could impact the particulars of an environment and then discussing requirements and challenges of architecture and software choices can ensure that each team, at each level, can remain agile and adapt to change effectively.

    The question is: Do you have the management rigor to dig into these challenges and own them? The answer likely lies in how important the pursuit of agility is to you and your business.

    — Ari Weil

  • Why Did DevOps Become So Popular? 3 Theories

    Why Did DevOps Become So Popular? 3 Theories

    DevOps has now been a thing for a solid decade. As we look back at the history of DevOps, it’s worth asking: Where did DevOps come from, and why did it take off when it did?

    In honor of the 10-year anniversary of DevOps, I’d like to explore these questions.

    A Brief History of DevOps

    The very basic history of DevOps goes like this: First, there was agile, an idea exemplified in the Agile Manifesto that gained prominence among software developers in the early 2000s.

    Then, in 2008, Patrick Debois, a developer from Belgium, conceived of DevOps as a way to improve upon the agile concept by encouraging developers to work more closely with ITOps teams. His ideas began spreading in 2009. By the early 2010s, they had gained a sizable following and the rest is history.

    That, again, is a really basic history of DevOps. For more detail, I recommend this DevOps history post by Steve Mezak.

    Why DevOps? Why Now?

    The narrative of how DevOps originated is one thing. Explaining why DevOps became so popular in a relatively short span of time is another.

    As I see it, there are three possible theories to explain the rise of DevOps over the past decade. The first is to argue that Debois simply happened to have some very good ideas, and he promoted them well. You could think of this as the great man theory of DevOps’ origins. This seems to me, however, to be an unlikely explanation. It’s very rare for highly influential ideas to be born from just a single mind, or to spread through the singular efforts of one person.

    The second possible explanation for why DevOps became popular is it is simply an evolved form of agile. This is like arguing that World War II was simply a continuation of sorts of World War I, and therefore the origins of World War II are ultimately the same as those of World War I. From this viewpoint, the history of DevOps is really the history of agile, and so DevOps itself doesn’t have a unique history at all. I’d find this argument compelling if I believed DevOps is really just agile by another name, but I don’t. DevOps is broader, and has a much stronger implementational and practical element.

    The third theory—and the one I find most persuasive—is DevOps was born out of a particular moment in the history of computing and IT. That moment, which started in the mid-2000s, was marked by several key features that helped give rise to DevOps, including:

    • The widespread adoption, starting circa 2007, of cloud computing.
    • The success of the open source software movement around 2010 in making open source the go-to licensing strategy for many popular software projects and in making collaboration around code easier.
    • The rise beginning around 2010 of microservices and containers, which made applications much more complex to design, deploy and manage.
    • The explosive popularity of mobile computing starting with the launch of the iPhone in 2007. The mobile revolution meant organizations increasingly had to deliver software for multiple target environments (PCs, Android phones and iOS, for example) at the same time, necessitating branched delivery pipelines.
    • The demand for ever-increasing speed in software delivery as a way to gain an edge in software markets which, by the late 2000s, had grown more competitive than ever.

    When you put these changes together, you end up with a need to manage much more complex, fast-moving software delivery pipelines. Powered by cloud infrastructure and microservices architectures, the software market starting around 2010 required more responsive, better coordinated management by IT teams. DevOps provided an answer by increasing efficiency, decreasing response times and making software delivery faster.

    I don’t think DevOps would have taken off if the idea had emerged in the 1990s, when there was much less demand for fast software delivery, most applications ran locally and codebases were relatively simple.

    Nor am I sure DevOps would prove as popular if it were first introduced today. At present, we have a litany of management tools (such as Ansible and Kubernetes, to name a couple of examples) that didn’t exist 10 years ago. Those tools make it easier to handle all of the complexity of modern software environments even if you don’t have a management strategy rooted in DevOps culture.

    To put it simply, DevOps resulted from the combination of several specific developments in the world of IT between the mid- and late-2000s. Debois may certainly deserve credit for helping to spread the idea, but it would not have spread so quickly if it had not emerged at that particular time.

    — Chris Tozzi

  • DevOps at the Speed of Business: 5 Tips for Success

    DevOps at the Speed of Business: 5 Tips for Success

    It’s an exciting time to be an engineer. With companies today moving faster than ever, engineering teams are developing and deploying new code daily, continuously improving and advancing the business. But while the pace of modern development creates new opportunities for engineering teams, it introduces new challenges as well—in particular, making sure new code releases don’t bring the system crashing down. With more code comes more opportunity for error.

    When organizations scale fast, the challenges compound. As the engineering team grows to keep pace with expanding business, it becomes more difficult to keep track of the new code being developed. This lack of visibility can frustrate even the best teams. Without a clear view into what changes are being made, it becomes more difficult to fix them when something goes wrong.

    What do you do? Here are five key DevOps practices critical for organizations scaling fast:

    Put a Premium on Collaboration and Communication

    DevOps teams, no matter their size, need to be able to share information easily and quickly. When a problem occurs, forensics and root cause analysis must be performed as fast as possible, and engineers need to be able to annotate events that occur within the product deployment stream. Most companies already have the tools to do this, but they often fail to communicate what they find. Opening lines of communication between disparate, often geographically dispersed teams enables everyone to expand beyond their own knowledge base and capabilities to help one another. When everyone can share their knowledge, it raises the collective talent of the entire engineering community, creating a more collaborative learning environment and a culture of sharing.

    Democratize the Tools

    Tools that are accessible only to a small group of power users always fail. There’s not a person in the world who wants to put hours into teaching themselves a new tool if it isn’t approachable and interesting. That’s trouble, because the fewer people that understand how to use a given tool, the more difficult it is to use it to fix a problem. For example, if the ability to query log files is limited to the three engineers who are certified on a tool, the size of your team won’t matter; you can have 50,000 of the best engineers, but effectively, it’s a team of three. This bottleneck can have serious business consequences. Imagine you’re an online retailer having your biggest sale of the year and your website crashes. Every minute you spend finding an authorized user is a minute lost, and when the internet is your business, time is quite literally money.

    Spread Recognition of Value

    No one wants their work to go unnoticed, but recognition is a learned practice and one that requires continued focus. DevOps teams and their work save their organizations vast amounts of time and money, and business leaders should take care to highlight the value of their team’s successes, both internally and externally. Not only does it encourage their teams to work harder and smarter, impacting the entire organization, but it also lifts up DevOps teams everywhere, publicizing best practices to outside teams and creating an exponential impact across the entire engineering community.

    Don’t Just Expect Change, Embrace It

    Innovation generally happens for two reasons: The tools being used to solve problems aren’t working, or the problems you’re trying to solve have changed. Every day, companies get frozen in time—the tools they use may work now, but the world around them is changing. It’s easy to get caught in a cycle of developing new products, but what if the tools your business uses to solve problems are out of date? When engineers make changes in the code, they must be in lockstep with every other department, from QA to customer service. Organizations that embrace change always will have a leg up on the competition.

    Capture Your Knowledge Base

    As business scales, their teams scale with them. What once may have been a two- or three-person DevOps team becomes a 40 person machine, and with scale comes a lack of coordination. More and more, DevOps teams are scattered across the globe, in offices and remote, and no two people have the same workflow. In this fragmented environment, it becomes imperative for companies to keep a store of knowledge their engineers can reference wherever they are, whenever they need to.

    Fostering a strong DevOps culture isn’t easy, but it’s necessary. At its core, DevOps is about collaboration and communication—companies that treat each team as separate units risk siloing their employees, creating closed information channels that are difficult to break through in times of crisis. Whether you’re pushing new code or bringing your business back online, timing is everything and engineers need to be able to move at the speed of business. These five tips won’t fix your code or craft new features, but they’ll certainly ease the process.

    — Dave McAllister

  • Transforming the Security Team Into a DevOps Partner

    Transforming the Security Team Into a DevOps Partner

    Securing DevOps environments is an increasingly important concern for chief information security officers (CISOs) and security teams. While developers often recognize security is important, it is not their top priority. More typically, the DevOps team prioritizes delivering new capabilities and features to the business and customers, often as part of a larger digital transformation initiative. And, developers often view security as something that will slow down deployments.

    Security teams usually have limited DevOps knowledge or expertise. Too often the result is that DevOps adoption begins and even takes hold inside an organization before the security team gets involved. Consequently, security vulnerabilities are not always adequately addressed in DevOps environments and can drive unnecessary risk.

    Integrating Security in DevOps

    The priority is for the security team to take the lead in integrating security into the DevOps processes before poor practices become entrenched. But as both teams are often siloed and don’t tend to work collaboratively, how can security teams better engage, energize and collaborate with their DevOps counterparts to strike the right balance? In a nutshell, how can organizations bring their DevOps and security teams into alignment and establish collaboration for stronger overall security?

    There are a few crucial steps to take to achieve true integration of security and DevOps.

    1. Establish the Requisite Skills to Get in the Driver’s Seat. Effective collaboration requires effective communication. While developers write the actual code, it’s important for security teams to gain knowledge about programming languages along with how applications are built, tested and deployed automatically. This will help them have more meaningful discussions and credible conversations. Security professionals can start by learning some of the fundamentals: PowerShell, Python and Rust, as well as how DevOps tools use REST calls and containerization technologies–particularly Docker and Kubernetes.
    2. Make it Easy for Developers to Do the Right Thing. You can’t be the manual cog in their completely automated process. Make it easy for developers to do the right thing by training them in secure coding practices and implementing a self-service model for security capabilities. For example, you could provide security policy as code that can be integrated into the developers’ automated processes.
    3. Establish Effective Ways to Collaborate. Set up formal systems to ensure DevOps practitioners understand security risks and implement good security practices across the organization. Consider how best to deploy security resources into existing or new organizational models and structures. This includes establishing centers of excellence, community leaders, security champions and embedding security team members inside development teams.
    4. Get Developers to Think Like Attackers. Educate DevOps teams on specific attacker tactics, show how sample code modules could expose secrets and provide examples as user stories. For example, “As an attacker, I would scan the organization’s code repositories looking for secrets.” Take the team through a penetration testing exercise or engage a red team to demonstrate how an attacker would compromise a CI/CD pipeline.
    5. Adopt Agile and DevOps Methods. Security should begin utilizing agile and DevOps methods within their own teams, not only to gain a deeper understanding of DevOps methodologies but also to achieve greater efficiency by automating tasks or delivering capabilities in smaller increments more frequently.

    The bottom line is, it is crucial to understand how other enterprises approach secrets management challenges across DevOps and cloud environments. This can help encourage collaboration and help fast-track the security team’s own efforts. Ultimately, this will ensure agility is not just implemented for the sake of innovation, but companies reflect on their processes and prioritize security to make the most of their transformation.

    — Josh Kirkwood

  • 3 Reasons Why DevOps Is More Popular Than Ever

    3 Reasons Why DevOps Is More Popular Than Ever

    How popular is DevOps? More popular than ever, if Google Trends is to be believed. Here’s a look at how the popularity of DevOps has increased over time, and what has driven the change.

    The Spiking Popularity of DevOps

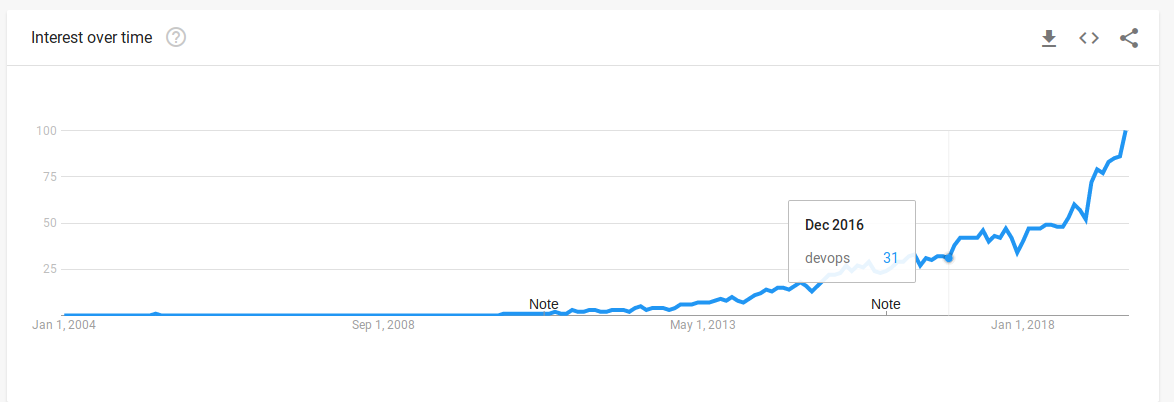
    Here’s what Google Trends tells us about interest over time of the term “DevOps” over the past 15 years:

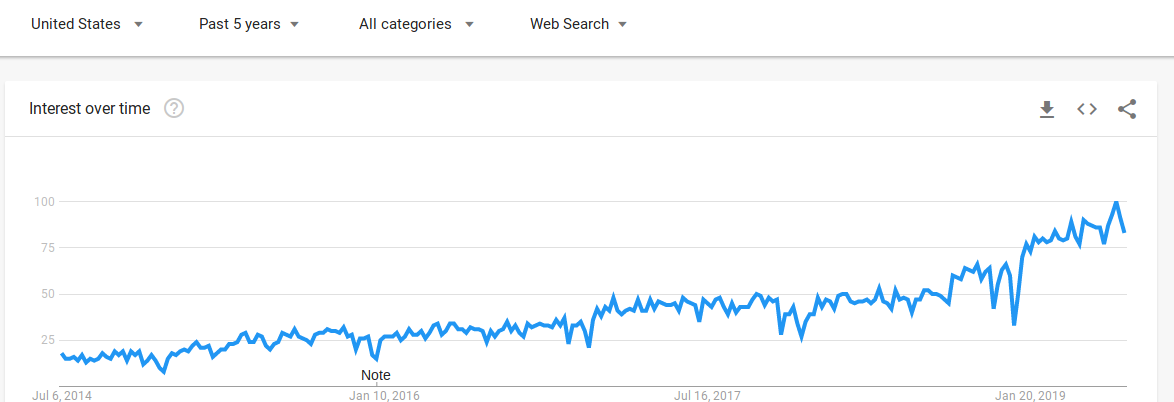
    And here’s the data for the same term over the past five years:

    As you can see, talk about DevOps began circa 2010 and increased steadily thereafter. But it wasn’t until early 2019 the interest in DevOps sharply increased.

    Granted, Google Trends is a crude, closed-source data source. And interest in DevOps as measured by Google is certainly not a straightforward representation of things such as the economic importance of DevOps or the influence of DevOps within programming communities specifically (as compared to within Google’s user base as a whole).

    Why is DevOps More Popular Than Ever?

    Still, I was surprised to see such a large and sudden spike in interest in DevOps starting early this year. I can’t think of any singular event that explains the trend. But I can think of several longer-term factors that, when added together, probably have been responsible for ushering in a world where more people than ever are talking about DevOps.

    One is the fact that DevOps finally seems to have made its way into mainstream computer science and IT education. Here, I’m speaking a bit anecdotally. I’m not aware of any surveys of how many universities overall include DevOps in their curricula. But I can attest it is at least mentioned in some of the CS and IT courses at the technical university in the U.S. where I teach. To my knowledge, this was not the case just a few years ago.

    What this means is the university is now graduating students who are already familiar with DevOps as they enter the workplace. They are spreading the gospel of DevOps to organizations that have not already heard it, and they are reinforcing it where it is already present.

    Another factor at play, I think, is the market for DevOps tools has matured and consolidated. Even just five years ago, most companies talking seriously about DevOps were startups. Now, many of those startups have become hugely successful independent companies (such as Slack) or have been acquired (such as Wercker or Electric Cloud) by larger organizations.

    To be sure, plenty of other DevOps startups have failed or stalled. But the fact that others have succeeded spectacularly has done much to drive continued interest in DevOps.

    Last but not least, the tooling for DevOps has matured along with the market. Circa 2010, when the conversation about DevOps was getting started, it was much easier to talk about de-siloing your IT organization than it was to break down the silos in practice. At the time, DevOps-friendly collaboration tools had not yet gone mainstream. Release automation suites were also mostly limited to PaaS-style offerings whose features amounted primarily to automating deployments. They lacked the end-to-end integration, testing, building and management features of modern DevOps release tools. And many of the more advanced DevOps release platforms were built by startups, which made adopting them somewhat risky (because you could end up with a platform of a vendor that went out of business suddenly).

    Today, in contrast, there is a litany of mature, feature-rich CI/CD tools to choose from—not to mention communication and collaboration solutions such as Slack and GitHub. It’s very easy to build a DevOps toolset, and you no longer have to rely on new, market-untested solutions to do so. This fact, too, has helped make DevOps more popular than ever.

    How will the popularity of DevOps change from here? My guess is it will continue to rise as the market and DevOps tooling mature even more, and as DevOps continues to make its way into mainstream educational programs.

    — Chris Tozzi

  • Digital Transformation Drives C-Suite Discord

    Digital Transformation Drives C-Suite Discord

    In the sport of rowing, each crew member has to row in synchrony or the boat risks undesired turns and even potential tipping. It takes practice, communication and discipline for each crew member to raise their oar to the appropriate height and apply the appropriate power. Obviously, those crews who work best together are more likely to win.

    When it comes to winning at digital transformation, the same is true for the executive crew or C-suite. However, the drive to  digitally transform enterprises rapidly puts a strain across C-suite relationships.

    That’s the main takeaway from a new report published by the Financial Times Focus and business management software provider Apptio, “Disruption in the C-suite.” The report is based on a survey of 555 senior executives, about half in CxO roles and from Australia, Denmark, France, Germany, Italy, Japan, the Netherlands, Norway, Spain, Sweden, the UK and the U.S.

    The survey found considerable uncertainty regarding the IT department’s ability to be effective. In fact, 51% of respondents said they have concerns about IT’s ability to govern cloud adoption. And, surprisingly, less than one-fifth of companies using agile have defined performance indicators they use to track their results.

    Further, 47% of leaders surveyed agreed digital transformation has blurred work responsibilities throughout the C-suite. And the same number of respondents admitted digital transformation has exacerbated strategic differences among finance and IT leaders. In fact, 71% of finance leaders said the IT function needs greater influencing skills to deliver the change their business requires.

    According to the survey, while the CFO was the least deeply aligned member of the C-suite crew with the CIO, the lack of deep alignment with the CIO’s office and other C-level executives was shown to be disturbingly common. Only 56% of CEOs reported being deeply aligned with the CIO, the survey found.

    There are signs of hope. Eighty-seven percent of respondents in the U.S. said digital transformation has increased collaboration across C-level executives when it came to developing new products and services.

    Still, 63% of those surveyed said the IT function needs greater influencing skills to deliver the change their business requires.

    That lack of influencing skills—and lack of defined metrics to measure progress—has taken its toll. About one-third of CFOs said there is a lack of consensus among CxOs when it comes to how to measure the impact of new technologies.

    It’s interesting, 56% of respondents said they shift their IT strategy continuously as their technology leaders receive input from the business and customers. That’s hopefully advantageous, but with so much digital transformation discord among technology and business leaders within organizations, it’s a coin flip whether that’s good stewardship or blind steering.

    It’s absolutely vital that organizations get their digital transformation efforts right, and to also be able to do so successfully at the necessary speed. As we covered in the recent story, “Digital Transformation Vital for Business Survival,” 78% of organizations believe their company’s primary industry is evolving rapidly and digital transformation is necessary to survive the changes underway.

    Those businesses cited enhanced customer experience and customer relationship management, the ability to maintain competitiveness, enabling new ways of doing business, increased productivity, cost savings, increased revenue generation and enhanced product development.

    Few would doubt the accuracy of that assessment, nor that the entire C-suite crew must be in synchrony, understand each other’s roles and objectives and know where the entire team is heading. Otherwise, the entire effort is likely to veer off course.

    — George V. Hulme

  • What Quality Metrics Matter Most for DevOps?

    What Quality Metrics Matter Most for DevOps?

    The way we develop and deliver software has changed dramatically in the past five years—but the metrics we use to measure quality remain largely the same. Despite seismic shifts in business expectations, development methodologies, system architectures and team structures, most organizations still rely on quality metrics that were designed for a much different era.

    Every other aspect of application delivery has been scrutinized and optimized as we transform our processes for DevOps. Why not put quality metrics under the microscope as well?

    Are metrics such as number of automated tests, test case coverage and pass/fail rate important in the context of DevOps, where the goal is immediate insight into whether a given release candidate has an acceptable level of risk? What other metrics can help us ensure that the steady stream of updates don’t undermine the very user experience we’re working so hard to enhance?

    To provide the DevOps community an objective perspective on what quality metrics are most critical for DevOps success, Tricentis commissioned Forrester to research the topic. The results are published in a new eBook, “Forrester Research on DevOps Quality Metrics that Matter: 75 Common Metrics—Ranked by Industry Experts.”

    The goal was to analyze how DevOps leaders measured and valued 75 quality metrics (selected by Forrester), then identify which metrics matter most for DevOps success. Here’s a look at the process:

    1. Survey 603 global enterprise leaders responsible for their firms’ DevOps strategies.
    2. From that sample, identify the firms with mature and successful DevOps adoptions (157 met Forrester’s criteria for this distinction).
    3. Learn what quality metrics those experts actually measure and how valuable they rate each metric they regularly measure.
    4. Use those findings to rate and rank each metric’s usage (how often experts use the metric) and value (how highly experts value the metric).
    5. Compare the DevOps experts’ quality metric usage versus that of DevOps laggards. If there was a significant discrepancy, the metric is considered a DevOps differentiator.

    The 75 DevOps quality metrics were divided into four categories:

    • Build
    • Functional validation
    • Integration testing
    • End-to-end regression testing

    For each category of quality metrics, we came up with a heat map showing usage versus value rankings. For example, here is the heat map for the Build category metrics.

    We also plotted the data for each metric into a quadrant with four sections:

    • Value Added: Metrics that are used frequently by DevOps experts and consistently rated as valuable by the organizations that measure them.
    • Hidden Gem: Metrics that are not used frequently by DevOps experts but are consistently rated as valuable by the organizations that measure them.
    • Overrated: Metrics that are used frequently by DevOps experts but not rated as valuable by the organizations that measure them.
    • Distraction: Metrics that are not used frequently by DevOps experts and not rated as valuable by the organizations that measure them.

    For example, here is the quadrant for Build category metrics:

    The eBook provides both heat maps and quadrants for all four categories, a quick look at each of the 75 metrics per-category and overall analyses, as well as a few fun lists.

    Here’s a preview:

    Hidden Gems

    The following metrics are not commonly used (even among DevOps experts), but are ranked as extremely valuable by the select teams who actually measure them:

    1. New defects (IT)
    2. Critical defects (FV)
    3. Automated tests prioritized by risk (Build)
    4. Code coverage (Build)
    5. Test cases executed (Build)
    6. Static analysis results (Build)
    7. Variance from baselines of percent of test cases passed (E2E)
    8. Release readiness (E2E)

    Top DevOps Differentiators

    DevOps experts/leaders measure the following metrics significantly more than DevOps laggards measure them:

    1. Automated tests prioritized by risk (Build)
    2. Percent of automated E2E test cases (E2E)
    3. Risk coverage (IT)
    4. Release readiness (FV, IT, E2E)
    5. Test efficiency (FV and IT)
    6. Requirements covered by tests (Build, FV, IT, E2E)
    7. Test case coverage (Build, E2E)
    8. Static analysis results (Build)
    9. Variance from baseline of percent of test cases passed (E2E)
    10. Test effectiveness (FV, IT, E2E)

    Most Used by DevOps Experts

    The following metrics are the most frequently used (overall) by DevOps experts/leaders:

    1. Test case coverage (E2E)
    2. Pass/fail rate (FV)
    3. API pass/fail rate (IT)
    4. Number of tests executed (E2E)
    5. API bug density (IT)
    6. Requirements covered by tests (FV)
    7. Requirements covered by tests (E2E)
    8. Blocked test cases (FV)
    9. Percent of automated E2E test cases (E2E)
    10. Successful code builds (build)

    Most Valued by DevOps Experts

    The following metrics are the most highly valued (overall) by DevOps experts/leaders:

    1. Requirements covered by API tests (IT)
    2. Percent of automated E2E tests (E2E)
    3. Requirements covered by tests (E2E)
    4. Requirements covered by tests (FV)
    5. Count of critical functional defects (FV)
    6. Total number of defects discovered in test (E2E)
    7. Number of test cases executed (E2E)
    8. Pass fail rate (FV)
    9. New API defects found (IT)
    10. Automated tests prioritized by risk (build)

    — Cynthia Dunlop

  • DevOps Is Killing the ITOps Engineer (and That’s Bad)

    DevOps Is Killing the ITOps Engineer (and That’s Bad)

    In theory, DevOps is about bridging the gap between developers and ITOps teams. In practice, however, DevOps often can feel as though its real goal is to turn ITOps engineers into developers, without really requiring developers to dive head-first into ITOps work.

    In this article, we’ll explain why DevOps gives more glory to development work than to ITOps, and how that poses a problem to the DevOps world as a whole.

    In DevOps, Developers Come First

    We live in a world that fetishizes code and the creation of code. Developers fetch among the highest salaries in IT. The work they do is sometimes compared to magic. There are a litany of boot camps designed to teach people to code. From Silicon Valley to The Social Network, coders are depicted in popular media as whiz kids who are building a fantastical world the rest of us can’t even imagine until the coders hand it to us.

    By comparison, ITOps engineers—people whose main job is to deploy and manage software, not write it—get much less glory. I’ve yet to hear of an ITOps boot camp. Generally speaking, ITOps employees get paid much less than developers; some ITOps workers, such as those who do help desk work, barely make minimal wage. And no one makes movies where an ITOps engineer saves the world by rebooting a crashed server or applying the latest security patches.

    This trend is problematic, of course, because the work performed by ITOps is equally critical as development work for sustaining our digital world. Without ITOps teams, all of the code developers get paid so much to write would be useless because there would be no one to put it into production and keep it running when it’s there.

    There are many possible explanations for our tendency to celebrate programmers much more than the people who manage the software programmers build. The most important reason, I think, is we live in a world where creators of all types are generally held in greater esteem than maintainers. That’s true in a variety of fields, from building science (where architects who design structures are held in much higher regard than, say, the roofers and painters who maintain them) to the automotive industry (the white-collared engineers who designed your car are probably paid a lot more than the grit-streaked mechanic who changes your oil). The IT industry is not special in this regard.

    DevOps as Euphemism for ‘Everyone Should Program’

    The fetishization of programming would probably happen even if DevOps didn’t exist. But sometimes, I think DevOps is exacerbating the tendency to deny ITOps teams their fair share of prestige.

    Beneath the surface of many conversations about DevOps culture and continuous delivery is the idea that if only ITOps engineers knew more about how to write code and discuss code with developers, their organizations would be better positioned to deliver software more quickly while also improving quality.

    In my experience, it’s much rarer to find DevOps advocates interested in pushing developers to play a more hands-on role in ITOps work. Almost no one goes around saying, “If only developers spent more time provisioning infrastructure, software delivery would be more efficient.” And when they do, they are accused of trying to kill the developer by requiring programmers to participate in maintenance-related tasks below their pay grade.

    I’d therefore suggest one of the challenges DevOps faces today is not killing developers, but killing ITOps engineers and further devaluing the work they do. To keep advancing DevOps, we need to pursue greater parity between developers and ITOps teams within DevOps culture.

    — Chris Tozzi

  • JFrog swampUP: DevOps Culture Is a Powerful Force

    JFrog swampUP: DevOps Culture Is a Powerful Force

    The notion that culture is such an important part of DevOps and high-performing IT teams gets plenty of lip service, but not every organization really buys into it. In my years covering the DevOps space, I can count only a handful of companies that truly represent the epitome of “DevOps culture.” One of these companies is JFrog.

    Every time I have the chance to interact with “the Frogs” and their community, I am reminded of what a powerful force culture can be in forging success. At the recent swampUP user conference in San Francisco, the JFrog secret sauce was again on display. From the little things, such as designing and decorating the conference themselves, to the bigger things in terms of the theme of the sessions and activities, swampUP was a great and learning time for all. Our Digital Anarchist team was on hand and we did a bunch of videos that you can watch up on DigitalAnarchist.io. The videos are with speakers at the conference, attendees, JFrog employees and partners.

    One of my favorite videos from swampUP was the one I have embedded here. It is the three co-founders of JFrog—Yoav Landman, Fred Simon and Shlomi Ben Haim and I discussing business and what makes JFrog’s culture so special. Have a listen and maybe get some insight into making the culture of your own organization better.

    Also, if you are in Israel Sept. 24, check out Yalla DevOps, a first-time conference JFrog and others are producing that looks like it will be a great event. The Digital Anarchist team will be there covering with video (even broadcasting live), along with John Willis as a keynote speaker; Jayne Groll, my co-founder at DevOps Institute; and others.

    In the meantime, enjoy the video:

    Transcript

    Alan Shimel: Hey, everyone, it’s Alan Shimel for devopsy.kinsta.cloud on Digital Anarchist, and we’re here in San Francisco at JFrog swampUP 2019. It’s been a great conference, and I’m really, really lucky and happy to be joined—I feel like I’m at a Beatles reunion, for some reason. I’ve got Ringo, Paul, John—

    Shlomi Ben Haim: Who’s John Lennon? I’m afraid. [Laughter]

    Shimel: – done. Anyway, but no, we’re not at a Beatles reunion, but we do have the three JFrog co-founders here with me. I’m gonna let them introduce themselves. We’re gonna go to the far right to Fred. Fred, go ahead.

    Fred Simon: Hi, I’m Fred Simon, co-founder and Chief Data Scientist today at JFrog and I’m really happy to be here. Thank you.

    Shimel: Thanks, Fred.

    Yoav Landman: Yoav Landman, CTO and co-founder of JFrog.

    Ben Haim: I’m Shlomi Ben Haim, CEO and co-founder of JFrog.

    Shimel: Three co-founders on one panel—there you go. So, guys, first of all, congratulations on another great event.

    Simon: Thank you.

    Shimel: You know, you know this, but you guys don’t know this—my wife wants to come work with you.

    Simon: [Laughter]

    Shimel: Because she loves the company and the culture and the buzz that she gets when she’s around the Frogs that, you know, when she grows up, she wants to come work at JFrog.

    But all kidding aside, it’s a tremendous—you can’t come to a JFrog event, whether it be swampUP or SwamPower or Meetup or whatever without kinda feeling the love, right? Feeling that culture. And it’s an interesting dynamic. Take it from me—I go to a lot of conferences, I deal with a lot of companies. They don’t all have that. They don’t have that culture.

    So, I wanted to talk a little bit about—look, 2009, you started Artifactory, right? What was the idea on the culture, here? How do you instill that culture—not in the community, right now. Let’s talk about the company, because every high performing team ranked culture as important. How do you instill that pride to be a Frog, we’re all in this together, we’re making the world a better place? Who wants to answer?

    Simon: You want to start? You started this mess! [Laughter]

    Yoav Landman: So, yeah, Artifactory started before JFrog. So, Artifactory was there to solve a real pain, and we were all developers, and it’s our second—except for Shlomi—it’s our second venture.

    So, I guess this idea of solving pains, being very connected to the community, to customers, speaking a lot with customers, getting feedback from every engineer and every employee in JFrog that comes and says that they think that something should work differently or that we should develop something that may contribute to more success of our product is something that is instilled into the culture of JFrog.

    Shimel: Excellent.

    Simon: Yeah, we got lucky that everybody else who is working at JFrog is working for someone like him. So, that’s scratching our own itch. So, at the end of the day, you are a developer at JFrog and you hear about a customer having an issue, you feel it, because this is your job. You’re writing code, you’re a developer, and you know that what you are doing is impacting people. And so, this strong care about the customer and the strong feedback of the culture was here right from the beginning.

    And then Shlomi one day decided, “Oh, that’s too big, too full of a culture. I’m gonna try to write it down.” [Laughter]

    Shimel: [Laughter] And Shlomi, with all due respect, you like to deflect and you let him talk, but you’re the CEO. At some point, the buck stops here, right? You know, it’s important to you, but how do you build this culture? How do you get this loyalty, this feeling of buy-in from people?

    Ben Haim: That’s, you know, I’m listening to the question and I’m  getting excited like it’s my first day at JFrog. I think culture matters. Everybody knows that, everybody said that. But it’s hard to practice. It’s hard to maintain it for 10 years. And this—this goes back 18 years. I think I’m with these guys before I got married, and what you see in JFrog is that when you have the right culture, it’s viral. But it’s not just an internal move, it’s also reflecting outside of the company.

    And you spoke about Artifactory and how it started, and when we started, the only thing that we had was the technology that we believed in and ourselves. And it’s very hard to start a company when nobody understands what you do on the technical level, nobody understands what’s the pain. There is no budget line for it. So, the only thing that you can fight with is your team.

    Shimel: Right.

    Ben Haim: And just yesterday, as we set up this amazing conference here, I saw more than 70 JFrog employees. You know that we do our conferences ourselves.

    Shimel: Right.

    Ben Haim: No producers, it’s just us. Our team built it for the community. And I saw them here walking, and it doesn’t matter whether it’s building Artifactory or Xray or JFrog Pipelines or JFrog Distribution or swampUP—same culture, same values, comes over and over again as our one very big advantage.

    Shimel: Absolutely. But now—so, that in and of itself is fantastic, right? But now, there’s a second key ingredient to the success. How do we take that culture that we built at JFrog and let the community, infect the community with it, right, to use a security term? How do we transform the community with that same—not transform, infuse that community with that same culture, with that same passion?

    Because that’s something that always, again, it screams, right? It’s easy to see. And building that kinda community is not easy, because at the end of the day, today’s software world with open source and everything else is community, right? It’s all about—so how, is that something that’s done on purpose? If so, how? What do we do?

    Landman: I can try and start.

    Shimel: Go ahead, Yoav.

    Landman: So, part of being driven by input is also being very direct. And it all comes down to people—at the end of the day, it’s all people. So, the way that we interact with the community, the way that we interact with customers is not very much different than the way we interact internally in JFrog.

    So, by bonding with people, by investing in clear and open discussions with no fluff, I think that drives results, at the end of the day.

    Shimel: Fred?

    Simon: First of all, I don’t think it’s intentional. I mean, it’s just the way we are and the way—and it’s pure and it’s just true, okay? We truly care about the suffering of our customer, and the customer feels it. So, once he feels it and then he’s part of it—and sometimes, it’s a little bit disturbing for the customer, because the customer feels like he’s gonna get more help and better integration with the JFrog community and with JFrog than with his peers inside the company, because of the [Laughter]—

    Shimel: Yeah, exactly.

    Simon:  – some cultural clash between the company and JFrog. And so, by, you know, not saying, “Okay, whenever a customer is telling you something, just be compassionate”—we never told our employees, “Please be compassionate about the customer.” This is just, this is who we are, and this is what the—and they see, and the customer feels it, and he sees the effort we put to make sure that… And it’s like here, the communication, also. The effort of communication, the effort of knowledge, knowledge transfer. We are not shy on transferring what we know, what we need, what we did. It’s just—yeah, I think truth and natural truth is a [Cross talk].

    Shimel: So, the word that comes to my mind is genuine, right? You can’t fake this. It has to be genuine. And if it’s not genuine, people see through it and it smells, right? So, I think that’s a key ingredient of that, for sure.

    And the transfer, too—I mean, I’ve done, I don’t know, maybe 10 interviews, 12 interviews, maybe more today, to a lot of customers. And that knowledge transfer and sharing in this kinda—it’s huge to them.

    So, now—so, we’ve got the culture to the community. Now, we’re gonna talk, Yoav, you said Artifactory existed before there was a JFrog, right? It’s 10 years, right? In technology terms, that’s like dog years, it’s 90 years, you know? It’s almost 100 years old already.

    Landman: Frog’s years. [Laughter]

    Shimel: Frog years. How do you—so, obviously, the Artifactory today is not Artifactory, what it was.

    Landman: For sure.

    Shimel: JFrog today is not what JFrog was. We mentioned something things—JFrog Pipelines, there was the Shippable acquisition, Xray came out about two years ago now, right? Two, three years ago—Xray. JFrog today—let’s talk about the technology, the tools, the solutions. What are you most—you’re CTO, Yoav. What are you most proud of with that?

    Landman: Artifactory was the centerpiece and it still is. It’s the place where you put—we call it the golden bits. It’s what you’re going to, at the end of the day, put in production, right? But the world has changed dramatically since Artifactory was written. It was just a very basic Maven remote proxy. And then other features came about, but the whole DevOps and the whole pipeline automation process that we’re seeing today within companies, it didn’t exist back then to the same level of automation.

    So, bringing in security into the pipeline is an integral part, with Shippable, making sure—we can maybe talk about this later—making sure that we can drive the pipeline, adding functionality to give you insights into the pipeline. These are all things that came along and are going to be injected into the pipeline from JFrog, from other companies, but this is the natural evolution. Artifactory is still the base of what you’re going to shift, but all the services around it is what makes JFrog a lot bigger and why it’s very different than what we started.

    Shimel: Fred, I wanna come to you in a second, but I have a follow up question for Yoav. So, Yoav, I think another great example is—so, in the last year, you announced you’re gonna start a repository for Go, yeah? And so, that’s an example of, you see what the community is doing. I spoke yesterday to a Microsoft fellow here who’s, like, their advocate for the Go community—so happy to be here because JFrog’s supporting him with that.

    Where does that come from? Like, where—the idea of saying, “Hey, we should do something for Go?”

    Landman: So, it comes from, I think, two angles. The first is purely technical, just being able to be there first. The other one is, I think, a little bit cultural, just being able to instill innovation into the company, even before the market adoption happens. And it kind of goes together. Both goals, they serve one another. So, we did the same, by the way, with Docker. With Docker, we had support for the Docker beta versions, even before Docker was a thing.

    And the same thing we wanted to do with Go, even when the standards were not that stable yet and we had to rewrite our implementation once the standards have stabilized. But yeah, this is the source of this motivation.

    Shimel: Fred, I wanna go to Liquid Software with you, right? So, it’s a book, we can probably have someone throw us a copy for a prop, if we can get Brian maybe get us a Liquid Software book over here, it’s right by Netta.

    But you’re one of the co-authors, Yoav, Baruch is one. So, that’s another concept, right? This whole concept of liquid software and what it is. Talk to us about that. What do we—where does that come from? How does that fit?

    Simon: Yeah, so the—by the way, where it goes to Go and all these kind of communities and things like that? The origin of manipulating software and trying to put software in production into an environment, we always try to manipulate it as boxes. A box where we put a bunch of software and we try to run it. And with the advent of releasing multiple ________ multiple versions and making all those services micro-micro-microservices—basically, the flow of those packages got higher and higher and the size of the packages got smaller and smaller.

    And so, instead of thinking about it in terms of ship management and supply chain management of shipping packages, it didn’t make sense any more. It was really, really a big burden on the tagging.

    And so, when you want to put a piece of software in production, you have the final run time, which is the software in the hands of your end user, the one that really, really wants to use it. And deploying software is actually easy. You just created a new piece of software, you just run it for the first time, and it’s quite easy, and then you run. What’s hard is to update it, okay? Deploying is easy, updating is hard. And the only way to update it is to get the new version. And if you keep thinking about it in terms of blocks, you’re stuck. You need to think about it in terms of pipes and liquid and this is the liquid software. Is that, as soon as you create a run time that can receive software, you need to think about all the pipes that you need to plug to get the liquid to it and to update it continuously.

    And it changed all the way to the developer. This is—it starts from the pressure from the end users from, like you said, your wife, your daughter or whatever that wants to get the latest software all the time without any, and it put the pressure all the way to the developer. And what’s funny in our environment is that it’s hard for a developer to do it correctly, and a lot of times they said, because they are used to it, when they interact with technology, actually, the developers are a lot more, first, reluctant to update software. If you see all the developers and their phones, iOS and Android, they have the most, the oldest version, the one that doesn’t update. [Laughter] And they want to control [Cross talk].

    Shimel: It’s the mechanic’s car.

    Simon: Yes, exactly. [Laughter]

    Shimel: Never drive the mechanic’s car.

    Simon: And so, for them, it’s not that complicated to do a complicated update. So, it really comes from the pressure from the market, and life is ________ is a really good, it’s life pushing it and so liquid software is gonna happen whenever it’s gonna happen.

    But the change that we need to push is to put the tools and the mechanism and the practices into the hands of the developer. Because it’s not that hard. It’s hard, it’s some work and stuff, but it’s not as impossible as the community of developers think.

    So, it’s a book, I highly recommend it.

    Shimel: Here’s the book. We’ve got the book, thanks to the folks offstage.

    Simon: But it kind of tried to remove this fear from the developer community of writing liquid software. It’s possible.

    Ben Haim: And, you know, Alan, I think that the experience of being in a very successful company for over eight years and not being able to explain what is it that we are doing, why it’s more than just managing your binaries, why it’s more than just providing you with a better repository. And when Fred came up with this phrase, liquid software, it was one presentation that everybody in JFrog understood and immediately aligned to it. Because this is actually what we believe in. And when you go and raise your Series D and you say—

    Shimel: Which was this year.

    Ben Haim: – this last year, last October, seven months ago. And when we said—nine months ago.

    Shimel: Yeah. [Laughter]

    Ben Haim: When we said, “We are the liquid software company,” we had all kinds of eyebrows moving, and people are asking us more and more about that, because they start to understand that this is beyond just the vision of JFrog. This is where the world is going. We are just one of the enablers of the liquid software world.

    Shimel: Absolutely. So, first of all, I still can’t explain to my family what I do for a living, but that’s another story.

    Ben Haim: [Laughter] The story of my life.

    Shimel: Yeah. But, you know, in some ways, this is also the story of JFrog, because 9 years ago, 10 years ago, Artifactory, I would’ve told you, “Liquid software? What is it? What do you”—stop.

    Ben Haim: Yeah. Stop with the drugs.

    Shimel: Right. But yet, the kernel of what is liquid software according to you was there in Artifactory 10, 11 years ago. Yeah.

    Landman: The essence is.

    Shimel: Yeah. and so, it’s—you know, I learned once, what we do in technology is, 99 percent of the time evolutionary, not revolutionary. And so, this is the revolution of it.

    So, I’d like to, now, if we can—and Liquid Software is available, you can get it. The book’s on Amazon. I think it’s on—

    Simon: Audible. It’s Audible, also.

    Shimel: Yep. We had it on devopsy.kinsta.cloud on a link, too, at one time. We probably still do, obviously.

    But I wanna now turn a little bit, you mentioned D round was a couple dollars, 165,000,000—that’s not even shekels, dollars.

    Ben Haim: [Laughter] It sounds better in shekels, by the way.

    Shimel: Yeah. It’s like the speed of light. But you know what, when you raised—Yoav and I were talking earlier—you raise that kind of money, with a lot of money comes a lot of responsibility, a lot of expectations. Where does JFrog go from here, right, and how do you chart that course, right? As a CEO, CTO, developer advocate, technology—how do we, where do you, where do you go? How do you know where to go, right? You’ve got tremendous resources now at your disposal, probably more than you might have dreamed you’d have to do.

    Where do we go and how do chart that course?

    Ben Haim:  So, I’ll try to answer that from a high level and then, of course, Fred and Yoav can take it to the technology solution. I think that JFrog has done something really big. And when you see what happened in the world, it’s beyond the developer. It’s beyond the people who are actually using our solution. It’s the destination that was changed. And what people expect to have is a fast and fluid software update. And if JFrog, with 5,000 customers today and growing fast, can be the company that powers this need, then I think we have a very big story.

    So, when we raised our money—you know, when you raise such an amount with such an evaluation, you also understand that the dream about M&A and exit is kind of pushed away and the list of acquired got changed to maybe three or four companies.

    Shimel: Very small—a handful.

    Ben Haim: So, you have to go and ask your wife about it, because this is 10 years, together 30 years of investment that our family was part of this journey. And I asked Donna, my wife, and I said, “Donna, you understand that there will be no exit soon. We have to go all the way—all the way towards it.” And the answer that I got is that, “If this is really what you say it is, if it’s really changing the world, if it’s really about electricity and water and aircraft and cars and everything you do, I’m so excited about it, and I’m not even a technologist, then you guys should go after it.”

    So, I think we have made the right choice, and you’re right, there is a lot of responsibility here. It’s a responsibility not just to our VCs, but also to our employees that trust us and follow us, and also to our customers—

    Shimel: And the community.

    Ben Haim: – that comes and uses it and over and over again, we are growing at 150 new logos per month—new logos per month. These are people that adopt this solution and say, “This is what we are going to do in the next 10 to 20 years. We are making software liquid.”

    Landman: So, JFrog for a long time is not just the sum of the founders, it’s much, much bigger than that, and we have wonderful people in the company that leaped forward with JFrog and take the company forward, basically, for us and for the other investors.

    One thing that you have to understand is that, today, JFrog is taking the responsibility of serving huge organizations and our end customers are also sharing this responsibility of serving the automation for huge organizations, and the automation patterns that we are seeing, they are not constant. They are changing and they keep evolving over time.

    So, this is kind of great, an ever growing challenge for us to develop a new set of tools, a new set of solutions, new pains to cure. To tell you that we exactly know what the next pains are going to be—we don’t. If we would, it would probably be too boring to continue going, like Shlomi said. But this is basically what drives us and keeps us committed to this responsibility.

    Simon: Yeah, still a ton of work to do. I mean, the liquid software vision, there’s still a lot, a lot, a lot to do. And like Yoav said, the responsibility that we have as being a critical piece of keeping those pipes, making sure they don’t leak, making sure nobody’s injecting stuff into it. And making it happen and making the water system trusted and the software delivery trusted is a huge amount of work, responsibility, and systems that we have to create on the way, we have to build, and we have to scale to worldwide—really, worldwide impact and environment.

    So, you can say that 160 is a lot of money, and when I see the amount of things that need to be done, maybe not. [Laughter]

    Shimel: Yeah. Well, there’s always more out there. Guys, we’re way over time, but I wanted to end it with this. I sold my first company in 1997, and I sold it to, well, a guy named Brad Feld who’s a pretty well-known venture capitalist himself. But his mentor was an older Jewish man, Len Fassler—a little older, he was like my grandpa. I couldn’t negotiate against him.

    Ben Haim: [Laughter] No, it’s impossible.

    Shimel: It was like negotiating with your grandpa. But Len had good—he did several billion dollar companies, rollups and good stuff. And I then worked for him and we did 30 acquisitions in 36 months, and we wound up taking the company public in the dot cot days.

    And one of the things he always said to every founding group, whether we bought the company or not, was, “Any time you can build a company that someone’s willing to reach into their pocket to invest in and write you a check, you have a lot to be proud of,” right? To write a check for $165,00,000.00—that’s plenty to be proud of. But even beyond the money, when you look out at swampUP, when you look out at all those Frogs’ faces, you guys have a lot to be proud of, so congratulations.

    Ben Haim: Thank you very much.

    Shimel: Thanks for joining us.

    Ben Haim: Thank you.

    Shimel: And continued success. Hey, we’re gonna wrap it here in San Francisco from JFrog swampUP, this is Alan Shimel for devopsy.kinsta.cloud and the Digital Anarchist.

    — Alan Shimel
  • Top DevOps Challenges at DOES19

    Top DevOps Challenges at DOES19

    I recently attended the prestigious DevOps Enterprise Summit in London. During the three-day event, I asked people what their major DevOps transformation challenge is. I wanted to examine these at global events, asking the same question.

    I was GamingWorks’ booth boy at the event, which gave me a chance to ask a lot of delegates visiting the stand.

    Here is a summary of what they said, with my commentary based on what I have picked up on my travels as The IT Paradigmologist.

    Business Value

    • Understanding the link between IT work and the business strategy.
    • Seeing the whole end-to-end picture (visibility, transparency).
    • Measuring the right things—team performance in terms of business outcomes.

    Commentary: Not only do IT people have difficultly understanding the business value of their work, they often are poor at articulating it to business executives. My DASA white paper, “The Business Value of DevOps,” and accompanying webinar elaborate on the topic.

    Governance

    • Finding the right balance in standardization across teams.

    Commentary: Governance is such a tricky topic. What do people mean by it in the first place? How negotiable should the boundaries be? Particularly in complex and therefore unpredictable systems, professionals need to make judgment calls and act for the best. Regarding standardization, the question is always about value: Does standardization and centralization lead to significant improvements in results without introducing frustrating bureaucracy? Otherwise, you’re better off letting the individual teams decide for themselves what is most effective for their value streams. Yes, it might be more expensive than one-size-fits-all, but the benefits usually outweigh the costs.

    Velocity

    • Doing things quickly while maintaining quality.

    Commentary: It’s a question of balance. Not only speed and quality (depending how you define it, of course), but also resilient operations, co-created value and assured conformance. I like the Deloitte #BVSSH way of putting it: Better, value, sooner, safer and happier.

    Value Streams

    • Breaking down silos.
    • Collaborating better between silos.
    • Giving more autonomy.
    • Integrating DevOps parts in a predominantly non-DevOps value stream and vice versa.

    Commentary: On the conference scene, almost everybody has an idea of what value streams are. Visit an average IT department though, and for most people it’s an alien concept. We live in a bubble. You have to take a few steps back and start from where they are. Take it step by step. Collaboration seems to be one of the top challenges as confirmed by the recent DOI skills survey, which had this as a top soft skill. It may be a soft skill but it is hard to achieve. The article “DevOps and Collaboration: Fraternizing with the Enemy” provides some guidance on collaboration.

    Ops

    • Discovering a new way of doing ops.
    • Shifting from old ops to new ops.

    Commentary: This is a very hot topic. Witness the promising changes in ITIL 4. Less process, more heuristics, more value-orientation (for instance, value streams and co-creation with the service consumer) and more human. It’s very encouraging to see how DevOps communities—some more enlightened than others—are developing their ops capabilities to restore the balance. But ops work differs fundamentally from dev work, and that has to be reflected in the way of working.

    Organizational Change

    • After the initial enthusiasm, “what’s next and how?”
    • Overcoming resistance to change and inertia in general.
    • Accepting the consequences of doing DevOps.
    • Unlearning 30 years of doing the same thing.
    • Learning quickly.
    • Developing skills to transform.
    • Assessing the risk of transformation.
    • Sharing (and learning from others’) practices.
    • Upscaling.

    Commentary: There is too much lip service and too little commitment. There are notable exceptions, but too many people are looking for the quick fix and believing they’ll find it. Good luck. As Taiichi Ohno said, “You have to think for yourself and face your own difficulties instead of trying to borrow wisdom.” If you don’t know who Ohno-san is, that’s a good place to start. If you’re serious, take a look at Paul Wilkinson’s astute observations about challenges and enablers for DevOps success at DOES18 USA. You’ll notice many similarities with my findings at DOES19 UK.

    Culture and Emotions

    • Getting enough diversity in the team.
    • Getting different personalities to work together.
    • Trusting and being trusted.
    • Feeling non-DevOps teams are worth less, but not worthless.

    Commentary: More on culture and people can be had on the DOES18 blog, but it is encouraging that people are actually talking about this more often. It’s something that almost always crops up in The Phoenix Project business simulations that I facilitate for organizations. Topics such as psychological safety: whether you feel comfortable being and expressing who you are. So, do you? Dr. Christina Maslach referred to the toxicity of some workplaces with the analogy, “You want less toxic mines, not more resilient canaries.” Work-in-progress.

    Tooling

    • Understanding which tools are around (tool confusion).
    • Integrating and then orchestrating tools.

    Commentary: Finally a topic I know little about, but I wholeheartedly endorse many vendors’ socks.

    — Mark Smalley