Category: Continuous Delivery

Continuous delivery is a software engineering discipline that allows organizations to consistently develop and release quality software at a rapid pace. It is achieved by automating the software development lifecycle, enabling tasks such as development, testing and release to occur concurrently and continuously.

  • Only 30% of Orgs Fully Implement DevSecOps

    Only 30% of Orgs Fully Implement DevSecOps

    With the pressure to release more rapidly, security is shifting left within the continuous development pipeline at most organizations. This imperative is increasing with the rise of cyberattacks. Yet both a lack of training and poor visibility are stalling many DevSecOps rollouts, a recent CSA study found.

    DevSecOps is still a relatively new practice and has yet to reach maturity throughout most organizations. Though nearly all companies are on their way, only 30% of security professionals say they fully implement DevSecOps in practice today. That leaves most organizations in some state of DevSecOps ideation and planning.

    CSA recently released its Secure DevOps and Misconfigurations 2021 report which was commissioned by Trend Micro. The report found that misconfigurations commonly arise from default security settings. A lack of internal guidance and accessibility of security resources commonly hinder DevSecOps maturity, too.

    Below, I’ll review the other major takeaways from the report to see how they can inform organizations as they move to implement DevSecOps.

    State of DevSecOps Adoption

    DevSecOps is all about increasing the security around rapid deployment. It literally puts the security into DevOps by shifting security automation left and de-siloing the boundary between DevOps and IT security teams.

    While most engineers realize the benefits of DevSecOps, the state of each organization’s DevSecOps journey is very different. While an impressive 90% of organizations are in some phase of the journey toward DevSecOps, only 30% are implementing DevSecOps while 24% are in the planning phase, 18% are designing and 18% are still refining their DevSecOps strategy. Just over one in ten security professionals say their team has no plans to invest in DevSecOps at all.

    Looking to the future, 42% say they will implement full DevSecOps within the next 12 months. But due to its current nascent state, misconfigurations are still getting through. The primary reason cited for these misconfigurations was flawed or lacking internal guidance (33%).

    Many professionals say there is simply not enough training, support or internal knowledge around vulnerabilities and misconfigurations. Other top reasons for misconfigurations include insecure default settings (18%) and negligence (16%).

    Outside of misconfigurations, groups also report challenges with identity, authorization and access. Ensuring the correct privileges is vital to avoid escalation attacks, which are a prevalent issue. Between 2019 and 2020, 80% of companies experienced a data breach of some kind, many of which were due to misconfigured access controls. OWASP also reported that broken authorization is a top vulnerability for high-traffic web API endpoints.

    Common Threat Mitigation Practices

    To mitigate these threats, development and security teams must maintain best practices, yet certain issues prevent DevSecOps from emerging. For one, 60% of security professionals say their top challenge is insufficient visibility into security or compliance gaps—this is by far the most common challenge—and 11% also cite inconsistent cloud account onboarding. Finally, 10% say time-consuming, slow and/or insufficient architecture holds them back.

    One way to mitigate threats is to introduce routine security reviews more frequently. Yet it’s hard to set a definite benchmark here, as the frequency at which organizations review their cloud infrastructure for vulnerabilities or misconfigurations varies widely. Currently, 22% perform such security reviews daily, 22% monthly, 18% weekly and 23% quarterly, according to the survey. This rate will likely increase as DevSecOps becomes more commonplace and automated within the development life cycle.

    Staying up-to-date with modern security frameworks is another facet impacting DevSecOps adoption; and organizations tend to follow multiple frameworks to inform their security strategy. More than three-quarters (78%) follow the National Institute of Standards and Technology (NIST) guidelines, 67% follow the Center for Internet Security (CIS) benchmarks, 66% follow Cloud Security Alliance (CSA), 54% follow International Organization for Standardization (ISO) and 44% say they follow security recommendations from Amazon Web Services (AWS).

    For example, NIST, the government-operated standards-setting body, recently set cybersecurity guidelines that recommended the use of zero-trust and service mesh across departments. These security guidelines can be thought of as architectural benchmarks, especially for large, highly-regulated industries.

    DevSecOps Training Types

    Finally, investing in community resources and training is another way to increase DevSecOps awareness. Only half of survey respondents reported their DevSecOps best practices resources were moderately accessible—thus, the onus is on leaders to democratize such knowledge within their organization.

    The majority (81%) of respondents cited online articles and training as their primary form of learning about cloud security tools and vendors. Workshops, conferences and webinars follow closely. Organizations also adopt many internal knowledge-sharing methods in response to incidents. A full 85% said they conduct awareness training followed by table-top exercises (52%), attack simulations (45%) and protocol or response framework training (37%).

    Future DevSecOps In The Cloud

    It appears that most teams are still formulating their DevSecOps strategy. But looking to the future, 42% say they will implement full DevSecOps within the next 12 months. Simultaneously, more cloud traction is projected throughout the industry.

    Right now, 40% of organizations have between 41% to 99% of their workloads in the public cloud. And 55% of organizations will have between 41% to 99% of their workloads in the public cloud in the coming year. The type of workloads will also likely evolve in the coming year, as more organizations move to container platforms, Function-as-a-service and other serverless capabilities. To fully reap the benefits these new technologies promise, organizations must undoubtedly respond to a new class of cloud-native vulnerabilities.

    About The Report

    The Cloud Security Alliance (CSA) is a not-for-profit organization with a mission to widely promote best practices for ensuring cybersecurity in cloud computing and IT technologies. The Secure DevOps and Misconfigurations survey was conducted from July 2021 through September 2021 and collected over 900 responses from a global pool of IT security professionals working in various sectors and organizational sizes. For a full copy of the report, you can swap some personal information for a PDF download here.
  • Best of 2021 – 7 Popular Open Source CI/CD Tools

    Best of 2021 – 7 Popular Open Source CI/CD Tools

    As we close out 2021, we at DevOps.com wanted to highlight the most popular articles of the year. Following is the fourth in our series of the Best of 2021.

    DevOps is a software development strategy that incorporates agile practices for fast, efficient product creation and release. It focuses on integration of development and operations teams, continuous integration/continuous delivery (CI/CD) and automation of tasks and processes.

    Typically, DevOps teams use pipelines to streamline and standardize processes. DevOps pipelines are toolchains that teams can use to automate tasks and provide visibility into the software development life cycle. In this article, we’ll cover seven popular open source CI/CD tools.

    How DevOps Will Change in the Near Future

    Although DevOps has been around for just over a decade, it has continued to evolve. New DevOps technologies and changing infrastructure have caused teams to adapt and technology advancements that will continue to drive change. Below are a few of the ways you can expect DevOps to evolve in 2021 and beyond.

    AI and Data Science

    Artificial intelligence (AI) and machine learning have significant potential to improve current DevOps processes. Teams can use AI to identify inefficiencies in pipelines, optimize testing or evaluate user needs. Increasing amounts of data about environments, customers, markets and individual habits can all be applied to increase productivity and, ultimately, revenues.

    Serverless Architectures

    Serverless platforms, such as the AWS serverless ecosystem, including AWS Lambda and Fargate and the Azure serverless platform, including Azure Functions and Azure App Service, are becoming increasingly popular. These platforms enable DevOps teams to focus on just their code and eliminate many other variables, such as concern for host operating systems. These architectures provide scalability, deployment speeds, and user experiences that are difficult to match. This value will further secure FaaS in the coming years.

    Cloud-Native

    The growth of cloud-native applications has both driven and been driven by widespread adoption of cloud services. The containers and microservices that make up many cloud applications are used in many pipeline deployments and environments. Efficiently developing cloud-native applications require agility and automation that are difficult to meet without DevOps strategies.

    For the above reasons, DevOps has become almost synonymous with cloud-native. As cloud-native technologies change, tooling and processes adapt, as well. Additionally, since cloud growth isn’t slowing down, you can expect that DevOps will continue to focus on and refine cloud-native development.

    DevSecOps

    When developing applications in an automated CI/CD pipeline, security cannot be an afterthought. Especially in complex microservices architectures, security must be built in from the planning and development stages. Everyone must be aware of security requirements – developers, DevOps engineers and infrastructure teams.

    Transitioning to a DevSecOps paradigm requires a culture change, but also a new technology stack. Shifting security left requires tight integration of application security tooling into the development life cycle, and implementation of cloud security solutions that can help gain visibility, and apply automated security controls, to complex cloud environments.

    Which CI/CD Tools will You Use in 2021 and Beyond?

    As technologies change, so does tooling. While you can continue to use the same tools you started with, you should at least consider if other tools can increase your efficiency. Below are a few popular, open source tools you might want to integrate.

    Argo CD

    Argo CD is a CI/CD tool for Kubernetes development. It is an open source project which is currently in the incubation status at the Cloud Native Computing Foundation (CNCF). It uses Git repositories to store the state of Kubernetes applications, monitors applications and can resync clusters to the desired state, as represented in the git configuration.

    This innovative approach also allows you to store multiple desired states of a Kubernetes application, using branches, tags, or by pinning manifest versions using a Git commit. This provides a flexible environment for managing Kubernetes configurations during the development process.

    CircleCI

    CircleCI is an open source CI/CD tool. It includes features for job orchestration, resource configuration, caching, debugging, security and dashboard reports. CircleCI integrates with a variety of tools, including GitHub, Heroku, Slack and Docker.

    CircleCI is available in three tiers, one of which is free. You can use it in the cloud or on-premises with Linux, Mac or Windows machines.

    GitHub Actions

    GitHub Actions are a recently released open source tooling feature you can use to automate workflows. It enables you to build, test and deploy code directly from GitHub. You can base your automation on any GitHub events, including push or issue creation.

    GitHub actions include features for matrix workflows, hosted runners for all major operating systems, built-in secrets storage and live log reviews. It supports all common programming languages.

    GitHub actions includes hosted runtime environments that are free to use for the first 2000 minutes of use per month. If you need more time for testing, you can purchase time by the minute or in bulk. You can use GitHub actions by including them in your YAML files.

    GoCD

    GoCD is an open source build tool that lets you build CI/CD development pipelines. At its core, it is a continuous integration (CI) server, which lets you work with complex release workflows. It goes beyond classic CI to let you construct a full continuous delivery (CD) pipeline, all the way from automated and secure deployment to production.

    GoCD defines pipelines using code checked into source control – this infrastructure-as-code (IaC) approach lets you test, manage and reuse pipelines across multiple projects. Pipelines can be represented by JSON or YAML templates.

    Another feature of GoCD is the ability to run pipelines both sequentially and in parallel, with configurable dependencies. You can view entire workflows from development to production and track a feature from initial commit to production deployment, using value stream mapping.

    GoCD is extremely flexible, providing an ecosystem of plugins and the tool also allows you to develop and contribute your own.

    Gradle

    Gradle is an open source build automation tool that has been around for about a decade. It continues to be well-adopted and supported. Although it is not a new tool, it can be a good alternative if you’re looking to replace Maven as your build management solution. Gradle is more extensible and faster than Maven, and can be used for native development of C/C++ applications.

    Gradle includes features for incremental builds, build caching and parallel execution. It supports a variety of languages and platforms, including Java, Scala, Android and C/C++. You can integrate Gradle with a range of tools, including Eclipse, IntelliJ and Jenkins.

    You can use Gradle on-premises or with a virtual machine in the cloud. Gradle is free to use; however, if you want enterprise support or training, you need to pay an additional fee.

    Helm

    Helm is an open source Kubernetes package manager. You can use it to define, install and upgrade Kubernetes-orchestrated applications. Helm includes a wide range of pre-built charts (sets of distributable Kubernetes resources) that you can use to deploy services faster and more easily. You can use Helm on Linux, Mac and Windows devices.

    Jenkins X

    Jenkins X is an updated version of the well-known Jenkins. It builds on the existing features of Jenkins with capabilities tailored to Kubernetes and Docker workflows. It includes features for pre-built pipelines, integrated GitOps support, automatically generated preview environments and feedback integration.

    Jenkins X integrates with Tekton, Prow, Helm, Knative and Skaffold. You can use it on Linux, Mac or Windows machines.

    CI/CD and Automation Go Hand-in-Hand

    Agile teams need automation tooling, especially when creating and working with CI/CD pipelines. DevOps environments are dynamic, built for fluid workflows and constant change. Automation helps DevOps teams maintain a high level of visibility and reduce time spent on repetitive tasks. When adding AI and data science into the mix, DevOps teams gain the ability to make data-driven decisions, in addition to automated alerts and response.

  • Quali Adds Free Tier to DevOps Automation Platform

    Quali Adds Free Tier to DevOps Automation Platform

    Quali has added a free tier of service to its Torque platform for automating infrastructure provisioning and application workload deployments.

    In addition, the company has updated the software-as-a-service (SaaS) platform to provide blueprints through which it provides tighter integration with Terraform, an open source infrastructure-as-code (IaC) tool, along with support for custom tags to make it easier to generate reports and dashboards that provide greater visibility into infrastructure costs.

    Quali CEO Lior Koriat said the free tier is intended to make the Torque platform more accessible to both small teams of DevOps professionals and individual users. It includes the ability to build environments on Amazon Web Services (AWS) or the Microsoft Azure cloud in addition to providing integration with a variety of DevOps tools and platforms and access to a sample blueprint library. Support for the free tier is provided via an existing community edition of the platform.

    Koriat said Torque takes IaC a step further by also making it possible to automatically deploy complete application environments on top of infrastructure provisioned as code using blueprints rather than low-level Terraform scripts. The goal is to increase developer productivity by extending Terraform so that developers can spin up environments across multiple cloud computing platforms via self-service, he added.

    That approach also sharply reduces the chances a cloud platform will be misconfigured, which Koriat noted is the bane of cloud security professionals’ existence. Most developers lack the cybersecurity expertise required to ensure cloud computing environments are configured properly. Simplifying the provisioning of infrastructure is especially critical when developers employ complex platforms such as Kubernetes, added Koriat.

    At the same time, Quali’s Koriat said IT leaders want more visibility into how cloud resources are being consumed as the number of workloads deployed in these environments steadily increases. Developers tend not to remember to de-provision cloud resources when no longer needed, which Koriat noted conspires to increase cloud costs unnecessarily.

    It’s not clear just yet how quickly DevOps teams might be moving away from relying on lower-level tools toward automation frameworks accessed via a SaaS platform. However, as application environments become more complex, it becomes even more challenging to provision and manage IT environments—especially since many DevOps teams are still working from home to help limit the spread of the COVID-19 pandemic.

    One way or another, the amount of time and effort spent managing IT infrastructure needs to be reduced. After all, while application environments are increasing in both size and complexity the number of individuals that make up a DevOps team remains largely the same. The need to rely more on automation frameworks has reached a tipping point that is becoming increasingly obvious to all concerned.

    As more organizations start to operate as software companies in the age of digital business transformation, it’s clear the way IT has been managed in the past is about to fundamentally change. The issue now is determining which automation framework lends itself best to enabling DevOps teams to achieve that goal.

  • How Log4j Becomes a Serious DevOps Problem

    How Log4j Becomes a Serious DevOps Problem

    The recent discovery of the Apache Log4j vulnerability has wide-ranging implications for anyone who develops software, especially for those in the DevOps realm. What’s most troubling about the vulnerability (CVE-2021-44228) is how prevalent the use of Log4j is. The vulnerability is reported in a vast array of applications and directly impacts numerous Apache projects, including Druid, Dubbo, Flink, Flume, Hadoop, Kafka, Solr, Spark and Struts. There are also numerous Cisco programs impacted by the vulnerability. The list of impacted applications and libraries seems to be almost infinite, extending to Elastic LogStash, GrayLog2, Neo4J, Steam, Twitter and even the VMware Tanzu family of programs. 

    Simply put, any application that uses Log4J for logging and tracing is subject to the identified family of attacks known as Log4Shell. Those attacks prove easy to exploit and can be used to take control of vulnerable servers.

    Why DevOps Practitioners Should be Concerned

    The world of DevOps is all about reiteration, where features and improvements to applications are slipstreamed into production environments. To accelerate development, the QA process is usually limited to the most recent changes.

    In other words, developers, via their pipelines, can often establish a baseline of quality and then speed up their CI/CD pipelines by testing only what has changed since the last iteration of the application. This process ensures an acceptable level of quality without introducing what are perceived to be unnecessary steps.

    However, those processes do not take into account newly discovered flaws in older APIs and libraries, meaning that those flaws could telegraph into deployed applications and leave DevOps teams completely unaware of the impact and possible disruption. Detecting flaws after an application is deployed is like putting the cart in front of the horse.

    Further complicating the situation is that many developers lack a well-defined and well-maintained software bill of materials (SBOM), which means developers may be unaware of the components and/or libraries being used in a deployed application.

    Without an SBOM, it becomes increasingly difficult to remediate an issue with an application—especially if developers are unaware of the issue to begin with.

    Where Should Responsibility Lie?

    More often than not, vulnerabilities introduced into applications become a game of finger-pointing, where developers blame library suppliers or infosec staffers, and infosec blames developers for not performing due diligence on the components they are selecting to incorporate into their applications.

    Of course, finger-pointing only adds to the angst and delays the process of remediation and does nothing to determine where the responsibility for detecting and remediating vulnerabilities lies. DevOps teams need to put these squabbles aside and establish a process that deals with unintentionally introduced vulnerabilities. What’s more, DevOps teams need to invest in DevSecOps to make sure that vulnerabilities are detected and remediated as quickly as possible.

    To avoid the potentially massive disruption that a vulnerability like Log4Shell can cause, those running DevOps should consider:

    • Creating and maintaining an SBOM 
    • Deploying automated tools that scan for discovered vulnerabilities
    • Automatically comparing the SBOM against vulnerabilities
    • Including DevSecOps processes within their CI/CD pipelines
    • Frequently testing applications for flaws
    • Coordinating with cybersecurity personnel when a flaw is discovered
    • Patching frequently

    With more and more vulnerabilities discovered on an almost daily basis, DevOps teams must be ever vigilant about what components are incorporated into their applications. What’s more, with the increased use of low-code/no-code tools and integrated development environments (IDEs), DevOps will also need to consider if those tools use other libraries that can become compromised.


  • Red Hat Adds Service to Customize RHEL Images

    Red Hat Adds Service to Customize RHEL Images

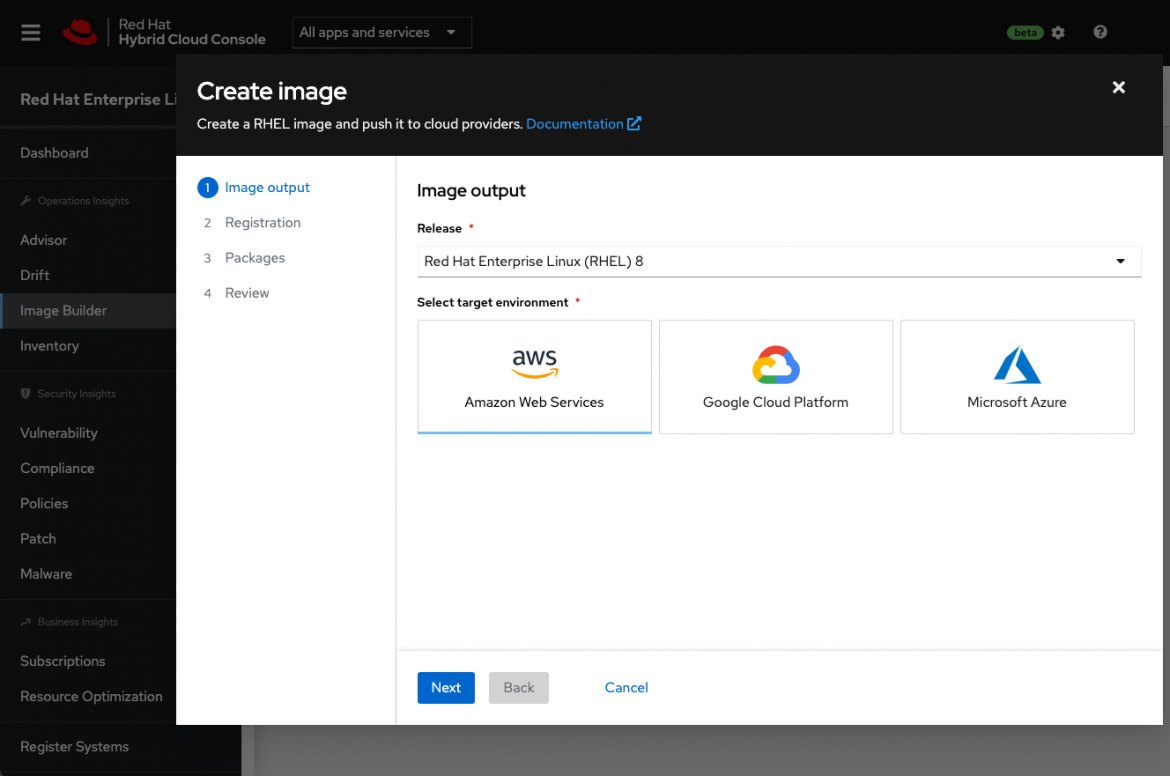
    Red Hat this week announced a public beta of an Image Builder service that streamlines the process of building customized instances of the Red Hat Enterprise Linux (RHEL) operating system.

    Scott Herold, director of product management for RHEL at Red Hat, said the Image Builder service enables an IT team to define a “gold” template for each target deployment environment that only contains the RHEL code required. Initially, Image Builder is configured to default to build a minimal, recommended RHEL server image for Amazon EC2, Microsoft Azure and Google Cloud Platform (GCP) cloud services.

    Future updates to the service will add support for VMware vSphere platforms as well as downloadable images and installation media for physical servers, customized filesystem layouts and versions 9.0, 8.5, 8.4 and 7.9 of RHEL. The service itself is accessed via the Red Hat Hybrid Cloud Console that is currently being made available in beta.

    Herold said building or installing operating systems is often a slow, tedious and error-prone process that needs to be manually performed in a slightly different way for each platform. Each physical server or edge computing platform requires different configurations and workflows. As a result, the chances mistakes will be made is high; Image Builder can greatly reduce the possibility of mistakes because there is no guesswork required, noted Herold.

    IT teams can also opt to include additional content from Red Hat in those builds to further streamline deployment processes, noted Herold. Those images can then be automatically registered with Red Hat to ensure future updates are received.

    The ability to customize those images also serves to reduce the overall size of the codebase that needs to be secured, added Herold. At a time when there is increased focus on software supply chains in the wake of a series of high-profile security breaches, many IT teams are revisiting their software deployment processes, he noted.

    Ultimately, Herold said Red Hat is moving toward providing IT teams with a more cloud-like experience regardless of where they deploy Red Hat’s curated open source software. The goal is to reduce as much friction as possible so that IT teams can more easily manage infrastructure at scale, he added.

    One way or another, the entiree software deployment process is becoming more automated. Much of the drudgery that has historically made it challenging to deploy and manage IT platforms at scale can be traced back to manual processes created when organizations ran a much smaller number of applications in on-premises IT environments. As IT teams increasingly deploy more applications in the cloud and at the network edge, it’s become more apparent that manual legacy processes won’t scale—especially when it’s already challenging to hire and retain IT personnel.

    It’s not clear how quickly IT teams will modernize software deployment processes using automated DevOps processes. Simple inertia is often a powerful force to overcome; however, most IT professionals can easily find something more compelling to do with their time that doesn’t involve using manually customizing operating system images.

  • Bridging the AppSec and DevOps Disconnect

    Bridging the AppSec and DevOps Disconnect

    Research estimates that cybercrime is going to cost the world $10.5 trillion annually by 2025, so it is no surprise that cybersecurity has become a top priority for business leaders. 

    Today, security teams are striving to harden their systems against cyberattacks and improve their resilience through more employee security training, incident response programs and the implementation of technology to monitor and detect threats. 

    Many organizations are also adopting a shift left security strategy, where security is being addressed earlier in the application development life cycle. These organizations are realizing that finding security issues in their software after it’s released is much riskier and more costly. After all, the longer a bug is in the wild, the longer an attacker has to find and exploit it. By implementing a shift left security strategy, the window of opportunity for an attacker decreases or can be completely removed if a security issue is addressed in the development stages, while also offering organizations significant security benefits and cost savings. 

    Shifting left is a security testing strategy where DevOps and security teams work in tandem to identify and address vulnerabilities during early development stages. This process significantly improves security as it means vulnerabilities are identified and mitigated before they are introduced to the enterprise environment.

    However, one of the biggest challenges organizations face when adopting a shift left security strategy (DevSecOps) is encouraging security teams and DevOps teams to work together.

    Encouraging AppSec and DevOps Collaboration

    Until recently, DevOps teams and AppSec teams were completely siloed. DevOps teams worked on accelerating the speed at which applications are released into the enterprise; application security teams only got involved in the later stages. However, this process has caused security concerns, particularly as more organizations move to agile development. 

    When security teams eventually got their hands on new applications and updates, security flaws were inevitably found that caused delays and friction with DevOps teams. 

    However, as organizations begin to embrace DevSecOps and shift left strategies, these two previously siloed teams are being forced to work together more closely. So, how can the friction be reduced and the disconnect bridged?

    Culturally, some ingrained attitudes and behaviors challenge the success of any DevSecOps efforts. Security teams have seen DevOps processes accelerate the speed at which software is delivered, but without security considerations, while DevOps teams experienced security slowing down processes and giving inconsistent results and feedback on security issues. Each party has their own manager to please; their own set of metrics that they’re measured against and a priority list as long as their arms already. Both teams follow different processes and, crucially, use different tools. DevOps can’t get around the security tool complexity and lack of integration with their existing toolset and security teams have no control over the CI pipeline to best implement security assurance.

    One of the best ways to overcome this friction is through better technology, process and culture that enables collaboration between teams. First, DevOps teams do care about security, but it might be lower on their priority list. Security teams must understand that DevOps teams care about code, quality and efficiency. They are not security experts and just because an organization is shifting left doesn’t mean they need to become one. Instead, organizations should implement tools for DevOps where security checks can be easily embedded.

    So, what can organizations do to improve the collaboration between AppSec and DevOps teams to achieve DevSecOps?

    DevSecOps is a culture and it requires a shift in thinking. Security teams and DevOps teams need to understand each other’s priorities and understand that by working together they are improving the overall security of the organization and decreasing the risk of cyberattacks. Does the DevOps team understand the potential risks a vulnerability could have on the organization overall? If not, security teams need to educate them.  

    Security automation tools offer great support when organizations are moving to DevSecOps, as they allow bugs and vulnerabilities to be flagged automatically as applications are being developed. This will allow them to be addressed before services go live; however, because they generate frequent alerts, this could add to DevOps’ already busy workloads. By deploying tools which can be synced with CI/CD pipelines and provide custom advisories so DevOps teams can address bugs themselves without having to ask AppSec teams, this can significantly speed up the process, reduce friction and ease workloads.

  • Hasura Adds Engine to Transform REST APIs to GraphQL

    Hasura Adds Engine to Transform REST APIs to GraphQL

    Hasura today unveiled a Data Hub repository for integrating application programming interfaces (APIs). The repository includes a connector that makes it easier for IT organizations to convert REST APIs into ones based on the GraphQL specification.

    Tanmai Gopal, Hasura CEO, said the connector eliminates the need to write custom code to connect existing REST endpoints to a GraphQL API using an update to the transformation engine developed by Hasura. Instead, the model for the GraphQL API is automatically overlayed on top of the REST API endpoint, explained Gopal.

    Originally developed by Facebook, GraphQL has emerged as a popular alternative to REST APIs because it enables developers to retrieve data at a more granular level, which results in improved performance. Hasura provides an instance of a GraphQL engine the company has developed around a project that is now hosted by the GraphQL Foundation, an arm of the Linux Foundation. GraphQL provides a complete description of the data made available via an API and is organized in terms of types and fields rather than traditional endpoints. In addition to clarifying what data is available via that API, developers can employ types to avoid writing manual parsing code.

    Hasura claims its engine has been downloaded more than 400 million times since its introduction in 2018. It automates the repetitive work involved in mapping models to APIs by providing common access patterns for pagination, filtering, joining, setting up authorization rules and optimizing performance. Hasura also provides APIs that are able to connect to multiple services and data sources, embed domain-specific authorization logic and provide additional layers of security.

    Hasura is now also adding a way to create identity-specific authorization policies for any GraphQL service or data source, enforcing security by limiting the models and fields of the GraphQL APIs in a way that eliminates the need for IT teams to cobble together disparate libraries and frameworks, said Gopal.

    In addition, Hasura is adding support for Google Cloud to Hasura Cloud in beta, a managed API integration service the company already provides via the Amazon Web Services (AWS) cloud. Support for the Microsoft Azure cloud will be forthcoming in 2022, added Gopal.

    It’s not clear the degree to which organizations are looking to replace existing REST APIs with ones based on GraphQL. However, Gopal noted there are plenty of instances where organizations need to overlay a GraphQL API on top of a REST API that they may not own. For example, a software-as-a-service (SaaS) platform that currently exposes a REST API may not have any plans to support GraphQL, he said.

    There’s no doubt the number of GraphQL APIs being employed in the enterprise is about to dramatically increase. The challenge now is finding a way to manage them alongside the previous generations of APIs that remain. The trouble is that many of those APIs were created by developers that may not have documented the APIs they created or, in some cases, never informed DevOps teams that they existed in the first place.

  • Log4j: It’s All About the Supply Chain, Baby!

    Log4j: It’s All About the Supply Chain, Baby!

    In 2021, the security story in DevOps and DevSecOps has been the supply chain. So, it’s only fitting that we are currently experiencing the mother of all supply chain issues with the Log4j Log4Shell RCE vulnerability to close out the year.

    I won’t waste your time rehashing what Log4j is, why it’s so dangerous and warning you to test all of your own and third-party apps to make sure you’re insulated against this. I will say, though, that I don’t think Log4j is a bug—I think it is a defect in design. Worse, as we are seeing, there are multiple defects in design. All of you Java haters out there—back in the box. Java is no worse or better than any other language that we regularly use to build applications.

    So, what exactly is so special about supply chain security? Why do DevSecOps teams, developers and our security incident management teams have to interpret this as a warning and stay at the top of their game from now on? It’s simple. In the age of SaaSOps; in a world where we Frankenstein applications by cobbling and stitching together numerous third-party components (some open source, some not), we are increasingly reliant on code, even in our own applications, that we did not write. We probably didn’t test it, either. We rely more than ever on the “community” and on unknown third-party suppliers. It has always been a leap of faith with these apps and components, and this year some of those chickens have come home to roost.

    The White House executive order on improving the nation’s cybersecurity calls for a software bill of materials (SBOM) for applications; that is, as they say at the tables in Las Vegas, a fine start, but we need more. If we really had a BOM included with the apps we use (and that includes SaaS apps), how many of you are actually going to read it and act on that information? And besides including all these components in a BOM, what further obligations do suppliers have to ensure that they are replacing and updating vulnerable code?

    This issue becomes increasingly acute with open source. My partner and colleague Mitchell Ashley recently asked if too much open source was a bad thing. I don’t know if I would go that far; the more the better, as far as I am concerned. But we do need better monitoring and management of the open source code that’s out there. More testing before it goes GA, maybe? Yeah, the Cadillac open source projects might have the money and time to do that, maybe, but take Log4j as a perfect example: It’s two guys maintaining it in their free time and trying to do right by the community. How can they possibly keep up?

    I used to think that the answer was in the repos. My friends at Sonatype had a component firewall that would not let you download an old or vulnerable version of code without warning. That was fine if you were downloading it for the first time. But if it was already embedded—then what? Can we scan for older components in an app? My friends at JFrog can do something similar and more with Xray. And Sonatype’s Nexus platform also allows current and prospective users to scan older apps for vulnerabilities—including scanning for Log4j, absolutely free. But is that enough?

    All of these questions involve open source components. What about third-party SaaS apps? Often, we don’t even know what components or code are in those SaaS apps. Again, it is a leap of faith we are making when using them. 

    These supply chain security issues are a problem that we are just beginning to grasp. And while 2021 has been the year the stuff hit the fan and Log4j may be remembered as the biggest of the first, I, for one, am afraid to think about what else is coming. 

    I do know that the only way to tackle this and any future supply chain issues is if developers, DevSecOps, DevOps, SREs and our security incident response teams all work together. Just like most security issues, supply chain security is all of our responsibility.  I hope Log4j hasn’t bitten you too hard, and that you are on top of your exposure. But let’s start thinking about the next one and how we can better prepare for it.

  • Speedscale Makes Free API Observability Tool Available

    Speedscale Makes Free API Observability Tool Available

    Speedscale today announced it is making a free edition of its observability tool for application programming interfaces (APIs) available to developers.

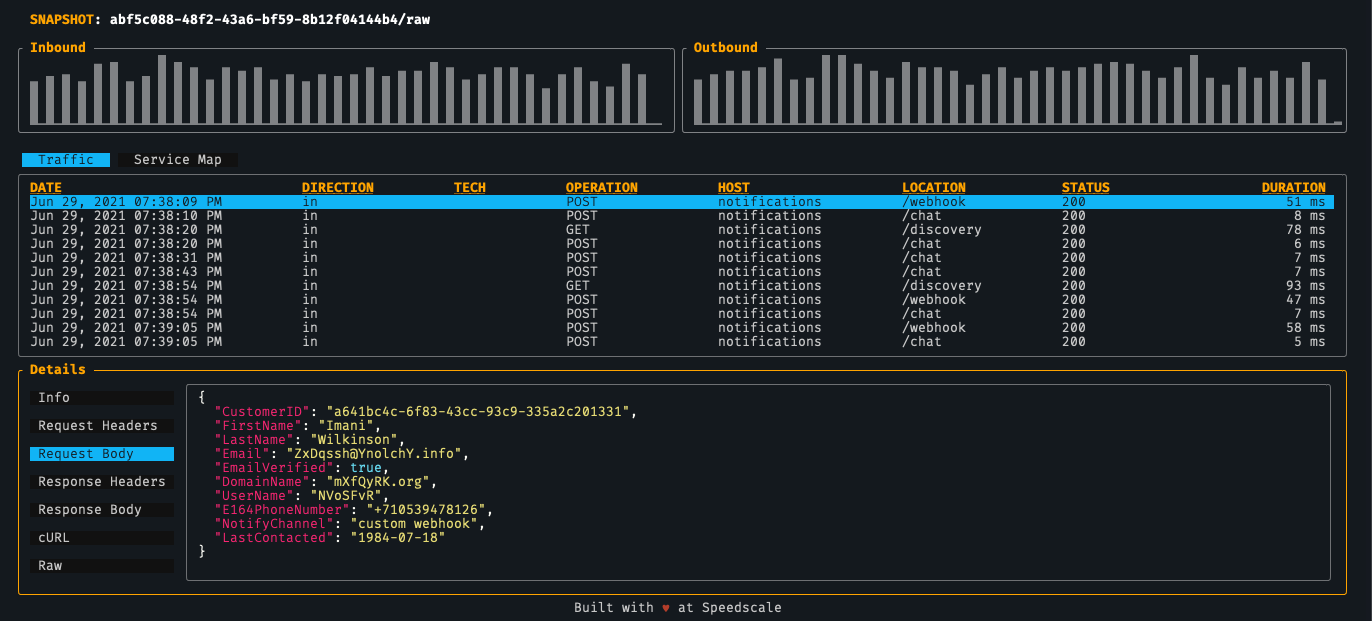
    Ken Ahrens, Speedscale CEO, said the goal is to expose more developers to the company’s API testing tool that can be accessed on their local machine via a command line interface (CLI). Dubbed Speedscale CLI, it is designed to enable individual developers to inspect, detect and map API calls on local applications or containers rather than having to subscribe to the company’s current API testing platform via a software-as-a-service (SaaS) model.

    That approach should reduce the number of disruptions DevOps teams are likely to encounter after an application is deployed in a production environment, noted Ahrens.

    Speedscale CLI features include service mapping, which enables developers to auto-detect and map external dependencies that could break, a traffic viewer for logging and tracing API calls and latency detection tools that show how code changes are impacting performance. In a forthcoming update, Speedscale also plans to include load generation capability to enable developers to run tests locally. The overall goal is to enable IT organizations to shift more responsibility for the management of APIs further left toward the developers that create them, said Ahrens.

    Naturally, Speedscale is also hoping that, as more developers are exposed to its observability platform for APIs, there will be increased demand for its SaaS platform among DevOps teams that need to manage and maintain APIs in production environments within their existing workflows. Speedscale exposes a set of APIs of its own to enable that integration, noted Ahrens.

    At its core, the Speedscale SaaS platform is designed to enable DevOps teams to replay how calls are made between APIs and external mock services to make it easier to diagnose issues.

    In general, there’s a lot more focus these days on APIs, thanks to digital business transformation initiatives that are dependent on APIs to integrate processes. The challenge organizations face is many of those APIs are built by separate development teams. In some instances, organizations can find themselves deploying redundant APIs. Other organizations will create APIs that, over time, are simply forgotten about or that go dormant when the developers that created them leave the organization. These “zombie APIs” often represent a security risk because cybercriminals now routinely scan IT environments for unattended APIs through which they can exfiltrate data without anyone noticing.

    One way or another, the management of APIs is becoming a distinct discipline within many organizations as they come to appreciate the level of IT flexibility they enable. Replacing backend services is a lot simpler when the APIs calls that invoke them both internally and externally remain relatively simple. The challenge is that building and maintaining microservices-based applications based on APIs is a more complex endeavor than building a monolithic application. The first step toward reducing that complexity is, of course, to provide more visibility into the application environment for all concerned.

  • Extending GitOps to the Enterprise

    Extending GitOps to the Enterprise

    GitOps is a relatively new term, but it continues to gain momentum as more organizations embrace the paradigm. In DevOps, GitOps lands on the software engineering side of the development and operations continuum. Even though GitOps is more likely to be adopted by smaller organizations, larger enterprises can successfully implement GitOps with just a few tweaks to the overarching framework.

    Let’s start at the beginning. Wouldn’t it be great if we could combine DevOps and GitOps approaches and use the Git distributed version control system as the ultimate source of truth? Then, when there’s a dispute over the correct state, people know where to go for the correct version.


    In GitOps, the system’s desired configuration is stored in a revision control system such as Git. Any difference between the desired state stored in Git and the system’s actual state indicates to DevOps teams that not all changes have been deployed. These changes can be reviewed and approved through standard revision control processes such as pull requests (PRs). When a PR is approved and merged to the main branch, an operator software process is responsible for changing the system’s current state to the desired state based on the configuration in Git.

    GitOps doesn’t require a particular set of tools, but the tools must:

    1. Operate according to the desired system state stored in Git.
    2. Detect differences between the desired and actual states.
    3. Perform required operations on the infrastructure to synchronize the actual and desired states. 

    In an ideal implementation of GitOps, manual changes to the system are not permitted and all changes to configuration must be made to files stored in Git. The infrastructure and operations engineers’ roles in a GitOps model shift from performing infrastructure changes and application deployments to developing and maintaining GitOps automation and helping teams review and approve changes through Git. 

    GitOps is great for non-critical environments, but enterprises are less likely to adopt GitOps due to a number of challenges facing GitOps users.

    Challenges with GitOps

    GitOps is applicable only to a subset of the software development life cycle (SDLC). This is important because GitOps tools are sometimes marketed as a one-size-fits-all solution that will solve all release problems—this is simply not true. First, GitOps requires that your deployment artifacts are already there. This means that tasks such as

    • Compiling code
    • Running unit/integration tests
    • Security scanning
    • Static analysis

    are not a concern of GitOps tools and are assumed to already be in place. GitOps also doesn’t address promotion of releases between environments.

    Auditability

    A default GitOps process is not fully auditable because of force push. Force push essentially allows users to remove any unwanted blocks of commits from Git history on the central repository.

    Business Approvals

    PRs are a typical approval model used in GitOps. Developers make changes, create PRs and then an approver may accept that PR. This would be recorded and a change would be deployed. A PR-based approval model assumes peers are already using Git and are familiar with PRs. 

    Generally this works great until we need to include business approvals. Business personnel may not be familiar with Git or PRs. If a team needs business approvals, they have to build a process on top of GitOps. This drastically increases lead time. 

    Governance 

    GitOps is dependent on a pure PR-approval based model, one in which the PR approver is responsible for reviews. After a PR is approved, there is no way to enforce enterprise policy rules. Enterprises need to control what end users can do on specific clusters to ensure those clusters are in compliance with policies to meet governance, legal requirements or enforce best practices.

    An Enterprise Approach to GitOps

    However, there are ways to solve this problem at the enterprise level.

    Alerting on Drift Detection 

    Enterprise customers get alerted whenever there is a drift in their repository and, based on that, customers can choose to approve or reject the drift. If rejected, the merged PR should be reverted to the previous state to ensure that Git is in sync with the desired state of the cluster.

    Use a Pipeline for Promotion of Releases Between Environments

    To promote an artifact between environments, users would have the ability to use a pipeline with deployment stages, performance monitoring and log analysis/approvals. 


    Let’s say the developer commits the source code and the GitOps deployment happens in the QA environment. The PR can be automatically approved upon meeting the policy standards set by the company. Then it can be pushed to a production environment.

    Governance 

    There are many reasons why developers and platform engineers integrate policy-as-code into their current GitOps processes. For one, this strategy helps to accelerate application development and deployment because it helps solve many of the change management hurdles that slow development pipelines.

    On the development side, policy-as-code helps app developers understand and abide by the company’s configuration, security and compliance policies. For example, a developer may not remember—or may have no reason to know—when deploying a load balancer onto Kubernetes in AWS is or is not sanctioned. Policy-as-code solves this problem automatically.

    The ability to run policies during GitOps deployments and adhere to those policies as a part of the deployment and upon any violations—alert, audit, notify and automatically roll back the changes from Git to the previous successful compliant state so that Git remains in sync with the cluster.

    GitOps + AIOps

    There is a notion that once GitOps is in place, everything will work seamlessly with no problems. Not so much; it is important to continually monitor deployment state to ensure everything stays as it should. That is where AIOps comes into picture.

    GitOps enables DevOps and development teams to see any manifest change, infrastructure change or artifact change. Post-deployment, the GitOps operator can instantly understand the changes in the service health, see what caused those changes and automate the process of investigating them using AIOps. If any severe anomalies are found, the operator can determine the current state of the system and, should anything differ, revert to the previous compliant Git commit.