Category: Continuous Delivery

Continuous delivery is a software engineering discipline that allows organizations to consistently develop and release quality software at a rapid pace. It is achieved by automating the software development lifecycle, enabling tasks such as development, testing and release to occur concurrently and continuously.

  • Top Nine Skills for SREs to Master

    Top Nine Skills for SREs to Master

    It’s easy to talk at a high level about what site reliability engineers do: They ensure that IT systems achieve availability and performance requirements.

    But which skills, exactly, do SREs need to do to perform their jobs? That’s a more complicated question.

    To answer, let’s look at the top nine site reliability engineer skills that modern SREs (or aspiring SREs) should master. Although SRE skills may vary from one team to the next depending on the types of systems managed and the main types of reliability challenges faced, virtually all SREs need a core set of standard skills that allow them to understand and manage the type of complex, distributed systems they will have to support at the typical organization today.

    Here’s a breakdown of top SRE skills.

    Networking Expertise for SREs

    The network plays a pivotal role in connecting modern, distributed environments. As such, it’s often the culprit when something goes wrong—a lesson that Facebook, for example, learned when a networking problem brought down its entire global infrastructure.

    Situations like this are why SREs should master networking concepts. Even if their organization also employs networking engineers, site reliability engineers need a deep understanding of networking themselves to know when the network is the root cause of an incident and how to resolve network-caused issues effectively.

    Linux and Unix

    If you come from a Windows background but you want to be an SRE, there’s no getting around it: You’ll need to learn how to work with Linux and other Unix-like systems in addition to Windows.

    That’s because, even at organizations that don’t rely heavily on Linux servers, you’re likely to find that Linux and Unix concepts are deeply embedded within other systems that you have to work with. Most public cloud management tools follow the conventions of Linux CLI tools, for example. So do systems like Docker and Kubernetes, even if you run them in a Windows environment.

    Cloud Computing

    Like Linux and networking, cloud computing is another category of skill that modern SREs can’t live without.

    The reason why is almost self-explanatory: Around 90% of businesses use the cloud, and you can’t manage reliability for cloud environments very well if you don’t understand cloud architectures, cloud networking, cloud data storage, cloud observability and so on.

    CI/CD Pipelines

    SREs don’t typically help to develop software, but they nonetheless need a deep understanding of how software is written and deployed—which, at most organizations, today, is a process that happens via a CI/CD pipeline.

    It’s hard to engineer reliability if you don’t know how to address reliability problems that emerge from application source code or deployment processes. Understanding how CI/CD processes work and which tools drive them is key for virtually every SRE today.

    Quality Assurance and Software Testing Automation

    SREs also don’t usually help to test software pre-deployment. That task falls to developers or quality assurance engineers.

    Nonetheless, understanding how software is tested—and how to use test automation to speed tests and expand test coverage—is a vital SRE skill. After all, the more thoroughly and efficiently your team can test software, the greater your chances of catching reliability problems pre-deployment, when they are easier to fix and pose a much lower risk to the business.

    Security Engineering and Response

    Securing is another domain that SREs don’t “own,” but where they nonetheless require significant skills.

    Indeed, good reliability engineering makes security a priority, and vice versa. SREs who don’t understand security fundamentals are at risk of implementing reliability solutions that are effective from a reliability standpoint, but not necessarily secure.

    DevOps

    Although SREs are not DevOps engineers, SRE and DevOps are closely related domains. SREs at most organizations today will be expected to understand DevOps concepts and, in many cases, work alongside DevOps teams.

    So, plan to master DevOps skills as part of your site reliability engineer skills acquisition strategy.

    Incident Management

    Perhaps the single most important type of skill for SREs to learn is incident management. Although many roles may participate in incident response, SREs usually take the lead in organizing the incident response team, communicating with stakeholders and devising the best strategy for resolving each incident as quickly as possible.

    This means SREs should know how incident response roles are structured and understand incident response concepts. They should also be familiar with incident response platforms that automate the complex processes required to ensure rapid, effective incident resolution.

    Managing Postmortems

    In addition to overseeing incident response, SREs may be tasked with managing post mortems. Knowing how to run a postmortem—as well as when a postmortem is necessary, and when it makes sense to use a “blameless” postmortem approach—is an essential SRE skill.

    The list of SRE skills could certainly go on. Above are only the most fundamental types of skills SREs will need for most modern environments. But if you’re just starting out on your journey to becoming an SRE, the nine skill domains described above are a good place to begin acquiring the knowledge you’ll need to excel in an SRE career.

  • How to Seamlessly Transition to DevSecOps

    How to Seamlessly Transition to DevSecOps

    In the last few months, the cybersecurity world has been taken by storm following the discovery of the Log4Shell vulnerability. The zero-day had the potential to put much of the connected world at risk and left security teams scrambling to quickly apply security patches to software just before Christmas 2021.

    As a result of the chaos caused by Log4Shell, many organizations kicked off the new year by carrying out security assessments to identify ways to improve detection and mitigation of future vulnerabilities. One approach that is gaining a lot of attention is DevSecOps.

    DevSecOps introduces and automates security in the earlier phases of the software development life cycle rather than bolting it on at the end. The approach saves money, saves time on tedious manual tasks, helps organizations meet regulatory compliance requirements and significantly reduces the risk of critical security bugs being found after an application’s final build.

    However, when it comes to kicking off DevSecOps projects, there are a few challenges application security teams need to overcome first to ensure their programs fit seamlessly into CI/CD pipelines.

    DevSecOps Isn’t Simple

    While moving to DevSecOps delivers organizations clear benefits in the way of security, one of the key concerns for business leaders is that it slows down the delivery pipeline of software and applications. Today, being an agile software delivery machine is essential and a critical part of an organization’s survival, so no business leader wants to put development velocity at risk because of security testing.

    Application security teams are tasked with ensuring DevSecOps fits seamlessly into software and application delivery, without causing delays or adding more pressure onto already over-stretched DevOps teams. As a result, they need to identify which tools are needed for security testing and integrate them into development stages seamlessly as well as which ones can be automated and which can scale to meet the demands of CI/CD pipelines.

    The great news for application security teams is there are hundreds of security tools available; the bad news is choosing which to use and learning how to use them is a minefield, even for those with the right training and know-how.

    A DevSecOps automation program needs lots of technical aspects to come together to make it work. Security teams need static analysis tools to check the code, third-party library analysis to check the dependencies, separate analysis to check the infrastructure-as-code configuration, scanners to check the containers for issues, tools to test the running system, cloud security checks and infrastructure testing for patches and ports. They also need to match these tools up to the right technology each team is using and keep up with the constant changes.

    So, what are the most important features that application security teams should look for in DevSecOps security testing tools?

    Tips for Approaching DevSecOps

    Security teams need a way to manage their security tools so that tedious tasks are removed but collaboration with development teams is streamlined. They need a platform that handles the automation process, flags only the issues they want to flag and presents them in a way that is accessible to everyone, from execs to board members to developers.

    You’re Going to Need a lot of Security Tools

    We commonly see teams using 10+ tools to cover the needed checks, so be prepared to chain together multiple security tools. Some to check each source code language the development teams are using, more to check your containers, cloud setup and dynamic testing against the staging system, etc. 

    Tip: Be prepared to do some up-front analysis to establish which security tools are going to make up your DevSecOps initiative.

    Think of the Day-to-Day ‘Security-as-a-Service’

    How are you, or your teams, going to work with the security tools? Is someone going to check the output of 10 tools in every build? Are they going to compare each set of issues against the last to see what’s new? How will they handle the open source tools that don’t track false positives? This is a major part of the DevSecOps process, and a very common place where we see processes fail—if the automation of the tools leads to awkward handling of vulnerabilities, it’s doomed.

    Tip: Have tools send their vulnerabilities to a centralized store for ease of use.  

    Tip: Track the difference between runs so it’s easy to see new and high-risk issues.  

    Tip: Think of how developers and security teams can more easily collaborate on issues.  

    Tip: Think of how false positives, duplicates or non-issues can be handled and tracked so developers are not flooded with the same issues over and over again.

    Be Flexible With Your Security Tools

    No matter how you intend to integrate security tools, know that different teams are going to need different tools. Some will use Docker, for example, others won’t. Often, different development teams end up working in different coding languages, which means there will also be different security tools required to scan. Some teams will be up and running with DevOps, others won’t be there. Keeping security testing consistent and repeatable is difficult.

    Tip: Whatever DevSecOps platform you use or build, make sure you can slot in the right tools for the right job. If you’re too rigid, you’ll waste time running tools and dealing with nonsense issues and no one will want to play with you.

    Work With the Existing SDLC Environment

    If your teams use Jira to track development tickets, for example, work with that and have new issues entered and tracked there. If they use five different DevOps pipeline platforms, be prepared to integrate and work with each of them. If you have metrics for security, know how you’re going to track changes per repo, project, team, division, etc. for each pipeline run and all the various categories of tools.

    Tip: Run your DevSecOps implementations where your development teams are, work with their systems and make security an easy extension of their existing workflows.  

    Tip: Be able to track historical metrics across categories of issues and tools, so you can show what good progress you’ve made, and where your security investments are (and are not) working.

  • Updating and Managing Infrastructure-as-Code (IaC)

    Updating and Managing Infrastructure-as-Code (IaC)

    Infrastructure-as-code (IaC), often embodied by open source Terraform, is an essential ingredient to cloud and cloud-native strategies. But without the ability to scale, secure and manage IaC, you very quickly experience drift. Tim Davis, DevOps advocate with env0, pronounced “N zero”, discusses establishing a single source of truth and reigning in drift by updating and managing infrastructure as code. The video is below, followed by a transcript of the conversation.

    Announcer: This is Digital Anarchist.

    Mitch Ashley: I have the pleasure of being joined by Tim Davis. Tim is DevOps Advocate with env0, and so, we’re going to be getting into some infrastructure as code type discussions, so, looking forward to that. Welcome, Tim—good to be talking with you.

    Tim Davis: Same for you, Mitch. Great to meet you. Thanks for having me.

    Mitch Ashley: You, too. I love your cloud off to your right shoulder, by the way. [Laughter] Anyways, so—introduce yourself, tell us a little bit about env0.

    Tim Davis: Absolutely. So, I am the DevOps Advocate with env0. dnv0 is a TACoS platform, if you will, the Terraform Automation and Collaboration Software space. We really focus on infrastructure as code, automation, teams and governance, and other tools to help you with the life cycle of your infrastructure as code environments.

    Mitch Ashley: Cool. Good. Well, you know, it’s a great conversation to have, because something that I observed always happens in our industry is, you create a new technology, it’s kinda easy to get started and starting to use, sometimes it isn’t always easy, but the complexity comes—alright, how do I scale this? How do I do this across a larger development team or multiple development teams? How do I operate it? How do I secure it through the day two kinda stuff?

    Tim Davis: Right.

    Mitch Ashley: And I wouldn’t be surprised if you told me the same is true for infrastructure as code, and in fact, I know that to be true.

    Tim Davis: [Laughter] Exactly right.

    Mitch Ashley: Let’s talk about that. What are some of the challenges once people get into doing infrastructure as code, particularly with Terraform? What are some of the challenges that you run into?

    Tim Davis: Yeah, and most of those kind of lie around the visibility and kind of the control space of that. Infrastructure as code is great. It is a fantastic way of speeding up, kind of pushing yourself into the future for DevOps, getting into that real GitOps life cycle. But with that, you know, if it usually just starts out with either one developer or one infrastructure person that starts running it locally on their laptop and figuring it out, it’s great, it does what they want.

    As soon as you start to scale that methodology and doing it locally to multiple people, that’s when you start losing that visibility of, “Where are my state files stored? Who just deployed something into the cloud? What variables might they have used for that?”

    So, it really becomes kind of an, “I don’t know who’s doing what in my cloud anymore.”

    Mitch Ashley: Mm-hmm.

    Tim Davis: So, really making sure that you’re staying on top of that, kinda centralizing everything to maintain that visibility is very important when you’re scaling it.

    Mitch Ashley: Let me ask you, then—is it fairly typical that within one software Dev team you have a person or sort of a close enough coordinated group of people that are doing the software as code, infrastructure as code. And then the confusion may exist as you start to go across multiple teams, or does it also occur within one team, just sometimes, it’s every developer for themselves and so—

    Tim Davis: Yep.

    Mitch Ashley: – you could have a wild, wild West kinda situation before you know it.

    Tim Davis: [Laughter] And the answer of that, of course, is yes, I mean, it’s all of the above. It could be even just two people on a small team that start to use these tools and they start to step on each other’s toes by having deployments that kind of counteract each other. Or you have it where somebody is deploying out into the cloud using your infrastructure as code and somebody else is just going into the cloud and clicking around and deploying stuff manually where you get something called drift, where what the infrastructure as code says is out there isn’t necessarily matching with what’s actually there.

    Mitch Ashley: Mm-hmm.

    Tim Davis: So, it can be across a single team, multiple teams—any time you really scale it past a single person on a laptop is really where you start to see those issues.

    Mitch Ashley: Yeah, okay. It’s a familiar problem, right?

    Tim Davis: [Laughter] That’s exactly right.

    Mitch Ashley: We’ve had this in other things, too. Well, what are some of the best practices or kind of good infrastructure as code hygiene to keep your worlds at least sane to start with so you—the first question is always, “What’s there?” If you don’t know what’s there, then—

    Tim Davis: Right.

    Mitch Ashley: – everything is up for grabs, or you question everything because you just don’t feel like you have a good grounding of what you’re looking at and what you’re dealing with. What are some of those best practices?

    Tim Davis: And I really—I try to stay away from the best practices thing, because sometimes what’s good for somebody isn’t great for somebody else, but that—

    Mitch Ashley: Well, and I say that as best practice is not universal, right?

    Tim Davis: Absolutely. And there are some things that you can do to help yourself out, for sure. If you’re using infrastructure as code, having the single source of truth can be very helpful for everybody, essentially stopping that drift that I just mentioned. So, if you are using infrastructure as code, save them in a repository somewhere. Make that the single source of truth where whatever’s in there, whatever’s in those infrastructure as code files, that’s what’s there.

    So, whenever you decide to go for infrastructure as code, stop using the cloud UI, stop going around and click, click, clicking and adding resources and things. Do it by updating the infrastructure as code file and then re-deploying. That can really help you make sure that you’re not causing any problems, nobody’s stepping on anybody’s toes, and you know if I see it in the files here in this one spot, that’s what’s out there.

    Mitch Ashley: Mm-hmm. Yeah, I totally agree with you. That makes a lot of sense to me. What are some of the complexities, then, you have to deal with? Because now we’re working an environment where infrastructure, the stack, the distribution of that, the locations, whether geographic or service provider really can change instantly without necessarily the full development team, which is an advantage, right? You want that sort of abstraction.

    Tim Davis: Exactly.

    Mitch Ashley: But it also can be—introduce new variables and maybe even new problems.

    Tim Davis: Yeah, and it could be new problems, it could be the same old problems, or it could be new problems that you kinda deal with the same, old way. And, you know, adding controls of making sure you’re adhering to policy, like, you’re only allowed to deploy to certain regions or you’re only able to deploy a certain number or size of instance, making sure that you have some form of role based access control there to know, you know, this person is allowed to deploy straight out to development, no problem, but if it’s going to production, it needs to wait for approval and somebody from either the DevOps team or the SRE team needs to validate everything first before we actually make that push.

    Mitch Ashley: Mm-hmm. I think something else that always happens, too, is in—you know, I’m a security guy as well as a software guy, so, I always worry about the security side of it. Now, automation can make that, you know, much better.

    Tim Davis: Exactly right.

    Mitch Ashley: Much more reliable, less human error. There’s a lot of good things that come with infrastructure as code from a security standpoint, but it also can be, it’s sort of security is in the eye of the scripter and the person who’s—

    Tim Davis: Right. [Laughter]

    Mitch Ashley: – doing, you know, configurations or doing the scripting, too, which can be good or bad. How do you address security in this kind of a world?

    Tim Davis: Yeah, and this is just one of those things where we’ve all heard the term shift left, and shifting all of these different things—security, performance, you know, billing—everything, if you shift it left into the deployment process, it really helps if you foster that communication. I mean, we know that old school term of silos where one hasn’t isn’t talking to the other hand. If everybody gets involved, if the security team is involved with writing the policy, they’re involved with double checking that it is implemented into the deployment process so that you don’t have to go and fix a problematic deployment later, it’s just stopped before it starts. That can really make sure that everybody kind of gets what they want, but security folks still have to be involved. They are still in charge of the overall process and procedure and policy, it’s just, it’s kind of a new way of getting that implemented and at what stage of the life cycle you’re implementing it.

    Mitch Ashley: Do you think it shifts—and this is actually, I just did a talk on this about shifting left of, we wanna shift everything left, which is generally a good idea, right?

    Tim Davis: Right.

    Mitch Ashley: To be able to address some of those things early and design it in, design security in, et cetera. Oftentimes, it’s interpreted as, “Let’s put that on the developers, too. Let’s have them—the developers will worry about that. The developers will worry about all those.” Now, it’s pretty much, it could be everything, sort of a ridiculous request, right?

    Tim Davis: Right.

    Mitch Ashley: Because that’s not a developer’s expertise to necessarily know all those things. What is your—when you say shift left or infrastructure as code—

    Tim Davis: Right.

    Mitch Ashley: – in practical terms on a software team, what does that look like?

    Tim Davis: Yeah, and a lot of folks think that that just means, “Hey, I’m taking away your job as the security guy and I’m gonna give it to the developer” and that’s not the case. The developer, they may be a little security conscious, they may understand the infrastructure or the networking piece, but nowhere near as much as the career security guy or the career networking and infrastructure guys. It just kind of brings them in and fosters that conversation.

    I definitely think the developers are going to be part of the conversation, because it is bringing it into their tooling, into their languages, into their life cycle, but it still requires that expertise to be able to make sure that it is done correctly, it’s implemented correctly, and that it’s being checked the way it needs to be done.

    Mitch Ashley: Mm-hmm. So, does it look like security engineers, to use that as a term, they’re sitting down with the developers, saying, “Okay, how are we configuring the environment?” and, “Here’s how you’re building your Terraform configurations”—going through that with them?

    Tim Davis: I think so.

    Mitch Ashley: Is it saying, “Here’s the principles we want you to follow”—

    Tim Davis: Yeah.

    Mitch Ashley: – “and as you’re creating this, please do these things, and then we don’t have to sit on your shoulders”?

    Tim Davis: I definitely think there’s lots of different ways you can do that. I mean, obviously, you know, having your standup meetings, making sure that they are kinda telling them, “This is what the policy should look like, however you want to implement it is fine, but this is the kind of processes and procedures, these are the rules that we need to check.” So, it can definitely be done however works best for everybody, but as long as you’re having that communication and you’re making sure that everything’s going through—yeah, you know, you can always do it different ways and be successful, still.

    Mitch Ashley: Mm-hmm. Interesting. What are some of the things that you’ve seen change? You know, there’s been a lot of acceleration over the last 12 to 18 months.

    Tim Davis: Right.

    Mitch Ashley: And, you know, I’ve heard people talk—of course, you always hear about the, as much digital transformation happened in the last year that was planned for five years.

    Tim Davis: Yeah.

    Mitch Ashley: And there is some truth to that, and I’m sure some exaggeration, too. But there’s a strong belief that, you know, people are now thinking they can deploy applications much, much faster and they’ve proved it in this last window. Have you seen that happening?

    Tim Davis: Yeah, absolutely, and you know, technology changes. They used to say it doubles every six months or what have you, and really, we are iterating and changing and kind of moving forward very, very quickly. A lot of times, we get a new tool and it’s great and then people are like, “Alright, I’m gonna pull this tool in and automate it” and then they figure out, “Oh, there’s some extra complexity here and we’re having to go back through and figure it out.”

    I definitely think there’s a lot changing, you know, even just the shift from on prem legacy, I guess, enterprise architecture through to new, like, cloud native architectures and things like that. We’re moving fast, we’re able to change and pivot and do what we need to do, but as long as we make sure that we’re kind of keeping grasp of what we’re supposed to be doing from either a security or an infrastructure construct, we can make sure that we can iterate and change and adapt as fast as possible without causing any major issues down the line.

    Mitch Ashley: Mm-hmm. Cool. What do you think the next 6 to 12 months look like? If you had to put on your crystal ball, your Magic 8 Ball, that says, “Ask Again”?

    Tim Davis: [Laughter] Yeah, I love to look into that. Obviously, it’s good to see, you know, what am I gonna have for lunch next week, but also, you know, looking into the industry of what’s gonna happen. We’re seeing more and more X as code. We’ve got infrastructure as code, you’ve got security as code, you’ve got policy as code tools. I think we’re gonna see more and more and more, you know, performance as code and things like this that just are able to bring those day two plus operational tools closer left into the deployment cycle and have all of these single source of truth in the repositories of, we know exactly what our infrastructure is supposed to look like, we know how it’s supposed to be secured, we know how it’s supposed to perform. All of this is just declaratively set up there. I think we’re gonna see a lot more of that going forward.

    Mitch Ashley: Mm-hmm. Well, certainly, as you said, it follows the “everything as code,” right?

    Tim Davis: Exactly right.

    Mitch Ashley: And if we’ve learned nothing else, I think that’s been a lesson of the past 12 to 18 months, right? It is software, it’s all about software.

    Tim Davis: It absolutely is.

    Mitch Ashley: What do you think some of the skill challenges are for people as we continue to evolve this and move into this rapid world, shifting things left, doing more infrastructure as code, and maybe asterisk as code—everything? You know, it’s always the self-learners can be at the edge of the curve, other folks have other ways of learning. How do we bring everyone along in terms of their skills and their learning, their development?

    Tim Davis: Yeah, and that’s definitely something. I mean, I ran into myself. I’m an infrastructure guy at heart, that’s where I’ve been, you know, my whole career, and eventually, someone was telling me, “Hey, this Python thing might take off” or, “I’ve heard of this thing called Terraform and it’s basically like code, but it’s our job.” And, you know, just realizing that nobody’s trying to take away your job as a security guy or an infrastructure guy or girl or what have you. They’re not trying to take it away from you and move it over to a developer, it’s just one of those things where you need to adapt to move forward faster.

    Now, it’s not just infrastructure folks that are learning to code, it’s also developers that are kind of learning infrastructure and figuring out how can I optimize my application against this infrastructure a little better? How can we work together to move forward faster? So, it’s kind of a melding of skills from different, you know, old school silos now to work together to solve the problem.

    Mitch Ashley: I made that recommendation to a network and security engineer about 10 years ago. It’s like—learn Python, and he looked at me like I had six eyes instead of two.

    Tim Davis: [Laughter]

    Mitch Ashley: And he came back from the Cisco conference, he goes, “Now I know why you said that.” [Laughter]

    Tim Davis: Exactly right. And that’s a great piece of advice even today in 2021. I mean, if you’re in infrastructure or you’re a network tech or you’re a security person, look into Python. It’s not as hard as you think and you can do so much with it. It’s a fantastic way to kind of break into that DevOps automation type space.

    Mitch Ashley: I like that, too, and not that we’re trying to make everybody a developer, but if it’s not a skill you have, it sort of leaves out this whole domain of things that you can either do to understand what’s happening—

    Tim Davis: Right.

    Mitch Ashley: – or do to automate or et cetera. It’s sort of like you’ve got one arm tied behind your back, why don’t you have two out in front where you can fully work?

    Tim Davis: Yeah. And it also helps from a cohesive understanding between groups. Back when I was a dedicated infrastructure person, myself and the development team didn’t care for each other, because we all were trying to get in each other’s way, it seemed. We were trying to solve the same problems, just going about it in different ways, because we didn’t necessarily understand the methodologies or how those people were trying to get their work done.

    If you as an infrastructure, security, or other operations person start to kind of learn the development methodologies and figure out how things work, it’ll help you to communicate and solve problems across teams better, simply because you kinda see where they’re coming from with their tool sets and the way that they do business.

    Mitch Ashley: Great. Well, it’s been a great conversation. I’m glad we got to explore this path together.

    Tim Davis: Absolutely.

    Mitch Ashley: Where can folks find out more about env0? I know you have a kind of funky spelling of env0.

    Tim Davis: [Laughter] Yes. We are at env0, E-N-V and the number 0.com. You can find us on Twitter @E-N-V-Z-E-R-O and on YouTube at E-N-V-Z-E-R-O.

    Mitch Ashley: Great. So, environment zero, right?

    Tim Davis: Exactly right.

    Mitch Ashley: Perfect. Well, hey, it’s been fun talking with you and hope you’ll come back again.

    Tim Davis: That sounds great. I look forward to it. Great to meet you, Mitch. Thanks for the time.

    Mitch Ashley: Alright, take care.

    [End of Audio]

  • Netlify Leverages GraphQL to Simplify Access to Backend Services

    Netlify Leverages GraphQL to Simplify Access to Backend Services

    Netlify this week added a Netlify Graph tool to its portfolio that makes backend services available to developers via a single click. The tool aims to simplify DevOps teams’ access to those services when building their applications.

    Netlify Graph is based on the GraphQL query language for application programming interfaces (APIs) and enables developers to integrate services such as GitHub, Salesforce and Stripe within frontend and web application development tools without any direct intervention required from a DevOps team.

    Netlify provides an application development framework based on JavaScript, application programming interfaces (APIs) and markup languages, otherwise known as a JAMstack, to isolate frontend and backend components of an application.

    Netlify CEO Matt Biilmann said Netlify Graph is based on the GraphQL technology the company gained when it acquired OneGraph. The overall goal is to make it simple for frontend developers to invoke backend services accessed via either GraphQL or REST APIs, he said. Services based on GraphQL can be especially complex for developers to invoke as they navigate the management of tokens and application secrets, Biilmann added.

    It’s not clear to what degree GraphQL APIs will supplant REST APIs. However, developers tend to prefer GraphQL APIs because they provide more granular control over what data is accessed. The challenge is the number of backend services that expose GraphQL APIs is still comparatively limited. As GraphQL becomes more widely adopted, the level of effort DevOps teams now need to expend to expose backend services should decline as tools such as Netlify Graph are employed by frontend developers.

    As a result, at least theoretically, the rate at which new applications are built and deployed to drive digital business transformation initiatives should increase. Most IT teams will not be replacing REST APIs with GraphQL-based APIs overnight, but the percentage of new applications that rely on GraphQL APIs will steadily increase. DevOps teams looking for easier ways to provide developers with simpler access to backend services now have an incentive to embrace GraphQL.

    Ultimately, Biilmann said, the goal is to enable developers to build applications without having to directly engage anyone on the IT team. Each backend service can be managed in isolation from the frontend of any application. It’s not clear how long it might take to achieve that goal, but as responsibility for the end-to-end management of the application experience continues to shift left toward developers, the need to surface backend systems-as-a-service becomes more pronounced. In fact, given the current focus on improving developer productivity, IT organizations might soon face a mandate to embrace GraphQL more broadly. After all, every minute that a developer spends on plumbing is time they’re not spending writing actual business logic.

    Naturally, it may take time for enterprise IT to be truly transformed into a set of services that developers can easily consume. But as progress continues to be made, that dream may finally be realized.

  • Best Practices to Improve your Engineering Sprints

    Best Practices to Improve your Engineering Sprints

    What is the purpose of sprints? We break work into sprints so we can more easily monitor, estimate and predict what we want to ship and when. Over the years, engineering teams have gotten used to moving quickly from one sprint to the next, but I think it’s important to be more thoughtful in how we plan and execute sprints.

    Running effective and successful sprints can define whether or not your organization is able to ship high-quality software fast and often. It also gives teams more flexibility and the ability to quickly change something that is not working or, on the other hand, to iterate on a successful technology. 

    After almost 20 years as an engineer, manager and as a CTO, I have found there are several best practices that improve the sprints that are part of my team’s software development life cycle. 

    Sprint Planning

    When planning a sprint, there are several things to keep in mind.

    Make Sure the Work Aligns with Business Priorities

    There are always a number of elements an engineering team can focus on during any given sprint. It’s fairly easy to lose sight of the business’ end goal. Make sure to gut-check to make sure that the sprint goals align with current business priorities.

    Ensure the Workload is Balanced From the Start

    This seems like an obvious statement, but make sure team members have equivalent workloads so you avoid burnout. It is also important to understand how different engineers on the team work—some people work best by selecting their own tasks with items that are unassigned, some pick up unfinished tasks as they finish others and some prefer to be assigned certain tasks because they have specialized skills. 

    Don’t Underestimate the Time That Interruptions/Additions Take 

    Along the same lines as the above, don’t overlook this for several reasons. Without adequate, data-driven insight into the actual state of each team member’s workload, it is almost impossible to gauge what’s happening in real-time. While business-critical sprints are assumed to take priority, side projects, Slack interruptions and meetings can easily consume an engineer’s day. Make sure to proactively check that each member has enough true deep work time without becoming burned out. 

    Don’t Underestimate the Time it Takes to get Things to a Done State

    Sometimes engineering teams only look at the development stage, but the full cycle required for the software to get to the end user might take longer. Allotting the right amount of time to get the job done across all phases of development will help avoid unexpected surprises. 

    When You Get to Mid-Sprint

    Monitor Unplanned Work

    Initial planning doesn’t necessarily take into account the bugs and fire drills that will likely arise after the sprint starts. Pay close attention to any mid-sprint additions and adjust as necessary. There may be team members who have cleared their sprint queue and are capable of taking on this work, but being aware of team members’ workloads at every stage is critical. 

    Do Daily Stand-Ups and Raise Flags as Early as Possible

    This will help anyone encountering roadblocks so a small issue doesn’t turn into a huge bottleneck. If you look closely at your PR cycle time, you will find a ton of insights about where roadblocks often happen. Using historical data during sprints can also go a long way toward helping identify potential bottlenecks, allowing you to proactively avoid friction by delegating reviews or setting out additional time for approvals. 

    Get Ahead of Burnout

    The tech industry has a turnover rate of 13.2%—pretty high when compared to other sectors. But the reality is that it can be really difficult to identify burnout without hard data. Don’t wait until people start speaking out about being overworked: Burnout prevention should be a full-time focus. Before sprints, make sure people aren’t coming in with high levels of fatigue and make sure that overtime doesn’t routinely increase throughout.

    Use Sprint Progress Estimations to Reprioritize

    Each sprint starts off with a set workload, but in reality, every sprint is dynamic. Take a look at each day’s progress and evaluate if your team is ahead of or behind schedule. If you are on track to finish a majority of the work, you can anticipate a successful sprint end. If not, don’t worry; you can always recommend that your team recalculate priorities. Engineering managers can take this time to load-balance some of the heavier work and shift goals to the next sprint as needed. Staying flexible while maintaining a clear view of what is actually happening during the sprint, will inevitably result in success. 

    At the End of the Sprint

    Do a Thorough Sprint Retrospective 

    As a team leader, you should constantly be thinking about how things are going and how people are feeling. If you can, use hard data to look at things like time allocation, PR throughput and any items added mid-sprint. Taking notes throughout the sprint will help remind you of any issues that came up, and you can discuss ways to improve for next time. Each sprint is a chance to learn; the more you learn, the better the sprint and the better the product will be for end users. 

  • IBM ‘is Ageist and Sexist’ | IBM Mainframe-aaS | IBM Vaccine Mandate

    IBM ‘is Ageist and Sexist’ | IBM Mainframe-aaS | IBM Vaccine Mandate

    Think! Welcome to Big Blue Week here at The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: IBM’s employment practices scrutinized, IBM z/OSaaS breaks cover, and IBM encourages staff back to the office.

    1. ‘Dinobabies’ and ‘Dated Maternal’ Workforce Woes

    First up this week: IBM’s defense in an employment age discrimination lawsuit looks to be shredded. Internal emails “appear to show high-level discussion about paring the ranks of older employees.”

    Analysis: Not a good look

    According to one of the plaintiff’s lawyers, unnamed “top IBM executives were explicitly plotting with one another to oust older workers … to make room for millennial employees.” On the face of it, they seemed to be doing the polar opposite of the Age Discrimination in Employment Act.

    Noam Scheiber: Making ‘Dinobabies’ Extinct: IBM’s Push for a Younger Work Force

    Top IBM executives were directly involved in discussions about the need to reduce the portion of older employees … sometimes disparaging them with terms of art like “dinobabies.” … Documents made public by a Federal District Court … show executives discussing plans to phase out older employees.
    …
    The newly unsealed documents, which quote from internal company emails … show top IBM executives specifically emphasizing the need to thin the ranks of older workers and hire more younger ones. [One] email refers to IBM’s “dated maternal workforce,” an apparent allusion to older women, and says: “This is what must change. They really don’t understand social or engagement.”
    …
    Adam Pratt, an IBM spokesman, [claimed,] “IBM never engaged in systemic age discrimination.” [He] said that some of the language in the emails “is not consistent with the respect IBM has for its employees” and “does not reflect company practices or policies.”


    Yikes, ageism and sexism? Experienced staff are valuable, says MrBanana:

    I did some time at IBM [and] remember being invited to a meeting with a new group, headed by a new “thinker,” who had something to present to myself and a colleague. We walked past the foosball table to the meeting room. Naturally the room had no chairs, and was covered in multi-coloured Post-it Notes. Once they had gone through their mood boards and the non-linear presentation of this new idea, I turned to the other old geezer in the room. “Didn’t we look at something like this 8 years ago?”

    “Yeah, we worked out that compute power just to run the UI for one session wouldn’t be available for a couple of decades.” The children were somewhat disappointed, and (fortunately) we were never asked back to their romper room.


    But experience can be both a blessing and a curse, learned aahortwwy:

    I experienced both sides of this in five years at a company in hypergrowth. … I learned so much at that job: … In year 1, I was determined to accomplish X and ignored the skeptical comments of some colleagues who’d been at the company longer than me. I failed and wasted some time. In years 4 and 5, new colleagues were determined to accomplish X and ignored my skeptical comments.


    2. IBM Wazi as-a-Service Confusion

    “Mainframe” is not a dirty word. It’s secure, vertically scalable, and it put the VM in VMware. Now, what IBM Wazi did for on-prem LPARs, Wazi aaS promises to extend to hosting z/OS instances.

    Analysis: Mainframe-as-a-service reinvented

    Mainframes and cloud-native DevOps need not be incompatible. To modernize legacy apps using hybrid cloud instances for dev/test—and even prod—can be a big productivity boost. But isn’t it weird that IBM spun out its mainframe-as-a-service zCloud offering only a few months ago?

    Mike Vizard: IBM Shifts Mainframe App Testing to the Cloud

    While many workloads over the years have been migrated off mainframes or simply retired, the applications that run on z/OS today are still among the most mission-critical that organizations run. … IBM this week revealed it has added the ability to set up testing environments on the IBM Cloud for z/OS mainframe applications.
    …
    IBM plans to make IBM Wazi as-a-Service (Wazi aaS) for z/OS generally available in the second half of this year, [which] will enable DevOps teams to self-provision an instance of a z/OS virtual server on a secure private space running on IBM Cloud. … At the same time, it will become easier to modernize mainframe applications by making them more accessible to other applications via a set of secure APIs … using a cloud-native set of DevOps tools that run in a Kubernetes environment.
    …
    Modernizing mainframe applications is a less complicated endeavor than migrating them. The challenge is that building, deploying, maintaining and securing all the APIs required to do so represents a significant amount of effort.


    OK, boomer, why are we talking about 1960s mainframes on DevOps.com? Here’s ArchieBunker:

    Mainframes are different beasts altogether, almost alien when you compare them to PC hardware. You have binaries written for the S/360 system in the 1960s? Good news you can still run them natively without a recompile.

    You think virtualization and containers are a hot topic? IBM was running multiple OS instances inside a VM in the 1970s. … The engineering is incredible.


    But z/OSaaS? It’s déjà vu time for Beleagured Greybeard:

    “Cloud Managed Services for z” AKA “zCloud” has been around for over 10 years. … IBM offloaded it with the Kyndryl spin, so its odd that they now want to re-invent it.
    …
    If it’s a strategic platform, why didn’t they hold onto it instead of spinning it off to Kyndryl? Sounds like yet more daft leadership decisions.


    3. IBM’s Return to Work Plan has Vaccine Mandate

    IBM wants to “keep employees safe” as they return to office work after being fully remote. In practice, this means a vaccine mandate.

    Analysis: IBM Digital Health Pass is divisive to vocal minority

    Although there are exemptions on medical or religious grounds, IBM has promised to place dissenters on unpaid leave. As you might expect, the policy has a few employees up in arms.

    Cassie Werber: How Salesforce, IBM, and HSBC are approaching return to work

    When the pandemic hit, and IBM moved 95% of its workforce to fully remote, it was pleasantly surprised to discover no drop in productivity. … Still, they planned to return to offices.
    …
    The company saw this as a way to keep employees safe. … One example … is its development of the IBM Digital Health Pass as an alternative to vaccine cards or paper vaccine certificates, which they use to make sure all the staff that come into their offices are vaccinated.
    …
    Arvind Krishna, IBM’s CEO, meanwhile came up with what he called the IBM Work From Home Pledge. [It] included commitments to flexibility, kindness, sensitivity to family, setting boundaries, and acknowledged video fatigue. It concluded with a commitment to “be connected.”


    Tricky to “be connected” if you’re not allowed back in the building. Anne D’Innocenzio, Heather Hollingsworth, Tali Arbel, Mae Anderson, Ken Sweet, Matt O’Brien and Dee-Ann Durbin:

    IBM software engineer Justin Albano said his company recently notified employees that it would be revoking badge access to workers who aren’t vaccinated or haven’t proved that they are. “We’re not able to enter an IBM office at this time,” said Albano.
    …
    He said some workers have successfully sought religious exemptions but “my thought process was I shouldn’t have to explain to my company my faith” to get out of a policy that’s “immoral in its foundation.”


    What’s the alternative? With a perspective, it’s Chris Haney:

    Or, get the vaccine. Protect yourself and the people around you. You people really are detached from reality.


    The Moral of the Story: Those who know do not speak; those who speak do not know.


    You have been reading The Long View by Richi Jennings. You can contact him at @RiCHi or tlv@richi.uk.

    Image: Marcin Wichary—cc:by; leveled and cropped (ask your parents)

  • Cloudify Integrates DevOps Automation Platform With Terraform

    Cloudify Integrates DevOps Automation Platform With Terraform

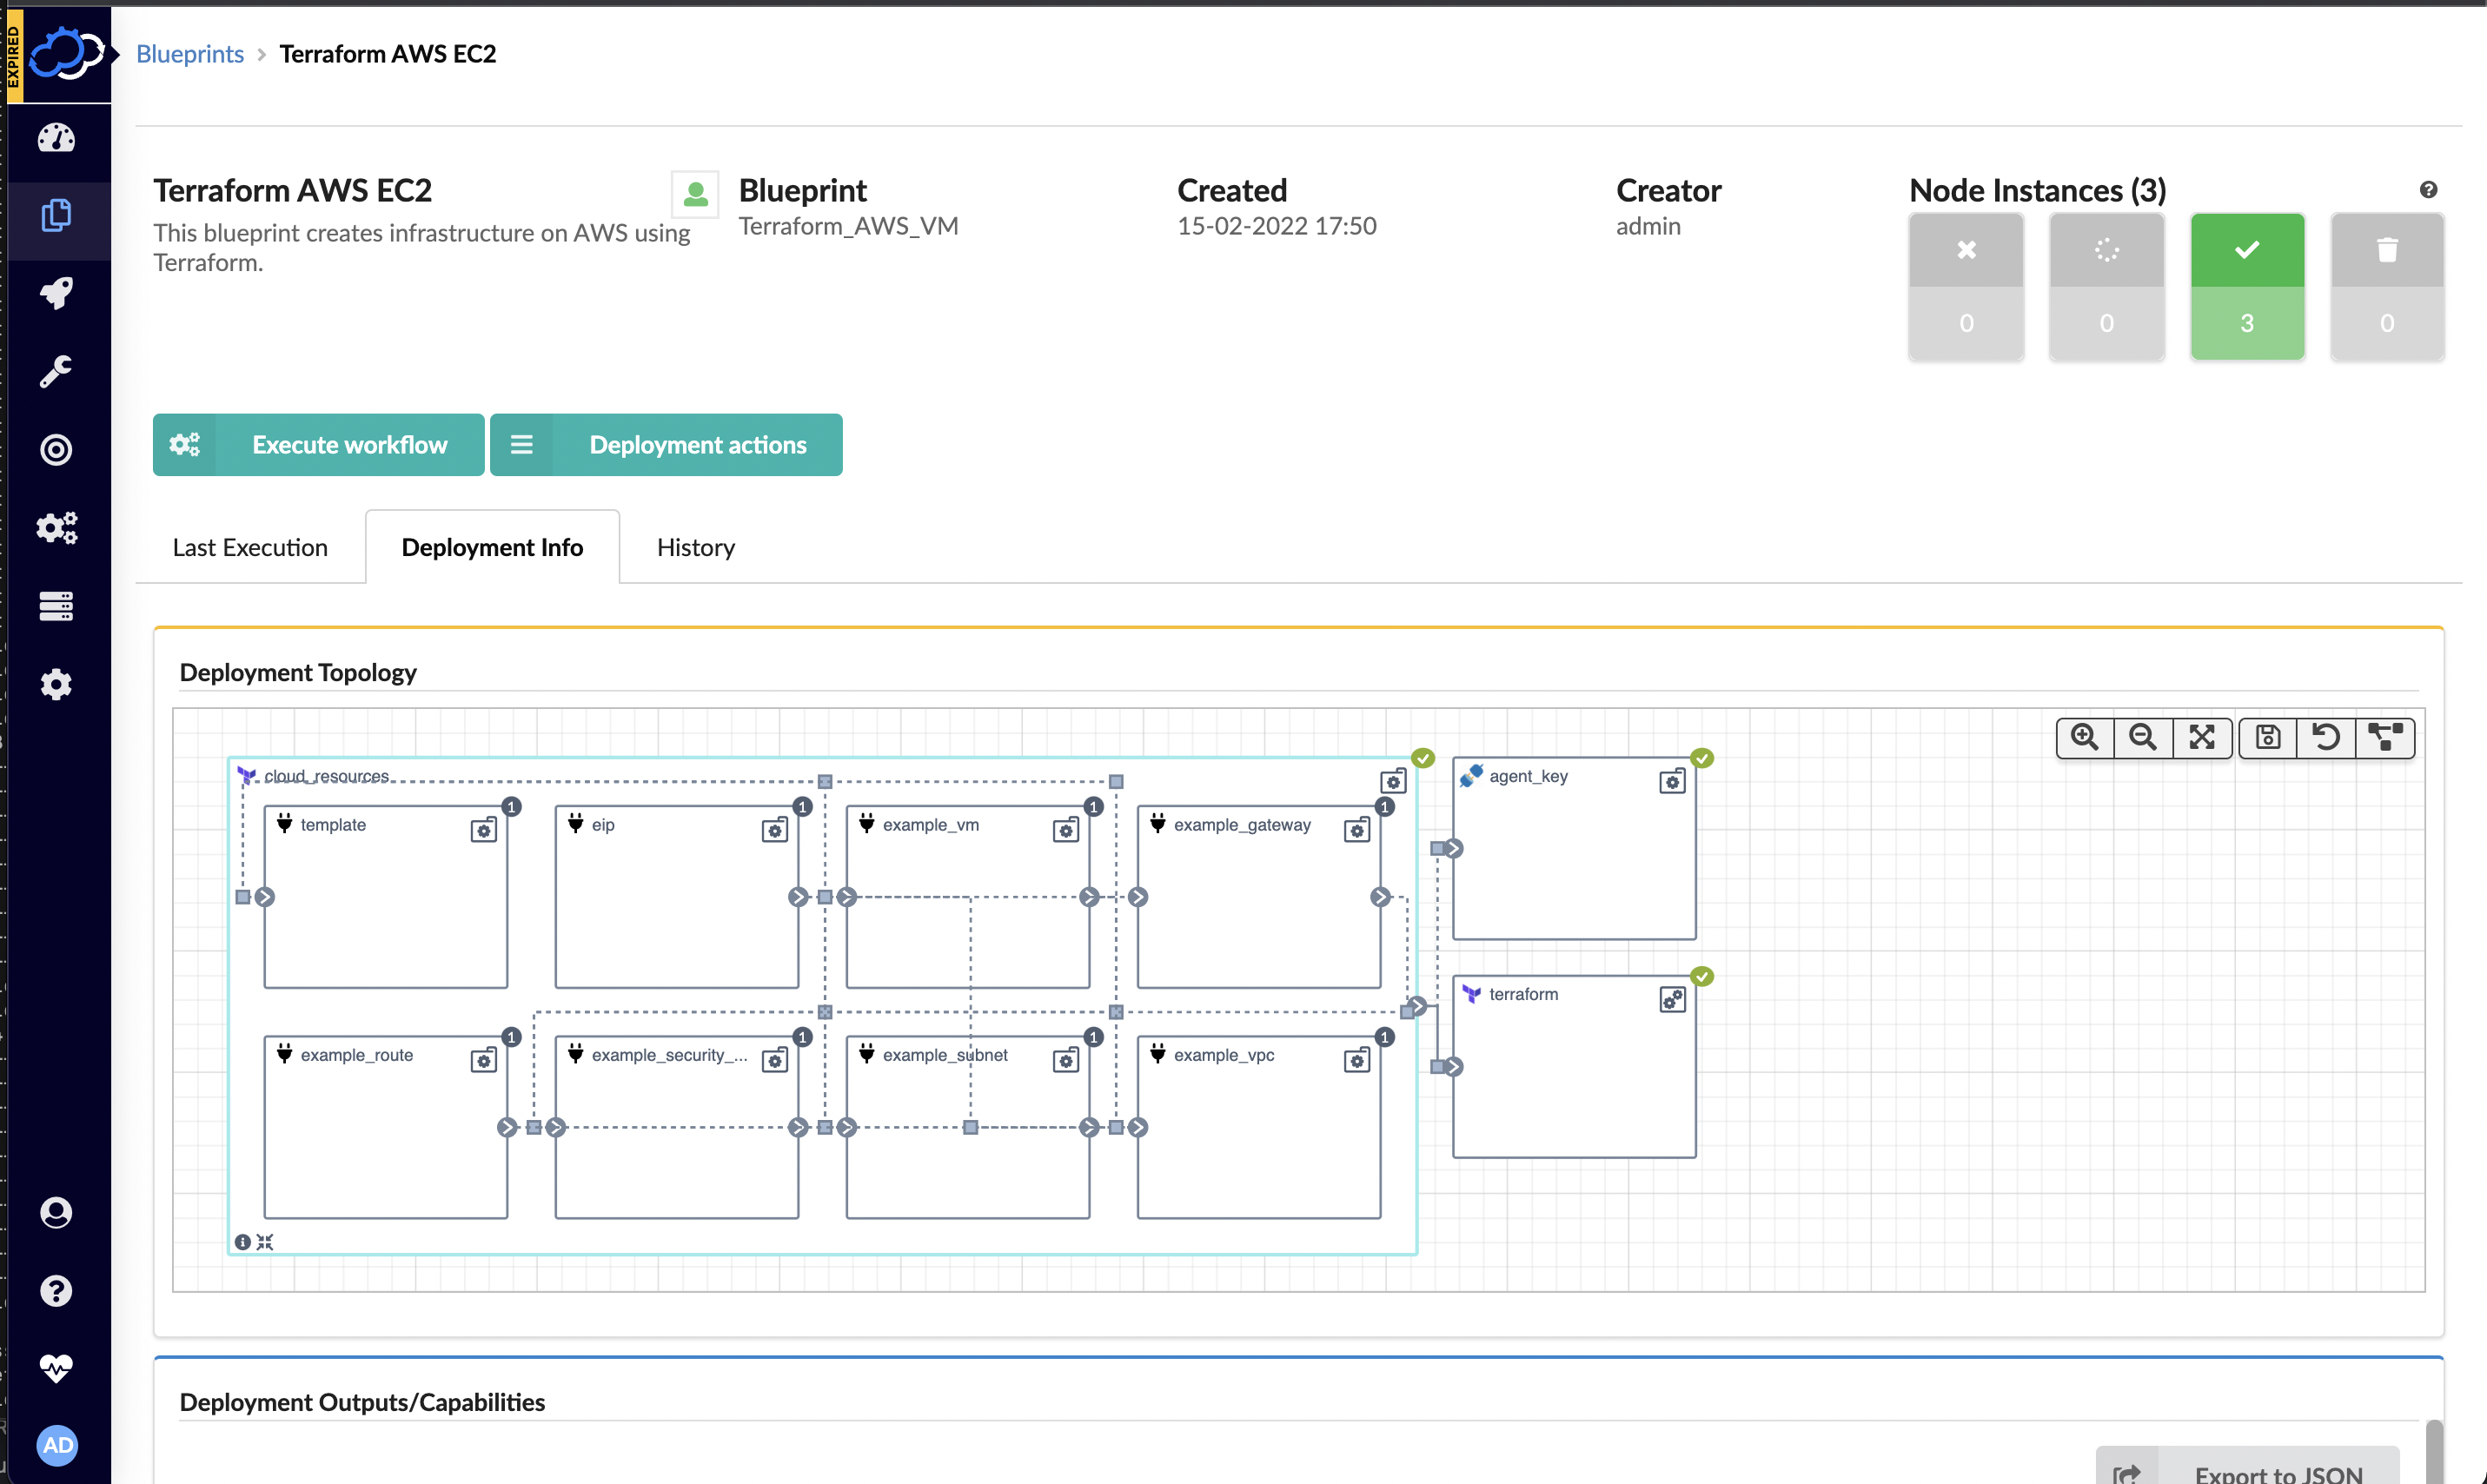
    Cloudify this week announced a free user interface (UI) module that extends its infrastructure provisioning platform and enables DevOps professionals to integrate unlimited Terraform modules.

    Nati Shalom, Cloudify CTO, said Terraform UI provides a familiar construct for DevOps teams using the open source DevOps automation platform to provision infrastructure-as-code (IaC). The module enables DevOps professionals to seamlessly import Terraform modules to Cloudify without writing blueprints or any additional glue code, he said.

    Cloudify now automatically generates the wrapper required for each Terraform template to enable DevOps teams to collaboratively manage secrets, execute concurrent deployments, store states remotely and monitor deployments, users and versions via any Git repository. Those Terraform modules can then be integrated with application programming interfaces (APIs) and continuous integration/continuous delivery (CI/CD) platforms as DevOps teams require.

    DevOps teams can also import existing automation modules and scripts into Cloudify. Those modules and scripts can be automatically converted to environments that can be centrally managed via the Cloudify console or via export to ServiceNow’s IT service management (ITSM) platform as a software-as-a-service (SaaS) application.

    That approach provides the added benefit of enabling DevOps teams to centrally manage all Terraform modules and versions via a single console as part of an effort to reduce misconfigurations that lead to security breaches, he added.

    Cloudify enables DevOps teams to create a self-service catalog and portal through which infrastructure can be managed. Many DevOps teams have built their own portals to manage this process. However, Shalom noted those DevOps teams then need to devote resources to maintaining that portal when those resources could be allocated to other critical tasks.

    DevOps teams can not only use Cloudify to apply patches, change topologies, add security features, make configuration changes or make additional resources available, Shalom added, they can also now integrate Terraform tooling with platforms such as Kubernetes or other automation frameworks such as Ansible. Cloudify also makes available an enterprise-grade version of the platform with these integrations.

    It’s not clear how much time and effort IT organizations are investing in building and maintaining DevOps environments. In many cases, however, organizations should probably revisit decisions about building capabilities that, at the time, didn’t exist. That doesn’t necessarily mean that replacing custom DevOps tools makes sense across the board, but it is likely that, in the intervening years, the range of tooling made available via DevOps platforms has greatly expanded. Relative newcomers to DevOps, meanwhile, are enjoying the benefit of platforms they did not have to construct themselves.

    In fact, Shalom noted that, in terms of DevOps adoption, an inflection point has been reached as more organizations launch digital business transformation initiatives that require applications to be both built and deployed faster than ever. The challenge, of course, is enabling that to occur both safely and at a reasonable cost.

  • CircleCI Adds CI/CD Service for macOS Development

    CircleCI Adds CI/CD Service for macOS Development

    CircleCI today added a dedicated continuous integration/continuous delivery (CI/CD) edition of its namesake platform for developers building applications on the macOS platform.

    Jim Rose, CircleCI CEO, said this offering is aimed at developers that either want dedicated resources to speed up their build processes or have to address compliance and security requirements that prevent them from using shared infrastructure via the existing CircleCI cloud service.

    Most of the developers building applications on macOS platforms are creating applications that will ultimately be deployed on Apple iOS devices, noted Rose. Given the popularity of those devices, the number of organizations using CI/CD platforms to accelerate creation and updates of those applications has increased, Rose added. CircleCI estimated there are now more than 30 million developers building applications on the macOS platform that would benefit from a CI/CD platform running on dedicated bare-metal infrastructure accessed via the Amazon Web Services (AWS) cloud. CircleCI’s dedicated host provides secure access to 50% more cores and more than twice the storage capacity than is available via a CI/CD platform running on top of virtual machines.

    Other capabilities provided by CircleCI include the ability to monitor the performance of apps being developed for multiple platforms in the same pipeline. Many applications deployed on iOS are also deployed on other platforms such as Android, Windows or Linux, noted Rose.

    CircleCI also provides access to testing tools that the company recently added to its portfolio of DevOps tools. Those testing tools are especially critical given the stringent requirements developers face when trying to get approval to make their iOS applications available via the Apple Store, said Rose.

    Developer productivity is, of course, a major issue for organizations trying to strike a balance between automating software development tasks and the art that goes into building applications. While developers appreciate automation, they don’t necessarily want to feel they are working in a factory. Given the demand for their expertise, many developers will simply jump ship when they feel software development processes have become overly onerous. While many managers tend to believe they have a handle on measuring developer productivity, there is often too much focus on, for example, how many lines of code are written versus the business outcomes achieved.

    A recent CircleCI survey also found that more than half (52%) of respondents don’t allow their software developers to choose their own tools. While there is a clear need for a consistent approach to building and deploying applications, organizations will find it challenging to attract and retain the best developers if they don’t allow them to experiment with different tools.

    One way or another, however, the rate at which developers can build and deploy applications is rising as DevOps best practices are adopted. It’s not clear that organizations are going to be able to absorb all that software but, in the wake of the COVID-19 pandemic, the appetite for mobile applications that drive digital business transformation initiatives has never been greater.

  • Dependability is Crucial for Real-Time Experiences

    Dependability is Crucial for Real-Time Experiences

    Millions of people around the world experienced a major disruption after an October 2021 outage saw Facebook, WhatsApp and Instagram go offline. A few days prior, the popular workplace collaboration platform, Slack, also went down for some users. And in the last few weeks of 2021, Amazon’s AWS caused considerable global chaos after significant networking issues in its busiest data center, US East 1, disrupting streaming services such as Disney+ and Netflix.

    Downtime can be costly, causing organizations to lose $5,600 per minute and up to $300,000 per hour, on average, according to Gartner. But it’s not only financial and reputational loss that businesses need to worry about. Outages also seriously downgrade—and in the case of real-time experiences, completely disrupt—the customer experience.

    At a time when consumers are demanding more live and interactive digital experiences, organizations can ill afford disruption or downtime, as customers quickly move to other services that ‘just work’.

    It’s not just the capacity within a real-time system that matters, but also globally distributed failover capabilities when something does go wrong. While organizations could try to build their own failover mechanisms, it’s extremely difficult to failover so services continue seamlessly, regardless of the status of its underlying infrastructure. Simple failover systems not only take longer to resume but typically suffer data loss during the time that a region is disrupted. Businesses need to know that even if, say, AWS suffers an outage, they won’t be affected.

    This is why it’s vital that organizations get it right when looking to develop their own real-time infrastructure. Managing tens of thousands if not hundreds of thousands of concurrent connections while synchronizing data in real-time means that if anything does go wrong it’s immediately obvious to users. If tech behemoths like Amazon and Facebook can’t get it right, what chance do organizations with far fewer resources have when building and managing their own real-time infrastructure?

    The Steps to Success With Real-Time Infrastructure

    Regardless of whether it’s for synchronized multi-user collaboration, audience engagement or instant updates, developers have a hard enough time developing even the most basic of real-time infrastructure, let alone making sure it’s dependable. There are four key elements to achieve dependability: Predictable performance, data integrity, reliability of service and high scalability.

    • Predictable performance: When we think of performance we usually imagine more computing power or speed. But when it comes to real-time, it’s not just about minimizing latency and bandwidth, it’s about having a predictable system. If developers have global latencies and bandwidth within certain operating boundaries, it provides certainty in uncertain operating conditions. This makes it easier to design, build and scale features around this certainty.
    • Data integrity: As we all know, the internet can be an unreliable network. Users abruptly disconnect and reconnect all the time, resulting in data that gets lost, is delivered in the wrong sequence or that is sent multiple times. As a result, organizations must ensure their infrastructure can guarantee high integrity without sacrificing anything else.
    • Reliability of service: The live nature of delivering updates in real-time requires total reliability. Outages can cause distrust and annoyance from users. Organizations could find their reputation taking a hit or customers quickly jumping ship if reliability proves to be a recurring issue. To prevent this, organizations should develop infrastructure that’s fault-tolerant and redundant at both a global and regional level so they can deliver a great experience even if there are multiple failures.
    • High scalability: More often than not, delivering an experience in real-time can result in unpredictable traffic; for example, a huge number of people wanting sports updates for a World Cup game. If thousands of devices connect over a short period of time but capacity can’t scale up quickly enough, then an outage will occur. To avoid this, developers must use infrastructure that can be elastic and meet changing levels of demand. Otherwise, the user experience is seriously affected and real-time capabilities crash when the network is swamped with connections it can’t cope with.

    While organizations often build their own infrastructure with the best of intentions, it’s easy for them to run into trouble. Most lack the internal expertise, resources and time; plus, going it alone often results in a huge technical debt. It’s also a massive undertaking, due to the amount of ongoing complexity and cost involved.

    Third-Party Partnerships Enable Dependability

    Unless organizations have the resources, finances and expertise of the likes of Amazon or Google, then building your own real-time infrastructure is just setting yourself up for failure. Instead, they should save on development cycles and focus on generating revenue more quickly by offloading their real-time infrastructure needs to a third party. This will mean organizations can design without limitations and focus on solving the challenges that really matter to them while putting in place real-time infrastructure that is as dependable and future-proof as possible.

  • How to Automate PKI for DevOps With Open Source Tools

    How to Automate PKI for DevOps With Open Source Tools

    Historically, DevOps and security have been diametrically opposed practices. DevOps wants to move fast and break things, or so they say, but security policies tend to slow things down. However, it has become clear that this school of thought has evolved, as both practices have something to learn from the other. Organizations have embraced a “shift left” approach to integrate security earlier into application development, while security teams are learning to embrace the automation, flexibility and scalability of DevSecOps.

    For example, consider public key infrastructure (PKI), a security technology that is commonly used to authenticate identities, devices and software. There are many valuable use cases for PKI in DevOps such as authenticating services and infrastructure (instead of hard-coded secrets) and validating software and third-party applications. Likewise, there is a worthwhile use case for DevOps to automate manual and ticket-based certificate management; especially since this can create unacceptable bottlenecks for DevOps.

    In this example, PKI and DevOps are like two sides of the same coin:

    • PKI for DevOps – Leverages DevOps to efficiently deploy PKI-based credentials for business applications and services
    • DevOps for PKI – Automates the deployment and configuration of PKI with DevOps

    In either case, these processes use a lot of similar techniques and tools. Best of all, many of them are available through open source communities.

    EJBCA – Open source PKI

    EJBCA is an open source certificate authority that provides a full life cycle certificate management solution, from registration and enrollment to certificate validation and revocation. The project’s source code is available under the terms of the GNU Lesser General Public License (LGPL). EJBCA is used to install a private certificate authority which is highly scalable. In comparison, public certificate authorities are monolithic and expensive, which makes them poorly suited for agile DevOps.

    Ansible – Open source IT automation

    Ansible is an IT automation tool that can install and configure software (in this example, EJBCA). The process is easily repeatable through the creation of playbooks, roles and tasks. Ansible is simple to use because it is YAML-based, a language that is designed to be easily understood, which makes it ideal for DevSecOps environments that have implemented infrastructure-as-code (IaC). Ansible is also highly scalable because it is modular and agentless, which makes it lightweight and fast. Additionally, Ansible playbooks can secure the deployment of other software with keys and certificates from EJBCA, making it possible to leverage Ansible as a universal automation tool, PKI for DevOps and DevOps for PKI.

    HashiCorp Vault – Open source secrets management

    HashiCorp Vault is a secrets management solution, which can be used to secure, store and control access to tokens, passwords, certificates and encryption keys. Its use cases include secrets management, data encryption and identity-based access. As organizations have shifted to more dynamic cloud and hybrid infrastructure, secrets management has become integral to ensure that keys are not exposed in applications and APIs and that certificates are securely issued to the right machines.

    Jenkins – Open source continuous integration

    Jenkins is an automation server for building, testing, delivering and deploying software. Jenkins may be used to automate the deployment of certificates and keys as part of a continuous integration and continuous delivery pipeline (CI/CD). Essentially, a playbook defined in Ansible may be streamlined by Jenkins in the CI/CD pipeline that is a hallmark of DevOps. 

    PKI for DevOps and DevOps for PKI

    The ultimate goal of PKI for DevOps is to provision PKI credentials for business applications without hard-coded secrets, which is one less risk to concern the security team. The goal of DevOps for PKI is to automatically deploy a completely configured PKI solution, which is one less roadblock for DevOps teams. Organizations can leverage a collection of open source Ansible playbooks to automate the installation of EJBCA, which makes this process easily replicable.

    The nature of DevOps is to embrace automation and flexibility at scale. That means that PKI certificate provisioning needs to be integrated and automated into DevOps. When this is done correctly, security and DevOps don’t need to be diametrically opposed—organizations can achieve the best of both worlds: Security and efficiency.