Category: AI

  • Heat Cooks Twitter DC | AI Will Kill All Humans | Patreon Layoffs, CSAM Claim

    Heat Cooks Twitter DC | AI Will Kill All Humans | Patreon Layoffs, CSAM Claim

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Twitter is in a “non-redundant state” thanks to a hot summer, AI is likely to eliminate us, and Patreon fires 80 staff amid nasty allegations (TW: Child safety). (more…)

  • How’s Facebook Work? They Don’t Know! | Cali. Pay Law | NASA RISC-V Launch

    How’s Facebook Work? They Don’t Know! | Cali. Pay Law | NASA RISC-V Launch

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Facebook engineers admit they’ve no idea what Meta stores (or where), California requires job ads quote salaries, and RISC-V will power future NASA spacecraft. (more…)

  • Stable Diffusion Goes Public — and the Internet Freaks Out

    Stable Diffusion Goes Public — and the Internet Freaks Out

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters. (more…)

  • Automation has Become an Absolute IT Necessity – Techstrong TV

    Automation has Become an Absolute IT Necessity – Techstrong TV

    Vijoy Pandey, vice president of emerging technologies and Incubation for Cisco, explains why automation has become an absolute IT necessity. The video is below followed by a transcript of the conversation.

    Michael Vizard: Hey, guys, thanks for the throw. We’re here with Vijoy Pandey, who’s vice president of emerging technology and incubation for Cisco. We’re gonna be talking about all things related to automation. Vijoy, welcome to the show.

    Vijoy Pandey: Thank you, Mike, pleasure to be here.

    Michael Vizard: Right now, everybody is struggling, looking to find people, hire people, retain people, and this was an issue before COVID came, but it seems like it’s much worse these days, and there seems to be no end in sight. So, what is your best advice to folks about how to think about managing talent these days?

    Vijoy Pandey: Yeah, I think that’s a pretty important point you raise there, Mike. Just like everybody else, we’ve been seeing not just news articles around the great resignation, but also we’re feeling that inside of Cisco as well. We know that our partners, our customers, all of us are feeling that pinch, where it’s incredibly important to retain top talent, but it’s also very hard to find talent, given the trends that we’re seeing around us.

    Anything about cloud computing, anything about AI, all of those things. So, we think of the problem in a very different way. We think – and we’ve done a bunch of surveys inside of Cisco – what we realized was given the global nature of events – we know some events unfolding right now – and all of the geopolitical events happening, all the pandemic, people really are realizing that life is too short.

    It’s not a pithy statement here, it’s actually people believe that life is just too short, and they actually want to do meaningful work. They want to make an impact, not just to the team that they are with, nor the company that they’re with, but even a global impact with the work that they do.

    But they also want to grow and learn, and make sure that they are on a path themselves towards meaningfully improving their own lives. So, I think those are pretty important characteristics that we have gathered, and as organizations and as teams we need to harness that desire to make both local impact as well as global impact as well as figure out how to drive meaning into everybody’s personal lives – yours, mine, our teams’, and so on and so forth.

    So, there’s a bunch of things that we are doing inside of Cisco to make sure that this meaning, or meaningful impact, is nurtured. One of the things that we keep on saying is that yes, there is a business to run, but there’s also an avenue we need to give our employees and our teams to innovate, to look at impact beyond the run-of-the-mill business that any corporation needs to do.

    So, typically what we end up doing is we end up taking problem statements that we face, let’s say, as a team or an organization, and we start splitting it into buckets. So, think about buckets that deal with run-of-the-mill business, because that, you need to absolutely take care of.

    But also, there are buckets that you need to innovate around or do meaningful work around. So, we have a portfolio management system inside, at least on my team, that says let’s take 60 percent of your time and make sure that that’s allocated towards run-of-the-mill business as usual projects, and then maybe 30 percent of the time which is future-looking and adding new features or looking at new markets and so on and so forth, and maybe 10 percent of your time is actually towards growing yourself, nurturing yourself, or making some meaningful impact on the global stage. So, that’s actually how we’ve been viewing the problem.

    Michael Vizard: Early on, I think a lot of people were intimidated by automation, and there was concerns that people might lose their jobs. Now, I wonder if we’ve flipped that entirely, where people are saying hey, I don’t really wanna work for organizations that don’t have automated IT process in place because of your points – there’s just things that I don’t wanna spend my day doing anymore. So, has the whole conversation flipped, as far as automation is concerned?

    Vijoy Pandey: I would say the conversation is flipping as we speak, again, yeah, going back to the previous comment, yes, people don’t want to spend time on repeatable tasks, on things which a computer can do better than you and I can do. I have this constant struggle with my kid nowadays as to why do I need to learn grammar when there’s Grammarly? But that’s a different matter.

    But I think it’s a similar mindset going through every individual in the workforce, as to am I really adding value in the workplace, and am I being more productive, which in turn translates is the organization being more productive, which in turn translates to is the economy and the country being more productive.

    So, I think the bump towards productivity is definitely a goal that people are more concerned about, and you hear the other side of this, which is, as you pointed out, is the digitization of the workplace is the digitization of all economy. That’s in progress.

    We’ve called that using various phrases – software eating of the world, or the API economy – whatever term that you want to use. But we are moving towards a world where software is critical in driving everything that we do. Software in terms of automation, or even beyond that, is definitely key to whatever we do.

    Michael Vizard: Not too long ago we all thought we’d be running around by flying cars by now, and that IT would be easy. We’ve seen neither, and it looks like IT is getting more complex than ever. So, my question to you is is IT getting to the point where it is just too complex to manually deal with and we need automation, because we are seeing all these microservices, serverless frameworks.

    There’s all our existing monolithic applications, it’s distributed all the way out to the edge now. Have we reached some sort of inflection point?

    Vijoy Pandey: Yeah, I think to your point IT is definitely way more complex than it was even a decade ago, and I think the crux of the matter is that the way you are building applications and all of the digitization that we talked about is actually taking place in a very, very distributed manner.

    So, as an application developer, first and foremost, we at Cisco like to say that the application is your brand. So, if I am a bank, how my customers interact with the apps that I build defines me, my company, my bank, as the brand. Because if bank A has more capabilities in their software, their mobile app, versus bank B, I will migrate towards bank A.

    So, I think the application is becoming the front end to everything customer experience is all about. So, if you take that notion and play it out, that means the application developer that is developing those applications is under extreme pressure to deliver velocity behind features, do deliver trust with the data of the customers, to deliver uptime and security and so on and so forth.

    So, which means that they are picking and choosing all of these APIs that exist anywhere to make their job faster, easier more secure, more trustworthy. So, if you think about that kind of an environment, as a developer, I’m picking APIs from cloud providers, SaaS providers, I have legacy systems, I have transaction systems, I have edge devices, in the case of a bank. It might be sitting at a branch office.

    I have all of these APIs and systems that I need to interface with just to build one particular app or feature. So, in this kind of a distributed environment, think about the IT – more IT people, right? It’s like I’m trying to build a platform that caters to these kind of demands, and so it is definitely getting more complex, it’s getting more distributed, and every provider in the distributed environment has their own semantics, their own lifecycle management behind their APIs and their infrastructures.

    So, automation – I mean, it’s just humanly impossible to not just deploy but even manage and observe such a highly distributed – and secure, by the way – such a highly distributed system. So, automation is key to doing all of this, a direction automation, to me, is discoverability.

    It’s intent-based, it’s security, which is there’s no longer a perimeter of security, and it’s observability across all of these end points, API to mainframe. That is key to moving forward.

    Michael Vizard: Do you think as we go along that organizations – at least some of them I talked to, it’s almost like a chicken and an egg kind of issue. They have so much legacy stuff that can’t be automated that they can’t invest in automation, and they can’t necessarily buy all new platforms tomorrow. So, how do we get over the automation hump to kind of get from point A to point B without necessarily breaking the IT budget?

    Vijoy Pandey: Yeah, that’s a great point. I think some of that, I’ve dealt with in my previous lives as well. The way to do that is – and there’s no questions about it, that for some period of time, there is going to be more chaos and more money spent than before that time or after that time.

    So, we just have to acknowledge that as vendors, as customers, as organizations, that for some period of time, there’s going to be turmoil. That’s the way, at least, I’ve handled it in the past, where you say let’s put milestones, where we say maybe we look after a pocket of the organization, and say we’re going to build this out in a highly automated, distributed, cloud-first, API-first manner.

    This part of the application, this part of the infrastructure goes out and does that. To do that, we’re going to do a clean slate process here. So, we’ll think about – we won’t get ourselves bound to organizational boundaries, skill set boundaries – that is very hard to do. Most people’s jobs, peoples’ skill sets, organizational structures, all of that.

    But we have to try in some pockets, and then give ourselves strict guidelines and metrics, and try and meet those metrics. If we meet those metrics, the resulting outcome is that I will be spending less moving forward than I’m spending today.

    So, I might spend a little bit more in getting maybe SREs or software engineers, and marrying them up with IT folks or architects, and getting something going. I’ll give myself a timeline of let’s say a year or 18 months; it cannot be longer than that, otherwise it’s a science project. 

    But after those 18 months, these are the metrics I’m going to come back to. I’ll get X percent improvement in productivity, and Y percent reduction in head count, let’s say. We shall measure ourselves to that objective, and I’ve seen that work.

    If it works – and start with something simpler. But go all the way, don’t go 80 percent. Let’s not do 80 percent automation or 80 percent of the use cases. Hundred percent automation, 100 percent of the use cases for this pocket of your environment, and then grow that out over time.

    Michael Vizard: We, of course, hear a lot about artificial intelligent and AI Ops. Are the machines gonna save us from ourselves? What’s the reality of AI?

    Vijoy Pandey: To me, AI is a tool, just like all of the other tools that we’ve talked about, which is we’ve talked about automation or infrastructure as code, we’ve talked about cloud native and serverless and microservices. Each one of these tools, programming and scriptings tools.

    So, all of these tools bring in something to the table, and infrastructure as code brings in consistency and intent-based infrastructures, and serverless and microservices, or cloud-native, bring in immutable architectures.

    The fact that you can grow and scale out and do all of those things, and availability goes through the roof and velocity goes through the roof. Similarly, AI and ML bring in insights to the table where it was humanly, again, impossible to do that just by looking at the vast variety of data and the deluge of data coming our way.

    If we could just take all of that – and it’s all unstructured. So, if I could take all of that and somehow put it in a structured database and somehow make sense of it as an individual, sure, we don’t need the AI or ML. But if I need to take all of that unstructured data and make some sense out of it, there’s no other way out, and I do need AI and ML.

    I mean, I do need some statistical mechanism first, to figure out and make some sense out of it. I do need AI/ML, maybe deep-learning, to make some sense out of it. But then I need to marry that tool with subject matter expertise, I need to marry that tool with what I as an individual, or as humans, we’ve learned in the past, because AI doesn’t have that context.

    Yes, we can do learning, all sorts of learning, but it doesn’t always work in all kinds of environments. We need to marry that with subject matter expertise, with some boundary conditions, and then we need to marry it with actions. Because AI/ML is gonna give us insights, but somebody needs to take actions on the insights.

    So to me, it’s a tool in the toolbox, and we need to leverage it when it makes sense. We need to rely on subject matter expertise when it makes sense, and eventually things will get to a point where we need to go to the next level of abstraction. 

    So, it’s always a game of moving that level of abstraction higher and higher, and that’s what we are after. So, maybe someday there will be flying cars and robots that will take all our jobs, but not right now.

    Michael Vizard: How do I bridge this divide in IT that maybe we don’t talk enough about, but there’s clearly a DevOps community that’s very programming-centric. The use APIs. Then there’s traditional IT administrators that use ITSM tools. They tend to be more graphical in nature. As we move forward with automation, do you think that those two camps are gonna converge, or how will this all play out?

    Vijoy Pandey: In my opinion, I think they have to converge. I think each one of those pieces have their space in the hierarchy of things. One of the things I learned pretty early on in one of my previous lives is what good is a dashboard if you cannot take an action on it?

    So, if you think about all dashboards that exist today, eventually, there is data being presented in a certain way about a certain problem, so that somebody can look at that and take an action. If you think about infrastructure as code, it’s exactly that.

    It’s basically let’s remove the dashboard, and let’s figure out what goes – triggers that, that allow me to take those preset actions. Let’s try and remove the action of a human looking at a dashboard, thinking about it, and taking some action on it.

    Now, again, I’m describing utopia, but I think that’s where, as engineers, as operations folks, we all need to move towards. To me, dashboards are a good start when the problem is less well understood. As we understand the problems better, we need to move towards code.

    Dashboards will still have their place in helping us understand more and more complex problems, but as problems are better understood, they need to move towards code. And that’s the way at least I think through it.

    Michael Vizard: All right, so automation needs to be our new North Star, as it were. Hey, Vijoy, thanks for being on the show.

    Vijoy Pandey: Thank you so much, it was a pleasure, and I enjoyed our conversation.

    Michael Vizard: All right, back to you guys in the studio.

  • NewOps? AIOps? NoOps? Just Don’t Call Me Late for Dinner

    NewOps? AIOps? NoOps? Just Don’t Call Me Late for Dinner

    Once again, we are seeing an uptick in the use of the term NoOps. I always felt that NoOps was a misleading and, in fact, empty phrase. I don’t care what magic you think you have; you are never going to eliminate the need to operate your software, applications and infrastructure.

    I first heard the term NoOps early in the maturation curve of DevOps. Back then, the idea seemed to be that Dev was going to absorb Ops. Between that and the cloud, there really wasn’t a role for traditional Ops to deploy. Managing apps would be easy with the cloud and automation. At least, that was the pie-in-the-sky thinking—but I never bought that.  

    There were other terms that popped up, like NewOps and AIOps, though that became something else entirely. But really, I think the rise of the systems reliability engineer (SRE) role put the NoOps movement in its grave (where it probably belonged). SRE became the shiny new identity of the Ops crowd and SRE continues to be one of the most popular topics here on devopsy.kinsta.cloud.

    This latest incarnation of NoOps seems to be a little different. From what I have seen, it is not really NoOps; instead, it is more of a “not your Ops to worry about” movement. It is shifting who is responsible for Ops from the company developing and using the apps to a service provider (or SaaS provider) who is responsible for Ops. It is more a “MyOps” not “YourOps” movement, but there is still most certainly an Ops there.

    In my neighborhood growing up, we used to have a saying, “I don’t care what you call me, just don’t call me late for dinner.”  Originally, to me, NoOps was very much like that. We changed the name of something, but it didn’t go away or fundamentally change the thing itself.

    Now, we still have Ops, it is just a question of who is doing it. That is not NoOps to me. It is “somebody is doing MyOps for me.” 

    We saw a similar pattern in security. The idea of outsourcing security was never called “NoSec,” because the idea of no security is, frankly, downright scary. Instead, it just meant relying on a cloud vendor or an MSSP to handle your security for you; it was outsourcing your security. An important lesson learned from that was that you can outsource your security ops, but you can’t escape your security responsibility. That is to say, when your customers’ information is breached, saying “We had someone doing this for us!” did not absolve you of responsibility.

    The same thing holds true for this new “OutsourceOps.” The outsourcer may do a better job than you at Ops. They may give you SLAs and SLOs that give you reasonable expectations of performance and remedies if those SLAs and SLOs are not met. But it is still your company’s name and reputation on the line.

    So is what we seeing as NoOps really NoOps? No, it is Outsourced Ops. But as we said in the old neighborhood, I don’t care what you call it, just don’t call it late for dinner.

  • Techstrong TV: Scratching the Surface of Testing Through AI

    Techstrong TV: Scratching the Surface of Testing Through AI

    Mark, Torsten and Alan discuss the findings of the “Disrupting the Economics of Software Testing Through AI” report. The report identifies critical factors that hinder software engineering and DevOps teams including the escalating costs of quality control, and growing complexity associated with the increasing release velocity, number of smart devices, operating systems, and programming languages. The video and a transcript of the conversation are below.

    Announcer:                 This is Digital Anarchist.


    Interviewer:                Hey, everyone. Welcome to another segment here on Techstrong TV. I am really happy to tell you, introduce our guests for this next segment. First of all, he’s a returning guest with us. He’s from our friends at Applitools. It’s Mark Lambert. Hey, Mark. How are you, man?


    Interviewee 1:             Fantastic. Thank you, Alan. Great to have you – for you to have me on. Yeah, great to talk to you.


    Interviewer:                Absolutely. And then joining Mark and I today is Torsten Volk. Torsten is – I just drew a blank – EMA, right? Enterprise Management Associates?


    Interviewee 2:             Yes, exactly.


    Interviewer:                Yep. And we were talking off camera. Torsten is actually a friend of our friend, Andi Mann, who he knew or was his predecessor at EMA 11 years ago.


    Interviewee 2:             Yeah.


    Interviewer:                And, Torsten, welcome to Techstrong TV. It’s great to have you on.


    Interviewee 2:             Thank you very much. It’s awesome to be here.


    Interviewer:                Thank you. So, guys, look, Applitools, leader in visual testing. We’ve had, beyond Mark we’ve had many Applitools people on over the last almost two years now of doing Techstrong TV, so I think our audience is familiar. But just in case people aren’t, Mark, how about a little quick Applitools backgrounder?


    Interviewee 1:             Sure, yeah. So Applitools is known for inventing Visual AI, so helping software development teams accelerate their releases by mimicking the human eye and brain and how we as humans analyze computer screens, highlighting differences and issues within your UI so you can do not only visual testing, but also fundamentally change and modernize your functional test automation. So it’s really the glue that plugs right into your existing practices, so Selenium, Cypress, we support over 50 SDKs. There’s a free account as well, so you can get in there and get going, kind of feel the water, so to speak. But what we’re seeing is that it’s helping leading brands accelerate their digital experiences, and really it ties directly into the research obviously that Torsten’s been doing around AI and how that can help organizations disrupt the economics of software testing.


    Interviewer:                Love it. And, Torsten, look, I know EMA from before 2010 even, but for those folks who maybe, you know, a lot of our audience are technical people. They may not necessarily follow the analyst beat. Why don’t you give them a little EMA background?


    Interviewee 2:             My boss describes it always as the industry and analyst firm for enterprise grade solutions, and in the beginning – I’ve been here for a while. In the beginning I was always a little bit wondering, you know, what does that really mean? And what it at the end of the day means is we have all of those emerging technologies coming up, especially in the area of artificial intelligence and cloud native applications and intelligent automation, and what we are looking at is really how can we leverage those capabilities within an enterprise setting. So once the dust has settled and we’ve all gorged ourselves, you know, by consuming the leading edge of all of those tools, the question then is how do I expand that footprint of those tools across the enterprise so that the enterprise as a whole is more competitive in the end. So basically projecting those constraints of all of those cool new products and technologies into the enterprise, that is really what EMA is all about. And my specific practice is focused, as you can see in the background here, as one of my research graphics is focused on looking at machine learning, deep learning, reinforcement learning, and how those capabilities can enhance the enterprise.


    Interviewer:                I get it. Great use of the background, Torsten. Thank you. All right. So, Mark, we’ve got all that out of the way. Let’s jump into what we really want to talk on today, and I’m gonna let you kick it off if it’s okay.


    Interviewee 1:             Yeah, I’d love to. Thank you. So yeah, so recent report from EMA, and Torsten is the author and I’ll kind of throw the ball to him very quickly, obviously, but really talking about how artificial intelligence and machine learning is revolutionizing the software testing space, and is really important right now because there’s so much buzz around AI, machine learning, and kind of where it comes in. You want to understand where does the rubber meet the road? What is impactful today? What’s impactful for the future? And then what’s, what are the drivers that are getting us there? So I mean, Torsten, I’ll turn over to you, and maybe kind of like talk about some of the capabilities that you talk about in the report and the challenges that they, that you’ve seen come into play.


    Interviewee 2:             We started that report by looking at the key pain points, like we start almost all of our reports. Right? What is not sustainable anymore in a specific discipline, and in this case it’s test engineering. And we have pressure factors. One of them is that we, the business needs us to release software a lot more often, and in a really granular manner where somebody’s asking for a feature capability and the software development team is expected to release that thing very quickly, ideally in an ongoing manner. So that is one part, and the second part is that the end users are very, have become very much more diverse than they even were in the recent past, where we have multiple charts where we show the escalation of the number of devices with different screens, different processors, a different network connection, different interfaces for your fingers and for voice control. And all of those things make testing much, much more difficult, and one of my favorite parts always is the little war stories that you get told. Right?

    So in the beginning when we look at al the material that we have, we talk to a lot of developers and test engineers and DevOps guys, and my war stories or their war stories always started with, “Oh, yeah, regression testing, Torsten. That is really not doable anymore. This is kind of a dreamland that you are living in as an analyst if you think that we can regression test all of those releases. It’s just too much, and it would take forever to be able to do that.” So if we can’t regression test, we are running a significant risk, Mark, that something goes awry. Right? We always are sure that in theory things should work, but in real life there are combinations of technologies, of code functions, that they then don’t work. And that’s where we start with artificial intelligence and this whole pair of eyes, Mark, that you are describing, right, where you say, “Oh, yeah, my test engineers don’t have to be that pair of eyes that check through dozens of boxes and just say yes, yes, yes, yes, yes everywhere, and then also overlook some things.

    But that pair of eyes is something more. It’s something that has a certain degree of – when I say understanding, I think I’m gonna embarrass myself, but it has a certain degree of ability to comprehend – maybe that’s the same word – but to pick up things of a similar character and to categorize and cluster things in a manner that makes sense for human beings then to review, Mark. Right? And that is –


    Interviewee 1:             Yeah.


    Interviewee 2:             – where a tool like Applitools is very interesting, and also unique in the marketplace, right, where it’s a pair of eyes that you guys are building.


    Interviewee 1:             Yeah, and I think that talks – I mean your research touches on several different areas where AI comes in, and visual inspection, which is obviously where Applitools fits, is really a highly impactful and the most impactful today of those techniques because it does so many different things. So first of all, obviously there’s the streamlining of the manual review effort. Right? So I’ve got this explosion of devices. How do I check them all? Well, because of the high level of accuracy of Applitools Visual AI, and it’s been trained on over a billion images and has got four nines of accuracy, so what that means is as a human I don’t have to review tens or hundreds of screenshots. I’m just focused in on a very small subset. But that’s just the first part of it, because then you layer on top of that and this explosion of release velocity, increasing device combinations, and as well as the, just the complexity of the application and so many things out of your control, you need help in reviewing the volumes of data and really saying, okay, all of these things kind of look like the same.

    So and then bringing them together. I talk about basically sorting your visual review into different stacks of paper, so for example I might have 76 screens that have a visual defect, but I can break those down into two categories of 40 and 36. And those types of techniques go beyond just the basic pixel dipping approach, which is the one that would be a traditional visual testing technology, and really the ability to categorize that you talk about, Torsten, is the key driver that, or the key foundation that all of these things get built on top of. So it’s a really powerful technique, and as I said earlier plugs right into existing, so you don’t have to rip and replace. That’s one of the things that a lot of AI technology today is say, okay, it’s great, but you have to build it all new in this track. The thing that is really powerful with Applitools is we plug right into your existing frameworks, open source as well as third-party commercial tools, and then we elevate the process with the dashboard to really enable cross-team collaboration. So it’s not just your testers or your test automation or developers that are engaged. Your domain experts, even other parts of the team like UI, UX design, for example, get to be involved in that collaboration process.


    Interviewee 2:             Yes, and we see often that communication is key, and it’s not happening in testing where we have those more and more decentralized product teams that are doing their own thing with their own toolkits and pipelines, but they’re not really benefiting from what other teams are finding. And so coming back to that horrible list approach, right, where you have, you check those boxes or you don’t check them. Right? So it’s a very monotonous affair as a human being to review this, but then once you’ve reviewed it usually it comes back to you again and again, and then it comes back and hits other people in that organization because there is no communication and there’s no unified platform to retain that knowledge. Right? And with reinforcement learning, you can teach the system what it needs to come back to a human with, and then what it shouldn’t. So if one team makes decisions, all the other teams are benefiting from that and it’s less and less of this toil type of task where you just also as a human tend to make mistakes and it’s just not scalable. Right? So that whole scalability aspect is an interesting one that deep learning and reinforcement learning brings us there, Mark.


    Interviewee 1:             Yeah, you hit on the key things. Right? You’re scaling to meet the current demands of release velocity, shorter release cycles. But the other thing I always think about when I think about AI machine learning and how it can help us from a software quality perspective, it’s an assistive technology so you’re reducing or removing mundane and repetitive tasks, which in themselves are error prone. Humans are great at creative work. We’re terrible at boring, monotonous things  because we miss stuff. Whereas leveraging AI, and especially Applitools Visual AI, it’s highlighting those things. So that same example I talked about, 76 screens, you’re gonna miss stuff. If you’re looking at them all and you’re like, oh, it’s the same. It’s the same. It’s the same. But the Visual AI will identify key differences between the 76 images to really kind of like focus and improve the efforts.


    Interviewee 2:             Yeah. And that gets even when you look a little bit into the future, Mark. I know that you can’t share roadmap items, but that whole idea of having a Visual AI can go even beyond just user interface testing, right, where you can do sanity checks in certain areas, where you say, “Oh, yeah, no, that number can never be a billion because of what I know about the data in the background.” Right? And a lot of the things that come through that we continuously see coming through when you release and then you don’t want to be the one in the test team to hold off a, to hold back a release in the middle of the night.

    It’s funny that when I was young and had a ton of hair still, that was what happened, and it’s still happening today just as much, right, where people think, “Oh, no. I shouldn’t be the one who says that. I think it’s all fine. Let’s sign off on that.” Right? So the release data kind of getting mushy and mushy and mushier in those areas, and that ability to say, “Oh, yeah, I had somebody look over it, and something horrible had happened,” some compliance violation or some crazy numbers in the shopping cart that can never add up. Can be even simple things where it’s, oh, this cost a billion dollars, or it’s euros instead of dollars but we are in a certain country. Those are things that you can catch more and more.


    Interviewer:                Fair. Guys, I feel like you didn’t let me, I didn’t get much of any words in here –


    Interviewee 1:             We feel the same way.


    Interviewer:                – but it’s okay. You know, I would – but I try to be a good host and let the guests talk, and you guys had it. Right? This is something, Torsten, you’re obviously very, very passionate and involved in and, Mark, it’s kind of, it’s your life. Right? And so I let it go. However, we are just about out of time, believe it or not, and we went on here for 15-plus minutes on this. But –


    Interviewee 1:             Can I just let people know where they can get the report? Would that –


    Interviewer:                That’s what I was going to ask you.


    Interviewee 1:             Sorry, I just wanted to make – yeah. So –


    Interviewer:                Go ahead.


    Interviewee 1:             – yeah, go to applitools.com/ema and you’ll be able to download the full report and access all the information there. So yeah, thank you, Alan.


    Interviewer:                Thank you, Mark. So it’s applitools.com/ema.


    Interviewee 1:             Yes.


    Interviewer:                Which also happens to be where Torsten works, at EMA, Enterprise Management Associates. Guys, it sounds like it was a really worthwhile research project here with some really good results and really good findings and insights. Look, this whole, there’s a reason Applitools has been as successful as it has. The whole idea of AI and testing is like peanut butter and chocolate in some way, and we can – but we barely scratched the surface in a lot of ways, right? There’s so much more yet to be done, and looking forward to hearing more about it in the future.


    Interviewee 1:             Yeah.


    Interviewer:                All right.


    Interviewee 1:             Thank you, Alan. Look forward to talking again soon.


    Interviewee 2:             Thank you.


    Interviewer:                All righty. Excellent. Torsten Volk, EMA, of course Mark Lambert from Applitools here on Techstrong TV. We’re gonna take a break and we’ll be right back with our next guest.


    [End of Audio]

  • Techstrong TV: The Use of AI in Low-Code

    Techstrong TV: The Use of AI in Low-Code

    In this talk, Dave Wright, Chief Innovation Officer of ServiceNow, talks about how low-code is accelerating organizations’ AI journeys and is expanding into new, scalable use cases as we move into a post-COVID-19 world. The video and a transcript of the conversation are below.

    Recorded Voice:         This is Digital Anarchist.


    Charlene O’Hanlon:   Hey, everybody. Welcome back to TechStrong TV. I am Charlene O’Hanlon and I’m here now with Dave Wright, who is the chief innovation officer over at ServiceNow. Dave, thanks so much for taking a couple minutes and talking with me today. Always appreciate it.


    Dave Wright:              No, thanks for the opportunity.


    Charlene O’Hanlon:   Okay, great. So first, I’m really interested in your title, chief innovation officer. What’s that all about? Tell me.


    Dave Wright:              So it has multiple roles I suppose. Part of it is looking at how we understand what customers are doing with the products, so looking at customer stories, building out reference cases. Some of it is looking at what we do around the world of evangelism and looking at how we talk about what the technology does.

    And a lot of it is around looking at new technology and trying to understand, is that new technology gonna impact us in any way, or do we need to potentially look at some of these new areas of areas that we can move into to as well. So, it’s pretty cool. I get to spend a lot of time researching things. I get to speak to people, everyone from psychiatrists and sociologists all the way through to technologists. So it’s a pretty cool job.


    Charlene O’Hanlon:   Yeah, sounds pretty nifty. All right. Well, I wanna talk to you about low-code and it’s something that – We’ve been talking a lot about low-code over the last 18 months or so. It seems to have – I almost kind of feel like we’ve jumped the shark on the topic, but I wanna talk to you about artificial intelligence and the use of AI in low-code as organizations are swiftly adopting it and recognizing the real value that low-code has for the business.

    Obviously, AI is kind of icing on the cake, if you will, if it’s done correctly. So, interested in getting your thoughts on the role of AI in low-code and maybe kind of see what’s going on in the industry, what you’re seeing there.


    Dave Wright:              So I think a lot of times when people produce low-code applications, one of the things they’re really trying to drive is adoption of those applications. So when you build something, it’s gotta be better than whatever people were using before. And I think that when people start to integrate artificial intelligence into those low-code apps, what actually does is it starts to elevate the experience a little bit.

    So, it makes sure that the application you create actually delivers smarter outcomes. And this can be anything from ease of use of the application. So how do you start to process data and collect data in a different way? Or it can be the actions that the application then takes. So how does it learn from more and more people using the system to gradually improve and modify the experience to make it easier to use?

    So I think those are elements that you see people building in conversationally, or you see people building in with ML models. I think there’s probably a second part of the conversation, and maybe we’re not quite there yet, but I think in the future, you’ll actually start to see artificial intelligence influence the coding side of low-code. So actually helping people develop those applications as well, but we can go into that a bit more later.


    Charlene O’Hanlon:   Yeah. Well, that’s actually kind of one of the things that I was thinking about, because if we’re talking about low-code as a business enabler, so obviously we’ve got a lot of folks out there creating code or creating applications using low-code, and who don’t really have that experience in coding.

    So I imagine AI is kind of like a tutor to – That’s how I view it as AI within the low code application being used as kind of maybe the conscience of the voice of reasons. Like, “Are you really sure you wanna do that in that application?” Or just kind of helping them build a better application and user experience as part of that.

    So I guess we’re kind of talking about two different things. We’re talking about low-code and AI, because we could be building AI application using low-code technologies, or we could be using AI within the low-code application.

    So, are both of them kind of happening right now? And then, do we really need to distinguish exactly what we’re talking about in our conversation? And we could be talking about both of them, which is fine. I’m totally okay with that, but –


    Dave Wright:              So I think the both happening, the one that’s happening the most is people using AI within low-code applications. So that’s gonna happen on multiple levels. So it could be I’m building an application where part of it is collecting data or it’s interfacing to a person. So that might be the inclusion of things like virtual agents.

    And this is where you start to get into the real benefit of low-code developments. When you’ve got pro-code developments, you go out there and you build something, you’ve got a program of entirely skill that can build out exactly the interface you want, can build out the data structure.

    When it comes to something like that, building a national language understanding conversation, , it’s not the programming that’s hard, it’s the subject matter expertise, it’s knowing what to ask and what to ask next.

    So if you can put that capability to build those conversations into the hand of the SMA without them having to be some programming god, then it means that the conversations flow more naturally and you get what you want. So I think being able to enable people to build those types of interfaces when they haven’t got the programming skills, really speeds up what happens in the world of low-code development.

    And then I think you have the second part of it, where perhaps it’s using machine learning algorithms to then simplify processes. So, a great example of that is, let’s say you build an application and in that application, you’re gonna describe a certain type of request that you’ve got or something that you need.

    And what you do in a traditional non-AI powered system is, then you walk the user through some system where they had to categorize what type of issue it was. And then based on the categorization, you’d pass it to someone to execute. But if you can put, let’s say a machine learning step in that, where it looks at the description, and it goes, “Okay, based on this, I know what type of request this is, so I’m gonna categorize it.”

    Then you start to, A, remove the potential for human failure, where someone miscategorizes, but you also start to think about how you design your interfaces, because now you don’t need drop-down lists.

    So you merge and you take that app, you mobilize it, you put it on a mobile device. You can have a much more cleaner, simpler interface, because a lot of the work around data collection and data determinations being done by ML algorithms sitting in the background.


    Charlene O’Hanlon:   That’s interesting. I hear so much about low-code actually being used within an organization to create kind of those secondary internal business applications or internal business processes, and then kind of leaving the big stuff, the customer-facing stuff out to the developers themselves. But it sounds like, with this infusion of AI into the low-code applications, that may not necessarily be true forever?


    Dave Wright:              Probably not. I mean, I think the use case that you talked about them, where people are doing it for business applications, or maybe not business applications, the way I see people building them are applications for core operations. And it depends which area of business you go to.

    So you might go to a financial Institute and they’re looking at how they do loan processing, or you might go to a hospital and they might be looking at how they do clinician onboarding or how they set own emergency medical centers. So it tends to be something that’s very close to your core business, what you’re all about, that things don’t necessarily come off the shelf and that you need that specialist knowledge to build. So that’s where you see it now.

    I think moving forward, perhaps we start to see this concept of people using it for much wider use cases and starting to build bigger and bigger applications, or perhaps even more interesting, starting to chain the applications together. So there is also wrong application is actually driving something in another.

    And then we have concepts like the bigger AI models that we start to see emerging now. So some of these large language learning models, the GCP three-type concepts where you are starting to look at the capability to be able to describe an application and then have AI build that application based on the description. That’s an interesting development, and it’ll be interesting to see where that goes in the next two or three years.


    Charlene O’Hanlon:   Yeah, that is definitely something that I think is fascinating, but it’s also slightly frightening if you just tell the robot to go build something or the machine to go build it. So, with that in mind though, are we starting to see a shift in the way developers, their roles moving forward, because we are in effect kind of taking away at least some of the remote or the rote tasks that they do these days, kind of the lower through low-code and AI. So how do you see that changing, how developers view their jobs and what they actually do?


    Dave Wright:              So I think a lot of the things with artificial intelligence in the role of developments will be the same that we’ve seen the way that artificial intelligence works in the regular world. So what most people use artificial intelligence for is to either improve the accuracy or remove the mundaneness to try and take some of the stuff that people just don’t wanna focus on away.

    And I think that’s where you’ll start to see the first AI use cases in the world of developments where people are looking at standard routines that they use, or they’re looking at tasks that they just – They wanna focus on the complex side of it and have the simple side of the stuff just built from –

    So that coordination and that orchestration of being able to take what you need to be able to build the application. I think it’ll be it more AI as an assistant to programmers. I did a presentation a few weeks ago and someone said, “Does this mean AI is gonna replace all the programmers in the world?” And that’s not true. It’s no more than it’s gonna replace all the artists in the world, so that [crosstalk] in the thought process still sits in a program’s mind.


    Charlene O’Hanlon:   Yeah. And there’s also a level of experience and expertise that developers bring that low-code never could. If you’ve got somebody working with a low-code technology who is not a developer, they might not see the things that might trip up the program the way a developer might see.

    So I firmly believe that obviously there will always be a place for developers in the development environment, but I do certainly see the value of low-code. Even though I was joking at the top of our conversation that I kind of feel like low-code may have jumped the shark, but I think that there are so many different and practical use cases for low-code technology in organizations that are technology organizations, or they just happen to build sneakers or something like that.

    There’s always gonna be an application there where a part of what they do, whether it’s customer-facing or internal, they won’t necessarily have to even bother the developers or the IT part of the organization to get those things done. So yeah, I think low-code is actually going to kind of permeate the entire organization moving forward. It’s a matter of time. And I think AI is gonna be a huge enabler for that.


    Dave Wright:              I think so. I mean, if I look at our world, if I look at ITS ServiceNow’s world and how people build up on the platform there, we’ve done things like introduced the concept of app engine studio to make it simple for people to build apps if they can’t code. But then even on top of that, more and more people have said, “Hey, can we have standard templates?”

    Because a lot of people are gonna say, “Well, I’m gonna build an application.” And all the application really is, is an approval process, the way to track something being approved, or it’s a way to track leave, or it’s a way to track something that’s really simple that people do every day. “Can you just give me a template that allows me to go in and be able to do that?”

    So we’ve seen that concept already start to emerge, but the thing that always surprises me is, I’ll speak to businesses and some people say, “Well, even though you call it low-code people still need a bit of skill to be able to build these things. But I always think the irony of that is I’ve seen people do things in Excel that I couldn’t do in a million years.

    The complexity of the stuff they’ve got in the background, it’s like, “Wow, I don’t know if I can build a low-code app.” We’ve moved on quite a bit now, the concept of low code is available to everyone.


    Charlene O’Hanlon:   I think it’s amazing and I think it’s great technology. And we’ve been covering low-code on devopsy.kinsta.cloud for, going on five years now. So, it’s obviously been a technology that’s kind of been waiting in the wings for its moment. And the pandemic really highlighted its value to organizations.

    And I firmly believe it is here to stay and I’m excited about seeing how it can be extended in an organization and really bring a lot more business value than it is currently. So Dave, thank you so much for having the conversation with me, always enjoyable. And hopefully, maybe this time next year, we can have another conversation on the same topic and see where we are compared to where we are today.


    Dave Wright:              I would love to do that. All right. Thanks so much.


    Charlene O’Hanlon:   It sounds great. All right. All right. Well, thanks again, Dave, for your time. I really do appreciate it. All right, everybody, please stick around. We’ve got lots more TechStrong TV coming out. So stay tuned.


    [End of Audio]

  • MLOps Vs. DevOps: What’s the Difference?

    MLOps Vs. DevOps: What’s the Difference?

    Machine learning operations, or MLOps for short, is a key aspect of machine learning (ML) engineering that focuses on simplifying and accelerating the process of delivering ML models to production and maintaining and monitoring them. MLOps involves collaboration between different teams including data scientists, DevOps engineers, IT specialists and others.

    MLOps can help organizations create and improve the quality of their AI and machine learning solutions. Adopting MLOps allows machine learning engineers and data scientists to collaborate to improve model performance by implementing continuous integration and continuous deployment (CI/CD) practices. It accelerates the ML model development process by incorporating the appropriate monitoring, governance, and validation of ML models.

    What Is DevOps?

    DevOps combines the concepts of development and operations to describe a collaborative approach to performing the tasks usually associated with separate application development and IT operations teams. DevOps, in its broadest sense, is a philosophy that encourages improved communication and cooperation between these (and other) teams within an organization. 

    In its narrowest sense, DevOps refers to adopting practices that enable the deployment and maintenance of iterative application development, automation, and programmable infrastructure. It also includes changes in the workplace culture, like trust-building and bonding between developers, system administrators and other team members. DevOps aligns technology with business objectives and can transform the software delivery chain, job functions, services, tools and best practices.

    MLOps Vs. DevOps: Key Differences

    Here are some of the main differences between MLOps and traditional DevOps.

    Development

    The concept of development refers to different things in each model, with a slightly different CI/CD pipeline.

    DevOps:

    • Usually, the code creates an interface or application. 
    • The code is wrapped into an executable or artifact before being deployed and tested with a set of checks. 
    • Ideally, this automated cycle will continue until the final product is ready.

    MLOps:

    • The code enables the team to build or train machine learning models. 
    • The output artifacts include serialized files that can receive data inputs to generate inferences. 
    • Validation involves checking the trained model’s performance based on the test data.
    • This cycle should also continue until the model reaches a specified performance threshold.

    Version Control

    DevOps:

    • Version control typically only tracks changes to code and artifacts.
    • There are few metrics to track.

    MLOps: 

    • MLOps pipelines usually have more factors to track. Building and training an ML model involves an iterative experimentation cycle, requiring tracking of various metrics and components for each experiment (essential for later audits). 
    • Additional components to track include training datasets, model building code and model artifacts. 
    • Metrics include hyperparameters and model performance indicators, such as error rates.

    Reusability

    DevOps:

    • DevOps pipelines focus on repeatable processes.
    • Teams can mix and match processes without following a specific workflow.

    MLOps: 

    • MLOps pipelines repeatedly apply the same workflows. The common framework across projects helps improve consistency and allows teams to progress faster because they start with familiar processes. 
    • Project templates offer structure, enabling customization to address the unique requirements of each use case.
    • Uses centralized data management to consolidate the organization’s data to accelerate the discovery and training processes. Common approaches to centralization include a single source of truth and data warehouses.  

    Continuous Monitoring

    Monitoring is essential for both DevOps and MLOps, but for slightly different reasons.

    DevOps:

    • Site reliability engineering (SRE) has been trending over the past few years, emphasizing the need for monitoring software from development through to production deployment. 
    • The software does not degrade in the way an ML model does. 

    MLOps:

    • Machine learning models can degrade quickly, requiring constant monitoring and updating.
    • Conditions in the production environment affect the model’s accuracy. After deployment to production, the model starts generating predictions based on new data from the real world. This data is constantly changing and adapting, reducing model performance. 
    • MLOps ensures that algorithms remain production-ready by incorporating procedures to facilitate continuous monitoring and model retraining.

    Infrastructure

    DevOps and MLOps both rely heavily on cloud technology, but have different operational requirements.

    DevOps relies on infrastructure such as:

    • Infrastructure-as-code (IaC)
    • Build servers
    • CI/CD automation tools

    MLOps relies on infrastructure such as:

    • Deep learning and machine learning frameworks
    • Cloud storage for large datasets
    • GPUs for deep learning and computationally-intensive ML models

    DevOps and MLOps Trends

    Here are some of the major trends driving the development of DevOps and MLOps.

    GitOps

    A new evolution of the DevOps workflow, GitOps is a new paradigm for controlling and automating infrastructure. A Kubernetes-oriented paradigm enables developers and operations teams to manage Kubernetes clusters and deliver containerized applications using Git. Implementing Git workflows for operations and development teams allows developers to leverage Git pull requests to manage software deployments and infrastructure.

    GitOps incorporates existing development tools to manage cloud-native and cluster-based applications with CI/CD. It automatically deploys, monitors, and maintains cloud-native applications using a Git repository as the single source of truth.

    GitOps is a way to implement and maintain clusters in Kubernetes. Continuous delivery and deployment allow developers to build, test, and deploy software faster through incremental releases. Kubernetes continuous integration and runtime pipelines must be able to read and write files, update container repositories, and load containers from Git. GitOps helps businesses manage their infrastructure with version control, real-time monitoring, and alerting of configuration changes.

    Synthetic Data

    Synthetic data is any information generated artificially instead of collected from real events. Algorithms generate synthetic data for use as a replacement for operational and production test datasets. Synthetic datasets are also useful for validating mathematical models and training machine learning models.

    Benefits of synthetic data include:

    • Minimizing the constraints associated with using sensitive and regulated data.
    • Customizing data to specific requirements and conditions not available in real-world data.
    • Generating data for testing software quality and performance for DevOps teams.

    Codeless Machine Learning and AI

    Machine learning often involves computer code to set up and process model training, but this is not always the case. Codeless machine learning is a programming approach that eliminates the need for ML applications to go through time-consuming processes.

    Codeless ML eliminates the need for experts to develop system software. It is also simpler and cheaper to deploy and implement. Using drag-and-drop input during machine learning processes can simplify training efforts in the following ways:

    • Evaluating results.
    • Dragging and dropping training data.
    • Creating predictive reports.
    • Using plain-text queries.

    Codeless ML gives developers easy access to machine learning applications, but it is no substitute for an advanced, nuanced project. This approach is suitable for small businesses that lack the capital to maintain an in-house data science team.

    TinyML 

    TinyML is a new approach to machine learning and AI model development. It involves running models on devices with hardware restraints, such as microcontrollers powering smart vehicles, refrigerators and electric meters. This strategy is the best fit for these use cases because it speeds up the algorithm—there is no need for the data to go back and forth to a server. It is especially important on large servers and can speed up the entire ML development process.

    Running TinyML programs on an IoT edge device has many benefits:

    • Lower energy consumption.
    • Reduced latency.
    • User privacy guarantees.
    • Reduced bandwidth requirements.

    Using TinyML offers greater privacy because the computation process is entirely local. It consumes less power and bandwidth, resulting in lower latency because it doesn’t require sending data to a central location for processing. Industries that are taking advantage of this innovation include agriculture and healthcare. They typically use IoT devices embedded with a TinyML algorithm to monitor and predict real-world events using collected data.

    Conclusion

    In this article I covered the key differences between MLOps and DevOps:

    • Development—DevOps pipelines focus on developing a new version of a software product, while MLOps focuses on delivering a working machine learning model.
    • Version control—DevOps is mainly concerned with tracking binaries and software artifacts, while MLOps tracks additional factors like hyperparameters and model performance.
    • Reusability—DevOps and MLOps both strive to create reusable processes and pipelines, but use different strategies to achieve repeatability. 
    • Continuous monitoring—Monitoring is important to DevOps, but even more important in MLOps because models degrade in performance due to model and data drift.

    Finally, I covered a few key trends that will transform DevOps and MLOps in the near future. I hope this will be useful as you discover your place in the new and exciting development ecosystem.

  • Recession! DevOps Hiring Freeze | Data Centers Suck (Power) | Intel to ‘be’ Wi-Fi 7

    Recession! DevOps Hiring Freeze | Data Centers Suck (Power) | Intel to ‘be’ Wi-Fi 7

    Welcome to The Long View—where we peruse the news of the week and strip it to the essentials. Let’s work out what really matters.

    This week: Engineer jobs are being cut, cloud infrastructure is using too much energy, and Intel’s 802.11be silicon is alive. (more…)

  • Iterative Adds Registry to GitOps Portfolio for ML Models

    Iterative Adds Registry to GitOps Portfolio for ML Models

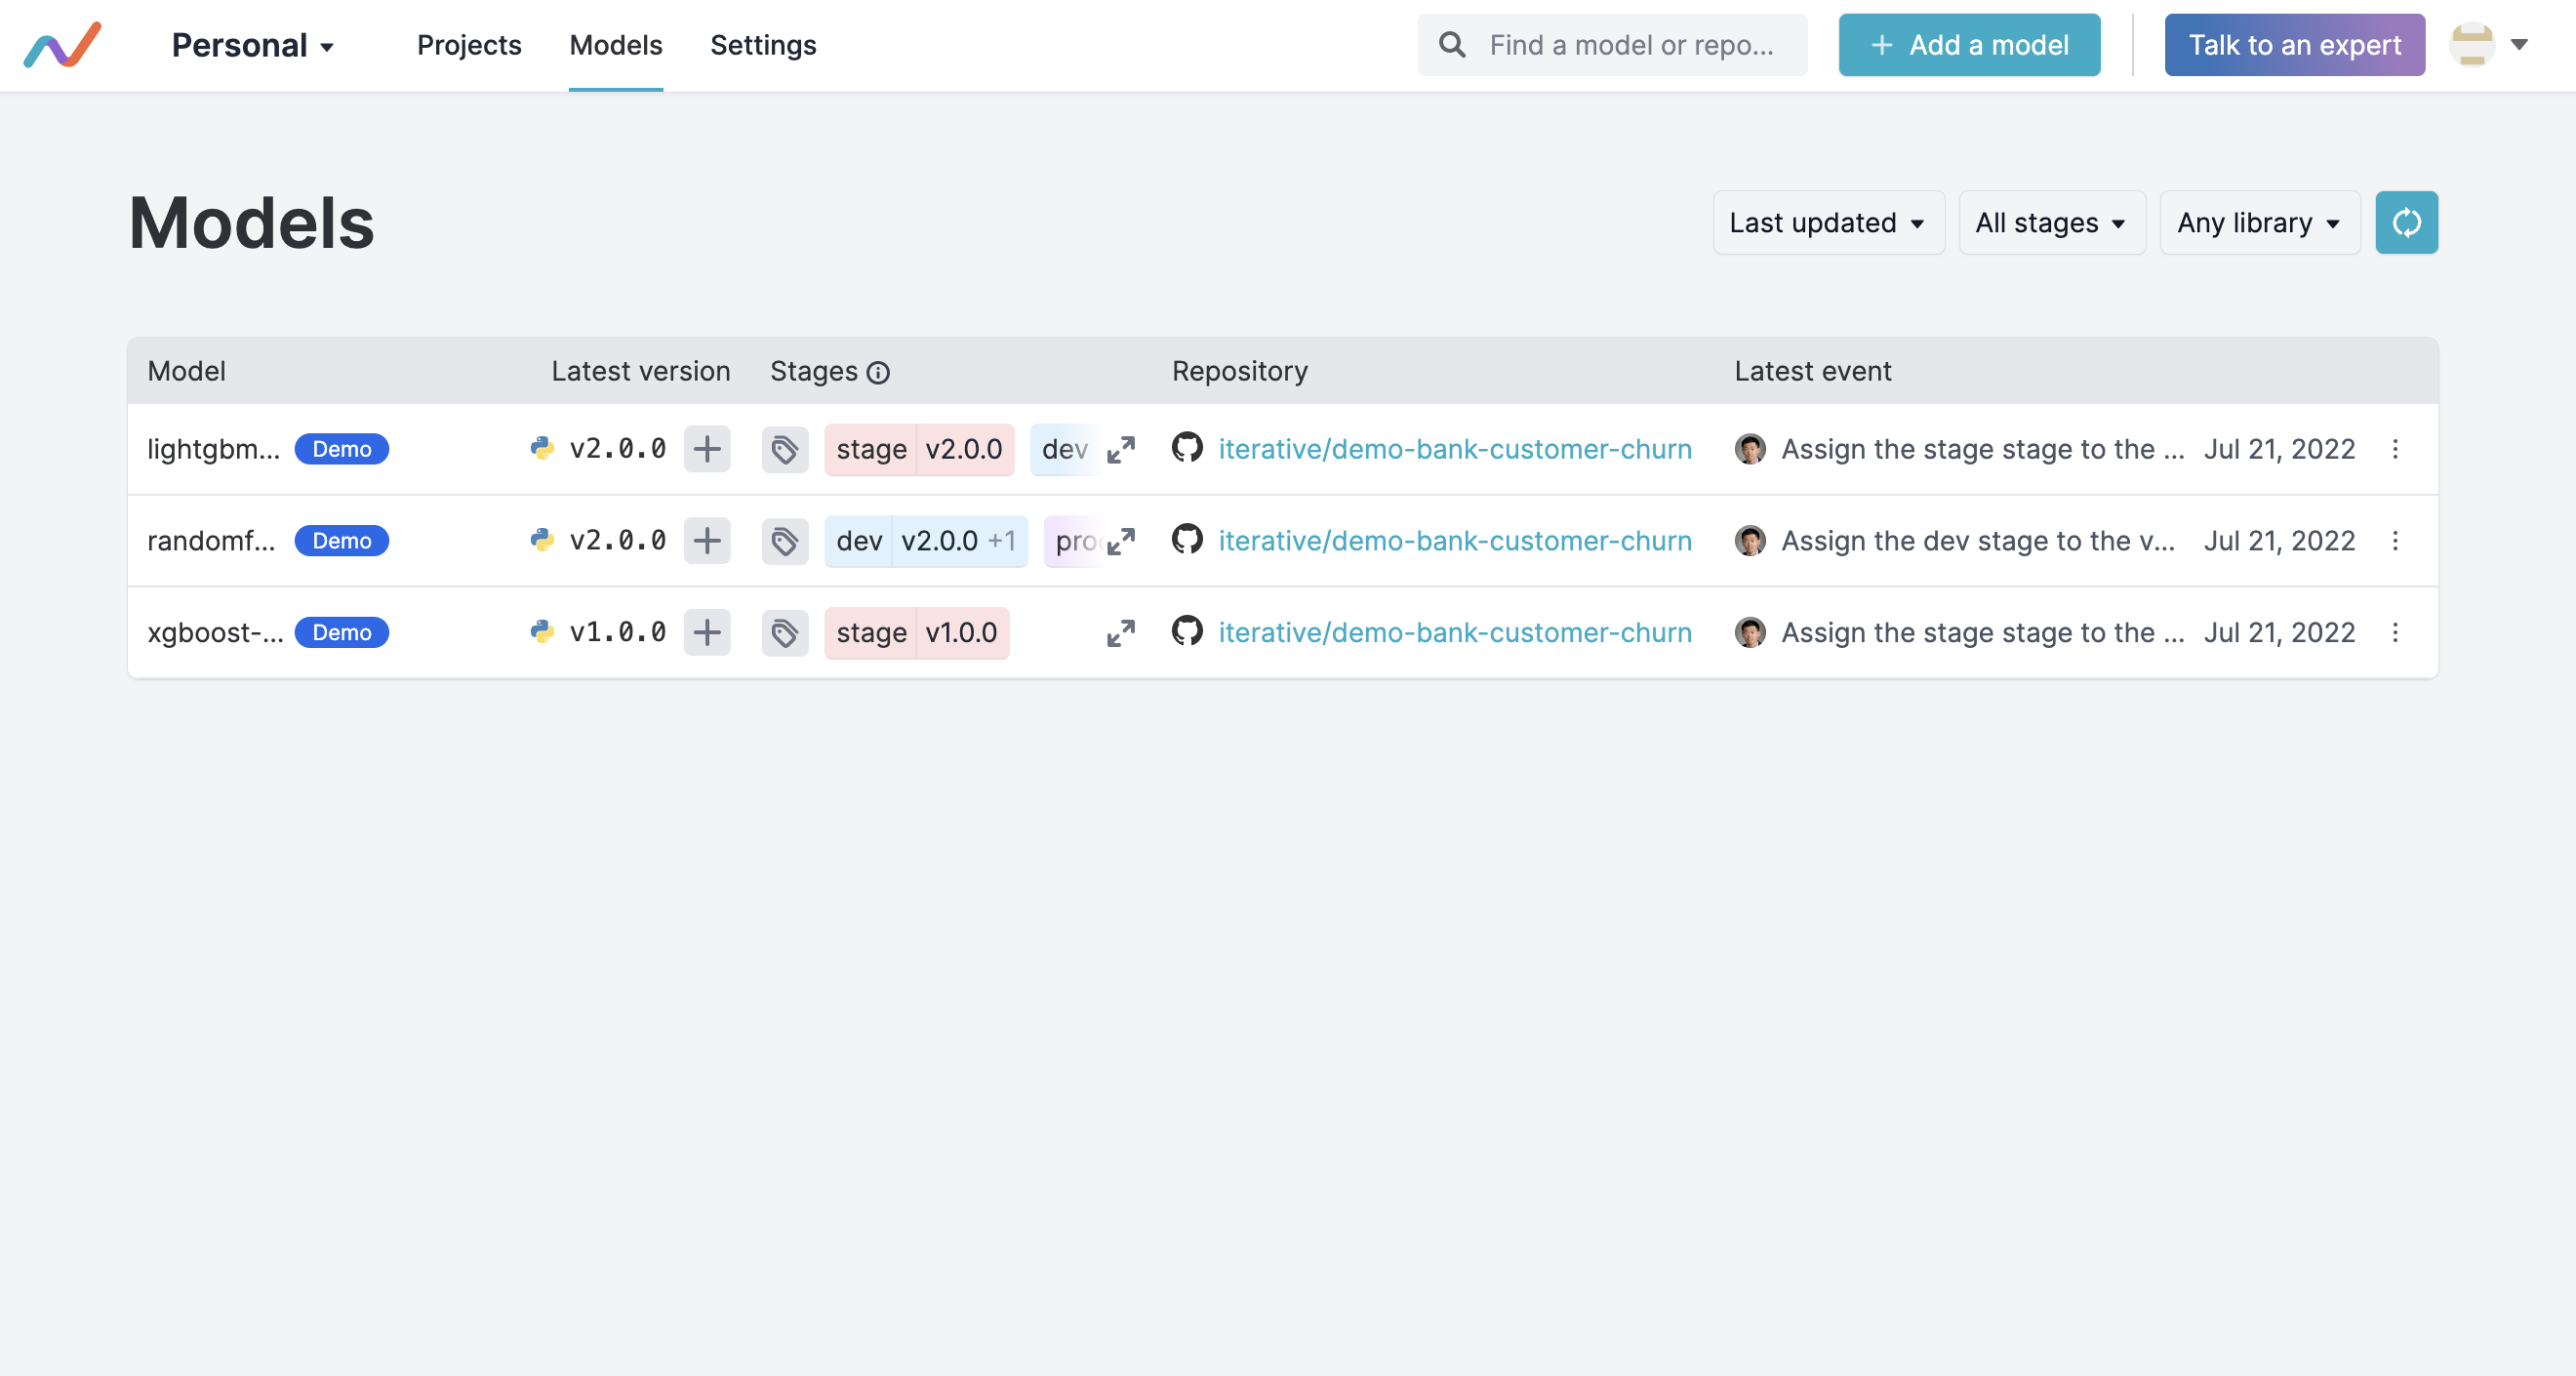
    Iterative added a registry for machine learning models to its portfolio of Git-based tools for infusing artificial intelligence into applications.

    Iterative CEO Dmitry Petrov said the Iterative Studio Model Registry is intended to make it easier for application development teams to track which models are being used as the number of applications infused with AI capabilities continues to grow.

    The Iterative Studio Model Registry, accessible via a graphical interface, command line interface or application programming interface (API), makes it simpler to explore models, including history, versions and stages, via a central dashboard. Teams can also identify the experiment that produced the model and track how, when and by whom a model version was created.

    The Data Versioning Control (DVC) platform created by Iterative exposed a Git-like interface to enable organizations to track multiple versions of data sets, models and pipelines across a machine learning operations (MLOps) workflow. That approach enables those models to be stored in a Git repository alongside other software artifacts versus requiring organizations to deploy a separate platform just to store ML models.

    Providers of platforms used by data science teams have been making a case for separate repositories for tracking the artifacts used to construct an AI model. Iterative contends it is more efficient to employ Git repositories where other types of software artifacts are already being stored because, after all, an ML model is just another type of software artifact.

    That approach also makes it simpler for DevOps and data science teams to collaborate because the DevOps team will have more visibility into what AI models will eventually need to be incorporated into an application, noted Petrov.

    The challenge organizations face is the cultural divide between data science and application development teams. Data science teams today typically have defined their own workflow processes using a wide range of graphical tools. However, as it becomes obvious that almost every application is going to be infused with machine learning and deep learning algorithms to some degree, the need to bridge the current divide between DevOps and data science teams will become more acute.

    In fact, DevOps teams should assume that many more AI models are not only on the way but that those models will need to be continuously updated. Each AI model is constructed based on a set of assumptions; however, as more data becomes available, AI models are subject to drift that results in less accuracy over time. Organizations may even determine that an entire AI model needs to be replaced because the business conditions on which assumptions were made are no longer valid. One way or another, the updating and tuning of AI models are likely to soon become just another continuous process being managed via a DevOps workflow.

    No IT organization can, of course, manage what it can’t track. Registries have become an essential component of a DevOps workflow as the volume of types of artifacts that make up application environments has increased. It remains to be seen to what degree ML models become just another software artifact but one way or another someone in the IT organization needs to know what model is being employed in which application for what purpose.