Author: Don Macvittie

  • The Life and Times of Feature Flags

    The Life and Times of Feature Flags

    A while back, I had the opportunity to look closely at DevSecOps tools (as the market currently defines them). There was a lot to like, and they are moving forward to a “Find all of the vulnerabilities, all of the time” future … Except there will be new vulnerabilities that aren’t as easy to catch once we get there, and our journey will continue.

    More recently, I’ve had the pleasure of diving into application and API protection, which I can’t (actually, I’m not certain if I can or can’t, so won’t) say too much about at this time, but which are also moving forward in a similar direction, if not in a similar manner.

    And as a developer, feature flags have intrigued me since they first appeared.

    Sing the Sesame Street song with me: “One of these things is not like the others.” Feature flags are … a feature.

    When they first hit the scene, it was literally developers writing #if and #ifdef statements in their code to turn bits on and off at compile time. That reminds me of nothing so much as the Seinfeld episode where they’re explaining to network execs what the show is about. “A developer does his job … that’s a product!”

    The market has come a long way since then. But, honestly, I just don’t see these as stand-alone products. Take a look at the breadth of things most products are doing these days—CI/CD tools, either of the two markets I just mentioned or just about any other market in a similar space. Feature flags are still just about “turn this functionality off, turn it back on”. Newer iterations allow this without rebuilding the entire app. But it’s just not up there with the potpourri that current tools markets offer.

    My take is that these tools will end up as part of a larger toolset. Microsoft, Atlassian and Cloudbees (to name the ones I’ve seen without looking too hard) already implement feature flags, shrinking the available market. And they implement them because it’s a perfect fit with several markets. DevOps tools—which is where each of these vendors implements them—are one of the best market fits.

    Which market will end up with them? I have no idea, and that’s part of the fun as an analyst. The best on-the-surface fit would be DevOps toolchain systems like Atlassian offers, where no matter your toolchain, you can use them to speed acceptance testing or save a release without re-releasing. But I can make valid arguments for other locations too, so I guess you all will decide as options come available—decide with your dollars, that is.

    Watch for it. I’m not at all saying “Avoid feature flag companies because it’s not a real product!” I’m just saying that your feature flag vendor is likely to become part of a larger solution at some point, so make sure you have a plan to move off of it in case the larger solution is something your organization just doesn’t want to deal with.

    I am saying, “If you don’t have a feature flag solution—even a homegrown one—in place, it’s time to put one in place. The ability to say “Oh, yeah, that feature is mucking things up, let’s turn it off, quick!” is huge. For larger sub-projects that take multiple sprints, the ability to have the code right in the stream with regular check-ins, but feature-flagged out of the build, is also huge. No merging or other craziness, just “BuildNewFunction=FALSE” in the source or config file. The more advanced the feature flag system in place the better—the newest ones can turn things on and off with an environment variable from a dashboard. This makes feature flag code inclusion far easier and more intuitive than, “Did we account for that database update not happening?” of hand-rolled solutions. Still not perfect—because this is a journey—but store-bought is now better than anything you’re likely to hand-roll.

    And keep rocking it. Feature flags or not, you’re making systems that power the world—or at least your corner of it—and not getting the recognition you deserve. So once again, thank you. For all those people who don’t even know that they should thank you.

  • Best of 2021 – Hiring When You’re Not FAANG

    Best of 2021 – Hiring When You’re Not FAANG

    As we close out 2021, we at devopsy.kinsta.cloud wanted to highlight the most popular articles of the year. Following is the twentieth in our series of the Best of 2021.

    Most of us are not FAANG, and we shouldn’t act like we are. Instead of using that, I’m going to use the term we used to use to refer to them: “Web Monsters”, which isn’t 100% accurate, but includes more than just the five FAANG members (Facebook, Amazon, Apple, Netflix and Google) for this article. At some point, we are going to need a new term. Web Monsters doesn’t clearly include Apple or Citi, but FAANG clearly excludes Citi and eBay. But this blog is about something else, so please accept my apologies for that lack of clarity. Assume that ‘Web Monster’ means “Big, popular high-tech company that pays well and looks good on a résumé.”

    There are several angles to “Not Web Monsters” that we can address, but I’m mostly going to focus on DevOps hiring, with a nod to irrelevant sales/marketing techniques. Hiring is an easy target because Web Monsters offer resume-building, pay and benefits that are super attractive in the industry, so they can (right now, at least) reject 99% of applicants and still have a good selection of candidates to choose from. Most organizations cannot compete in even one of those areas, though a few can when it comes to salary and/or benefits.

    We in IT have long had a bad habit of asking our applicants to be more qualified than the average employee. It’s pretty ridiculous at times; things like asking for a candidate to have more years of experience with a technology than the technology itself has actually existed. What happens when you ask for the impossible? Honest, qualified applicants self-select out, and only those who don’t realize the technology hasn’t been around that long and liars end up applying. That’s just bad hiring policy, even if you are a Web Monster. But at smaller organizations where each hire has a larger impact on the organization, it can be devastating.

    It seems worse in DevOps. In fact, all of the hiring items listed here seem worse in DevOps because DevOps is actually a nightmare mish-mash of skill sets. No two people define the job the same because “the job” covers everything from cradle to grave for an application. There is no part of app dev that “DevOps” couldn’t touch. That’s problem number one. Define the responsibilities of the role clearly, don’t ask for everything that it could be. As a rule, an Ansible specialist is not going to be a DevSecOps expert, and you shouldn’t expect them to be. I think, at a minimum, we need to split hiring along my traditional emphasis lines… DevOps and DevOps. If you are writing code and using Checkmarx while GitLab is building the results and you configured it to roll out to test … you’re not a DevOps engineer, even though there’s a bit of ops in there. Your strengths need to be in development and app configuration. Your job description needs to focus on that.

    Could there be roles that need it all? Yes, particularly in the SRE or chaos engineering space; I could see that. But they are certainly not entry-level roles, or even close. Knowledge in the breadth of technologies required to touch the entire DevOps toolchain is developed over years and with a healthy curiosity. And, of course, the person you are hiring should have a similar skill set to those doing the job today. Which is a good sanity check against the “Throw in the kitchen sink” syndrome.

    Next up is take-home tests and shared coding during interviews. We know that you have a vested interest in landing the best people, but if you are doing coding exercises with people who are primarily DevOps, you are wasting everyone’s time. Most DevOps jobs are done with PowerScript and/or bash with YAML files. Other languages used occasionally have no more place in a core job interview than other occasional bits. “It’s about how you think” is a common refrain. I would argue that an assignment that takes an applicant hours to complete (or in several cases I know of, days) is not an efficient way to evaluate the way a prospective employee thinks. And, in at least one case, I’m pretty certain the interview solved an actual problem that employees didn’t—or couldn’t—solve. Ask the candidate questions about how they’d solve problem X. Ask them convoluted questions. They don’t need to get to code level to show you how they think.

    And finally, my nod to bad marketing: Unless you actually are doing the volume of one of the Web Monsters, the fact that Facebook is a customer of vendor X is totally irrelevant. In fact, like the government, most vendors can mark one or more of the Web Monsters as their customers, just because Web Monsters are so big they try a lot of different tools across many different teams. So having them as a customer should be irrelevant, but if it isn’t considered irrelevant, should be expected.

    The team you have today is rocking it. Hire more people like them. You know what works and what you need. Get back to customizing hiring processes to deliver more of what you need and stop over-asking. There are more great people out there looking for roles; don’t scare them off by asking for irrelevant experience. Stick to the core. What are they going to do daily? Require that, then probe for other useful items at interview time. And get more good peeps in the seats!

  • Best of 2021 – Programming Languages: Choose Wisely?

    Best of 2021 – Programming Languages: Choose Wisely?

    As we close out 2021, we at devopsy.kinsta.cloud wanted to highlight the most popular articles of the year. Following is the first in our series of the Best of 2021.

    We’ve got decades of experience in programming and language adoption under our belt at this point, and there are a few things we can say definitively that developers in general (and DevOps engineers specifically) should be aware of.

    First, it doesn’t matter as much as you think. It really doesn’t. Most developers don’t choose programming languages based on important things like optimization or general applicability. They choose a language based on ease of use, availability of third-party libraries and simplification of things like UI. Open source version availability helps, but only insofar as it spawns more third-party libraries. So, use the language that works best for the project, and don’t get too hung up on whether or not it’s the newest shiny one.

    Second, the changes in use and adoption that matter–the top five to 10 languages that make up the vast majority of all professional programming activity–don’t happen overnight. Both JavaScript and Python are considered “rapid ascent” in terms of uptake when they took off … but both were around for years before that spike in adoption occurred. So, learning any of the top few languages is a far better long-term investment than learning the hottest new language.

    Third, those top languages actually don’t change much. They were written to fulfill a need, and that doesn’t change much over time. Indeed, the only language I can think of that has fundamentally changed in its lifetime is C++, which seems to want to keep up with the times rather than keep serving its original niche. Python? Java? Still pretty much the same as when they became popular back in the day. And that’s a good thing. But that means if you want to try something new and engaging, you need to look to up-and-coming languages. At the time of this writing, specialist languages like R and Kafka are having their day, and that’s a good thing. After all, we know that different applications have different needs and different platforms have different needs–and have been trying to address that second one forever, currently with languages like Flutter. All of these will offer new ways of doing things, which is good exposure.

    Fourth, (though we briefly toyed with eliminating this one) organizations do determine the pool of available languages. Frankly, allowing each team to build a separate architecture was never a good idea from a long-term maintenance point of view … but a fairly large number of organizations played with the idea and learned the lessons about technical debt all over again. Now we’re back to “We use these languages, pick one,” which is better than “We’re an X shop,” and offers maintainability over time without burning a ton of man-hours.

    And finally, you can do anything with those languages your organization makes available. I’ve seen object-oriented assembler, I’ve seen entire websites served in C; the list goes on. The language you choose makes certain things easier or harder, but if you need to get it done, you’ll either get an exception to the language list, or you’ll figure out how to get it done with what’s available. But you can … But as my father used to love to say, “Just because you can, doesn’t mean you should.” He had nothing to do with programming and as little as possible to do with computers, but his logic still applies perfectly.

    So, grab an approved language, and crank out solutions. Just keep driving it home; you’re rocking it. Don’t stop, and don’t worry too much about which language you’re using, just focus on the language and do what needs doing–like you’ve done all along.  And spin us up even more cool apps.


  • Some Change is Bad

    Some Change is Bad

    Some time toward the end of the year, I start considering the volume of change we, as practitioners, have been under for … literally years, even decades. And I start to try and think of ways to keep you all from drowning in change. And then I write something that I hope helps you all focus on good change, and keeps moving your environment forward.

    This year I’m going to say “consider the reasons for the change.” I will attempt to find examples that do not require mentioning a specific product or vendor, so apologies if these read a bit convoluted as I attempt to illustrate this point without castigating.

    There are three basic reasons that a market or marketers want you to consider a change. There are, of course, variants and cases where it is a bit of this reason and a bit of that, but most demands that we change what/how we are doing things can be lumped into “mostly one of these”. They are:

    1. A great idea that is really a game-changer for some subset of the market.
    2. A shifting of who is in control.
    3. Locking customers in or expanding revenue.

    All of these happen at the vendor/project level, and all of them happen at the market level.

    Number one is best illustrated by any of the waves of server virtualization that have come through. From virtual machines to containers, each has solved problems and changed the way we do business. Notably, I’m only talking about server virtualization efforts here. Most of the other virtualization attempts have really not fit the “great idea that is a game-changer” category, though some have limited usefulness. Personally, I think the new version of storage virtualization will be in the game-changer category but am waiting to see it in use.

    Number two is one to watch out for and is most obvious when big-name OSS projects are forked. It is rarely about the technology being implemented (after all, a fork is a copy of the original; at first it is not at all about the technology), but rather about who is calling the shots. There is a bit of this in every public cloud vendor implementing their own version of container management (though this example is more about lock-in, in my opinion).

    Number three is multi-pronged. If your vendor went from selling you hardware or software to selling you a service, they want that recurring revenue and they want you to be linked into that service so deep that you can’t walk away. The much-reviled 1990s mantra of “embrace and extend” is the poster child for this kind of change. There might be a value-add in there somewhere and sometimes the added functionality makes the move a no-brainer. Often, though, the change is simply to the vendor’s advantage, not their customers. As most major Linux distros have shown, open source is not immune to this one, as most of them are making OSS users the de facto beta testers for their paid offerings.

    None of this is to say that the change in front of you is bad—even if the reason it was originally spawned is bad. It is reminding you that, after a constant stream of change, we’re more open to it than maybe we should be and you should remember the only important thing about new changes—do they make our environment more secure, faster, more agile? Everything else is just noise. Yes, all the cool kids are switching to coding in [insert flavor du jour], but does it offer your organization anything new? Yes, it seems everyone is using [insert current CI/CD flavor], but does it address the weaknesses of your current toolchain?

    You all are nailing it. Keep doing it. And don’t be afraid of change, but make sure you know if that new OSS database system is really new, or just a lot of installing the same code under a slightly different name. Because someone didn’t like the new owners.

  • Are You Feeling the Hiring Crunch?

    Are You Feeling the Hiring Crunch?

    After years of experience, we can now definitively say one thing about information technology: There is always a hiring crunch, and it will always be better soon.

    I first noticed this trend in InfoSec years ago. Everyone was short-staffed and looking for available candidates. Everyone wrote their recruitment text like there was no shortage and they could ask for the moon and everyone was certain that this temporary staffing shortage would end soon.

    It didn’t. It still hasn’t. And it has spread. DevOps in general, development in particular are acting exactly the same these days. And it’s not going to get better.

    So, my advice? If you absolutely must have a person, write your recruitment copy to reflect the actual skills you must have. No bells and whistles, no “We always include…” no “But what if we…” Hire for what you need. Or hire with an eye to training what you need. And offer competitive pay. No one here will argue that IT is underpaid, but when there is a shortage of people, or more are leaving than coming in, then the cost of employees goes up. That’s just the way it is. If you are only hiring the ones you must have, then you can afford to pay them a bit more.

    Meanwhile, invest in even more automation. Let’s face it; again, we can learn from InfoSec. They are doing more with less staff—even if “more” is not “everything that everyone wishes they could”.  They have at least partially conquered their staffing woes by increasing the use of automation. DevSecOps is automating even more of the space, so we really will eventually get over the InfoSec staffing shortage.

    We can do this for all of IT, too—just follow their lead. Invest in automation, take the risk and turn on automated actions. Start small, but get started. Relatively high turnover and lower qualified applicant counts are likely to be the status quo for the foreseeable future, so automating processes as much as possible is not taking away jobs at this point, it is improving response in light of a lack of people for the available jobs.

    So, to sum up:

    • Hire when you can, but be focused. Don’t ask for experience in all three big cloud providers if you’re looking for an Azure person. Don’t ask for fifteen years of experience in Go for that entry-level position. Be realistic, be laser-focused and get the person you need in.
    • Train when you can’t hire. Let’s face it, there are going to be people who are massively familiar with application security but who have never done DevSecOps specifically or never used your DevSecOps solution. Train them—whether they are internal or hired with an eye toward training.
    • For non-critical, long-term needs, explore automation options. That includes both things that are being done manually today and things that are not being done at all. Find a way to get it done in the absence of hiring someone.

    And keep rocking it. You are already getting the job done—I’m just recommending ways to stay on top of it and deliver more while you try to find the additional people you need. A balance of automation and hiring will help you sleep at night and make the rest of the org certain that IT is on the ball.

  • How Dispersed Can We Be?

    How Dispersed Can We Be?

    It is interesting to consider DevOps from the storage perspective. DevOps in general—and specifically newer development and deployment models—tried to pretend that long-term storage was not a necessary component of software delivery. In short, it appears that because there wasn’t a good answer to long-term state in stateless development models, the storage and databases that used state were hand-waved away. Which, of course, failed. Container deployment models did the same thing and failed just as miserably. Oh, containers didn’t fail, but the attempt to ignore persistent storage did; from the very beginning, it was clear that was going to happen. We were doing early container implementations and working through how to ensure that containers ABC had access to the same shared storage. That need never went away and was never going to. Apps can run without persistence, but business doesn’t run without persistent data.

    Checking out the wave of cool new products like, for example, Ionir (disclosure—I know more about them simply because I’m friends with their CMO. Other vendors likely have good solutions, too) makes me realize the answers that we needed were right in front of us. And not just the answer to persistent storage, but to storage portability, which has been a problem from the beginning of the cloud. Data gravity is the idea that data holds apps in place. Tools like Ionir reduce the gravity of data. A lot. They can’t get rid of data gravity, because some platforms charge for data storage, data ingress and egress, etc. but that becomes a TCO operations problem rather than a near-insurmountable tech problem.

    But just as interesting is this: What if the slow but steady increase in core Internet speeds will allow us to access data from anywhere? We could do that now, but performant applications struggle if you force them to leave cloud A and go to your data center or to cloud B to get a dataset. Yet we use APIs that do just that on a regular basis. What are Google Maps and Google Places if not simply big old honking databases? And yet we call out to them from just about every platform.

    So, it’s worth trying out and seeing if the idea of data gravity is maybe an obsolete idea for you. For some applications that really do need super-fast response times, the concept is still relevant. But for many applications? Where your app sits in relation to data may not be as important as you think. Write or grab an API wrapper for a critical dataset and throw a simple test app up on a different platform. See what you get. If it performs well, consider putting apps where it makes sense and using a wrapper API with secrets to grant access to data from any validated app.

    Some of you are doing this already. Not many, but it’s out there. Excellent job; keep rolling!

    Everyone else is kicking rear and taking names, with the world still online every day because of your collective work. So keep rocking it, but consider if you really need the application close to the data these days and, if you do, how data mobility tools might facilitate moving data to the app—something most of us would not have considered for large datasets before the last year or so.

  • Organized Architecture

    Organized Architecture

    I’ve mentioned IT pendulums plenty of times before, but today I’m going to use them to explore a different angle on IT: The age of containers and microservices. It’s time to ask yourself if the current architectural design of the overall product offering of IT is the best one you can afford to offer.

    Agile and the whole “developer is king” movement brought us a whole lot of independent app teams running off and doing their own thing. While the core of that movement was short-lived, we got a lot of good and bad out of it. The good included breaking the traditional “We change at glacial rates” process that some IT shops had—because a team absolutely wants the tools that will make their job easier, not the ones pre-approved by committee or whatever process a given org used. And the bad included the very things those of us who’ve seen this type of thing play out before warned about. Suddenly, we had critical apps and infrastructure relying on tools that one dev used in his hobby development. Sometimes that was good, and for sure it happened before Agile came along, but now we had an avalanche of it. Stuff that hadn’t been through security; often code/libraries/apps that no one outside the team (or the individual) knew was running in the organization. Some of that stuff is still happening.

    And then we hit true uptake of microservices. That drove us to break things up in non-traditional ways. A lot of good came of that process, but a lot of complexity did, too. Complexity shared across applications with a huge spike in API calls and operations with a spike in deployed processes and routing. Perhaps the worst thing to come out of the combination of the two is “Who cares why it failed? Just spin up another!” That movement is mostly dead (thank goodness), but it only died because of the number of high-profile “Oops” issues that it caused. It allowed attackers to go unnoticed; it caused paying customers to spread security details across the web; it caused users to suffer crashes that would have been fixed in any sane development environment … and some of those are still out there. Cases where there’s a script to restart an app or service every X hours because it crashes randomly. Not acceptable. Make all the excuses you like, but if you don’t know what’s causing the crash, you’re wrong to leave the app or service running.

    And we introduced a huge amount of complexity. Now we have double the infrastructure—one physical, one virtual (container or cloud). We have applications spread across a lot more systems (be they instances or physical systems) and often across platforms; even across data centers. We live in a very cool time, with some sweet stuff going on. But complexity is a very real problem we need to solve. One app/app portfolio may have limited complexity, but we still allow teams too much leeway in defining the environment the application lives in. We need to offer a happy medium—a world where there are options, but those options are defined, manageable, and secure.

    So we’re likely to see a resurgence in the importance of enterprise architecture teams again, with their focus being on organizing the mess we’ve made. Indeed, I know this is underway in a couple of Fortune 500 companies I stay in touch with. And I know of one organization that isn’t doing this and has all their UI functionality running through a single container … for multiple applications. That is no better architecture than each using a completely different UI toolset. So, I expect they’ll want coordinated solutions also. Just so something like that can’t happen again.

    You all are doing it, day in and day out. As I often say, just don’t let this bit drag you down. Confront it head-on, approach standardization with “Yes, where it is good; no, where it is not” as your credo. Security is the big one, but maintainability is another. Even with tools like Ansible at their disposal, managing 50 different environments is a bit much for ops if it could be done with five. And keep rocking it. Through a pandemic, meeting increased demand, giving users more and more. Thanks once again, from all of those users who don’t know to thank you.


  • Learn a Bit About AI

    Learn a Bit About AI

    Every once in a while, a trend becomes broad enough that I feel the need to offer career advice. This year it will be simple: Know enough about AI/ML to be dangerous. We are past the point where not having at least a basic understanding is a good idea. Looking around the data center, AI is in use from the earliest stages of development through production network performance evaluation. Somewhere in your environment, you are using AI and ML. More to the point, somewhere in the places you may interview going forward, they are using AI and ML.

    I’m not suggesting you become an AI/ML expert—though you certainly could; I have a relative that is a data scientist and that’s all he does—design and tweak algorithms. He’s learning new things pretty much daily, so if you like that (as I do), it’s an option. But for those of us doing DevOps or SRE or even regular old operations, we’re only going to have to understand a bit.

    Understand what tools like Jupyter are, and what the most commonly used ML algorithms in your space are. Then, learn about how AI and ML help with what you are doing. Just as knowing more about the compiler/interpreter of your chosen language helps you solve more odd problems, AI is going to have that same issue. Think about how those folks who understand the guts of routing are the ones we want solving our routing problems. Again, same scenario.

    Moving forward, AIOps, NetOps, DevSecOps … All intend to increase the amount of work offloaded onto the AI in question. In a lot of cases that is great. We have enough to do; if you can paw through those logs and give me relevant summary info, go for it. But it doesn’t end there—some AI engines are making the calls and implementing changes. In both network and application security, a fair number of vendors will tell you there is no time to wait for humans to stop an attack, and they encourage their customers to turn on automated responses. That’s the first of many applications for AI/ML. We will see an increasing number of AI/MLOps tools being used for full-on automation. We all do difficult jobs with a complex—sometimes bewildering—number of inputs. But we use pattern recognition and experience to make determinations and do what’s best for our organization. Our software has reached the point where sometimes, it can do that for us on the easier tasks so we can focus on the more complex ones. When the AI/ML fails—and it will, because pattern recognition and historical trends are not always indicative of normal usage—knowing what is going on under the covers can help you determine if it did the right thing in the wrong way, or simply did the wrong thing. And it can help you to quickly recover. I can’t speak for every organization, but I’ve never seen one that lamented, “Sure wish that outage had lasted another couple of hours!”

    And keep rocking it. Somewhere in the distant future, an  AI may be able to do your job as well as you. But that isn’t today. Even if it can handle one bit, it certainly isn’t rocking the entire breadth of your responsibilities like you are. Thank you, from all the users that don’t realize you’re keeping them live.

  • Security is About People, not Technology

    Security is About People, not Technology

    Just a random thought of the day: We have the world’s best example of how many of our security woes are actually people problems, not technology problems.

    We all know that. We’ve all discussed it—but let’s consider this example and have a quick discussion about 2FA.

    Epic Games had a problem not unlike the rest of us. But it was costing them money every day, in part because of the nature of their user base. The problem? Attackers taking over the accounts of legitimate Fortnite users. In the world of gaming, scammers are rife because the player base is younger. At least since Ultima Online (1997), online games have been growing and Fortnite is at the forefront of that movement, with user counts unheard of before it became popular. That many users combined with hackers and scammers taking advantage of the younger demographic attracted to games—over 60% of Fortnite’s massive user base is under 24 years old—they do not provide a further breakdown, but there are certainly kids as young as six playing; and possibly even younger players).

    That made for a problem. Investment of time and money and energy for supporting customers having account issues was no doubt huge. I do not have an insider feeding me information, but simple math—and the evidence of steps they’ve taken—suggest that this is the case.

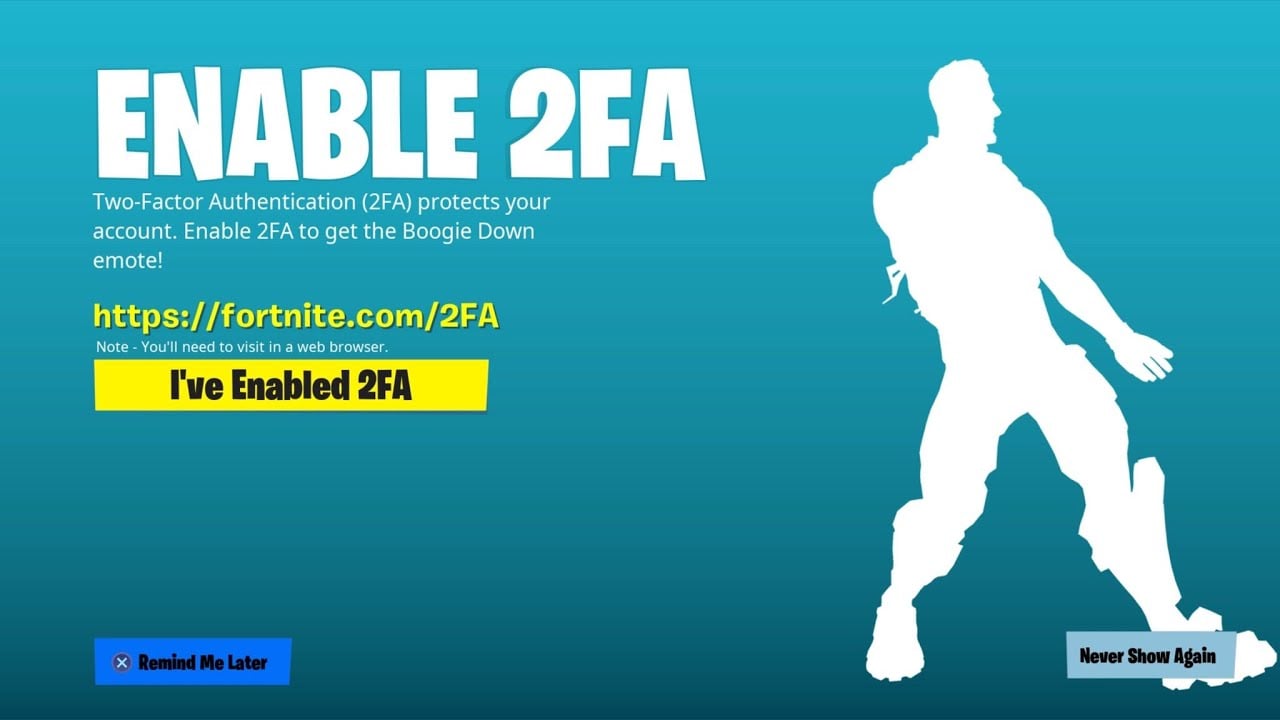
    So they did with kids what far too many of us don’t have the guts to do with our adult workforce. They implemented 2FA. While they did not require it—and, like most game companies, are tight-lipped about any kind of player statistics—they implemented it with a carrot-or-stick approach that, no doubt, has been successful. My gaming group of half a dozen all use it—because we either wanted the carrot or were avoiding the stick. It’s not really a stick. Call it carrot and wall. The carrot comes in two forms for the two most popular versions of the game: A free dance for your character (toon, if you prefer) to perform in Fortnite: Battle Royale.

    Fortnite Dance

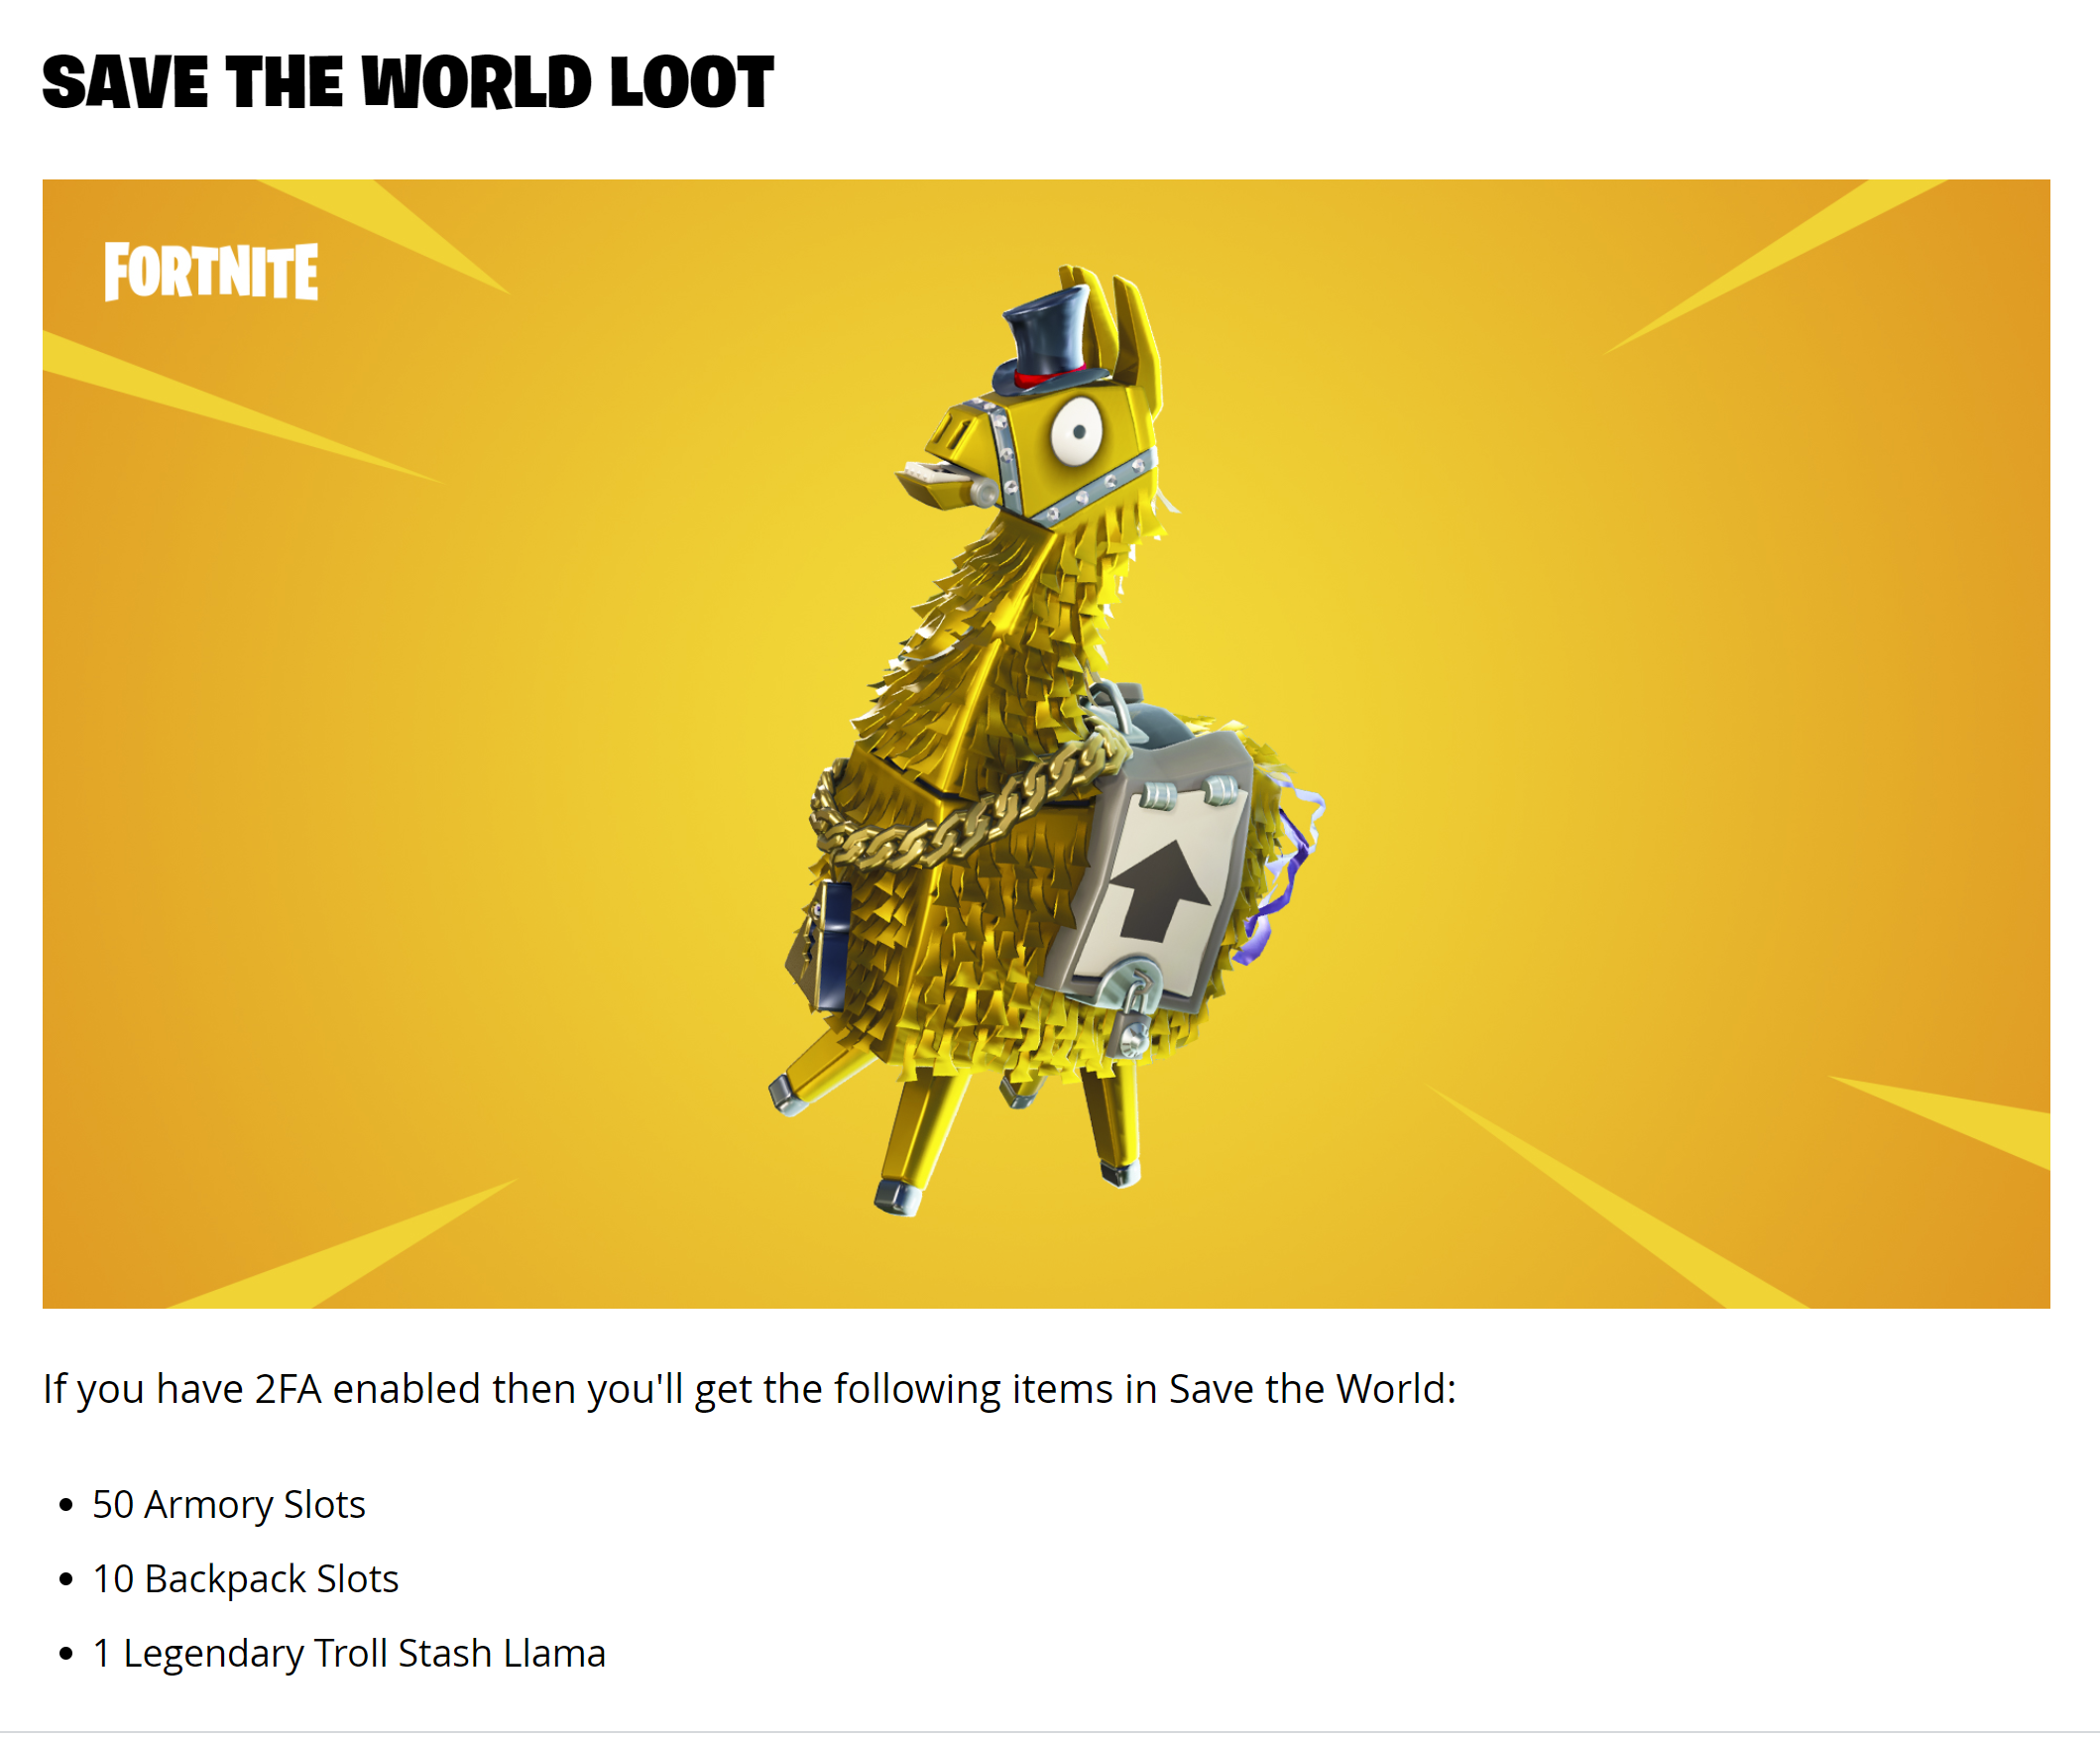
    And free gear in the paid version –  Fortnite: Save the World.

    Free gear

    For those of you who are not familiar, both of these are decent rewards; calculated by the Fortnite team to be compelling enough to warrant the steps, but not insane. The Save the World rewards are actually better in terms of usefulness, but the dance for Battle Royale is likely more popular.

    Then, they put up a wall. If you want to play competitive Fortnite, you must have 2FA turned on. It is possible that this was done to protect the sanctity of their tournaments, but it has the effect of providing the other half of the “reward and punish” equation. According to Compare Camp, 40 million players attempted to qualify for the game’s World Cup alone. So that is the minimum number of 2FA activated accounts—you cannot participate in competitive Fortnite without 2FA turned on.

    They then made turning 2FA on as easy as possible. You need to learn from this. It was harder for me to turn on 2FA and get it working for Discord than it was to turn it on and get it working for Fortnite. Strive to be as easy as Fortnite.

    At this point, we should all recognize that some form of 2FA, even the much-maligned ones like email (maligned because someone who compromises your email then has easier access to everything because 2FA is compromised), is almost essential. The cost of someone hijacking a valid user account—like the lead systems engineer or the CEO—is just too high to ignore. But some 2FA solutions are harder than others. So, we need to follow Epic Games’ lead, and make it as simple as possible, provide incentives to employees to turn it on and, if suitable, wield a stick. A minor ding on reviews until implementation is complete should be enough, if the incentives are nice. A free day off? A small bonus? You know your organization, both what management will agree to pay for and what users will find compelling.

    Get it done. The last thing you want is for your CEO to suddenly start saying/doing erratic things on corporate accounts. Unless they already do—then I suggest you consider looking for a new job. I know; there are 5,000 things to do and only a few of you. But this one is big. Don’t wait until you’ve lost accounts to turn on a pretty effective prevention mechanism.

  • But What About When You Fail?

    But What About When You Fail?

    One thing Agile and DevOps definitely brought IT was a more accepting view of the whole “mistakes happen” mantra. Crashing systems is no longer a guarantee of a free ticket out the door. Indeed, off the top of my head, I can think of at least two cases where a CIO themselves checked in sloppy code and it trashed the system—CIOs at orgs big enough that they probably should not have been coding in the first place.

    And that brings us to today’s blog. The standard response to “But what if there is a bad update?” is “We’ll just roll out a new version!” That works in some instances. In a lot of instances—most that involve GitOps as part of DevOps—it doesn’t. Implosions can be huge and take out chunks of infrastructure. So you need a better plan than just assuming you can fix it with a forward update. Do you have rollback capability? Are you making use of it, assuring all is set to roll back if needed? Testing to make sure rollback works with the other changes made across the system in this update?

    That is part of the problem. Fixing with a new update is the best option, simply because in the age of massively distributed, microservices-based solutions, rolling back comes with a ton of baggage—enough that it may not be viable for you. Okay. So you can’t quickly roll forward. You can’t quickly roll back. Quick! What do you do?!

    And I don’t have the answer to that question, because I’m not in your organization working on your systems. At some point, all IT is personal. And this is one of those points. You need to know what your best options are if an update spirals everything, and you need to have a plan to implement it. But what your best options are is not going to be the same as the next org. This is that point.

    One option is to keep the ability to build the entire system. That’s a large setup, but every minute systems are down is hurting the company. And that’s what you need to plan for. Think of it as disaster planning for DevOps. A man-made disaster that destroys systems and infrastructure.

    So, like any other disaster planning scenario, walk through the chain that makes the system work, identify weaknesses and list ways to address them. Then test those to make certain they do what you hope they will. Then, set up an automated system to keep this whole plan up-to-date.

    In short, we’re in a new automated landscape, and we need a new automated tool to pull our rears out of the fire when the inevitable happens. Be it from dev error or malicious attacker, it is a safe bet that, sooner or later, you will have a massive systems outage that your DevOps toolchain can’t adequately address. Know what you are going to do. Or at least have thought about it, so you’re not just starting to think it through while coworkers and customers can’t access systems.

    And keep rocking it. This is just another layer of protection for all the hard work you’re doing. Take the extra step. Like insurance, if you ever need it, you will absolutely be glad you did.