Author: Cory von Wallenstein

  • Dev + Ops + ???

    Dev + Ops + ???

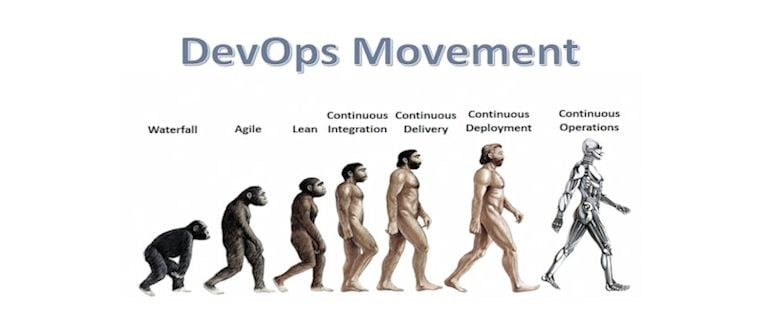
    If there’s one thing the DevOps cultural and professional movement taught us, it’s to question the status quo for the betterment of our customers, businesses, and ultimately, our teams. The combination of improved tooling, questioning structural barriers between teams, and a “shared outcome” culture have been powerful forces to date.

    Granted, we’ve seen the most demonstrated benefit in smaller organizations, but let’s face it… a big part of the movement is culture, and a set culture in a large organization is not easy to evolve. As we’ve mentioned before, you can’t sell DevOps. It will take time for large organizations to benefit from the movement.

    While we wait for the cultural evolution of large organizations to DevOps, it’s worthwhile to watch the continued professional and cultural evolutions of smaller organizations. The ones that first embraced DevOps from their start, what’s next for them?

    There are three ways I am currently exploring this question:

    • Dev + Ops + ???: Addition of a third functional pillar
    • DevOps evolution in parallel to Sales & Marketing evolution: Some interesting parallels
    • Org-wide evolution: DevOps cultural tenets deployed throughout the organization

    I would love to hear your observations as well.

    Dev + Ops + ???: As the title suggests, the most common finding thus far is another legacy functional silo having the structural, cultural and tooling barriers to collaboration torn down. These organizations have a solidly executing group of engineering and operator mindsets working closely together, and have actively embraced a third pillar of the organization. The most common I’ve found is the security team and the embrace of the term SecOps, though I’d love to find others. Do you fit this profile? Leave a comment below on your observations.

    DevOps evolution in parallel to Sales & Marketing evolution: In a small handful of organizations I’ve talked to, I’ve seen an interesting parallel evolution in the go-to-market teams to what was evolved in the technical teams.

    If DevOps tore down the fence where code was tossed over, and eliminated the “blame game” when things went wrong of “It’s not my servers, it’s your code” and “It’s not my code, it’s your servers”, there’s a remarkably similar parallel evolution happening in go-to-market teams… of course not about code, but instead about leads. To put it the most bluntly ableit controversially, there has been a long-standing tension between marketing, historically charged with generating leads for new customers, and sales, historically charged with engaging the leads and nurturing them into prospects and ultimately happy customers.

    Cue the blame game: “It’s not my leads, it’s your close” and “It’s not my close, it’s your leads”. Enabled by better tooling and visibility (e.g., customer relationship management software, marketing automation, etc.), progressive organizations are spending less time blaming each other, and more time collaborating on a shared outcome. Personally, I find the parallels between the evolution of technical teams and the evolution of go-to-market teams fascinating, and if you fit this profile, I’d love to hear your observations.

    Org-wide evolution: Our preceding two profiles are fundamentally about change from within; specific cultural, structural and tooling barriers being torn down between functions of an organization. We see examples of technology teams tearing down walls, and examples of go-to-market teams tearing down walls, but what about the many other key functions of an organization?

    Where’s finance? How about talent and human resources? Customer services and support? Product management? I would love to learn of more examples where cultural evolution is occuring not just in functional pockets of a comany, but across the entire organization at scale. If you fit this profile, I’d love to hear your observations.

  • DevOps resilience: going active-active with an existing application

    DevOps resilience: going active-active with an existing application

    What does it take to run an active-active architecture? It boils down to data, and how you interact with it. The most common disaster recovery strategies I encounter with folks are either “hope and pray” on a single location for running an application, or “we have a backup facility we can switch to in a disaster” with an active-passive configuration. This is a shame, as running an active-active architecture is not science fiction, and while it takes some work, for many business use cases the pros greatly outweigh the cons.

    The Devil’s in the Data

    If you work your architecture from the outside in, an active-active architecture is relatively easy to understand: you have more than physical datacenter or cloud region where you run your application, you have your application running in each, and you have traffic management to load balance users to the closest, fastest and most available location for them. Where folks get stuck is in the database. How do you make sure a change made in one location gets propagated to the others? What happens if a user “bounces” from one facility to the next and attempts to read back data they just wrote? How do you avoid race conditions where user A at location 1 and user B at location 2 make a conflicting change to the state of the application?

    The key to handling the scenarios above is understanding the business requirements of your data, and treating each type of data appropriately for an active-active architecture. If you try to “make all data available everywhere”, you’ll quickly run into either CAP theorem constraints or financial constraints on the high costs of this approach. Instead, let’s break the bigger problem down into smaller, more tractable problems.

    Three Classes of Data

    For each type of data your application accesses or produces, let’s classify it according to one of three types, using a banking metaphor for simplicity (and for easier explanation to your business peers):

    1) Is this data like a bank account balance? It changes frequently, and it’s incredibly important to make sure two conflicting changes don’t “break” the balance. We don’t want users A and users B making a withdrawal from two locations at the same time, thereby potentially overdrawing the account.

    2) Is this data like your address and mailing information your bank keeps for your account? It changes, but not frequently, and during a change, it’s OK if there’s some short period of time where the multiple locations that host your application are out of sync for this data. They’ll eventually gain consistency.

    3) Is this data like your banking statements? Once produced, they don’t change. They can be archived.

    Account balance. Mailing address. Historic statement. Three categories, and for each, we have a data replication strategy that can support active-active. By categorizing the data and treating each with a different replication strategy, we’re accomplishing two very important things:

    1) We’re being thoughtful about what data REALLY needs near realtime replication and race condition protection. By doing so, we’re reducing the amount of overall data that needs high priority replication. The less data to replicate, the better and more efficiently replication works.

    2) Rather than try to replicate all data with the same strategy, we’re willing to use the right tool in the toolbox for each type of data, which means we’ll save costs by using archival and eventually consistent strategies where they make sense.

    For each class, we’ll use an appropriate replication strategy:

    1) For “account balance” information, we’ll replicate changes as quickly as possible, and make sure our application is aware and capable of resolving change conflicts. This is certainly one of the hardest pieces to get right, but by reducing the scope of how much data we need to address with this strategy, the problem is much easier to solve than by trying to apply this strategy to all three categories of data.

    2) For “mailing address” information, we’ll use an eventually consistent replication strategy.

    3) For “historic statements” information, we may choose NOT to replicate this to all of our facilities. We may revisit some old assumptions on what’s important to save and what’s not, and decide to discard some of this information. We may choose to simply regenerate the statements should they be lost. We may choose to bulk replicate this data at certain times of the day.

    The Top Three Benefits

    After we migrate an application to active-active, we can expect three key benefits:

    1) Faster and more reliable failover in the event of a disaster. As opposed to an active-passive disaster recovery strategy, which depends on idle infrastructure coming up to full production speed in the event of a disaster, we avoid the risk of “we thought it was ready to handle production but something broke in between disaster recovery drills”. In an active-active scenario, we’re sending production traffic to each location all of the time, so we don’t have an “idle to full capacity” ramp-up problem; instead, we’ll have a “50% to 100%” (for two locations going to one) or “33% to 50%” (for three locations going to two” capacity challenge. We’ll need to make sure we always have spare capacity in an active-active configuration to handle the additional load during a failure.

    2) More flexibility for making changes to applications and infrastructure. During a site maintenance event, we can shift all traffic away from our facility, perform our maintenance, and then pull the traffic back, without downtime.

    3) Improved user experience. By connecting users with an application instance that is near where they are in the world, they’ll receive a better and faster user experience than if they were to be all sent to a single location.

    There are others, but those are the biggest three.

    The Top Three Drawbacks

    Of course, it’s not all sunshine and kittens, and it’s not without work and investment:

    1) You’re going to need spare capacity available, and be diligent and have conviction about maintaining a safe buffer for spare capacity. If you run two facilities each at 75% load, you’re going to have a big problem when one fails. Know your limits, and stick to them. Don’t fall behind in investing in this capacity.

    2) You’re going to need to change your application. If you were looking for a “drop in solution” to active-active, this is not it. You’re going to need to change your application. The most common scenario is you’re going from a single database instance on a single database technology to three separate data services that treat each type of data with the appropriate data management strategy. The most common problem is “I used to be able to JOIN these two tables to get a result, but one was an ‘account balance’ type, and the other was a “mailing address” type, and now they’re stored separately”. In this case, your application will need awareness to retrieve the data from each appropriate location, and “JOIN” in software.

    This sounds hard and time consuming, but there’s a great strategy for how to implement these changes. Presumably, your application accesses data using a core set of libraries (often an object relational mapping or ORM approach). In these libraries, you’ll want to make the changes for “what type of data is retrieved from where”. This will help minimize the impact to the rest of the application in terms of the interfaces to retrieve data, and keep the “data load balancing” functionality in one location in your codebase. Add in helper functions as appropriate to implement the JOIN functionality you need that previously was done in the database. Keep in mind, if you have a LOT of JOINs across categories of data, this strategy as a whole may not be viable for you.

    It’s highly recommended you take a dark architecture approach to these modifications. For some period of time after migrating data to a new strategy, have your application perform reads and writes to BOTH the legacy and new implementations for a single data interaction use case. Compare the values and results, and log/alert when different, while returning the legacy result. This gives you operational experience with the new data strategy while minimizing risk, since the application is still using the legacy implementation for all functionality. After you have confidence that the two approaches are functionally equivalent, you can start using the values from the new implementation, and turn down the legacy implementation. For more details on dark architecture, see here: http://gigaom.com/2013/06/20/making-it-change-less-scary-using-dark-architecture/

    3) You’re going to be running multiple database and data storage implementations. There’s a definite cost here in training your team, licensing, infrastructure, and having the monitoring and associated operational infrastructure required to run a dedicated strategy for each type of data. You’ll have to understand for your business whether the benefits outweigh the costs.

    There are others, but those are the biggest three.

    Your Next Step

    How important is uptime, infrastructure agility and user experience to your business? Are these investments worthwhile? Only you will be able to tell for your business. Once you quantify the value of uptime (e.g., how much money do you lose and damage to your brand is there during an outage?), the value of agility (e.g., how much faster could your team evolve your application if they had more flexibility to make changes anytime to production without affecting customers?), and the value of user experience (e.g., how much faster could your user experience be by splitting your infrastructure into multiple active-active locations, and how much would your users appreciate that improved experience?). Come up with those figures, and compare them to the technical investments required above, and you’ll have a pretty clear GO/NO-GO for evolving your application to active-active.
  • How to Evolve to DevOps

    How to Evolve to DevOps

    What is DevOps, and how do we do it?

    It’s a question I’m often asked, with confusion around job titles, team structures, tooling, personnel responsibilities, office layout and more as potential ingredients for a successful devops recipe. The first step in evolving an existing organization to a devops mentality is to take a step back, and level up your thinking, far from the tactics mentioned above.

    The first thing to recognize is that this is a cultural and professional movement of technology workers wanting to be more impactful for their businesses and be personally happier themselves, and this movement has three key strategic pillars of success: cultural, structural, and tooling. When we get all three right, we enable a devops mentality, the benefit of which is a business that can respond quickly to customer or market feedback (i.e., agility).

    devops-pillars

    The three pillars are foundational to the collaboration among technologists to enable this business agility.

    Evolving to DevOps

    You have a status quo of culture, structure and tools. Regardless of whether you explicitly defined each, or allowed some to more implicitly evolve than others, the fact remains that you have a status quo. How do you evolve? You need to tackle each pillar in turn, understanding your status quo, and what helps or hinders a devops mentality for your organization. The first pillar is the most critical: culture. Let’s speak to that first.

    A Culture to Enable DevOps

    What happens at your company when things go wrong? Be really honest. Do folks become defensive about their role in contributing to a problem? Do they blame others for problems? Do fingers point outward before they point inward? Do you ever hear, “It’s not my servers, it’s the change you made to the code!”, or the converse, “It’s not the code, something’s wrong with the servers!”.

    If any of the above holds true, stop everything right now, get everyone together, and talk about what you see in how you interact with each other. Your goal is to enable a shared outcome mentality across functions and jobs and roles (i.e., we all succeed or fail together), and a culture of self-improvement and introspection where the first thought when things go wrong is “what could I have done to prevent this from happening, and how do I want to change what I do in the future to make it better?”. When you get it right, people will gravitate TO problems and collaborate on solutions, not distance themselves AWAY from them to avoid blame.

    So what do you say? How do you say it? What’s necessary to evolve the culture? Every situation is unique, and you’re going to need to chart your own personal and organizational evolution to foster a culture that can enable devops. If you’re the leader of the team or business, start surrounding yourself with mentors and peers in other companies that have achieved this, and ask to learn from them.

    If you’re not the leader, again, surround yourself with mentors and peers that have built this culture, and ask to learn from them. Then be the change you seek in your organization, and lead a cultural shift from within. Either way, you’ll begin to discover your own unique path of learning, supported by many readings and mentoring conversations, that will empower you with the skills and conviction to bring about cultural change.

    If you’re the current leader of the team or business, and you’re not willing to undergo this difficult process of personal and organizational evolution of your culture, I have a rude awakening for you: you won’t be the leader for the long term. Over a period of years, either your business will succumb to competitors who are able to get this right, or a member of your team will take over for you as the rightful cultural steward. Choose wisely.

    A Structure to Enable DevOps

    Within your company, look at your organization chart, and look at the people that you are physically near or collaborate with the most, and answer the question: what are we responsible for? Now look at other parts of the organizational chart or office layout for departments or functions of the organization that you are dependent on for collective success. What you’re looking for is a physical or proverbial wall in the organization that draws boundaries on what one group of people are responsible for, and what the next group of people are responsible for; these walls create a “that’s someone else’s problem” mentality. In the most classic devops sense, we’re talking organizational (i.e., you report in to different parts of the organization from a managerial perspective, or you are accountable to metrics that put you at odds with another part of the company) and physical (i.e., you sit in different areas of the office) silos separating developers from operators. If you’ve ever heard the phrase “developers toss the code over the wall for operators to run,” you know what I’m talking about.

    Some of these physical and proverbial walls will make sense in the organization, while others you’re going to need to question why they are there. You may even find some walls that don’t make sense with other parts of your organization (say product management, or security, but we’re going to stick to the classic developers and operators example for brevity). Physical and proverbial walls that hinder collaboration toward shared outcomes must be evaluated for removal.

    The classic example from a proverbial perspective is a development function of an organization being held accountable for performance metrics such as number of features released, while an operational function of an organization being held accountable for reliability metrics. Clearly, there will be tension and angst as these metrics can easily pit two groups of people against one another. In this example, a common solution is to focus on shared outcomes, and hold everyone accountable for both feature velocity and reliability. Another common solution is to have both developers and operators report in to the same person. Another common solution is to put developers “on call”. The tactics will vary on the situation, the strategy remains the same: break down the physical and proverbial barriers to collaboration and embracing shared outcomes. If there is a wall that prevents people from working together to improve the business, tear it down.

    Tooling to Enable DevOps

    How effective are you on 3 hours sleep after being paged all night? How strategic is your thinking while typing in a command for the Nth repetitive time? How demotivating is it to put all of your energy into treading water without signs of visible forward progress? Even the greatest collaborative culture with a structure reinforcing shared outcomes will fail if everyone is burning out debugging problems and performing the same mundane tasks over and over. This is where you need to evaluate your tooling.

    Start with the repetition. Every time some task comes up a second time, make a commitment organization wide to automate it and track changes in revision control. Use this as a foundation to eventually drive to fully automated configuration management from revision control, but you have to start somewhere, and you will free up significant time and frustration over the long haul with this simple mentality shift. We’re going to invest this newly found time into the followup tooling activities.

    With that executing over time, turn your attention to telemetry. Are you collecting the right data from the right places to let you understand where problems are? Data debunks all blame, and properly aligns people toward investigating problems in a collaborative manner. Consider “monitoring” as the definition of thresholds on the right telemetry data, and “notifications” as the definition of who needs to know and when. Be diligent on getting the right threshold and right notifications; set thresholds too aggressive or notifications too broad, and folks will become numb to the system and lose trust, while setting thresholds too passive or notifications too narrow, and important issues affecting customers could get missed. Over time, improved telemetry will enable you to predict problems before they happen, and the right thresholds and notifications will ensure the right people know what to do to fix what problems right away, freeing up more time to go into the final phase of tooling.

    With common tasks automated, and a good, clear understanding of how well your systems are performing and where problems lie, you can focus your energy on improvements that will enable resilience for the future, both in your technical systems and in your teams. On technical systems, you’ll investigate refactored architectures that are more scalable and fault tolerant (e.g., horizontal scale, multi-datacenter load balancing). For your teams, you’ll invest in better collaboration systems (e.g., wiki, chat, ticketing, etc.).

    You’re Never Done

    While I’ve provided a framework to systematically tackle common barriers to enabling the business agility that comes from a devops mentality, truth be told, there will always be more to do, and there will always be more personal, organizational and technical improvement to be had. Embrace this journey, be proud for each new milestone along the evolution, celebrate every victory, and deliver wonderful things for your customers.

  • Zen and The Art Of Infrastructure Maintenance

    Zen and The Art Of Infrastructure Maintenance

    There’s a famous passage I’ve quoted from time to time when I see someone “stuck” with a problem, flailing potential fixes and solutions wildly in hope that one of them does the trick.

    “Assembly of Japanese bicycle require great peace of mind.”

    Just like that. Improper grammar and all, quoted verbatim from Robert Pirsig’s philosophical classic Zen and the Art of Motorcycle Maintenance. The quote is in reference to the first printed words on a set of technical instructions, which the narrator discusses with friends and colleagues on a long-distance motorcycle trip.

    And the response I get is the same every time, likely the same response you’re having right now…

    What in the world are you talking about?

    Well good, now I have your attention. And I’d be willing to bet that attention is on 1) the ludicrous loss of translation from Japanese to English and 2) debating whether or not something as seemingly superficial as “peace of mind” is really required to assemble a bicycle.

    Language barrier aside, let’s abstract away from modes of bipedal transport into a more generic “machine”. Do we really require “peace of mind” to assemble or create a machine?

    cory2

    Reliable? Maintainable? Usable?

    We certainly all want to receive peace of mind from our machines. We want them to do the job they were created to do without fail so we can move our attention onto other things.

    What words do we use to describe such machines that give us this peace of mind? Reliable? Maintainable? Usable? When we think of the reliability, maintainability or usability of a machine, we’re really just describing a machine that can produce peace of mind. I’d argue if we want that machine to produce peace of mind, then it must be created under peace of mind.

    Why is that? If we, the creators of machines, are in a state of peace of mind when we start our endeavor, we’re highly motivated to do that which will continue our state of peace of mind. We don’t want to lose this state. Since if the machine does break, we the creators will be forced to lose our peace of mind and fix it, we’re motivated to create a machine that’s resilient against failure and resilient against our loss of peace of mind.

    Without this key precondition to creation, we’re likely to build our existing personal problems right into the machine itself! Under time pressure? We’ll cut corners to make deadlines. Dealing with a different machine breaking? Likely to gloss over a key failure condition in the machine we’re actively building so we can fight a fire elsewhere. Worried about the problems of today? Then I can guarantee there’s no thought going into a machine that will be resilient to the problems of tomorrow.

    Quality creations produce serene creators as much as serene creators produce quality creations.

    Those in a state of serenity will continue to create that which maintains the state of serenity or peace of mind; those that are not in a state of serenity are unable to escape a vicious cycle of build-fix-build-fix, never achieving peace of mind. Ultimately, the serenity of the creator is the key test for the quality of creation.

    And ultimately, this passion for peace of mind from our machines is what you’ll find when you meet the folks in the DevOps community. We’re guided by a desire to maintain our peace of mind — for ourselves, for our families and for the folks that count on us the most: our customers.

    If the machine produces tranquility, it’s right. If it disturbs you, it’s wrong until either the machine or your mind is changed.

    The material object of observation, the bicycle or [in this case, the global infrastructure], can’t be right or wrong. Molecules are molecules. They don’t have any ethical codes to follow except those people give them. The test of the machine is the satisfaction it gives you. There isn’t any other test. If the machine produces tranquility it’s right. If it disturbs you it’s wrong until either the machine or your mind is changed. The test of the machine is always your own mind. There isn’t any other test.
    – Robert Pirsig

    So the next time you find yourself struggling with a problem, take a lesson from Robert Pirsig: step back, achieve peace of mind, combat that which threatens peace of mind and strive to maintain peace of mind.

    You’ll be a better (and happier) creator for it.

  • You Can’t Sell DevOps

    You Can’t Sell DevOps

    A few days ago, I made an introduction for colleague Jason Dixon (@obfuscurity) over email, and described Jason as “a leading supporter of the DevOps movement”. A mere 17 minutes later, Jason replies to me, “Are you trolling me?”.

    I was aghast. Granted, I haven’t known Jason terribly long (measured in months), but I’ve been well aware of his impact and contributions to the technical community (pulling together Monitorama , for starters). I couldn’t fathom the visceral reaction. But it did get me thinking… Why would someone so impactful want to distance themselves from the description?

    For Jason, and many like him, it’s a question of intentions. To explore that, we’ll have to go back to the beginning, and for me the beginning was 5:20pm PST on June 24, 2010, in the last session on the last day of Velocity CA… a “choose your own adventure” talk by Adam Jacob (@adamhjk ), answering the question “what is DevOps?”.

    I happened to have my flip cam handy…

    http://www.youtube.com/watch?v=Fx8OBeNmaWw

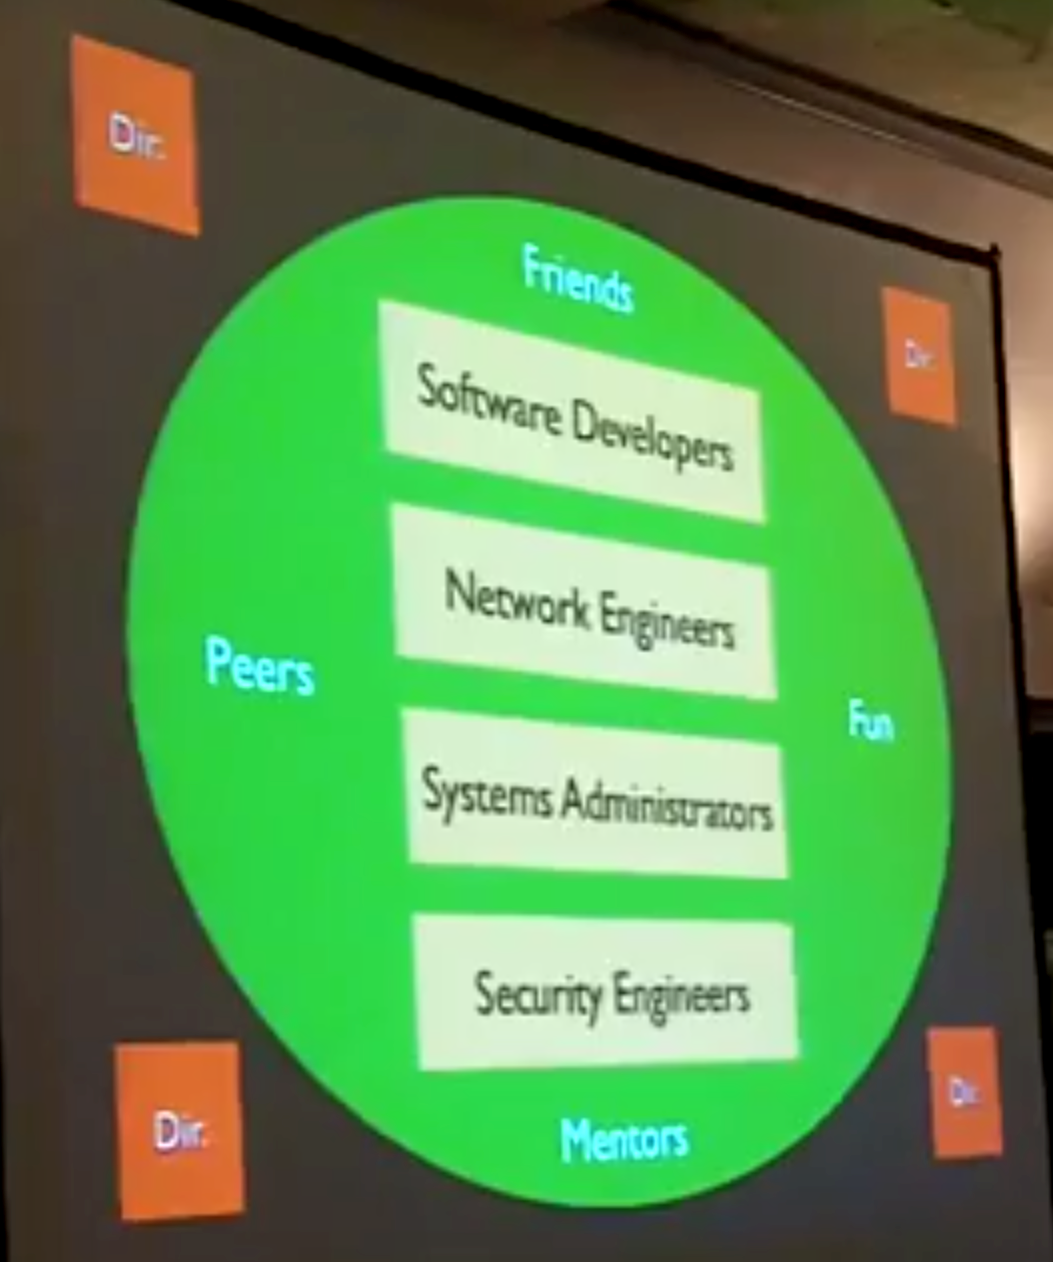
    “So here’s the thing: DevOps is a cultural and professional movement. Period. That’s it… There’s no technology, you can’t patent ‘devops’. Can you market a DevOps compliant toolset? You cannot.”Adam went on to describe the evolution of the system operation profession, and the challenges he personally found. Then came the org chart of a traditional silo approach to a technical organization hierarchy: software developers

    Adam proceeded to challenge this approach with an alternative. “So this is everybody in a big pile. What we are is peers, and friends, and mentors, and we are having fun!”. Hysterically live in one silo, reporting into a director who reports into a VP, network engineers live in a separate silo, reporting into a separate director, system administrators in a third silo, and security engineers in a fourth. Proverbial walls erected between technical contributors, isolated from one another through a formal hierarchy. Need to communicate across to a peer? Better go up the stack to go back down.

    Our hypothetical example continues of a conversation in the big pile: “Hey security dude, what’s that you’re doing?!?”, and he’s like “I’m breaking into the web site.” And you’re like “How’d you do that?!?”, and he shows you and the network engineer is like “I can stop you,” and you’re like “How?!?,” and he’s like “Firewall rules.” And you’re like “Whoa! Firewall rules?!?” and the security engineer is like “Why did you need to do that anyway, that’s a protected network”. And then everybody is having a good time. And the Directors. They’re just helping you out. They’re propping you up.” cory2

    While improvised, comical, and at best a generalization of an industry in a hypothetical example, one key point stuck in my mind from Adam’s talk: DevOps was about people, and how they were most effective and happiest working together. That was the point of the cultural and professional movement: to be more effective and happier as a team, embracing a “shared outcome.” Software developers, network engineers, system administrators, security engineers, directors, VPs, etc., we all succeed or fail together.

    That’s not something you can sell. (In this context, I’ve specifically referring to selling a tool or service.) Nor is it something you can pin down to one definition applicable everywhere. Nor is it something that you can transplant wholesale from one company to another and expect the same level of effectiveness and happiness. You can’t “bolt on” DevOps to your existing organization with only tools and services. You can’t buy a toolset and expect your challenges to be alleviated. You have to understand the role improved tooling has played for those that have found success in this field.

    Tools can certainly be enablers and facilitators, particularly when they free up person hours from manual tasks (assuming you can channel the new found time in an enabling direction), and particularly when they increase transparency as to where technical problems exist, helping to avoid the “It’s not my servers, it’s your code. It’s not my code, it’s your servers” blamefest. How we interact with them, and the patterns of behavior they impose on us as people, can lead to drastically different results from one organization to the next, even if those organizations have identical tools.

    When our tools look like the first silo org chart example above, with a different set of tools presenting different perspectives to different teams bound together by a shared outcome, the tools end up dictating and reinforcing the silo organization hierarchy for how people work together.  To break down the proverbial walls, our tools instead must help define how people should work together.

    Tools enabling configuration management, automation, improved monitoring, metrics collection, and source control won’t ensure success in isolation, because the DevOps movement isn’t ultimately about the tools. It’s about the people, and how they will work best together to succeed. The right tools can go a long way toward removing barriers, enabling the right conversations, and setting the stage for success.

    Part of the challenge is that the tools are one of the more tangible and visible aspects of how we work. In can be easy to take a stroll through a peer organization and take note of the different tools, and attribute their success accordingly. You might be sold on the idea that a tool they have has been the missing piece to your success all along. Fight this first impulse to the tangible and visible, and remember that it’s hard to see how folks really interact. It’s hard to see how well their people, processes and tools work together to produce results in sunny-day scenarios. It’s even harder to see when the sh*t hits the proverbial fan. That’s where the real test is though, and that’s where the real lessons are to be learned. 

    So let’s all be a little more focused on the lessons learned in ways to work together supported by tools than on the merits of one tool over another in isolation. No doubt, it’s a harder and deeper conversation to have, but the value is tremendously greater. If we keep it up, maybe we can make Jason proud to call himself a leading supporter of this professional and cultural movement.

    Or maybe I was trolling Jason Dixon all along.