Author: contributor

  • Bringing the Database into the DevOps Fold

    Bringing the Database into the DevOps Fold

    In my last post on devopsy.kinsta.cloud I asked the question, “Where is the DBA in the DevOps Conversation?” I have wonderful news. I’ve found them! Having not been offered a seat at the table with everyone else, the DBAs have decided to have their own party in the form of a survey and corresponding report by Unisphere Research for the Independent Oracle Users’ Group.

    Until now so much of the research, literature, and web content on the topic of DevOps has been completely devoid of talk about the database and DBAs. The oversight was significant and troubling given the immense strategic business value of any organization’s ever growing store of data. The IOUG report does an excellent job of framing the case for DevOps in terms of the special considerations required when trying to adapt to the lightning fast pace of change in modern IT.

    For me, the biggest take away from the report is that DBAs and their managers are feeling the pain of increased release velocity acutely.
    Interestingly, while the age of automation and cloud may be upon us, an increasing number of database managers and professionals report that they are being mired in manual processes. More than one-third cited this as a challenge, up a dramatic 162% from four years ago.
    There’s no question that companies large and small understand that releasing quality services and features based on market demand at a faster rate than your competition keeps your organization on top. It’s also apparent that product development and most of IT operations have made the necessary investments in process modification and the automation necessary to truly achieve faster delivery. Unfortunately the report confirms what the good folks at my company, Datical, have been saying all along. The lack of safe, intelligent deployment automation options for the database is starting to limit the potential gains of DevOps implementation…and the data team knows it. But it’s not the actual script execution that takes so much time. It’s all the time spent before that maintenance window making sure that security isn’t being compromised, that the change is compliant with external regulations and corporate standards, and that it won’t negatively affect your data.

    Today’s manual database operations, processes, and approval time are among the causes of delays holding up the real-time enterprise, many database managers and professionals admit. Frantic development cycles and the accelerated pace of business innovation requires that data and insights be available at a moment’s notice. Close to 41% of respondents report that it takes a week or more to approve change requests, as well as to configure new databases for key purposes, even for testing.

    To safely reduce these cycle times a DevOps solution for database deployments has to harness the expertise and experience of an organization’s DBAs to fuel intelligent, environment-aware automated validation of these change requests. The automation can’t simply parse the SQL script looking for patterns that may be problematic. It must be able to evaluate all 5 W’s associated with the change and make the correct determination as to whether it is acceptable or needs further review. By focusing the valuable finite resource that is your organization’s DBAs on only those changes that need their special attention, you’ll reap even greater rewards from your DevOps investments.

    I’ve just scratched the surface of what’s available in this report and I highly recommend you read and share it with the DBAs at your company. The survey covers responses from folks in every size company and at every level of the database team. It is full of facts and observations that will be readily familiar to any DevOps enthusiast or practitioner. DBAs, IT, Developers, and the business are now all speaking the same language when it comes to DevOps. Do what you can in your organization to make sure they are speaking that language to each other.

    About the Author/Pete Pickerill

    Pete Pickerill is Vice President of Products and Co-founder of Datical. Pete is a software industry veteran who has built his career in Austin’s technology sector. Prior to co-founding Datical, he was employee number one at Phurnace Software and helped lead the company to a high profile acquisition by BMC Software, Inc. His ability to understand product demands from a customer’s perspective and translate those demands into actionable product and development plans has led to expanded duties at every company for which he’s worked.

  • Choosing a Mobile Test Automation Solution: What You Need to Know

    Choosing a Mobile Test Automation Solution: What You Need to Know

    Organizations today rely more and more heavily on mobile apps to drive their business. In fact, many companies are already seeing more than half of their web traffic coming in via mobile devices. In some cases, their mobile app is the only way customers interact with their products.

    It’s no surprise, then, that developing, testing, and releasing quality mobile apps quickly and efficiently is a high priority for most organizations—as it should be! Fortunately, mobile development tools are evolving to meet these needs, with modern dev teams having access to better test automation than ever before.

    Of course, the effectiveness of a mobile testing process is only as good as the technology behind it. This makes it even more crucial for organizations to know what factors are most important to take into account when choosing or building a robust mobile testing solution. Below, we outline some key things to consider:

    Native, Hybrid, and Mobile Web Support
    Modern mobile applications come in three different flavors: native, hybrid and web. Native apps are built using the vendor-provided SDKs. Hybrid apps run some or all of their functionality inside a webview embedded in a native app. Finally, mobile web apps are simply mobile-optimized website that users access through their mobile browsers. While there is a growing trend towards mobile web and hybrid applications (rather than native), to ensure maximum flexibility and impact of your QA solution, it’s important that you choose a tool that supports all three kinds of apps.

    On-Demand Cloud Testing
    With QA teams becoming more and more distributed, it makes sense to ensure that your mobile application testing solution includes a cloud component. Leveraging an automation cloud enables teams to use organize around a single implementation of test architecture, with devices and test result data accessible from anywhere in the world. You can spend your time worrying about your testsuite, not the cost and maintenance headaches associated with keeping up multiple home-grown device grids and architectural patterns.

    Automation
    When it comes to mobile testing, automation is essential. Choosing the right automation frameworks (Selenium, Appium, etc…) and test tools (languages, test runners, etc…) can be a challenge, and it’s important to think about all the factors involved in getting a solid mobile build process going, relative to the expertise your QA team possesses. What kinds of user flows will you need to automate, and can the automation tool support them? Do you want automation code mixed in with your app code or cleanly separate? Is automation support available for the languages and tools you know best? Think about building a testsuite with the same level of architectural foresight as you would building an app.

    Integration with Key Support Systems
    It’s also important to consider what level of integration is needed with support systems in your environment – whether it’s a test management system, a CI server, or defect tracking system. A strong solution will be able to easily integrate with all of these other systems, perhaps all the way down to the IDEs your developers are using.

    Cross Platform Support
    With the majority of applications being developed for iOS and Android, it’s a minimum requirement for your mobile application testing solution to support automation on both platforms. Of course, this will no doubt expand as you consider other devices and operating systems such as Windows, FirefoxOS, etc…, based on your customer base.

    Scalability
    As the number of device types and operating systems being tested increases, it becomes increasingly important that your test architecture is able to scale automatically based on the number of tests you want to run and the amount of time you want your build to take. Building your automation on a framework like the open source Appium project is a good architectural investment; Appium’s client/server architecture makes it easy to build a testsuite than can automatically utilize a cloud service as your need for more emulators, simulators, and real devices grows.

    The proliferation of web and mobile applications across a myriad of devices and operating systems is fueling a demand for faster and faster delivery of software experiences, without any sacrifice of quality. Today’s leading software companies know that successful apps are built on the foundation of their mobile application testing processes and tools. By keeping in mind the key features mentioned above, organizations can work towards building and identifying the best testing solution for them. The QA process should be a breeze, rather than a hassle.

    About the Author/Jonathan Lipps

    jlipps Jonathan Lipps serves as the director of ecosystem and integrations at Sauce Labs, where he leads a team of developers to ensure that the open source ecosystem surrounding the company’s core products is always maintained. He is a frequent speaker on automated web and mobile app testing, and holds advanced degrees in Linguistics and Philosophy.  Reach Jonathan on twitter.


  • The Holistic Nature of DevOps, Architecture and Methodology

    The Holistic Nature of DevOps, Architecture and Methodology

    Throwing it Over the FenceDevOps

    DevOps…It’s become a term that has devolved to describe too many of the wrong things. Job titles like “DevOps engineer” and “Director of DevOps” and even DevOps training and certification programs hide an important issue of what DevOps was originally meant to be…

    If you’ve ever read “The Phoenix Project“, “Release It” or “Continuous Delivery“, (and you should) you probably already know that DevOps was never intended to be a title nor a department. DevOps is an organizational pattern. It’s what you get when development teams stop “throwing code over the fence” into production and start working together with IT operations personnel as members of cross-functional teams.

    Cross-Functional Teams

    Many so-called cross-functional teams usually consist of developers and testers; and sometimes even a business analyst or product owner. This is not what cross-functional means. True cross-functional teams include members representing the full spectrum of disciplines required to bring software from idea to production. Such teams include product owners, functional analysts, UX designers, developers, QA, DBAs, enterprise architects and IT Ops personnel, and these teams have full responsibility over all aspects of their software product until it is no longer in service.

    For many organizations, this is a bold departure from tradition in which development teams hand off completed software to a separate operations team for deployment and maintenance in production. The philosophy driving the DevOps movement seeks to eliminate this separation. But why?

    Handoffs are Wasteful

    Anytime the responsibility for a software product changes hands, even under the best of circumstances, some knowledge is inevitably lost. Additionally, each transfer of knowledge and responsibility along the production chain lengthens your product’s lead-time, incurring unnecessary costs. These costs might include time spent in meetings and writing detailed documentation instead of coding, plus delays in realizing revenue and ROI the longer your product takes to get to your customers.

    In Lean manufacturing and lean software development, any step in the process that moves unfinished product from one stage to another, making no changes to bring it closer to the state for which a customer would pay, is considered “waste of transport” – one of the original 7 forms of waste. One of the key goals of Lean is to reduce such waste, and one way to eliminate these handoffs is by having one team responsible for all aspects of the product. From the inception of ideas all the way into production—including bug fixes and production support—have one team communicating and working together all the way, making Conway’s Law work for you.

    Conway’s Law and Systems Architecture

    Over 40 years ago, programmer Mel Conway publicized his observation that the design of software systems reflect the communication structures of the organization that built it. This has since become known as Conway’s Law and recent studies have validated the idea.  The truth behind Conway’s Law is that, almost always, communication and activities in organizations follow the path of least resistance.

    For example, if the development team has to deal with too much red tape to get a database script into production, they’ll write a workaround in the application layer instead, which they control.

    This is also why most organizations in which development teams hand off code to ops teams wind up with code that is written well enough to pass acceptance tests in development and QA environments, but fail to take into consideration concerns like performance, security and scalability in a production environment. Teams that are structured to share information across departments and given autonomy to make decisions are better equipped to develop highly robust and cohesive systems.

    Not every team needs a dedicated architect, DBA, or Ops person. Depending on the needs of your organization, people in these roles can belong to multiple teams, providing much needed communication and consistency between their respective product teams and their departmental teams.
    In summary, organizing teams to be truly cross-functional, together with the application of Lean manufacturing principles, is how you can start to build a DevOps culture that will continue to deliver quality software for years to come.

    About the Author/Michael Ibarra

    Michael-Ibarra-devopsMichael Ibarra is a Solutions Consultant with AIM Consulting. A software craftsman, tech speaker and self-described troublemaker, he has been building software and development teams in the Seattle area for nearly 20 years.


  • Testing Will Never Be Automated

    Testing Will Never Be Automated

    “Come to think of it, no one speaks of automated programming or manual programming. There is programming, and there is lots of other stuff done by tools. Once a tool is created to do that stuff, it is never called programming again.”

    – James Bach and Michael Bolton, “Testing and Checking Refined

    That’s one of those points that tends to silence a room, as there’s really no way to successfully argue against it, but since similar positions of frustration came up time and time again at the 2015 STAREAST conference, it obviously deserves some further discussion.

    The issue lies in the surprisingly stark differences between the phrases “automated testing” and “test (or testing) automation.” And if you don’t know the difference:

    1. You’re not alone.
    2. You’re likely not a software tester.
    3. You’re discrediting and undervaluing the testing craft.

    The good news is that learning the difference is easy—and testers will forgive you for not knowing it until now! They’re very nice people.

    Here’s what today’s brightest and hardest working testers want you to know. “Test automation applies tools to testing.” They do not automate testing, and they certainly won’t ever replace it. There’s simply no such thing as automated testing.

    And I’m part of the problem. I wrote a column just last year, titled, “Automated testing’s ROI is right under your nose.” I’m somewhat embarrassed that I told the world something that doesn’t even exist provides an immediate ROI—though at least no one went out and bought a completely fictitious tool off of my suggestion.

    Judging by the boisterous cheers as numerous speakers at STAREAST pointed out the absurdity of believing that testing can be automated, this belief is something that I predict testers will likely soon make a concerted effort to erase.

    As companies focus more on collaborative, cross-functional, and quality-minded efforts like agile, test-driven development, and DevOps, testers have an incredible opportunity to clear up any misconceptions about their immense importance to their business.

    Respected tester, author, and public speaker Dorothy Graham recently pointed out a number of these misconceptions in her session, “Blunders in Test Automation” and the very first one on the list was “thinking that testing tools actually do testing.” Sounding almost exasperated at having to point this out, she chuckled, threw her hands up, and said, “They just run stuff, whatever they’ve been programmed to execute, including bad tests.” She almost got a standing ovation.

    When you get that kind of reaction from a room of a thousand software testers from around the world—we’re beyond semantics, and are in a real problem. This is a talented, valuable, and understandably fed-up group of people who are being unfairly cost and productivity-measured against software that provides a completely different service.

    So how did it get this bad, when entire conferences are dotted with calls to action for testers to clearly differentiate themselves from tools, especially when the differentiation is so easy to see?

    One group you may be surprised I’m largely letting off the hook is the tool manufacturers and their marketers. Sure, there are companies that make some claims that testers may wince at, but it’s really hard to find anyone claiming their tool beats, is smarter than, or should replace any human. There’s no reason for them to make these claims; they’re not true, and they certainly won’t help sell the product.

    What about journalists and writers like me who cover the software development and testing industries? After witnessing the frustrations of testers when they feel like they’re being replaced by non-human, non-equivalents—you make a mental note to scratch that phrase from your style guide. I hope other writers do the same.

    How about product owners and others closer to the business side of an organization? Are they contributing to an under-appreciation of the human aspect of software testing? That’s…a little tricky.

    Scott Barber has spent more than fifteen years as a performance tester, but recently experienced (and left) the role of a product owner. While I’m more than familiar with, and a real fan of Scott’s “the truth hurts” speaking style, when he revealed some truths he recently learned, the room grew incredibly uneasy. Many got their first introduction to Scott when he started his session with:

    “It’s not all about testing, you know. Testing is not a product. You are not a product…. Products are the source of profit. And as a product owner, I paid very little attention to testers and testing.”

    It may sting, but it’s the truth. Scott went on to point out that “there’s no need for certain job titles to know or care how things are built or tested. Nobody will ever ask them that.” However, by testers working to gain a much better understanding of the product and the risks that each release candidate poses, there is a massive opportunity to make the value of their work blindingly obvious and positively revenue-impactful.

    Scott’s pro-tip of testers asking a product owner, “Can I do some work with dev and prod so we can get some early observation going on to catch some of these bugs early and head off some of the damage that could come?” drew both a hushed “Wowwww” and “Yeah, I’m using that” from behind me.

    This is where the differentiation between testers and their tools should become clear to everyone. The human levels of empathy, ingenuity, and proactive approach cannot be scripted, automated or baked into any tool, and the best testers care enough about their product and its customers to prove it.

    About the Author/Noel Wurst

    noel wurstNoel Wurst, managing editor at Skytap, Noel is responsible for setting and executing Skytap’s content marketing strategy. That includes overseeing the creation and distribution of high-quality, targeted content, and managing the team and external resources associated with those efforts. By leveraging deep online marketing, project management, and editorial experience, Noel plays a crucial role in helping generate and nurture leads with compelling content.

     Follow Noel on Twitter, @NoelWurst, along with Skytap, @Skytap.

  • Launching Applications to the Cloud – It’s all about Scalability and Speed

    Launching Applications to the Cloud – It’s all about Scalability and Speed

    It is not hyperbolic to state that today’s web services deal in hyperscale realms when one considers stats such as

    • The Amazon cloud can handle up to 1 million transactions per second during peak loads
    • Facebook was managing 890 million daily active users on average for December 2014
    • There are 500 million tweets sent per day and 80 percent of those are sent from mobile devices

    Ironically, the move to hyperscale web services has been made possible by applications going micro, as in microservices as commonly defined as “small, independent processes communicating with each other using language-agnostic APIs.” The emergence of microservices based application architectures is a revolutionary departure from monolithic app development, which was purpose-built around a single service, e.g. storage management, CRM, etc. In its place now are 10 or more modular, reusable services each owning a limited and specific set of functionality in what might be best illustrated as replacing a singular black box with a set of Lego blocks.

    In turn, this has led directly to key advancements in the application development process, evolving from start-to-finish programming to agile, continuous integration/continuous development (CICD). This model offers two major advantages over the waterfall development approach:

    • One, decreasing software development time to align to the “speed of business” dictated by market factors and not by IT processes.
    • Two, enabling specific modules of an application to achieve “autonomous elastic scale” where instances can be scaled up or down dynamically and on an as-needed basis.

    The software world and its professionals are intimately familiar with these application megatrends, of course. They live it every day. However, they may be less familiar with what’s happening — or to be more precise what’s not happening — with the evolution of networking, specifically in the layer that manages server load balancing or application delivery control (ADC).

    This is so because legacy ADCs were built and optimized for applications that resided in a single hardware platform and at a single location. With the advent of Microservices, the days of a cozy 1-to-1 relationship between the ADC and a monolithic application is quickly becoming a thing of the past. A useful analogy here is to equate the management of these resources with how humans treat cattle vs. pets.

    Application microservices are like cattle in that while these resources are valuable, each resource can be easily replaced. Legacy ADCs are like pets in that they’re not easily replaceable and, at times, require painstaking levels of care and attention.  Indeed, it is clear that the pace of innovation for these networking devices has not kept pace with the requirements of application microservices in their current forms as either hardware appliances or as self-contained VM appliances.

    Though legacy ADCs may be upgraded to be microservice “aware” and even provide certain levels of integration; they are not optimized to support an application architecture that’s built on microservices written in different programming languages and distributed across many different hardware platforms, clouds, and even data center locations.

    The solution requires ADCs and load balancers to evolve to take on more of the characteristics microservices possess (be more like cattle and less like pets), namely:

    • Being tightly aligned with each app microservice and not with the entire monolithic app;
    • Delivering a consistent set of network services in a location-agnostic way, whether the app location is on-premises in a data center or distributed across private and public clouds;
    • Being hardware agnostic, whether the app is on bare metal, in VMs, or even in containers – without requiring additional configuration tools; and
    • Achieving autonomous and elastic scale to support each microservice throughout its useful lifecycle.

    Further, this evolution must be true and profound and not a mere incremental advancement, which has hindered the adoption of software-defined data centers among the large enterprise segments thus far.

    Specifically, ADCs must achieve the concept of “application affinity” which is based on the app-world concept of “processor affinity” where resources are aligned/pinned for specific functions. There are two major benefits to this approach. First, having the ADC resource side-by-side, the microservice will improve the application response time. The application delivery follows the “destiny” of the microservice – it grows, shrinks and moves with the app itself.

    Second, this tight alignment (affinity) enables ADC resources to achieve automatic lifecycle management of microservices without manual intervention, which reduces management complexity significantly.

    In summary, it’s been said that best things tend to come in small packages. Such is the case with the emergence of application microservices, which has paved the way for agile, continuous application development and hyperscale web services.

    It’s time for the ADC to undergo a similar evolutionary path in order to maintain its strategic value as the gateway between the network and application layers.

    About the Author/ Dhritiman Dasgupta

    DD_Exec MugDhritiman Dasgupta  the VP of Marketing Avi Networks.Prior to joining the Avi Networks team, Dhritiman Dasgupta (aka DD) was a Vice President at Juniper Networks where he headed up the data center, security, and SDN marketing efforts.  He launched the award-winning QFabric and MetaFabric systems. Prior to Juniper, DD spent 9 years at Cisco Systems in the LAN and Data Center switching divisions heading up product management for several multi-billion dollar platforms including the Catalyst series switches.  https://twitter.com/mandhriti

  • 5 Ways To Speed Up Mobile App Testing

    5 Ways To Speed Up Mobile App Testing

    We’re all familiar with the story of the tortoise and the hare, where a plodding tortoise wins a race against a speedy hare because the over-confident hare takes a nap midway through the race.

    It’s a valuable lesson about the power of smarts over sheer speed. But all due respect to the methodical approach, the tortoise does NOT win the race in mobile app testing. The hare wins. But he needs to be smarter than Aesop’s reckless rabbit.

    Despite efforts to expedite app release cycles, enterprise mobile teams still struggle with what we call “velocity blockers”, which are testing practices and processes getting in the way of fast, iterative app releases. To get to the bottom of velocity blockers, the Perfecto Mobile research team surveyed a group of 350 enterprise-level developers, DevOps and QA people of various responsibilities about what testing-related issues are slowing them down.

    The survey data revealed an encouraging shift to Agile practices that emphasize quick results and integrated feedback. It’s like having a hare’s body with a tortoise’s brain. Of our respondents, 86% said that they’re either Agile, or have made the first steps towards Agile. And 94% say they’ll be there within a year.

    This shift is reassuring, but testing lags remain in the way of progress, according to survey results. Here are the five main velocity blockers cited by respondents, with tips on how to be smart like a tortoise while moving as fast as a hare.

    1. Slow QA to Developer Feedback

    As developer teams begin using agile practices, the feedback loop between QA and developers tends to be unbalanced. Often when a company speeds up to a monthly release cycle, a team will spend three weeks developing and the last week testing and fixing bugs. The problem here is that as much work needs to happen in the final week as in the previous three weeks.

    Solution: We recommend embedding quality throughout the entire lifecycle, a concept we call Continuous Quality. QA feedback is always visible and developers always know where their code stands because it’s constantly being tested. Maintaining this kind of control over the quality of your mobile app throughout all stages of your SDLC will boost the speed of development and reduce the number and severity of defects reaching production.

    1. Ineffective Test Automation

    Automation, on its own, may speed up testing and releases. But it’s how automation is implemented that really makes a difference. Automating your test scripts is an important step, but it’s not enough. You must first make sure your environment is stable for automated tests. When you run automated testing across an unstable environment, false negatives happen.

    Solution: Start by automating the provisioning of your test environment to make sure it’s stable and will support your test automation correctly. If your environment is stable, your tests won’t return false negatives.

    1. Delays in Device Readiness

    Was your app ready to run on the Samsung Galaxy S6 when it released? Did someone on your team wait at the store to purchase it so you could deliver 0-day test results? Better yet, did you get it before it was released to test your app against it before users could upgrade? The answer is probably no, just based how quickly new devices are released to the market. But to maximize test coverage, device readiness is a full-time job. So how do you get the latest devices into your test lab, online and ready for testing before your users are impacted?

    Solution: Let a managed lab-as-a-service do some work for you, where a vendor acquires new devices, maybe before they’re publically available. Let them manage your test lab for you, and dedicate experts to you. Make sure they also offer an SLA. It costs an estimated $6,500 per device per year to manage in-house. Multiply that number by the total devices you need to test on, and this gets unscalable, unmanageable and unprofitable.

    1. Slow Access to Mobile Devices

    Let’s say you do buy devices and manage your own lab. The next issue you’ll run into is making those devices available to your testers all over the world in real time.

    At one of the top U.S. mobile carriers, when a new device was released, the carrier had staff who had to acquire the device and ship it to where testing was performed. This group had limited time to test the device before shipping it to another testing group. When timelines weren’t being met, the staff member physically traveled with devices, from test group to test group, to ensure they made it into the right hands and on time. Travel costs made for an inefficient process.

    Solution: Once the carrier chose to put devices in the cloud, the device procurement and deadline challenges were eliminated and a scalable, on-demand cloud emerged. They can now centrally manage devices for testing via the cloud and groups can access devices remotely while still ensuring the same user experience.

    1. Manual Testing Takes Too Long

    Manual testing is by far the top app development velocity blocker. We work with a lot of the major banks because, more than most industries, banks win and lose customers on the merits of their mobile app. One of the top U.S. banks came to us back in 2010. They were doing lots of manual testing of a wide range of complex scripts. It took them a long time to push through their test cycles, and app defects were missed.

    Solution: The bank’s pre-automated test environment relied heavily on manual testing, and included duplicate labs and a 16-20 day regression cycle. After automating their testing scenarios, they saw a 90% time reduction per regression cycle. That’s bringing weeks-long cycles down to mere hours. They were even able to quantify that they saved $40,000 per test cycle. In the end, the bank was able to decrease their cycle times and the defects released to production by doing test automation. A major velocity blocker was unblocked!

    About the Author/Eran Kinsbruner

    Eran Kinsbruner_150x175Eran Kinsbruner, is director of product marketing at PerfectoMobile, one of the leading mobile cloud and automation companies. Formerly CTO for mobile testing and Texas Instruments project manager at Matrix, Eran has been in testing since 1999 with experience that includes managing teams at Qulicke & Soffa, Sun Microsystems, General Electric, and NeuStar. The co-inventor of a test exclusion automated mechanism for mobile J2ME testing at Sun Microsystems, Eran has experience in the mobile testing world. You can find Eran on Facebook, Twitter @ek121268, LinkedIn, and his professional mobile testing blog at ek121268.wordpress.com.

  • DevOps, Containers and Faster Time-to-Parity

    DevOps, Containers and Faster Time-to-Parity

    DevOps discussions often focus on the value of getting innovative applications to market quickly. And it’s true. Getting a cool new application into production quickly can help you differentiate yourself in today’s app-sensitive marketplace.

    But, in reality, most development is devoted to “Me Too” applications—and these apps are no less important to the business than the much rarer innovative ones.

    In fact, as ironic as it may seem, consistently rapid time-to-parity may be more important to the business than occasionally rapid time-to-innovation.

    The Power of “Me Too”
    Every marketer and salesperson knows the power of “Me Too.” Yes, in competitive markets, it’s good to have something the other guy doesn’t. But that differentiation can be for naught if the other guy also has something you don’t.

    Conversely, you can quickly neutralize any advantages your competitors gain by simply replicating them ASAP.

    That’s why ….


    –THIS STORY HAS BEEN MOVED TO CONTAINER JOURNAL–


    About the Author/Aruna Ravichandran

    ravichandran arunaAruna Ravichandran is vice president of DevOps Solution Marketing and Management at CA Technologies, responsible for cross-portfolio solution marketing for DevOps across all product lines. Before joining CA Technologies, Aruna held several management positions in product marketing and engineering at Juniper Networks and HP. Aruna earned an MBA and master’s degree in Computer Engineering from Santa Clara University and holds a bachelor of science degree in computer science from Bangalore Institute of Technology. Ravichandran is  on twitter @aruna13 and on Linked in

  • Sleep easy: release automation reduces DevOps security threats

    Sleep easy: release automation reduces DevOps security threats

    Sleep easy: release automation reduces DevOps security threats

    “Devops reigns”. “DevOps redefines the way services are launched and managed”. Just two of the recent headlines from the sea of coverage on DevOps. It’s a reasonable argument. The software development methodology emphasizes communication and collaboration between software developers and other IT professionals, and is quickly gaining ground as organizations see a way to launch services faster and improve operations performance. The current DevOps talent shortage also points to Fortune 1000 companies waking up to the difference DevOps can make.

    Here’s the catch. While DevOps appears the master and commander of faster feature releases, it also has the potential to expose software vulnerabilities and security threats in your production environments. We all know that assembling existing code is more efficient than rewriting it from scratch, for example. And when assembling applications from libraries, developers typically use the latest version of that code, assuming it is likely to have less bugs.

    However, new releases can open up new security vulnerabilities. Take the Spring Framework, for instance, a Java platform that provides comprehensive infrastructure support for developing Java applications. According to Joshua Corman, CTO of Sonatype, 81 of the 85 versions of the Spring Framework have known vulnerabilities.

    Software and security vulnerabilities can also rise to the surface unless there is an audit of the production software for security defects. Developers can easily pick up any code they choose without identifying the source or what they did with it. Speaking at the RSA Security Conference, David Mortman, chief security architect at Dell Software, explained that when he began software audits at the company, 198 known execution flaws were found in the code base—putting the company and its applications at risk. And this risk is set to do more harm as DevOps is used to develop physical ‘Internet of Things’ products and services.

    Here’s another fact to put the issue of security into context. Organizations collectively spend $20 billion every year on network security, $10 billion on host security and $5 billion on data security. And you know how much is invested in software supply chain security by all companies? Just half a billion dollars.

    It’s not all bad news though. During the RSA Security Conference, Mortman commented, “A good DevOps process should be implemented using automation tools that can help to track and document updates. DevOps is about change management, process flow and documenting those processes.”

    And automation really is the answer here. It enables you to bring your new products and services to market faster, whilst remaining in control. By automating your application release process, you package the release from your continuous integration tool and securely promote it to the next environment via a reusable work flow. You maintain complete visibility throughout—and there’s no disruption to the business.

    Any software vulnerabilities are quickly identified using role-based access controls: only authorized staff get to promote packages, and only approved packages can move through the lifecycle. Moreover, the automated deployment model ensures you keep track of the code goes on each server and with what configuration settings. And if you are not happy with any aspect of the release, automation enables you to roll back the deployment to its previous state. Finally, comprehensive audit reports help you see who did what and when throughout the entire release process.

    Automation delivers other unique attributes to reduce security risks:

    • Packages and promotion paths so you can be confident that what is deployed is correct
    • Workflows so you have a standard and quality-assured way to consistently           deploy new changes
    • Deployment models to ensure the correct setting and configurations are applied to each environment.


    Your development squad is under more pressure than ever to deliver more functionality, faster without disrupting current applications. By automating your application release process, you not only embrace DevOps in full strength, you also gain back control.

    About the Author/ Dr. Chris Boorman

    chris-boormanAs Chief Marketing Officer, Dr Chris Boorman is responsible for Automic’s worldwide marketing.
    Prior to joining Automic, Dr. Boorman served as Chief Marketing Officer for cloud collaboration vendor Huddle, and data integration leader Informatica.  He has over 20 years of experience leading international teams at enterprise companies including SDL, salesforce.com, VERITAS and Oracle. Reach him on Twitter: @CHBoorman

  • Where is the DBA in the DevOps conversation?

    Where is the DBA in the DevOps conversation?

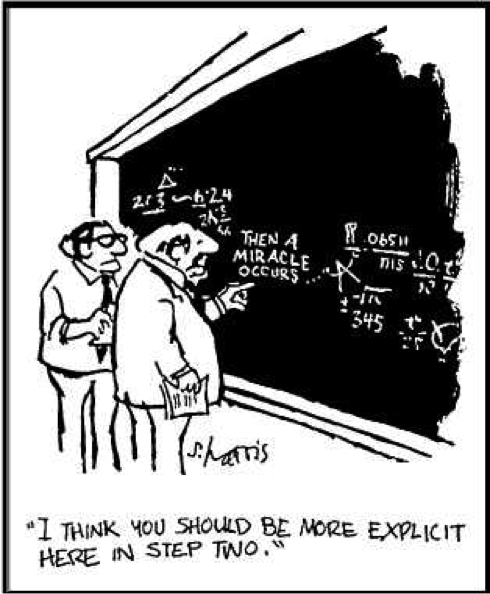
    dbapicIn reading case studies, surveys, and research articles on DevOps I am reminded of a cartoon I saw taped to my high school physics teacher’s file cabinet. Two scientists stand in front of a complex proof scrawled on a chalkboard. Separating steps 1 and 3 of the proof is the statement, “Then a Miracle Occurs.” One of the scientists points to the statement and says, “I think you should be more explicit here in step 2.”

    This is an apt metaphor for the DevOps zeitgeist’s avoidance of the database. ISVs and analysts spend a lot of time talking about how to streamline, accelerate, and automate application development and testing (Step 1) and how to monitor and automate the deployment of those applications (Step 3). But when it comes to managing the database change necessary to support the application and its release processes, it seems that everyone is waiting for that miracle to occur.

    This oversight is unfortunate. DBAs have a lot to offer when it comes to correlating the development of technology with the management of the environment in which it’s hosted. In a sense, DBAs have been DevOps all along.

    On the ‘Dev’ side, DBAs carefully evaluate each change request to ensure that it is well thought out, is compliant with organizational best practices and won’t have unintended consequences on database performance or the validity of dependent objects. They have developed and tested all of the SQL that has materially changed the database and crafted it into what it is today.

    On the ‘Ops’ side, DBAs have designed and provisioned the data platform. They are in charge of monitoring their databases and keeping them available and high-performing. They manage access to and the overall security of the platform. They perform release activities in support of the application and troubleshoot any errors that happen during that process or during day to day operation.

    So why isn’t the larger DevOps community including the data platform in the conversation? Why aren’t DBAs a crucial part of every DevOps team? Why are we relying on a miracle like the scientist in the cartoon?

    Every decision a DBA makes, every process or standard they put in place is influenced by the dual nature of their role. They are used to thinking about the impact of any task, requirement, or problem from both sides. It is deeply ingrained in them. They are deliberate and meticulous in their approach to change management because they understand that what they do has impact beyond what’s directly in front of them. They rely heavily on their expertise and their deep understanding of their organization’s data strategy to ensure they are making safe, future proof decisions to the best of their ability.

    This also explains why we haven’t seen the same proliferation of automation and orchestration solutions for the database that we have seen for other domains in the SDLC. True database automation has to be more than “run this script after that one” or “make this object look like that object over there.” To have a meaningful impact on your release throughput and staff productivity your database automation has to make use of your team’s intelligence. Any solution you implement has to harness the collective experience and knowledge of your DBAs and apply that knowledge to the evaluation of changes as they’re introduced in development. It has to be…miraculous.

    This is the whole reason we started Datical. When it comes to completing your DevOps vision, we wanted Datical to provide a real answer to Step 2 from that comic that has stuck with me all these years. Our flagship product Datical DB was designed and implemented to address the unique challenges associated with automating database changes in support of application releases. It automates and accelerates the propagation of database changes without sacrificing safety. We provide a highly customizable automation framework that is fueled by your experts. It allows you to define standards specific to your organization that are incorporated in our pre-deployment analysis. This greatly reduces the time spent manually reviewing SQL and checking the logic of your SQL scripts for errors that will cause application failures and downtime.

    About the Author/ Pete Pickerill

    High-Res-Peter-Pickerill-6571-150x150Pete Pickerill is Vice President of Products and Co-founder of Datical. Pete is a software industry veteran who has built his career in Austin’s technology sector. Prior to co-founding Datical, he was employee number one at Phurnace Software and helped lead the company to a high profile acquisition by BMC Software, Inc. His ability to understand product demands from a customer’s perspective and translate those demands into actionable product and development plans has led to expanded duties at every company for which he’s worked. In his time at Symantec, Pete worked directly with large financial services companies and online retailers to implement and improve online fraud prevention solutions that were used daily by millions of people worldwide. In addition to managing a development team and product schedule at BMC, Pete worked directly with large financial services institutions to provide the features they needed to achieve greater efficiency and cost savings in their application deployment processes.

  • On beginning software delivery acceleration

    On beginning software delivery acceleration

    Time and time again, we hear of companies achieving rapid acceleration with DevOps. Companies are touting success with the metric of deploys/day, sharing new baselines of 10, 50 or even 100 deploys/day. In more mature organizations the likes of LinkedIn, Netflix, Etsy, Facebook and others, this number is a startling 1,000+ number. But, what does this even mean?

    Unpacking this number is often one IT leaders stumble on, and is the greatest source of pushback when talking about rapid acceleration. How stable is the software being delivered? How many of these deployments are successful? What constitutes a deployment?

    These questions and more often end up creating analysis paralysis, and nothing changes. In fact, the most common response starts with, “There is no way we could implement something like that at my company because…” We know this to be false. Companies who have traditionally delivered in a waterfall fashion with a single, bloated deploy per month or quarter are successfully transitioning to rapid deployment posting similar baseline numbers as other teams.

    How then can you be successful in beginning software delivery? There is no single silver bullet or magic wand, but there is a fairly prescriptive methodology for achieving our goal of rapid delivery. Let’s dive in and take a look on how to get started.

    Ground Rules

    Let’s set the stage with some key principles that will light the path ahead. They are:

    • Embrace failure
    • Blamelessly analyze failures1
    • Quickly repair failures when understood
    • Always be iterating

    In a nutshell, the goal should be to Deploy Fast, Fail Fast, Learn Fast, and Improve Fast. This is a never-ending task, and it is important to consider it as such. Too many times, a project is spun up to start working on these tasks, and inevitably that project ends. Unless continual improvement becomes a core tenant of delivery, any efforts risk falling apart at the seams over time.

    With these rules in mind, let’s continue.

    How is software developed?

    The first stop is incidentally not within the delivery organization, but rather the development organization. This is where the empathy that is so often discussed alongside DevOps will come in; we first need to ensure the developers who are delivering features are equipped for success.

    How is software developed? What does it really mean to get into the flow of production? Ask yourself questions like: how is code introduced into the source tree? What does acceptance of that code look like? (For example: are there code formatting guidelines, are tests needed, etc).

    Once this is understood, the key is the gate that exists to advance code to the next stage of delivery. This is where bottlenecks often exist, and often have valid historic cases for existing. Usually, this is to try and improve quality by introducing checkpoints, but these checkpoints are often human driven, and will invariably contain defects of their own.

    It is important to make the distinction around delivery of code or delivery of features versus the delivery of the software itself. Both are important as illustrated in the next section, but two sides of the same coin that are often separated duties. In the context of the entire system, the need is the same: identify opportunities to reduce friction by either removing steps from process (non-value add unnecessary, vestiges of old days) or introducing automation to move things along.

    These conversations are always enlightening, as it will become pretty apparent where the slowdowns occur after some initial conversations. Keep those brain juices flowing, and let’s continue.

    Keep in mind:

    • Who can write software? Everyone?
    • What is the barrierto entry associated with learning how to write software?
    • How difficult is it to demonstrate working code to a colleague?
    • How difficult is it for a colleague to run your demonstration code?
    • Who can deploy the software?
    • What is the barrier to entry associated with learning how to ship the software?
    • Where is work being assigned?
    • Where are feature discussions happening?

    Kicking things into high gear

    By this point, it is possible that you have a laundry list of things you have already identified as areas to improve. But, where do you focus? The default tendency is to clean up shop first, and then go work with external teams to try and integrate better. However, that is actually the least ideal thing to do, because it ends up creating silos of isolation. Possibly against your better judgment, plan on integrating first.

    Your first steps should be focused on two objectives. The first of which is to embed yourself into the development work stream… get work items from development via their existing process and find yourself an advocate. This advocate will be your “first follower,” and will help you understand what changes are working and which are not, and will provide valuable and honest feedback that may not come from other members not because they don’t care, but as their energy is focused on other things. It is almost a necessity to start small.

    The point of empathy that comes up most times DevOps is mentioned will come into major play here. No matter what efforts that you make to try to improve things, any friction introduced into the life of a developer will dramatically affect your success in any real change. For example: It may be advantageous for you to change the underlying ticketing platform for you all to communicate better, but if you disrupt the existing delivery pipeline, the odds of making new friends may go down a bit.

    Work with your advocate to firm up how development reports issue to your team and vice versa, and run it through the gauntlet. Do not forget to apply ground rules… Deploy Fast, Fail Fast, Learn Fast, and Improve Fast. Fix easy process holes quickly. Do be mindful of the amount of change that is being introduced at any given time, don’t be afraid to make changes, but also be consistent and measured with this change. This will set the appropriate tone for sustained and long-term process improvement.

    Likewise, do a real project via this first process. One early victory can be to ensure that developers have the ability to run any version of code (git checkout, major version, doesn’t matter) with minimal effort.

    This allows me to run other colleagues’ code to test out fixes, confirm bugs, or whatnot. By having the ability to run arbitrary code, collaboration speeds up closest to the code, and the number of problems that bubble up to later phases of deployment are cleaned up much earlier. This may mean staging environments; this may mean local development environments. But, solving the smaller task of how developers can run code becomes a test bed for how a production delivery pipeline may behave.

    When you find failures in both process and tooling, it is essential to be blameless while analyzing and working through failures. Early on, there will be many, and it is essential to set tone early on. John Allspaw talks about this in his article when he discusses incentives.

    Because an engineer who thinks they’re going to be reprimanded are disincentivized to give the details necessary to get an understanding of the mechanism, pathology, and operation of the failure. This lack of understanding of how the accident occurred all but guarantees that it will repeat. If not with the original engineer, another one in the future. – Allspaw

    Another often-overlooked concern is how these solutions are implemented. Repair of these processes cannot be driven by a single person or in a top-down fashion. Rather, all members of the team must be a part of owning the solution. Time and encouragement will go a tremendous length.

    Finally, deploy. The entire point of this project is to deploy code. The work done up to this point largely will focus on the interaction between Development and Operations, but assuredly there is work to be done on both sides. Until you are able to deploy daily without any breakage, that should be your target. Every day, attempt a code deploy regardless if you know the outcome already. Pick one of two things to fix daily: a failure in the process, or a manual step. Repeat this until you can deploy each day with a minimal number of commands (best case: single command).

    The Path Ahead is Dangerous, Take These!

    As you go along this path, there will be two themes that appear to come up time and time again. The first has to do with communication. Processes to deploy may get faster or more streamlined over time, but there are always ways that communication roadblocks cause challenges for the best of teams.

    The second always has to do with tool disparity. Once engineers get wind that tools need to be implemented, all people and process concerns become secondary. This typically becomes a quagmire, as these tools need to actually participate in the communication streams within the organization to facilitate software delivery.

    To this end, there are two tools that are very beneficial to keep in mind as you go down this path: ChatOps2 and Workflow3,4. Both of these topics deserve entire sections dedicated to their own right, but in a nutshell, here are the two things that should whet your palette.

    ChatOps brings the context of the work you are already doing into the conversations you are already having. – James Fryman

    Human readable, machine scriptable language for declaring workflow is not just convenience. It’s a necessity for dynamic creation, uploading and updating workflows on a live system, and for treating “infrastructure-as-code.” – Dmitri Zimine

    Just remember: it’s not about one tool. These tools are a means to an end. The people and process have to be part of this conversation. ChatOps enables the communication and collaboration that creates and drives the development. Workflow enables collaboration around infrastructure process. Both of these will become essential.

    Closing

    To succeed, we as technologists need to know what’s going on in our organization, how technology efforts are helping delivery, and how the technology being deployed is being consumed and by whom. Without this understanding, we’re just throwing tools at a problem and often wind up complicating matters. These tools can jam things up or become shelf ware because nobody is ready to implement them. And in the rapidly moving, lean businesses of today, there is no time for breakdowns.

    Do you know how your teams deliver and collaborate around software? Do you have a tight feedback loop established between your teams and those you provide services to? Are you moving fast, and fixing even faster?

    How teams deliver software today is quickly being recognized as a market differentiator. This journey is neither easy nor quick, but will enable your organization to be prepared for the next phase of rapid growth in the industry.

    ###

    1https://codeascraft.com/2012/05/22/blameless-postmortems/

    2https://speakerdeck.com/jfryman/chatops-technology-and-philosophy

    3http://stackstorm.com/2015/04/10/the-return-of-workflows

    4https://www.slideshare.net/slideshow/embed_code/key/cHCIlAlU4Xb1Lw

    About the Author/James Fryman

    ph-james-2015-05-12James Fryman is an Information Technologist who builds, designs, curates, and evangelizes automation in all layers of the IT stack. Over the last decade, he has held roles in Information Technology that include the domains of Information Security, Service Delivery, IT Operations, Development, and IT Management. He has learned through these experiences the importance of automation in all facets of Information Technology to accelerate delivery, reduce human errors throughout an application lifecycle.

    James most recently worked at GitHub assisting in the development and curation of systems scaling within the Operations group. He is also a frequent speaker on the topic of automation at conferences throughout the world.

    James holds a BS in Information Technology from the University of Phoenix.   Twitter: http://www.twitter.com/jfryman