Author: Alec Lazarescu

  • Continuous Improvement: The Key DevOps Distinguisher

    Continuous Improvement: The Key DevOps Distinguisher

    DevOps has become a well-accepted and growing component for delivery success, shown in the State of DevOps Report among other respected publications. But even as it becomes more ubiquitous, it’s naive to think every organization will cease having delivery concerns. Implementations will differ widely, and adherence is essentially self-reported. So what is it, then, that separates those organizations that struggle with effective software delivery for years from those that consistently shoot further past their competitors?

    The fuzzier nature of the culture and relationships aspects of DevOps obstruct the potential for an ISO- or CMMI-style certification—which is likely a good thing, though it also opens the door for DevOps to be simply a re-branding exercise without any teeth. As a guideline, the CAMS model is still an excellent overview of key DevOps principles. It lays the groundwork for measurement, feedback and sharing that set the stage for improvement, yet stops before making continuous improvement a top-level concern.

    The rate of continuous improvement is the metaphorical equivalent of compounding interest. It takes just a simple illustration to show how starting further behind, but focusing on continuous improvement, can take you past those that have more initial resources.
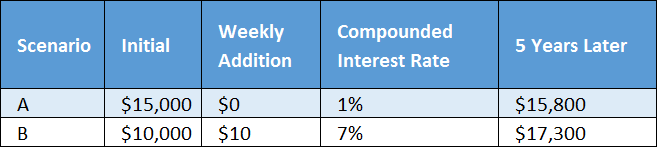
    Compounded Growth

    Prioritizing DevOps for Continuous Improvement

    DevOps with a focus on Kaizen or continuous improvement can catapult a company’s ability to effectively deliver software. Unfortunately, it falls squarely in the Important/Not Urgent quadrant in Stephen Covey’s model, where good ideas and good intentions are continuously frozen. An inability to keep momentum and traction in this state affects many companies.

    To reach our goal of continuous improvement in the DevOps implementation in a company, first we must examine how to successfully drive internal initiatives in general. As a default behavior, companies commonly relegate themselves to just making it through quarter to quarter, delivering mostly incremental customer features. More ambitious initiatives draw lots of excited talk in executive suites, yet often stall and get delayed in actual implementation. Why is that an all-too-common occurrence?

    There are three main hurdles:

    • Inconsistency of shared goals and priorities across all levels of the organization: There’s often a gap somewhere around either middle management or line management where initiatives can tend to slip. It doesn’t hurt to over-communicate and ensure it goes across all levels, especially when important changes are occurring.
    • Lack of individual accountability and empowerment: If communication is adequate, do individuals know not just the goals but also what they can and should be doing to reach them? This aspect is in principle tackled by official systems such as management by objectives (MBO) or objectives and key results (OKR). You can find success or failure in many systems, so rather than debating the merits of various people management systems, make sure to focus on the key goals and actions chosen.
    • Do people actually have the budget of time and potentially funding to take action? Without time for action, there is only a nebulous intention—and perhaps a slight feeling of guilt at not having made progress.

    Simply identifying the above obstacles and addressing their existence can be eye-opening and likely will cause common-sense measures to emerge to align the organization. After the initial quick wins, there certainly will be more difficult steps to follow that are specific to each organization. The end result is certainly worthwhile.

    Unblocking the organizational obstacles to DevOps implementation, not as a one-time project but an evolving program of continuous improvement, blazes the path for long-term success.

    As a further thought, imagine you also accelerate the rate of continuous improvement so it’s not a constant. An amazing example of the power of acceleration is the notion of a solar sail: Accelerating its velocity just 1 millimeter per second seems imperceptible, yet after one day, it’s moving 195 mph, and after 12 days, it’s up to 2,300 mph. “Astronomical” is an apt description of the delivery speed of some famous tech startups. That’s the power of continuous improvement!

  • Are we really back to “just reboot it”?

    Are we really back to “just reboot it”?

    The server infrastructure management style of pets vs cattle was originally coined by Bill Baker of Microsoft though Randy Bias of CloudScaling further popularized it in 2012 and revised and clarified in this presentation. Essentially the original “pets” style of server management has mainly hand-built, named, and configured servers that are heavily cared for as much time has gone into their setup while the newer cloud style of “cattle” management has servers that are often numbered and created and scaled via automation and simply removed from service in the case of any issue. Colloquially the removal is termed “shoot the offending node in the head (STONIH)”.

    In the past due to poor practices or OS service instability (NT4 comes to mind), sysadmins and developers often did not bother to figure out the root cause of issues and simply made reboots part of standard operation procedure. In the times before 24/7 global customer bases and always on broadband and smartphones it may not have even been a big deal.

    On the surface cavalierly destroying and refreshing machines misbehaving in some way seems eerily similar to reboots. It’s different this time. Really.

    Virtualization

    Virtualization itself can cause a special class of issues that are out of your control. Noisy neighbor problems, underlying VM infrastructure/network or other issues can often only be resolved by starting a fresh node (possibly in a different logical area).

    High Availability (HA)

    HA has become more ingrained in systems architecture. For most instances, without inordinate effort you should be able to smoothly take out a bad server out of a cluster or load balancer with no or minimal downtime so you’re not making your users suffer and in fact will be giving them a better experience than potentially landing on a server with intermittent or worse issues.

    Following a few proper procedures provides some important differentiation and further opportunities to investigate compared to simple reboot techniques.

    Automation and Configuration Management

    Solid automated provisioning allows you to bring up the EXACT same machine configuration, put it in a different network subnet, or tweak it to have newer OS patches or software versions for testing if needed. Recreation is not a binary choice. You have options on how you do it and opportunities to learn from it.

    Centralized Monitoring

    Monitoring has come a long way from simple CPU/Disk/Memory and service uptime. Many vendors offer deep views into your application through application performance management (APM). It’s also easier to historically dig into not just that a CPU spike occurred but which processes were hogging cycles at the time to get at a root cause. You can more readily identify if an issue lies with your application or some supporting/OS services and with good automation simply spinning up a new server to test a theory is easier than excessive pondering.

    Centralized Logging

    Centralized logging can allow easier further log inspection after the node is removed and with much better search, analysis, and correlation capabilities than opening each file in a text editor on the machine itself.

    See you later, not farewell…

    The node often doesn’t have to be destroyed. It merely can be pulled out of service or stopped. It or its virtual disks can be examined further at a later time if needed. Exercise caution with spinning up a node again if it has any behavior to auto-join a cluster/farm or will start processing jobs, sending e-mails, etc on its own. Having a practiced isolated network environment can be handy for further analysis and can double as a test bed in the case of potential security breach analysis.

    Herd away

    By following the guidelines above, STONIH will minimize the time any misbehaving nodes affect your user experience. Just don’t forget to follow-up on a root cause especially if patterns or recurrences start!

  • You can’t automate relationships

    You can’t automate relationships

    As an organization sold on the idea of DevOps what’s your first step in the journey?

    Despite a constant deluge of well-reasoned guides for implementing DevOps the most prevalent step most companies have made is simply contributing to a proliferation of DevOps job titles.

    Most likely it’s in no small part because asking the HR department to add “DevOps” to the latest sysadmin job posting title and “Chef” or “Puppet” to the requirements is easy. This is a woefully low bar to set for DevOps implementation. Compounding this further, afterwards when the CIO gets a survey asking about DevOps adoption, they gleefully indicate the company is well on their way and join many others as they artificially inflate industry statistics of a very worthwhile but nonetheless major undertaking for large companies.

    Surveys can contribute to confused starts. Any survey that does not include questions on specific practices and draws its conclusions from simply asking if a company is doing a practice that has positive buzz in the industry is worthless. A welcome contrast is the Puppet Labs 2014 State of DevOps report which is quite a beneficial collection of supporting information covering various practices, recommendations and nuances of organizational structures.

    Even actually making progress on an individual automation project, whether with newly titled DevOps members or from a grass roots effort in an existing engineering or operations team, does not fulfill a complete implementation strategy nor is it the best way to start. Automation is certainly vital to reliably and repeatably managing environments, but groups shouldn’t rush to tackle automation first only because it’s comfortable to start hacking away at a problem they think they can deal with on their own.

    These isolated and well-intentioned practitioners may find that without buy in and solid trust and relationships across groups they may not be given access to automate and orchestrate certain key areas.

    You can’t automate relationships!

    There needs to be a holistic understanding of the value streams driving engineering work and how best to make improvements. Instead of diving headfirst into automation work on identifying common goals, shared pain, and potential wins across organizational groups. Starting either with collaboration between group members directly or through management level alignment can work provided the other quickly follows. Buy in is required from both engineering and management or progress will stutter.

    Taking people through a story can bring support more readily than just listing bullet points. People need to feel emotionally engaged and connected to the pains of the culture and process prior to DevOps and how they can be realistically mitigated. For a large company audience, seeing a story from another large company with timeframes and phases that shepherd the transformation in bold, yet manageable steps can be helpful. The story of SAP Global IT is a candid and useful case study.

    Once the stage is set then tackle automation together in a cross-functional group with shared measures of success leading your focus. Depending on the complexity of your process it may be beneficial to collaborate on a smaller application or time boxed simple proof of concept to vet new ideas and working relationships.

    Despite the potential for rocky or inefficient starts, the transformative power of a meaningful DevOps implementation contributes to incredible innovation speed and satisfaction. What has worked to keep your organization keeping the long view in mind regarding DevOps?

    Many companies are misappropriating the term DevOps to get attention, headcount, or perceived leverage in internal turf wars instead of building a cross-team continuous improvement engine. Is this a sign of the early peak of inflated expectations in the hype cycle?

    Are we heading for a serious backlash? Is the tireless promotion of proper practices from prolific thought leaders enough to make failures clearly misguided implementations and not fundamental flaws in the movement?

    I’m eager to hear your thoughts in the comments.